© The Author(S) 2025
Kun Wang, Zi Wang, and Zhang Li have contributed equally to this work. Extended author information available on the last page of the article Oriented object detection in optical remote sensing images
Using Deep Learning: A Survey
Kun Wang1,2 · Zi Wang1,2 · Zhang Li1,2 · Ang Su1,2 · Xichao Teng1,2 · Erting Pan1,2 ·
Minhao Liu3 · Qifeng Yu1,2
Artificial Intelligence Review (2025) 58:350
Abstract
Oriented object detection is a fundamental yet challenging task in remote sensing (RS), aiming to locate and classify objects with arbitrary orientations. Recent advancements in deep learning have significantly enhanced the capabilities of oriented object detection methods. Given the rapid development of this field, a comprehensive survey of the recent advances in oriented object detection is presented in this paper. Specifically, we begin by tracing the technical evolution from horizontal object detection to oriented object de tection and highlighting the specific related challenges, including feature misalignment, spatial misalignment, oriented bounding box (OBB) regression problems, and common issues encountered in RS. Subsequently, we further categorize the existing methods into detection frameworks, OBB regression techniques, feature representation approaches, and solutions to common issues and provide an in-depth discussion of how these methods ad dress the above challenges. In addition, we cover several publicly available datasets and evaluation protocols. Furthermore, we provide a comprehensive comparison and analysis involving the state-of-the-art methods. Toward the end of this paper, we identify several future directions for oriented object detection research.
Keywords Oriented object detection · Remote sensing · Deep learning
1 Introduction
With the rapid advancement of remote sensing (RS) technologies, an increasing number of images with various resolutions and distinct spectra can be easily obtained by optical satel lites or unmanned aerial vehicles (UAVs). Naturally, the research community has an impera tive need to investigate a variety of advanced technologies for automatically and efficiently processing and analyzing massive numbers of RS images. As a pivotal foundation for auto matically analyzing RS images, object detection is aimed at identifying objects belonging to predefined categories within the given images and regressing a precise localization for
1 3
K. Wang et al. each object instance (Liu et al. 2020; Zou et al. 2023). Currently, object detection is a vital component in a broad range of RS applications, including intelligent monitoring (Zhao et al.
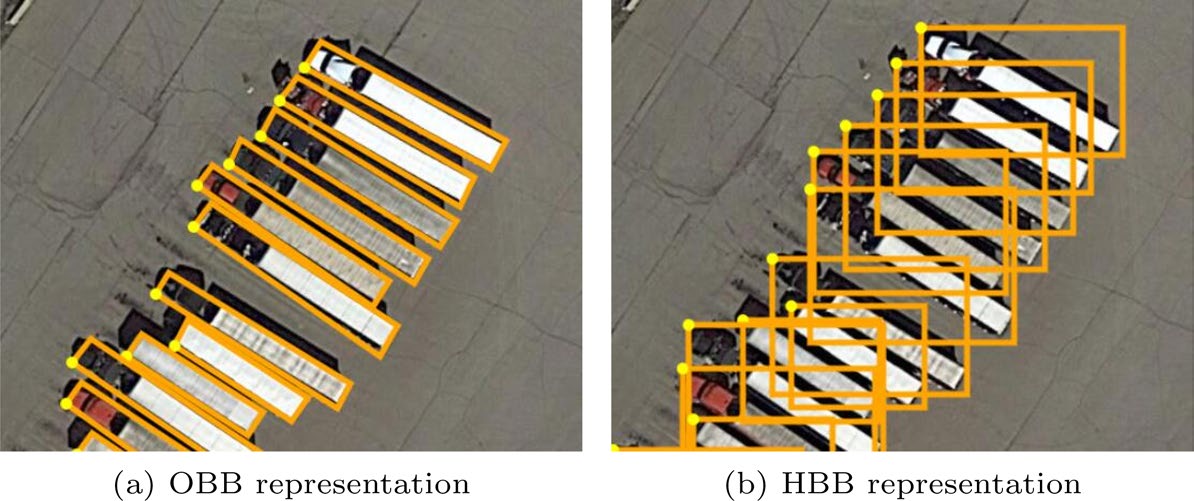
2018), precision agriculture (Osco et al. 2021), urban planning (Burochin et al. 2014), port management (Zhang et al. 2021), and military reconnaissance (Liu et al. 2022). Objects in RS images typically exhibit arbitrary orientations due to their bird’s-eye view (BEV) acquisition perspectives, making the general (horizontal) object detection methods inadequate. In contrast with general object detection, which involves performing object localization via a horizontal bounding box (HBB), oriented object detection (also called rotated object detection) employs an oriented bounding box (OBB) to tightly pack the ori ented object, as shown in Fig. 1. This OBB can not only provide orientation information but also precisely locate the object. Consequently, oriented object detection has attracted considerable attention, especially within the past five years. Although many methods are available, a comprehensive survey specifically focused on oriented object detection is still lacking. Given the continued maturity and increasing concerns about this field, this paper seeks to present a thorough analysis of recent efforts and systematically summarize their achievements.
1.1 Comparisons With Related Surveys
Many prominent surveys have been published in the object detection field in recent years, as summarized in Table 1. Numerous notable surveys have concentrated on generic (hori zontal) object detection, which aims to detect horizontal objects in natural scenarios (Liu et al. 2020; Wu et al. 2020; Zhao et al. 2019; Zou et al. 2023). These surveys covered various aspects, including deep-learning-based detection frameworks, training strategies, feature representation approaches, evaluation metrics, and typical applications.
Furthermore, several efforts have been devoted to specific categories, such as text detec tion (Ye and Doermann 2015) and pedestrian detection (Cao et al. 2022). Additionally, recent surveys have focused on object detection tasks conducted under specific conditions, including small object detection (Cheng et al. 2023), few-shot object detection (Pannone 2022), and weakly supervised object detection (Zhang et al.
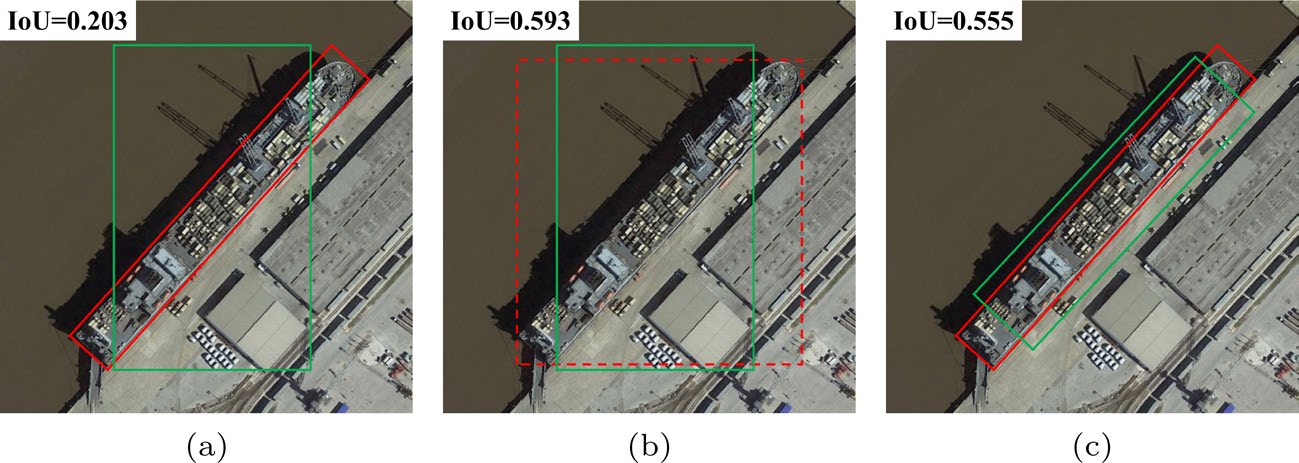
Although a few surveys have analyzed and summarized the RS object detection domain, they frequently lack in-depth analyses of oriented object detection (Cheng and Han 2016; Li et al. 2020, 2021; Han et al. 2021; Wu et al. 2022). Zhang et al. (2023) classified the sub Fig. 1 Comparison between OBB and HBB (Xia et al. 2018; Ding et al. a OBB representation of objects. b is a failure case of the HBB representation, which brings high overlap compared to a
Page 2 Of 61
Oriented object detection in optical remote sensing images using deep… Table 1 Summary of related object detection surveys in recent years
From Handcrafted To Deep Features For
pedestrian detection: a survey (Cao et al.
Towards Large-Scale Small Object Detec
tion: survey and benchmarks (Cheng et al.
Including Rotation Invariance, Anchor-Free
mechanism, and loss function. Top generic object detection. Middle object detection focusing on specific tasks. Bottom RS object detection
350
K. Wang et al. categories belonging to RS object detection as oriented object detection, providing only a brief introduction to OBB representation and rotation-insensitive feature learning methods.
Wen et al. (2023) focused only on describing the details of previously developed oriented object detection methods. Unlike previously presented object detection surveys, which focused on general object detection methods (Liu et al. 2020; Wu et al. 2020; Zhao et al. 2019; Zou et al. 2023), other related fields (Ye and Doermann 2015; Cao et al. 2022; Cheng et al. 2023; Pannone 2022; Zhang et al. 2022), horizontal RS object detection (Cheng and Han 2016; Li et al. 2020, 2021; Han et al. 2021; Wu et al. 2022), or limited numbers of oriented object detection models (Zhang et al. 2023; Wen et al. 2023), this work systematically and comprehensively reviews the recent advances in the field. In particular, relative to the existing surveys con cerning oriented object detection (Zhang et al. 2023), our survey provides a deeper, more comprehensive dive into this field; offers a better taxonomy of the litera ture; and presents discussions regarding the current challenges, comparisons, and future research directions. It involves in-depth analyses of various aspects, many of which, to our knowledge, have never been discussed in oriented object detection surveys. In particular, we review the technical evolution from horizontal to oriented object detection and summarize the main challenges. We systematically summarize and discuss the recent advancements developed under the proposed taxonomies (including detection frameworks, OBB regres sion techniques, feature representation approaches, and solutions to common issues). We provide a comprehensive comparison among the state-of-the-art methods on typical datas ets, along with an in-depth analysis of the pros and cons of these methods.
1.2 Scope
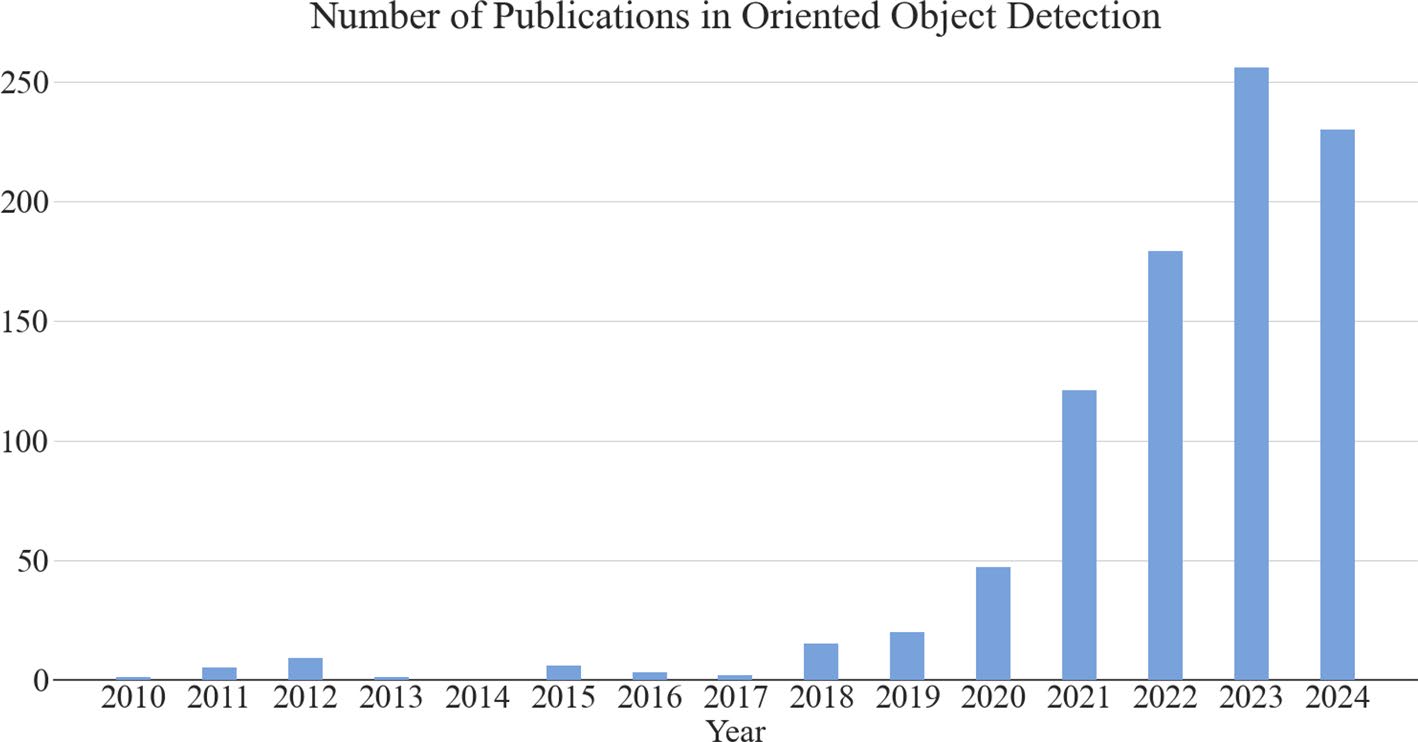
Fig. 2 shows the increasing number of publications related to "oriented object detection" or "rotated object detection" over the past decade. In particular, in the last five years, explo sive growth has been observed in the number of papers published on deep-learning-based oriented object detection methods, rendering it impractical to review all of them. Conse Fig. 2 Increasing number of publications in oriented object detection from 2010 to 2024
Page 4 Of 61
Oriented object detection in optical remote sensing images using deep… quently, it is necessary to establish selection criteria to limit our focus to the influential papers published in top journals and conferences. Owing to these constraints, we extend our sincere apologies to authors whose works are not included in this paper. Notably, we restrict our attention to oriented object detection methods for single images. Nevertheless, for completeness and improved readability, some well-known works on horizontal object detection are also included.
1.3 Contributions
Our contributions are manifested in four aspects. (1) A comprehensive review of the technical evolution from horizontal object detection to oriented object detection On the basis of the characteristics of RS images and the cur rent object detection models, we categorize the main challenges involved in oriented object detection into four main parts: feature misalignment, spatial misalignment, OBB regression problems, and common issues encountered in RS.
(2) A thorough taxonomy of the existing oriented object detection methods To help researchers gain a deeper understanding of the key features of oriented object detection methods, we categorize and summarize the existing oriented object detection methods according to detection frameworks, OBB regression techniques, feature representation approaches, and solutions to common issues.
(3) A comprehensive comparison among the state-of-the-art methods We provide a com prehensive comparison among the state-of-the-art methods on typical datasets, along with an in-depth analysis of the advantages and disatvantages of these methods. This analysis aims to offer valuable insights into the efficacy and applicability of these methods in terms of addressing the main challenges associated with oriented object detection.
(4) Overview of the open issues and future research directions We thoroughly examine several essential issues, shedding light on potential directions for future research, i.e., light weight methods, scenario-specific datasets, multimodal datasets, and large-scale datasets, as well as multimodal large models.
The structure of this paper is organized as follows. We first introduce the development trend from horizontal object detection to oriented object detection and highlight the major related challenges in Sect. 2. We review the existing deep neural network (DNN)-based detection frameworks in Sect. 3. Furthermore, we discuss the OBB regression techniques and feature representation approaches in Sects. 4 and 5, respectively. In addition, we sum marize the solutions to other common issues encountered in RS scenarios in Sect. 6. After an overview of the commonly used datasets is provided in Sect. 7, we analyze and compare the state-of-the-art methods in Sect. 8. Finally, we conclude our work and discuss future directions for oriented object detection research in Sect. 9.
2 From horizontal object detection to oriented object detection The early object detection methods relied on handcrafted descriptors (Lowe 2004; Dalal and Triggs 2005; Fei-Fei and Perona 2005; Wright et al. 2009) and machine learning algo rithms (Cortes and Vapnik 1995; Blaschke 2010; Leitloff et al. 2010; Blaschke et al. 2014).
These methods often have limited performance because of their weak feature representa
350
K. Wang et al. tions. Although such approaches lag far behind deep learning methods in terms of accu racy, their instructive insights still have profound impacts on modern detectors, e.g., sliding windows (Viola and Jones 2001, 2004), hard negative mining, and bounding box regres sion (Felzenszwalb et al. 2008, 2010). Readers interested in these early object detection methods are referred to a recent survey (Cheng and Han 2016) that provided an in-depth analysis of the classic RS object detection methods.
The world has witnessed impressive progress in computer vision with the advances achieved in deep neural networks (DNNs) since 2012 (Hinton and Salakhutdinov 2006; LeCun et al. 2015; Chen et al. 2018; He et al. 2016; Krizhevsky et al. 2012, 2017). Owing to the persistent increases in computing resources, DNNs can learn high-level patterns from large-scale datasets in an end-to-end manner. The pioneering studies bring a little glimmer to the object detection field, especially because the performance of handcrafted-feature- based detectors reached a plateau after 2010. Since then, a growing number of DNN-based detectors have emerged and have dominated the state-of-the-art methods due to their power ful feature representation capabilities.
The early research in the deep learning era was primarily concerned with designing hori zontal object detectors (Girshick et al. 2014; Girshick 2015; Ren et al. 2015, 2017; Liu et al. 2016; Lin et al. 2017, 2020; Redmon et al. 2016; Redmon and Farhadi 2017; Hei and Jia 2020; Duan et al. 2019; Zhou et al. 2019; Yang et al. 2019) for natural scene images taken from a horizontal perspective. Naturally, as horizontal object detectors rapidly evolve, e.g., the region-based convolutional neural network (RCNN) series (Girshick et al. 2014; Gir shick 2015; Ren et al. 2015, 2017), You Only Look Once (YOLO) series (Redmon et al.
2016; Redmon and Farhadi 2017), and RetinaNet (Lin et al. 2017, 2020), numerous stud ies are harnessing their immense potential in RS scenarios. A growing number of efforts have focused on refining network structures and crafting innovative data augmentation techniques, all of which have been aimed at addressing the core challenges encountered in RS object detection scenarios, including scale variations (Liang et al. 2020; Ye et al.
2022; Liu et al. 2022; Khan et al. 2022; Li et al. 2023; Wang et al. 2025), complex back grounds (Lu et al. 2021; Huang et al. 2022; Ma et al. 2022; Zhou et al. 2023), and weak feature responses (Tian et al. 2022; Wu et al. 2022; Zhuang et al. 2024).
Nevertheless, RS images are typically captured from a BEV, leading to objects appear ing with arbitrary orientations. Hence, directly applying horizontal object detectors to RS images may lead to the following problems. (1) The intersection-over-union (IoU) between one HBB and the adjacent HBBs can be very large in densely arranged scenarios, espe cially for objects with extremely large aspect ratios, as illustrated in Fig. 1b. Thus, the nonmaximum suppression (NMS) technique tends to result in missed detections. (2) HBBs are inclined to contain background areas, whereas OBBs can tightly enclose objects, thereby achieving more precise localization effects, as shown in Fig. 1a. Given the above predica ment concerning HBBs, OBBs are considered more appropriate for RS object detection tasks.
With the remarkable development of detection frameworks (Ren et al. 2015, 2017; Lin et al. 2017, 2020; Redmon et al. 2016; Carion et al. 2020), backbone networks (He et al. 2016; Liu et al. 2021), and robust feature representations (Liu et al. 2022; Dosovitskiy et al. 2021), the field of object detection has achieved dramatic breakthroughs. Naturally, an intuitive strategy for designing oriented object detectors is to modify the representative hori zontal object detectors by predicting additional parameters to represent OBBs (Zhou et al.
Page 6 Of 61
Oriented object detection in optical remote sensing images using deep… 2022). However, such a straightforward strategy is plagued by several additional challenges, including feature misalignment, spatial misalignment, and OBB regression problems.
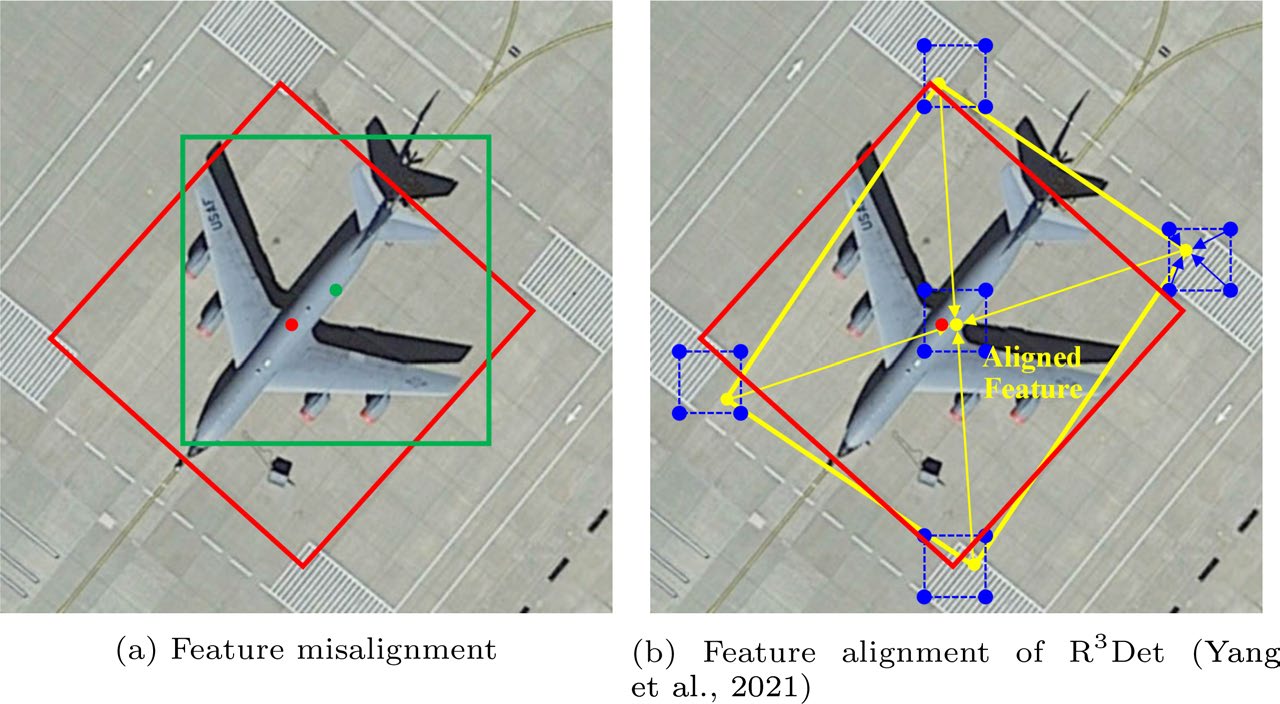
(1) Feature misalignment The prevailing generic object detectors typically contain a fea ture extraction network followed by a detection head, where the latter leverages the feature representations generated by the former to make decisions. However, these feature rep resentations are generally extracted via axis-aligned convolutions, thereby exposing non negligible misalignment issues w.r.t. the oriented objects, as shown in Fig. 3a. This type of misaligned feature representations degrades the performance of oriented object detectors because of their lack of rotational information, making the detectors struggle to identify objects and regress precise OBBs.
(2) Spatial misalignment In addition to feature misalignment, the widely used anchor- based detection methods also struggle with spatial misalignment. Generic anchor-based detectors typically use horizontal anchors as priors, thereby having limited IoUs with ori ented objects, especially for objects with extremely large aspect ratios, as shown in Fig. 4a.
This poses a significant challenge to generic label assignment strategies (Ren et al. 2015, 2017), which assign positive or negative samples depending on their IoUs. Thus, the naïve anchor generation mechanism is likely unable to provide sufficient positive samples during the training process.
(3) OBB regression problems The current detectors commonly use the regression para digm to represent the locations of objects, which has been proven to be an effective approach and has yielded dramatic achievements. The most commonly used representation methods for OBBs include θ-based and quadrilateral representations. However, the former suffers from the periodicity of angles (PoA), causing angular boundary discontinuities (Yang et al.
2021, 2022; Qian et al. 2021, 2022). Specifically, a small angle difference may cause a large loss change when the angular value approaches the angular boundary range. On the other Fig. 3 Illustration of feature misalignment and feature alignment. a The misalignment between oriented objects and the axis-aligned feature representations of anchor. b A example of feature alignment proposed by R3Det (Yang et al. 2021), which align the feature representations by integrating the features accord ing to the five refined points of the predicted obb. The red, green, and blue boxes represent the ground truth (GT), anchor, and predicted obb, respectively. The blue and yellow points denote anchor points and refined feature points, respectively. The blue and yellow arrows denote feature interpolation and feature
350
K. Wang et al. hand, the latter faces challenges related to vertex ordering because an inappropriate vertex sorting process may cause inconsistencies between the vertex sequences of the predicted OBB and the ground truth (GT). Overall, both the PoA and vertex ordering problems can seriously confuse the networks, leading to training instability. For more details, please refer to Sects. A and B of the Appendix.
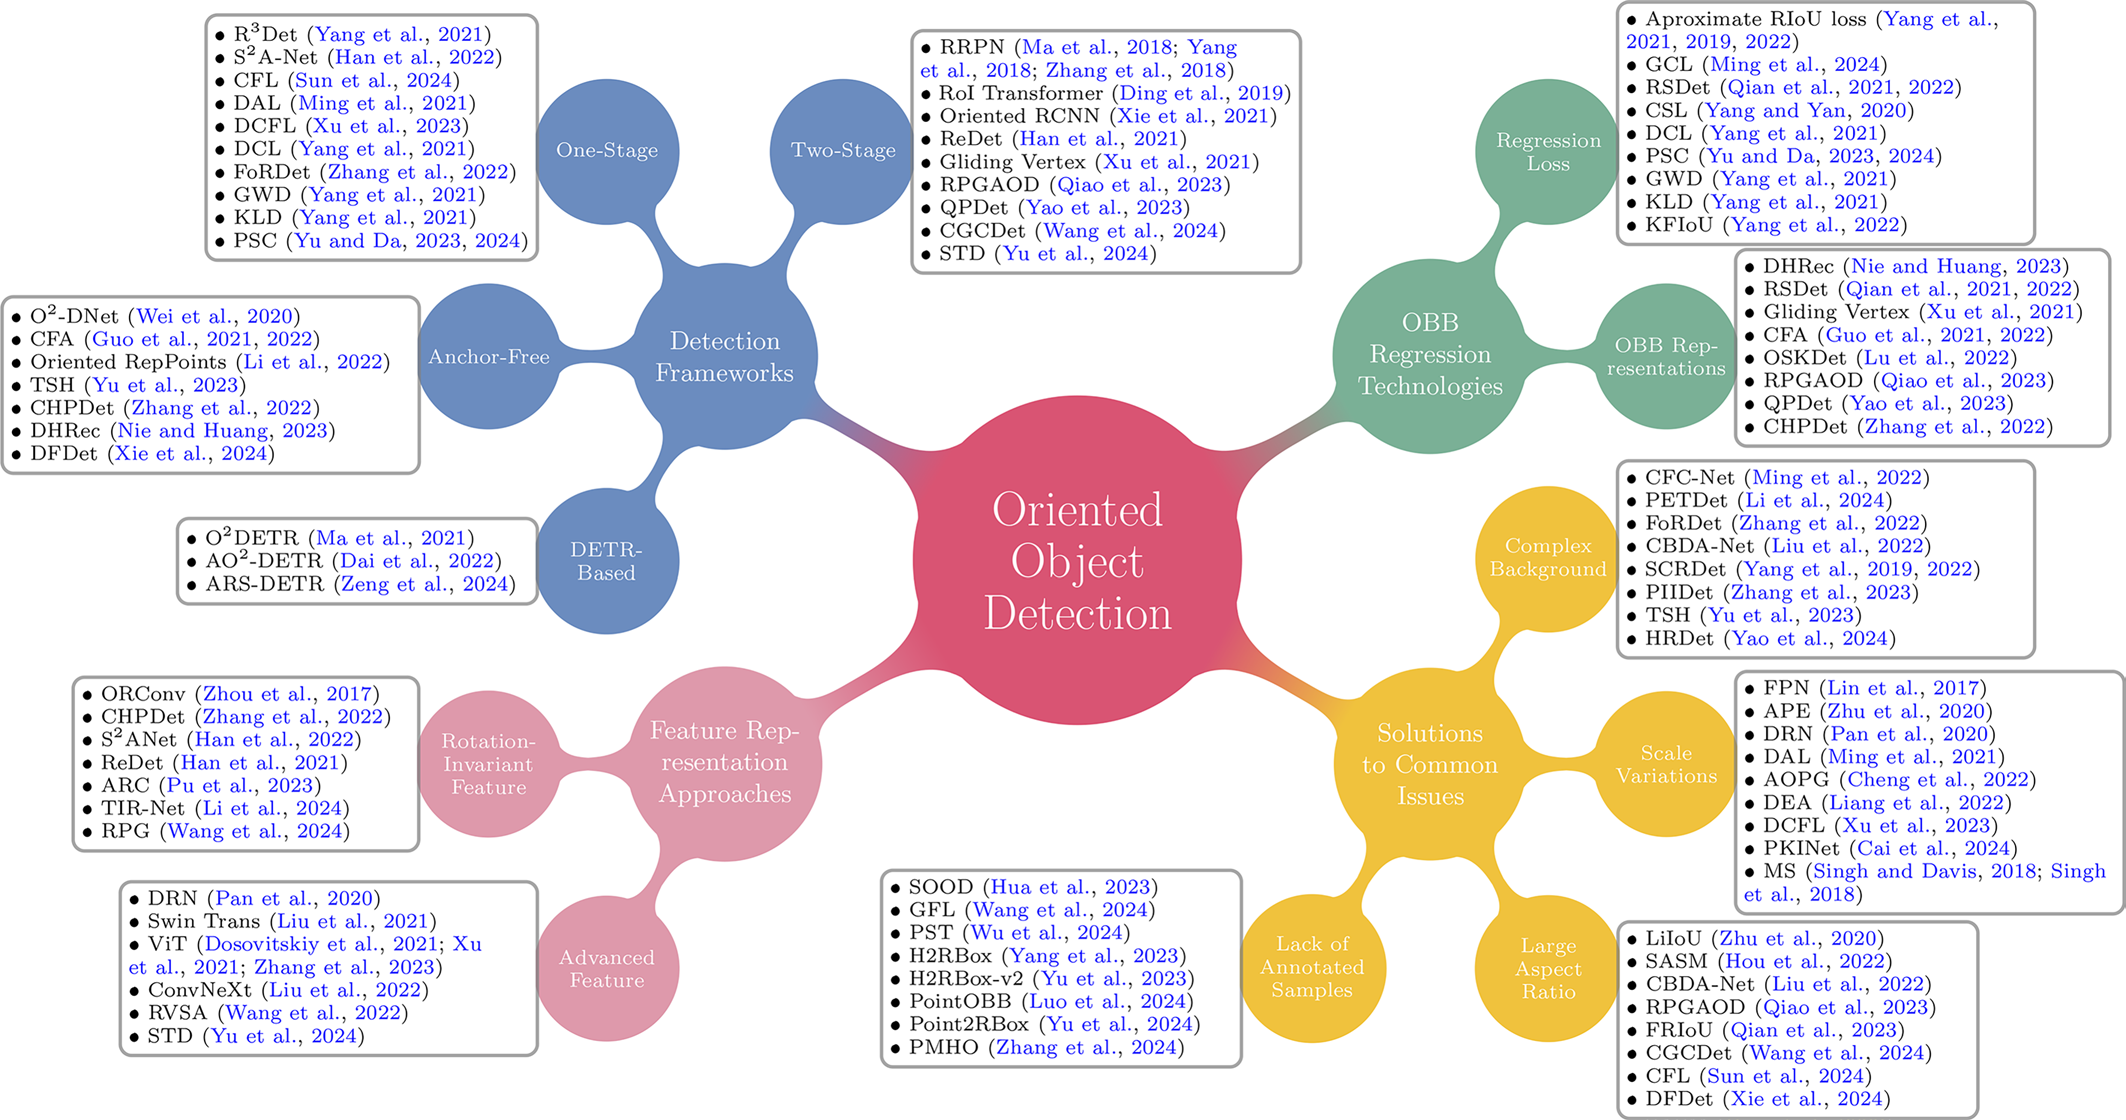
To address the above dilemmas, various works have been conducted and have achieved notable advancements. Several methods construct well-designed detection frameworks by devising rotated proposal generation networks (Sect. 3.1) or refined heads (Sect. 3.2) to remedy feature misalignment. To address spatial misalignment, researchers have focused on improving their assignment schemes (Sect. 3.1) and adopting anchor-free mechanisms (Sect. 3.3). For OBB regression problems, several efforts have been made to design effec tive OBB regression technologies through the development of new loss functions (Sect. 4.1) and OBB representation schemes (Sect. 4.2). In addition, high-quality feature representa tions are crucial for performing object detection; hence, much effort is concentrated on designing networks to produce better feature representations, including rotation-invariant feature representations (Sect. 5.1) and advanced feature representations (Sect. 5.2). We also cover the solutions for addressing several common issues (Sect. 6) encountered in RS sce narios. Figure 5 shows the taxonomy of the oriented object detection methods examined in this survey.
3 Detection Frameworks
Object detection methods can be categorized into two primary groups: two-stage and one- stage detection (Liu et al. 2020; Zou et al. 2023). The former work in a coarse-to-fine paradigm, whereas the latter accomplish classification and regression in one step, thereby exhibiting high efficiency but poor accuracy. In contrast with the aforementioned two cat egories, which rely on anchor mechanisms, anchor-free methods directly detect objects without the need for predefined anchors. In addition, a series of DETR-based methods have recently emerged; such methods regard the detection process as a set prediction task, thereby effectively eliminating several handcrafted components, e.g., NMS and anchor mechanisms.
Considering that each category has advantages and disadvantages, we divide the representa Fig. 4 Illustration of spatial misalignment. a The IoU between horizontal anchor and oriented object is very small, causing spatial misalignment. b, c Calculating the IoU between either horizontal anchor and horizontal bounding rectangle of object, or rotated anchor and oriented object, can alleviate the spatial misalignment. The red and green boxes represent the GT and anchor, respectively
Page 8 Of 61
Oriented object detection in optical remote sensing images using deep… Fig. 5 Structured taxonomy of the deep learning based oriented object detection methods in this survey
350
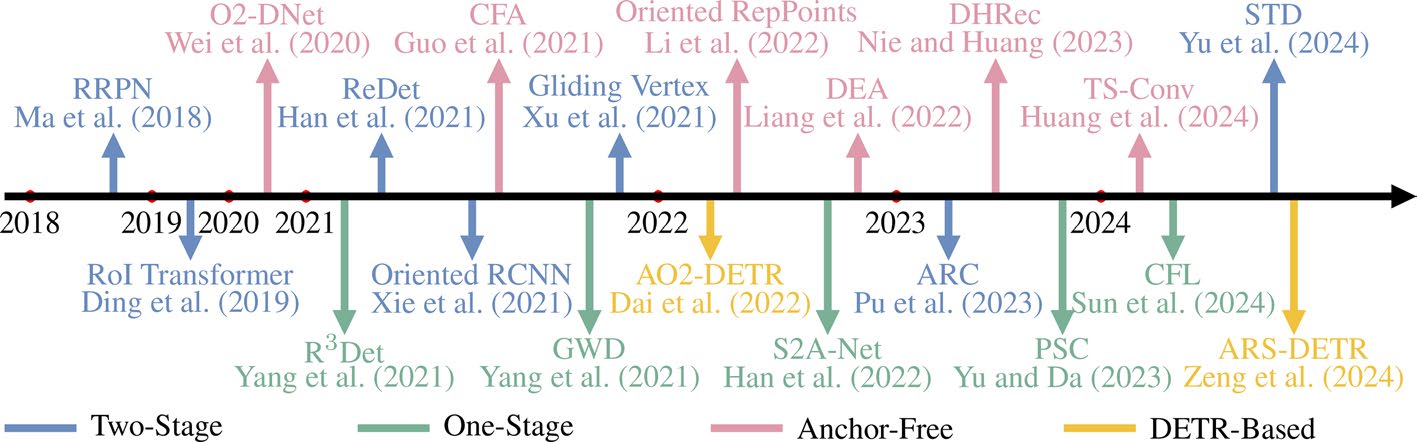
K. Wang et al. tive oriented object detectors into four categories: two-stage, one-stage, anchor-free, and DETR-based. Several key methods are presented in Fig. 6. Next, we concisely review how each category addresses the feature misalignment and spatial misalignment via deliberate framework designs.
3.1 Two-Stage Detectors
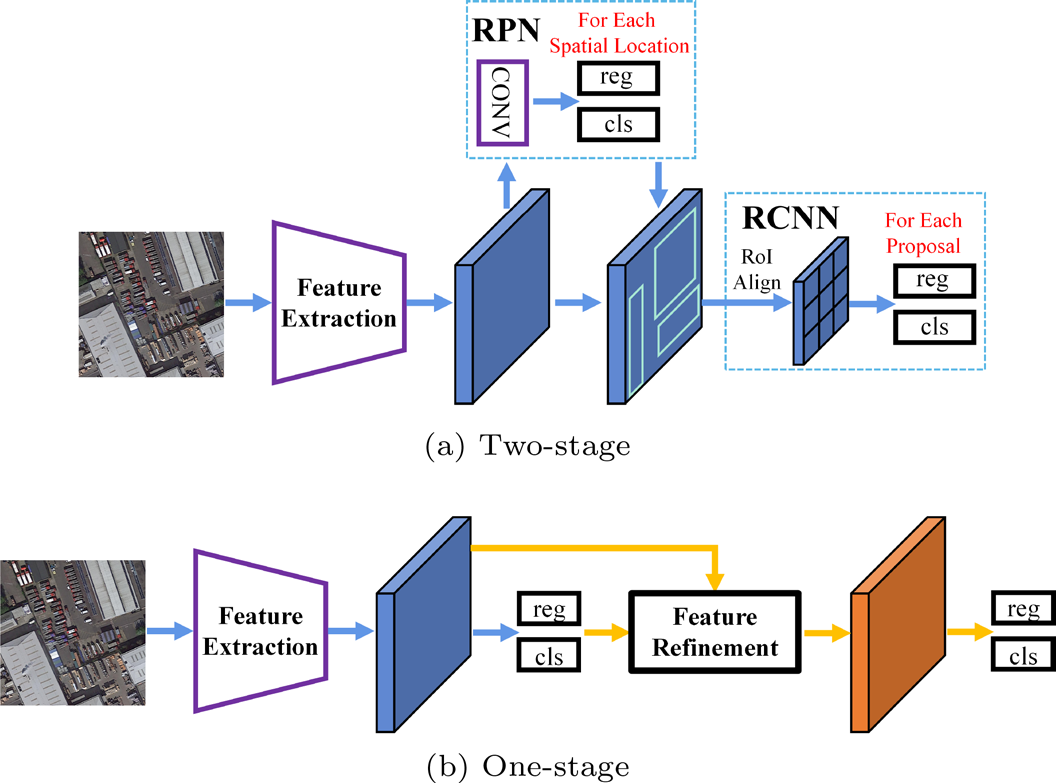
Among the numerous prominent two-stage detectors (Ren et al. 2015, 2017; Lin et al. 2017; Cai and Vasconcelos 2018; He et al. 2020; Qiao et al. 2021), the Faster RCNN (Ren et al. 2015, 2017) armed with feature pyramid networks (FPN) (Lin et al. 2017) is commonly used as a benchmark owing to its exceptional accuracy and efficient design. As depicted in Fig. 7a, its workflow consists of the following pipeline: a feature extraction module, a region proposal network (RPN), and an RCNN. In the first stage, a sparse set of high-quality region proposals that can potentially contain objects is generated via the RPN (Chavali et al.
2016; Hosang et al. 2016). During the second stage, the region features of each proposal are extracted and then used for classification and refined regression processes via the RCNN. Finally, several post-processing operations, such as NMS, are leveraged to finalize the detection results (omitted in Fig. 7a). The oriented version of this method, termed Rotated Faster RCNN or Faster RCNN OBB, predicts the orientation of each object by adding an extra channel in its regression branch.
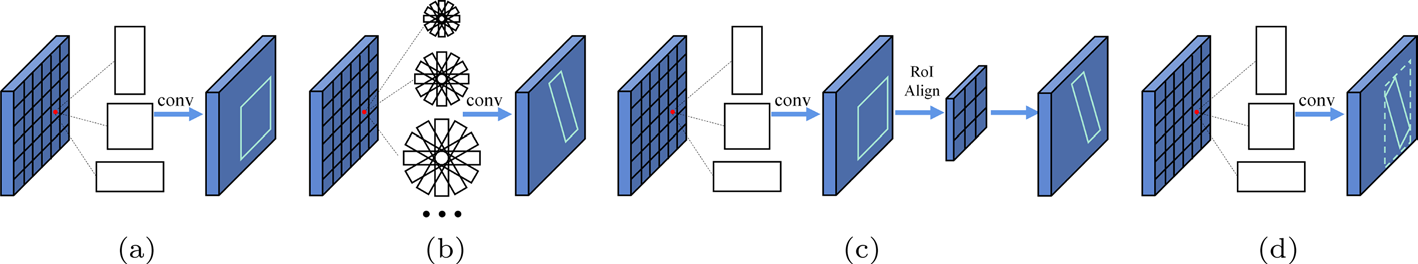
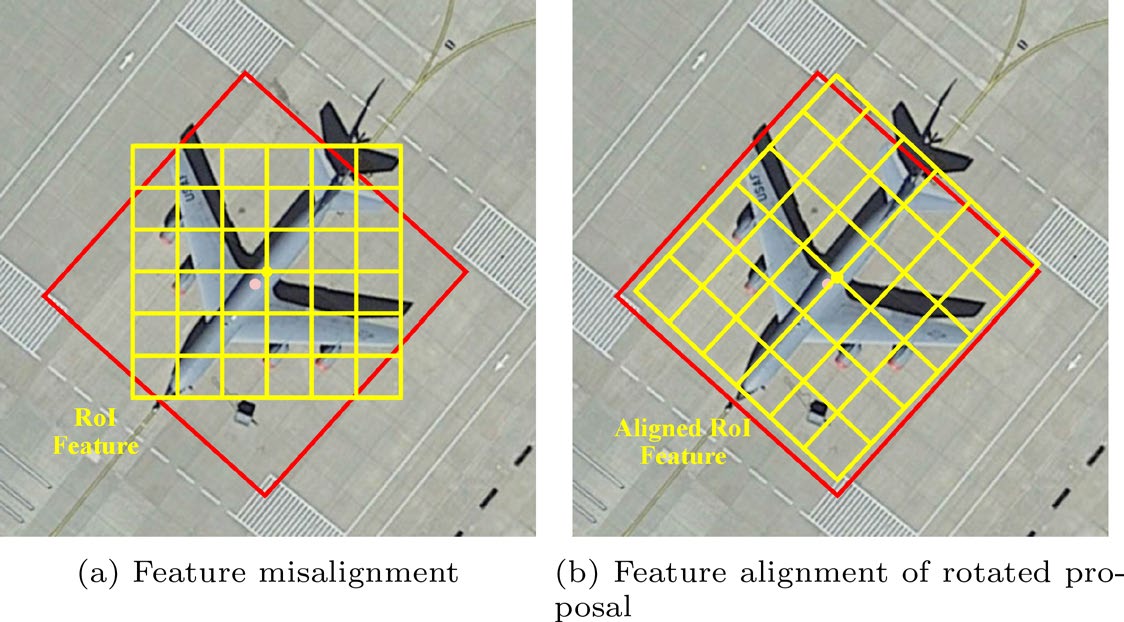
However, the naïve RPN only generates horizontal region proposals as regions of inter est (RoIs), as shown in Fig. 8a. Apart from the feature misalignment caused by axis-aligned convolutions, another factor that may impair the performance is the feature misalignment between the horizontal RoI (HRoI) and the OBB, as shown in Fig. 9a. The feature misalign ment significantly harms the feature representations, making the utilized detector struggle to identify objects and regress precise OBBs yet inspiring successive innovations.
To cope with feature misalignment, various efforts have been dedicated to generating rotated proposals and then adopting rotated RoI (RRoI) operators to extract spatially aligned features, as shown in Fig. 9b. The RRPN (Ma et al. 2018; Yang et al. 2018; Zhang et al.
2018) incorporates rotated anchors to accommodate objects with various orientations. In addition to scales and aspect ratios, different orientation parameters can be added to further generate additional rotated anchors, as shown in Fig. 8b. This method can alleviate spatial misalignment (as shown in Fig. 4c), thereby achieving better performance in terms of recall.
However, redundant rotated anchors lead to significantly increased computational costs and memory footprints. To reduce the number of rotated anchors, the RoI Transformer (Ding et al. 2019) retains the naïve RPN structure to alleviate spatial misalignment (as shown in Fig. 4b) and then introduces a lightweight RoI learner module. As shown in Fig. 8c, the RRoI learner converts HRoIs directly into RRoIs, generating precise RRoIs without enormous numbers of rotated anchors, thus increasing the efficiency and accuracy. However, the added complexity of the RoI learner, which includes an extra RoI operator and a regression stage, makes the network less efficient.
Consequently, Xie et al. (2021) designed a simpler structure, Oriented RCNN, to directly generate high-quality RRoIs from horizontal anchors, as shown in Fig. 8d. This lightweight module benefits from the proposed midpoint offset representation, which includes the cor responding external HBB and the offsets of vertices w.r.t. the midpoints of the external
Page 10 Of 61
Oriented object detection in optical remote sensing images using deep… Fig. 8 The comparisons of different strategies for proposal generation. a RPN only generates horizontal proposals (Ren et al. 2015, 2017). b RRPN densely places rotated anchors with different scales, ratios, and angles (Ma et al. 2018; Yang et al. 2018; Zhang et al. 2018). c RoI Transformer generates rotated pro posal from horizontal RoI via RPN, RoI Alignment, and OBB regression (Ding et al. 2019). d Oriented RCNN can generate high-quality rotated proposals using a lightweight module (Xie et al. 2021) Fig. 7 The basic architecture of two-stage and one-stage detectors. a Two-stage detectors first utilize RPN to predict a set of proposals, then extract corresponding region features for classification and refined re gression. b One-stage detectors predict the class probabilities and locations for each spatial location. Most of them add a refined stage to alleviate the feature misalignment. The blue arrows denote the workflow of RetinaNet (Lin et al. 2017, 2020), while the orange arrows denote the workflow of refined stage Fig. 6 Chronological overview of the representative oriented object detection frameworks
350
K. Wang et al. HBB. This representation scheme maintains horizontal regression mechanisms, ensuring a more stable training process relative to regressing OBBs from horizontal anchors. Benefit ing from the design of the oriented RPN and midpoint offset representation, the Oriented RCNN can achieve competitive accuracy w.r.t. advanced two-stage detectors and reach approximate efficiency in comparison with one-stage detectors.
The excellent designs of the RoI Transformer and Oriented RCNN address the spatial misalignment and feature misalignment faced by two-stage detectors, laying the foundation for subsequent research in this field. Numerous two-stage detectors have since adopted the RoI Transformer or Oriented RCNN as their baseline framework, harnessing exceptional feature representations (e.g., ReDet (Han et al. 2021), RVSA (Wang et al. 2022), ARC (Pu et al. 2023), and STD (Yu et al. 2024)) or crafting superior OBB representations (e.g., Glid ing Vertex (Xu et al. 2021), RPGAOD (Qiao et al. 2023), and QPDet (Yao et al. 2023)) and loss functions (e.g., FRIoU (Qian et al. 2023), CGCDet (Wang et al. 2024), and GCL (Ming et al. 2024)) to increase their performance. These methods will be discussed in detail in the subsequent section.
3.2 One-Stage Detectors
As illustrated in Fig. 7b, one-stage detectors first extract multilevel feature maps and then predict the class probabilities and locations for each anchor per spatial location. Owing to the absence of RPN and RoI operators, one-stage detectors encounter more severe feature misalignment than two-stage detectors do. Thus, a series of one-stage algorithms, such as R3Det (Yang et al. 2021) and S2A-Net (Han et al. 2022), have been developed to alleviate this dilemma.
R3Det (Yang et al. 2021) adopts a feature refinement module (FRM) to align features. First, R3Det transforms its horizontal anchors into rotated anchors, which can provide more accurate positional and oriented information. Then, the FRM employs pixelwise feature interpolation to integrate features derived from the five locations (i.e., one center and four corners) of the corresponding refined rotated anchors, as shown in Fig. 3b. Similarly, S2 Fig. 9 Illustration of feature misalignment in two-stage detectors. a The feature misalignment between oriented object and horizontal region proposal. b Detectors can extract aligned features from rotated
Page 12 Of 61
Oriented object detection in optical remote sensing images using deep… A-Net (Han et al. 2022) aligns features via alignment convolution (AlignConv), which is a variant of deformable convolution (Dai et al. 2017). The offset field of AlignConv is inferred from the guidance of rotated anchors. Both the FRM and AlignConv operate in a coarse- to-fine manner but differ significantly from the RRoI operator. Notably, they follow a full convolution structure with fewer sampling points, resulting in increased efficiency.
Based on S2A-Net, CFL (Sun et al. 2024) introduces a spatial transform selection (STS) strategy and a critical feature sampling (CFS) module. STS dynamically assigns labels by calculating IoU thresholds on the basis of aspect ratios, angle differences, and the initial IoU threshold determined by ATSS (Zhang et al. 2020). The adaptable IoU threshold con trols the number of samples assigned to easy objects while ensuring that sufficient positive samples are provided for hard objects with large aspect ratios and angle differences. CFS incorporates a deformable convolution in which the sampling positions are derived from the initial detection results (center point, vertices, and midpoints) combined with a learnable offset field.
Both R3Det and S2A-Net utilize an extra refined head for feature alignment, making them popular baseline choices as one-stage detectors. These methods further solve the spa tial misalignment and OBB regression problems via innovative sample assignment strate gies (e.g., DAL (Ming et al. 2021) and DCFL (Xu et al. 2023)) or regression losses (e.g., DCL (Yang et al. 2021), FoRDet (Zhang et al. 2022), GWD (Yang et al. 2021), KLD (Yang et al. 2021), and PSC (Yu and Da 2023, 2024)). In the following section, we provide a detailed introduction to these methods.
3.3 Anchor-Free Detectors
The above two categories follow the anchor paradigm, which suffers from spatial misalign ment between horizontal anchors and OBBs. To address the above issues, numerous anchor- free methods have been developed to detect objects without relying on preset anchors. These methods eliminate anchor-related hyperparameters, showing potential for generalization to wide-ranging applications (Zhang et al. 2020). According to their representations of OBBs, anchor-free methods can be divided into keypoint-based methods and center-based methods.
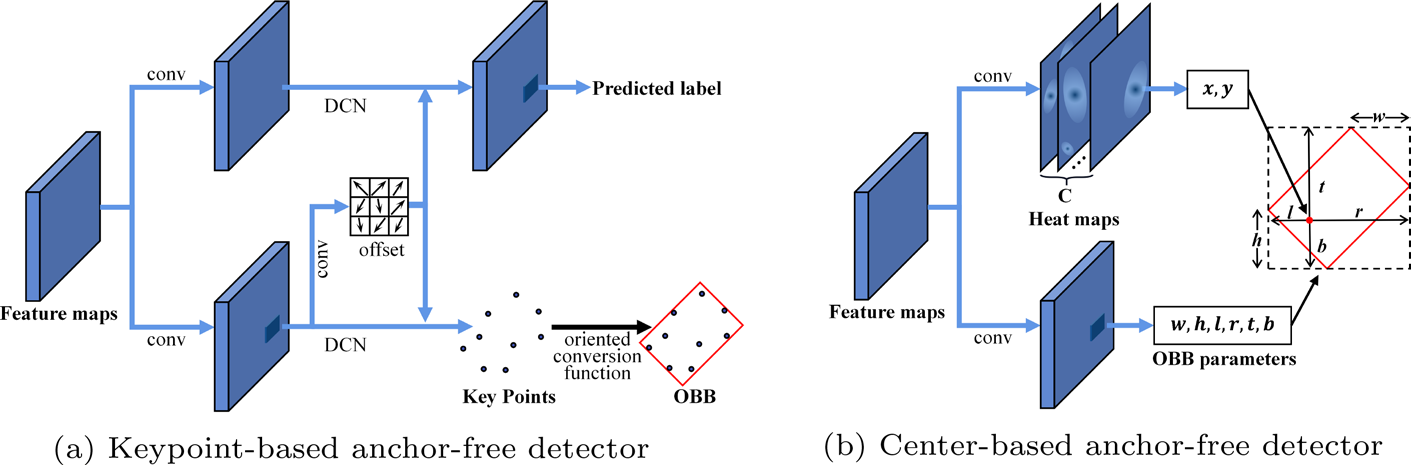
Keypoint-based methods first locate a set of adaptive or self-constrained keypoints and then circumscribe the spatial extent of an object, as shown in Fig. 10a. For example, O2 -DNet (Wei et al. 2020) first locates the midpoints of four sides of the OBB by regressing the offsets from the center point. The two sets of opposite midpoints are subsequently con nected to form two mutually perpendicular midlines, which are decoded to represent the OBB. In addition, a self-supervision loss constrains the perpendicular relationship between two middle lines and the collinear relationship between the center point and the two oppo site midpoints. Following RepPoints (Yang et al. 2019), CFA (Guo et al. 2021, 2022) uses deformable convolution (Dai et al. 2017) to generate a convex hull for each oriented object.
The convex hull, which is represented by irregular sample points, is refined using a convex IoU (CIoU) loss. To alleviate the feature aliasing problem between densely packed objects, convex hull set splitting and feature antialiasing strategies are designed to refine the convex hulls and adaptively optimize the feature assignment process.
Furthermore, to predict high-quality oriented reppoints, Oriented RepPoints (Li et al. 2022) employs an adaptive point assessment and assignment (APAA) scheme to measure the quality of the reppoints. The APAA process assesses reppoints across four dimensions
350
K. Wang et al. (classification, localization, orientation alignment, and pointwise correlation) to select high-quality points without imposing an additional computational burden during inference.
Subsequently, Yu et al. (2023) proposed a dynamic information aggregation (DIA) module based on a multihead self-attention mechanism (Vaswani et al. 2017). By mining the rela tionships between reppoints, DIA not only helps obtain more accurate reppoint positions but also enriches the feature representations, thereby further increasing the model localization accuracy.
Center-based methods typically generate multiple probabilistic heatmaps and a series of feature maps. As shown in Fig. 10b, the heatmaps provide a set of candidates (peak points) as coarse center points, whereas the feature maps regress the transformation parameters to represent the OBB. Currently, most center-based methods, including CHPDet (Zhang et al.
2022), GGHL (Huang et al. 2022), and DHRec (Nie and Huang 2023), are dedicated to designing a variety of OBB representations for addressing PoA problems. However, these methods typically follow one-stage paradigms and tend to predict coarse locations due to feature misalignment, whereas the state-of-the-art methods generally involve one or mul tiple refined stages to improve their performance.
Hence, an effective scheme for increasing the performance of such an approach is to leverage anchor-free methods to generate coarse detection results that are then refined via a subsequent feature alignment stage, e.g., AOPG (Cheng et al. 2022), DEA (Liang et al.
2022), DRDet (Zhang et al. 2023), and TS-Conv (Huang et al. 2024). AOPG (Cheng et al. 2022) initially produces coarse oriented boxes via the rotated FCOS approach (Tian et al. 2019), subsequently refining them into high-quality oriented proposals. DEA (Liang et al.
2022) leverages two parallel branches, which separately generate proposals using anchor- free and anchor-based approaches, followed by an interactive sample screening procedure to select high-quality training samples.
In contrast with the above two methods, which capitalize on the merits of anchor-free techniques to mitigate spatial misalignment and facilitate an appropriate sample assignment process, DRDet (Zhang et al. 2023) and TS-Conv (Huang et al. 2024) concentrate on feature refinement. DRDet (Zhang et al. 2023) adopts two perpendicular rotated lines to represent the OBB. Then, an orientation-guided feature encoder (OFD) is employed to encode the orientation-aware information into refined features along each rotated line. Compared with rectangular features, the line features extracted from the OFD can introduce less noise and alleviate the feature aliasing issue caused by overlapping objects. TS-Conv (Huang et al.
2024) utilizes different sampling offsets for localization and classification to alleviate the Fig. 10 The basic architecture of keypoint-based and center-based anchor-free detectors
Page 14 Of 61
Oriented object detection in optical remote sensing images using deep… task misalignment problem (i.e., localization and classification tasks may focus on different feature regions (Song et al. 2020)). The sampling offsets are restricted by the initial OBBs predicted in an anchor-free manner, allowing for dynamic adaptations to objects with vari ous shapes.
3.4 Detr-Based Detectors
In addition to the above convolution-based methods, DETR-based detectors, including DETR (Carion et al. 2020) and its variants (Zhu et al. 2021; Sun et al. 2021; Gao et al. 2021), have exhibited great potential and achieved state-of-the-art performance in the detec tion community. On the basis of DETR (Carion et al. 2020), O2DETR (Ma et al. 2021) was proposed to utilize a transformer for completing oriented object detection tasks. In addition, depthwise separable convolutions (Sifre and Mallat 2013; Chollet 2017; Haase and Amthor 2020) were introduced to replace the computationally complex self-attention mechanism, making networks more lightweight and speeding up their training processes. To address feature misalignment, Dai et al. (2022) proposed AO2-DETR by improving the deformable DETR (Zhu et al. 2021); they designed an oriented proposal generation mechanism and an adaptive oriented proposal refinement (OPR) module for aligning the features. Recently, several improved DETR-based detectors have been proposed for generic object detection tasks, e.g., DN-DETR (Li et al. 2022), DAB-DETR (Liu et al. 2022), and DINO (Zhang et al. 2022), resulting in dramatic breakthroughs in terms of accuracy and convergence speed. ARS-DETR (Zeng et al. 2024) attempts to exploit DINO (Zhang et al. 2022) in oriented object detection tasks. Compared with other advanced oriented object detectors, it achieves greater detection accuracy in terms of a more rigorous metric (i.e., AP75), but it lags w.r.t. the standard metric (i.e., AP50). Moreover, the long training convergence time and heavy computational cost of this method are still open problems.
3.5 Discussion
Feature misalignment and spatial misalignment severely impair the performance of ori ented object detection methods. To address these issues, substantial research has contributed to modifying the current detection frameworks. The existing two-stage detectors typically employ efficient and precisely oriented proposal generation modules, leveraging RRoI operators to extract rotated aligned features. Similarly, one-stage detectors are inclined to incorporate an extra refined stage for feature alignment. Thus, the above two schemes can empower detectors to mine rotation-related information, thereby enhancing the semantic representations of oriented objects.
Nevertheless, spatial misalignment remains a persistent issue. Anchor-free detectors address this problem by eliminating the anchor mechanism and, in advanced methods, incorporating extra feature refinement stages to further mitigate feature misalignment.
In addition, DETR-based methods provide a new detection paradigm and have received widespread attention. However, the exploration of DETR-based methods in oriented object detection is not sufficiently comprehensive, and further research is needed to accelerate the convergence of the training process and reduce the computational overhead.
Well-designed detection frameworks are conducive to alleviating feature and spatial misalignment but fail to address PoA problem. In addition, the extracted features are not
350
K. Wang et al. equipped with rotation invariance, as the convolution operators are axis-aligned. To over come these dilemmas, suitable OBB regression techniques and powerful feature repre sentations of oriented objects have also been widely studied since they can be seamlessly integrated into various detection frameworks. Next, we discuss the OBB regression tech niques and feature representation approaches.
4 Obb Regression Technologies
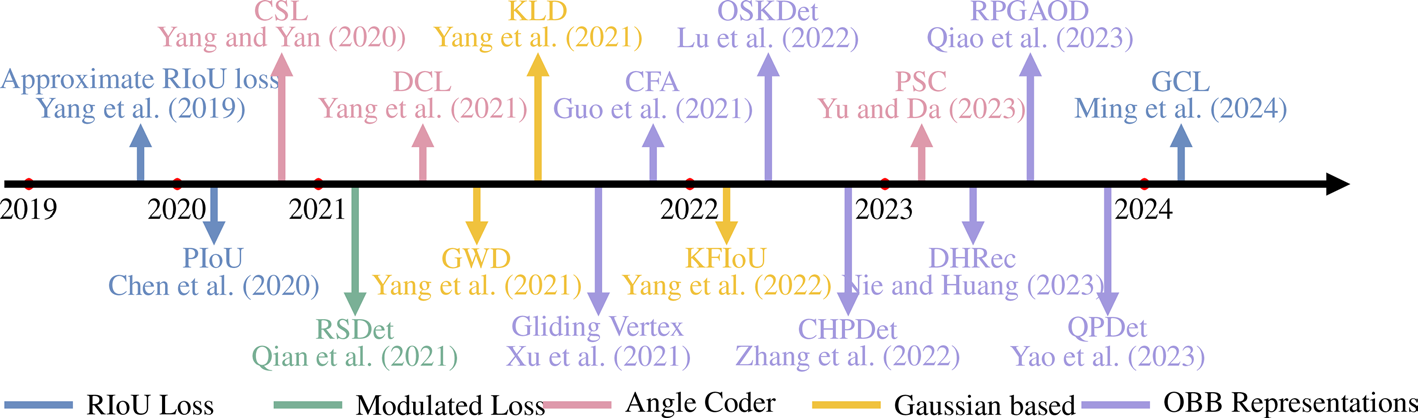
Oriented object detectors typically locate objects through regression. Specifically, a custom ized regression head predicts the orientation parameters when the most frequent θ-based representation is used. Unfortunately, such a regression paradigm suffers from several limi tations, including metric-loss inconsistency and angular boundary discontinuities. For more details about the above issues, please refer to Sect. A of the Appendix or the corresponding papers (Qian et al. 2021, 2022; Yang et al. 2021, 2022; Xu et al. 2021). To address these issues, the existing oriented object detection methods usually develop novel loss func tions or alternative representations for OBBs. Several representative methods are shown in Fig. 11. Next, we briefly introduce them and discuss their advantages and disadvantages.
4.1 Regression Loss
(1) Metric-loss inconsistency Metric-loss inconsistency generally imply that the optimal choice for the regression task may not guarantee high localization accuracy in terms of the IoU. To bridge this gap, the existing generic object detectors generally introduce IoU- induced loss functions, such as the GIoU (Rezatofighi et al. 2019) and DIoU (Zheng et al.
2020). However, these IoU-induced losses cannot be incorporated directly into oriented object detection because of the nondifferentiable nature of the RIoU (Yang et al. 2021). Thus, several differentiable functions have been designed to approximate the RIoU loss (Yang et al. 2019, 2021, 2022). The PIoU (Chen et al. 2020) introduces a differentiable kernel function that accumulates the contributions of interior overlapping pixels to approximate their intersection area. Several solutions (Yang et al. 2019, 2022, 2021) integrate the RIoU
(1)
Fig. 11 Chronological overview of oriented object detection methods for addressing OBB regression
Page 16 Of 61
Oriented object detection in optical remote sensing images using deep… Lreg denotes the commonly used smooth L1 loss (Ren et al. 2015, 2017). g(·) is a loss func tion related to the RIoU, e.g., −log(·). This loss is composed of a normalized regression
Loss Lreg
|Lreg| for controlling the direction of gradient propagation and a scalar g(RIoU) for adjusting the gradient magnitude. When the RIoU is close to 1, g(RIoU) ≈0, and Lreg is approximately equal to 0, effectively mitigating metric-loss inconsistency.
In addition to designing a regression loss for approaching the RIoU, Ming et al. (2024) analyzed the gradient of the RIoU loss and proposed a gradient calibration loss (GCL). The GCL constructs a corrected gradient w.r.t. the RIoU, angular error, and scale and then calculates the optimized regression loss through integration. Despite these efforts, angle regression still faces challenges, particularly the PoA problem.
(2) Angular boundary discontinuities Owing to the PoA problem, the regression loss sharply increases when the angle approaches its boundary or the aspect ratio approaches 1, which seriously confuses the utilized network and causes training instability. Thus, several methods have been proposed to address these issues, and they can be divided into three types.
Modulated rotated loss (Qian et al. 2021, 2022). The modulated rotated loss adds an extra loss item based on the naïve regression loss to eliminate angular boundary discontinui ties. Specifically, it first transforms the original predicted OBB bp = (xp, yp, wp, hp, θp) to
P = (Xp, Yp, Hp, Wp, Θp −Π
2 ),1 and then it takes the minimum of their regres
P, Bg)}
, where bg denotes the corresponding GT. This scheme can adaptively choose the appropriate representation for the predicted OBB that results in the smallest loss value, thereby mitigating the sudden loss increases near angu lar boundaries. However, this approach does not fully resolve the metric-loss inconsistency.
Angle coder (Yang and Yan 2020; Yang et al. 2021; Yu and Da 2023, 2024). The circular smooth label (CSL) approach discretizes angles into intervals and predicts a discrete angle via classification (Yang and Yan 2020). In addition, to increase its tolerance to error con cerning the adjacent angles and to handle the PoA problem, CSL uses a window function for angle label smoothing. Although CSL eliminates boundary discontinuities, its heavy predic tion layer harms its efficiency. To address these issues, Yang et al. (2021) further adopted densely coded labels (DCLs) to reduce the code length. Furthermore, Wang et al. (2022) analyzed the limitations of CSL when continuous focal loss functions (Lin et al. 2017, 2020) were directly applied to the soft labels of an angle classification task. Specifically, when the label y̸ = 1, the extreme point of the derivative of the focal loss function FL(x) is not at x = y, yielding an inaccurate angle prediction. Thus, Gaussian focal-CSL (GF-CSL) was designed to obtain more accurate angle predictions with higher responses at the peaks by implementing adaptive Gaussian attenuation on the negative angle categories. However, the hyperparameters of these methods have significant effects on their performance. Even worse, the optimal settings for different datasets also differ, thereby requiring laborious tun ing processes.
To solve this problem, Yu and Da (2023, 2024) designed a differentiable angle coder named the phase-shifting encoder (PSC). The PSC encodes the angle into a periodic phase to solve the boundary discontinuity problem. Moreover, an advanced version, PSCD, maps angles to phases with different frequencies to further solve the square-like problem.
1 Notably, the modulated rotated loss is customized for representing OBBs under the OpenCV definition, which is an intractable problem to the exchangeability of edges and the PoA.
350
K. Wang et al. Gaussian distribution-based methods (Yang et al. 2021, 2022, 2021, 2022). Gaussian distribution-based methods provide unified and elegant solutions to the boundary discon tinuities and the square-like problem. First, the OBB representation b = (x, y, w, h, θ) is converted to a 2-D Gaussian distribution representation N(m, Σ), where m = (x, y) and Σ
(2)
A distance function is subsequently used to measure two Gaussian distributions, such as the Gaussian Wasserstein distance (GWD) (Yang et al. 2021) or the Kullback–Leibler diver gence (KLD) (Yang et al. 2021). Furthermore, the measure is converted into an approxi mate IoU loss by using a nonlinear transformation to achieve metric-loss consistency. The merit of the Gaussian distribution is that the angle is encoded by a trigonometric function and is thereby not constrained by the PoA problem. Moreover, the OBB parameters are jointly optimized in a dynamic manner so that they can influence each other during training.
Despite their advantages, both the GWD and KLD maintain only value-level rather than trend-level metric-loss consistency. To achieve better trend-level alignment, the KFIoU loss was proposed; this approach is differentiable and does not require additional hyperparam eters. The KFIoU can calculate the overlapping area between two Gaussian distributions, resulting in improved performance relative to that of the GWD and KLD.
4.2 Obb Representations
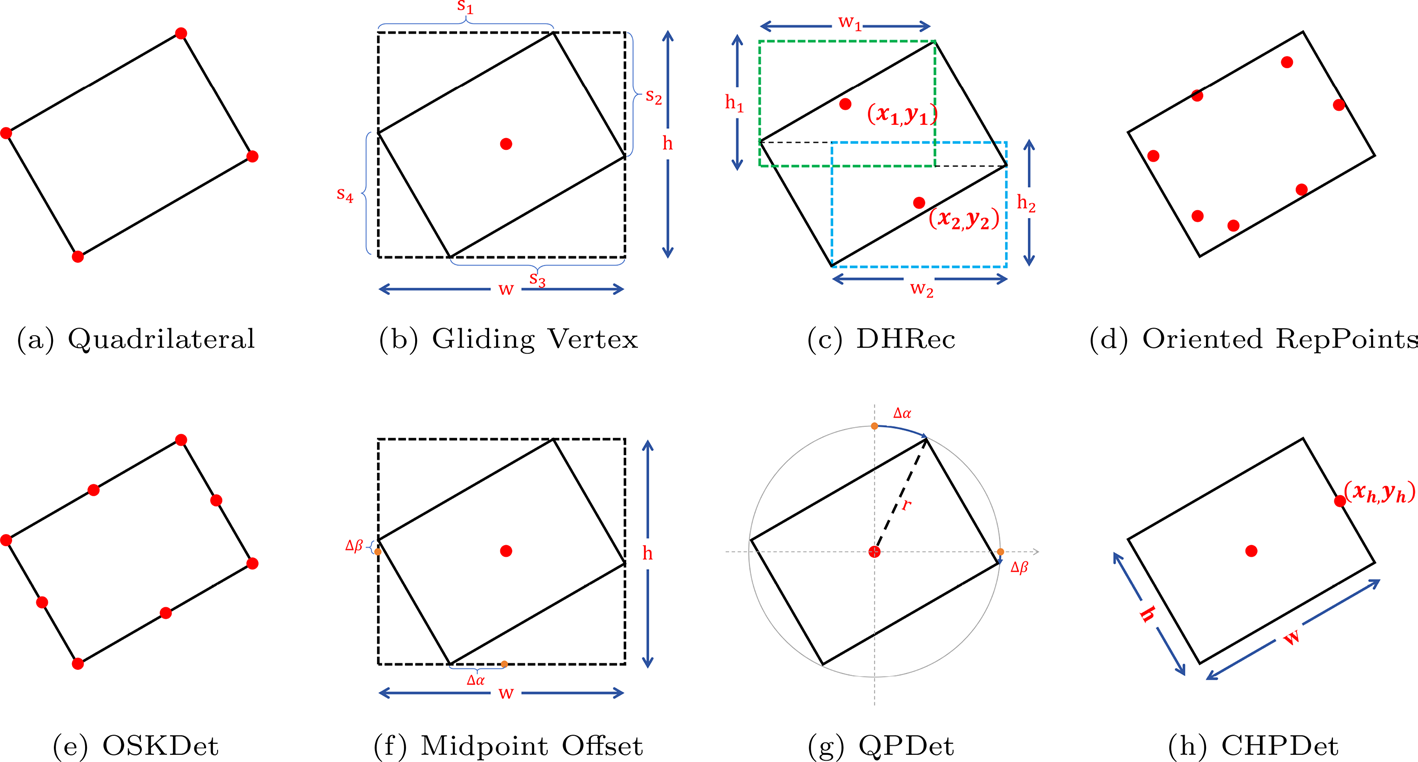
The most straightforward approach for handling angular boundary discontinuities is to design a novel OBB representation. One common scheme exploits new parameters to rede fine the OBB, e.g., quadrilateral representation (Xu et al. 2021) and DHRec (Nie and Huang 2023). The quadrilateral representation adopts the coordinates of four vertices to represent an OBB but suffers from inconsistency when conducting vertex sorting2 between the predic tions and the GT, as shown in Fig. 12a. RSDet (Qian et al. 2021, 2022) mitigates this prob lem by introducing a modulated loss that considers different vertex orderings, minimizing the regression loss across these variations. Furthermore, Xu et al. (2021) proposed an effec tive way to glide the vertex of a horizontal anchor on each corresponding side, as shown in Fig. 12b. Specifically, it regresses four length ratios representing the gliding offset on each corresponding side, eliminating the confusion caused by vertex sorting. To remedy the confusion encountered in cases with nearly horizontal objects, it directly selects horizontal detection guided by the predicted obliquity factor, albeit with slightly imprecise regression results. DHRec (Nie and Huang 2023) encodes the OBB using double HBBs derived from the sorted horizontal and vertical coordinates, as shown in Fig. 12c. Hence, such a method allows any horizontal object detector to be harnessed to predict OBBs.
In addition, several anchor-free methods utilize keypoints to denote an OBB, which can provide rich semantic features for oriented objects. Following RepPoints (Yang et al. 2019), CFA (Guo et al. 2021, 2022) and Oriented RepPoints (Li et al. 2022) utilize deformable con volution (Dai et al. 2017) to generate a group of reppoints, as shown in Fig. 12d. A minimum bounding rectangle is then computed for each set of predicted reppoints to yield detection 2 For more details, please refer to Sect. B of the Appendix.
Page 18 Of 61
Oriented object detection in optical remote sensing images using deep… results. OSKDet (Lu et al. 2022) encodes 8 ordered points (4 vertices and 4 midpoints) to represent an OBB because the object has more obvious features in its vertex and edge areas, as shown in Fig. 12e. Furthermore, an orientation-sensitive heatmap was designed to better fit object shapes, allowing the utilized model to implicitly learn orientations and shapes.
Although angular discontinuities have been eliminated, the redesigned OBB representa tion still have limitations. The quadrilateral representation is irregular, and DHRec adds extra position and oblique factors to ensure the uniqueness of the produced OBB represen tation. Moreover, the keypoints rely on a complicated post-processing operator to generate a rectangular box.
Therefore, another approach for OBB representation only uses some extra parameters to determine the orientations of objects. The classic midpoint offset representation (Xie et al. 2021) infers orientations via midpoint offsets, as shown in Fig. 12f, but it typically produces parallelograms that require regularization. On the basis of the midpoint offset representa tion, Qiao et al. (2023) analyzed the geometric relationship between an OBB and its external HBB to derive the height directly from the width and two offsets, using only five parameters to generate a high-quality OBB directly from the horizontal anchors. QPDet (Yao et al.
2023) adopts two symmetrical offsets w.r.t. the quadrant points to account for the rotation and aspect ratio, and a single parameter (radius r) controls the scale, as shown in Fig. 12g. CHPDet (Zhang et al. 2022) defines a head point to indicate the correct orientation but requires proper annotations that specify the direction of the object head within the range of 2π, as shown in Fig. 12h. These orientation representation can discard angle regression, thus naturally eliminating angular boundary discontinuities. Additionally, the advantages and disadvantages of the above OBB representation methods are summarized in Table 2.
Fig. 12 Comparison of different OBB representation methods. The red dots and parameters denote cor
350
K. Wang et al.
4.3 Discussion
As stated above, an enormous amount of research effort is committed to resolving the chal lenges encountered by OBB regression. Redesigning a novel regression loss for mainstream θ-based representations empowers the detector to solve the metric-loss inconsistency prob lem and eliminate the confusion caused by the PoA, thereby enhancing the stability of the network backpropagation process. In particular, Gaussian distribution-based methods draw upon a trigonometric encoder and joint optimization to achieve strong performance. On the other hand, novel OBB representation approaches can avoid performing orientation regres sion, in which completely redefined OBB representations commonly rely on complex post- processing operations or extra constraints, whereas the orientation representations provide a simple yet efficient way to determine the orientation. Nevertheless, only a handful of novel OBB representation approaches consider the inconsistency problem.
Table 2 Comparison among different OBB representation methods
Quadrilateral Repre
sentation (Xia et al. 2018; Qian et al.
Huang 2023)
It can directly use horizontal object detectors to
Reppoints Into An Obb
OSKDet (Lu et al.
Ing Procedure For Regularization
QPDet (Yao et al.
Depends On The Precision Of The
center point and the head point.
Page 20 Of 61
Oriented object detection in optical remote sensing images using deep…
5 Feature Representation Approaches
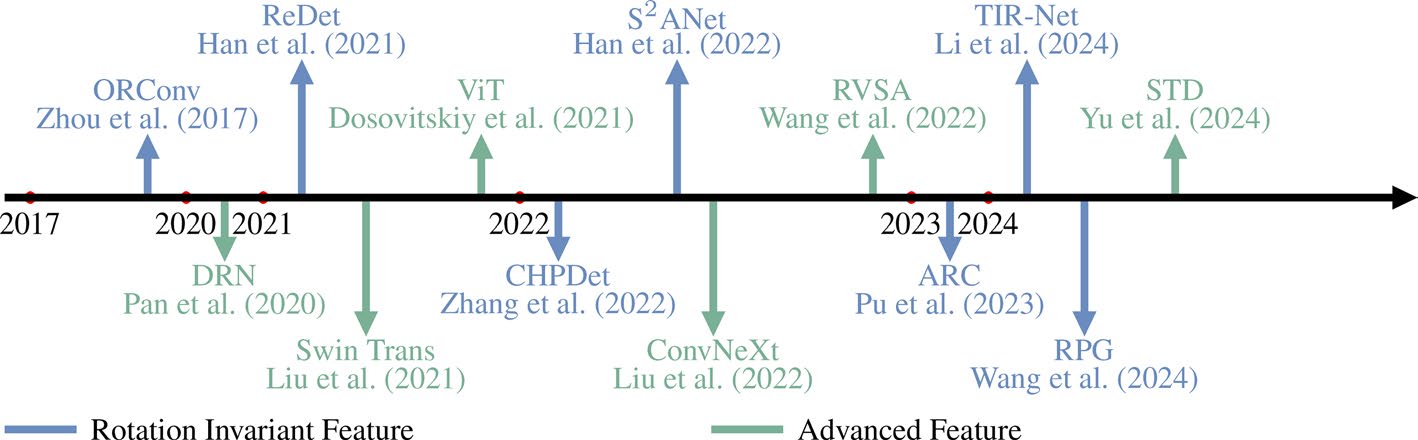
Robust and discriminative feature representations play pivotal roles in improving both localization and classification tasks. As a result, the most recent improvements in detec tion accuracy have been attained via research conducted on enhancing feature representa tions through innovative network architectures. In this section, we review the effort devoted to improving the feature representations of oriented objects, i.e., rotation-invariant feature representations and advanced feature representations. Several key methods are shown in Fig. 13.
5.1 Rotation-Invariant Feature Representations
Rotation invariance is an essential problem when learning visual feature representations for oriented objects (Lowe 2004; Han et al. 2021; Yu et al. 2024). The commonly used approaches, including RRoI operators (Ma et al. 2018; Yang et al. 2018; Ding et al. 2019) and random rotation data augmentation (Han et al. 2021), are suboptimal, as they can extract only approximately rotation-invariant features (Lenc and Vedaldi 2015; Worrall et al. 2017).
Recently, the exploration of rotation-sensitive feature extraction networks has provided new insights for the community; these methods utilize different channels to represent feature information derived from different orientations, e.g., oriented response convolu tion (ORConv) (Zhou et al. 2017) and group-equivariant convolutional neural networks (G-CNNs) (Cohen and Welling 2016; Worrall et al. 2017; Marcos et al. 2017; Weiler and Cesa 2019; Weiler et al. 2018). Several methods, e.g., RRD (Liao et al. 2018), CHP Det (Zhang et al. 2022), and S2ANet (Han et al. 2022), replace ordinary convolution mod ules with ORConv to obtain orientation-dependent responses, which are then transformed into rotation-invariant features using ORAlign and ORPooling. Additionally, ReDet (Han et al. 2021) incorporates G-CNN into RoI Transformer (Ding et al. 2019) to generate rota tion-equivariant features; then, a rotation-invariant RoI alignment operator is designed to adaptively extract rotation-invariant features from the equivariant features according to the predicted orientations. Furthermore, Li et al. (2024) introduced selective rotation of the kernel (SRK) to enhance classification features. The SRK module rotates the convolution kernel at different angles to extract rotation-invariant features, where the output channel dimensionality of the corresponding rotated convolution kernel is adaptively obtained by network learning.
Fig. 13 Chronological overview of feature representation approaches
350
K. Wang et al. In contrast with ORConv and G-CNNs, which extract features via static kernels with a group of fixed orientations, ARC (Pu et al. 2023) dynamically rotates its convolution ker nels according to the orientations of the objects, where these orientations are predicted in a data-dependent manner. As a result, ARC can capture the rotation information of objects with different orientations and boost the feature representations produced in oriented object detection scenarios.
However, Wang et al. (2024) noted that the cyclic shift phenomena exhibited by the fea tures acquired from a rotation-equivariant network are unstable due to dilation and pooling operations. To maintain rotation invariance for features, a rotation-robust prototype genera tion (RPG) scheme was designed with a stabilization module and an enhancement module.
The former aggregates features with different orientations to generate a rotation-robust pro totype, whereas the latter employs this prototype to enhance the original features in each group.
5.2 Advanced Feature Representations
In addition to rotation-invariant networks, advanced feature extraction networks, particu larly vision transformers (ViTs) (Vaswani et al. 2017; Dosovitskiy et al. 2021; Liu et al. 2021), have played a crucial role in achieving high-precision detection. ConvNeXt (Liu et al. 2022) is another notable architecture that has also contributed to the field, although the corresponding discussion will be brief in this context.
Recently, ViTs have achieved significant success in computer vision (Dosovitskiy et al. 2021; Liu et al. 2021; Han et al. 2023), primarily because their self-attention mechanisms capture global feature representations. This exceptional feature representation capacity has led to the increasing adoption of ViTs in object detection tasks, yielding remarkable results.
Representative architectures such as the ViT series (Dosovitskiy et al. 2021; Xu et al. 2021; Zhang et al. 2023) and the Swin transformer (Liu et al. 2021) can serve directly as back bone networks, exhibiting better feature representation capabilities than CNNs do. Further more, the unsupervised MAE-based (He et al. 2022) pretraining scheme has made notable progress in terms of developing ViTs for object detection. Consequently, these powerful ViT architectures contribute to establishing a solid foundation for delivering outstanding achievements in oriented object detection tasks.
Nevertheless, their utilization in oriented object detection field is fairly unexplored; e.g., an essential problem is how to extract rotation-related features. Wang et al. (2022) addressed this concern by designing a rotated variable-size window attention (RVSA) mechanism based on a ViT, which adaptively generates locally oriented windows with different sizes, locations, and angles. Although RVSA outperforms all the previously proposed methods, it relies on a self-attention mechanism to create oriented windows without explicitly leverag ing guidance information.
On the other hand, STD (Yu et al. 2024) adopts a controlled scheme for manipulating the feature extraction process according to the decoupled OBB parameters, i.e., the center posi tion, sizes, and angles. It follows a divide-and-conquer approach that estimates the position, size, and angle parameters via separate network branches in different stages. Furthermore, the cascaded activation masks created by the decoupled OBB parameters are integrated to gradually enhance the features extracted by stacked transformer blocks. The progressive refinement of feature representations enables STD to reach state-of-the-art performance,
Page 22 Of 61
Oriented object detection in optical remote sensing images using deep… achieving mean average precision (mAP) values of 82.24% and 98.55% on the DOTA- V1.0 (Xia et al. 2018) and HRSC2016 (Liu et al. 2016) datasets, respectively.
More recently, ConvNeXt (Liu et al. 2022) gradually modified the standard ResNet model according to a series of design decisions made by the Swin transformer (Liu et al. 2021) and demonstrated that pure CNNs outperform ViTs in terms of accuracy and robust ness. Moreover, ConvNeXt can maintain the efficiency of standard CNNs, thus becoming the dominant architecture in many applications.
5.3 Discussion
The investigation of feature representations can lead to improvements in the whole object detection field. ORConv and G-CNNs empower the corresponding models to mine rota tion-invariant features by using different channels to represent feature information derived from different orientations, whereas advanced feature extraction networks are dedicated to enhancing semantic representations via powerful and well-designed architectures. Although the former is conducive to extracting rotation-invariant features in both the spatial and chan nel dimensions, they are built on conventional CNN modules that lag behind the latter. Thus, it is crucial to validate the effectiveness of integrating rotation-invariant feature extraction networks and advanced networks. We hope that further research efforts will explore more powerful rotation-invariant and high-level semantic feature representations for performing oriented object detection.
6 Solutions To Common Issues
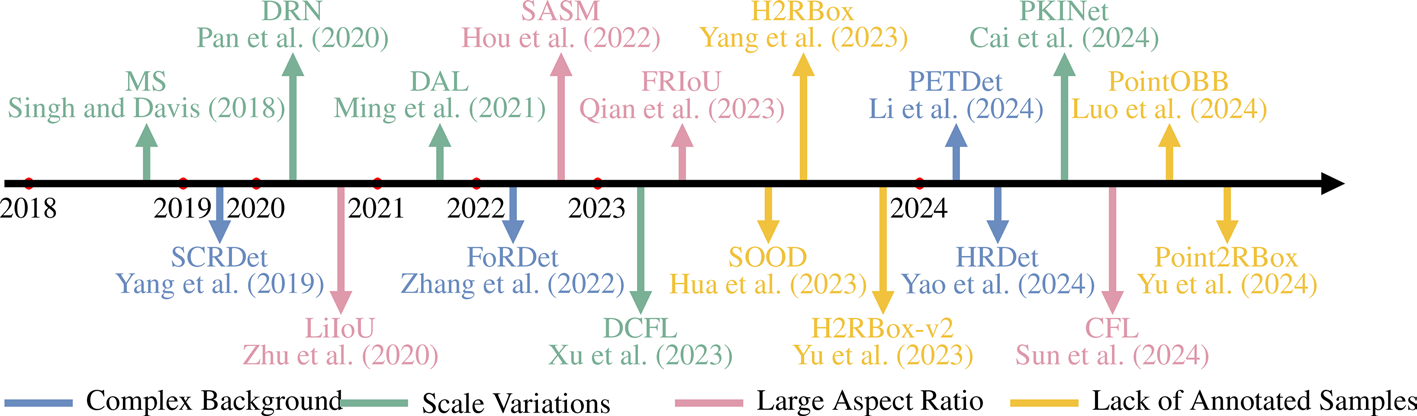
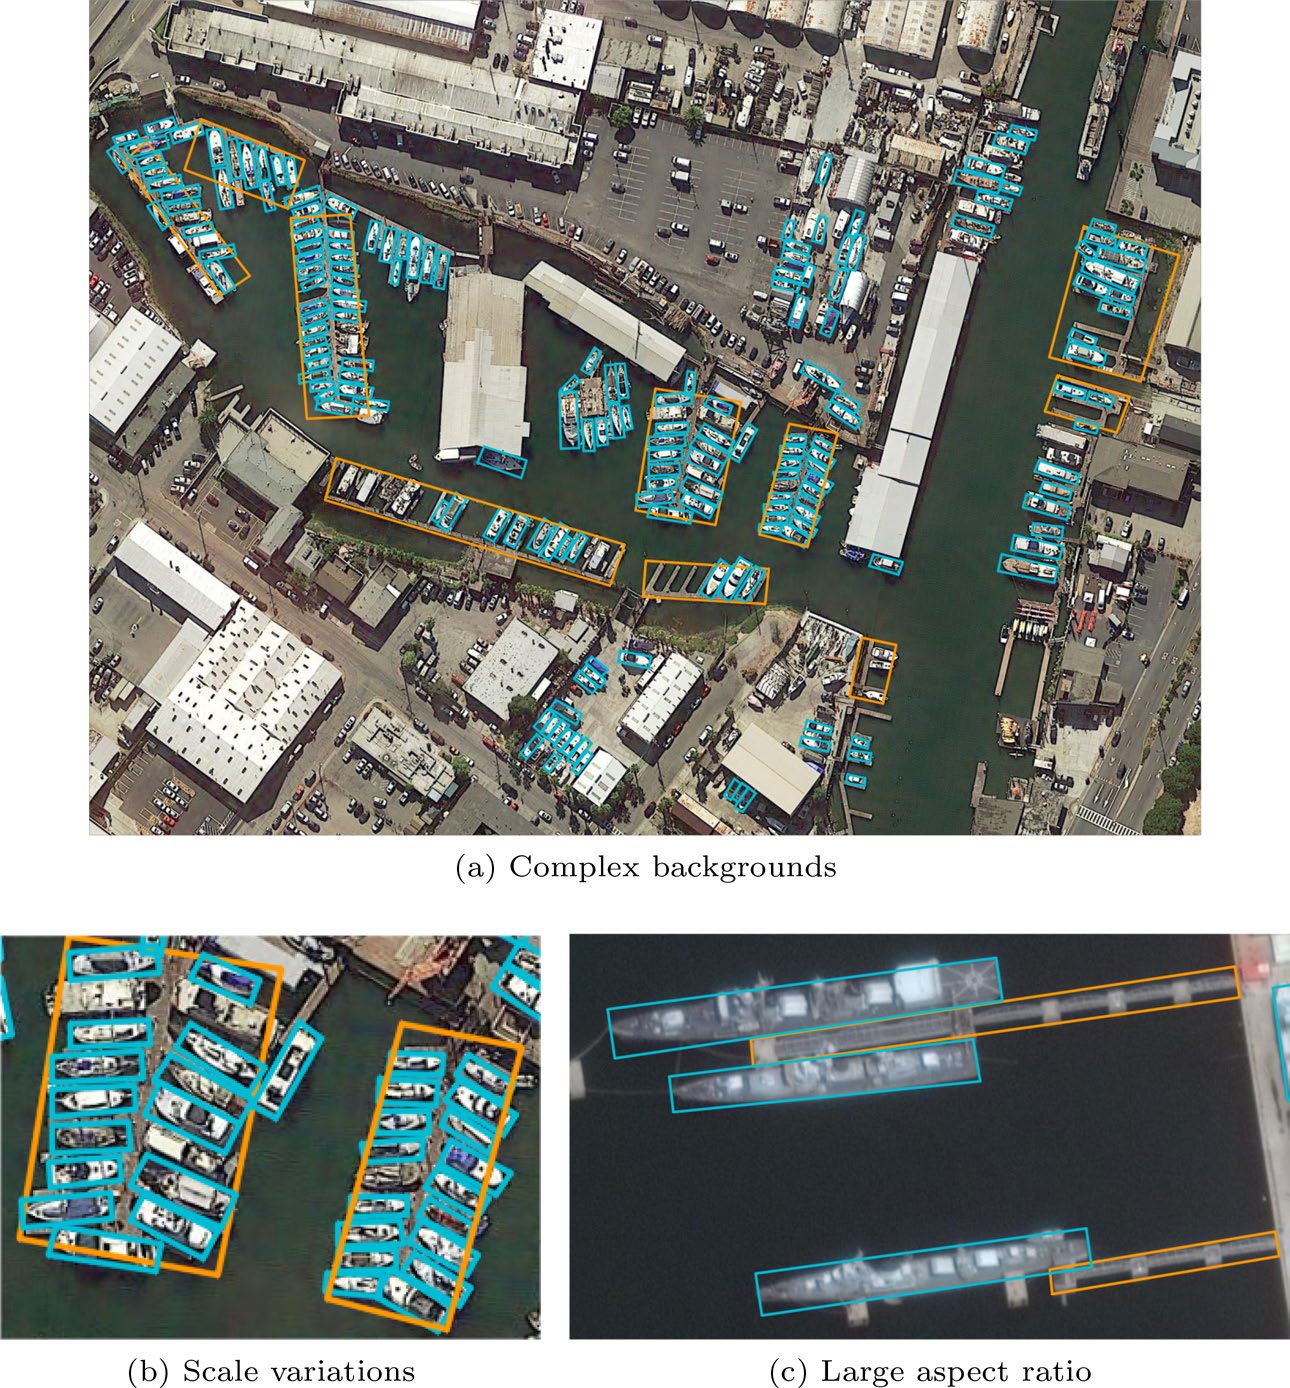
In addition to the specific challenges associated with oriented object detection, several com mon issues still exist w.r.t. RS scenarios, e.g., complex backgrounds, scale variations, large aspect ratios, and the lack of annotated samples, as shown in Fig. 14. Several representative methods for tracking these common issues are shown in Fig. 15.
6.1 Complex Backgrounds
Owing to their wide visual fields and complex earth surfaces, RS images typically contain a variety of complex backgrounds, causing significant interference in detection tasks. Objects are frequently surrounded by different backgrounds, necessitating detectors with height ened discriminative capabilities. In addition, the presence of backgrounds with textures and shapes resembling the objects leads to a high false-positive rate.
To this end, a series of efforts have been made to suppress background noise and empha size the valuable areas of objects. CFC-Net (Ming et al. 2022) and PETDet (Li et al. 2024) both combine channel and spatial attention modules to learn the semantic correlation between the foreground and background of the image. However, these methods rely on self-attention mechanisms and lack direct foreground guidance. To enhance the ability to discriminate the foreground, Zhang et al. (2022) proposed a foreground relation module for obtaining foreground contextual representations under the supervision of the designed foreground map. Similarly, CBDA-Net (Liu et al. 2022) builds two parallel spatial atten tion streams to capture center and boundary attention features, which can assist detectors in
350
K. Wang et al. Fig. 15 Chronological overview of oriented object detection methods for addressing common issues Fig. 14 Illustration of common issues in RS scenarios (Xia et al. 2018; Ding et al. 2022). a–c Examples of complex backgrounds, scale variations, and large aspect ratio, respectively
Page 24 Of 61
Oriented object detection in optical remote sensing images using deep… improving their object localization accuracy. In addition, SCRDet (Yang et al. 2019) adopts a pixel attention network to generate a saliency map that can separate the foreground from the background and uses squeeze-and-excitation (SE) blocks (Hu et al. 2020) as its channel attention network to further enhance the saliency map.
Building on SCRDet, SCRDet++ (Yang et al. 2022) introduces an instance-level denois ing (InLD) module that weakens the feature response of the background region while decoupling the features of different categories into their corresponding channels. Similar to InLD, several methods (Zhang et al. 2023; Yu et al. 2023; Yao et al. 2024; Zheng et al. 2024) introduce semantic mask modules that are supervised by classwise masks transformed from the oriented GT. These semantic mask modules separate the features of different categories in the channel dimension, which can help the networks reduce both background interference and interclass interference.
6.2 Scale Variations
As the ground sampling distance (GSD) can range from a few centimeters to hundreds of meters, the RS images taken by different sensors usually have large-scale variations. Addi tionally, even within the same category, object instances exhibit wide-ranging sizes. These interclass and intraclass scale variations pose additional challenges. In particular, the most critical challenge concerns small objects because of their insufficient feature information, inaccurate localization effects, and inadequate positive samples (Cheng et al. 2023). Worse still, the task concerning oriented objects becomes more difficult because of the extra orien tation regression process and limited overlaps with anchor boxes.
In recent years, many effective strategies have been developed to increase the robustness and adaptability of detectors to objects with various scales; these approaches can be clas sified into two categories: network-level methods and data-level methods. Network-level methods develop novel network structures for multiscale feature extraction, e.g., feature pyramid architectures (Lin et al. 2017) and their variants (Tian et al. 2024), as well as multibranch architectures (Li et al. 2019; Pan et al. 2020; Cai et al. 2024). Pan et al. (2020) designed a feature selection module to adjust receptive fields; they proposed a channel attention network to adaptively fuse the features extracted by using kernels with various sizes, aspect ratios, and orientations. PKINet (Cai et al. 2024) employs parallel multiscale convolution kernels without dilation to effectively capture features across various receptive fields. On the other hand, data-level methods strive to design data augmentation strategies that are independent of the applied network architectures and can be generalized to any detector. Multiscale training and testing is a useful data augmentation approach that scales input images at different resolutions (Singh and Davis 2018; Singh et al. 2018) and has been shown to reduce overfitting and improve generalizability (Ren et al. 2015, 2017; Rus sakovsky et al. 2015). However, this approach inevitably leads to poor temporal efficiency.
In addition to enhancing semantic representations or amplifying object sizes, several optimal assignment strategies have emerged to enable adequate sample assignments for small oriented objects. Anchor-free methods can generate more positive samples of small objects that are apt to be ignored in anchor-based methods. Consequently, approaches such as APE (Zhu et al. 2020) and AOPG (Cheng et al. 2022) generate samples in an anchor- free manner, refining them for obtaining high-quality detection results. Liang et al. (2022) proposed a dynamic enhancement-based anchor network that combines the advantages of
350
K. Wang et al. anchor-free and anchor-based methods and uses an interactive sample screening procedure to yield higher-quality training samples.
Rather than relying on the IoU alone, several methods (Ming et al. 2021; Zhang et al. 2023; Fu et al. 2024; Huang et al. 2024) use the prior (e.g., the IoU between the anchor and GT) and posterior information (e.g., classification and localization confidences) as the evaluation criteria for screening positive samples. This scheme can push detectors to dynamically mine high-quality anchors as positive samples. In contrast to static priors (e.g., anchor boxes or points) with fixed strides, Xu et al. (2023) designed a dynamic prior with a coarse-to-fine assigner. Specifically, it first uses deformable convolution (Dai et al. 2017) to adaptively adjust the prior location and then leverages coarse prior matching and a finer posterior constraint to dynamically assign samples. This strategy can adaptively assign posi tive or negative samples according to the shape and posterior information of the objects, increasing the performance achieved by mainstream detectors for small objects.
6.3 Large Aspect Ratios
RS images frequently encompass several categories with extremely large aspect ratios, such as bridges, ships, and harbors. The RIoUs between these categories with anchors are highly sensitive to orientation errors, thereby causing two primary challenges, i.e., spatial mis alignment and inaccurate localization.
Accordingly, a series of well-designed assignment strategies and regression losses have been proposed to remedy the corresponding issues. Zhu et al. (2020) introduced a length- independent IoU (LiIoU). The LiIoU intercepts part of the object box along its long side based on the length of the anchor and subsequently calculates the IoU between the inter cepted object box and the anchor. Compared with the conventional IoU, the LiIoU facili tates the assignment of more positive samples to long objects, thereby increasing the recall rate. Qian et al. (2023) emphasized that the sampling locations of positive samples should be close to the center distribution of the oriented GT. This is because two horizontal anchors, despite having the same IoU as that of the external HBB of an oriented GT with a large aspect ratio, can differ considerably in their coverage of the GT. Consequently, Qian et al.
(2023) and Wang et al. (2024) both combined the horizontal IoU and sample feature align ment overlap degree to evaluate the quality of an anchor, where the sample feature align ment overlap degree is defined as the ratio of the intersection between the horizontal anchor and the oriented GT to the GT itself, reflecting the overlap proportions of oriented object features.
Furthermore, inspired by ATSS (Zhang et al. 2020), SASM (Hou et al. 2022) and CFL (Sun et al. 2024) use a monotonically decreasing function of the aspect ratio as a weight for an IoU threshold that controls the sample assignment process. This approach allows long objects to be assigned lower IoU thresholds. Additionally, several methods (Liu et al. 2022; Qiao et al. 2023; Gong et al. 2024; Xie et al. 2024) construct weighted orienta tion losses that depend on the aspect ratio, effectively mitigating the effect of the aspect ratio on orientation regression.
6.4 Lack Of Orientation-Annotated Samples
Owing to its reliance on numerous and laborious annotations, oriented object detection has experienced significant advancements in recent years. However, OBB annotation is a time- consuming and expensive process, resulting in many detection datasets that use HBB anno tations but do not provide OBB annotations, thereby restricting their potential application scopes. To alleviate the annotation burden, researchers have explored two avenues: weakly supervised learning, in which OBB annotations are replaced by HBB-level or even point- level annotations; and semisupervised learning, in which only a few images from the whole training dataset are annotated.
The mainstream semisupervised oriented object detection methods commonly follow the pseudo-labeling framework, which consists of a teacher model and a student model. The teacher model, which is an exponential moving average (EMA) (Tarvainen and Valpola 2017) of the student model at different historical training iterations, generates pseudo-labels for unannotated images. The paired models are iteratively trained via the following steps.
The teacher model provides pseudo-labels for the unannotated images in a batch, whereas the student model makes predictions for both the annotated and unannotated images. Then, the loss for the predictions of the student model is computed. However, the unsupervised nature of the teacher model introduces noise that can mislead the training process of the student model, especially considering the arbitrary orientations of objects, which further impact the resulting pseudo-label quality. Therefore, the current semisupervised oriented object detection methods (Hua et al. 2023; Wang et al. 2024; Wu et al. 2024) are committed to generating high-quality pseudo-labels.
SOOD (Hua et al. 2023) introduces two loss functions, i.e., a rotation-aware adaptive weighting (RAW) loss and a global consistency (GC) loss. The RAW loss focuses on the orientation consistency between each pseudo-label-prediction pair, dynamically weight ing each pair based on their orientation gap. The GC loss measures the global similarity between the pseudo-labels and the predictions, effectively mitigates noise disturbances and implicitly regularizes the object relations. Wang et al. (2024) provided an in-depth analy sis of the limitations of conventional pseudo-label- and dense pseudo-label-based meth ods (Zhou et al. 2022). The former approaches adopt a fixed threshold, whereas the latter methods use a fixed quantity, both of which fail to adaptively select high-quality pseudo- labels. To address this issue, global focal learning was proposed to judge important regions on the basis of the difference between the predictions of the teacher model and the student model, guiding networks to focus more on inconsistent regions during training. In addition, the Pseudo-Siamese Teacher (Wu et al. 2024) adopts two teacher models that are updated by different optimization schemes to improve the reliability of pseudo-labels and uses the Jensen-Shannon divergence measure to eliminate inconsistent pseudo-labels.
The mainstream weakly supervised oriented object detection methods commonly con sist of multiple branches that are fed with multiple augmented views of the input image. Various consistent losses are then designed to align the features or predictions derived from different views. H2RBox (Yang et al. 2023), which was the first HBB annotation-based weakly supervised method, follows a weakly and self-supervised angle learning paradigm.
The weakly supervised part calculates the regression loss between the external HBB of the predicted OBB and the horizontal GT, whereas the self-supervised part measures the con sistency of the angles predicted from two views with different rotation augmentations. On
350
K. Wang et al. the basis of H2RBox, H2RBox-v2 (Yu et al. 2023) leverages reflection symmetry to learn the orientations of objects in a self-supervised manner. Furthermore, a CircumIoU loss is designed, allowing H2RBox-v2 to be compatible with the random rotation augmentation method.
Compared with OBB and HBB annotations, point annotations have lower costs and greater efficiency.3 The main challenge faced by the point annotation-based methods lies in enabling the models to perceive the orientations and scales of objects on the basis of point annotations. PointOBB (Luo et al. 2024) was designed with a resized view (by random scaling) and a rot/flp view (implemented by random rotation or vertical flipping) based on original view. Upon these three views, a scale augmentation module and an angle acquisi tion module were constructed. The former aims to perceive object scales by improving the consistency between the predicted scores of the original and resized views, whereas the latter incorporates self-supervised angle learning to predict angles.
Furthermore, Yu et al. (2024) presented Point2RBox, including synthetic pattern knowl edge combination and self-supervised transformation schemes. The former first generates synthetic patterns with known boxes by sampling around each labeled point and then over lays these patterns on the original image, providing knowledge that enables the network to estimate sizes and angles. The latter is similar to PointOBB, which uses original and transformed (randomly selected from rotated, flipped, and scaled) views to perceive the size and orientation differences between objects. In addition, Zhang et al. (2024) proposed a progressive method, named point-to-mask-to-HBB-to-OBB (PMHO), to achieve oriented object detection. However, this framework is time-consuming, with each component being optimized independently; thus, it relies heavily on the capabilities of well-trained models such as the SAM (Kirillov et al. 2023).
6.5 Discussion
Complex backgrounds, scale variations, large aspect ratios, and the lack of oriented-anno tated samples are crucial issues encountered in RS object detection tasks, and they become more severe in oriented object detection tasks. As stated above, numerous methods have been proposed to address these issues from various perspectives, e.g., data augmentation schemes, assignment strategies, reweighted orientation losses, attention mechanisms, self- supervised losses, and pseudo-labeling frameworks. Unfortunately, the exploration of solu tions for these issues is far from mature, so further research may be beneficial. For example, a significant performance gap remains w.r.t. detecting small or long objects compared to normal objects, even for the state-of-the-art detectors. On the other hand, the general split- and-detect scheme is inefficient during inference because too many empty patches that contain only background information are used. Several prior works have preliminarily con sidered these points, e.g., superresolution-based object detection (Shermeyer and Van Etten 2019; Liu et al. 2023; Zhang et al. 2023) and focus-and-detect schemes (Duan et al. 2021; Koyun et al. 2022). Additionally, the accuracy of semi-/weakly supervised oriented object detection is still far from satisfactory, lagging significantly behind that of fully supervised 3 According to https://cloud.google.com/ai-platform/data-labeling/pricing, the cost of point annotations is approximately 50.0% lower than that of HBB annotations and 104.8% lower than that of OBB annotations, and their time consumption is only 1.2x greater than that of image-level annotations.
Page 28 Of 61
Oriented object detection in optical remote sensing images using deep… methods. The combination of weakly supervised and semisupervised methods may lead to new breakthroughs (Wu et al. 2024).
7.1 Evaluation Protocols
Accuracy and efficiency are both crucial criteria for evaluating the performance of oriented object detectors. The evaluation protocol for OBBs is slightly different from that used for HBBs, as the IoU is replaced with the RIoU. Efficiency evaluations use the frames-per-sec ond (FPS) metric, which is defined as the number of image frames processed by a detector per second, whereas accuracy evaluations account for both precision and recall. The most universally agreed-upon metric for accuracy evaluations is AP.
For the object detection task, the detector outputs M predicted results {(bj, cj, sj)}M
J=1,
where each item contains an OBB bj and a category label cj with a corresponding confi dence score sj. Then, the predicted results are assigned to the GT objects {(b∗
K And The Superscript ∗ Denote The Obb, Cat
egory label, and GT, respectively. A predicted result (bj, cj, sj), which is assigned a GT
K, C∗
k), is judged to be a true positive (TP) if the following criteria are met. (1) The predicted label cj accords with the label c∗ k of the GT object.
(2) The RIoU between the predicted OBB bj and the GT OBB b∗
K, Denoted By The Riou
(b, b∗), is not smaller than the predefined RIoU threshold TRIoU. Otherwise, it is regarded as a false positive (FP). Once the numbers of TPs and FPs have been obtained, the precision and recall metrics can be calculated. Precision is the proportion of correctly predicted instances among the total number of predicted results, whereas recall is the proportion of all positive instances predicted by the detector among the total number of GT objects. Their formulas are defined
(4)
where NT P , NF P , and NF N denote the numbers of TPs, FPs, and false negatives (FNs), respectively, which are determined by the score thresholds Ts and TRIoU. Note that the precision and the recall metrics are functions of the confidence threshold Ts with a fixed TRIoU.
However, neither precision nor recall can independently evaluate the accuracy of a detec tor, whereas AP can combine both precision and recall. For each category, by gradually vary ing Ts from 1.0 to 0.0, the recall increases as NT P increases, and a list of pairs (Prec, Rec) can be obtained. This allows precision to be considered a discrete function of recall, i.e., the precision–recall curve (PRC), which is denoted by P(R). The AP value is obtained by computing the average precision value P(R) over the interval from R = 0.0 to R = 1.0:
350
K. Wang et al.
(5)
Ultimately, to evaluate the overall accuracy across all categories, the mAP averaged over all categories is adopted as the final evaluation metric.
7.2 Datasets
Recently, several research groups have released dozens of high-quality RS image datas ets, each of which dramatically boosts the development of RS object detection methods. Datasets annotated only with HBBs, including DIOR (Li et al. 2020), LEVIR (Zou and Shi 2018), NWPU VHR-10 (Cheng et al. 2014), RSOD (Xiao et al. 2015; Long et al. 2017), xView (Lam et al. 2018), and HRRSD (Zhang et al. 2019), are not covered here. In addi tion, several oriented object detection datasets with horizontal views, e.g., text detection datasets (Karatzas et al. 2015), and datasets derived from different modalities, such as SAR datasets (Wei et al. 2020; Lei et al. 2021), exhibit significant differences in their viewing angles, scenes, and imaging characteristics relative to optical RS datasets. Thus, this paper does not introduce these datasets. In this subsection, we only focus on introducing optical RS datasets annotated with OBBs, including SZTAKI-INRIA (Benedek et al. 2012), 3K vehicle (Liu and Mattyus 2015), UCAS-AOD (Zhu et al. 2015), VEDAI (Razakarivony and Jurie 2016), HRSC2016 (Liu et al. 2016), DOTA (Xia et al. 2018; Ding et al. 2022), ShipRSImageNet (Zhang et al. 2021), DIOR-R (Cheng et al. 2022), DroneVehicle (Sun et al. 2022), FAIR1M (Sun et al. 2022), and GLH-Bridge (Li et al. 2024). Table 3 shows the parameters of the above RS-oriented object detection datasets for making an intuitive comparison. Given that the emergence of DOTA has greatly promoted the development of oriented object detection, we divide the datasets into two parts, namely, early and modern datasets, based on the time at which DOTA was introduced. Only the most typical datas ets among the above datasets are described in detail owing to space restrictions. For more details, please refer to Sect. C of the Appendix.
DOTA (Xia et al. 2018; Ding et al. 2022) contains large quantities of objects with a considerable variety of orientations, scales, and appearances. The images were selected from different sensors and platforms, including Google Earth, the GF-2 satellite, and UAVs.
Three versions of this dataset are available. The numbers of images and instances contained in the three versions of DOTA are summarized in Table 4. DOTA-V1.0 (Xia et al. 2018) and DOTA-V1.5 share the same images, which are split into training, validation, and test subsets. As an extension of DOTA-V1.0, DOTA-V1.5 annotates extremely small instances whose sizes are equal to or less than 10 pixels. Compared with the previous versions, DOTA- V2.0 (Ding et al. 2022) contains more images. In addition, many images were taken under an oblique view and a lower foreground ratio to approach real-world application scenes.
The number of instances has increased to approximately 1.8 million. Moreover, it contains two test subsets, namely, test-dev and test-challenge. The latter comprises a greater number of object instances (approximately 1.1 million) and more complicated scenes, making the associated task more challenging.
DIOR-R (Cheng et al. 2022) is a large-scale dataset that contains 192,518 instances cov ering 20 common categories with notable interclass similarity and intraclass discrepancies.
Authors:
Peder EZ Larson 1, 2,* , Jenna ML Bernard1, James A Bankson 3, Nikolaj Bøgh 4, Robert A Bok1, Albert P. Chen 5, Charles H Cunningham 6,7, Jeremy Gordon1, Jan-Bernd Hövener 8, Christoffer Laustsen 4, Dirk Mayer 9,10, Mary A McLean11 12, Franz Schilling13, James Slater1, Jean-Luc Vanderheyden5, 14, Cornelius von Morze 15, Daniel B Vigneron1, 2, Duan Xu1, 2, and the HP 13C
94143, Usa.
Denmark. 5 GE Healthcare, Menlo Park, California, USA. 6 Physical Sciences, Sunnybrook Research Institute, Toronto, Ontario, Canada.
8 Section Biomedical Imaging, Molecular Imaging North Competence Center (MOIN CC), Medicine, Baltimore, MD, USA. Cambridge, United Kingdom.

14Jlvmi Consulting Llc, Dousman, Wi, Usa
#See Acknowledgements for a list of all HP 13C MRI Consensus Group Members This work was supported by the ISMRM Hyperpolarized Media MR Study Group, the ISMRM Hyperpolarization Methods & Equipment Study Group, and the Hyperpolarized MRI Technology Resource Center (NIH/NIBIB grant P41EB013598).
Abstract
MRI with hyperpolarized (HP) 13C agents, also known as HP 13C MRI, can measure processes such as localized metabolism that is altered in numerous cancers, liver, heart, kidney diseases, and more. It has been translated into human studies during the past 10 years, with recent rapid growth in studies largely based on increasing availability of hyperpolarized agent preparation methods suitable for use in humans. This paper aims to capture the current successful practices for HP MRI human studies with [1-13C]pyruvate - by far the most commonly used agent, which sits at a key metabolic junction in glycolysis. The paper is divided into four major topic areas: (1) HP 13C-pyruvate preparation, (2) MRI system setup and calibrations, (3) data acquisition and image reconstruction, and (4) data analysis and quantification. In each area, we identified the key components for a successful study, summarized both published studies and current practices, and discuss evidence gaps, strengths, and limitations. This paper is the output of the “HP 13C MRI Consensus Group” as well as the ISMRM Hyperpolarized Media MR and Hyperpolarized Methods & Equipment study groups. It further aims to provide a comprehensive reference for future consensus building as the field continues to advance human studies with this metabolic imaging modality.

Keywords: Hyperpolarized MRI, metabolic imaging, carbon-13, pyruvate, dissolution dynamic
Introduction
MRI with hyperpolarized 13C agents, also known as hyperpolarized (HP) 13C MRI, has shown great potential as a novel imaging modality, particularly for its ability to probe metabolic processes in real time. The first human studies with HP [1-13C]pyruvate were performed in 2011 in prostate cancer patients (1).
Since then, there have been over 60 papers published with imaging results of human subjects from 13 different sites, with applications including prostate cancer, brain tumors, breast cancer, kidney cancer, pancreatic cancer, metastatic disease, liver disease, ischemic heart disease, diabetes and cardiomyopathies. The vast majority of these studies used [1-13C]pyruvate (1–63), where [2-13C]pyruvate (64) and 13C-urea (56) have been demonstrated too.

As clinical HP 13C MRI advances, there is a growing need to build consensus for best practices, which are critical for comparing data across sites, performing multi-site trials,deploying methods to new sites, partnering with vendors, and potentially for obtaining broader regulatory approvals.

In March 2022, we initiated an effort to build consensus within the HP 13C MRI community with this opportunity in mind, and it was greeted with strong enthusiasm. The “HP 13C MRI Consensus Group”, containing over 55 members from 27 sites, identified the area of greatest need and opportunity for consensus building to be HP [1-13C]pyruvate human
●
Pyruvate is the most mature and widely used HP agent and has the most significant translational evidence emphasizing the potential clinical impact.
●
Clinical trials, particularly multi-site trials, have the strongest need for consensus methods to ensure that data can be combined across sites. This work is a Position Paper for which the goal is to describe current successful practices and study methods for HP [1-13C]pyruvate human studies along with justification to support those practices. This is divided into four major topic areas: (1) HP 13C-pyruvate preparation, (2) MRI system setup and calibrations, (3) data acquisition and image reconstruction, and (4) data analysis and quantification (Fig. 1). The current successful practices and study methods include a literature review of published peer-reviewed journal papers showing human HP [1-13C]pyruvate study data, up to September 2022 (1–63), as well as new unpublished information from surveys of HP 13C study sites. Based on this information, we also highlight the evidence gaps, strengths, and limitations of current practices which are summarized at the end of each section.

Figure 1: Illustration of the HP 13C MRI human study process, including the 4 major areas covered in this paper: Hyperpolarized 13C-pyruvate preparation, MRI system setup and calibration, Acquisition and Reconstruction, and Data Analysis and Quantification.

Figure 2: Anatomical targets of HP [1-13C]pyruvate MRI human studies published up to September 2022.
Hyperpolarized 13C-Pyruvate Preparation
This section covers the processes for creating the HP agent, 13C pyruvate, and will include many aspects and considerations that are needed to safely and effectively prepare doses for metabolic imaging studies in human subjects. These include material, personnel, equipment and facility, fluid path preparation, quality control, and release.

It is helpful to understand that the specifications of a dose of 13C pyruvate suitable for in vivo MR HP metabolic imaging were shaped in part by early preclinical studies performed by GE HealthCare summarized in Ref. (65). In short, the safety of the two novel drug components, 13C pyruvate and the electron paramagnetic agent (EPA) AH111501, were demonstrated in those studies. The more precise formulation of the dose suitable for human use was then determined from clinical studies (66) that included two Phase 1 clinical trials in young and elderly healthy volunteers without hyperpolarization of the 13C nuclei and another Phase 1/2a dose escalation and imaging feasibility study with HP 13C pyruvate in 31 prostate cancer patients at the With the exception of the first HP 13C imaging clinical trial, which utilized a prototype device in a cleanroom (1), all HP 13C studies performed in humans to date have utilized the SPINlab polarizer (manufactured by GE HealthCare). Consequently all doses of the HP 13C pyruvate delivered by SPINlab have been produced using the “SPINlab Pharmacy Kit” that serves as the container-closure system for the various drug components (13C pyruvic acid and EPA mixture, dissolution medium, and neutralization and dilution medium) during sample polarization, dissolution and quality control (QC) processes. Thus many aspects of the HP sample preparation considerations discussed below are related to the SPINlab instrument and the consumables designed to be used with it (67).
General Considerations
While more than 860 patients or healthy subjects having been injected with HP 13C pyruvate as of January 2022 without reports of any serious adverse events (68), HP 13C pyruvate injection remains an investigational MR contrast agent and can only be administered by those with Investigational New Drug (IND) exemption from the Food and Drug Administration (FDA) in the USA, a Clinical Trial Application (CTA) in Canada, approval from National Research Ethics Committee Services in the UK, or approval from the relevant local regulatory body. Thus, methods and processes involved to produce a dose should have patient safety as the first priority. Since utilizing dissolution dynamic nuclear polarization (dissolution-DNP) for human use is still a relatively new development, there are no existing published regulatory guidelines specifically for this method.
There are two major production styles that determine how various sites approach the agent preparation. In the US, the most common approach is to rely on a sterilizing filter (“Terminal Sterilization”) to ensure sterility of the final product, akin to PET tracer production, where a starting molecule with a radioisotope is processed using various other ingredients to make the final, desired and injectable contrast agent within a necessarily short amount of time (69). For these sites, sterilization of the components and accessories upstream of this filter are not required, although many of them were manufactured and tested following Good Manufacturing Practice (GMP) or Good Laboratory Practice (GLP) requirements. The filling process is usually performed under an ISO 5 laminar flow hood, but a clean room or an isolator is not required.
This approach is typically accompanied by testing the integrity of the sterilizing filter prior to release of the dose for injection. Typically, post release endotoxin and sterility tests are performed using an aliquot reserved from each released dose.
In the UK and EU, the most common approach is to more-closely follow sterile pharmaceutical compounding guidelines (70), where all components and ingredients are required to be sterile or manufactured under GMP guidelines and are assembled and filled within a clean room environment or an isolator system (“Sterile Preparation”). Typically a batch of Pharmacy Kits for HP 13C pyruvate injection are prepared together. The sterility of the final dose is also ensured by batch validation testing, in addition to the sterility of the ingredients and the sterile compounding process. The endotoxin and sterility testing are performed for the process validation but are not performed for each injected dose.
Some institutions fill and assemble the Pharmacy Kit required for a specific study on the same day or the day prior to polarization, dissolution, and patient administration, but others have also demonstrated the feasibility of preparing a batch of kits, keeping them in a -20ºC freezer and using them over a period of a few months.
Beyond the obvious requirements that the process and the facility has to ultimately produce a dose that is safe to inject into a human, regulatory authorities will also focus on the question “Are you in control of your processes?”. To be in control of your process requires an in-depth and broad understanding of all processes involved in pre, post, and during the production process.
Personnel
It is typical and may be required to have licensed personnel involved in the production process depending on local regulations.Typically a pharmacist, radiopharmacist or other similarly qualified person (QP), in charge of the facility where the Pharmacy Kit filling and preparation is taking place, is responsible for the overall process and the release of the injectable dose.
Qualified cleanroom technicians are often involved in the Pharmacy Kit filling under the supervision of the pharmacist or QP. As is required for pharmaceutical compounding or PET tracer production, training requirements and training records for all personnel need to be maintained and available for audit by the FDA or equivalent.
Equipment And Facility
The facility and all equipment need to have standard operating procedures (SOPs) that describe how equipment is used, maintained, and calibrated to comply with relevant legislation. Currently, almost all the filling of the Pharmacy Kit takes place within a compounding laminar flow hood or isolator (typically ISO 5). At some sites, the filling is conducted within a cleanroom, while at others, it is conducted in a dedicated non-cleanroom space, reflecting differences in cleanroom approach and specifications between regulators worldwide (71). Some equipment or facilities, such as the compounding hood or cleanroom, may require external certified laboratories for testing.
Material Handling
Material handling guidelines (69,70) require SOPs detailing a system to track all of the materials involved in the HP production process for a particular patient dose, similar to current good manufacturing practice (cGMP) requirements for material handling for drug compounding. This includes acceptance standards, storage conditions, amount used in the patient dose for each ingredient and materials used in the assembly of the fluid path and Pharmacy Kit. Currently some users choose to open and inspect and sometimes modify the Pharmacy Kits upon arrival, but some users keep them in the sealed packaging until they are required for dose preparation.
Pharmacy Kit Filling And Assembling
As required by an IND or its equivalent, the preparation of the doses of HP 13C agent are detailed in the Chemistry, Manufacturing, and Control (CMC) section of an applicable regulatory submission; an example of this has been made available (72). It describes the processes of filling the Pharmacy Kit with the different components that make up the final drug product, and of assembling the final kit for either storage or immediate use in the polarizer. Special attention should be given to the laser welding process in order to satisfy installation qualification (IQ) and operational qualification (OQ). Typically, the final developed process is validated by process qualification (PQ) runs, during which 3 or more Pharmacy Kits are filled and used and the final HP 13C products are tested for endotoxin and sterility and to confirm that they meet the dose specifications for injections (usually including pyruvate concentration, residual EPA concentration, pH, liquid state polarization level and dose temperature). The data from 3 consecutive PQ runs are submitted as part of the IND submission (or its equivalent), and are often also reviewed by the Institutional Review Board (IRB) where the studies are conducted.
Quality Control And Dose Release
The quality control (QC) and dose release can be separated into two aspects: one is the QC and release of the filled Pharmacy Kit, and second is the QC and release of the HP 13C agent for injection, after polarization and dissolution. For institutions filling a batch of kits and storing them to use over a period of time, typically the batch can be released based on initial validation, environmental monitoring data from the day of kit production, and if filters are used during preparation of any of the components, filter integrity testing. But in some cases one or more kits are used for validation before the batch of kits are released for future use. For institutions that fill only the kits required for specific studies shortly before the experiment, the filled kits often do not go through separate release tests before they are used.
The quality control of the HP 13C pyruvate solution post dissolution is primarily performed to ensure that the agent meets the dose specifications (Table 1) before it is administered to the subject. These specifications target both safety (pH, residual EPA, temperature) and efficacy (pyruvate concentration, polarization, volume). Typically, the pyruvate concentration, residual EPA concentration, pH, dose temperature, dose volume, and liquid state polarization are measured by the QC accessory associated with the SPINlab polarizer. Some users perform a secondary measurement for one of the parameters, such as pH, using a different instrument or pH paper. For sites that do not go through a separate release testing process for batch filled kits, the integrity of the sterilization assurance filter, a part of the Pharmacy Kit, is typically tested as a part of the dose release. It is also common for these users to preserve an aliquot of the final HP 13C pyruvate solution for post-release endotoxin and sterility testing. This testing cannot be completed fast enough to test an individual dose prior to injection, but this is why other processes such as PQ runs and validation testing are done to minimize the chance a subject could be injected with a contaminated dose.
The Final Dose Release And Injection
should be done under the supervision of a licensed professional, based on local regulations.
Some Key Challenges
Many of the challenges associated with HP 13C pyruvate preparation can be attributed to the conditions required for the dissolution-DNP method of high magnetic field (~3-7 T) and very low temperature (~1 K) during polarization, with pressurized and superheated water necessary for the rapid dissolution event. These extreme conditions are quite challenging for the design of the container-closure and fluid path system. In particular, the cryogenic temperature in the polarizer requires special attention to any moisture or ambient (moist) air introduced into that portion of the fluid path, which can form an ice block at ~1 K. This ice can lead to flow restriction during the dissolution event and reduce the strength of the laser welded bond between the cryovial and its cap. This can ultimately produce failures in the dissolution step, including variations in final pyruvate concentration and pH that may fail to meet QC release criteria as well as fluid path ruptures that provide no available dose and result in polarizer down-time.
The polarization of the HP 13C pyruvate sample decays quickly over the span of a few minutes after dissolution, and thus the process of dissolution, QC for release, and injection should be completed as fast as possible to preserve the high polarization level achieved. Any delays in the preparation process, such as transportation time or equipment malfunction, can significantly reduce the final polarization and result in lower quality imaging data.
Current Practices
A summary of data collected from all sites performing clinical trials with HP 13C-pyruvate is shown in Fig. 3 and Table 1, including the specification of the final dose and how the quality control and release of the final dose are performed. There is a split in the Production Style, described in the General Considerations section above, with 8/13 sites using Sterile Preparation versus 5/13 using Terminal Sterilization. While many of the dose specifications show notable differences in acceptable ranges, all of these variations listed in tables have been successfully and safely been used to perform HP 13C pyruvate studies in humans. Their differences depend on the institutions’ preferences, resources and their particular regulatory situation. There is high similarity in pyruvate ranges, temperature ranges, EPA limits, and volume limits. There is modest variability in pH ranges and large variability in the endotoxin test limit. There is a 3-fold difference in acceptable polarization levels, which are measured to ensure a futile dose is not injected since the polarization is directly proportional to SNR. This reflects the decision by several sites to believe that useful data can be still be obtained with suboptimal polarizations.
Figure 3: Hyperpolarized agent preparation methods reported by sites currently performing HP
In House
Table 1: HP 13C-pyruvate preparation parameters, methods, and dose specifications used for quality control testing and release as well as validation. These were obtained from a survey of all sites performing clinical trials with HP [1-13C]pyruvate. The parameters used for product release are noted in bold text, otherwise these parameters are measured for batch validation or other QC measurements. The endotoxin and sterility testing are performed during process validation of the batch and/or post-injection, and largely depends on the agent production approach.
Summary
The overall safety record of HP 13C-pyruvate has been very strong, and the SPINlab hyperpolarizer has proven to provide high polarizations at human sized doses while meeting numerous QC and release criteria. A weakness remains the failure modes of the SPINlab Phamacy Kits (e.g. ice blocks, path ruptures), which are placed under extreme requirements particularly during dissolution. The preparation process still requires a high degree of expertise.
Therefore, there is a significant need to improve the reliability, robustness, and ease of operation for generating HP 13C-pyruvate doses for human studies. Furthermore, there is a divide between manufacturing and sterile compounding style preparation as well as other site-specific practices, resulting in variations in SOPs and justification required to relevant regulatory bodies. There have also been no comparisons between these approaches. It is also unclear what release criteria and QC parameters are truly required to ensure patient safety.
However, all of the reported methods are acceptable and approved by the appropriate regulatory authorities, and have led to the rapid expansion of successful human studies in recent years.
Mri System Setup And Calibrations
This section covers the MRI system setup, including the imaging system, RF coils, phantoms, and prescan calibration methods.
Imaging System
The main prerequisite for a given MRI scanner to be capable of supporting studies with HP 13C is its “broadband” capability to transmit and receive radiofrequency (RF) signal at the frequency of 13C, which is around 4 times lower than 1H. This does not come as a default on clinical MR devices. The transmit power of the broadband amplifier should also be sufficient to support the intended flip angle and RF pulse shape with the employed transmission RF coil(s) for 13C. Most studies to date use relatively low flip angles (< 90 degrees) for HP 13C in order to preserve polarization for time-resolved imaging. The capability to receive 13C signal on multiple channels is also desirable to increase SNR, as discussed further in the “RF coils” section.
The choice of magnetic field strength is primarily dependent on the metabolites’ frequency separation due to chemical shift dispersion and 1H imaging. High field strengths do not enhance hyperpolarized 13C signal as they do for 1H because the signal strength in a HP experiment relies on manipulating the population of quantum energy states outside of the MRI scanner.
However, the injected HP 13C-pyruvate and its metabolic products have greater frequency separation at higher fields, and it may thus be easier to separate and quantify these resonances at higher fields. This comes at the cost of a reduction in the achievable T2* and often reduced T1. As the initial polarization is independent of the imaging field strength it has been proposed that the increased T2* at 1.5T can potentially be exploited to increase SNR by adapting the acquisition bandwidth or reduce off-resonance imaging effects in cases when the decay of the transverse magnetization is dominated by T2* (73). In practice, 3T has been used in all published human 13C-pyruvate studies surveyed (Supporting Table S1), and comprises the majority of scanners currently in use for human studies (Table 3). A field strength of 3T is well-suited for 1H MRI anatomical reference and correlative imaging.
Stronger and more rapidly slewing magnetic field gradients support more rapid spatial encoding, particularly for metabolite-specific single-shot imaging using echo-planar imaging (EPI) or spiral imaging (See “Acquisition and Reconstruction”). Although the spatial resolution acquired for HP 13C imaging is typically much coarser than for 1H MRI, the factor of ~4 in gyromagnetic ratio leads to the same reduction factor in performance of the gradient system, so 13C experiments are potentially more limited by gradient hardware performance. To date, all human studies have used the commercially-available integrated gradient systems provided in clinical MRI scanners.
Optimization of scanner design has understandably focused on minimization of artifacts in 1H MRI, where devices such as room lights, the gradient amplifiers, and the motors driving the patient bed are checked to ensure that they do not produce RF interference at the 1H frequency, but artifacts may arise at other frequencies. Eddy current compensation is also not always appropriately adjusted for nuclei at other frequencies (74). In order to optimize for 13C, many sites have performed checks on phantoms for RF interference, gradient artifacts, and eddy currents (74), including the use of post-hoc gradient impulse response function characterisation and correction, and some vendors have fixed these issues as well.
Rf Coils
For HP 13C imaging studies in humans, RF coils for both 1H and 13C nuclei are needed, with 1H MRI providing an anatomical reference for registration and optional additional multiparametric MRI readouts. At the Larmor frequency of 13C nuclei, the relative contributions from coil noise compared to sample noise increase compared to 1H (73,75), although sample noise still is likely the dominant contributor for human-sized coils at 32.1MHz - the resonance frequency of 13C nuclei at 3T.
The key requirement for human 13C-pyruvate RF coils are that the coil geometry and sensitive volume must cover the volume of interest in the subject. Table 2 and Figure 4 shows coil configurations that have been used and optimized for applications in different anatomic regions.
Volume resonators are most commonly used for transmit, as they surround the subject to
Provide B1 Transmit Across The Fov (B1
+). While 1H relies on a large birdcage (“body”) coil built into the scanner, 13C transmit coils must be placed inside the bore. This takes up valuable space within the magnet, and also has led to the use of designs with relatively inhomogeneous
B1
+. Many human studies have used Helmholz pair resonators for transmit, including the “clamshell coil”, which has a notably inhomogeneous B1
+ Profile But Has Been Used Because Of
relatively easy integration into the scanner bore. B1
+ Variation Results In Variations In The Flip
angles that control the use of the hyperpolarized magnetization and creates errors in common HP metrics (9,76). The exception are head coils, where birdcage designs with highly
Homogeneous B1
+ can be placed around the head while easily fitting inside the bore. As with 1H MRI, higher SNR can typically be achieved by smaller receive coil elements, such as surface coils or phased arrays, and the majority of 13C receive coils used have layouts similar to 1H phased arrays.
RF coil quality control is important to ensure proper functioning of the coils to provide consistent imaging quality, especially with limited natural abundance 13C signal in vivo. It typically involves 1) a physical integrity check of the coil cables and connectors and 2) phantom SNR tests to check the coil’s performance and to monitor it over time (see Phantoms below). An useful reference for RF coil quality control is outlined in the MRI accreditation program of the American College of Radiology (77) and can be adapted for 13C coils.
Notably, configurations for brain and prostate studies used dual-tuned 1H/13C coil designs, which greatly simplify workflow and registration of 1H and 13C images, as no switching of coils is needed.
(1)
Table 2: RF coil configurations reported for human HP [1-13C]pyruvate studies.
Tx = Transmit
coil, RX = receive coil. The commonly used “clamshell” TX coil is a Helmholz pair design. For 1H RF configurations, all used the Body coil for TX unless otherwise noted, and “repositioned” indicates the 13C coil was removed for 1H imaging. One representative reference is listed for each configuration. The RF coil configurations reported in the reviewed papers are shown in Supporting Table S1.
Figure 4: Examples of RF coil configurations used for human HP [1-13C]pyruvate brain studies. (A,B) 13C Clamshell TX (Helmholz pair) and 2× 4-channel paddle RX arrays. (C) 13C Birdcage volume TX and 32-channel RX array (RX array slides into TX coil). (D) 13C Birdcage volume TX and 24-channel RX array, combined with a 1H 8-channel RX array. Image reproduced with permission from Ref (16).
Phantoms
Since hyperpolarized magnetization is non-renewable, phantoms containing 13C nuclei are important to: 1) test the multi-nuclear capabilities of the imaging system, including all parts of the signal excitation and receive chain; 2) perform calibration measurements before a scan with hyperpolarized nuclei; and 3) perform necessary pre-scan adjustments (see “Prescan Calibration” section). The phantoms currently in use are listed in Table 3. Their composition must provide sufficient 13C signal, with additional considerations of conductivity, stability, chemical shift(s) present, potential for dynamic imaging, and cost. The phantom geometries are typically either compact, in order to be used alongside the subject during a HP scan, or large enough to mimic the inner volume of a RF coil for system testing.
One popular compact design contains enriched 13C-urea at high concentration, typically 8 M, which provides a single resonance, placed inside a small container ~1 mL. The most common recipe mixes 13C-urea in a 90% water/10% glycerol solution, with glycerol used to increase the urea solubility and doping with a Gd-based contrast agent to shorten T1 which increases the potential SNR per unit time. For example, when Dotarem is added at a 3:1000 volume ratio the 13C-urea T1 is around 500 ms and T2 is around 100 ms. However, when testing pulse sequences influenced by T1 and T2, doping should be used carefully. This phantom is suitable for frequency calibration, transmit gain calibration, sequence testing, and as a fiducial marker when placed next to a patient. However, enriched 13C-urea has a relatively high cost compared to natural abundance compounds.
For larger volumes (>100 ml), the phantoms most often used contain undiluted ethylene glycol, glycerol, or dimethyl silicone. These compounds have sufficiently high carbon concentrations to provide sufficient 13C signal even with the 1.1% natural abundance of 13C. These larger phantoms matching the inner volume of an RF coil are useful for coil testing, including transmit
+) And Receive (B1
-) coil profile mapping, as well as to mimic acquisitions using in vivo FOV requirements. In this case, size and conductivity should match the expected subject size in order to mimic coil loading and get a realistic estimation of B1+. Large-volume natural abundance urea phantoms have also been used by some sites, but suffer from higher conductivity compared to biological tissues. Typically, it is easier to increase the conductivity and hence coil loading of the non-conductive phantom by adding NaCl to match physiological loading (16,78).
Dynamic phantoms that aim to mimic metabolite kinetics have also been developed (79–81), and have the potential to more closely mimic the HP experiment, but so far these are not widely used.
Prescan Calibration
Prior to performing an MRI acquisition, the so-called prescan procedure is used to set the shim parameters to maximize B0 homogeneity over the field of view (FOV) or a specific region of interest (ROI), the scanner center frequency (CF), the RF transmit gain, and the receiver gain.
While this calibration procedure is usually automated for 1H, the lack of sufficient natural abundance 13C signal prevents use of automated methods. (Although natural abundance 13C lipid signal has been detected, there are so far no reports on using this signal for prescan.) Table 3 shows current practices across sites.
Maximizing B0 homogeneity is independent of the nucleus and is therefore performed prior to 13C imaging using the 1H water signal and existing shimming tools, such as by a standard automated process (“Auto Shimming”) or using high order shimming routines. Similarly, the 13C CF can be calculated from the 1H CF using a predetermined scaling factor that depends on the target chemical shift (82). Another common approach used is to have a small, high-concentration 13C phantom, e.g. 8M 13C-urea, integrated in the RF coil or placed next to the scan subject (1). The reference frequency can also be based on real-time measurements after the HP injection but prior to imaging (83). Both the CF and B0 shimming are critical when using spectrally-selective RF pulses, as inmetabolite-specific imaging methods, where the desired excitation bandwidths are typically very narrow and frequency offsets can lead to a failure mode that is only apparent after injection.
The calibration of the RF transmit power is typically performed on a small, high-concentration 13C phantom placed near the region of interest during the scan or on a large 13C phantom of similar size and coil loading as the subject, prior to the subject scan. Reference power is often done by sweeping the power in a pulse-acquire sequence (53,62), or the Bloch-Siegert method (52,84). When using a small phantom, the location of the phantom, B1
+ Inhomogeneity As Well
as any shielding effects, e.g., when the phantom is integrated into a coil (1), may degrade the accuracy. Other methods include real-time Bloch-Siegert method measurements after the HP injection (83), and using the stronger natural abundance 23Na signal that is close enough to the 13C resonance frequency to be detected by 13C coils (82).
The receiver gain is predetermined, either systematically based on independent phantom measurements and assuming the dose and polarization of the HP compound is known prior to injection, or based on past HP imaging studies.
Power [Kw]
Phantom(s) - during study Phantom(s) - before study 13C Frequency
8
13C-bicarbonate doped with dimethyl silicone, various
Maximum Values
Table 3: Summary of the imaging systems, phantoms, and prescan procedures used at sites currently performing HP 13C-pyruvate human studies. These were obtained from a survey of all sites performing clinical trials with HP [1-13C]pyruvate. *Previously performed studies with a Siemens 3T Tim Trio. The imaging systems, phantoms, and prescan procedures reported in the reviewed papers are shown in Supporting Table S1.
Summary
Commercially available 3T MRI systems are by far the most commonly used for human HP 13C-pyruvate studies, although a systematic investigation of the impact of B0 has only recently been investigated (73). The multi-nuclear RF transmit and receive chain has proven sufficient for current acquisition strategies, although many sites have observed artifacts due to RF interference, gradient interference, and residual eddy currents when operating at the 13C frequency. A variety of 13C RF coils, tailored for numerous anatomical targets, have been successfully demonstrated, with the main limitation that most transmit coils take up a lot of additional space inside the bore and provide relatively inhomogeneous B1
+ Profiles. The
phantoms used have converged into generally 2 categories - small phantoms containing 13C-enriched compounds that can be used during the study and human-sized phantoms containing compounds with high carbon concentrations but without 13C enrichment that are used to test and calibrate the coils. There are no standardized compositions or geometry, and dynamic phantoms that recapitulate in vivo kinetics would be desirable but are still an emerging area. Prescan calibration procedures were not well defined in most publications, so we surveyed individual sites to determine current practices. Calibration procedures for the B0 field (13C CF and shimming) for most sites take advantage of 1H signal and methods, while methods
For Calibration Of B1
+ is more variable across sites, likely a reflection of remaining challenges in how to perform this calibration. Standardization of both phantoms and calibration procedures would synergistically improve the robustness and reproducibility of HP 13C studies.
Acquisition And Reconstruction
Data acquisition strategies in human HP [1-13C]pyruvate MRI studies must account for multiple chemical shifts, efficiently utilize the non-renewable HP magnetization, and acquire data quickly relative to metabolism and relaxation decay processes. These studies require spectral encoding to separate metabolites, necessitating pulse sequences that efficiently encode up to 5D data (3 spatial + 1 spectral + 1 temporal dimension). RF pulses must efficiently sample without immediately saturating the non-renewable HP magnetization, and sequences must acquire data quickly and be robust to both experimental and physiologic variation (e.g. B1
+ Inhomogeneity,
variation in perfusion) to ensure reproducibility and minimize scan-to-scan variability. This section covers current successful practices for data acquisition in human [1-13C]pyruvate studies, and accompanying 1H imaging, from different anatomic regions, including scan parameters and image reconstruction.
Acquisition And Reconstruction Methods
The acquisition methods used in human [1-13C]pyruvate studies can be classified into 3 categories: 1) MR spectroscopy or MR spectroscopic imaging (“MRS/I”), 2) chemical shift encoding methods, and 3) metabolite-specific imaging (Fig. 5).
Mrs/I Methods Specifically
resolve a spectrum that can be analyzed to extract expected as well as unexpected resonances, making this approach very robust. It was used in many initial studies (1).
Chemical Shift
encoding methods, most commonly the Iterative Decomposition of water and fat with Echo Asymmetry and Least-squares estimation (IDEAL) method, use imaging sequences acquired with multiple TEs and rely on a model-based separation of expected chemical shifts (85).
Metabolite-specific imaging methods use specialized RF pulses that are spatially and spectrally selective to excite individual metabolites which are then typically imaged with fast k-space trajectories such as echo planar imaging (EPI) or spirals (86).
Their Application To Different
organ systems is described below. The image reconstruction methods used in human [1-13C]pyruvate studies have typically been conventional methods (e.g. FFT, non-uniform FFT, or equivalent). The incorporation of accelerated imaging and advanced reconstruction methods including parallel imaging (4,57,87) and compressed sensing (7) has also been applied in human studies for improved spatial resolution, temporal resolution and coverage, but have the potential for additional artifacts as well as SNR losses due to ill-conditioning of the reconstruction (e.g. g-factor).
The Majority Of
published studies do not use accelerated imaging indicating the resolution and coverage achievable without acceleration is currently adequate for successful data collection. Performing coil combination, even with fully sampled data has also been shown to have specific challenges for HP human images: using naive sum-of-squares methods suffer from high noise amplification in the relatively low SNR regime of HP [1-13C]pyruvate (compared to 1H), motivating several HP 13C-specific methods that include data-driven coil sensitivity estimation which have shown obvious improvements over sum-of-squares (11).
More recently denoising techniques have been applied as post-processing of human HP data(41,42,44). The techniques applied are based on spatial-temporal singular value decomposition for unsupervised estimation of signal and noise components. They have shown improvements in apparent SNR in the brain and liver, while care must be taken to choose parameters such as the rank threshold to avoid oversmoothing and overfitting to the estimated signal components.
Prostate Studies
Prostate cancer was the first human application of HP [1-13C]pyruvate (1), and data was acquired with MRS/I methods: 1D dynamic MRS, single-slice 2D dynamic echo-planar spectroscopic imaging (EPSI), and single time point 3D EPSI. Advances in imaging strategies led to the development and application of new acquisition schemes, including undersampled 3D EPSI with compressed-sensing (7), model-based chemical shift encoding methods that use a priori information (47,59), and metabolite-specific EPI (10), all of which can provide volumetric whole-organ coverage and dynamic acquisitions.
The pyruvate bolus arrival in the prostate can vary by ± 10 s between patients, necessitating dynamic imaging to reliably and consistently capture the pyruvate bolus (18). For this reason, all currently ongoing studies acquire dynamic data. While MRS/I, chemical shift encoding, and metabolite-specific imaging can all achieve dynamic imaging, chemical shift encoding and metabolite-specific imaging provide greater dynamic and volumetric coverage (85). For scan prescriptions, the FOV is designed to provide full prostate coverage and typically to match the orientation of the anatomic imaging used for registration. Flip angles used in current studies are constant through time, as quantification with a variable-through-time flip scheme is highly sensitive to bolus timing (8) and errors in the RF transmit (B1 +) field (76).
Heart Studies
Data acquisition methods for 13C imaging in the heart must be designed to meet the demands of significant cardiac motion and blood flow. To cope with the periodic cardiac motion, most human heart studies to date used gating to the diastolic window, the longest cardiac cycle interval, which has reduced motion (2,22,28,30,35,36,38,45,52). The duration of the diastolic window limits the available data sampling time, making cardiac acquisitions the most time-constrained of the HP 13C MRI applications. The most common acquisition approach is metabolite-specific imaging with spiral k-space trajectories (2). Their single-shot imaging capability makes these methods particularly robust to motion effects. Furthermore, spiral k-space trajectories provide rapid k-space coverage and relatively benign flow and motion artifacts. The majority of studies have used 2D multi-slice acquisitions, but 3D encoding has also been used successfully (35).
Brain Studies
For HP 13C MRI of the human brain, the majority of studies have also used 2D (slice selective) acquisitions (10–12,14,16,28,33,40,41,44,51,53,60), with a trend toward volumetric coverage using 2D multi-slice metabolite-specific imaging. 3D metabolite-specific imaging of the whole brain, with phase encoding of the slice direction (34,57), has been shown to provide similar SNR efficiency (88) compared with multislice imaging. A number of studies have employed MRS/I (5,6,29,31–33,50,55) resulting in a spectrum from each voxel, which has the advantage of not requiring a priori information about which peaks to encode. This was important in early brain studies when it was not known which peaks would be detectable. Chemical shift encoding, using a set of images with different echo times and an iterative reconstruction of the individual resonances (i.e. the IDEAL approach (85)), has also been used (12,49,54), with the drawback that coverage in the slice direction was limited due to the time required to acquire multiple echo time images.
Abdomen And Breast Studies
The fundamental approaches to data acquisition and reconstruction in the abdomen and breast are largely similar to the aforementioned applications, but demand attention to particular challenges associated with these anatomic regions, especially relating to respiratory motion.
Although it has been shown that a basic 2D MRSI approach based on phase encoding and FID readout can be successfully applied for HP 13C imaging in breast (15) and kidney (13), major advantages in terms of spatiotemporal resolution and coverage have been realized using tailored approaches based on metabolite-specific imaging (43,62) and chemical shift encoding (43), which have facilitated multi-slice or 3D dynamic acquisitions over large FOVs in the abdomen (4,37,46).
The significant respiratory motion encountered in these regions can directly blur 13C images, and has further favored these rapid acquisition strategies. Motion also degrades B0 homogeneity, which can shift frequency-selective excitation profiles and introduce artifacts into rapid imaging readouts. This makes accurate determination of the acquisition center frequency and shimming essential in these regions which often cover large FOVs. (See “Prescan Calibration” section for more information). In some studies, breath-holding was used to minimize motion effects and enforce frame-to-frame data consistency (42). A pragmatic and reasonably effective approach for dealing with respiratory motion during 13C data acquisition is an initial breath-hold (as long as can be tolerated), followed by free-breathing (46,62).
1H Imaging
Collection of 1H imaging data is essential both for prescribing the 13C acquisition and for interpretation of the resulting 13C data. Multi-planar 1H scouts are acquired prior to 13C acquisition to enable graphical prescription of the 13C imaging region. All human HP 13C-pyruvate imaging studies acquire conventional MRI scans (e.g. T1- and T2-weighted volumes) for anatomic reference, aiming to cover at least the full 13C FOV. Acquiring these anatomic scans as close as possible to the time of 13C imaging (immediately before or after) minimizes potential misregistration between the data sets. Depending on the application, other advanced 1H sequences are also acquired (e.g. diffusion-weighted imaging for cancer imaging).
When contrast-enhanced data is acquired, it is done after 13C imaging, as paramagnetic contrast agents will accelerate 13C relaxation.
Reported Study Parameters
Figures 5 and 6, and Supporting Table S2 shows the reported acquisition study parameters for human HP [1-13C]pyruvate studies published as of September 2022. Figure 5 shows a mixture of MRS/I, metabolite-specific imaging, and chemical shift encoding methods have been successfully used, where spectroscopy-based methods have become less prevalent in recent studies. Figure 6 shows the acquisition timing, including the important start time and interval/temporal resolution, is quite variable across studies.
Figure 5: Acquisition methods used in published HP [1-13C]pyruvate human studies published up to September 2022, classified into: MR spectroscopy and spectroscopy imaging (MRS/I); chemical shift encoding methods, such as IDEAL, that use multiple TEs and model-based reconstructions; and metabolite-specific imaging methods that use spectrally-selective excitation to image a single resonance at a time.
Figure 6: Temporal acquisition characteristics reported in HP [1-13C]pyruvate human studies published up to September 2022. (a) Reported referencing of acquisition start times.
(B)
Acquisition start times reported when using dynamic imaging and when timing was reported relative to the end of the injection. (c) Temporal resolutions. “Not Applicable” indicates dynamic imaging was not used.
Summary
Three general categories of acquisition strategies have been used successfully for human HP 13C-pyruvate studies: MRS/I, model-based chemical shift encoding (e.g. IDEAL) methods, and metabolite-specific imaging methods. These have enabled successful studies in the prostate, heart, brain, abdomen, and breast. Recent studies increasingly have used the imaging-based strategies of metabolite-specific imaging and chemical shift encoding which are the fastest methods, although a heads-to–head comparison between techniques has not been performed.
Metabolite-specific imaging is quite popular because of its speed and compatibility with single-shot imaging, but is sensitive to B0 field variations and thus requires careful calibrations. Nearly all studies surveyed acquired data dynamically, allowing measurement of the bolus and metabolite kinetics. The exact timings and associated flip angles vary quite widely across reported studies, with no consensus yet as to how to choose these parameters. Image reconstruction is typically done directly using Fourier Transform methods, and accelerated imaging strategies are uncommon.
Data Analysis And Quantification
This section covers the analysis of data from human HP [1-13C]pyruvate studies, including modeling and metrics, visualization, as well as considerations for how to store data and metadata. Depending on study design, the analysis may need to give quantitative or semi-quantitative output reflecting a biological process or may just reflect a contrast between different regions of interest for quantitative evaluation.
Metrics
Figure 7: HP [1-13C]pyruvate raw data (A) have typically been quantified using four categories of metrics depending on the acquisition. Data acquired as a single time point are often quantified using normalized metabolite images or metabolite ratios (B). Dynamic data can be quantified using normalized metabolite images or metabolite ratios (B), or with metabolite timings such as time-to-peak (TTP) or pharmacokinetic (PK) models (C). The latter two require the data to be time-resolved. [1-13C]alanine and 13C-bicarbonate are analyzed similarly to [1-13C]lactate but omitted here for display.
Metabolite images are commonly used as summary metrics for HP MRI data, often including some form of normalization as well as summed over time as an area under the time curve (AUC) (17). These are analogous to the visual evaluation that is most used for routine clinical work (89,90). In these metabolite images, we expect that the [1-13C]pyruvate AUC signal is predominantly weighted towards perfusion and uptake, while [1-13C]lactate, [1-13C]alanine and 13C-bicarbonate AUCs represent metabolic conversion. The strength of this approach lies in its simplicity and relatively few underlying assumptions. Limitations to the use of single-metabolite images or AUCs include sensitivity to inhomogeneous coil profiles (57,87,91), the acquisition strategy and acquisition parameters, pyruvate polarization and concentration level, and signal relaxation rates (92). Further, the reader must be careful to interpret all the images in conjunction to better understand the underlying biology; for example, increased [1-13C]lactate in the presence of decreased [1-13C]pyruvate delivery can have a very different meaning compared to increased [1-13C]lactate with increased [1-13C]pyruvate delivery.
In an attempt to address variations in coil sensitivity, polarization level, and pyruvate delivery, AUC images are often computed by normalizing to a specified parameter, such as the maximum pyruvate or average lactate signals, or presented as a ratio such as lactate/pyruvate or divided by “total Carbon” - the sum total of HP 13C signal observed across all metabolites. The AUC ratios between metabolites and pyruvate are proportional to the corresponding forward kinetic rates (81,93), but are not directly comparable to rate constants when magnetization loss rates (e.g. relaxation and losses due to signal excitation) differ between studies. Similarly, the ratios between the produced metabolites (e.g. bicarbonate/lactate) can reflect the balance between downstream metabolic pathways (12,55). Care must be taken to consider how AUC images are calculated and normalized before comparing values between studies.
To further quantify the interpretation, pharmacokinetic (PK) modeling approaches were developed to compute the apparent kinetics of pyruvate-to-metabolite exchange (92,94–99). These yield semi-quantitative to quantitative apparent rate constants, given in s-1. Some models require a vascular input function, while others avoid this requirement (95). PK models can explicitly account for acquisition-specific details such as excitation angle and repetition time, and thus may reduce the effects of these details on quantification. An input-less model, provided in the Hyperpolarized-MRI-Toolbox (https://github.com/LarsonLab/hyperpolarized-mri-toolbox) (100) and thus frequently employed for human data, has been shown to fit well and robustly to prostate and brain data (8,20). PK models are quantitative in nature, arguably provide more relevant biological information (8,20), and appear to be reproducible across sites (51). However, rate constants derived from PK models are still apparent rates, and likely do not reflect a single biological characteristic.
Some additional considerations include whether complex or magnitude data is used, as the noise behaviors will impact the analysis differently. Additionally, cut-off thresholds or other criteria may be used to identify and avoid voxels with insufficient SNR before analysis to improve robustness (20,41).
Regardless of the analysis approach, the underlying biology is not always clearly represented by the data; instead, the metrics may be influenced by perfusion, barrier permeability, intercellular shuttles, enzyme activities, co-substrate concentrations, or combinations thereof, depending on the organ and disease of interest (19,43,94,101–103). This may be addressed by incorporating complementary information. As an example, HP 13C pyruvate data is influenced by perfusion, and thus addition of perfusion MRI could be important for interpretation (98,104,105).
All the methods outlined above have been explored in clinical studies, described in Supporting Table 3 and summarized in Figure 8. As of September 2022, approximately 52% of studies involving human subjects report rate constants derived from a PK model with a few different models reported. A nearly equal fraction (51%) of the studies report AUC ratio values.
Approximately 66% of these studies report metabolite-specific images or AUC values. About 40% report SNR values; this metric is particularly frequent in manuscripts that describe technical developments for clinical HP MRI. Approximately 16% of these studies summarize model-free metrics, and 10% report measurements from a single timepoint. Most studies report a combination of quantities.
Figure 8: Reported metrics used for analysis in HP [1-13C]pyruvate human studies published up to September 2022.
Visualization
A wide variety of approaches have been used for visualizing data from human HP 13C-MRI studies. The challenges and practical considerations are: 1) choosing the appropriate metrics to display, 2) how to encode the parameters (e.g. the colormap), and 3) choosing how to provide anatomical context and other multi-parametric data. The choice of visualization also depends on the goal which could be for diagnostic interpretation, but also quality control, reproducibility among readers and publication.
Metrics
The choice of HP 13C metrics is described in detail above. At this stage in HP 13C development where there is no standardized metric, often a combination of metabolite images and ratios or PK model parameters are shown.
Parameter Encoding
The mapping function chosen should provide an adequate, often quantitative, impression of the parameter mapped. There is a consensus in the visualization field that perceptually uniform maps are best suited to visualize continuous parameters, like the greyscale typically used by radiologists as well as other monochrome (black to blue) and color ranges (fire-type, rainbow-type) (106,107). Multi-color heatmaps have been the most frequently employed method for HP 13C data, while greyscale has infrequently been used but it ensures there is no coloring-based bias as well as facilitating later reuse (Fig. 9a). Among the color schemes employed in the clinical HP 13C literature, fire-type scheme seems to be the most common [similar to “Plasma” or “Inferno” in matplotlib.org]. Next most commonly employed is the rainbow-type scheme [similar to “Rainbow” in matplotlib.org].
Anatomical Context
HP MRI faces the challenge that it does not necessarily depict the anatomical features, similar to PET, and thus requires an anatomical reference. Most often, a grayscale anatomical image is overlaid with a HP colormap (Fig. 9c,d). This approach is very intuitive, but can skew perception as the grey-scale anatomical reference may affect the brightness of the HP data (e.g. signal in the skull). This bias does not occur when showing adjacent maps (Fig. 9a, b). Here, anatomical outlines may help to provide reference (Fig. 9b).
Related Journal Articles & DOI Links
Selected peer-reviewed publications relevant to 12 Lead ECG Acquisition. Click the DOI to access the full paper (may require institutional access).
-
1. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
IEEE Journal of Biomedical and Health Informatics
https://doi.org/10.1109/JBHI.2020.2981234 -
2. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Medical & Biological Engineering & Computing
https://doi.org/10.1007/s11517-020-02145-6 -
3. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
IEEE Transactions on Biomedical Engineering
https://doi.org/10.1109/TBME.2019.2895762 -
4. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Frontiers in Bioengineering and Biotechnology
https://doi.org/10.3389/fbioe.2020.00123 -
5. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Biosensors and Bioelectronics
https://doi.org/10.1016/j.bios.2021.112345 -
6. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
Computers in Biology and Medicine
https://doi.org/10.1016/j.compbiomed.2021.104567 -
7. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Nature Communications
https://doi.org/10.1038/s41467-020-12345-6
Why Choose Us?
Bangalore guidance for robotics, Spectre and autonomous systems projects.
Spectre & Simulation
Gazebo, cloud twin and Webots worlds with navigation, SLAM and control stacks.
Control & Planning
Compliance, deep learning control, path planning and behavior trees.
Hardware Bring-up
Motors, sensors, ESP32/STM32 firmware and HIL validation paths.
Report & Viva
University-format documentation, PPT and viva preparation.
FAQ
CFD Lab — Bangalore
Simulation, control and hardware support for final-year robotics projects.
Stacks
Worlds
Digital Twin
Control
Robots
Offline
Bring-up