Tokyo, Japan
Vivek B.S.
Though Deep Neural Networks (Dnn) Show Excellent
performance across various computer vision tasks, several works show their vulnerability to adversarial samples, i.e., image samples with imperceptible noise engineered to ma- nipulate the network’s prediction. Adversarial sample gen- eration methods range from simple to complex optimiza- tion techniques. Majority of these methods generate adver- saries through optimization objectives that are tied to the pre-softmax or softmax output of the network. In this work we, (i) show the drawbacks of such attacks, (ii) propose two new evaluation metrics: Old Label New Rank (OLNR) and New Label Old Rank (NLOR) in order to quantify the extent of damage made by an attack, and (iii) propose a new ad- versarial attack FDA: Feature Disruptive Attack, to address the drawbacks of existing attacks. FDA works by generat- ing image perturbation that disrupt features at each layer of the network and causes deep-features to be highly corrupt.
This allows FDA adversaries to severely reduce the perfor- mance of deep networks. We experimentally validate that FDA generates stronger adversaries than other state-of-the- art methods for image classification, even in the presence of various defense measures. More importantly, we show that FDA disrupts feature-representation based tasks even with- out access to the task-specific network or methodology.1
1. Introduction
With the advent of deep-learning based algorithms, re- markable progress has been achieved in various com- puter vision applications. However, a plethora of existing works [9, 49, 8, 39], have clearly established that Deep Neu- ral Networks (DNNs) are susceptible to adversarial sam- ples: input data containing imperceptible noise specifically crafted to manipulate the network’s prediction.
Further,
Szegedy et al. showed that adversarial samples trans- ∗Work done as a member of Video Analytics Lab, IISc, India. 1Code available at https://github.com/BardOfCodes/fda
(C) Clean Sample’S Inversion
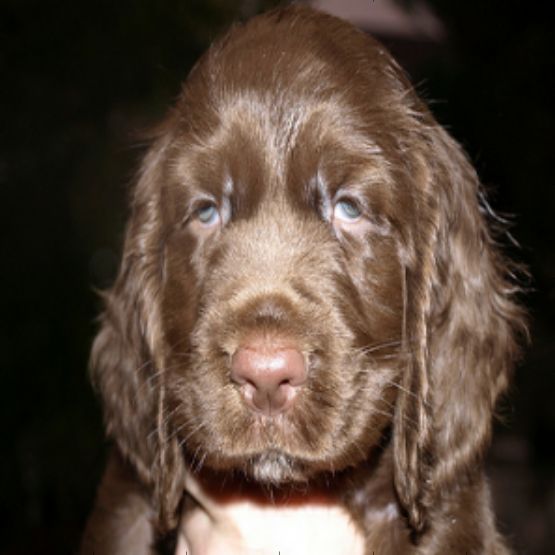
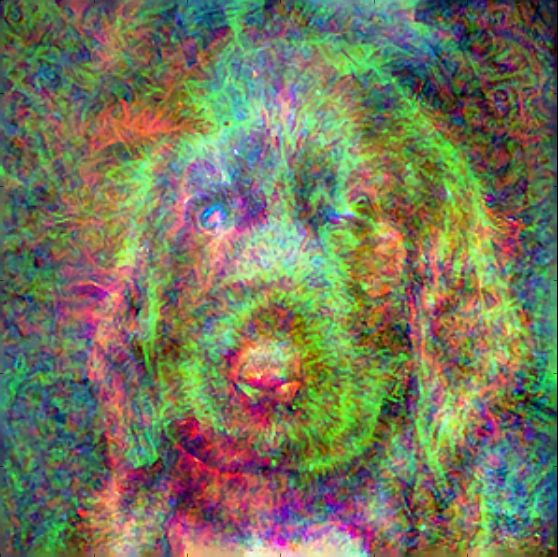
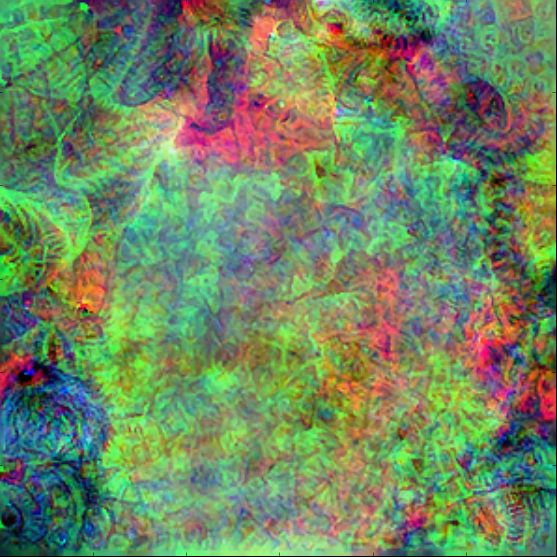
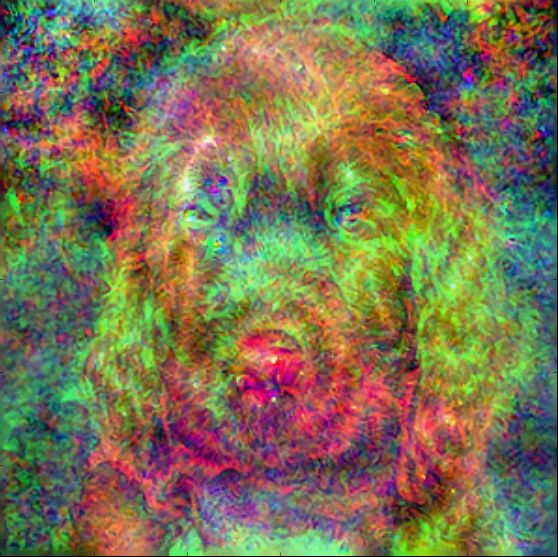
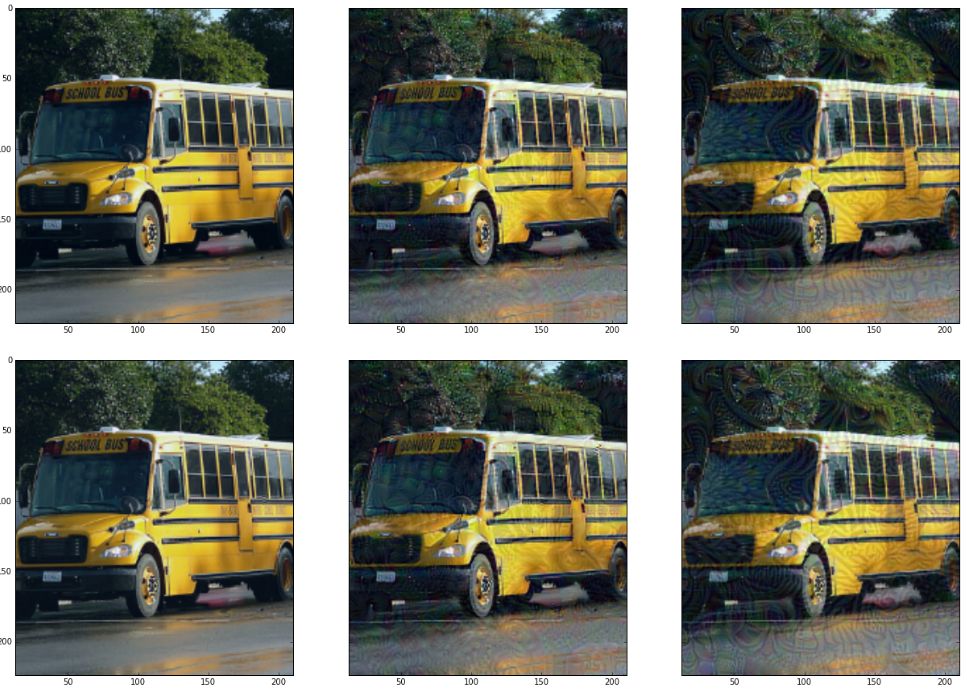
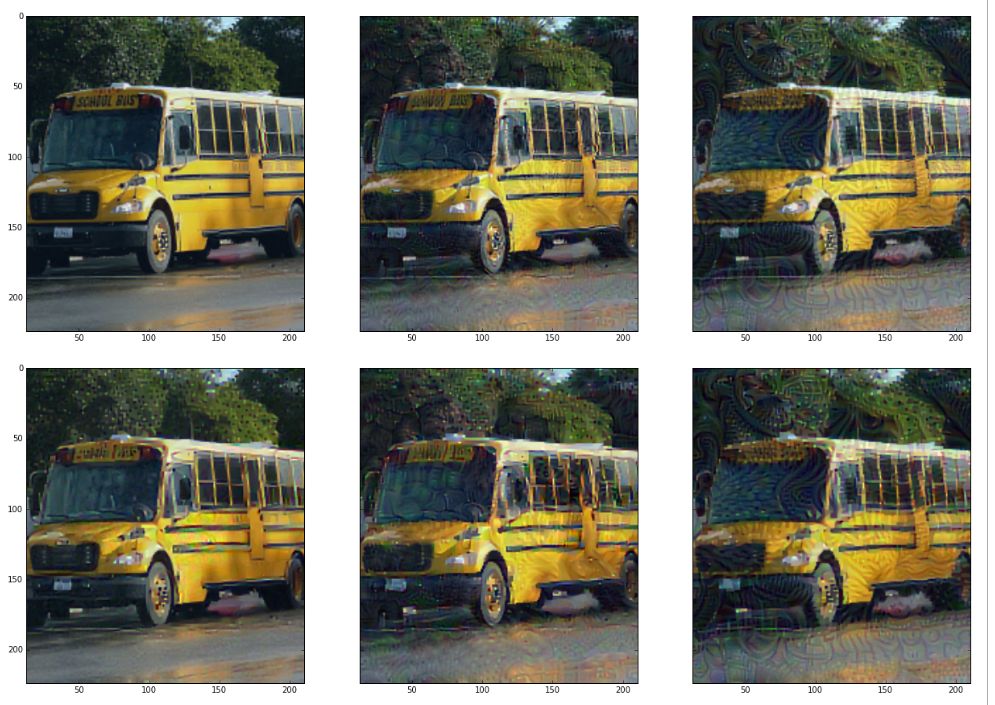
Figure 1. Using feature inversion , we visualize the Mixed7b representation of Inception-V3 .
The Inversion Of Pgd-
attacked sample (d) is remarkably similar to inversion of clean sample (c).
In Contrast, Inversion Of Fda-Attacked Sample (B)
completely obfuscates the clean sample’s information. fer across models i.e., adversarial samples generated for one model can adversely affect other unrelated models as well.
This transferable nature of adversarial samples further in- creases the vulnerability of DNNs deployed in real world. As DNNs become more-and-more ubiquitous, especially in decision-critical applications, such as Autonomous Driv- ing , the necessity of investigating adversarial samples has become paramount.
Majority of existing attacks [49, 13, 33, 16], generate ad- versarial samples via optimizing objectives that are tied to the pre-softmax or softmax output of the network. The sole objective of these attacks is to generate adversarial samples
Arxiv:1909.04385V1 [Cs.Cv] 10 Sep 2019
which are misclassified by the network with very high con- fidence. While the classification output is changed, it is un- clear what happens to the internal deep representations of the network. Hence, we ask a fundamental question: Do deep features of adversarial samples retain usable
Clean Sample Information?
In this work, we demonstrate that deep features of adver- sarial samples generated using such attacks retain high-level semantic information of the corresponding clean samples.
This is due to the fact that these attacks optimize only pre- softmax or softmax score based objective to generate ad- versarial samples. We provide evidence for this observation by leveraging feature inversion , where, given a feature representation ψ(x), we optimize to construct the approxi- mate inverse ψ−1(ψ(x)). Using the ability to visualize deep features, we highlight the retention of clean information in deep features of adversarial samples. The fact that deep fea- tures of adversarial samples retain clean sample information
Has Important Implications:
• First, such deep features may still be useful for vari- ous feature driven tasks such as caption generation [52, 58], and style-transfer [21, 25, 51].
• Secondly, these adversarial samples cause the model to either predict semantically similar class or to retain high (comparatively) probability for the original label, while predicting a very different class. These observa- tions are captured by using the proposed metrics i.e.,
New Label’S Old Rank (Nlor) And Old Label’S New
Rank (OLNR), and statistics such as fooling rate at kth rank. These implications are major drawbacks of existing attacks which optimize only pre-softmax or softmax score based objectives. Based on these observations, in this work, we seek adversarial samples that can corrupt deep features and inflict severe damage to feature representations. With this motivation, we introduce FDA: Feature Disruptive attack.
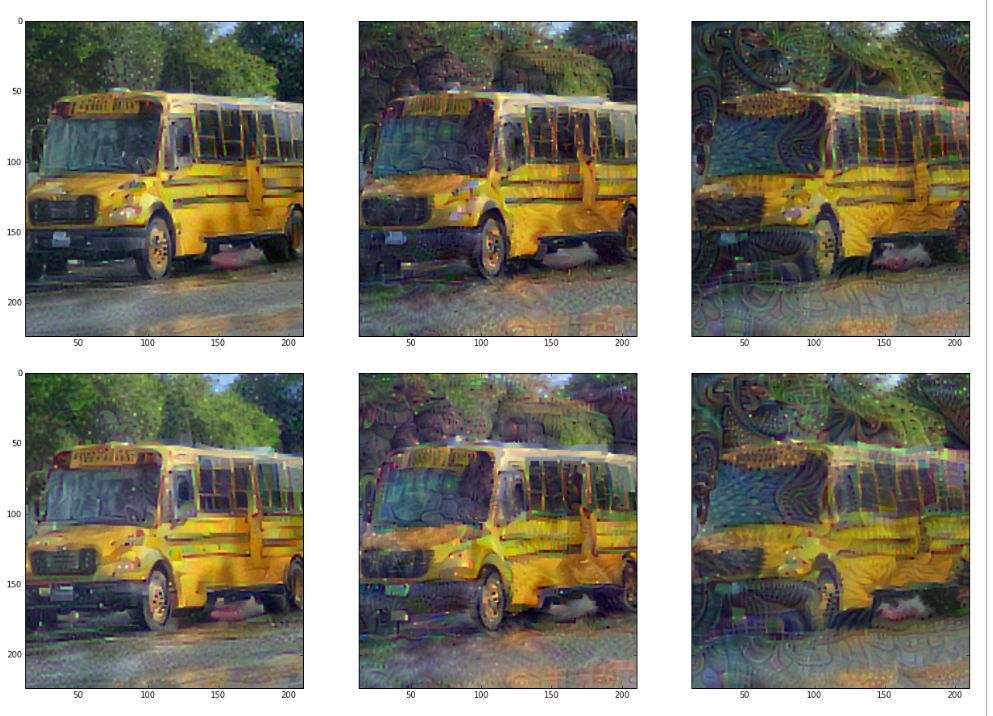
FDA generates perturbation with the aim to cause disrup- tion of features at each layer of the network in a principled manner. This results in corruption of deep features, which in turn degrades the performance of the network. Figure 1 shows feature inversion from deep features of a clean, a PGD attacked, and a FDA attacked sample, highlight- ing the lack of clean sample information after our proposed attack.
Following are the benefits of our proposed attack: (i) FDA invariably flips the predicted label to highly unrelated classes, while also successfully removing evidence of the clean sample’s predicted label.
As We Elaborate In Sec-
tion 5, other attacks [49, 30, 13] only achieve one of the above objectives. (ii) Unlike existing attacks, FDA disrupts feature-representation based tasks e.g., caption generation, even without access to the task-specific network or method- ology i.e., it is effective in a gray-box attack setting. (iii) FDA generates stronger adversaries than other state-of-the- art methods for Image classification. Even in the presence of various recently proposed defense measures (including adversarial training), our proposed attack consistently out- performs other existing attacks.
In summary, the major contributions of this work are: • We demonstrate the drawbacks of existing attacks. • We propose two new evaluation metrics i.e., NLOR and OLNR, in order to quantify the extent of damage made by an attack method.
• We introduce a new attack called FDA motivated by corrupting features at every layer. We experimentally validate that FDA creates stronger white-box adver- saries than other attacks on ImageNet dataset for state- of-the-art classifiers, even in the presence of various defense mechanisms.
• Finally, we successfully attack two feature based- tasks, namely caption generation and style transfer where current attack methods either fail or are exhibit
Weaker Attack Than Fda. A Novel “Gray-Box” Attack
scenario is also presented where FDA again exhibits stronger attacking capability.
Following The Demonstration By Szegedy Et
al. on the existence of adversarial samples, multiple works [22, 38, 29, 16, 4, 33, 13, 10] have proposed various techniques for generating adversarial samples. Parallelly, works such as [36, 57, 6] have explored the existence of adversarial samples for other tasks.
The works closest to our approach are Zhou et al. , Sabour et al. and Mopuri et al. . Zhou et al. create black-box transferable adversaries by simultaneously opti- mizing multiple objectives, including a final-layer cross en- tropy term. In contrast, we only optimize for our formula- tion of feature disruption (refer section 4.3). Sabour et al.
specifically optimize to make a specific layer’s feature ar- bitrarily close to a target image’s features. Our objective is significantly different entailing disruption at every layer of a DNNs, without relying on a ’target’ image representa- tion. Finally, Mopuri et al. provide a complex optimization setup for crafting UAPs whereas our method yields image- specific adversaries. We show that a simple adaptation of their method to craft image-specific adversaries yields poor results (refer supplementary material).
Defenses: Goodfellow et al. first showed that including adversarial samples in the training regime increases robust- ness of DNNs to adversarial attacks. Following this work, multiple approaches [30, 50, 27, 54, 17, 33] have been pro- posed for adversarial training, addressing important con- cerns such as Gradient masking, and label leaking.
Recent works [40, 31, 1, 46, 15, 11], present many al- ternative to adversarial training. Crucially, works such as [23, 56, 53] propose defense techniques which can be eas- ily implemented for large scale datasets such as ImageNet.
While Guo et al. propose utilizing input transformation as a defense technique, Xie et al. introduce randomized transformations in the input as a defense.
Feature Visualization: Feature inversion has a long history
In Machine Learning . Mahendran Et Al. Proposed
an optimization method for feature inversion, combining feature reconstruction with regularization objectives. Con- trarily, Dosovitskiy et al. introduce a neural network for imposing image priors on the reconstruction. Recent works such as [45, 20] have followed the suit. The reader is referred to for a comprehensive survey.
Feature-based Tasks: DNNs have become the preferred feature extractors over hand-engineered local descriptors like SIFT or HOG [5, 7]. Hence, various tasks such as cap- tioning [52, 58], and image-retrieval [12, 24] rely on DNNs for extracting image information. Recently, tasks such as style-transfer have been introduced which rely on deep fea- tures as well. While works such as [25, 51] propose a learn- ing based approach, Gatys et al. perform an optimiza- tion on selected deep features.
We show that previous attacks create adversarial sam- ples which still provide useful information for feature- based tasks.
In Contrast, Fda Inflicts Severe Damage To
feature-based tasks without any task-specific information or methodology.
We Define A Classifier F : X ∈Rm →Y ∈Y C, Where
x is the m dimensional input, and y is the c dimensional score vector containing pre-softmax scores for the c differ- ent classes. Applying softmax on the output y gives us the predicted probabilities for the c classes, and argmax(y) is taken as the predicted label for input x. Let yGT represent the ground truth label of sample x. Now, an adversarial sample ˜x can be defined as any input sample such that:
(1)
where d(x, ˜x) < ϵ acts as an imperceptibility constraint, and is typically considered as a l2 or l∞constraint. Attacks such as [49, 22, 16, 33], find adversarial sam- ples by different optimization methods, but with the same optimization objective: maximizing the cross-entropy loss J(f(˜x), yGT ) for the adversarial sample ˜x. Fast Gradient Sign Method (FGSM) performs a single step optimiza-
On The Other Hand, Pgd And I-Fgsm Performs
a multi-step signed-gradient ascent on this objective. Works such as [16, 4], further integrate Momentum and ADAM optimizer for maximizing the objective.
Kurakin Et Al. Discovered The Phenomena Of Label
leaking and use predicted label instead of yGT . This yields a class of attacks which can be called most-likely attacks, where the loss objective is changed to J(f(˜x), yML) (where yML represents the class with the maximum predicted prob- ability).
Works such as [27, 50] note that above methods yield adversarial samples which are weak, in the sense of being misclassified into a very similar class (for e.g., a hound mis- classified as a terrier). They posit that targeted attacks are more meaningful, and utilize least likely attacks, proposing minimization of Loss objective J(f(˜x), yLL) (where yLL represents the class with the least predicted probability). We denote the most-likely and the least-likely variant of any at- tack by the suffix ML and LL.
Carlini Et Al. Propose Multiple Different Objec-
tives and optimization methods for generating adversaries. Among the proposed objectives, they infer that the strongest
(3)
where (e)+ is short-hand for max(e, 0). For a l∞distance metric adversary, this objective can be integrated with PGD optimization to yield PGD-CW. The notation introduced in this section is followed throughout the paper.
Feature inversion: Feature inversion can be summarized as the problem of finding the sample whose representation is the closest match to a given representation . We use the approach proposed by Mahendran et al. . Additionally, to improve the inversion, we use Laplacian pyramid gradi- ent normalization. We provide additional information in the supplementary.
4.1. Drawbacks Of Existing Attacks
In this section, we provide qualitative evidence to show that deep features corresponding to adversarial samples generated by existing attacks (i.e., attacks that optimize ob- jectives tied to the softmax or pre-softmax layer of the net- work), retain high level semantic information of its corre- sponding clean sample. We use feature inversion to provide evidence for this observation.
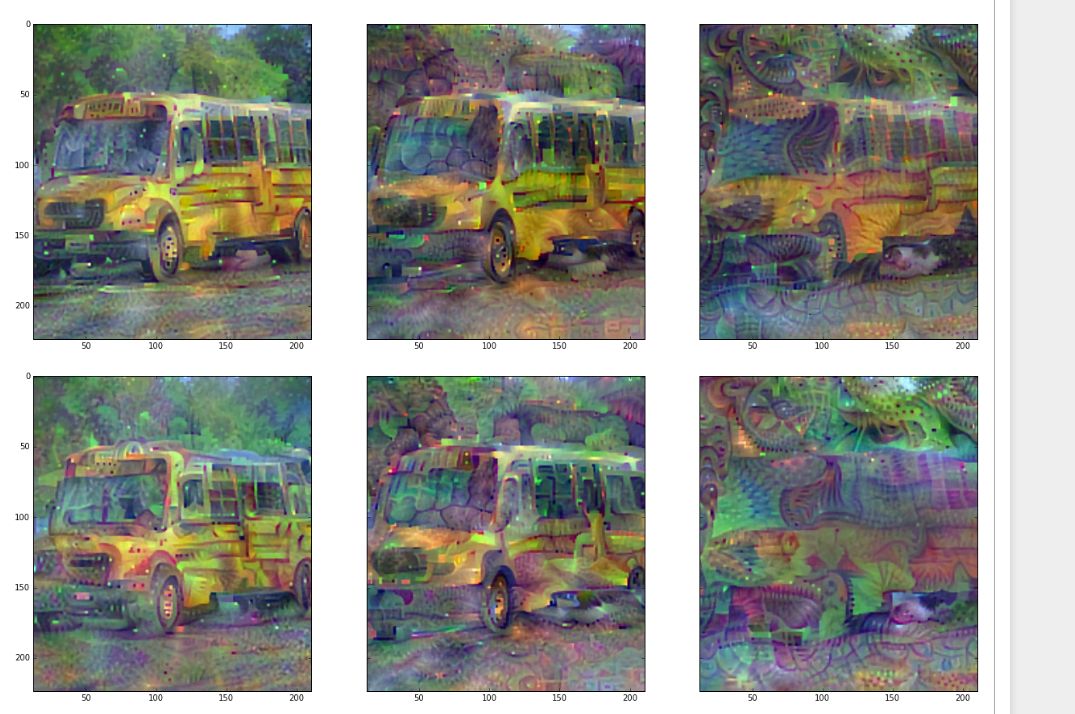
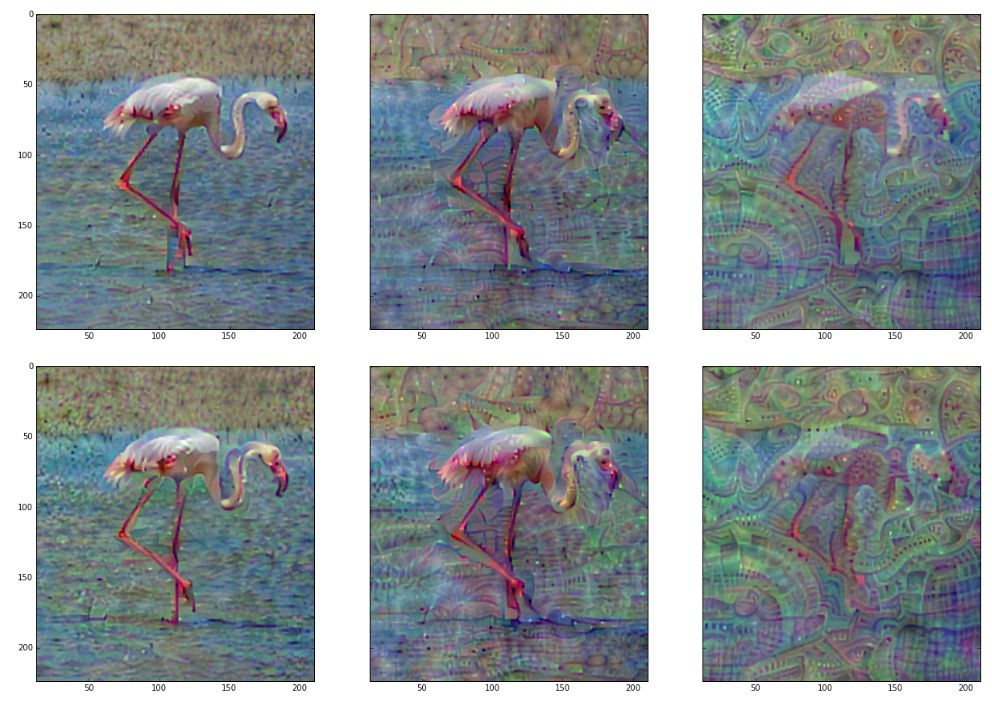
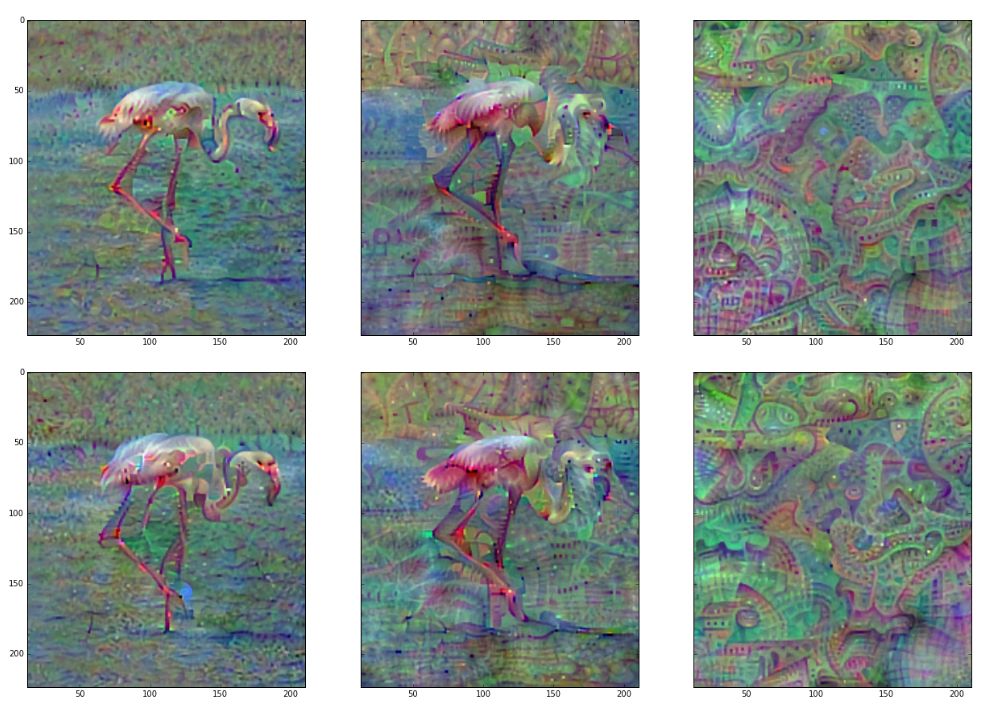
Figure 2 shows the feature inversion for different layers of VGG-16 architecture trained on ImageNet dataset,
(C) Fda Adversarial Sample’S Feature-Inversion
Figure 2. Feature Inversion: Layer-by-layer Feature Inversion of clean, PGD-LL-adversarial and FDA-adversarial sample. Note the significant removal of clean sample information in later layers of FDA-adversarial sample.
for the clean and its corresponding adversarial sample. From Fig. 2, it can be observed that the inversion of ad- versarial features of PGD-LL sample is remarkably similar to the inversion of features of clean sample. Fur- ther, in section 5.1, we statistically show the similarity be- tween intermediate feature representations of clean and its corresponding adversarial samples generated using differ- ent existing attack methods.
5.2 We
show that as a consequence of retaining clean sample infor- mation, these adversarial samples cause the model to either predict semantically similar class or to retain high (compar- atively) probability for the original label, while predicting a very different class. These observations are captured by us- ing the proposed metrics i.e., New Label Old Rank (NLOR) and Old Label New Rank (OLNR), and statistics such as fooling rate at k-th rank.
4.2. Proposed Evaluation Metrics
An attack’s strength is typically measured in terms of fooling rate , which measures the percentage (%) of images for which the predicted label was changed due to the attack. However, only looking at fooling rate does not present the full picture of the attack. On one hand, attacks such as PGD-ML may result in flipping of label into a se- mantically similar class, and on the other hand, attacks such as PGD-LL may flip the label to a very different class, while still retaining high (comparatively) probability for the orig- inal label. These drawbacks are not captured in the existing evaluation metric i.e., Fooling rate.
Hence, we propose two new evaluation metrics, New La- bel Old Rank (NLOR) and Old Label New Rank (OLNR). For a given input image, the softmax output of a C- way classifier represents the confidence for each of the C classes. We sort these class confidences in descending or- der (from rank 1 to C). Consider the prediction of the net- work before the attack as the old label and after the attack as the new label. Post attack, the rank of the old label will change from 1 to say ‘p’. This new rank ‘p’ of the old label is defined as OLNR (Old Label’s New Rank). Further, post attack, the rank of the new label would have changed from say ‘q’ to 1. This old rank ‘q’ of the new label is defined as NLOR (New Label’s Old Rank). Hence, a stronger attack should flip to a label which had a high old rank (which will yield high NLOR), and also reduce probability for the clean prediction (which will yield a high OLNR). These metrics are computed for all the mis-classified images and the mean value is reported.
4.3. Proposed Attack
We now present Feature Disruptive Attack (FDA), our proposed attack formulation explicitly designed to generate perturbation that contaminate and corrupt the internal rep- resentations of a DNN. The aim of the proposed attack is to generate image specific perturbation which, when added to the image should not only flip the label but also disrupt its inner feature representations at each layer of the DNN.
We first note that activations supporting the current predic- tion have to be lowered, whereas activations which do not support the current prediction have to be strengthened and increased. This can lead to feature representations which, while hiding the true information, contains high activations for features not present in the image. Hence, for a given ith layer li, our layer objective L, which we want to increase is
(4)
where li(˜x)Nj represents the Njth value of li(˜x), Si repre- sents the set of activations which support the current pre- diction, and D is a monotonically increasing function of activations l(˜x)Nj (on the partially ordered set R|Si|). We define D as the l2-norm of inputs li(˜x).
Finding the set Si is non-trivial. While all high activa- tions may not support the current prediction, in practice, we find it to be usable approximation. We define the support
(5)
where C is a measure of central tendency. We try various choices of C including median(li(x)) and inter-quartile- mean(li(x)).
(C)
Figure 3. Overview Image: From network (a), for each selected feature blob (b) we perform the optimization (d) as explained in equation 6. (c) shows a spatial feature, where the support set Si is colored red, and the remaining is blue.
C(h, w) (mean across channels) to be the most effective formulation. Finally, combining Eq. (4) and (5), our layer
(6)
We perform this optimization at each non-linearity in the network, and combine the per-layer objectives as follows:
(7)
Figure 3 provides a visual overview of the proposed method. In supplementary document we provide results for ablation study of the proposed attack i.e., different formula- tion of C such as median, Inter-Quartile-mean etc.
5. Experiments
In this section, we first present statistical analysis of the features corresponding to adversarial samples generated us- ing existing attacks and the proposed attack. Further, we show the effectiveness of the proposed attack on (i) im- age recognition in white-box (Sec.
5.2) And Black-Box
settings (shown in supplementary document), (ii) Feature- representation based tasks (Sec. 5.4) i.e., caption genera- tion and style-transfer. We define optimization budget of an attack by the tuple (ϵ, nbiter, ϵiter), where ϵ is the L∞ norm limit on the perturbation added to the image, nbiter defines the number of optimization iterations used by the attack method, and ϵiter is the increment in the L∞norm limit of the perturbation at each iteration.
Cosine Distance
Cosine distance between features of clean and its
PgdCw
Figure 4. Cosine distance between features of clean image and its corresponding adversarial sample, at different layer of P- NasNet architecture.
5.1. Statistical Analysis Of Adversarial Features
In this section, we present the analysis which fundamen- tally motivates our attack formulation. We present various experiments, which posit that attack formulations tied to pre-softmax based objectives retain clean sample informa- tion in deep features, whereas FDA is effective at removing them. For all the following experiments, all attacks have been given the same optimization budget (ϵ = 8, nbiter = 10, ϵiter = 1). Reported numbers have been averaged over 1000 image samples.
First, we measure the similarity between intermediate feature representations of the clean and its corresponding adversarial samples generated using different attack meth- ods. Figure 4, shows average cosine distance between in- termediate feature representations of the clean and its cor- responding adversarial samples, for various attack methods on PNasNet architecture. From Fig. 4 it can be ob- served that for the proposed attack, feature dis-similarity is much higher than to that of the other attacks. The signif- icant difference in cosine distance implies that contamina- tion of intermediate feature is much higher for the proposed attack. We observe similar trend in other models at different optimization budgets (ϵ, nbiter, ϵiter) as well (refer supple- mentary).
Now, we measure the similarity between features of clean and adversarial samples at the pre-logits layer (i.e., input to the classification layer) of the network. Apart from cosine distance, we also measure the Normalized Rank Transformation (NRT) distance. NRT-distance represents the average shift in the rank of the kth ordered statistic ∀k.
Primary benefit of NRT-distance measure is its robustness to outliers. Table 1, tabulates the result for pre-logit output for mul- tiple architectures. It can be observed that our proposed attack shows superiority to other methods. Although the pre-logits representations from other attacks seem to be cor-
Related Journal Articles & DOI Links
Selected peer-reviewed publications relevant to 12 Lead ECG Acquisition. Click the DOI to access the full paper (may require institutional access).
-
1. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
IEEE Journal of Biomedical and Health Informatics
https://doi.org/10.1109/JBHI.2020.2981234 -
2. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Medical & Biological Engineering & Computing
https://doi.org/10.1007/s11517-020-02145-6 -
3. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
IEEE Transactions on Biomedical Engineering
https://doi.org/10.1109/TBME.2019.2895762 -
4. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Frontiers in Bioengineering and Biotechnology
https://doi.org/10.3389/fbioe.2020.00123 -
5. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Biosensors and Bioelectronics
https://doi.org/10.1016/j.bios.2021.112345 -
6. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
Computers in Biology and Medicine
https://doi.org/10.1016/j.compbiomed.2021.104567 -
7. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Nature Communications
https://doi.org/10.1038/s41467-020-12345-6
Why Choose Us?
Bangalore guidance for robotics, Spectre and autonomous systems projects.
Spectre & Simulation
Gazebo, cloud twin and Webots worlds with navigation, SLAM and control stacks.
Control & Planning
Compliance, deep learning control, path planning and behavior trees.
Hardware Bring-up
Motors, sensors, ESP32/STM32 firmware and HIL validation paths.
Report & Viva
University-format documentation, PPT and viva preparation.
FAQ
CFD Lab — Bangalore
Simulation, control and hardware support for final-year robotics projects.
Stacks
Worlds
Digital Twin
Control
Robots
Offline
Bring-up