Chiara Bartolozzi1 , And Arren Glover1
Istituto Italiano di Tecnologia, Via Morego 30 16163 Genova, Italy
{Mikihiro.Ikura,Luna.Gava,Jiahang.Wu,
Abstract. Event cameras provide low-latency, high temporal resolution perception for real-time vision tasks such as robotics.The novel circuitry (i.e. asynchronous, independent pixels) that enables these advantages also introduces new algorithmic challenges. Velocity-invariant represen- tations alleviate missing observations under slow motion and motion blur under fast motion, but most discard temporal information by converting events into image-like representations. We propose Set of Centre Ac- tive Receptive Fields (SCARF), a real-time velocity-invariant represen- tation that preserves raw events while consistently handling fast motion, stationary scenes, and independently moving objects. SCARF achieves state-of-the-art performance in both computational efficiency and repre- sentation quality.
Keywords: Event Camera · Velocity Invariant Representation · Real-
Introduction
Event cameras respond only to change in light and output a sparse, asynchronous stream of pixel activations. They produce low-latency and high dynamic range visual data with lower processing requirements compared to traditional cameras.
Potential applications exists in applications that have power and processing con- straints, such as mobile robotics, space, and wearable devices . As the data are sequentially produced and processed, rather than having the full frames of pixel readings at a single point in time, new algorithmic challenges must be addressed.
Event representations are a common method to create pixel neighbourhoods that are fundamental to visual processing, and also allow downstream applications to be decoupled from the exact rate of data being produced .
Event batches are a representation that capture the rich spatio-temporal in- formation of the event stream that can then be encoded as a tensor or directly processed . Motion-blur that occurs due to the temporal ac- cumulation can be compensated for, e.g. , or implicitly within a network .
However batches assumes the relevant information occurs within a hard limit, typically 10-100 ms. In the wild, situations such as the camera stopping can
2
M. Ikura et al.
From Fast Moving Camera At
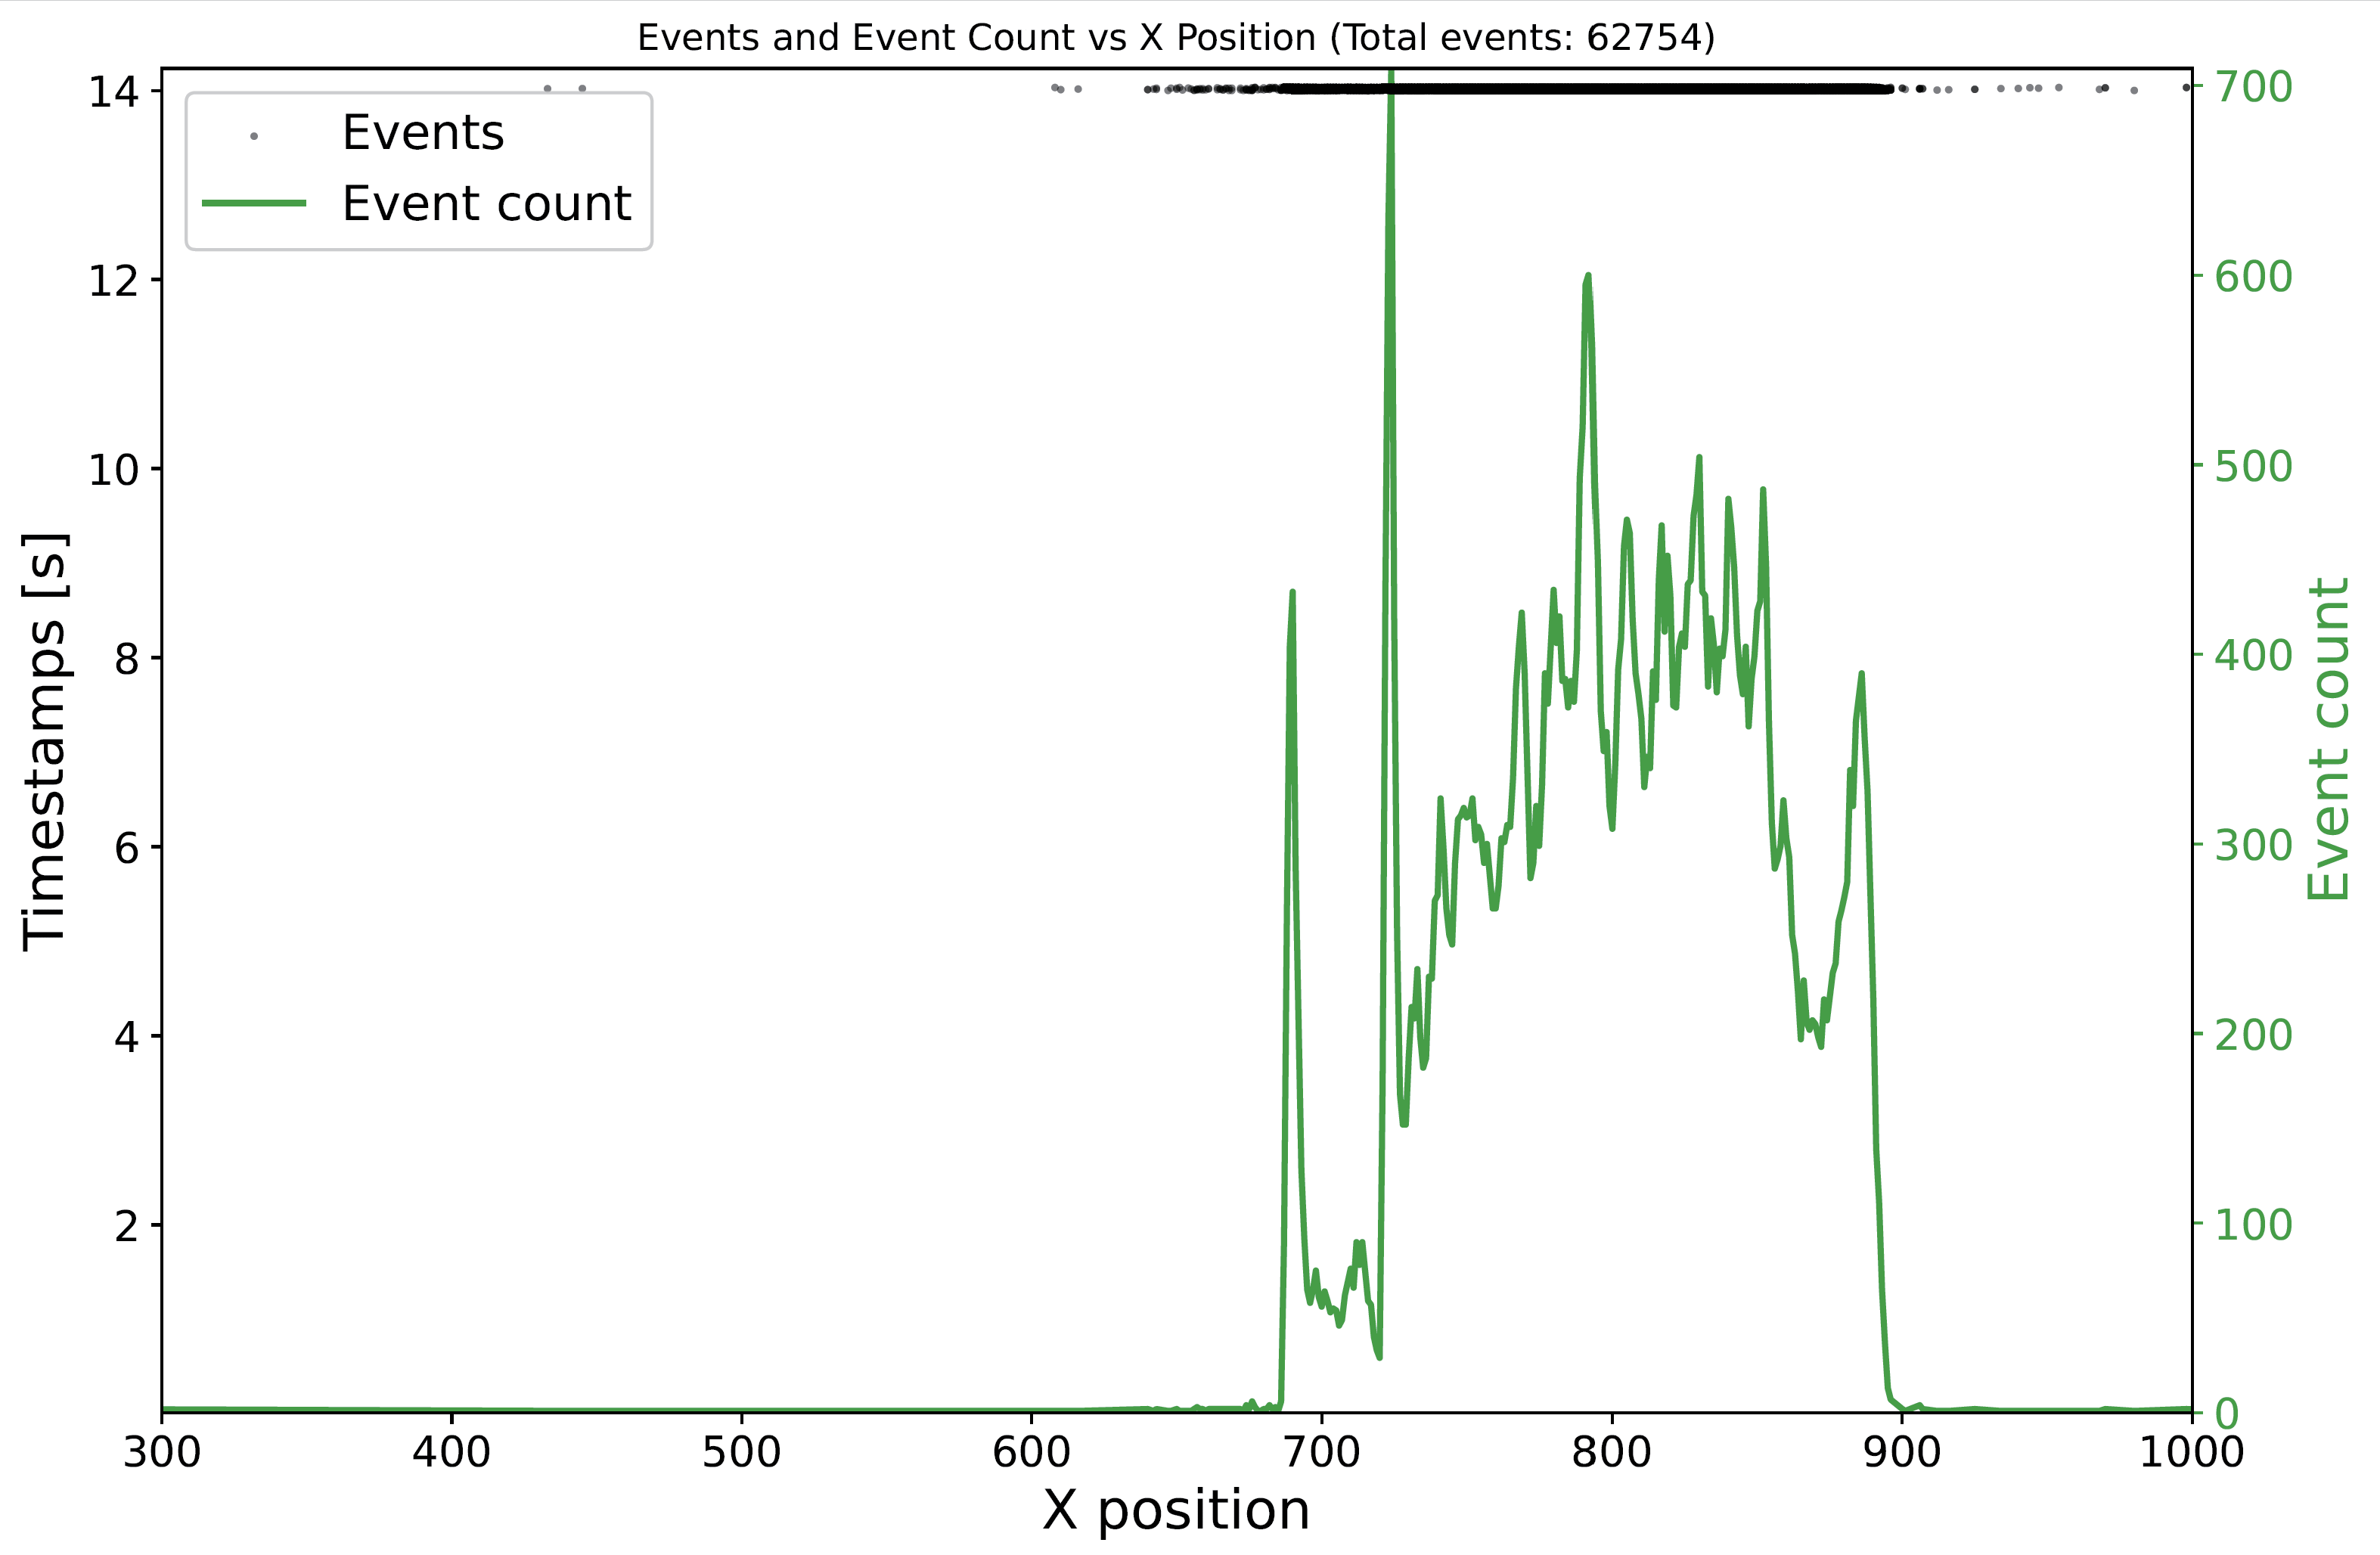
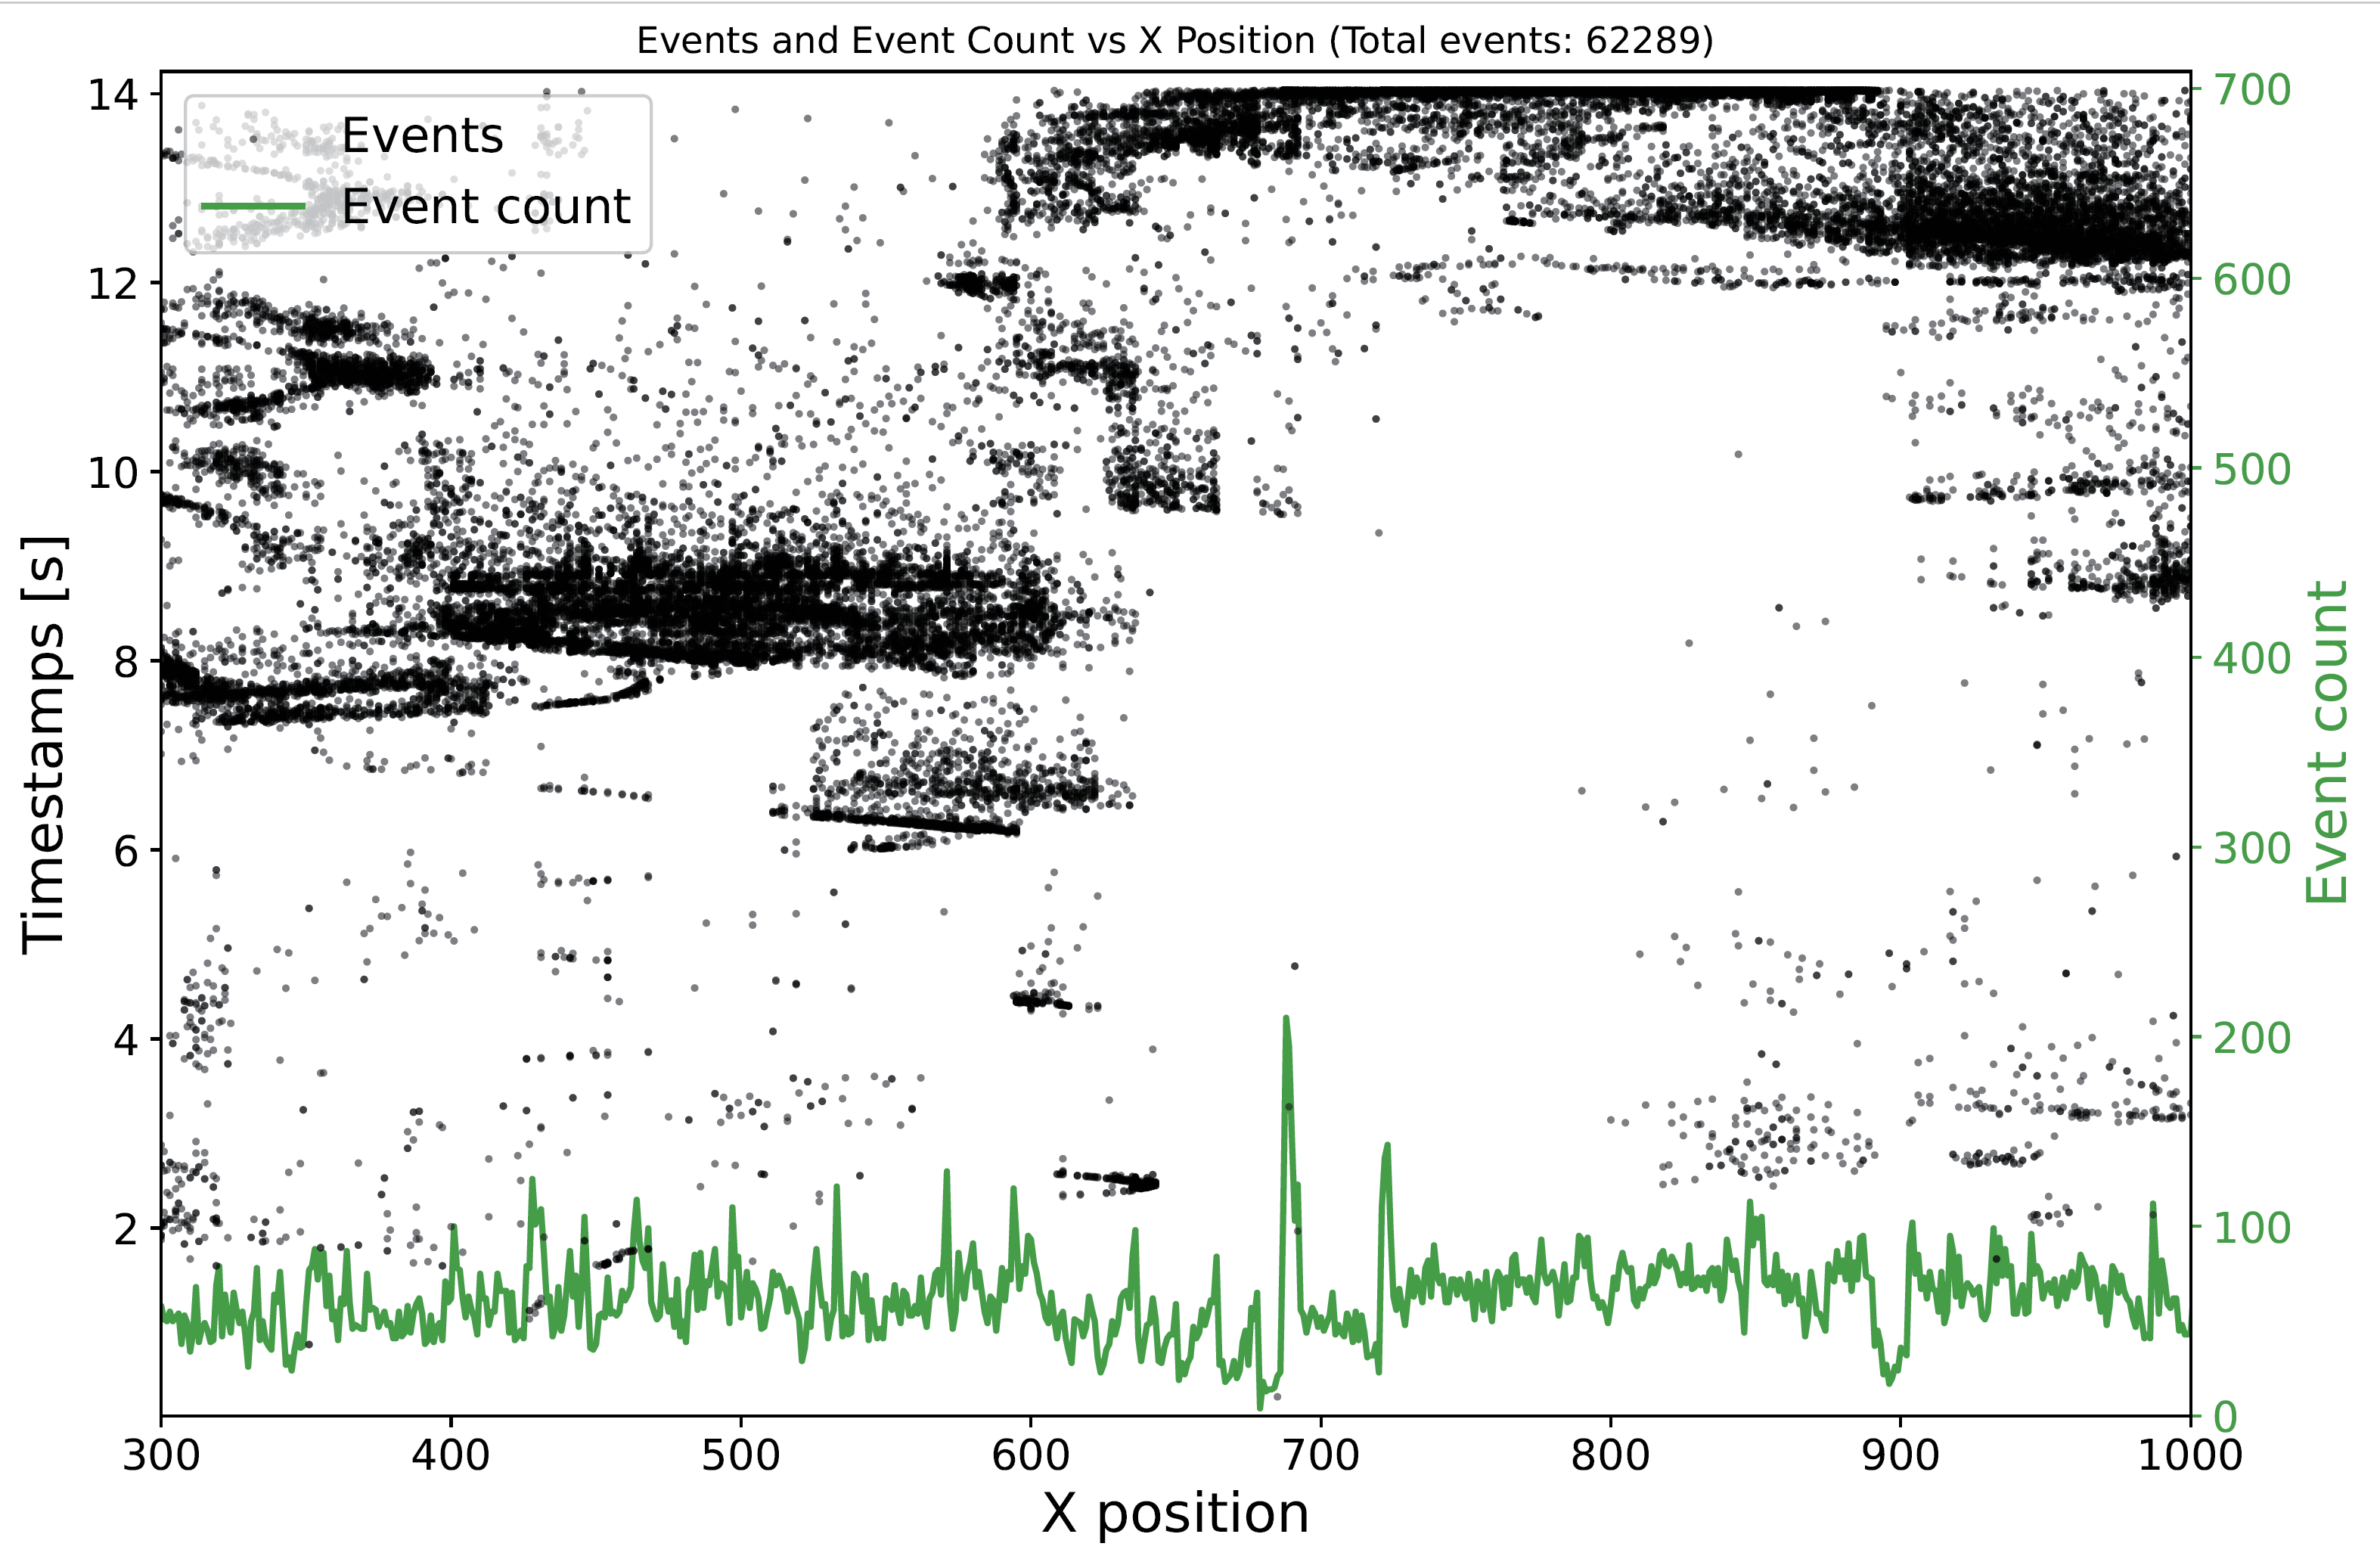
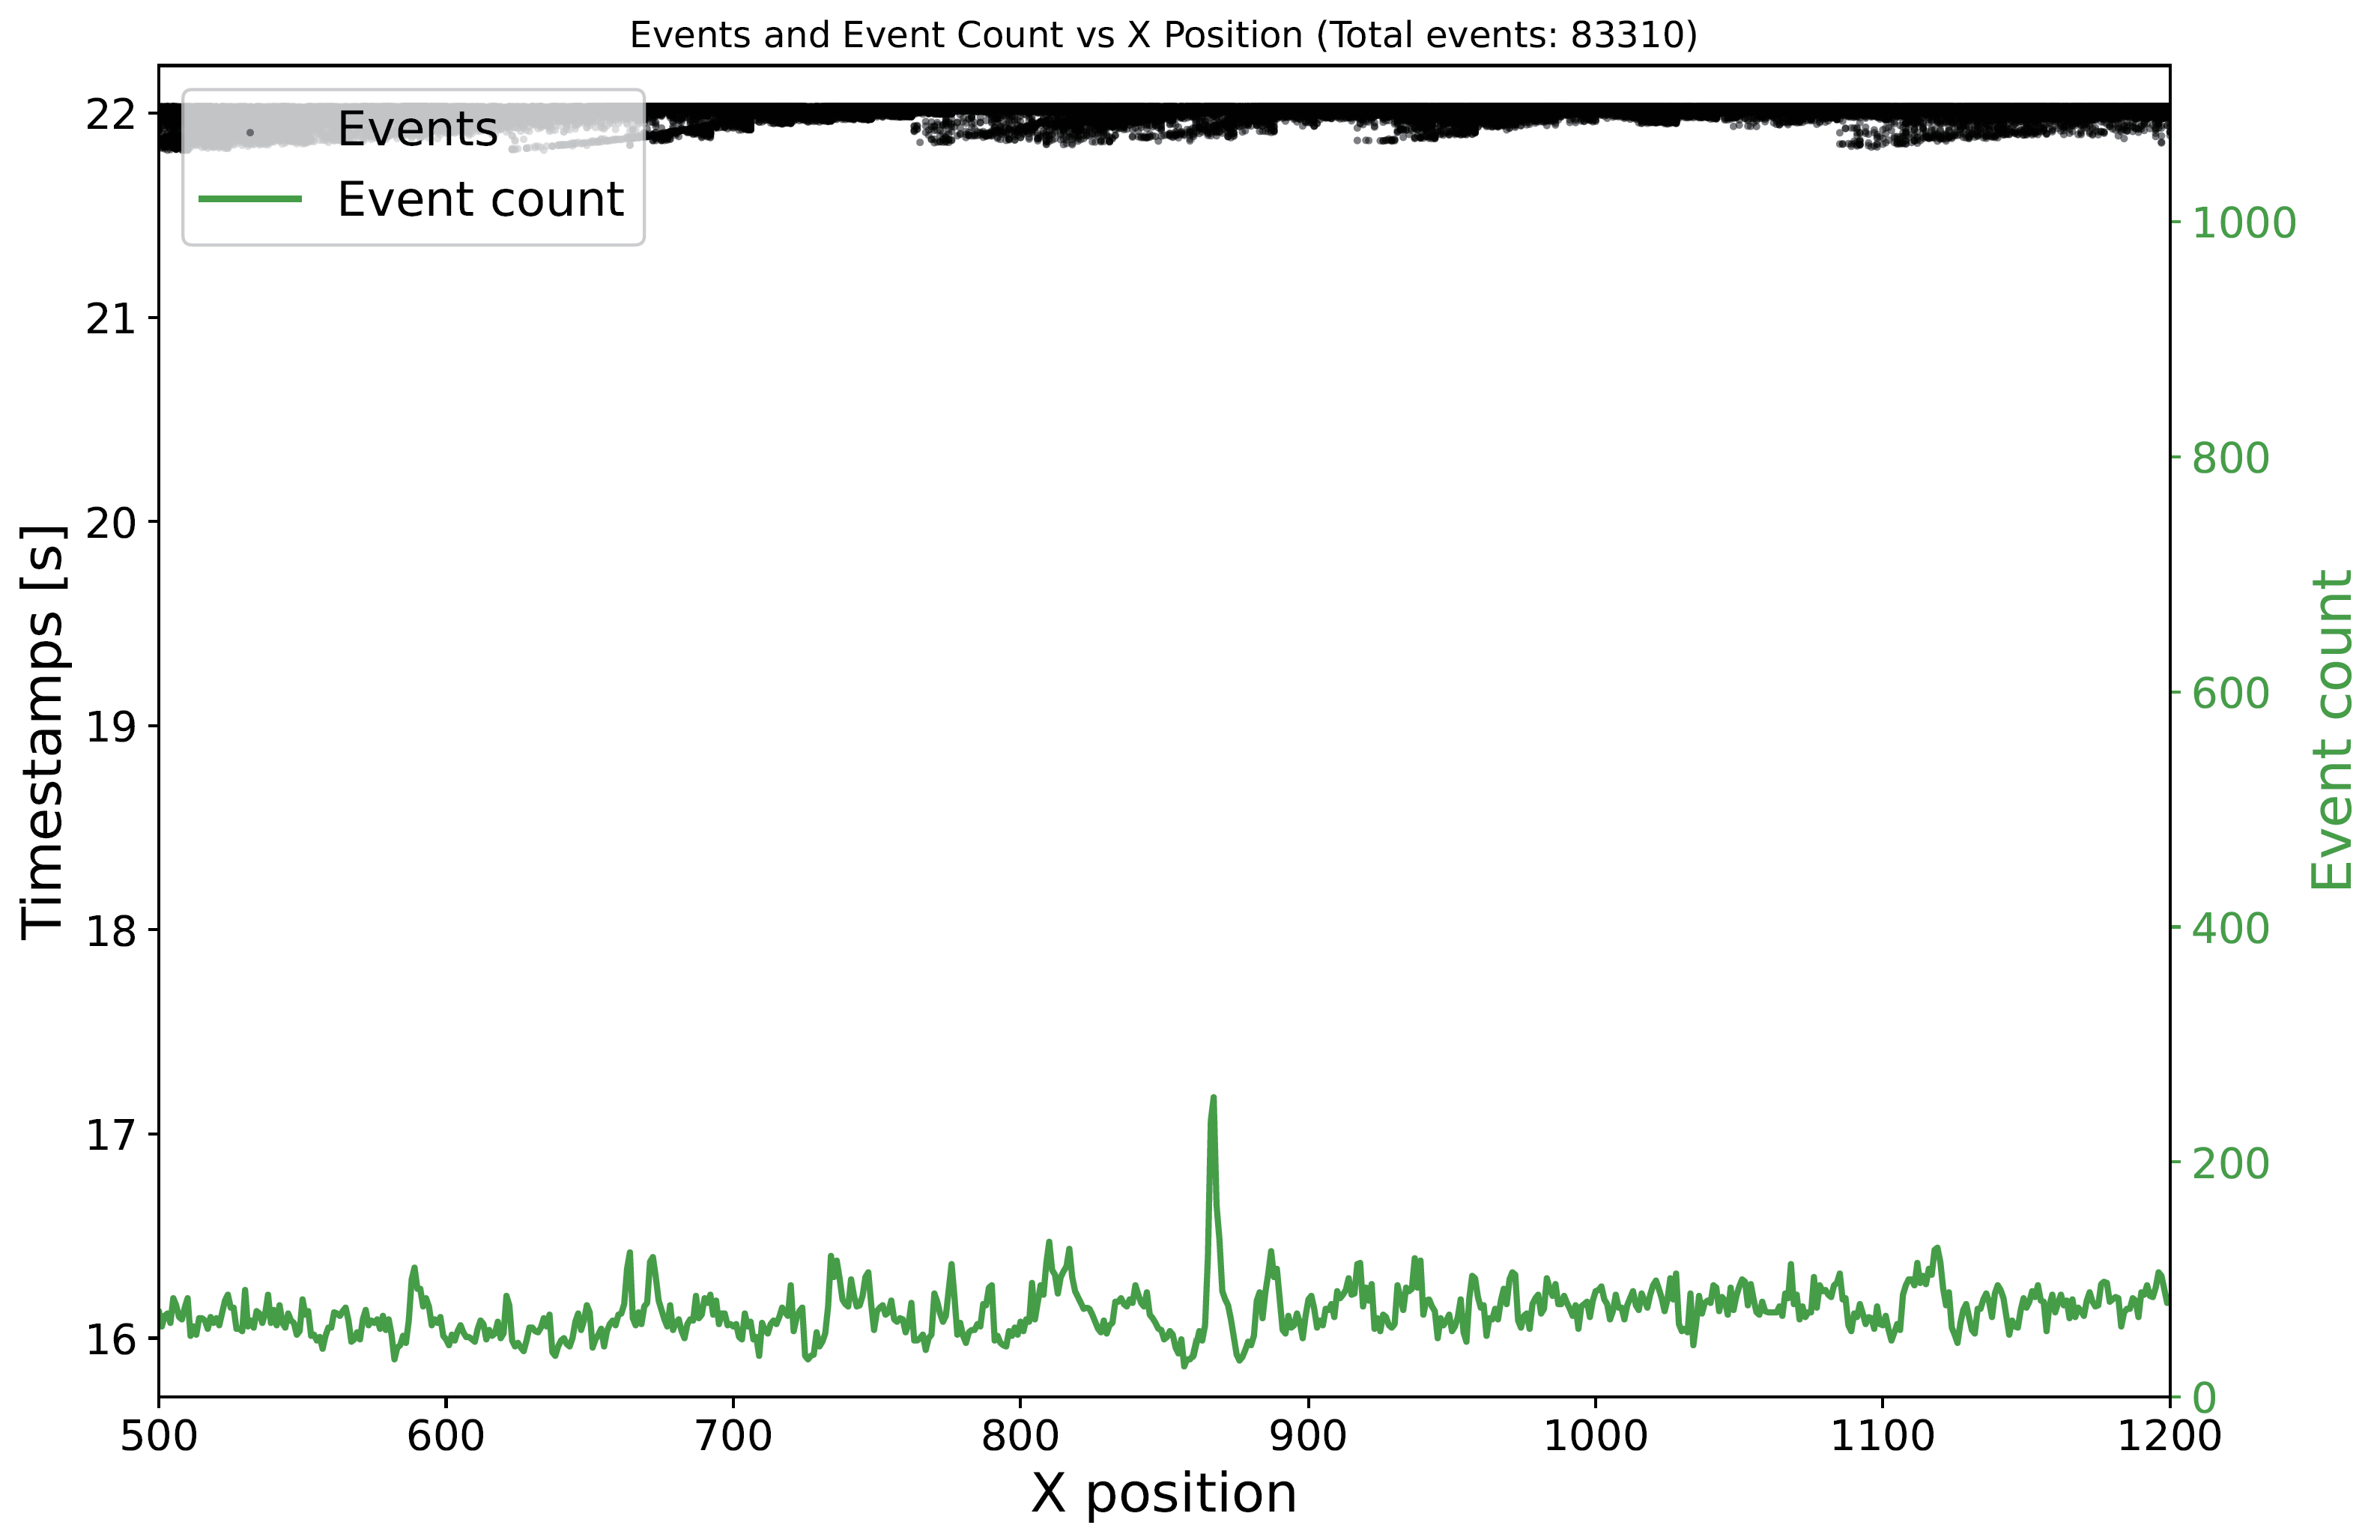
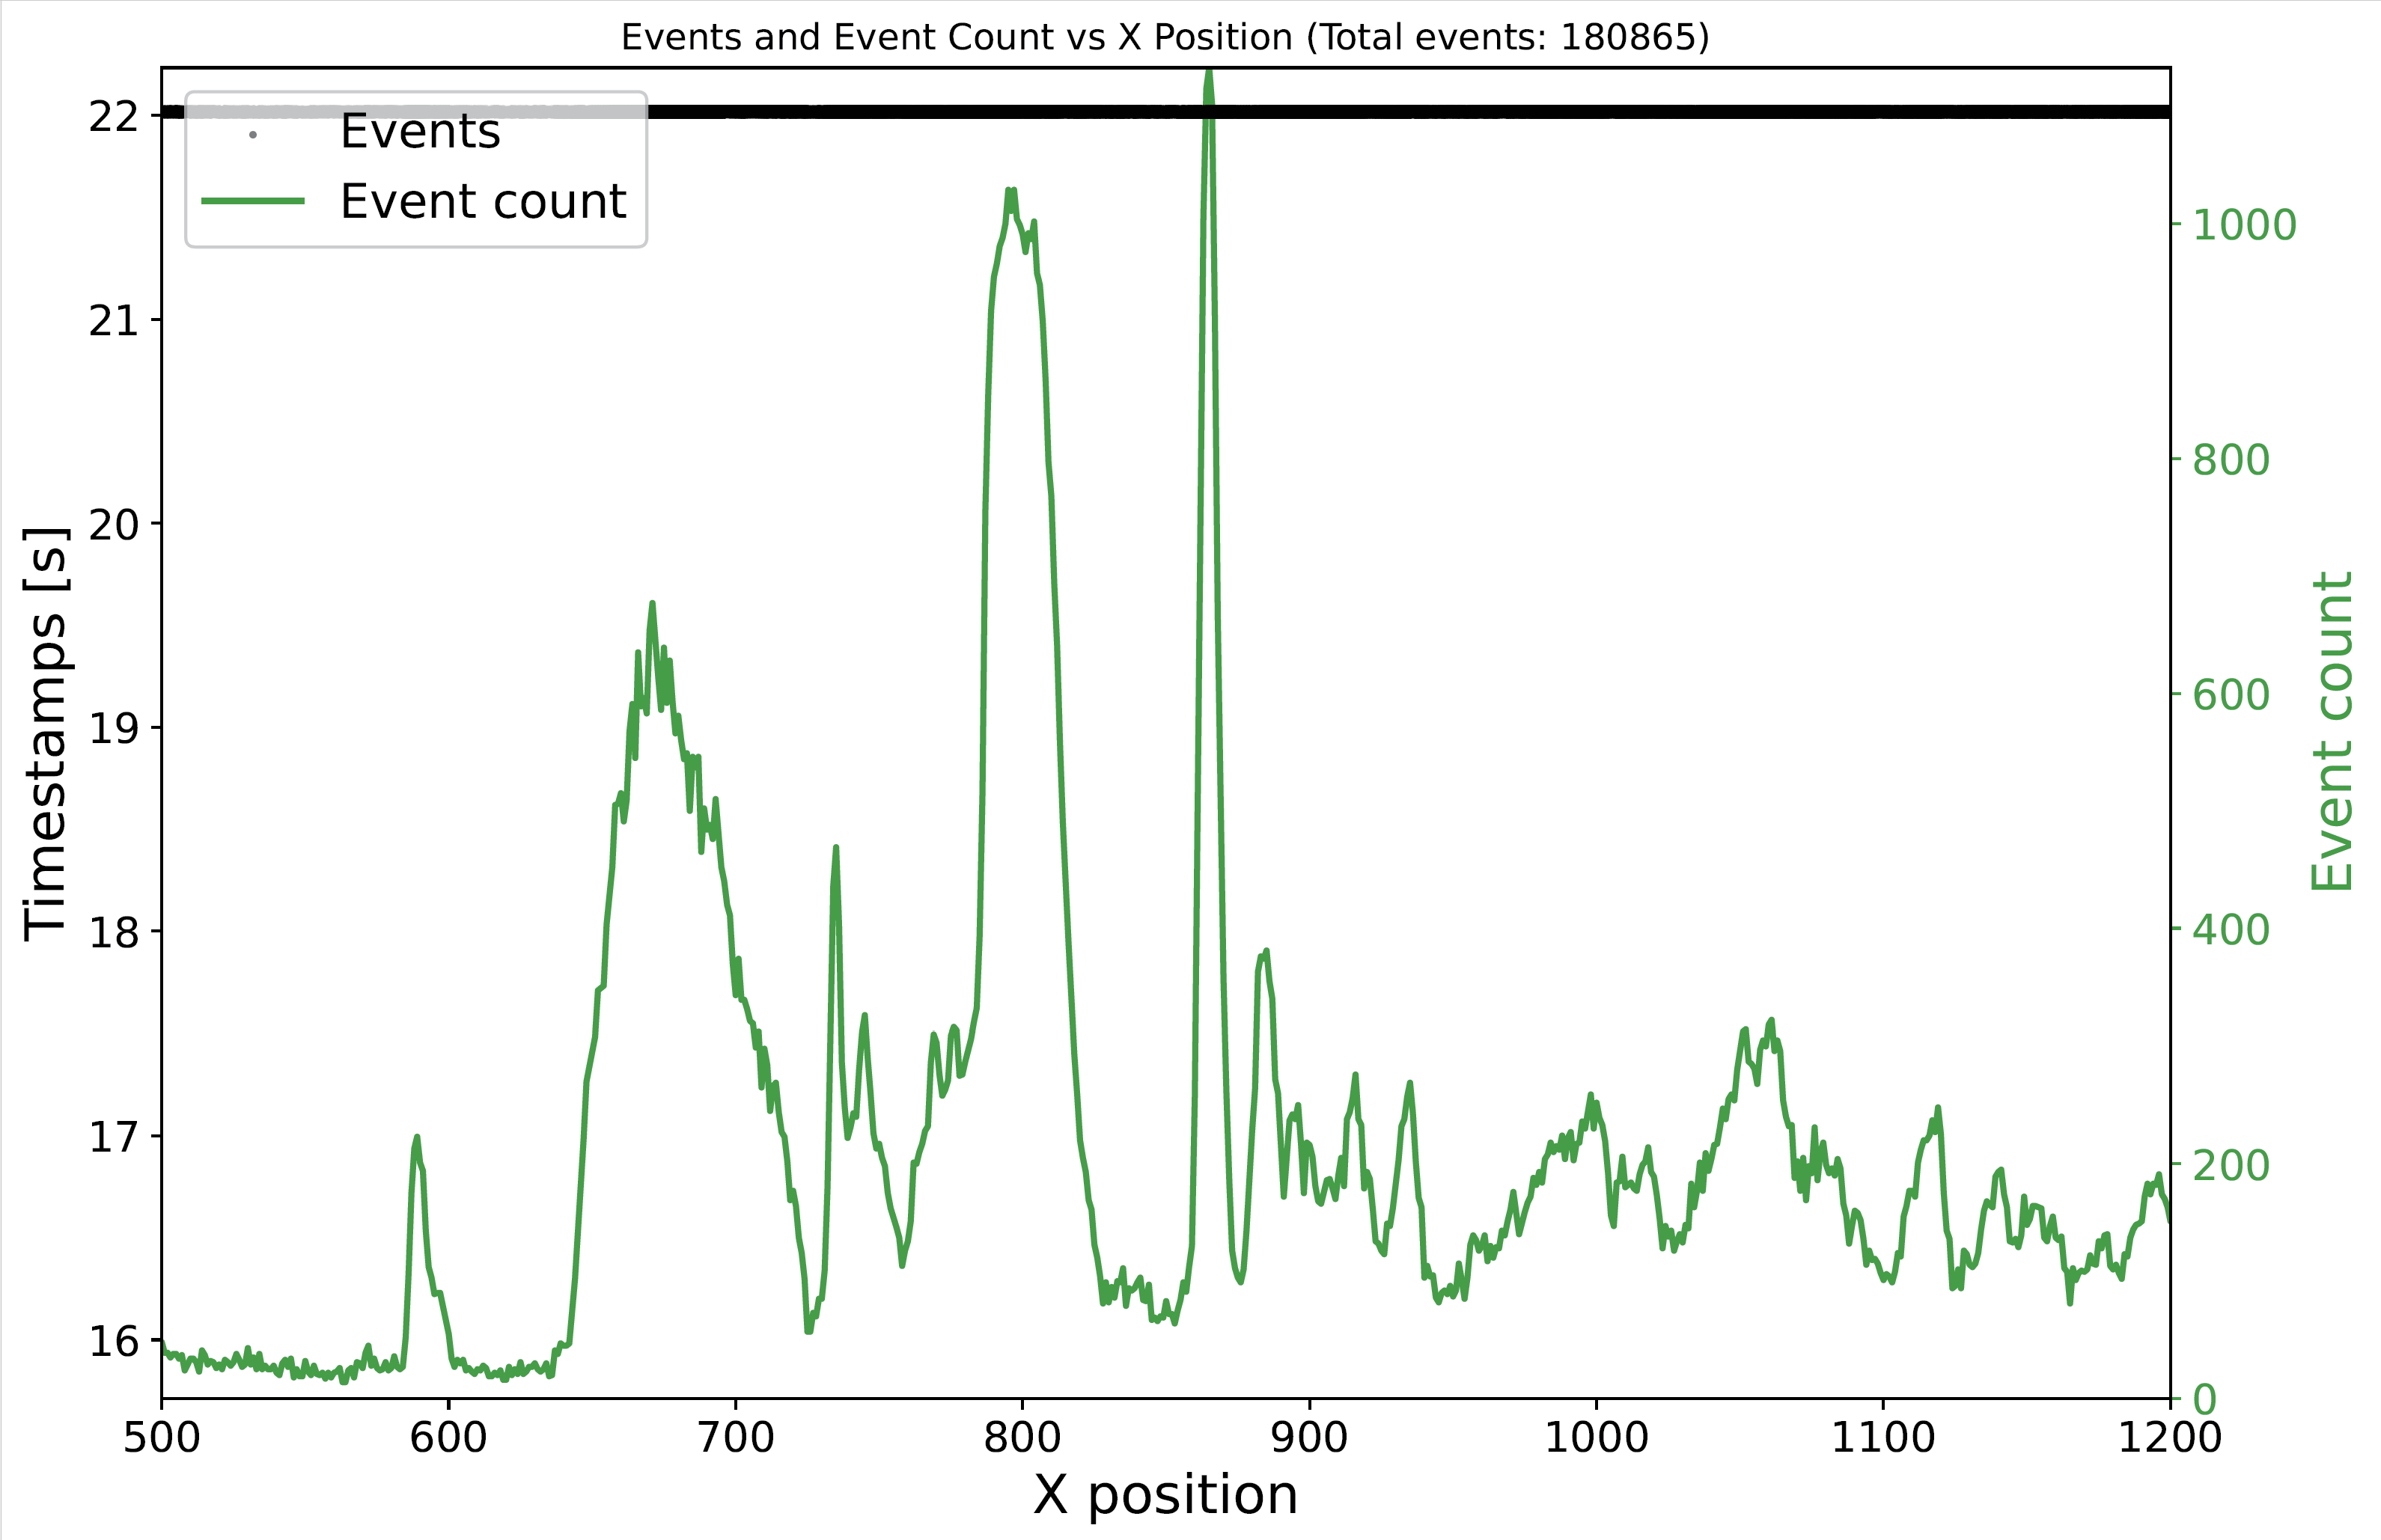
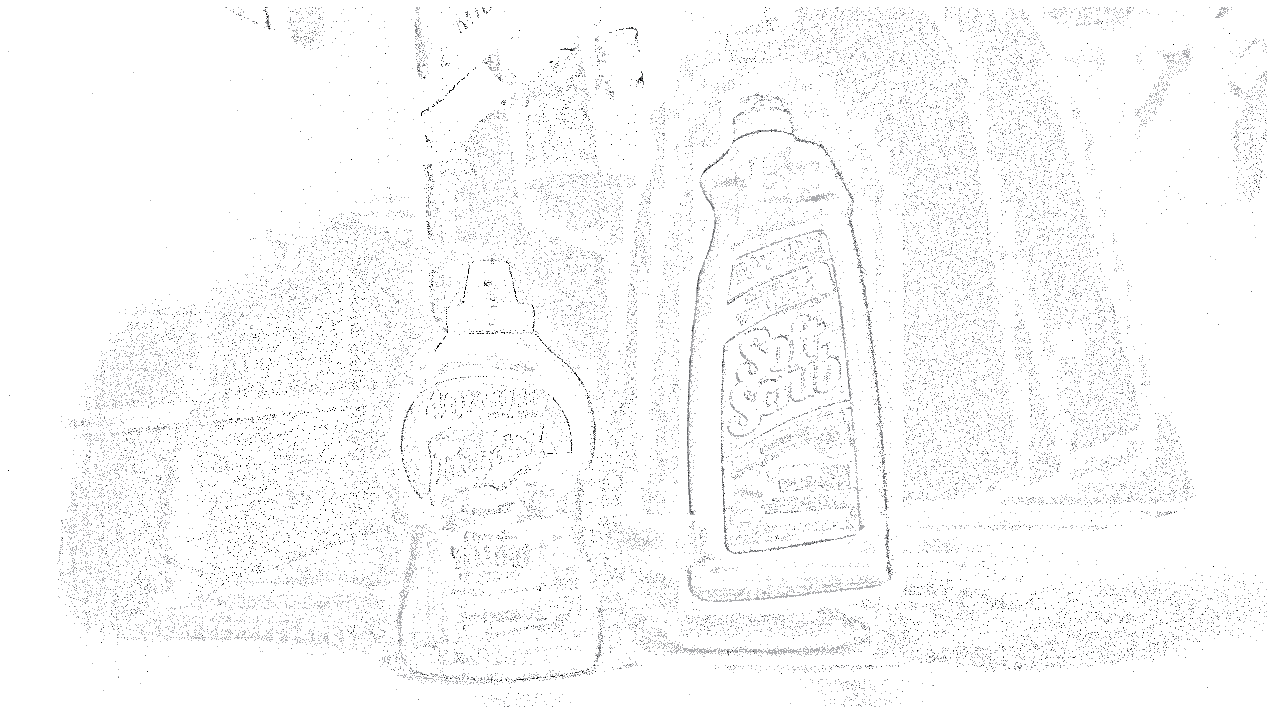
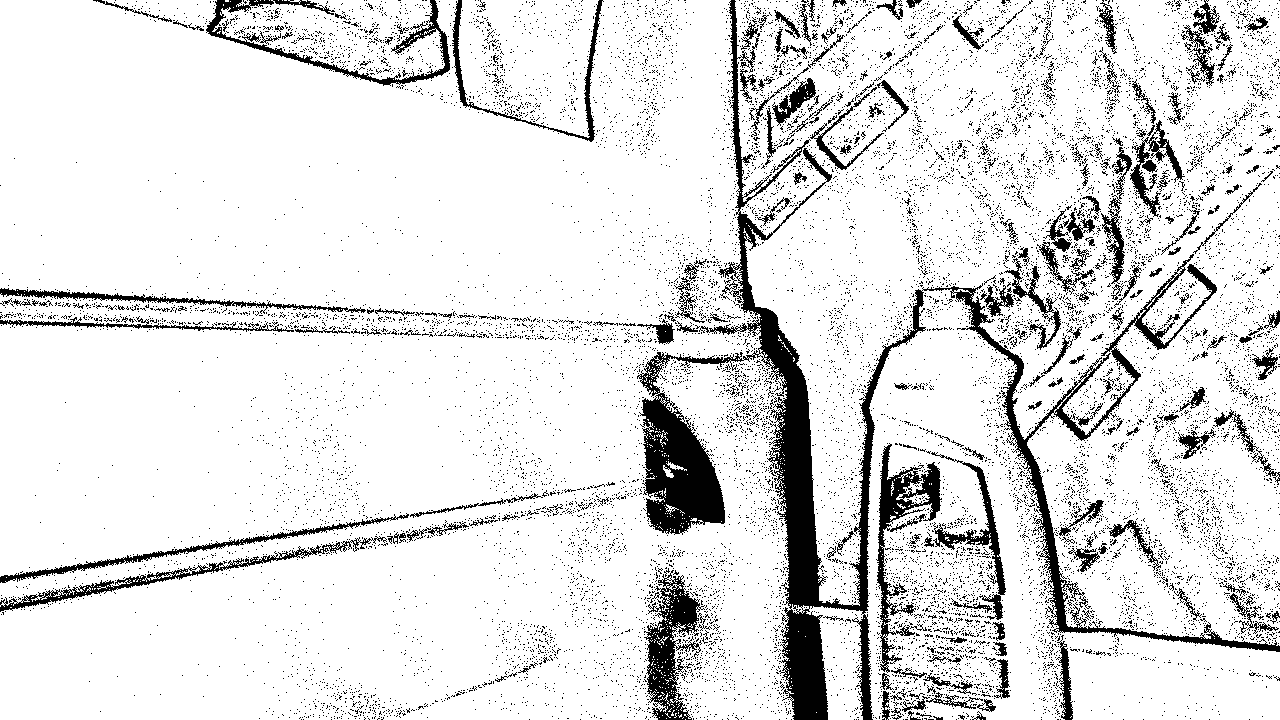
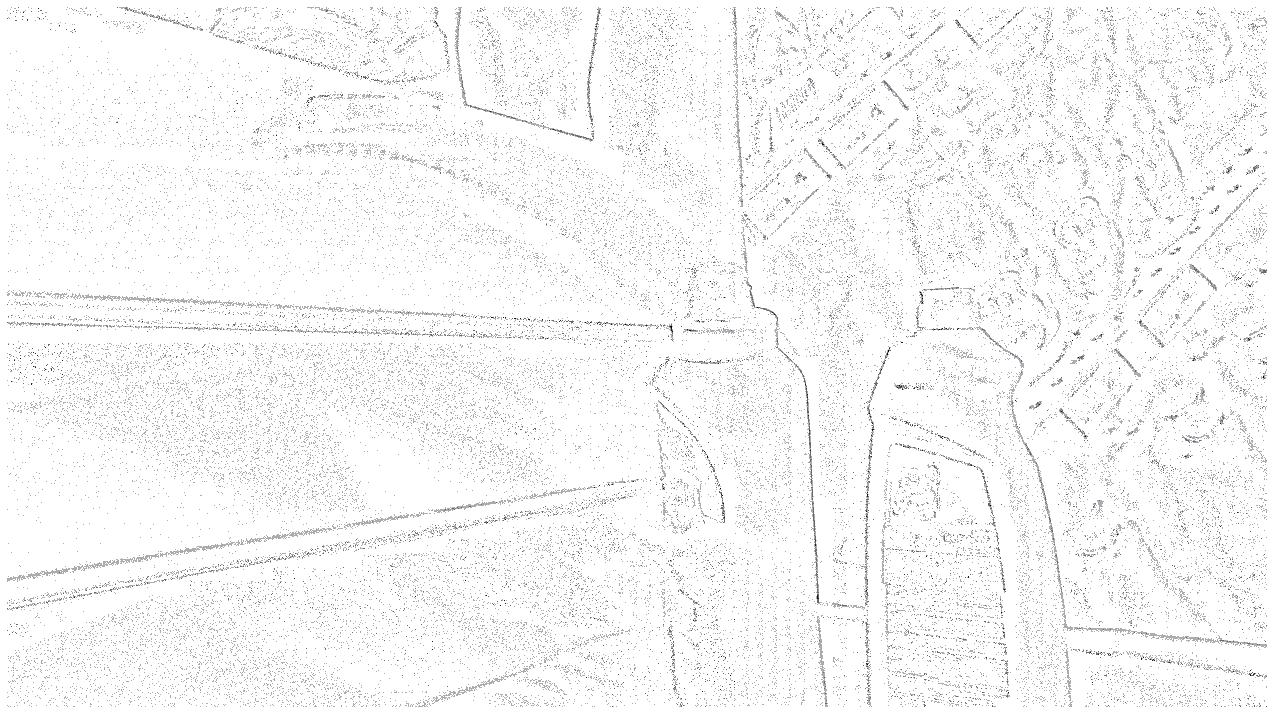
Fig. 1: Velocity-independence of SCARF compared with a fixed temporal window (33 ms). Top: event-rate transition of the dataset, where two bottles and the event camera move independently. Middle: Fixed temporal window and SCARF. Bottom: event dis- tributions (black) and event counts (green) along the x-axis. (a) The event rate varies significantly with scene motion. (b) The fixed temporal window fails to represent the slowly moving bottle due to insufficient events, whereas SCARF preserves a consis- tent representation by retaining older events. (c) For fast motion, the fixed temporal window introduces motion blur due to excessive events, while SCARF maintains sharp edges through consistent event storage.
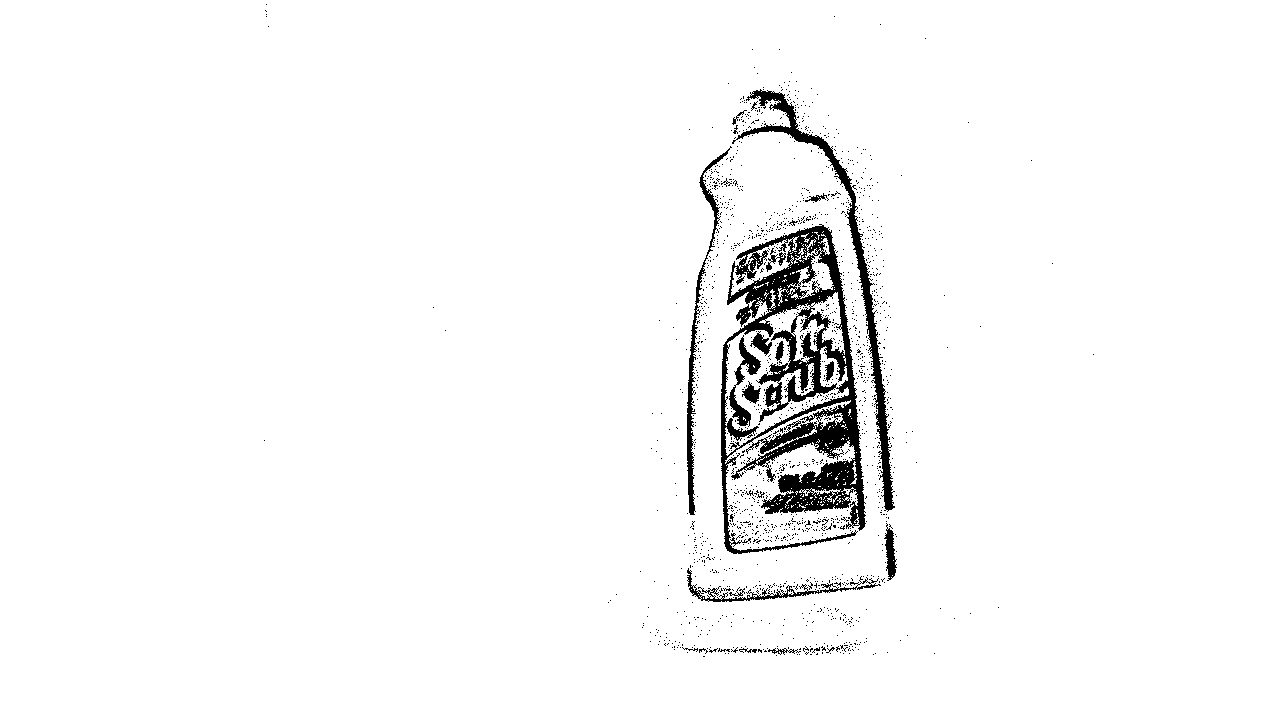
cause algorithms to fail as data no longer contains the information expected (shown in Fig. 1 (b)). On the other hand, exceedingly fast motion can also break the velocity consistency that is assumed algorithms (shown in Fig. 1 (c)). Dy- namic batch sizes cannot solve the common case in which there is more than one velocity profile - in this case an object that stops will still disappear from view.
Velocity invariant representations [1, 2, 8, 9, 12, 16–18] can be used to more robustly represent scenes with various motions. Combined with event-by-event, continual updates of the representation, the temporal cut-off is removed such that fast, slow, and stopped objects are represented with consistency. Such rep- resentations are especially compatible when motion isn’t a major feature of the task, such as feature [8, 16, 18], object , or human pose recognition, but most modify the visual data as some function of the raw events - resulting in a 2D array with arbitrary values. The raw events and timestamps are discarded, and any specific tensor encoding for a downstream task most likely cannot be achieved.
An Event Preserving Velocity Invariant Representation for Event Cameras
3
The proposed method, Set of Centre Active Receptive Fields (SCARF), is a representation with memory that achieves velocity consistency and also preserves raw events as well as timing information as shown in Fig. 1 (b, c). SCARF is also lightweight, enabling real-time processing with high event resolution and event rates. The representation consists of dividing the sensor space into overlapping patches each with a circular buffer of a fixed amount of events. The intuition is that a fixed amount of texture is not valid for the full sensor array, but becomes more valid as the patch size decreases, and secondly that the overlapping region allow data to pass from patch to the next, as an object or edge passes across the scene. The paper describes the SCARF algorithm, compares to batch and velocity invariant representations, as well as performing an ablation study in regards to two downstream tasks: edge extraction and stereo depth estimation.
Related Work
Event cameras produce events that correspond to individual camera pixels chang- ing their measured light level, and fire sparsely and asynchronously. Processing data in batches can lead to speed and performance improvements compared to individual event processing, but isn’t robust to velocity variation, as illustrated in Fig. 1. Event surfaces instead aim to integrate individual events into a data structure to achieve some useful benefits, such as event memory, maintaining a fixed size data representation, and processing over pixel neighbourhoods. The Time Surface (TS) or Surface of Active Events (SAE) explicitly represents timing information by storing a 2D array, T, with identical size as the camera
(1)
As the SAE achieves different representations for cameras or objects moving at different speeds, it is not velocity invariant. Tasks such as object recognition and pose estimation are sensitive to velocity and velocity invariance can make them more robust.
“Event representation” can refer to a wide range of topics including: how to encode data in a 2D/3D space for input into a neural network (e.g. Voxel- Grid or TORE ) or representing the data with features (e.g. Hots or Hats ). These representations handle data encoding specifically for the network or downstream algorithm, but don’t modify which data is used for the encoding. Typically a fixed size batch is used, which requires that the item of interest to have moved within the defined period. In this paper, we focus on algorithms which define which data should be encoded, specifically those that achieve velocity invariance. Many of these algorithms modify the data in some way, possibly making them incompatible with encoding methods, and propose that algorithms which both maintain raw events as well as achieving some in- variance to velocity achieve the best of both worlds. We define the following characteristics for velocity invariant representations:
4
M. Ikura et al. Table 1: A summary of state-of-the-art velocity invariant event-based representations.
Events
– Motion Blur: typically all velocity invariant representations aim to remove motion blur. – Persistent/Time Limited: some algorithms integrate all data incremen- tally, while others consider only a fixed length history. Time limited cannot achieve velocity invariance for stationary scenes.
– Global/Local: some algorithms consider a single velocity for the global scene, while others handle multiple different local velocities. – Integration Metric: the metric used to integrate data can generally come from a time parameter, a count of events, or recording the event order.
– Output: how is the data represented and what is available for downstream processing. – Event throughput: how much processing is required per event.
– Generation Speed: how fast processing is required when querying the sur- face. – Accuracy: how well the surface captures the features required for a down- stream task.
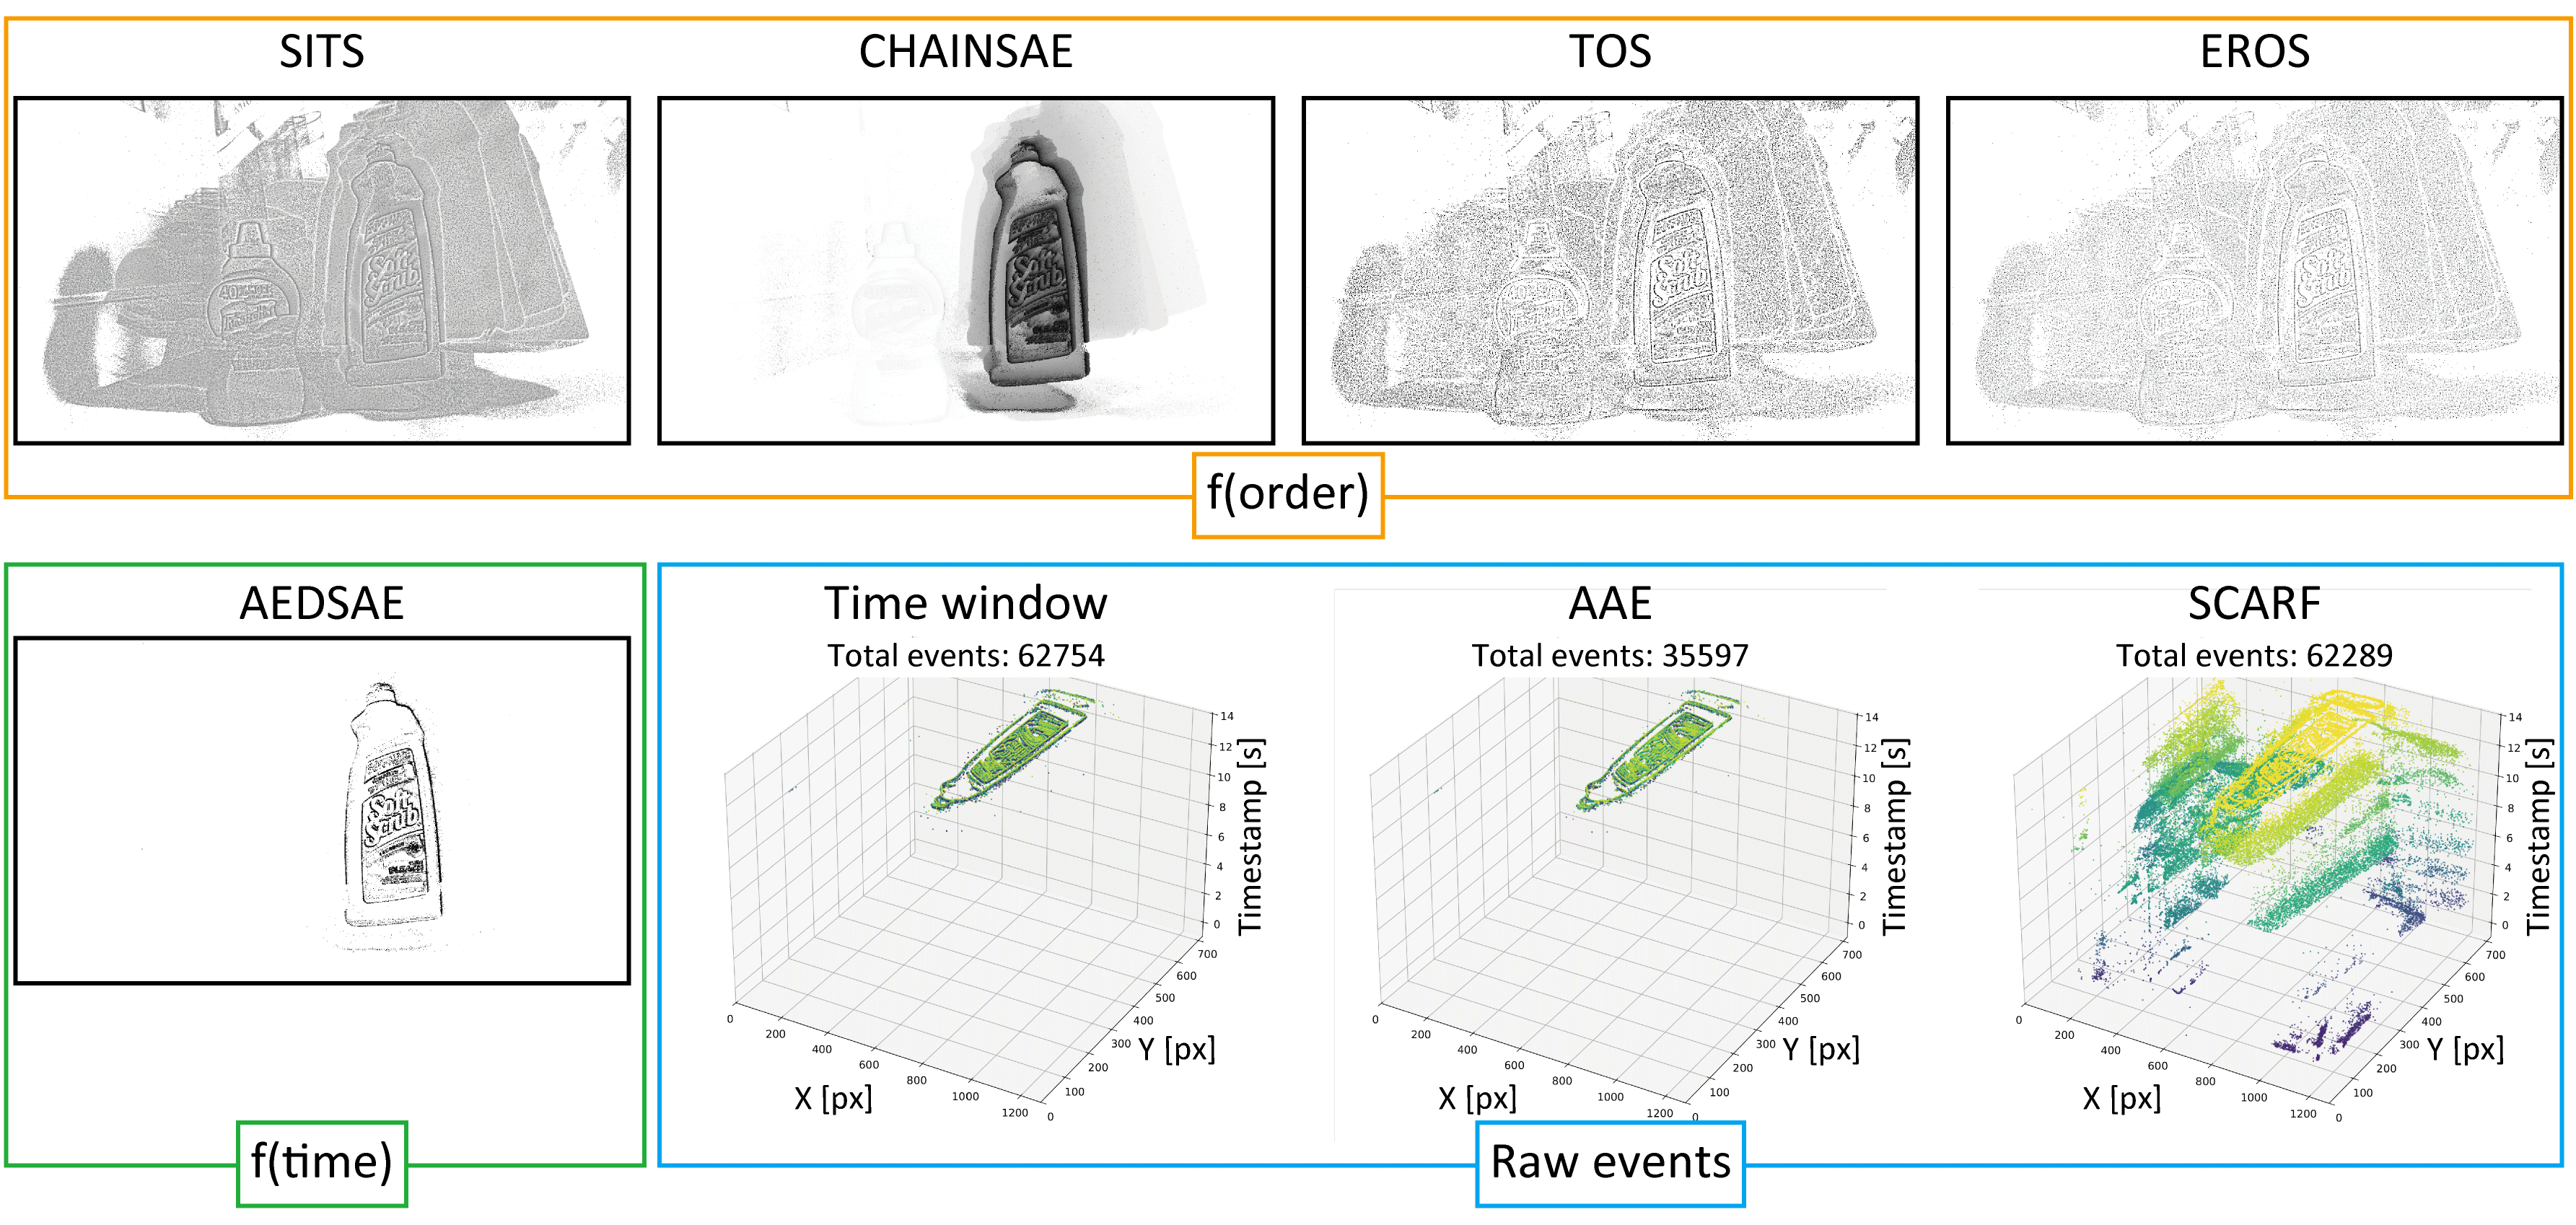
A summary and the output visualization of each algorithm according to these properties is shown in Table 1 and Fig. 2, respectively, while an analysis of speed, throughput and accuracy forms the results of this paper.
The first velocity invariant representation was the Speed Invariant Temporal Surface (SITS) , which records the pseudo-ordering of event arrival in local regions without requiring an expensive sorting operation over the entire sensor array. SITS introduced the idea of velocity invariance through event ordering as the same order of events theoretically occurs when moving quickly or slowly. The input is continuous, allowing long term memory, and local, allowing multiple simultaneous velocities. However, the algorithm performed pixel updates per event, reducing throughput, and also resulted in “ghosting” as targets moved.
The Chain Surface of Active Events (CHAIN-SAE) proposed to maintain the precise event order in a quickly updatable linked-list, with a precomputed non-linear function to reduce ghosting. The CHAIN-SAE was fast to compute, with long term memory, but due to its global nature could only robustly represent a single velocity. The parameters of the precomputed function should have also been modified based on the texture in the scene, making it effective in driving scenarios but unsuitable for irregularly motion of the camera or objects. While An Event Preserving Velocity Invariant Representation for Event Cameras
5
Fig. 2: Output visualizations of state-of-the-art velocity-invariant event representa- tions. SITS, CHAIN-SAE, TOS, and EROS construct 2D representations based on event order, while AED-SAE uses event timestamps. These methods discard the orig- inal timestamps and raw events in their final outputs. In contrast, AAE and SCARF preserve raw events while achieving velocity-invariant representations.
the authors proposed sub-regions CHAIN-SAE for smaller regions there existed no means to combine sub-regions, thereby requiring a-priori knowledge of object size and location.
The Threshold Ordinal Surface (TOS) used local region updates similar to SITS and used a discrete cut-off function to reduce ghosting, but produced an almost binary image. To reduce artifacts introduced by the discrete function, the Exponentially Reduced Ordinal Surface (EROS) instead used a smooth exponential decay function for 6-DoF object pose tracking, as well as human pose estimation . Both of these representations convert the events to a 2D matrix structure that hold the filtered pseudo-order, and the raw events are no longer recoverable. They achieve long term memory and can represent multiple velocities simultaneously, but also have no method to remove noise in adverse conditions.
The Adaptive Exponential Decay Surface of Active Events (AED-SAE) and the Accumulation of Events algorithm (AAE) both take a large batch of events and attempt to refine the set to remove motion blur. As the batch is of finite time, the methods only have short term memory and cannot represent stationary objects. AED-SAE estimates the number of edges in the scene using a frequency domain analysis, from which it dynamically adjusts an SAE normal- isation parameter in time. The method is global, and best for a single velocity of the camera or an object. The AAE also uses a (different) statistical approach to decide the number of events in the final representation. However, it does so for each patch the scene is divided into and can represent different velocities in each patch. Additionally, as the events themselves are stored, they are also recoverable for sparse downstream processing.
Data driven methods for learning velocity invariant representations include the event-LSTM , in which the features of the hidden layers of a temporal
6
M. Ikura et al. encoder-decoder aimed to become robust to velocity variation. A batch of data was required to be fed to the network resulting in limited temporal memory. The Variable Kernel Speed Invariant Surface (VK-SITS) combined the velocity invariance of SITS with the learnability of TORE to provide a modified time ordered feature for use as a neural network input.
To date, a comparison of these algorithms in terms of event-rate throughput, update rate, and performance on memory, motion-blur removal, and downstream tasks has not been performed.
A Set Of Centre Active Receptive Fields
An event-camera produces an asynchronous stream of events for each pixel, with a polarity (increase and decrease in light), and a timestamp, i.e. < u, v, p, t >. The event is only triggered if the light changes beyond a logarithmic threshold.
In practice, the majority of events come from scene or object edges due to object motion, or the camera itself moving. Images are not extracted from the camera, rather individual pixel locations are asynchronously emitted from the sensor in the precise temporal order at which they occurred. An object moving quickly will produce more events than an identical slowly moving object, however for a significant number of vision algorithms it is often desirable that both objects are represented identically (velocity invariance) such that processing/analysis obtains an identical outcome.
We propose SCARF as a velocity invariant representation that is suitable for all conditions including fast and slow motion with multiple moving objects. Ad- ditionally, we focus on minimising event-throughput and allowing a high output frequency for suitability in real-time operation. The intuition behind SCARF is that, while a fixed amount of texture is not valid for the full sensor array, such an approach becomes more valid as the patch size decreases, and secondly that as an object moves across the sensor array, from one patch to the next, inactive regions are used to overwrite the data in active regions, allowing SCARF to remain sparse with areas of no texture.
The SCARF is composed of a set of local patches in which a fixed number of events, N, are stored in an ordered circular buffer. The full patch size is defined as r.k × r.k where an internal active region of k × k is centered. The value of r therefore defines the size ratio to an inactive border around the central patch. The set of active events will form the velocity invariant output of SCARF, while the inactive border is necessary as it instigates the forgetting of no-longer- relevant events.
A patch has a fixed location on the sensor array such that events occurring in the overlaid region are added to the circular buffer, and the oldest event of the same buffer is removed. The event is also tagged as active or inactive depending on which region in the patch it occurs. The circular buffer will therefore be composed of a mix of active and inactive events. Only active events contribute to the representation output, allowing SCARF to maintain sparsity if all data in a buffer is filled from inactive regions.
An Event Preserving Velocity Invariant Representation for Event Cameras
7
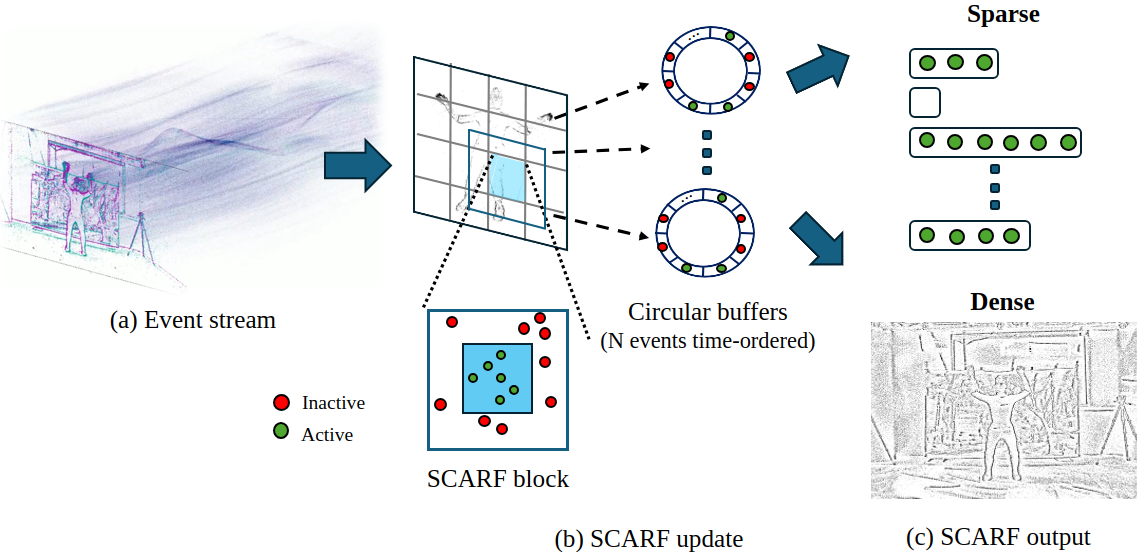
Fig. 3: The SCARF pipeline: (a) event stream - asynchronous pixels with microsecond temporal resolution, (b) the set of overlapping blocks with active regions (blue) covering the entire sensor plane, (c) circular buffers store events in active (blue) and inactive (white) regions in temporal order, (d) visualising the contents of the buffers by drawing active events on the sensor plane.
SCARF patches are tessellated across the sensor array such that the active regions of each patch align and cover the full array. Therefore, each pixel has a single active region associated with it, but due to patch overlap of the inactive region, can have several inactive region associations. The representation used by downstream tasks is formed only from active events across all patches. Active events can be extracted from each patch in two modes: – Sparse: extract the raw, sparse, events and iterate through the list for an algorithm, e.g. line detection, Hough transform.
– Dense: extract the optional 2D array, generated on-the-fly, which can be compatible with image-based vision processing, e.g. a convolutional neural network.
Pixel-to-Patch Mapping SCARF is initialised to achieve a fast update by pre-computing the mapping between incoming pixel location and the associated patches. Each pixel in the sensor plane (of resolution W × H) is covered by a patch in its active region, and multiple other patches in their inactive regions.
SCARF is initialised with the set of patches {P}, a set of connection maps that relate each pixels in the sensor plane to receptive fields for all active regions, {A}, and a similar set of connection maps for inactive regions, {I}.
Event-by-Event Update SCARF is updated for each event produced by the event-camera as it occurs. The data does not need to split into batches in any way. The connection maps are queried at each event’s < u, v > pixel position to identify associated P and their corresponding circular buffers. The update
8
M. Ikura et al.
Algorithm 1 Scarf Update (Per Event)
Require: e = ⟨u, v, p, t, a⟩{new event with activity tag}
4: End For
procedure is simply to copy events into the circular buffers. Events added to circular buffers from {A} get tagged as active, a = 1, and events added to circular buffers from connection maps {I} get tagged as inactive, a = 0.
The update procedure is cheap as it is a simple copy of data. The number of circular buffers that need to be updated scales with the ratio r, however, typically there are only 4 buffers per event. In contrast to other velocity invariant algorithms, there is no region update required, which means many less operations per event, and computational requirements do not scale with kernel size, k.
If image-like arrays are desired as an output of SCARF, it is also very cheap to iteratively construct such an image on-the-fly, event-by-event. When an event in the circular buffer is overwritten, it is first checked to see if it was an active event, and if so, the image at that pixel location is decremented by c. Each new active event is added to the image by increasing the pixel location by c.
3.1
Comparison with Velocity Invariant Representations SCARF is similar to SITS , TOS , and EROS as it has local updates to handle multiple velocities simultaneously and long-term persistence, however it doesn’t require a kernel update for each event, resulting in a higher event throughput. Additionally, un-like VK-SITS , SCARF can be queried for the raw sparse events, not only the dense image-like array. CHAIN-SAE and AED-SAE perform global updates making them more suited to a single velocity in the scene. AAE is similar to SCARF in that they are local and can generate sparse event outputs - however as AAE only operates over a limited memory, also like event-LSTM , SCARF should achieve longer-term memory.
Experiments And Results
Comparison is performed to velocity invariant representations by demonstrat- ing particular failure cases, quantitatively evaluating robustness to motion blur, and measuring event throughput and algorithm update frequency. Finally two use cases are presented using the representations: depth estimation and line fea- ture extraction. The SITS, TOS, CHAIN-SAE, EROS, AED-SAE, AAE and SCARF algorithms are re-implementated in the open source code1 and com-
1 Https://Github.Com/Robotology/Event-Driven
An Event Preserving Velocity Invariant Representation for Event Cameras
9
pared. The main parameter of each algorithm is ablated using line feature ex- traction described in the supplementary as a metric. The VK-SITS and Event- LSTM implementations were not available and required training, so could not be compared validly. The temporal window was also compared as a baseline (non- velocity-invariant) representation. Encoding algorithms such as VoxelGrid , TORE ), Hots and Hats are not valid for comparison as they don’t modify the batch used and therefore belong to the temporal window evalua- tion. The advantage of SCARF, as it doesn’t modify the underlying data and keeps raw events, is that the output of SCARF could be encoded with such an algorithm to achieve a velocity invariant coding with e.g. VoxelGrid/TORE.
Persistence And Multi-Object Speeds
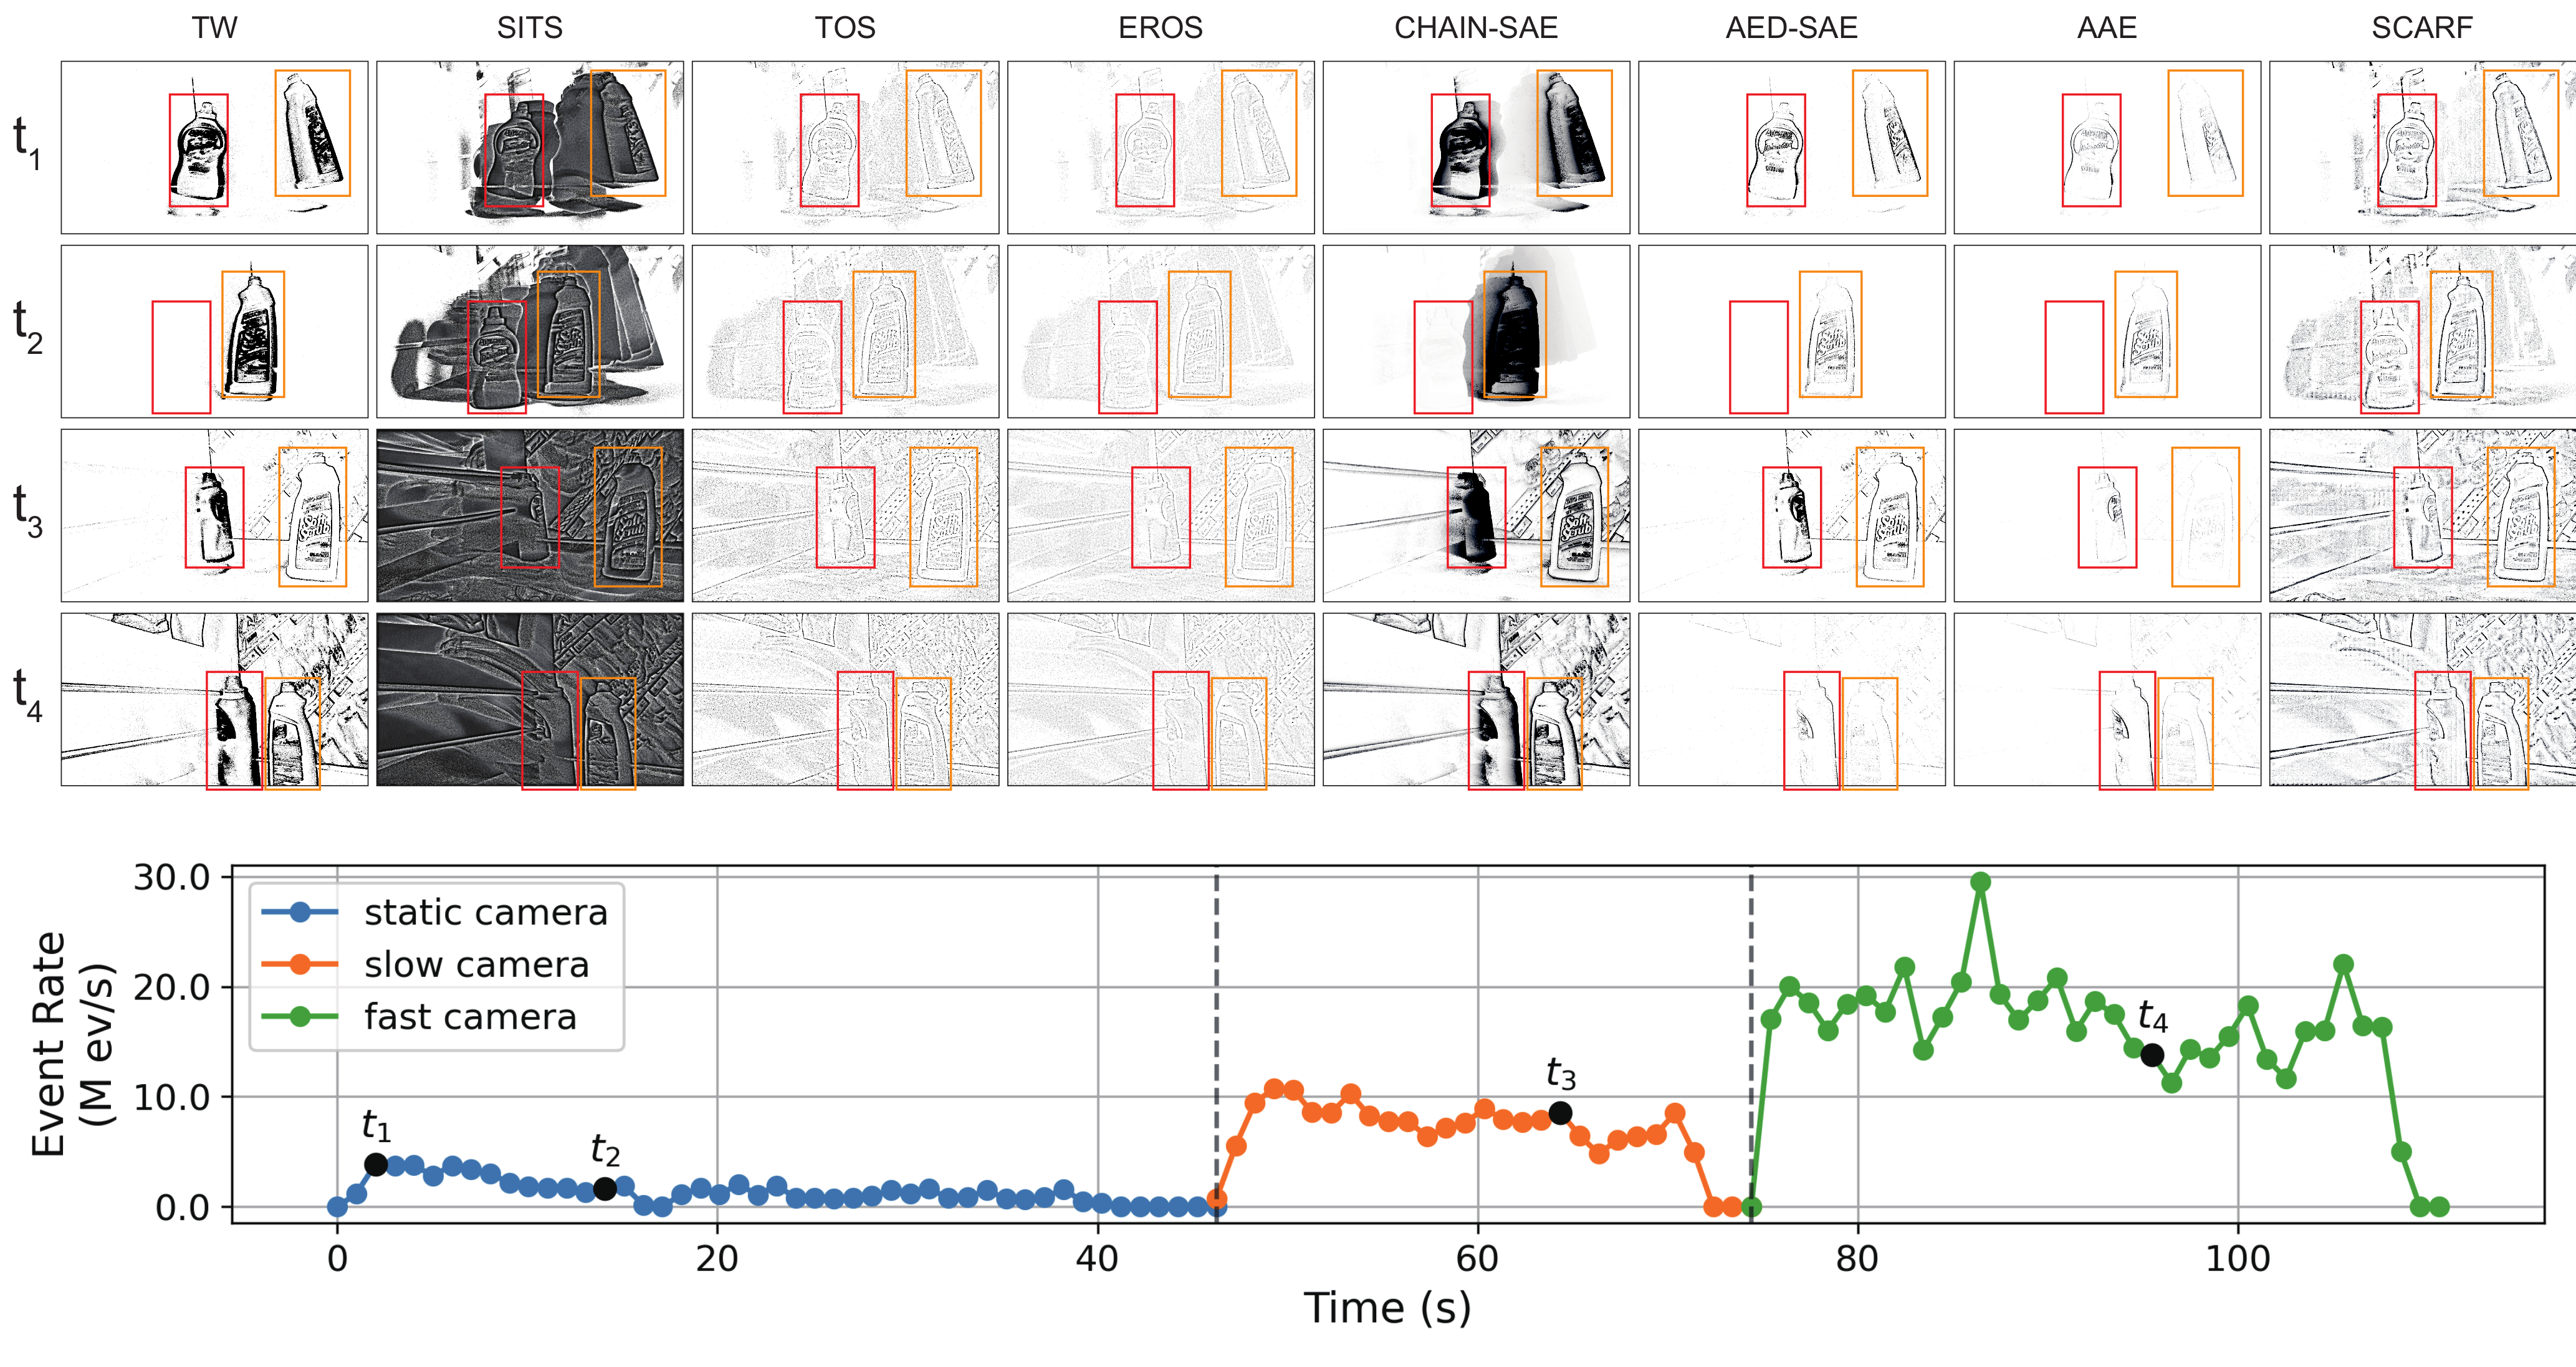
To particularly highlight issues that can arise “in-the-wild” for autonomous per- ception systems, but which are not always present in typical driving or object moving datasets, a qualitative comparison was performed with a self-recorded dataset which contains camera motion and motion of multiple objects. Specifi- cally, there are periods of non-motion (which commonly occurs) of both objects and cameras, as shown in Fig. 4. As a baseline it can be seen that the Time Win- dow (TW) consistently exhibited motion blur and/or fading because it was tuned for a single temporal window (i.e. velocity) and therefore cannot accommodate different object or camera speeds simultaneously. CHAIN-SAE produced con- sistent representation for camera motion but motion blur when objects moved independently, e.g. t2 and t3, additionally the non-moving object was lost when the secondary object was moved. TW, AAE, and AED-SAE also lost the sta- tionary object during secondary motion at t2 as they have a limited temporal memory. SITS, TOS, EROS, and SCARF maintained visual signal of both ob- jects under all conditions, however have differences in their representation values.
SITS had a ghosting effect due to its decay design, while TOS and EROS had reasonable noise artefacts “left behind” in non-moving parts of the scene. SCARF also had noise artefacts, but possibly achieved a stronger contrast between true edges and noise.
Motion blur and fading can effect downstream algorithms which assume a consistent visual input over time. Noise also effects downstream algorithms, but if uniformly distributed, can be more easily disregarded by algorithms looking for strong features for vision tasks. The local and persistent properties of SCARF (and others) are important for operating “in-the-wild” in which consistent object and camera motion cannot be guaranteed.
Motion Blur
To quantify the velocity invariant output in representing edges, while removing motion blur, the algorithms were compared across several publicly available se- quences, see Fig. 5. The available sequences were limited and chosen to give fair- ness to all algorithms, and therefore contained typically only a single velocity of motion, and from datasets with RGB aligned frames. ECD dynamic_6dof ,
10
M. Ikura et al. Fig. 4: Qualitative comparison of event-based representations during various scenarios: (t1) static camera, two moving objects, (t2) static camera, one moving object, (t3) slow- moving camera, one moving object, (t4) fast-moving camera, one moving object.
Table 2: Mean±std of 3-SSIM and TEPR for sequences from three different datasets.
0.63±0.06
EVIMO boxes_seq00 , and event-H36m h36m_Sitting were therefore chosen. The RGB frames served as a proxy ground truth by extracting Sobel- filtered greyscale images to identify pixel locations in which events should be located in the velocity invariant representation. As in , 3-SSIM and TEPR metrics are used to compare velocity invariant representation and the Sobel im- ages (computed only on pixels where event data is present).
Results on the three representative sequences in Fig. 5 are reported in Tab. 3. SCARF achieved performance comparable to the other representations, although not consistently the highest scores. While methods such as AAE and CHAIN- SAE often obtain higher metric values, qualitative overlays (Fig. 1) reveal that they produce thicker edges or motion blur. In contrast, SCARF generates con- sistently thin, sharp contours that better reflect velocity invariance, but are penalized by 3-SSIM and TEPR, which inherently favour denser edge responses.
This suggests that current metrics may not fully capture the structural fidelity and thin-edge characteristics that SCARF is designed to preserve.
Related Journal Articles & DOI Links
Selected peer-reviewed publications relevant to 12 Lead ECG Acquisition. Click the DOI to access the full paper (may require institutional access).
-
1. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
IEEE Journal of Biomedical and Health Informatics
https://doi.org/10.1109/JBHI.2020.2981234 -
2. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Medical & Biological Engineering & Computing
https://doi.org/10.1007/s11517-020-02145-6 -
3. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
IEEE Transactions on Biomedical Engineering
https://doi.org/10.1109/TBME.2019.2895762 -
4. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Frontiers in Bioengineering and Biotechnology
https://doi.org/10.3389/fbioe.2020.00123 -
5. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Biosensors and Bioelectronics
https://doi.org/10.1016/j.bios.2021.112345 -
6. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
Computers in Biology and Medicine
https://doi.org/10.1016/j.compbiomed.2021.104567 -
7. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Nature Communications
https://doi.org/10.1038/s41467-020-12345-6
Why Choose Us?
Bangalore guidance for robotics, Spectre and autonomous systems projects.
Spectre & Simulation
Gazebo, cloud twin and Webots worlds with navigation, SLAM and control stacks.
Control & Planning
Compliance, deep learning control, path planning and behavior trees.
Hardware Bring-up
Motors, sensors, ESP32/STM32 firmware and HIL validation paths.
Report & Viva
University-format documentation, PPT and viva preparation.
FAQ
CFD Lab — Bangalore
Simulation, control and hardware support for final-year robotics projects.
Stacks
Worlds
Digital Twin
Control
Robots
Offline
Bring-up