Complete Technical Paper Content — Adversarial Attacks On Machine Learning Security Models Project
Overview & System Context
Adversarial Attacks On Machine Learning Security Models Project: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9548 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Adversarial Machine Learning (AML) addresses vulnerabilities in AI systems where adversaries manipulate inputs or training data to degrade performance. This article provides a comprehensive analysis of evasion and poisoning attacks, formalizes defense mechanisms with mathematical rigor, and discusses the challenges of implementing robust solutions in adaptive threat models. Additionally, it highlights open challenges in certified robustness, scalability, and real-world deployment.
Modern machine learning (ML) systems achieve superhuman performance on benchmarks like ImageNet [ 17 ] but remain vulnerable to adversarial perturbations. For example, adding imperceptible noise to a panda image can misclassify it as a gibbon with 99% confidence [ 18 ] . This paper systematically analyzes: Formal unification of attack methodologies under I \epsilon -constrained optimization frameworks Machine learning (ML) systems, particularly deep neural networks, are vulnerable to adversarial attacks. These attacks manipulate model inputs to produce incorrect predictions, which can have severe consequences in security-critical applications like biometric authentication, medical diagnostics, and autonomous driving. In this section, we categorize different types of adversarial attacks based on the attacker’s capabilities and objectives.
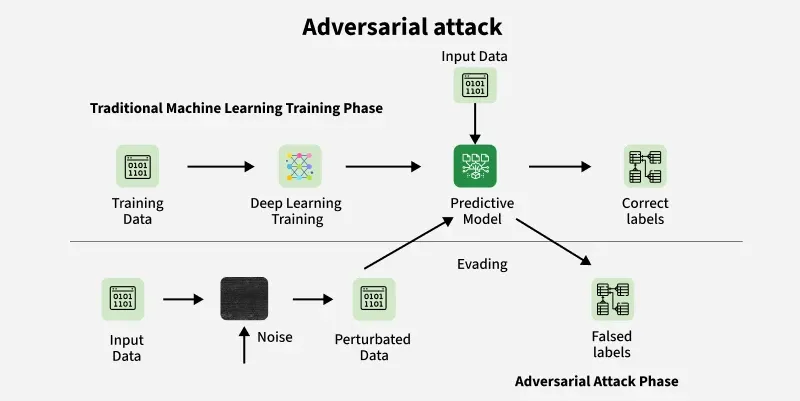
Figure 1: What is Adversarial Machine Learning? - GeeksforGeeks Adversarial capabilities define the level of knowledge and control an attacker has over the target model. The two primary categories of attacks based on knowledge are white-box attacks and black-box attacks . In a white-box setting, the attacker has complete knowledge of the target model, including its architecture, parameters θ \theta , gradients, and training data. This allows precise gradient-based optimization to craft adversarial examples.
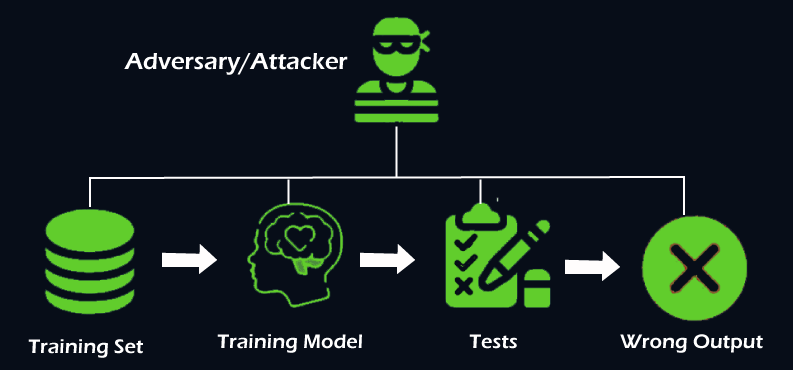
For a neural network f θ f_{\theta} with ReLU activations, the exact gradient computation is given by: Fast Gradient Sign Method (FGSM) : Perturbs input along the gradient direction [ 1 ] . Figure 2: Adversarial Attacks In Deep Learning – XVFPIK Projected Gradient Descent (PGD) : Iteratively refines adversarial examples with bounded perturbations [ 14 ] .
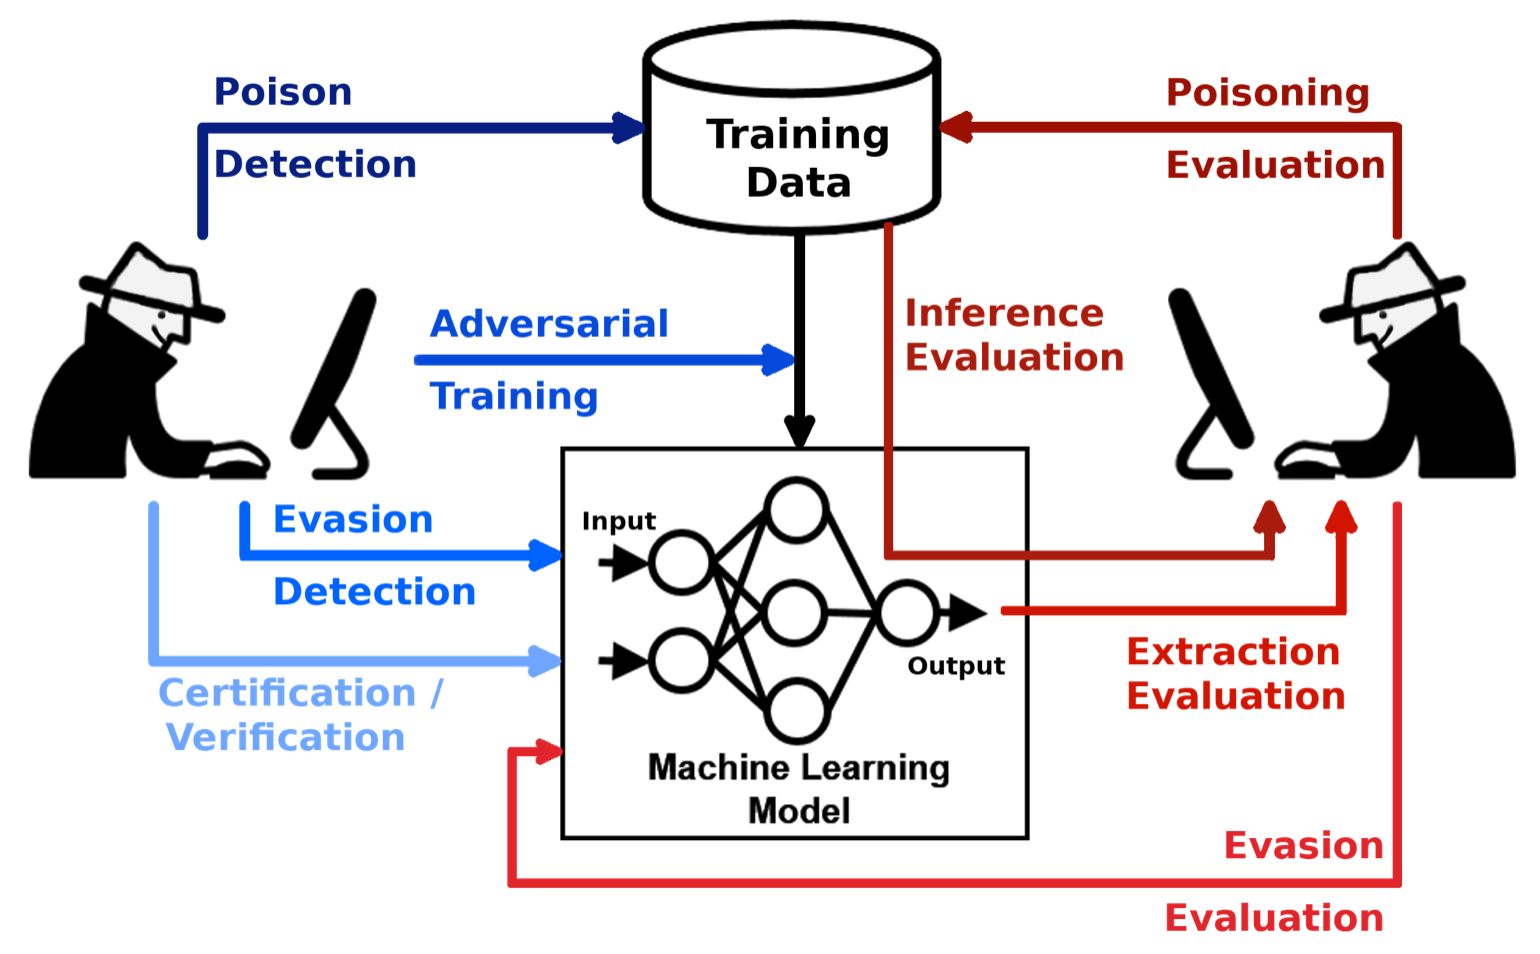
Carlini & Wagner (C&W) Attack : Solves an optimization problem to find minimal perturbations [ 4 ] . In a black-box setting, the attacker has limited or no knowledge of the target model’s architecture or parameters. Instead, they rely on input-output queries to infer model behavior. One common approach to estimate gradients is through finite difference methods, which require O I ( d ) O(d) queries: Figure 3: Adversarial Machine Learning - Tpoint Tech Zeroth Order Optimization (ZOO) : Uses gradient-free optimization to craft adversarial examples.
Boundary Attack : Starts from a misclassified example and moves toward the decision boundary. Transfer Attacks : Adversarial examples crafted on a surrogate model are transferred to the target model. An adversary’s objective determines how they manipulate the model’s predictions. The two key goals are untargeted and targeted attacks.
In targeted attacks, the adversary aims to mislead the model into misclassifying an input as a specific target class t t . This is formulated as an optimization problem: I η I p \|\eta\|_{p} controls the perturbation norm (e.g., L 2 L_{2} or L ∞ L_{\infty} ), In untargeted attacks, the adversary only seeks to induce a misclassification without a specific target class: Evasion Attacks : Modify inputs at inference time to fool the model (e.g., adversarial examples).
Privacy Attacks : Infer sensitive training data, such as through membership inference. Evasion attacks focus on modifying inputs at inference time to cause incorrect predictions while keeping the perturbation imperceptible. These attacks exploit the model’s vulnerability to adversarial perturbations and can be categorized into optimization-based attacks and transfer attacks.
Optimization-based attacks rely on solving mathematical formulations to find adversarial perturbations that mislead the model. These attacks often minimize a perturbation norm while ensuring the input is misclassified with high confidence. The Carlini-Wagner attack [ 4 ] is a powerful L p L_{p} -norm attack that uses an optimization-based approach to generate adversarial examples. It formulates the attack as a constrained optimization problem, which is solved using Lagrangian relaxation: Z I ( x ′ ) Z(x^{\prime}) represents the model logits for perturbed input x ′ = x + η x^{\prime}=x+\eta .
ϕ I ( x ′ ) \phi(x^{\prime}) is a loss function ensuring that class t t is predicted with confidence margin κ \kappa . The constant c c is adjusted via binary search to balance perturbation size and attack success. The CW attack is highly effective against defensive distillation and adversarial training, as it directly optimizes for minimal perturbations that cause misclassification.
Projected Gradient Descent (PGD) [ 14 ] is an iterative attack that maximizes the model’s loss while keeping the perturbation within a bounded norm. A key limitation of traditional PGD is the choice of a fixed step size α \alpha . To improve efficiency and convergence, an adaptive step-size strategy is employed: This approach dynamically scales the step size α \alpha based on loss behavior, ensuring: Adaptive step-size PGD enhances attack efficiency, especially in scenarios with strong defenses such as adversarial training.
Transfer attacks leverage adversarial examples generated on one model to attack another model with a different architecture or training data. This is particularly useful when black-box access is the only option, making transferability a critical factor for real-world adversarial threats. I I ( ⋅ ) \mathbb{I}(\cdot) is an indicator function returning 1 if both models misclassify x ′ x^{\prime} .
Transfer attacks exploit common vulnerabilities between models and are effective when: The attack uses high-dimensional, query-efficient perturbations (e.g., momentum-based methods). Momentum Iterative FGSM (MI-FGSM) : Enhances transferability by accumulating past gradients [ 6 ] . Diversity Input Transformation (DIM) : Randomly transforms inputs to improve robustness against defenses [ 7 ] .
Ensemble Attacks : Generate adversarial examples against multiple models to generalize attack effectiveness. Poisoning attacks manipulate the training data to degrade model performance or implant hidden behaviors. By introducing adversarially crafted samples into the training dataset, an attacker can influence model decisions, either causing misclassification of specific inputs (targeted poisoning) or generally degrading model accuracy (untargeted poisoning).
Poisoning attacks are particularly dangerous in scenarios where data sources are not fully controlled, such as federated learning, web-scraped datasets, or crowdsourced labeling. Optimal poisoning involves crafting adversarial training samples that maximize the impact on the model’s parameters. The influence function [ 8 ] provides an efficient approximation of parameter shifts due to small perturbations in the training data: ∇ θ I I ( z p I o I i I s I o I n , θ ) \nabla_{\theta}\ell(z_{poison},\theta) is the gradient of the loss function with respect to model parameters, evaluated at the poisoned sample z p I o I i I s I o I n z_{poison} .
By solving for θ I \theta_{\epsilon} , an attacker can determine optimal poisoning perturbations that shift model behavior in a desired direction. This approach is particularly effective in convex settings, such as logistic regression or linear models. For deep neural networks, approximation techniques like stochastic estimation of the Hessian are required due to computational constraints.
Backdoor attacks introduce poisoned samples that appear correctly labeled during training but induce misclassification when an attacker-controlled trigger is applied at inference time. Unlike traditional poisoning, clean-label backdoor attacks maintain consistency between poisoned samples and their assigned labels, making detection more challenging. To craft clean-label backdoor examples ( x p , y p ) (x_{p},y_{p}) , an attacker ensures: y p y_{p} is the assigned label, ensuring the poisoned sample appears correctly labeled.
2. System Architecture & Core Working Principles where I v I i I s \epsilon_{vis} controls the visual perceptibility of the trigger. The attacker ensures τ \tau is imperceptible to human annotators while still being effective at inference time. **Feature Collision Attacks**: Modify benign samples so their internal representations match those of target-class examples [ 9 ] .
**Adversarial Perturbation Backdoors**: Use adversarial optimization to generate subtle perturbations that guide the model toward a specific decision boundary. **Watermark-Based Triggers**: Embed small, structured perturbations (e.g., translucent overlays, invisible noise) that the model learns to associate with the backdoor target class.
Data Sanitization : Identify and remove anomalous training samples using anomaly detection techniques. Differential Privacy : Limit individual sample influence to reduce the impact of poisoning [ 10 ] . Robust Training : Use techniques such as adversarial training and model ensembling to mitigate poisoned sample influence. Trigger Pattern Detection : Analyze feature space activations to identify and neutralize backdoor triggers.
As adversarial attacks become increasingly sophisticated, various defense mechanisms have been proposed to enhance the robustness of machine learning models. These defenses aim to mitigate the impact of adversarial perturbations by modifying model training, altering gradient computations, or leveraging certified robustness techniques. Gradient masking is a defense technique that obstructs an attacker’s ability to compute reliable gradients, making gradient-based adversarial attacks less effective. However, improperly implemented gradient masking can lead to obfuscated gradients, which may be bypassed using adaptive attack strategies [ 16 ] .
One effective approach to gradient masking is defensive quantization, which reduces the precision of computed gradients. The gradients are quantized to b b bits using: ∇ x \nabla_{x} is the original gradient of the loss function with respect to input x x . Experimental results show that reducing gradient precision to b = 4 b=4 can decrease attack success rates by up to 38 % 38\% [ 12 ] . By limiting the attacker’s ability to generate precise adversarial perturbations, defensive quantization increases the difficulty of crafting effective adversarial examples.
Certified robustness techniques provide formal guarantees on a model’s resistance to adversarial perturbations. Unlike empirical defenses, which are tested against specific attacks, certified defenses ensure that a model remains robust within a mathematically provable bound. Interval Bound Propagation (IBP) is a certified defense technique that propagates interval bounds through the network layers, ensuring robustness within a predefined perturbation range. Given a neural network layer k k with weight matrix W k W^{k} , IBP computes pre-activation bounds: W + = max I ( W , 0 ) W_{+}=\max(W,0) and W − = min I ( W , 0 ) W_{-}=\min(W,0) ensure the correct handling of weight sign changes.
l k − 1 l^{k-1} and u k − 1 u^{k-1} are the bounds propagated from the previous layer. IBP guarantees that all activations remain within these bounds, ensuring that small adversarial perturbations cannot push inputs outside a safe region. This method is particularly effective in defending against I ∞ \ell_{\infty} -bounded attacks [ 13 ] . Another fundamental defense technique is adversarial training, where a model is explicitly trained on adversarial examples to improve robustness. The adversarial loss function is formulated as: δ \delta is an adversarial perturbation constrained by norm I δ I p ≤ I \|\delta\|_{p}\leq\epsilon .
Adversarial training forces the model to learn robust representations by minimizing the worst-case loss over perturbed inputs. While effective, adversarial training can significantly increase training time and may not generalize well against unseen attack types [ 14 ] . Randomized smoothing is a probabilistic defense that converts a classifier into a certifiably robust one by adding noise to inputs. A smoothed classifier is defined as: This technique provides a robustness guarantee under I 2 \ell_{2} norm perturbations and is scalable to large models [ 15 ] .
The BPDA (Backpropagation Through the Attack) attack [ 16 ] is a widely studied method designed to circumvent gradient masking defenses. Gradient masking is a strategy used to make adversarial attacks more difficult by masking the gradients, which are often the key to generating effective adversarial examples. BPDA bypasses this defense mechanism by approximating the gradient computation through a randomized method.
The attack leverages the fact that, during backpropagation, the adversary can apply a stochastic noise component to the input image, δ ∼ I I ( 0 , σ 2 I I ) \delta\sim\mathcal{N}(0,\sigma^{2}I) , where I \mathcal{N} is a normal distribution and σ \sigma is the standard deviation of the noise. This approximation allows the attack to bypass the gradient masking while still generating adversarial examples. The approximation is defined by the following equation: where ∇ x f θ I ( x + δ ) \nabla_{x}f_{\theta}(x+\delta) represents the gradient of the neural network’s output with respect to the input perturbed by noise δ \delta . While this technique can make adversarial training and other defenses more resilient, it also raises concerns about the robustness of machine learning models, especially when combined with adaptive attacks that learn to exploit vulnerabilities in these defenses.
Another significant open challenge in the domain of neural networks, particularly when used in safety-critical applications, is the complexity involved in verifying their behavior under various conditions. Verification is the process of ensuring that a neural network model behaves as expected for all inputs in its domain. For deep learning models, especially large-scale neural networks, the verification process can be computationally expensive.
For an L L -layer neural network with n n neurons per layer, exact verification involves checking all possible input-output relations to ensure that the network does not misclassify inputs or behave incorrectly. The complexity of this verification is typically represented by the following equation: This means that the number of operations required for exact verification grows exponentially with both the number of layers L L and the number of neurons n n in each layer. This exponential growth in complexity becomes particularly problematic for large networks with more than 10 layers, which are common in deep learning. The verification process thus becomes intractable as L L increases, making it impractical to fully verify the behavior of large models in real-world applications. This challenge necessitates the development of more efficient methods for model verification, potentially relying on approximations or probabilistic techniques.
The need for scalable verification techniques is especially important for safety-critical systems, such as autonomous vehicles and medical applications, where the stakes of model failure are high. Methods like formal verification, which guarantees correctness, and approximate verification, which provides probabilistic guarantees, are areas of active research aiming to mitigate this challenge.
Adversarial ML remains a critical frontier in AI safety. While defenses like TRADES and certified smoothing improve robustness, significant gaps persist in scalability and real-world deployment. Future work must address adaptive threats while maintaining computational efficiency. arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website.
Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them. Have an idea for a project that will add value for arXiv's community? Learn more about arXivLabs .
Adversarial attacks are carefully crafted inputs designed to fool machine learning models into making incorrect predictions or behaving in unintended ways. The concept was first demonstrated in 2013 when researchers showed that imperceptible pixel-level changes to images could cause state-of-the-art neural networks to misclassify objects with high confidence — for example, causing a model to classify a panda as a gibbon with 99.3% confidence after adding a tiny perturbation invisible to the human eye.
Adversarial attacks exploit the fundamental differences between how neural networks and humans process information. While humans rely on high-level semantic features, neural networks often depend on subtle statistical patterns in the data that can be manipulated. This vulnerability is not a bug in specific models but a fundamental property of high-dimensional machine learning systems.
The threat is real and growing. Adversarial attacks have been demonstrated against image classifiers, speech recognition systems, natural language processing models, autonomous driving systems, malware detectors, and large language models. In the LLM era, adversarial attacks have evolved to include prompt injection, jailbreaking, and adversarial suffix attacks that can bypass model safety training.
Evasion attacks are the most common type, where adversarial inputs are crafted at inference time to cause misclassification without modifying the model itself. These include gradient-based attacks like FGSM (Fast Gradient Sign Method), PGD (Projected Gradient Descent), and C&W (Carlini-Wagner) that use the model's gradients to find minimal perturbations. Optimization-based attacks solve a constrained optimization problem to find the smallest perturbation that causes misclassification. Score-based and decision-based attacks work with limited access to the model, using only output probabilities or final decisions to craft adversarial examples .
Poisoning attacks corrupt the training data to influence model behavior after training. Backdoor attacks (also called trojan attacks) insert hidden triggers into training data so the model behaves normally on clean inputs but produces attacker-chosen outputs when the trigger is present. Data poisoning can also degrade overall model performance by injecting noisy or mislabeled examples.
Model extraction attacks aim to steal a model's functionality by querying it and training a substitute model on the responses. This enables intellectual property theft and can also facilitate follow-up evasion attacks since the attacker now has a white-box copy of the model. Membership inference attacks determine whether a specific data point was used in training, potentially revealing sensitive information. Model inversion attacks reconstruct training data features from model outputs. Both pose serious privacy risks.
For LLMs specifically, adversarial attacks include prompt injection (overriding system instructions through user input), jailbreaking (bypassing safety training through carefully crafted prompts), adversarial suffix attacks (appending optimized token sequences that bypass safety filters), and indirect prompt injection (embedding malicious instructions in external content that the LLM processes).
Autonomous vehicles have been shown vulnerable to adversarial patches — physical stickers placed on stop signs that cause perception systems to misclassify them as speed limit signs. Researchers demonstrated that a few strategically placed stickers could reliably fool multiple commercial object detection systems. In cybersecurity, adversarial examples have been used to evade malware detection systems. Attackers modify malicious executables with minimal changes that preserve functionality but cause ML-based antivirus systems to classify them as benign. This has become an active area of concern as security vendors increasingly rely on ML for threat detection.
LLM jailbreaks have been widely demonstrated against ChatGPT, Claude, Gemini, and other frontier models. The GCG (Greedy Coordinate Gradient) attack discovered by Zou et al. (2023) showed that adversarial suffixes optimized on open-source models could transfer to closed-source production models, enabling automated jailbreak discovery at scale. 3. Software Implementation, Frameworks & Protocols In healthcare, adversarial attacks on medical imaging AI could cause misdiagnosis. Researchers have shown that imperceptible perturbations to chest X-rays can flip a model's prediction from healthy to pathological or vice versa, with potential life-threatening consequences.
Financial systems using ML for fraud detection, credit scoring, and trading are also vulnerable. Adversarial manipulation of input features can bypass fraud detection or manipulate algorithmic trading strategies. Adversarial training is the most widely studied defense. It augments the training set with adversarial examples generated during training, forcing the model to learn robust features. PGD-AT ( adversarial training with Projected Gradient Descent) remains one of the most effective defenses, though it increases training cost by 3-10x and can reduce clean accuracy by 1-5%.
Certified defenses provide mathematical guarantees on robustness within a specified perturbation radius. Randomized smoothing creates a smooth classifier by averaging predictions over random Gaussian noise, providing provable robustness certificates for l2 perturbations. IBP (Interval Bound Propagation) and similar methods provide deterministic robustness guarantees but are currently limited to smaller models.
Input preprocessing defenses transform inputs before classification to remove adversarial perturbations. Techniques include input compression (JPEG compression, bit-depth reduction), denoising (using autoencoders or diffusion models), and input transformation (random resizing, padding). These are easy to deploy but can be circumvented by adaptive attacks. Detection methods aim to identify adversarial inputs rather than correctly classifying them. Feature squeezing compares model outputs on original and squeezed inputs; large discrepancies indicate adversarial examples . Statistical tests on input feature distributions can also flag anomalous inputs.
For LLMs, defenses include perplexity-based detection (adversarial prompts often have unusual perplexity scores), instruction hierarchy enforcement (ensuring system prompts take priority), input/output guardrails (filtering known attack patterns), and constitutional AI training (making models inherently resistant to manipulation). Ensemble methods combine multiple models with different architectures or training procedures. Since adversarial examples often do not transfer perfectly across diverse models, ensembles can improve robustness. However, sophisticated attacks can optimize against ensembles.
IBM Adversarial Robustness Toolbox (ART) is the most comprehensive open-source library (MIT license, 4,800+ GitHub stars) for adversarial machine learning. It supports 40+ attack methods, 15+ defense methods, and works with TensorFlow, Keras, PyTorch, MXNet, scikit-learn, and more. ART covers evasion, poisoning, extraction, and inference attacks, making it the standard tool for adversarial ML research and testing.
Foolbox (MIT license, 2,700+ stars) provides a clean API for running adversarial attacks against machine learning models. It supports multiple deep learning frameworks and offers both gradient-based and decision-based attacks. Foolbox is particularly useful for benchmarking model robustness. CleverHans (MIT license, 6,100+ stars) was one of the first adversarial ML libraries, created by Ian Goodfellow and Nicolas Papernot. It provides reference implementations of key attacks and is widely used in academic research.
RobustBench is a standardized benchmark for adversarial robustness that maintains leaderboards tracking the most robust models across different threat models (Linf, L2, corruptions). It provides a reproducible evaluation framework that has become the standard for comparing adversarial defenses. TextAttack (MIT license, 2,800+ stars) focuses specifically on adversarial attacks for NLP models. It provides implementations of 16+ attack methods and 9+ search methods for generating adversarial text examples.
For LLM-specific testing, Garak is an open-source LLM vulnerability scanner that tests for prompt injection, jailbreaks, and other adversarial attacks. PyRIT (Python Risk Identification Toolkit) by Microsoft automates AI red-teaming. HarmBench provides a standardized framework for evaluating LLM attacks and defenses. Microsoft Counterfit is a command-line tool for security testing of AI systems, designed for security professionals rather than ML researchers. It provides a familiar interface for those with penetration testing backgrounds.
Adopt a threat modeling approach. Before deploying an AI system, conduct adversarial threat modeling to identify which attack vectors are relevant to your use case. A medical imaging system faces different threats than a chatbot. Use frameworks like MITRE ATLAS (Adversarial Threat Landscape for AI Systems) to systematically map threats. Test before you deploy. Use tools like ART, RobustBench, or Garak to evaluate your model's robustness against known attack methods. Establish robustness baselines and set minimum thresholds before production deployment. Automate adversarial testing in your CI/CD pipeline.
Layer your defenses. No single defense is sufficient against all attack types. Combine adversarial training (for inherent robustness), input preprocessing (for perturbation removal), detection mechanisms (for flagging suspicious inputs), and output validation (for catching incorrect predictions). This defense-in-depth approach mirrors best practices in traditional cybersecurity.
Monitor for adversarial activity in production. Track input distributions for anomalies that might indicate adversarial probing. Monitor model confidence distributions — adversarial examples often produce unusually high or low confidence scores. Set up alerting for distribution shifts in model inputs and outputs. Consider the robustness-accuracy tradeoff. Adversarial training typically reduces clean accuracy by 1-5%. Budget for this tradeoff and communicate it to stakeholders. In safety-critical applications, the robustness gain is usually worth the accuracy cost.
Foundation model robustness is an active frontier. As AI capabilities concentrate in a few large foundation models, ensuring their adversarial robustness becomes critical. Research on scaling laws for adversarial robustness suggests that larger models may be inherently more robust, but this remains an open question. Multimodal attacks are emerging as AI systems process text, images, audio, and video simultaneously. Attacks that combine modalities — for example, hiding adversarial instructions in images processed by vision-language models — represent a growing threat surface.
Adversarial attacks on AI agents are a new frontier. As autonomous AI agents interact with tools, APIs, and the real world, adversarial attacks can manipulate their planning and decision-making processes, not just their perception. Indirect prompt injection in agentic systems is a particularly active area of research. Automated adversarial testing using AI to find vulnerabilities in AI is scaling rapidly. Tools like Garak, PyRIT, and DeepTeam use LLMs themselves to generate diverse adversarial test cases. This AI-vs-AI dynamic is likely to define the future of adversarial ML defense.
Standardization through NIST AI 100-2, MITRE ATLAS, and OWASP ML Security Top 10 is bringing structured frameworks to adversarial ML. These standards help organizations systematically assess and mitigate adversarial risks rather than relying on ad-hoc testing. NIST taxonomy and terminology for adversarial machine learning attacks and mitigations across predictive and generative AI.
MITRE's knowledge base of adversary tactics and techniques targeting AI/ML systems, modeled after the ATT&CK framework. OWASP's list of the top 10 critical security vulnerabilities in machine learning systems beyond LLM-specific risks. Industry-standard list of the top 10 critical security risks for LLM-based applications with mitigation guidance.
NIST's voluntary framework for managing AI risks through governance, mapping, measurement, and management functions. Open-source LLM vulnerability scanner that probes AI models for prompt injection, toxicity, and other weaknesses. Microsoft's open-source Python framework for red-teaming and risk identification in generative AI systems. Open-source Python framework for adversarial attacks, data augmentation, and adversarial training in NLP.
Framework-agnostic Python library for creating adversarial attacks against ML models in PyTorch, TensorFlow, and JAX. Foundational adversarial ML library for benchmarking model vulnerability to adversarial examples. Enterprise adversarial ML platform for automated red-teaming and security testing of AI systems. Open-source LLM red teaming framework with 40+ vulnerability classes and 10+ adversarial attack methods.
AI safety company building reliable, interpretable AI systems and the Claude family of AI assistants. AI research and deployment company working on safe and beneficial artificial general intelligence. UK government institute evaluating frontier AI safety and developing testing methodologies. Industry consortium of leading AI labs coordinating safety research and best practices for frontier AI models.
Open-source AI security framework covering LLM Top 10 risks and comprehensive AI threat and control guidance. Nonprofit evaluating frontier AI models for dangerous autonomous capabilities and catastrophic risk potential. Meta's AI research division publishing open-source safety tools including LlamaGuard and LlamaFirewall. Microsoft's responsible AI program with an AI Red Team, safety office, and open-source red-teaming tooling.
4. Practical Deployment, Analysis & Case Studies How to defend AI models against evasion attacks, adversarial examples, and robustness failures with practical tools and techniques. Everything you need to know about data poisoning attacks — backdoor attacks, trojan attacks, training data manipulation, detection methods, and defenses for securing the AI training pipeline.
A deep-dive into AI jailbreak attacks — taxonomy of techniques, real-world incidents, why they succeed, and defense strategies to harden LLM systems. How backdoor and trojan attacks compromise AI models — insertion methods, detection techniques, and defense frameworks for securing the ML pipeline.
Embedded into information systems, artificial intelligence (AI) faces security threats that exploit AI-specific vulnerabilities. This paper provides an accessible overview of adversarial attacks unique to predictive and generative AI systems. We identify eleven major attack types and explicitly link attack techniques to their impacts—including information leakage, system compromise, and resource exhaustion—mapped to the confidentiality, integrity, and availability (CIA) security triad. We aim to equip researchers, developers, security practitioners, and policymakers, even those without specialized AI security expertise, with foundational knowledge to recognize AI-specific risks and implement effective defenses, thereby enhancing the overall security posture of AI systems.
The field of artificial intelligence (AI) has undergone rapid advancement in recent years, resulting in revolutionary changes across diverse domains, including healthcare, finance, and content generation. Innovations have not only expanded the potential applications of AI but also significantly increased its societal influence. As AI systems become integrated into critical infrastructures and decision-making processes, there has been a notable increase in global awareness and demand for ensuring their safe, reliable, and ethical operation — collectively referred to as AI safety .
In response to these mounting global concerns, Japan has assumed a pioneering role by spearheading the Hiroshima AI Process ( of the Group of Seven, G7 ) , a comprehensive policy framework that was adopted in 2023. Concurrently, the United Kingdom and the United States established national AI Safety Institutes 1 1 1 The UK AI Safety Institute was renamed the AI Security Institute on February 14, 2025 ( Kyle, 2025 ) . 2 2 2 The plan to transform the US AI Safety Institute into the US Center for AI Standards and Innovation (CAISI) was announced on June 3, 2025 ( of Commerce, 2025 ) . to address AI-related risks. In alignment with these global developments, the Japan AI Safety Institute (J-AISI) was established in February 2024. It functions as Japan’s central hub for AI safety, with the mission of aggregating technical expertise and promoting both domestic and international collaboration toward the responsible deployment of AI technologies. The secretariat of J-AISI is situated within the Information-technology Promotion Agency (IPA), thereby ensuring effective coordination and support for its activities ( (2024b), J-AISI ) .
Within the broader domain of AI safety, AI security has emerged as a crucial subset focused explicitly on protecting AI systems from malicious actions designed to compromise their confidentiality, integrity, or availability. As AI systems handle increasingly sensitive data and perform critical societal functions, failures in AI security could result in severe consequences, including privacy violations, operational disruptions, economic damages, and threats to public safety. Consequently, a clear understanding of AI security risks and practical strategies to mitigate them is vital, not only for AI specialists but also for developers, security practitioners, and stakeholders responsible for deploying, operating, and managing AI systems across various sectors.
This paper contributes to AI security by providing broad stakeholders, especially security practitioners, including those without specialized AI security, with a comprehensive yet highly accessible overview of attacks against AI systems shown by Figure 1 . A comprehensive survey of the latest and most advanced attacks is beyond the scope of this paper. Due to the abundance of research on AI security, it can be challenging for practitioners, especially those who are new to the field, to develop a coherent and comprehensive understanding of its landscape and underlying context. Accordingly, a practical guide is needed to support a comprehensive understanding of AI security.
The distinguishing features of this work are its emphasis on the impacts of attacks on AI systems and intuitive visual summaries illustrating their relationships. By explicitly linking each established attack type with specific impacts on AI systems, this paper furnishes readers with actionable insights useful for security management practices. Developers and practitioners can leverage this structured knowledge to perform risk assessments or red-teaming exercises and identify critical attack vectors specifically relevant to their own AI systems.
Furthermore, this paper summarizes the referenced attack literature in Table 4 organized by modality (e.g., text, image, or tabular), model type (e.g., neural network, logistic regression, or decision tree), and attacker’s capabilities. This table offers readers practical guidance for evaluating realistic risk scenarios within broader cybersecurity contexts. Identifying eleven attack types on AI systems by incorporating globally established references from various AI relevant stakeholders.
Explicitly linking each attack type to its specific impacts on AI systems, supporting practical risk assessments, including red-teaming exercises. Identifying attacker’s capabilities associated with each attack, supporting realistic evaluations of AI security scenarios and risks.
Providing intuitive summaries that facilitate an easy understanding of attack mechanisms and their implications, suitable for developers and security practitioners without specialized AI security expertise. Organizing referenced attack literature according to data modalities and AI model types, serving as a clear roadmap for readers pursuing further in-depth study.
The remainder of this paper is organized as follows. Section 2 reviews related works in AI security, contextualizing our contributions within existing frameworks and literature. Section 3 details the AI system architecture and defines the scope of the attacks considered in this paper. Section 4 introduces our categorization of eleven major attack types and discusses their potential impacts on AI systems, mapped to the CIA security triad. Section 5 provides in-depth descriptions of each identified attack, including its mechanisms, attacker capabilities, and affected AI modalities and model types, supported by examples from the literature. Finally, we conclude the paper by summarizing our key findings and suggesting directions for future research in Section 6 .
We review related works on adversarial threats to AI systems, highlighting their contributions and limitations to contextualize this paper within AI security. We deeply respect the significant contributions of the existing frameworks and literature discussed here, which have led the global conversation on AI security. The purpose of this paper is not to negate or replace these works but rather to provide additional insights that can contribute to their practical application. By highlighting the differences and supplementary perspectives, we aim to promote understanding among these works, point out key attack characteristics especially from the viewpoint of security practitioners, and contribute to the future development of international discussions.
Several academic surveys have systematically analyzed adversarial threats and defense methods relevant to predictive AI systems. Kong et al. provide a comprehensive classification that focuses on modality-based attacks, specifically targeting image, text, and malware domains, detailing typical attack algorithms and their corresponding defenses ( Kong et al., 2021 ) . Oseni et al.
analyze adversarial attacks, providing an overview of machine learning and mathematical explanations of attacks ( Oseni et al., 2021 ) . Additionally, Hu et al. categorized adversarial attacks based on the AI system lifecycle, mapping threats to various developmental stages (e.g., data collection, preprocessing, model training, and inference) and highlighting lifecycle-specific vulnerabilities and defenses ( Hu et al., 2021 ) . Chen and Babar also adopt a lifecycle perspective but extend their analysis to software engineering practices and secure development methodologies, thereby offering guidance on the construction of robust AI systems ( Chen and Babar, 2024 ) .
Despite these comprehensive surveys, they predominantly address predictive AI systems, lacking insights into generative AI systems. Recent surveys have begun to address this gap by focusing on large language models (LLMs), a prominent category of generative AI. Yao et al. categorized LLM vulnerabilities into AI-Inherent and Non-AI-Inherent, identifying risks such as model extraction and remote code execution ( Yao et al., 2024 ) . Shayegani et al. systematically surveyed adversarial attacks on LLMs, including multi-modal attacks ( Shayegani et al., 2023 ) , while Dong et al. specifically examined conversation safety, including attack methodologies and corresponding defenses ( Dong et al., 2024 ) . Yan et al. provided a detailed analysis of privacy risks and countermeasures for LLMs ( Yan et al., 2025 ) , and Das et al. further highlighted various security threats, such as jailbreaking and data poisoning ( Das et al., 2025 ) . In contrast, Sun et al. recently surveyed generative adversarial networks (GANs) and variational auto-encoders (VAEs) ( Sun et al., 2023 ) , focusing primarily on model-centric vulnerabilities. Their analysis addresses model-centric vulnerabilities, barely considering broader system integration issues.
As shown above, existing surveys either focus on predictive models or generative models at the model level, leaving open the need for comprehensive studies encompassing systemic vulnerabilities within generative AI systems. Also, these academic surveys are intended for AI researchers rather than practitioners and do not explicitly contrast their findings with practical frameworks, such as NIST AI 100-2e2025 and MITRE ATLAS™.
In the following subsections, we review the prevalent frameworks from a practitioner’s perspective, highlighting their differences from and complementary roles to the academic surveys discussed above. A notable recent work is the updated report titled “Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations” (NIST AI 100-2e2025) ( Vassilev et al., 2025 ) by the National Institute of Standards and Technology (NIST).
Compared to its predecessor ( Vassilev et al., 2024 ) , this latest edition expands its literature review to over 400 references. This literature analysis thoroughly explicates their historical evolution from initial concepts to the latest research. The report also introduces a glossary that provides definitions for AI security terminology. Our paper refers to the NIST report, and the numerous sources cited therein have played a substantial role in our analysis.
Although the newly introduced index has improved navigation, the report’s taxonomy remains complex. NIST classifies attacks first by the targeted AI system type (i.e., predictive and generative AI systems) and then by the attacker’s objectives (i.e., availability, integrity, privacy, misuse, and supply chain attacks). However, many attack methods overlap across these classifications, resulting in repetitive descriptions. For instance, Indirect Prompt Injection ( NISTAML.015 ) and Misaligned Outputs ( NISTAML.027 ) describe identical attacks from different objectives. The specific attack, Model Poisoning, has different IDs ( NISTAML.011 , 026 , and 051 ) across various AI system types and objectives. These overlaps can obscure the practical utility of taxonomy, especially for practitioners.
In contrast, we deliberately adopts a simplified taxonomy. Rather than categorizing attacks according to the type of AI system targeted or the attacker’s objectives, we classify attacks according to their underlying technical methods. By explicitly separating each attack mechanism from the type of AI targeted or its intended objective, this paper remains intuitive and designed to avoid overlaps, thereby focusing on supporting easy comprehension and practical application.
Table 1 shows the mapping of the attacks in this paper to those in the NIST report. This paper includes several attacks not covered in the report that we believe warrant attention, such as I: Code Injection and J: Adversarial Fine-tuning . While we refer to the NIST report’s literature review and detailed technical analysis, this paper introduces simplified categorizations and intuitive visualizations to complement the report’s thorough yet duplicative approach.
Another relevant resource for categorizing adversarial threats against AI systems is MITRE ATLAS™ ( MITRE, 2021 ) , a structured knowledge base designed specifically for adversarial attacks on AI systems. Based on MITRE ATT&CK ® ( MITRE, 2013 ) , the well-known framework in the cybersecurity community, ATLAS systematically categorizes real-world attack scenarios according to hierarchical concepts of tactics (attackers’ goals) and techniques (methods used to achieve those goals).
A key benefit of ATLAS is its practical orientation, which explicitly maps attacks to specific threat scenarios observed in real-world deployments. It provides actionable insights, particularly for cybersecurity professionals, by linking detailed descriptions of adversarial tactics and techniques to documented examples. In addition, ATLAS effectively illustrates attacker capabilities and objectives, facilitating realistic risk assessments.
Table 2 illustrates the correspondence between our attack categorization and ATLAS. This work elucidates attacks not shown in ATLAS, including B2: Attribute Inference , B3: Property Inference , G: Prompt Stealing , J: Adversarial Fine-tuning , and K: Rowhammer attacks. Our work complements ATLAS’s practical nature by systematically integrating relatively recent findings, thereby providing broader coverage of emerging threats.
A further influential resource addressing security risks in LLMs is the OWASP Top 10 for LLM Applications (Version 2025) ( Wilson and Dawson, 2024 ) . This document is published by the Open Web Application Security Project (OWASP), an international organization recognized worldwide for its contributions to cybersecurity, most notably the famous OWASP Top 10 for web application security ( van der Stock et al., 2021 ) .
In the context of AI security, the OWASP Top 10 for LLM identifies the most critical vulnerabilities, including Prompt Injection, Sensitive Information Disclosure, Supply Chain Vulnerabilities, System Prompt Leakage, and emerging concerns related to multimodal interactions. The primary benefit of the OWASP approach is in its practicality and clarity, effectively translating complex AI security concepts into straightforward, actionable guidance.
While the OWASP framework provides clear and practical insights into the immediate security risks of LLM applications, it does not aim to provide a detailed categorization of attacker tactics and techniques. Consequently, it provides limited insight into attacker capabilities and the technical foundations of various attack methods. Additionally, OWASP primarily focuses on LLM-specific vulnerabilities, which may limit its applicability to broader AI system architectures and modalities.
Our categorization complements OWASP by providing a more systematic structure spanning a broader range of AI modalities, thereby supporting practical and analytical use cases. A further relevant resource is the AI Quality Management Guideline (AIQM) ( Digital Architecture Research Center et al., 2024 ) , whose fourth edition significantly expanded its coverage of AI security, particularly in Section 10.3. The AIQM focuses on the systematization of machine learning-specific threats, vulnerabilities, and security controls, providing substantial insights based on an extensive review of the academic literature and elaborating technical details in the paper ( Kawamoto et al., 2023 ) . Our paper also cites many of the same foundational sources and acknowledges the contributions of the AIQM.
Due to its lifecycle or process-oriented description style, AIQM structures its discussions through deeply nested subsections that spread explanations of individual attacks across multiple contexts, such as system impacts, attacker goals, and specific techniques. This structure could make it difficult for readers to gain a coherent understanding of specific attack scenarios. In contrast, our work provides a simpler representation of attacks and thus complements the detailed but dispersed approach by AIQM.
While various organizations have published guidelines and frameworks addressing risk management and secure development practices for AI systems ( of Standards and Technology, 2023a ; of Standards and Technology, 2023b ; Centre, 2024 ; Centre et al., 2023 ; Adamczyk et al., 2023 ; Ntalampiras et al., 2023 ) , specific AI attack methodologies are generally beyond the scope of these publications.
Finally, another relevant resource is the Guide to Red Teaming Methodology on AI Safety ( (2024a), J-AISI ) , published by J-AISI. This guide is a preliminary effort by our institute to provide practical and structured recommendations for planning, preparing, and conducting red teaming exercises for LLM systems. It briefly introduces representative attacks such as prompt injection as illustrative examples to support practical system evaluation and risk mitigation. The guide’s primary objective is to outline the overall red teaming process. Accordingly, its coverage of adversarial threats remains limited, offering neither detailed explanations nor a comprehensive taxonomy of attacks. This paper complements the guide by providing deeper technical explanations, a broader range of adversarial threats, and detailed insights into attack mechanisms and impacts. Our categorization serves as a handy resource for identifying and prioritizing adversarial threats, further enhancing the practical red teaming methodologies proposed by J-AISI.
To establish a foundation for the subsequent discussion, this section defines a generalized architecture for AI systems and outlines the scope of attacks that will be examined in this paper. An AI system is an information system that incorporates AI models as components. Figure 2 illustrates the generalized AI system architecture assumed in this paper. The system is conceptually divided into two primary environments: Training Environment (upper part of Figure 2 ): In this environment, AI models undergo training and fine-tuning using datasets that include data collected during real-world operations. We also consider scenarios involving continuous or periodic fine-tuning, leveraging data obtained from operational activities.
Operation Environment (lower part of Figure 2 ): Here, the trained AI model is deployed and integrated into an application framework. Data inputs from external systems, sensors, or human users are processed by the model, producing outputs that could be directed toward the same or different external entities. Data generally flows from left to right. Detailed descriptions of each component illustrated in Figure 2 are provided in Appendix A.1 . The system architecture considers the integration of internal and external knowledge through plugins or retrieval-augmented generation (RAG), primarily associated with LLMs. Note that our discussion applies beyond LLM-based systems.
5. Performance Evaluation & Extended Technical Observations This abstracted model simplifies complex real-world architectures while retaining enough detail to analyze vulnerabilities realistically and practically. Nonetheless, it is not a one-size-fits-all framework. Specific advanced machine learning architectures, such as federated learning, do not fit into this abstraction and necessitate dedicated analyses of unique vulnerabilities.
Securing AI systems inherently involves traditional cybersecurity measures to mitigate conventional cyber threats. In this paper, we presuppose that general cybersecurity practices such as protection against unauthorized network access are already in place. Thus, we explicitly focus on AI-specific attacks involving interference with AI model training or inference, as well as the manipulation or misuse of AI model inputs and outputs on the targeted system .
We do not address attacks that exploit standard cybersecurity vulnerabilities, such as unauthorized access resulting in the theft of AI models unless these attacks explicitly interfere with the AI-specific processes. The volume of research on attacks against AI systems has grown considerably, making it impractical to survey all existing literature exhaustively. Thus, this paper does not assert completeness in that sense. Instead, we have incorporated both well-known foundational works, as delineated in Section 2 , and recent advancements from academic conferences.
This section describes our classification of attacks targeting AI systems and explains the relationship between these attacks and their impacts on AI systems. We derived the types of attacks and impacts summarized in this paper from a review and integration of the sources discussed in Section 2 , following the procedure outlined below: Identification and Extraction: We identified and extracted relevant descriptions corresponding to potential attacks and impacts from the referenced materials in Section 2 . We also extracted unique attack methods identified by the authors in recent papers ( Chen et al., 2024 ; Li et al., 2024b ; Nazari et al., 2024 ; Yi et al., 2024 ; Zhao et al., 2024 ) from international conferences, such as the ACM CCS.
Mapping to the AI System Architecture: We mapped the attack methods extracted above to the generalized AI system architecture presented in Figure 2 , taking a technical perspective, such as the attack surface and targeted components. Grouping: We grouped similar or related attacks along with the mapping in (2) into attack types (see Figure 1 ). The impacts extracted in (1) were also grouped based on the components affected in the AI system architecture and the perspective of the CIA triad (see Figure 3 ).
Linking Attacks to Impacts: We linked each attack type to its impacts on the AI system based on referenced materials (see Figure 4 and Table 4 ). The following subsections explain the final categorization of attacks and impacts obtained through this methodology. As shown in Figure 1 , this paper classifies attacks against AI systems into eleven types, labeled A through K. Each type represents a unique attack vector linked to AI-specific vulnerabilities in AI systems. Detailed explanations of each attack type are provided in Section 5 .
The naming convention of attacks adopted in this work largely adheres to established academic and industry terminology, thereby enhancing readability and comprehension. Among the attack categories delineated in this work, “Training Data–related Information Gathering” (Attack B) is newly introduced as a class that encompasses attacks intended to extract or infer information about a model’s training dataset.
For multiple established terms describing the same attack from different perspectives, we primarily choose a naming based on the technical mechanism of the attack. For instance, while both “Prompt Injection” and “Jailbreak” frequently denote the same attack, we adopt “Prompt Injection” because it reflects the underlying mechanism, whereas “Jailbreak” emphasizes the result bypassing safeguards. This naming convention provides a precise understanding by recognizing that a single attack technique can fulfill multiple adversarial objectives. We reflect this insight in our taxonomy, which separates attacks and their impacts.
In certain instances, prevailing industry terminology does not adequately address attacker methodologies, and there is a lack of established alternatives. We retain these terms rather than introducing new ones to ensure familiarity and maintain compatibility with existing literature. In Figure 1 , we delineated a wide array of attacks on AI systems. Figure 3 illustrates the various impacts that these attacks can have on AI systems. Eleven types of impacts have been identified, ranging from model leakage and data leakage to operational failures, safeguard bypasses, and system compromise. Appendix A.2 gives additional explanations for these eleven impacts.
Figure 4 visually maps the relationships between attack types (shown in Figure 1 ) and their corresponding impacts (shown in Figure 3 ) on AI systems from the perspectives of confidentiality, integrity, and availability, known as the CIA triad of security. Dashed arrows indicate impacts that can facilitate subsequent attacks, thus capturing potential cascading risks. Notably, impact “9: System Compromise” is highlighted due to its potential to enable various subsequent attacks, including conventional cybersecurity threats, affecting all aspects of the CIA triad.
Table 3 provides a reverse-lookup capability to identify attack types from their impacts on AI systems. Each listed attack is hyperlinked to detailed discussions in Section 5 . This table can be used for risk assessment and red-teaming activities, as it directly links observed impacts to relevant attacks that need to be addressed. In this section, we provide detailed descriptions of the eleven attack types (A–K) previously introduced in Figure 1 . For each attack type, we present a figure of the high-level flow from the initiation of the attack to its eventual impacts on the system.
Table 4 summarizes known attack types and their corresponding impacts on AI systems. For each attack, the assumed capabilities of the attacker are listed, along with the modalities and the types of AI models demonstrated in the literature, accompanied by references to the relevant papers. It is important to note that the modalities and targeted AI model types listed in Table 4 are summaries based on experimental demonstrations documented in the literature and do not necessarily indicate inherent limitations of the attack methods themselves.
In Table 4 , the following abbreviations are used for AI model types: NN (Neural Network), LR (Logistic Regression), RR (Ridge Regression), SVM (Support Vector Machine), DT (Decision Tree), kNN (Nearest Neighbor), HMM (Hidden Markov Model), LM (Language Model), LSTM (Long-short Term Memory), RNN (Recurrent Neural Network), EM (Ensemble Method), and DA (Decomposable Attention).
Model extraction attacks involve adversaries who do not have direct access to the internal details of an AI model (e.g., users interacting via a publicly accessible API). By systematically querying the model with various inputs and analyzing the corresponding outputs, an attacker attempts to infer sensitive information about the underlying model structure and parameters (Figure 5 ).
The motivations for model extraction have grown alongside AI’s increasing economic and societal importance. State-of-the-art AI models typically embody extensive training investments, both in terms of computational resources and proprietary datasets. As a result, such an attempt could be highly valuable for attackers, for instance, who might sell the extracted model in black markets. Moreover, model extraction often acts as a stepping stone for more sophisticated attacks, such as Training Data-related Information Gathering (Attack B in Section 5.2 ) and Evasion (Attack E in Section 5.5 ).
Previous research has demonstrated the feasibility of extracting various forms of model-specific information, such as: Model Architecture (e.g., the structure and configuration of neural networks) ( Oh et al., 2019 ) Hyperparameters (e.g., regularization parameters to prevent overfitting during training) ( Wang and Gong, 2018 ) Decision Boundaries (boundaries where model predictions change class in input space) ( Juuti et al., 2019 ) Functionality (the model’s input–output relationships without internal structures) ( Correia-Silva et al., 2018 ; Orekondy et al., 2019 ) Table 4 summarizes the modalities and AI model types examined by these representative studies.
Several approaches have been proposed to mitigate model extraction attacks. A basic defense principle is to minimize unnecessary information disclosure, such as providing only discrete classification results without associated confidence scores. Detection-oriented methods, including tools such as PRADA ( Juuti et al., 2019 ) , monitor query patterns to identify suspicious extraction attempts. In addition, input perturbation or obfuscation techniques have been proposed to disrupt attackers’ attempts to accurately infer model information without significantly impairing legitimate usage ( Grana, 2020 ) .
Frameworks such as ML-Doctor ( Liu et al., 2022 ) have also been introduced to assess an AI model’s vulnerability to extraction attacks. Ensemble learning can also provide robustness by obscuring or diversifying the model’s behavior, thus complicating the extraction process. While not preventing the initial attack, watermarking ( Li et al., 2023 ) and fingerprinting ( Cao et al., 2021 ) methods have been explored as reactive measures, providing mechanisms to detect or prove unauthorized copies of models after extraction has occurred.
It is worth noting the conceptual similarity and critical distinction between model extraction and the well-known machine learning practice of knowledge distillation. Knowledge distillation refers to a technique intentionally used by developers to create smaller, computationally efficient (“student”) models that mimic the behavior of a larger, more complex (“teacher”) model. The fundamental difference lies in intent and legitimacy: knowledge distillation is explicitly intended and conducted by authorized entities for efficiency and scalability purposes, not for unauthorized reproduction or redistribution of intellectual property. Thus, it is typically not classified as an adversarial attack. Nevertheless, due to concerns about unauthorized model duplication, many AI service providers explicitly prohibit knowledge distillation in their terms of service.
In contrast to direct data theft, the category of attacks referred to as Training Data-related Information Gathering involves extracting or inferring information related to the training data of an AI model by systematically observing its inputs and corresponding outputs, and in some cases by exploiting internal information about the model itself (see Figure 6 ). The term “related information” here encompasses a broad spectrum of scenarios in which information about the training data is revealed indirectly, extending beyond the direct extraction of original training examples. Typical attacks include Membership Inference , which infers whether certain individuals or records were part of the training dataset; Attribute Inference , which infers unknown sensitive attributes of particular records in the dataset; Property Inference , which aims to infer general statistical characteristics of the dataset; Model Inversion , which reconstructs representative class-level samples by iteratively querying model outputs; Data Reconstruction , where attackers leverage internal model parameters or intermediate representations to theoretically reconstruct precise, specific training data samples; and Data Extraction , which retrieves exact memorized training examples directly from the model outputs, especially in generative contexts.
This type of attack involves inferring whether specific data samples were included in the training dataset by observing the model’s input–output behavior. Such attacks pose serious privacy threats, particularly when models are trained on sensitive data. For example, an AI system trained on financial records of loan defaults, could reveal sensitive personal information simply by leaking whether a specific individual’s history was part of its training dataset.
A typical implementation of this attack involves the use of shadow models that mimic the behavior of the target model. The attacker first trains shadow models using datasets whose membership status (included or excluded) of each sample is known. Then, another model (often referred to as the attack model) learns the differences in shadow model behavior for data samples that are included or excluded in their training datasets. Using this attack model, the attacker can infer the membership status of specific data points from the output of the target model. Table 4 summarizes the literature on membership inference attacks across various modalities and model types.
Preventing Overfitting: Employing regularization techniques during model training to minimize unintended memorization of training data. Assessment Tools: Utilizing specialized analysis tools (e.g., ML Privacy Meter ( Murakonda and Shokri, 2020 ) or ML-Doctor ( Liu et al., 2022 ) ) to proactively assess and mitigate membership inference attacks.
Output Control: Reducing the detail of outputs. Examples include reporting only top predictions without confidence scores or reducing the numerical precision of outputs. Differential Privacy: Incorporating differential privacy mechanisms to mathematically limit information leakage about any individual data point.
This type of attack refers to inferring unknown sensitive attributes (e.g., a specific genotype) of data samples used to train an AI model by exploiting publicly available or partially known information (e.g., age, gender obtained from social media) and the input–output behavior of the model ( Yeom et al., 2018 ) . In other words, with partial knowledge of certain attributes, an attacker can infer sensitive attributes that should remain confidential, potentially leading to the unintended disclosure of highly private personal information. Table 4 summarizes the literature on attribute inference attacks across various modalities and model types.
To mitigate attribute inference attacks, measures similar to those used for membership inference attacks can be employed, including regularization to prevent overfitting and differential privacy to limit leakage of sensitive attributes. This type of attack infers global statistical properties of the training dataset by analyzing information derived from the model. In contrast to membership or attribute inference, which target specific data samples or attributes, property inference attacks target general dataset-level characteristics (e.g., distributional properties, proportion of a particular demographic group).
Figure 1 in the foundational paper ( Ganju et al., 2018 ) provides an overview of how a property inference attack can be performed. First, an attacker trains multiple shadow classifiers, some on datasets containing a certain statistical property P P , and others on datasets lacking that property (denoted as P ¯ \overline{P} ). Then, features such as internal parameters or outputs are extracted from these shadow classifiers and used to construct a meta-training dataset. This dataset is subsequently used to train a meta-classifier capable of distinguishing between models trained with and without the property P P . Finally, by extracting similar features from a target model, the attacker can infer whether the target model’s training dataset possesses the property P P . Table 4 summarizes the literature on property inference attacks across various modalities and model types.
Harvested Online Documentation & Reference Sources • https://arxiv.org/html/2502.05637v1 • https://arxiv.org/abs/2412.11384 • https://aisecurityandsafety.org/en/guides/adversarial-attacks/ • https://arxiv.org/html/2506.23296v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Adversarial Attacks On Machine Learning Security Models Project.
[*] Metasploit Scan Running on Target Subnet for Adversarial Attacks On Machine Learning Security Models Project... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |