Complete Technical Paper Content — Ai Powered Penetration Testing Bot
Overview & System Context
Ai Powered Penetration Testing Bot: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9636 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background A penetration test, colloquially known as a pentest, is an authorized simulated cyberattack on a computer system, performed live to evaluate the security of the system. The test is performed to identify weaknesses (or vulnerabilities), including the potential for unauthorized parties to gain access to the system's features and data, as well as strengths, enabling a full risk assessment to be completed. The process typically identifies the target systems and a particular goal, then reviews available information and undertakes various means to attain that goal. A penetration test target may be a white box (about which background and system information are provided in advance to the tester) or a black box (about which only basic information other than the company name is provided). A gray box penetration test is a combination of the two (where limited knowledge of the target is shared with the auditor). There are different types of penetration testing, depending on the goal of the organization which include: Network (external and internal), Wireless, Web Application, Social Engineering, and Remediation Verification. A penetration test can help identify a system's vulnerabilities to attack and estimate how vulnerable it is. The UK National Cyber Security Center describes penetration testing as: "A method for gaining assurance in the security of an IT system by attempting to breach some or all of that system's security, using the same tools and techniques as an adversary might." Penetration tests are a component of a full security audit. For example, the Payment Card Industry Data Security Standard requires penetration testing on a regular schedule, and after system changes. Penetration testing also can support risk assessments as outlined in the NIST Risk Management Framework SP 800-53. Several standard frameworks and methodologies exist for conducting penetration tests. These include the Open Source Security Testing Methodology Manual (OSSTMM), the Penetration Testing Execution Standard (PTES), the NIST Special Publication 800-115, the Information System Security Assessment Framework (ISSAF) and the OWASP Testing Guide. CREST, a not for profit professional body for the technical cyber security industry, provides its CREST Defensible Penetration Test standard that provides the industry with guidance for commercially reasonable assurance activity when carrying out penetration tests. Since 2017 the terms Penetration Testing as a Service (PTaaS) has become popular. This involves using a platform to invoke a test as an alternative to using consultants.
Find an exploitable vulnerability. Design an attack around it. Test the attack. Seize a line in use. Enter the attack. Exploit the entry for information recovery. Over time, Anderson's description of general computer penetration steps helped guide many other security experts, who relied on this technique to assess time-sharing computer system security. In the following years, computer penetration as a tool for security assessment became more refined and sophisticated. In the early 1980s, the journalist William Broad briefly summarized the ongoing efforts of tiger teams to assess system security. As Broad reported, the DoD-sponsored report by Willis Ware "...showed how spies could actively penetrate computers, steal or copy electronic files and subvert the devices that normally guard top-secret information. The study touched off more than a decade of quiet activity by elite groups of computer scientists working for the Government who tried to break into sensitive computers. They succeeded in every attempt." While these various studies may have suggested that computer security in the U.S. remained a major problem, the scholar Edward Hunt has more recently made a broader point about the extensive study of computer penetration as a security tool. Hunt suggests in a recent paper on the history of penetration testing that the defense establishment ultimately "...created many of the tools used in modern day cyberwarfare," as it carefully defined and researched the many ways that computer penetrators could hack into targeted systems.
BlackArch based on Arch Linux BackBox based on Ubuntu Kali Linux (replaced BackTrack December 2012) based on Debian Parrot Security OS based on Debian Pentoo based on Gentoo WHAX based on Slackware Many other specialized operating systems facilitate penetration testing—each more or less dedicated to a specific field of penetration testing. A number of Linux distributions include known OS and application vulnerabilities, and can be deployed as targets to practice against. Such systems help new security professionals try the latest security tools in a lab environment. Examples include Damn Vulnerable Linux (DVL), the OWASP Web Testing Environment (WTW), and Metasploitable.
Proxmark3 — multi-purpose hardware tool for radio-frequency identification (RFID) security analysis. BadUSB — toolset for exploiting vulnerabilities in USB devices to inject malicious keystrokes or payloads. Flipper Zero — portable, open-source multi-functional device pentesting wireless protocols such as Sub-GHz, RFID, NFC, Infrared and Bluetooth. Raspberry Pi — a compact, versatile single-board computer commonly used in penetration testing for tasks like network reconnaissance and exploitation. SDR (Software-defined Radio)— versatile tool for analyzing and attacking radio communications and protocols, including intercepting, emulating, decoding, and transmitting signals. ChipWhisperer — specialized hardware tool for side-channel attacks, allowing analysis of cryptographic implementations and vulnerabilities through power consumption or electromagnetic emissions.
Figure 1: Top 10 Web Application Penetration Testing Tools 2026IEscape Reconnaissance: The act of gathering important information on a target system. This information can be used to better attack the target. For example, open source search engines can be used to find data that can be used in a social engineering attack. Scanning: Uses technical tools to further the attacker's knowledge of the system. For example, Nmap can be used to scan for open ports. Gaining access: Using the data gathered in the reconnaissance and scanning phases, the attacker can use a payload to exploit the targeted system. For example, Metasploit can be used to automate attacks on known vulnerabilities.
Once an attacker has exploited one vulnerability they may gain access to other machines so the process repeats i.e. they look for new vulnerabilities and attempt to exploit them. This process is referred to as pivoting. Maintaining access: Maintaining access requires taking the steps involved in being able to be persistently within the target environment in order to gather as much data as possible. Covering tracks: The attacker must clear any trace of compromising the victim system, any type of data gathered, log events, in order to remain anonymous. Reporting: Vulnerabilities are classified via risk matrix and documented in a report which contains executive summary, vulnerability description, and recommendations for remediation.
Remediation & Re-testing: Once the target organization assesses the penetration test report and remediates items based on their internal risk appetite, a re-test of those vulnerabilities is performed in order to confirm remediation was successful, and a cut down re-test report is provided showing the results. Red team exercises are an extension of penetration testing in which a dedicated adversarial team (the red team) simulates a sophisticated, sustained attack against an organisation's people, processes, and technology — without the defending team (the blue team) being fully aware of the timing or scope. This differs from a standard penetration test in that it focuses on testing the organisation's detection and response capabilities, not just its technical vulnerabilities. Purple team exercises involve the red and blue teams working collaboratively, such as by sharing information in real time.
F5, Inc. is an American technology company specializing in multicloud application delivery, API security, online fraud prevention, zero trust access, and enterprise AI workload security. While F5 originally developed hardware-based application delivery controller (ADC) load-balancing appliances, the company has transitioned to a software-led business model. Software subscriptions and cloud-delivered services now account for a major portion of its product revenue, driven by a corporate shift toward predictable, recurring subscription models. The technological core of F5's platform portfolio is its Traffic Management Operating System (TMOS). F5 offers these services as virtual machines (branded as the BIG-IP Virtual Edition) that deploy programmatically across hybrid, multi-cloud, on-premises, and network edge environments to manage traffic, secure public APIs, and enforce zero-trust identity policies.
F5 AI Red Team: An automated adversarial testing system that simulates attacks on AI applications to identify vulnerabilities, such as jailbreak vulnerabilities and model data poisoning, prior to production deployment. F5 AI Guardrails: A real-time, inline semantic firewall that inspects user prompts and model-generated responses. It is designed to block injection attacks, filter out off-topic or toxic responses, and apply dynamic data loss prevention (DLP) parameters to prevent sensitive data leakage.
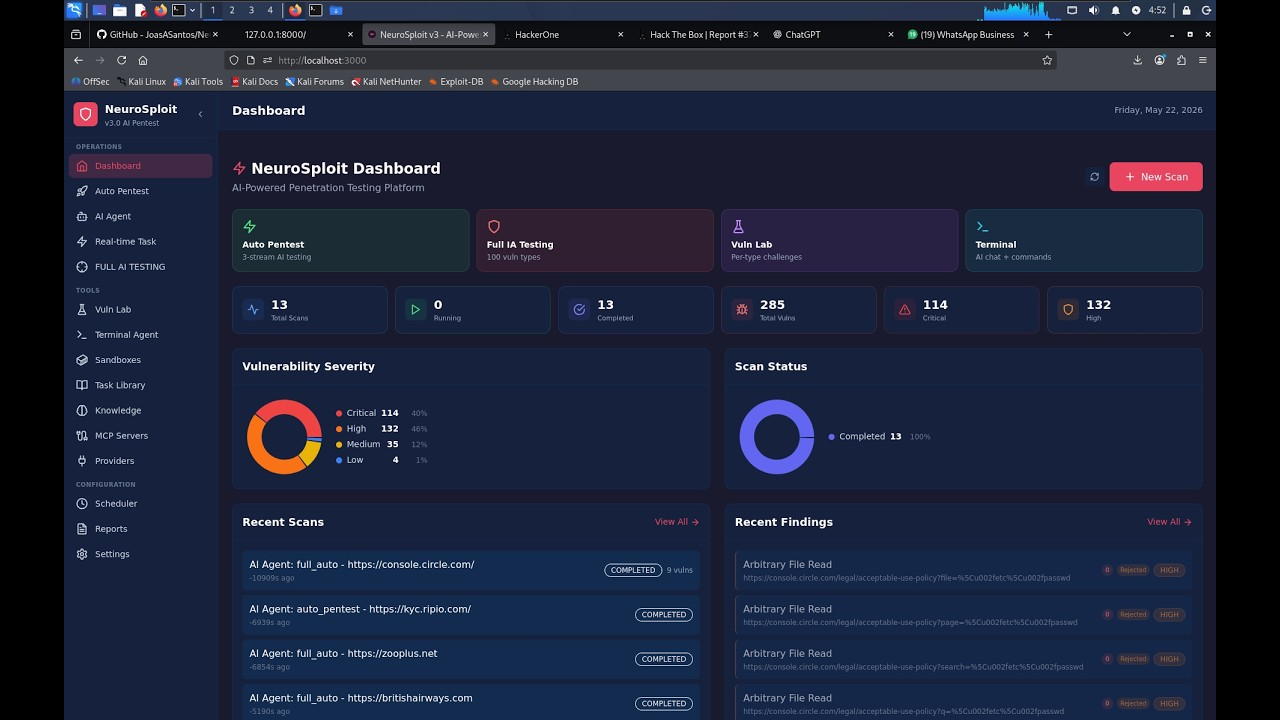
Figure 2: NeuroSploit AI I | Autonomous Penetration Testing Platform - YouTube The move from BSD to Linux to handle system management functions (disks, logging, bootup, console access, etc.) The creation of a Traffic Management Microkernel (TMM) to directly talk to the networking hardware and handle all network activities.
This is a list of free and open-source software (FOSS) packages, computer software licensed under free software licenses and open-source licenses. Software that fits the Free Software Definition may be more appropriately called free software; the GNU project in particular objects to their works being referred to as open-source. For more information about the philosophical background for open-source software, see free software movement and Open Source Initiative. However, nearly all software meeting the Free Software Definition also meets the Open Source Definition and vice versa. A small fraction of the software that meets either definition is listed here. Some of the open-source applications are also the basis of commercial products, shown in the List of commercial open-source applications and services.
Cline – AI coding agent for IDEs and the command line. Codex CLI – AI coding agent and command-line interface developed by OpenAI. Command Code — CLI and desktop AI agent DeepSeek Coder – large language model designed for code generation and AI-assisted software development. Eclipse Theia – integrated development environment and framework with AI-assisted software development features. goose – AI coding agent for the desktop and command line. Kilo Code — CLI and IDE extension developed by Anaconda OpenCode — CLI, desktop app, web app, and IDE extensions OpenHands — AI software development agent Oh My Pi – terminal-based AI coding agent developed as a fork of Pi. Pi – terminal-based AI coding agent. Zed – source-code editor with integrated AI-assisted development and agentic coding features.
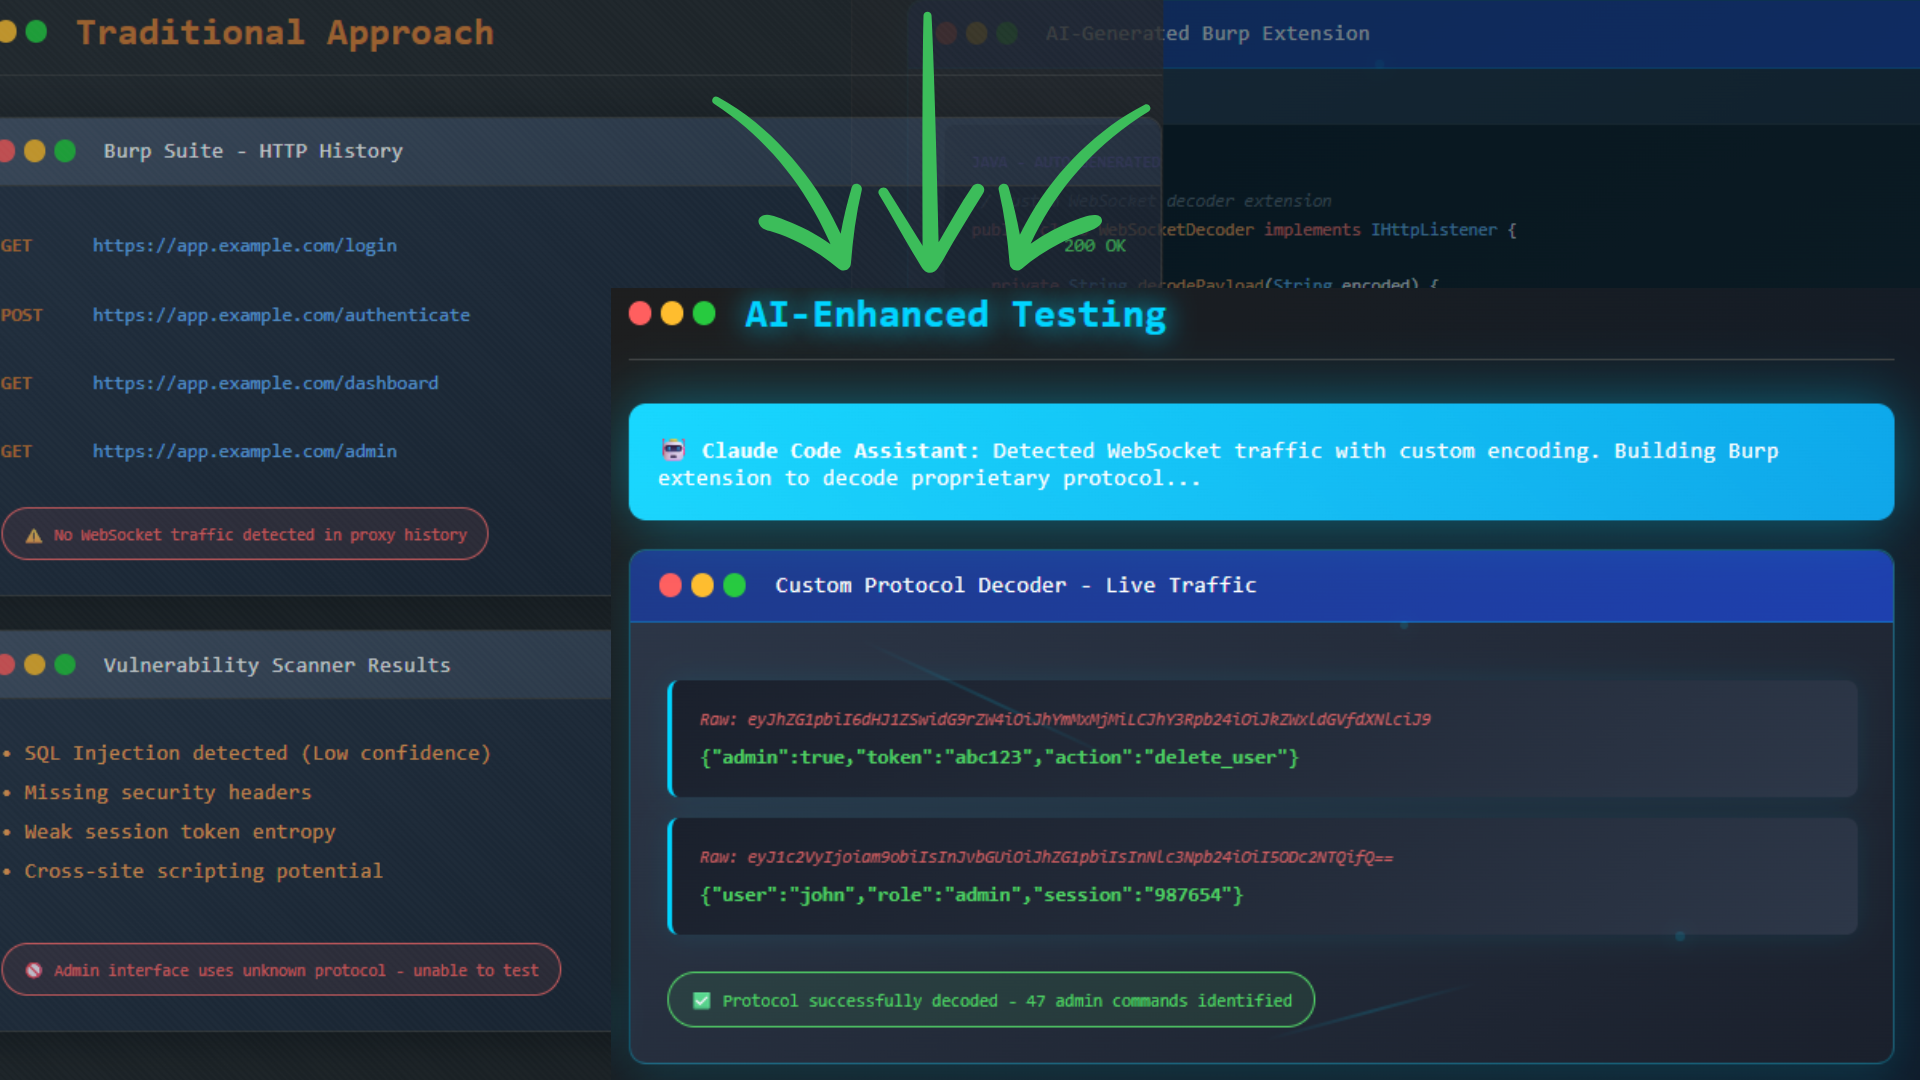
Apertus – Swiss National AI Initiative LLM BERT – Google LLM BLOOM – BigScience multilingual LLM Cerebras-GPT – Cerebras Systems LLMs DeepSeek – R1 and V3 models Gemma 4 – Google LLM GLM-4.5 and later versions – Z.ai LLMs GPT-1, GPT-2, and GPT-OSS – OpenAI LLMs GPT-J, GPT-Neo, and GPT-NeoX – EleutherAI LLMs Hy – Tencent open-weight LLM Granite – IBM LLMs Grok-1 – xAI LLM Inkling – Thinking Machines Kimi (some versions) – Moonshot AI LLMs MiMo (some versions) – Xiaomi LLMs Mistral (some versions) Muse Glimmer — Meta Superintelligence Labs LLM Nemotron 3 – Nvidia open-weight models OLMo – Allen Institute for AI LLM Phi – Microsoft LLMs Qwen (some versions) – Alibaba Cloud LLMs Sarvam-M, Sarvam-105B and Sarvam-30B – Sarvam AI LLMs SmolLM – Hugging Face small language models (SLMs) Step-3.7Flash – StepFun LLM T5 – Google LLM XLNet – Google LLM Figure 3: The Real AI Revolution in Penetration Testing ArduPilot CoppeliaSim Gazebo Mobile Robot Programming Toolkit OpenRTM-aist Paparazzi Project Player Project Python Robotics Robot Operating System (ROS) TurtleBot UBtech Thinker Webots – robot simulator Archimedes (CAD) Art of Illusion Blender BRL-CAD – constructive solid geometry (CSG) solid modeling computer-aided design (CAD) system FreeCAD – parametric 3D CAD modeler with a focus on mechanical engineering, BIM, and product design LeoCAD — beginner Lego 3D modeler LibreCAD – 2D CAD software using AutoCAD-like interface and file format MakeHuman MeshLab Open Cascade Technology (OCCT) – CAD kernel for 3D CAD, CAM, CAE OpenSCAD – scripting-based 3D CAD software QCAD SolveSpace – 2D and 3D CAD, constraint-based parametric modeler with simple mechanical simulation abilities Sweet Home 3D Wings 3D Electric FreePCB Fritzing – CAD software for the design of electronics hardware to build more permanent circuits from prototypes gEDA GNU Circuit Analysis Package (Gnucap) Icarus Verilog KiCad – suite for electronic design automation (EDA) for schematic capture, PCB layout, manufacturing file viewing, SPICE simulation, and engineering calculation KTechLab Magic Ngspice pcb-rnd Oregano Quite Universal Circuit Simulator (QUCS) Verilator XCircuit Blender – 3D computer graphics software toolset used for creating animated films, visual effects, art, 3D printed models, and motion graphics FreeCAD – equivalent of Blender geared toward mechanical engineers OpenFOAM – software used for computational fluid dynamics (or CFD) FlightGear – atmospheric and orbital flight simulator with a flight dynamics engine (JSBSim) that was used in a 2015 NASA benchmark to judge new simulation code to space industry standards SimPy – queue-theoretic event-based simulator written in Python Salome – generic platform for Pre- and Post-Processing for numerical simulation OpenPGP – open-source version of Pretty Good Privacy GNU Privacy Guard – replacement for PGP OpenSSL – library for applications that provide secure communications over computer networks NaCl (software) – crypto library Libsodium – fork of NaCl VeraCrypt – disk encryption software forked from TrueCrypt LUKS – standard for disk encryption on Linux systems Nym (mixnet) – mix network that uses noise and random packet timing for obfsucation, overlay network for NymVPN Tor (network) – free overlay network for enabling anonymous communication Tails (operating system) – security-focused Linux distro using Tor by default Signal (software) – secure messaging app Off-the-Record Messaging – protocol for secure instant messaging GPGTools – macOS suite for GnuPG-based encryption Aircrack-ng – Wi-Fi security auditing tool BackTrack – predecessor to Kali Linux Burp Suite Community Edition – security assessment and penetration testing of web applications Ghidra – software reverse engineering suite developed by the NSA Hashcat – password recovery utility High Orbit Ion Cannon – DDoS hping3 — packet crafting and network penetration-testing utility Hydra (software) – login cracker supporting numerous protocols John the Ripper – password cracking tool Kali Linux – penetration testing Linux distribution Metasploit Project – framework for developing and executing exploit code Netcat – network utility for reading/writing data across networks Nikto (vulnerability scanner) – web server vulnerability scanner Nmap – network scanning, port scanner, and auditing tool OpenSSH – implementation of the SSH protocol Radare2 – reverse engineering framework Snort (software) – network intrusion detection system sqlmap – automated SQL injection and database takeover tool Suricata (software) – network threat detection engine Volatility (memory forensics) – memory forensics framework for incident response Wireshark – network protocol analyzer YARA – tool to identify and classify malware qBittorrent – BitTorrent client Transmission (BitTorrent client) – lightweight BitTorrent client IPFS – InterPlanetary File System for decentralized storage and sharing RetroShare – secure communication platform with file sharing Zerocoin – privacy-focused cryptocurrency protocol Zcash – cryptocurrency based on Zerocoin using zk-SNARKs Monero – privacy-focused cryptocurrency using ring signatures NYM — Nym mixnet privacy- and security-focused token Tornado Cash — Cryptocurrency tumbler ClamAV – cross-platform antimalware toolkit written in C and C++, able to detect many types of malware including viruses ClamWin – antivirus tool for Windows and written in C, C++ Lynis – security audit tool (set of shell scripts) for Unix and Linux Bouncy Castle GnuPG GnuTLS KGPG NaCl OpenSSL Seahorse Signal stunnel TextSecure wolfCrypt 7-Zip Snort – network intrusion detection system (IDS) and intrusion prevention system (IPS) Suricata – network threat detection engine OpenVAS – software framework of several services and tools offering vulnerability scanning and vulnerability management Nmap – network scanner, port scanner, and security auditing tool Nikto – web server vulnerability scanner Volatility – memory forensics framework for incident response Cyberduck – macOS and Windows client (since version 4.0) Lsh – server and client, with support for SRP and Kerberos authentication OpenSSH – client and server PuTTY – client-only Apache Cassandra – NoSQL database from Apache Software Foundation offers support for clusters spanning multiple datacenter Apache CouchDB – NoSQL database from Apache Software Foundation with multi-master replication MariaDB – community-developed relational database management system with pluggable storage engines and commercial support PostGIS – adds support for geographic objects to the PostgreSQL as per Open Geospatial Consortium (OGC) PostgreSQL – relational database management system emphasizes on extensibility and SQL compliance and available for Windows, Linux, FreeBSD, and OpenBSD ATutor – web-based Learning Content Management System (LCMS) Canvas LMS – web-based, open, extensible learning management system Chamilo – web-based e-learning and content management system Claroline – collaborative Learning Management System DoceboLMS – SAAS/cloud platform for learning eFront – icon-based learning management system H5P – framework for creating and sharing interactive HTML5 content IUP Portfolio – educational platform for Swedish schools ILIAS – web-based learning management system (LMS) Moodle – learning management system OLAT – web-based Learning Content Management System Omeka – content management system for online digital collections Sakai Project – web-based learning management system SWAD – web-based learning management system Kiwix – offline web browser that allows users to download Wikipedia's entire content and use it for offline learning. Later it was expanded with repositories for Wikimedia Foundation, public domain texts from Project Gutenberg, many of the Stack Exchange sites, and other resources OpenStreetMap – OpenStreetMap was developed in 2004. It uses Open data and users data input through Crowdsourcing and Web mapping to create a complete and downloadable alternative to other online maps.
This allow users to enter data when there is no data available due to lack of governance and economic interest or due to lower population of the places mapped Advanced Simulation Library ASCEND Calcpad Calculix CHEMKIN – chemical kinetics COCO simulator – chemical process simulator CP2K – quantum chemistry and solid-state physics DWSIM – chemical process simulator General Mission Analysis Tool (GMAT) – space mission analysis GNU Octave – numerical-analysis GROMACS – simulations of proteins, lipids, and nucleic acids JSBSim – flight dynamics engine LAMMPS – Molecular dynamics Open Babel – chemical informatics OpenModelica – chemical process simulator OpenSees – earthquake engineering OpenVSP – parametric aircraft geometry tool Pyomo – mathematical optimization QBlade – wind turbine design and aerodynamic simulation software REFPROP – reference Fluid Thermodynamic and Transport Properties XFOIL – analysis of subsonic isolated airfoils .apng – Animated Portable Network Graphics .avif – AV1 Image File Format .bpg – Better Portable Graphics .exr – OpenEXR .fits – Flexible Image Transport System primarily for Astronomy .flif – Free Lossless Image Format .gif – Graphics Interchange Format .iff / .lbm – InterLeaved BitMap .jng – JPEG Network Graphics .jpg or .jpeg – Joint Photographic Experts Group .jxl – JPEG XL .mng – Multiple-image Network Graphics .miff / .mi – Magick Image File Format .pam, .pbm, .pgm, .ppm, .pnm – Netpbm file formats .pgf – Progressive Graphics File .png – Portable Network Graphics .qoi – Quite OK Image Format .tiff – Tag Image File Format .wbmp – Wireless Application Protocol Bitmap Format .webp .xbm – X BitMap .xcf – GIMP .xpm – X PixMap .adoc – AsciiDoc .epub – ebook format .latex – LaTeX, macro package built on top of TeX for simplification .md – Markdown .odt – OpenDocument .rtf – Rich Text Format .tex – high-quality typography for mathematical notation, physics, chemistry, engineering/scientific notation .texinfo 1DayLater – invoicing software GnuCash – double-entry book-keeping HomeBank – personal accounting software KMyMoney – double-entry book-keeping LedgerSMB – double-entry book-keeping RCA open-source application – management accounting application SQL-Ledger – double-entry book-keeping TurboCASH – double-entry book-keeping for Windows 2. System Architecture & Core Working Principles Bitcoin – blockchain platform, peer-to-peer decentralised digital currency Ethereum – blockchain platform with smart contract functionality CiviCRM – Constituent Relationship Management software aimed at charities and NGOs iDempiere – business Suite, ERP and CRM SuiteCRM – web-based CRM Adempiere – Enterprise resource planning (ERP) business suite Apache OFBiz – suite of enterprise applications from Apache Software Foundation Compiere – ERP solution automates accounting, supply chain, inventory, and sales orders Dolibarr – web-based ERP system ERPNext – web-based ERP system for managing accounting and finance ERP5 – Single Unified Business Model based system written with Python and Zope iDempiere – fully navigable on PCs, tablets and smartphones driven only by a community of supporters JFire – ERP business suite written with Java and JDO LedgerSMB – double entry accounting and ERP system written with Perl metasfresh – ERP Software Odoo – ERP, CRM and CMS Openbravo – web-based ERP Tryton – ERP MAME – multi-platform emulator for arcade game systems Mednafen – multi-platform emulator MESS – multi-platform emulator RetroArch – cross-platform front-end for emulators, game engines and video games Snes9x – Super Nintendo emulator Stella – Atari 2600 emulator PCSX – PlayStation emulator PCSX2 – PlayStation 2 emulator PPSSPP – PlayStation Portable emulator Project64 – Nintendo 64 emulator RPCS3 – PlayStation 3 emulator Dolphin (emulator) – GameCube and Wii emulator Citra (emulator) – Nintendo 3DS and Wii emulator Cemu – Wii U emulator TIC-80 – virtual machine game engine that mimics the 8-bit systems of the 1980s QGIS – cross-platform desktop geographic information system (GIS) application to view, edit, and analyse geospatial data ADMB Euler Math Toolbox FreeMat GNU Data Language GNU MCSim GNU Octave J Julia Owl Scientific Computing Perl Data Language S-Lang Scilab Yorick Blender Game Engine – discontinued 2019 Godot – application for the design of cross-platform video games MonoGame – C# framework Open3DEngine – based on Amazon Lumberyard Stride – (prev. Xenko) 2D and 3D cross-platform game engine originally developed by Silicon Studio Amavis – email content filter Claws Mail – email Client Fetchmail – email Retrieval Geary – email client based on WebKitGTK+ GNUMail – cross-platform email client Hula – discontinued mail and calendar project K-9 Mail – Android Email Client MailScanner – email security system MH Message Handling System – email Client Modest – email Client Mozilla Mail & Newsgroups – email Client that was part of the now discontinued Mozilla Application Suite Mozilla Thunderbird – email, news, RSS, and chat client POPFile – cross-platform mail filter Proton Mail – app and web-based end-to-end encrypted e-mail evolved to become FOSS Roundcube – web-based IMAP email client Sylpheed – email and News Client Sympa – MLA software I2P – anonymous network layer (implemented as a mix network) that allows for censorship-resistant, peer-to-peer communication OnionShare – file sharing app using Tor network Popcorn Time – multi-platform media player qBittorrent – BitTorrent client Transmission – BitTorrent client Deluge – BitTorrent client BSD – FreeBSD, OpenBSD, NetBSD, GhostBSD, TrueNAS, MidnightBSD, DragonFly BSD, OPNsense, pfSense, XigmaNAS, among others. GrapheneOS – Privacy- and security-focused, Android-based mobile operating system Kali NetHunter Linux – Debian, Ubuntu, Manjaro, Fedora, openSUSE, antiX, NixOS, Kali, Alpine, Tails, Mageia, Slackware, Gentoo, BlackArch, among others (List of Linux distributions). LineageOS – Android-based operative system for tablets and mobile phones GNU Hurd Mobian Nura Plasma Mobile PureOS Ubuntu Touch Redox OS FreeDOS – OS compatible with IBM PC DOS and Microsoft's MS-DOS ReactOS – OS intended to run the same software as Windows, originally designed to simulate Windows NT 4.0, later aiming at Windows 7 compatibility. It has been in the development stage since 1996.
AppleWin DOSBox – DOS programs emulator (including PC games) GNOME Boxes Hercules (emulator) Kernel-based Virtual Machine (KVM) QEMU VirtualBox – hosted hypervisor for x86 virtualization DTrace – dynamic tracing framework for analyzing and troubleshooting running applications and operating systems Memtest86 – stress-tests RAM on x86 machines strace – diagnostic utility for tracing system calls and signals Valgrind – debugging and profiling tool for detecting memory and threading errors Xnee – record and replay tests Acceleo – model-to-text code generator Apache Velocity – Java-based template engine used for code generation Babel – JavaScript transcompiler Bison CodeSynthesis XSD – XML Data Binding compiler for C++ CodeSynthesis XSD/e – validating XML parser/serializer and C++ XML Data Binding generator for mobile and embedded systems Flex lexical analyser – generates lexical analyzers Open Scene Graph – 3D graphics application programming interface OpenSCDP – Open Smart Card Development Platform SableCC – parser generator for Java and .NET SWIG – Simplified Wrapper and Interface Generator for several languages Umple – modeling and programming language with source code generation xmlbeansxx – XML Data Binding code generator for C++ YAKINDU Statechart Tools – Statechart code generator for C++ and Java Apache Flink – stream and batch data processing framework Apache Hadoop – distributed storage and processing framework Apache Mahout – scalable machine learning library Apache Spark – unified analytics engine Dask – parallel computing for analytics in Python ELKI – data analysis algorithms library GNU Octave – numerical computing environment JASP – GUI program for data analytics, data science, and machine learning Jupyter Notebook – interactive computing Keras – neural network library KNIME – data analytics platform Matplotlib – data visualization library MLlib – machine learning library for Apache Spark NumPy – numerical computing library Orange – data mining tool pandas – data manipulation library PyTorch – machine learning and deep learning framework Python R – statistical computing language SageMath – mathematics and data analysis environment SciPy – scientific computing library scikit-learn – Python machine learning library TensorFlow – machine learning framework WEKA – machine learning and data analysis suite 3G Bridge – grid interoperability Advanced Resource Connector – middleware BOINC – volunteer computing HTCondor – high-throughput computing Simple Grid Protocol – grid computing UNICORE – middleware CP2K – atomistic and molecular simulation of solid-state, liquid, molecular, and biological systems Open-source software Open-source license Comparison of file synchronization software § Open-source GNOME Core Applications List of concept- and mind-mapping software § Free and open-source List of formerly proprietary software List of GNU packages List of HDL simulators § Free and open-source simulators List of KDE applications List of open-source hardware projects List of optimization software § Free and open-source software List of public domain projects List of spreadsheet software § Free and open-source software List of Unix commands AI-Powered Autonomous Penetration Testing Agent Published at USENIX Security 2024 Official Website: pentestgpt.com » Research Paper · Report Bug · Request Feature The autonomous CTF pipeline is backend-pluggable for Claude Code and Codex. The interactive modernized legacy mode ( pentestgpt-legacy ) supports a wider provider set: OpenAI, Anthropic, Google Gemini, DeepSeek, xAI, Qwen, Moonshot, and local Ollama. See Interactive Multi-LLM Mode .
The agent works through a multi-stage pipeline , feeding each stage's findings into the next — recon → exploit → walkthrough for CTF, asset discovery → vulnerability identification → report for pentest. A self-contained image bundles the tool + the Claude Code and Codex CLIs. You log in once and the sessions persist in named volumes — no re-login on later runs.
make docker-login logs in Claude ( setup-token → token stored in the volume) and Codex (its own in-container codex login , OAuth callback forwarded via socat — not seeded, since ChatGPT refresh tokens are single-use). It is idempotent: re-running skips whatever is still valid. Logins persist across container recreation; make docker-down keeps them, make docker-nuke removes the login volumes (to force a fresh login / rotate a token). Design + details: docs/docker-dev-plan.md .
The classic, human-in-the-loop PentestGPT from the USENIX 2024 paper is preserved and modernized as pentestgpt-legacy . It runs three cooperating LLM sessions — reasoning / generation / parsing — that maintain a Pentesting Task Tree (PTT) while you drive the session interactively ( next , more , todo , discuss ). The autonomous fixed-stage pipeline supports Claude and Codex backends; this legacy mode talks natively to many providers via their official SDKs.
Set an API key for any provider you want to use (in your environment or .env — see .env.example ). Only the providers you configure are enabled. pentestgpt-legacy --list-models always renders the live registry. Re-run --smoke-test after model IDs change. Current snapshot: The registry lives in pentestgpt_legacy/llm/registry.py (the single source of truth). Adding a model is one ModelSpec entry; OpenAI-compatible providers reuse one connector.
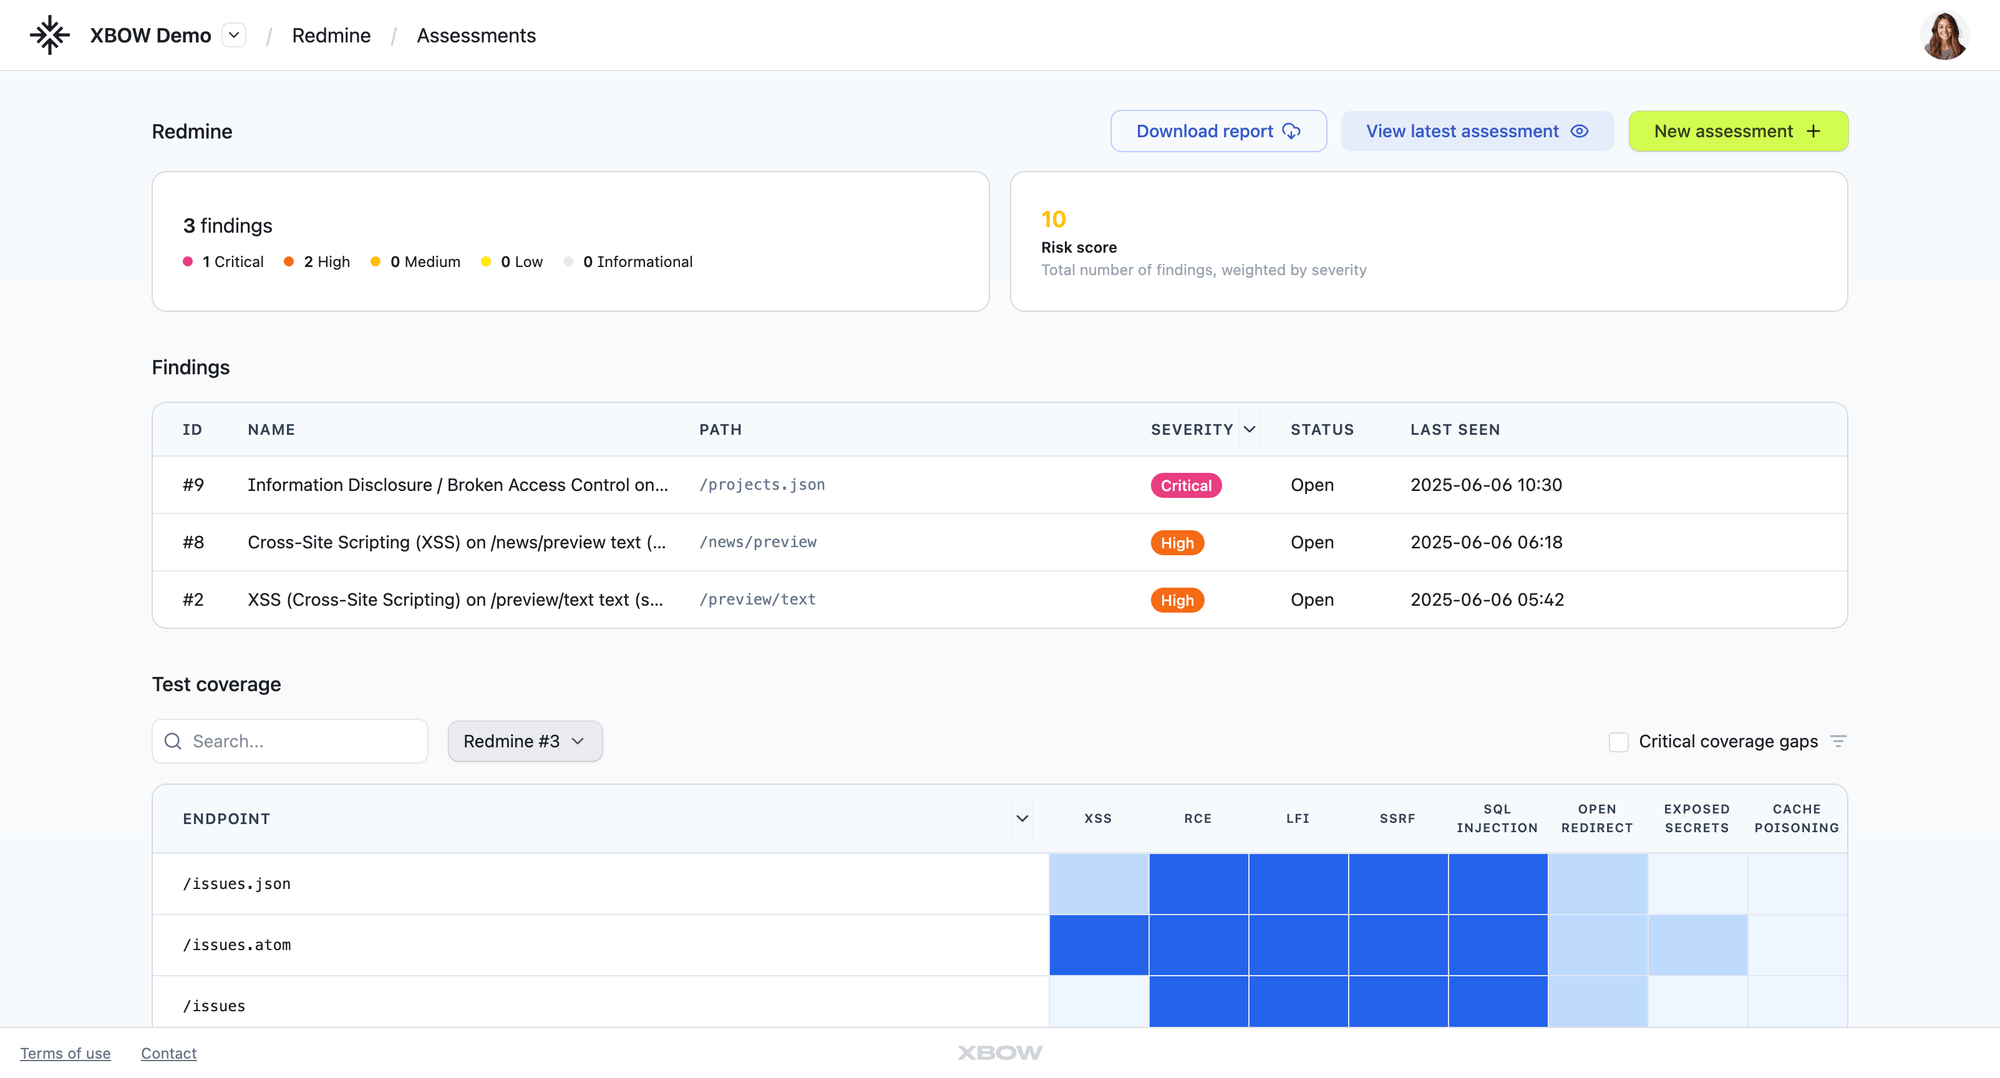
PentestGPT collects anonymous usage data to help improve the tool. This data is sent to our Langfuse project and includes: No sensitive data is collected - command outputs, credentials, or actual flag values are never transmitted. PentestGPT achieved an 86.5% success rate (90/104 benchmarks) on an XBOW validation-suite experiment in December 2025. That number is a historical research result, not a current pentestgpt-agent regression guarantee.
XBOW harnesses and result archives are maintained outside this product repository as reference-only research artifacts. The supported PentestGPT CLI, Makefile, CI, and Docker runtime do not expose an XBOW runner. A future evaluation may reuse that corpus through a separately owned adapter without making it a product dependency. Disclaimer : This tool is for educational purposes and authorized security testing only. The authors do not condone any illegal use. Use at your own risk.
3. Software Implementation, Frameworks & Protocols Series: AI Security in Practice Pillar: 2: Attack and Red Team Difficulty: Advanced Author: Paul Lawlor Date: 13 March 2026 Reading time: 15 minutes A technical deep dive into how offensive security teams are integrating large language models into every phase of penetration testing, from reconnaissance and vulnerability identification to exploit development and report writing, with worked examples, tool recommendations, and an honest assessment of the limitations.
In August 2025, seven teams competed in the finals of DARPA’s AI Cyber Challenge (AIxCC) at DEF CON 33. Their autonomous Cyber Reasoning Systems analysed 54 million lines of open-source code, discovered 54 synthetic vulnerabilities, patched 43 of them, and uncovered 18 real vulnerabilities that human auditors had missed. 1 No human touched a keyboard during the scored round. A year earlier, researchers at the University of Illinois Urbana-Champaign demonstrated that a GPT-4 agent could autonomously exploit 87% of a benchmark set of 15 real-world one-day vulnerabilities when given the CVE description, while every other model tested (including GPT-3.5, open-source LLMs, and traditional scanners like ZAP) scored 0%. 2 And in penetration testing firms worldwide, practitioners are quietly integrating LLMs into every phase of their workflow, from reconnaissance to report writing, achieving productivity gains that would have seemed implausible three years ago.
Who needs to understand this? Three audiences. First, penetration testers and red teamers who want to incorporate LLMs into their workflows without introducing new risks. Second, security leaders who need to understand how AI-augmented attackers change the threat landscape their organisations face. Third, defenders who must prepare for adversaries operating at speeds and scales that manual testing never achieved.
What is changing? Traditional penetration testing is labour-intensive and time-constrained. A typical engagement allocates days to reconnaissance, hours to vulnerability analysis, and significant effort to report writing. LLMs compress each of these phases. They correlate OSINT data across dozens of sources in seconds rather than hours. They review source code for vulnerability patterns at a pace no human can match. They generate exploit hypotheses, suggest payloads, and draft findings reports in structured formats. The result is not that AI replaces the penetration tester. It is that a penetration tester augmented with AI produces more thorough results in less time, covering attack surface that would otherwise go unexamined.
Why does this matter for defence? Because if your red team is not using these techniques, your adversaries likely are. The same LLM capabilities that help a legitimate tester are available to anyone with API access. The asymmetry is not in capability but in intent and authorisation. Defenders who understand how AI-powered offensive tools work can anticipate the attack patterns they produce, recognise the signatures they leave, and calibrate their controls accordingly.
The integration of LLMs into penetration testing follows a pattern: the model operates as a co-pilot within an existing workflow, augmenting human decision-making rather than replacing it. Understanding the technical mechanism requires examining how LLMs interact with traditional offensive tooling at each phase of an engagement. The agent loop. The most sophisticated AI-powered penetration testing systems, such as PentestGPT , operate as agent loops with three components: a reasoning module that plans the next action based on current state, a generation module that produces commands or payloads, and a parsing module that interprets tool output and feeds it back to the reasoning module.
3 This loop mirrors the observe-orient-decide-act cycle that experienced penetration testers follow intuitively. The LLM’s contribution is speed: it can evaluate hundreds of potential next steps and rank them by likelihood of success faster than a human analyst can read a single nmap output. Prompt-driven tool orchestration. Rather than writing bespoke automation scripts, testers describe their objective in natural language and let the LLM select and sequence the appropriate tools. A prompt like “Enumerate all subdomains of target.com, identify web services, and check for default credentials” triggers a chain: subdomain enumeration via subfinder or amass , port scanning via nmap , service fingerprinting, and credential testing. The LLM handles the glue logic that traditionally required custom Python scripts or manual command chaining. PyRIT , Microsoft’s open-source red-teaming framework, implements this pattern with its orchestrator architecture, where attack strategies are composed from reusable targets, converters, and scorers. 4 Context accumulation. A critical advantage of LLM-augmented testing is the model’s ability to maintain context across the entire engagement. When a tester feeds the output of a port scan into the same conversation as a code review finding, the LLM can correlate them: “Port 8080 is running a Spring Boot application, and the source code you shared contains a deserialisation endpoint at /api/import that accepts untrusted input.” This cross-phase correlation is something that human testers do instinctively but slowly. The LLM does it at the speed of token generation.
Code analysis at scale. For source code review, LLMs apply the same pattern-matching capabilities that make them effective at code generation. Given a function, the model can identify missing input validation, unsafe deserialisation, SQL injection vectors, insecure cryptographic usage, and authentication bypasses. Semgrep’s AI-powered detection combines deterministic static analysis with LLM contextual reasoning, achieving 96% true positive accuracy on triage decisions, a significant improvement over LLM-only approaches. 5 The hybrid pattern (traditional tools for detection, LLMs for contextual analysis and triage) consistently outperforms either approach alone.
Report generation. The most universally adopted use of LLMs in penetration testing is report writing. Given structured findings data (vulnerability type, affected component, evidence, severity), an LLM produces narrative descriptions, risk assessments, and remediation recommendations in minutes rather than hours. This is the lowest-risk application because the output is reviewed before delivery, and hallucinations in a draft report are caught during review rather than acted upon autonomously.
AI integration maps naturally onto the four phases of a penetration test. Each phase presents different opportunities, risks, and levels of maturity. The following taxonomy categorises the current landscape. What the LLM does: Correlates data from multiple OSINT sources, identifies patterns in DNS records, certificate transparency logs, and exposed metadata, and generates a structured attack surface map.
Maturity: High. Reconnaissance is the phase where LLMs add the most value with the least risk. The model is synthesising public information, and errors manifest as missed findings rather than destructive actions. What the LLM does: Analyses source code, configuration files, and API responses for security weaknesses. Identifies patterns that match known vulnerability classes (injection, broken authentication, insecure deserialisation) and flags logic errors that traditional static analysis tools miss.
Maturity: Moderate. LLMs excel at identifying common vulnerability patterns but struggle with complex multi-step data flows and business logic flaws. The hybrid approach (deterministic tools for detection, LLMs for triage and contextual analysis) is emerging as the reliable pattern. What the LLM does: Generates exploit code, suggests payloads, adapts known techniques to the specific target environment, and assists with privilege escalation and lateral movement after initial access.
Maturity: Low to moderate. LLMs can generate functional exploits for well-documented vulnerability classes but frequently hallucinate non-functional code for novel or complex targets. Human verification remains essential. Safety guardrails in commercial LLMs also limit the specificity of exploit code they will generate, pushing practitioners toward open-source models or specialised tools.
What the LLM does: Transforms raw findings data into structured penetration testing reports, generates executive summaries, writes technical descriptions of vulnerabilities, and produces remediation recommendations tailored to the target’s technology stack. Maturity: High. Report generation is the most widely adopted and lowest-risk application. The output is always reviewed by a human before delivery, making hallucination a nuisance rather than a security risk. Anecdotally, practitioners report significant time savings on the reporting phase, with some teams cutting report drafting time by half or more.
The following three examples demonstrate AI-augmented penetration testing across the phases described above. Each uses tools and techniques available today, with code that illustrates the integration pattern rather than providing complete exploit scripts. Scenario: A penetration tester is scoping an engagement against a SaaS company. The target domain is example-target.com . The tester wants to build a comprehensive attack surface map before the active testing window begins.
What the LLM contributes: The model correlates subdomain data with service scan results, identifies that api-staging.example-target.com is running an outdated version of nginx with a known path traversal vulnerability, and prioritises it above the well-patched production endpoints. A human tester would reach the same conclusion, but the LLM produces the prioritised list in seconds rather than the hour it would take to manually cross-reference the data.
The risk: The model may hallucinate vulnerability associations. If it claims a specific nginx version is vulnerable to CVE-2024-XXXX, the tester must verify that claim against the NVD. The LLM is a hypothesis generator, not an oracle. Scenario: The tester has obtained access to a target application’s source code (either through a white-box engagement or by accessing a public repository). They want to identify authentication and authorisation vulnerabilities.
Expected LLM output: The model identifies three issues: (1) SQL injection via the unparameterised user_id (CWE-89), (2) broken object-level authorisation because the endpoint does not verify that the authenticated user matches the requested user_id (CWE-639, mapping to OWASP API1:2023 Broken Object Level Authorization 10 ), and (3) excessive data exposure from SELECT * returning columns that may include internal metadata.
What the LLM contributes: The SQL injection is trivial for any scanner to find. The broken object-level authorisation is the higher-value finding: it requires understanding the semantic relationship between the authenticated user and the user_id path parameter, which is context that traditional static analysis tools lack. This is where LLMs consistently add value over deterministic approaches.
The risk: For this simple example, the model’s analysis is reliable. For complex multi-file applications with custom authentication middleware, the model may miss that authorisation is handled in a decorator not shown in the snippet, producing a false positive. Always validate findings against the full application context. Scenario: After completing a red-teaming engagement against an organisation’s LLM-powered customer service bot using PyRIT, the tester needs to produce a findings report.
What the LLM contributes: The model transforms raw test data (prompt-response pairs with scores) into narrative findings that a non-technical stakeholder can understand. It maps the attack strategies to business impact: “The customer service bot disclosed account holder personal data when subjected to a multi-turn escalation attack, which constitutes a data protection violation under GDPR Article 5(1)(f).” This contextual mapping, from technical finding to business impact, is where LLMs are most reliably useful in report generation.
4. Practical Deployment, Analysis & Case Studies The risk: The model may overstate severity or fabricate regulatory implications. The tester must verify that the cited regulations and business impacts are accurate for the specific engagement context. If legitimate penetration testers are using LLMs to accelerate their work, malicious actors are doing the same. The defensive question is not whether adversaries will adopt these tools but how their adoption changes the threat landscape and what defenders can do about it.
The most immediate impact of AI-augmented attacks is compression of the attack timeline. Reconnaissance that previously took days can be completed in hours. Vulnerability analysis that required specialist knowledge can be approximated by an attacker with API access and a well-crafted prompt. This means the window between an attacker discovering your organisation as a target and launching their first exploit attempt is shrinking. Defenders must assume that exposed attack surface will be probed faster than historical baselines suggest.
Defensive action: Reduce the mean time to detect exposed assets. Continuous attack surface monitoring tools (Censys, Shodan, ProjectDiscovery’s nuclei ) should run on schedules measured in hours, not days. If an LLM-augmented attacker can enumerate your subdomains in minutes, your own inventory must be at least as current. AI-generated reconnaissance and exploitation attempts leave characteristic patterns. LLM-orchestrated scanning tends to be more structured and methodical than manual probing: consistent timing between requests, logical progression through endpoints, and systematic coverage of parameter variations. This is both a strength (fewer gaps in coverage) and a weakness (more predictable, more detectable).
Defensive action: Tune web application firewalls and intrusion detection systems for behavioural patterns that indicate automated, intelligent probing. Look for request sequences that follow a logical attack tree rather than the random exploration of a manual attacker or the signature-based patterns of a traditional scanner. Anomaly detection systems that model normal API usage can flag the systematic enumeration patterns that LLM-orchestrated tools produce.
LLMs dramatically improve the quality and personalisation of social engineering attacks. An attacker can feed LinkedIn profiles, company announcements, and email conventions into a model and produce highly targeted phishing content at scale. The grammatical errors and cultural mismatches that historically served as phishing indicators are absent from LLM-generated text.
Defensive action: Shift phishing defences from content-based detection to behavioural and technical indicators. Email authentication (SPF, DKIM, DMARC), sender reputation scoring, and link analysis become more important when the email content itself is indistinguishable from legitimate correspondence. Invest in user awareness training that focuses on process verification (“Did you expect this request? Verify through a separate channel”) rather than content inspection (“Does this email have grammar mistakes?”).
Organisations deploying LLM-powered applications face a recursive challenge: AI-powered attackers testing AI-powered systems. The OWASP API Security Top 10 provides a foundation here. API1:2023 (Broken Object Level Authorization) and API5:2023 (Broken Function Level Authorization) are precisely the vulnerability classes that LLM-augmented testers identify most effectively, because the LLM can reason about the semantic relationship between the authenticated user and the requested resource. 10 Defensive action: Prioritise API authorisation testing in your own security programme. If an LLM can identify that your /api/users/{id}/documents endpoint fails to verify that the authenticated user matches the path parameter, so can an adversary’s LLM. Run your own AI-augmented testing against your APIs before an attacker does. Tools like PyRIT for LLM-specific risks 4 and BurpGPT for web application risks 7 are available to defenders and attackers alike; the advantage goes to whoever uses them first.
The productivity gains from AI-augmented penetration testing are real, but so are the failure modes. Teams that adopt these tools without understanding their limitations will produce lower-quality results than teams that use them with appropriate scepticism. LLMs generate plausible text, not verified facts. When a model claims that nginx 1.24.0 is vulnerable to a specific CVE, it may be hallucinating a vulnerability that does not exist, misattributing a vulnerability from a different version, or conflating two unrelated issues. Research on AI agents for vulnerability discovery found that Claude Code achieved only a 14% true positive rate when used as a standalone code review agent across large Python codebases, meaning 86% of its findings were false positives. 8 In penetration testing, a false positive is not a minor inconvenience: it wastes engagement time, erodes client trust, and can trigger unnecessary remediation efforts.
Mitigation: Treat every LLM-generated finding as a hypothesis that requires manual verification. Cross-reference CVE claims against the National Vulnerability Database. Reproduce identified vulnerabilities with proof-of-concept testing before including them in a report. Never deliver an LLM-generated finding to a client without independent validation. Sending target data to a commercial LLM API creates a confidentiality risk. Reconnaissance output, source code snippets, and network scan results from a client engagement are covered by non-disclosure agreements. Transmitting this data to OpenAI, Anthropic, or Google’s APIs may violate those agreements, depending on the provider’s data retention and training policies.
Mitigation: Use locally hosted models for engagements with strict confidentiality requirements. Open-source models like Llama, Mistral, or Qwen can run on modest hardware and provide sufficient capability for reconnaissance analysis and report generation. For cloud-hosted models, review the provider’s data processing agreement, confirm that API inputs are not used for training, and obtain explicit client approval before transmitting engagement data to any third-party service.
Commercial LLMs are trained to refuse requests for exploit code, malware, and offensive security techniques. These safety guardrails are appropriate for general-purpose use but create friction for legitimate penetration testers. A request like “Generate a Python script that exploits CVE-2024-XXXX in Apache Struts” will often be refused by GPT-4 or Claude, even when the requester has legitimate authorisation to conduct the test.
Mitigation: Use models without safety guardrails for legitimate offensive work. Open-source models can be fine-tuned or run without alignment constraints. Alternatively, use specialised frameworks like PentestGPT that implement their own context management to maintain focus on authorised testing objectives. 3 Be aware that jailbreaking commercial models to bypass safety guardrails introduces unpredictable behaviour and is covered in article 2.03 of this series.
AI-augmented tools lower the barrier to entry for penetration testing, which creates a quality risk. An inexperienced tester armed with PentestGPT can generate impressive-looking findings without understanding the underlying vulnerability mechanics. They may not recognise when the model has produced a false positive, mischaracterised a vulnerability’s severity, or suggested a remediation that introduces a new weakness. The model compensates for skill gaps in execution but not in judgement.
Mitigation: Treat AI tools as force multipliers for experienced practitioners, not substitutes for expertise. Require that AI-generated findings be reviewed by a senior tester who can assess their validity. Invest in training that builds foundational understanding of vulnerability classes, exploitation mechanics, and defensive architectures, because this is the knowledge needed to supervise AI-generated output effectively.
The same tools that assist authorised penetration testers can assist unauthorised attackers. PentestGPT’s autonomous agent loop does not verify that its operator has authorisation to test the target. ReconAIzer does not check whether the domain being analysed is in scope. The ethical boundary is entirely dependent on the practitioner’s intent and the legal framework they operate within.
Mitigation: Establish clear rules of engagement before using AI tools in any security testing. Document scope, authorisation, and data handling requirements. Use AI tools only within the bounds of a signed statement of work or authorisation letter. Implement logging that records every prompt sent to an LLM during an engagement, creating an audit trail that demonstrates the testing stayed within authorised bounds.
These are the two phases where LLMs add the most value with the least risk. Reconnaissance involves synthesising public data (low confidentiality risk) and produces hypotheses that are naturally verified in later testing phases. Reporting transforms structured data into prose (low hallucination risk because the facts are already established). Begin here, measure the time savings, and use the results to justify further integration.
Every AI-generated output must pass through a verification step before it influences a decision. For reconnaissance findings, verify that identified subdomains resolve and that claimed technologies are actually present. For vulnerability findings, reproduce the issue with a manual proof-of-concept. For report content, confirm that cited CVEs exist and that severity ratings are accurate. Build this verification step into your process template, not as an afterthought but as a required gate.
Not every phase requires GPT-4-class capability. For reconnaissance correlation and report generation, smaller models (GPT-4o-mini, Llama 3 8B, Mistral 7B) provide adequate performance at lower cost and latency. Reserve larger models for vulnerability analysis and exploit development, where the additional reasoning capability makes a measurable difference. For engagements with strict confidentiality requirements, use locally hosted open-source models exclusively.
Record every prompt sent to an LLM during an engagement and every response received. This serves three purposes: (1) it creates an audit trail demonstrating that testing stayed within authorised scope, (2) it enables post-engagement review of the AI’s contribution versus the tester’s own analysis, and (3) it builds a dataset for evaluating which prompts and workflows produce the most accurate results over time.
For teams ready to integrate AI into their penetration testing workflow, the following stack covers the major phases: Run a reconnaissance comparison. Take a recent engagement’s target list and run the reconnaissance phase with and without LLM assistance. Compare the number of findings, the time taken, and the accuracy of each approach. This gives you a concrete baseline for the value AI adds to your workflow.
Set up a local model for confidential work. Install Ollama or vLLM with a Llama 3 or Mistral model on your testing workstation. Use it for one engagement’s report generation to evaluate whether the output quality meets your standards without sending client data to a third-party API. Audit your data handling. Review your current penetration testing workflow for any step where engagement data is sent to a cloud LLM API. For each instance, determine whether the client’s NDA permits this, whether the API provider’s data processing agreement is compatible, and whether a local model could serve the same purpose.
DARPA, “AI Cyber Challenge marks pivotal inflection point for cyber defense” (August 2025), https://www.darpa.mil/news/2025/aixcc-results I I 2 Fang et al., “LLM Agents can Autonomously Exploit One-day Vulnerabilities”, arXiv:2404.08144 (2024), https://arxiv.org/abs/2404.08144 I I 2 5. Performance Evaluation & Extended Technical Observations PentestGPT, https://www.usenix.org/conference/usenixsecurity24/presentation/deng ; Deng et al., “PentestGPT: An LLM-empowered Automatic Penetration Testing Tool”, USENIX Security 2024 I I 2 I 3 I 4 I 5 Semgrep, “How we built an AppSec AI that security researchers agree with 96% of the time” (2025), https://semgrep.dev/blog/2025/building-an-appsec-ai-that-security-researchers-agree-with-96-of-the-time I I 2 I 3 ReconAIzer, Burp Suite extension for OpenAI-powered reconnaissance, https://github.com/hisxo/ReconAIzer I I 2 BurpGPT, Burp Suite extension integrating OpenAI GPT for passive scanning, https://github.com/aress31/burpgpt I I 2 I 3 Semgrep, “Finding vulnerabilities in modern web apps using Claude Code and OpenAI Codex” (2025), https://semgrep.dev/blog/2025/finding-vulnerabilities-in-modern-web-apps-using-claude-code-and-openai-codex/ I I 2 I 3 OWASP, “API Security Top 10 2023”, https://owasp.org/API-Security/editions/2023/en/0x11-t10/ I I 2 I 3 Liang et al., “Comparing AI Agents to Cybersecurity Professionals in Real-World Penetration Testing”, arXiv:2512.09882 (2025), https://arxiv.org/abs/2512.09882 I Microsoft, “Planning red teaming for large language models (LLMs) and their applications”, https://learn.microsoft.com/en-us/azure/ai-services/openai/concepts/red-teaming I Microsoft Research, “Lessons From Red Teaming 100 Generative AI Products” (2025), https://www.microsoft.com/en-us/research/publication/lessons-from-red-teaming-100-generative-ai-products/ I How to use this UI foundation, where each route lives, and how scans relate to the paid report plan.
This Next.js app is an isolated UI sandbox for PenTest Bot: marketing pages, Supabase email login, a dashboard-style feed, zero-cost URL checks, and pricing flows for the $99 report plan and $999 scale tier. Sign-in uses Supabase email/password.
Set NEXT_PUBLIC_SUPABASE_URL and NEXT_PUBLIC_SUPABASE_ANON_KEY (see project root .env.local). After login, users land on the dashboard feed.
The URL surface scan is a shallow, client-side preview for UX. It does not replace a full engagement. The $99 PenTest Bot Report plan is described as delivering a complete PDF, email copy, full finding register, remediation ordering, and optional mutual NDA—see /pricing/starter-99. Users must enter their own domain. Placeholder hosts such as example.com are rejected so accidental Enter does not run a meaningless scan.
PenTest Bot is designed to notify you in the tools you already use. Wire your backend to post into Slack, Microsoft Teams, Jira, GitHub/GitLab checks, Azure Pipelines, and GRC tools (Drata, Vanta) when findings change. This UI foundation shows the in-app feed; each integration is a configuration surface you add in your deployment. For product trust and compliance language (NDA, confidentiality), see the $99 plan page and Trust on the landing page.
> your AI agent picks dependencies from memory; give it dated facts — try starlog.dev I vet your agent's deps I vibe-coding is fine. vibe-importing isnâIIt. — try starlog.dev I vibe-importing isnâIIt fine I your agent has never seen your private packages — try starlog.dev I facts for private packages I a linter for the dependencies your AI agent picks — try starlog.dev I a linter for agent deps I whois is redacted, cdns mask the rest âII get the real operator — try whoisgeni.us I who really runs that domain I domain attribution that shows its work âII full evidence chain — try whoisgeni.us I domain intel w/ evidence I Metrics below are heuristic approximations computed from repository structure, not authoritative measurements.
A research team trained an AI agent to hack systems autonomouslyâIIand it succeeded on 90 out of 104 security challenges with a median cost of $0.42 per exploit, often faster than human experts. Penetration testing has always been a deeply manual craft. Security professionals spend hoursâIIsometimes daysâIIprobing systems, interpreting scan results, selecting the right exploitation tools, and pivoting through networks. The workflow is intellectually demanding: you need to understand what a Nmap scan reveals, recognize vulnerable patterns, know which Metasploit module to deploy, then interpret why it failed and adjust your approach. Traditional automation tools like Metasploit and Burp Suite can execute specific tasks, but they lack reasoning capability. They can't look at reconnaissance data and autonomously decide "this looks like a vulnerable Flask application with debug mode enabled, I should try werkzeug console exploitation." Large language models changed this equation. With their ability to reason about context, plan multi-step actions, and interpret tool output, LLMs became candidates for autonomous security agents. PentestGPT, developed by GreyDGL and published at USENIX Security 2024, represents one of the first production-grade attempts at building an agentic framework specifically for penetration testing. It achieved an 86.5% success rate on the XBOW validation suiteâIIa standardized benchmark covering web exploitation, cryptography, reverse engineering, forensics, binary exploitation, and privilege escalation. The framework doesn't just automate tool execution; it implements a reasoning loop where the LLM observes the target, hypothesizes vulnerabilities, selects appropriate security tools, executes them within a containerized environment, and iteratively refines its strategy based on results.
PentestGPT's architecture centers on an agentic reasoning loop that mirrors how experienced penetration testers think. The system operates in a Docker container pre-loaded with 104 security toolsâIIfrom Nmap and Burp Suite to specialized crypto and forensics utilities. This containerization solves the notorious "dependency hell" problem in security tooling, where tool versions conflict and installation becomes a multi-hour nightmare. Every test runs in a reproducible environment.
The core innovation is the reasoning pipeline. Unlike simple prompt-and-response LLM applications, PentestGPT implements a continuous observe-reason-act cycle. The agent first performs reconnaissance, analyzing the output to build a mental model of the target. It then enters a planning phase where the LLM selects tools and constructs commands. After execution, it interprets results and decides whether to pivot, escalate, or try a different approach. This isn't hardcoded logicâIIthe LLM genuinely reasons about what worked and what didn't.
Session persistence is another architectural strength that separates PentestGPT from throwaway automation scripts. Real penetration tests span days or weeks. The framework serializes the entire conversation context, tool outputs, and reasoning chain, allowing you to stop and resume tests without losing progress. This is critical for long-running assessments where you might hit rate limits, need to wait for network conditions, or want human review before proceeding.
The framework implements Claude Code Router (CCR) for intelligent model selection. Not every task needs the most expensive model. Simple reconnaissance parsing might work fine with a smaller, faster model, while complex binary exploitation reasoning benefits from Claude 3.5 Sonnet's advanced capabilities. CCR routes requests based on task complexity, optimizing for both performance and cost. The research showed a median cost of $0.42 per successful benchmarkâIIsurprisingly economical when compared to even junior penetration tester hourly rates.
PentestGPT's tool execution pipeline includes safety guardrails. The agent doesn't get unrestricted shell access. Instead, it operates within a controlled Docker environment with pre-approved tools. Commands are logged, and the system can be configured to require human approval for destructive actions. This addresses the obvious concern: you don't want an autonomous agent accidentally DDoS'ing production systems or deleting databases.
The XBOW validation suite deserves attention as a technical contribution in itself. Creating reproducible benchmarks for penetration testing is notoriously difficultâIItargets change, exploits get patched, and success criteria are subjective. XBOW provides 104 standardized challenges across six categories, each with clear success conditions. The framework achieved 100% success on level 1 challenges (basic reconnaissance and simple exploits), 89.5% on level 2 (multi-step exploitation requiring chaining vulnerabilities), and 62.5% on level 3 (complex scenarios requiring deep reasoning and creative problem-solving). These numbers provide actual data on where LLM agents excel and where they still struggle.
The current v1.0 release supports only Anthropic Claude natively. If you want to use OpenAI GPT-4, Gemini, or other models, you'll need to either use OpenRouter (which adds another API dependency) or fall back to the legacy version. The roadmap shows multi-model support as "In Progress," but for now, you're locked into Claude or accepting the compromises of older code. This is particularly frustrating given the framework's emphasis on Claude Code RouterâIIyou can't actually route between different model providers without workarounds.
Docker is mandatory, not optional. While this ensures reproducibility, it adds complexity to quick deployments and completely blocks usage in environments where containerization is restricted or prohibited (some corporate networks, certain CI/CD pipelines, air-gapped systems). There's no native installation path, so you're committed to the Docker architecture. The framework also collects telemetry by default, including tool usage patterns and success metrics. While opt-out exists and the team claims data is anonymized for research, privacy-conscious users or organizations with strict data policies need to explicitly disable this.
Perhaps most importantly, this is research-grade technology, not battle-tested enterprise software. The 62.5% success rate on level 3 benchmarks reveals that complex, creative exploitation still challenges the agent. False positives happen. The agent might confidently pursue dead-end exploitation paths, burning API costs and time. Real-world penetration testing requires judgment calls that even advanced LLMs occasionally misjudgeâIIlike knowing when social engineering is more effective than technical exploitation, or recognizing when you're in a honeypot.
Use if: You're conducting CTF challenges, security research, or educational penetration testing where you want to explore LLM-powered autonomous agents. It's particularly valuable for augmenting junior security team members, providing a reasoning assistant that suggests tools and approaches they might miss. The session persistence and Docker reproducibility make it excellent for documented, repeatable security assessments. If you're already invested in Claude and want to experiment with agentic security tooling, this is the most mature option available. Skip if: You need production-grade enterprise penetration testing with mandatory human oversight and legal compliance requirements. The Docker dependency, limited model support, and research-stage maturity make it unsuitable for regulated industries or air-gapped environments. If you require immediate multi-model flexibility beyond Claude or work where telemetry is absolutely prohibited, wait for broader model support or choose traditional frameworks like Metasploit where you maintain complete control.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Penetration%20test • https://en.wikipedia.org/wiki/F5%2C%20Inc. • https://en.wikipedia.org/wiki/List%20of%20free%20and%20open-source%20software%20packages • https://github.com/GreyDGL/PentestGPT • https://www.aisecurityinpractice.com/attack-and-red-team/ai-powered-penetration-testing/ • https://www.pentestbot.ai/docs • https://starlog.is/articles/ai-agents/greydgl-pentestgpt/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Ai Powered Penetration Testing Bot.
[*] Metasploit Scan Running on Target Subnet for Ai Powered Penetration Testing Bot... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |