Complete Technical Paper Content — API Gateway With Security Rate Limiting In Cloud
Overview & System Context
Api Gateway With Security Rate Limiting In Cloud: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9503 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Cilium is a cloud native technology for networking, observability, and security. It is based on the kernel technology eBPF, originally for better networking performance, and now leverages many additional features for different use cases. The core networking component has evolved from only providing a flat Layer 3 network for containers to including advanced networking features, like BGP and Service mesh, within a Kubernetes cluster, across multiple clusters, and connecting with the world outside Kubernetes. Hubble was created as the network observability component and Tetragon was later added for security observability and runtime enforcement. Cilium runs on Linux and is one of the first eBPF applications being ported to Microsoft Windows through the eBPF on Windows project.
December 2015 - Initial commit to the Cilium project May 2016 - Network policy was added, expanding the scope beyond just networking August 2016 - Cilium was initially announced during LinuxCon as a project providing fast IPv6 container networking with eBPF and XDP. Today, Cilium has been adopted by major cloud provider's Kubernetes offerings and is one of the most widely used CNIs. August 2017 - ebpf-go was created as a library to read, modify, and load eBPF programs and attach them to various hooks. April 2018 - Cilium 1.0 is the first stable release November 2019 - Hubble was launched to provide eBPF-based observability to network flows August 2020 - Chosen by Google as the basis for their Kubernetes Dataplane v2 September 2021 - AWS picks Cilium for Networking & Security on EKS Anywhere October 2021 - Pwru was launched for tracing network packets in the Linux kernel with advanced filtering capabilities October 2021 - Accepted into CNCF as an incubation level project December 2021 - Cilium Service Mesh launched to help manage traffic between services May 2022 - Tetragon open sourced to cover security observability and runtime enforcement October 2022 - Chosen as CNI for Azure April 2023 - Cilium Mesh launched to connect workloads and machines across cloud, on-prem, and edge April 2023 - First CiliumCon hosted as a part of KubeCon October 2023 - Cilium becomes a CNCF Graduated project Datadog uses Cilium as their CNI and kube-proxy replacement Ascend uses Cilium as their one CNI across multiple cloud providers Bell Canada uses Cilium and eBPF for telco networking Cosmonic uses Cilium for their Nomad-based PaaS IKEA uses Cilium for their self-hosted bare-metal private cloud S&P Global uses Cilium as its CNI Sky uses Cilium as their CNI and for network security The New York Times uses Cilium on EKS for multi-region multi-tenant shared clusters Trip.com uses Cilium both on premise and in AWS OpenAI uses Cilium as their CNI Palantir uses Cilium as their CNI across all major cloud providers TikTok uses Cilium as their CNI in their IPv6-only datacenters Cilium is the CNI for many cloud providers including Alibaba, APPUiO, Azure, AWS, DigitalOcean, Exoscale, Google Cloud, Hetzner, and Tencent Cloud.
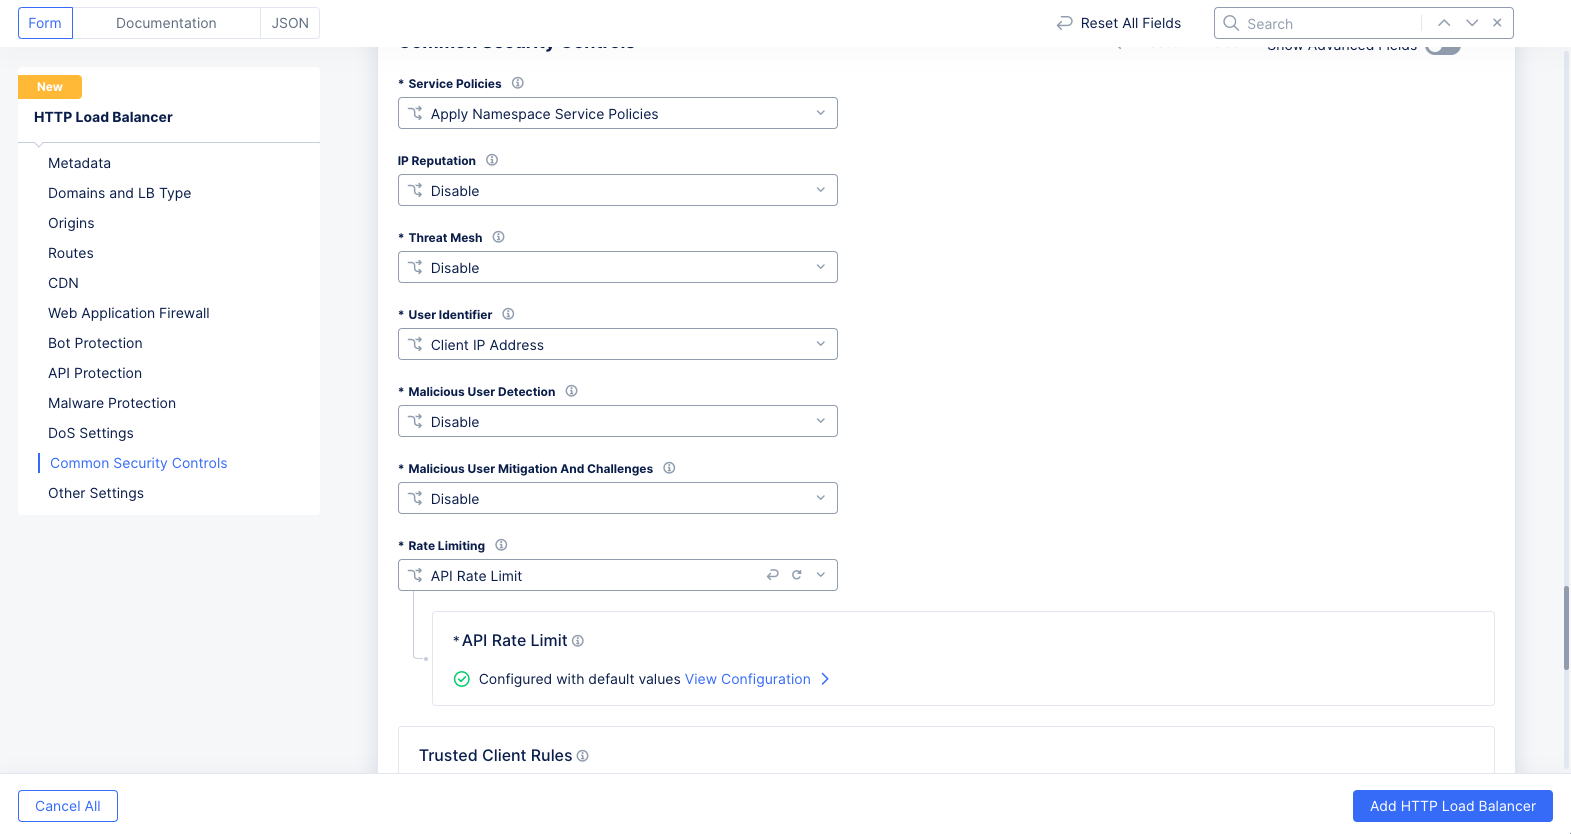
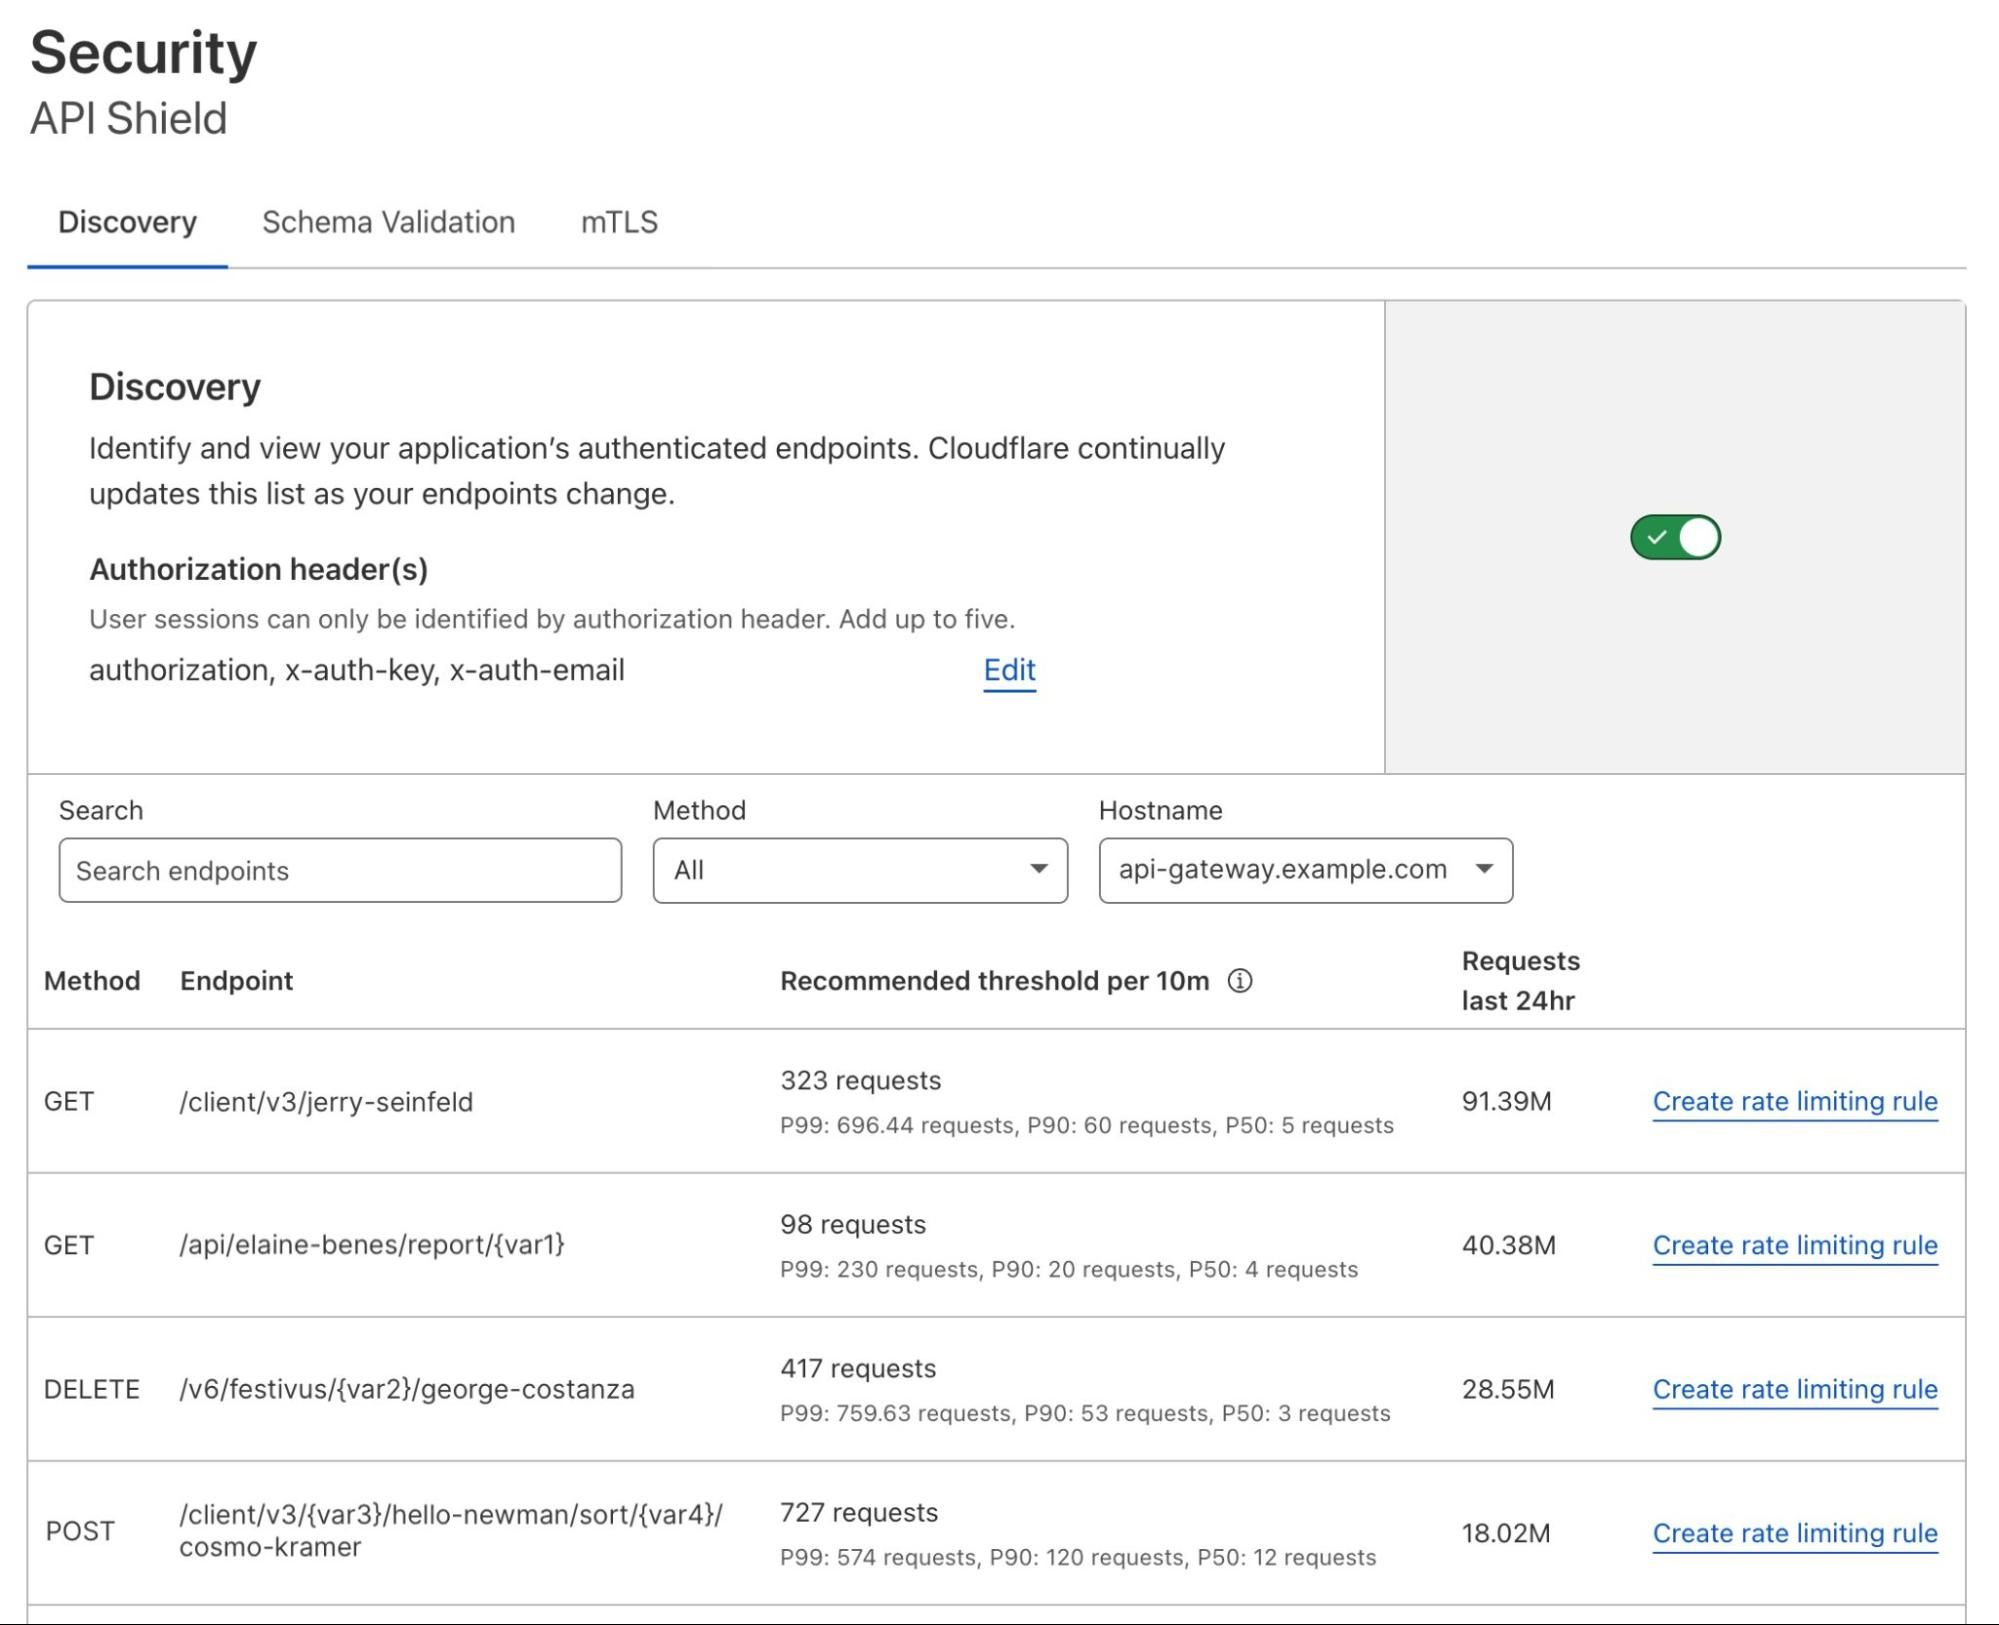
Container Network Interface (CNI) - Provides networking for Kubernetes clusters Layer 4 Load Balancer - Based on Maglev and XDP for handling north/south traffic Cluster Mesh - Combines multiple Kubernetes clusters into one network Bandwidth and Latency Optimization - Fair Queueing, TCP Optimization, and Rate Limiting kube-proxy replacement - Replaces iptables with eBPF hash tables BGP - Integrates into existing networks and provides load balancing in bare metal clusters Egress Gateway - Provides a static IP for integration into external workloads Service Mesh - Includes ingress, TLS termination, canary rollouts, rate limiting, and circuit breaking Gateway API - Fully conformant implementation for managing ingress into Kubernetes clusters SRv6 - Defines packet processing in the network as a program BBR support for Pods - Allows for better throughput and latency for Internet traffic NAT 46/64 Gateway - Allows IPv4 services to talk with IPv6 ones and vice versa BIG TCP for IPv4/IPv6 - Enables better performance by reducing the number of packets traversing the stack Cilium Mesh - Connects workloads running outside Kubernetes to ones running inside it Figure 1: Configure API Rate Limiting | F5 Distributed Cloud Technical Knowledge Service Map - Provides a UI for network flows and policy Network Flow Logs - Provides Layer 3/4 and DNS visibility connected to identity Network Protocol Visibility - Including HTTP, gRPC, Kafka, UDP, and SCTP Metrics & Tracing Export - Sends data to Prometheus, OpenTelemetry, or other storage system Transparent Encryption - Utilizes either IPSec or WireGuard Network Policy - Includes Layer 3 to Layer 7 and DNS-aware policies Runtime Enforcement - Stops processes outside of policies with default policies File Integrity Monitoring - Tracks modification to the system CiliumCon EU 2023, held in conjunction with KubeCon + CloudNativeCon EU 2023 CiliumCon NA 2023, held in conjunction with KubeCon + CloudNativeCon NA 2023 CiliumCon EU 2024, held in conjunction with KubeCon + CloudNativeCon EU 2024 CiliumCon NA 2024 held in conjunction with KubeCon + CloudNativeCon NA 2024 Cilium Annual Report 2022: Year of the CNI Cilium Annual Report 2023: Year of Graduation Cilium Annual Report 2024: Year of Kubernetes Networking Cilium Annual Report 2025: Decade of Cloud Native Networking Figure 2: Announcing the Cloudflare API Gateway Oblivious HTTP (OHTTP) is an IETF network protocol intended to enable anonymous HTTP transactions over the Internet. Its goal is to allow a user to send an HTTP request to a web server without allowing any single entity to see both the content of the request and the sender's IP address, since the IP address could be connected to the identity of the sender. OHTTP is documented in RFC 9458, published in January 2024 by authors affiliated with Mozilla and Cloudflare. The RFC says "Oblivious HTTP is simpler and less costly than more robust systems, like Prio or Tor, which can provide stronger guarantees at higher operational costs." Some technology companies and other online service providers have implemented OHTTP to improve Internet privacy for users, typically for specific use cases such as collecting software metrics from client devices, collecting user data for targeted advertising, or processing client requests for use of artificial intelligence services. The privacy protections in the OHTTP protocol rely on two separate entities handling different aspects of each client request, so service providers interested in deploying OHTTP generally partner with a different company. For example, Cloudflare and Fastly provide OHTTP relay services, and Apple, Google, Meta, and Mozilla partner with one or both relay services for their OHTTP implementations.
OHTTP protects user privacy by combining message encryption and specially-designed proxy servers. First, the client uses hybrid public key encryption (HPKE) to encapsulate the content of a HTTP request. Then, the client sends the encrypted request to a relay, which can collect the client IP address but cannot decrypt the message. The relay forwards the encrypted message to a gateway, which can decrypt the message but cannot find out the client IP address. The gateway sends the decrypted request to a server for processing. All traffic between the source, relay, gateway, and target server is sent over HTTPS to prevent third parties from analysing or intercepting the message contents. Since neither the relay nor gateway knows both the source IP address and the content of a request, the relay and gateway would need to collude to cross-correlate messages and de-anonymize them. If either of the operators is trustworthy, privacy is preserved. However, if both operators collude, they can compromise the privacy guarantees of OHTTP. The gateway and target server are typically operated by the same organization, while the relay is typically operated by a different organization to prevent collusion. An analysis by NCC Group of an OHTTP implementation also noted that, to reduce risk of traffic analysis and other attacks, "Deployment of OHTTP requires careful management of key rotation, rate limiting, and tolerances against network delays." Client applications configured to use OHTTP, such as applications designed to use OHTTP for certain API calls, do not need to try to find out whether OHTTP is available from a server. In other cases, if a server operator wants to tell clients that a service supports OHTTP, RFC 9540 (February 2024) defines an optional DNS resource record parameter. This mechanism enables a client to discover, after sending a DNS request, that they can send OHTTP requests, although the initial DNS request could expose the client's IP address to the server if not otherwise hidden.
An IETF working group, Oblivious HTTP Application Intermediation (OHAI), is responsible for working on OHTTP standards and collaborating with groups that work on related protocols. The Oblivious DNS over HTTPS (ODoH) protocol enables making Domain Name System (DNS) requests using similar architectural principles as OHTTP (RFC 9230, June 2022). Some people use virtual private network (VPN) services to address privacy concerns, but this enables a single entity to see identifying information about the user and all of their activity that passes through the VPN. Tor is a separate technology for protecting user privacy on the web by decoupling the sender from the receiver through at least three intermediate hops.
MASQUE (Multiplexed Application Substrate over QUIC Encryption) is a different set of protocols for improving the privacy of users making web requests. It can be used for web browsing. For example, Apple's iCloud Private Relay service uses MASQUE. This article lists standard and notable non-standard HTTP response status codes. Standardized codes are defined by IETF as documented in Request for Comments (RFC) publications and maintained by the IANA. Other, non-standard values are used by various servers. The descriptive text after the numeric code – the reason phrase – is shown here with typical value, but in practice, can be different or omitted.
Figure 3: Cloud-native Api protection: auth, access control, rate limiting ... 100 Continue The server has received the request headers and the client should proceed to send the request body (in the case of a request for which a body needs to be sent, such as a POST request). Sending a large request body to a server after a request has been rejected for inappropriate headers would be inefficient. To have a server check the request's headers, a client must send Expect: 100-continue as a header in its initial request and receive a 100 Continue status code in response before sending the body. If the client receives an error code such as 403 (Forbidden) or 405 (Method Not Allowed) then it should not send the request's body. The response 417 Expectation Failed indicates that the request should be repeated without the Expect header as it indicates that the server does not support expectations (this is the case, for example, of HTTP/1.0 servers). 101 Switching Protocols The requester has asked the server to switch protocols and the server has agreed to do so. 102 Processing (WebDAV; RFC 2518) A WebDAV request may contain many sub-requests involving file operations, requiring a long time to complete the request. This code indicates that the server has received and is processing the request, but no response is available yet. This prevents the client from timing out and assuming the request was lost. The status code is deprecated. 103 Early Hints (RFC 8297) Used to return some response headers before final HTTP message.
200 OK Standard response for successful HTTP requests. The actual response will depend on the request method used. In a GET request, the response will contain an entity corresponding to the requested resource. In a POST request, the response will contain an entity describing or containing the result of the action. 201 Created The request has been fulfilled, resulting in the creation of a new resource. 202 Accepted The request has been accepted for processing, but the processing has not been completed. The request might or might not be eventually acted upon, and may be disallowed when processing occurs. 203 Non-Authoritative Information (since HTTP/1.1) The server is a transforming proxy (e.g. a Web accelerator) that received a 200 OK from its origin, but is returning a modified version of the origin's response. 204 No Content The server successfully processed the request, and is not returning any content. 205 Reset Content The server successfully processed the request, asks that the requester reset its document view, and is not returning any content. 206 Partial Content The server is delivering only part of the resource (byte serving) due to a range header sent by the client. The range header is used by HTTP clients to enable resuming of interrupted downloads, or split a download into multiple simultaneous streams. 207 Multi-Status (WebDAV; RFC 4918) The message body that follows is by default an XML message and can contain a number of separate response codes, depending on how many sub-requests were made. 208 Already Reported (WebDAV; RFC 5842) The members of a DAV binding have already been enumerated in a preceding part of the (multistatus) response, and are not being included again. 226 IM Used (RFC 3229) The server has fulfilled a request for the resource, and the response is a representation of the result of one or more instance-manipulations applied to the current instance.
300 Multiple Choices Indicates multiple options for the resource from which the client may choose (via agent-driven content negotiation). For example, this code could be used to present multiple video format options, to list files with different filename extensions, or to suggest word-sense disambiguation. 301 Moved Permanently The link target was moved such that the request and future similar requests should be redirected to the given URI. If a client has link-editing capabilities, it should update references to the request URL. The response is cacheable unless indicated otherwise. Except for a GET request, the body should contain a hyperlink to the new URL(s). Except for a GET or HEAD request, the client must ask the user before redirecting.This code is considered best practice for upgrading users from HTTP to HTTPS. Both Bing and Google recommend using this code to change the URL of a page as it is shown in search engine results, providing that URL will permanently change and is not due to be changed again any time soon. 302 Found Indicates that the resource is accessible via an alternate URL indicated in the Location header field. The HTTP/1.0 specification (which used reason phrase "Moved Temporarily") required the client to redirect with the same method, but popular browsers instead changed the request to GET.
For this reason, HTTP/1.1 (RFC 2616) added two status codes: 303 which requires changing the request to a GET and 307 which preserves the original request type. Despite the greater clarity provided by this disambiguation, the 302 code is still used in web frameworks to preserve compatibility with browsers that do not support HTTP/1.1. As a consequence, RFC 7231 (the update of RFC 2616) changes the definition to allow user agents to rewrite POST to GET. 303 See Other (since HTTP/1.1) If a server responds to a POST or other non-idempotent request with this code and a location header field, the client is expected to issue a GET request to the specified location. To trigger a request to the target resource using the same method, the server responds with 307 instead. Use of this code has been proposed as one way of responding to a request for a URI that identifies a real-world object according to Semantic Web theory (the other being the use of hash URIs). For example, if http://www.example.com/id/alice identifies a person, Alice, then it would be inappropriate for a server to respond to a GET request with 200 OK, as the server could not deliver Alice herself. Instead, the server would respond with 303 to redirect to a URI that provides a description of the person Alice. Sometimes, this code is used when providing an HTTP-based web API that needs to respond to the caller immediately, but continue executing asynchronously, such as a long-lived image conversion. The web API provides a status check URI that allows the client to check on the operation's status. When complete, the response may contain this status code and a redirect URI to the final result. 304 Not Modified Indicates that the resource has not been modified since the version specified by the request headers If-Modified-Since or If-None-Match. In such case, there is no need to retransmit the resource since the client still has a previously-downloaded copy. 305 Use Proxy (since HTTP/1.1) The requested resource is available only through a proxy, the address for which is provided in the response.
For security reasons, many HTTP clients (such as Mozilla Firefox and Internet Explorer) do not obey this status code. 306 Switch Proxy No longer used. Originally meant "Subsequent requests should use the specified proxy." 307 Temporary Redirect (since HTTP/1.1) In this case, the request should be repeated with another URI; however, future requests should still use the original URI. In contrast to how 302 was historically implemented, the request method is not allowed to be changed when reissuing the original request. For example, a POST request should be repeated using another POST request. 308 Permanent Redirect This and all future requests should be directed to the given URI. 308 parallels the behavior of 301, but does not allow the HTTP method to change. So, for example, submitting a form to a permanently redirected resource may continue smoothly.
A 4xx status code is for situations in which an error seems to have been caused by the client. Except when responding to a HEAD request, the server should include an entity containing an explanation of the error situation, and whether it is a temporary or permanent condition. These status codes are applicable to any request method. User agents should display any included entity to the user.
400 Bad Request The server cannot or will not process the request due to an apparent client error (e.g., malformed request syntax, size too large, invalid request message framing, or deceptive request routing). 401 Unauthorized Similar to 403 Forbidden, but specifically for use when authentication is required and has failed or has not yet been provided. The response must include a WWW-Authenticate header field containing a challenge applicable to the requested resource. See Basic access authentication and Digest access authentication. 401 semantically means "unauthenticated", the user does not have valid authentication credentials for the target resource. 402 Payment Required Reserved for future use. The original intention was that this code might be used as part of some form of digital cash or micropayment scheme, as proposed, for example, by GNU Taler, but that has not yet happened, and this code is not widely used. Google Developers API uses this status if a particular developer has exceeded the daily limit on requests. Sipgate uses this code if an account does not have sufficient funds to start a call. Shopify uses this code when the store has not paid their fees and is temporarily disabled. Stripe uses this code for failed payments where parameters were correct, for example blocked fraudulent payments. Cloudflare Turnstile uses this code when requesting resources with cURL. 403 Forbidden The request was valid, but the server refuses action. This may be due to the user not having permission to a resource or needing an account of some sort, or attempting a prohibited action (e.g. creating a duplicate record where only one is allowed). This code is also typically used if the request provided authentication by answering the WWW-Authenticate header field challenge, but the server did not accept that authentication. The request should not be repeated. This code differs from 401 in that while 401 is returned when the client has not authenticated, and implies that a successful response may be returned following valid authentication, 403 is returned when the client is not permitted access to the resource despite providing authentication such as insufficient permissions of the authenticated account. The Apache web server returns 403 in response to a request for URL paths that corresponded to a file system directory when directory listing is disabled and there is no Directory Index directive to specify an existing file to be returned to the browser. Some administrators configure the Mod proxy extension to block such requests and this will also return 403. IIS responds in the same way when directory listings are denied in that server. In WebDAV, 403 is returned if the client issued a PROPFIND request but did not also issue the required Depth header or issued a Depth header of infinity. 404 Not Found The requested resource could not be found but may be available in the future. Subsequent requests by the client are permissible. 405 Method Not Allowed A request method is not supported for the requested resource (for example, a GET request on a form that requires data to be presented via POST, or a PUT request on a read-only resource). 406 Not Acceptable The requested resource is capable of generating only content not acceptable according to the Accept headers sent in the request. See Content negotiation. 407 Proxy Authentication Required The client must first authenticate itself with the proxy. 408 Request Timeout The server timed out waiting for the request. According to HTTP specifications: "The client did not produce a request within the time that the server was prepared to wait. The client MAY repeat the request without modifications at any later time." 409 Conflict Indicates that the request could not be processed because of conflict in the current state of the resource, such as an edit conflict between multiple simultaneous updates. 410 Gone Indicates that the resource requested was previously in use but is no longer available and will not be available again. This should be used when a resource has been intentionally removed and the resource should be purged. Upon receiving a 410 status code, the client should not request the resource in the future. Clients such as search engines should remove the resource from their indices.
Most use cases do not require clients and search engines to purge the resource, and a "404 Not Found" may be used instead. 411 Length Required The request did not specify the length of its content, which is required by the requested resource. 412 Precondition Failed The server does not meet one of the preconditions that the requester put on the request header fields. 413 Content Too Large The request is larger than the server is willing or able to process. Previously called "Request Entity Too Large" and "Payload Too Large". 414 URI Too Long The URI provided was too long for the server to process. Often the result of too much data being encoded as a query-string of a GET request, in which case it should be converted to a POST request. Called "Request-URI Too Long" previously. 415 Unsupported Media Type The request entity has a media type which the server or resource does not support. For example, the client uploads an image as image/svg+xml, but the server requires that images use a different format. 416 Range Not Satisfiable The client has asked for a portion of the file (byte serving), but the server cannot supply that portion. For example, if the client asked for a part of the file that lies beyond the end of the file.
Called "Requested Range Not Satisfiable" previously. 417 Expectation Failed The server cannot meet the requirements of the Expect request-header field. 418 I'm a teapot (RFC 2324, RFC 7168) This code was defined in 1998 as one of the traditional IETF April Fools' jokes, in RFC 2324, Hyper Text Coffee Pot Control Protocol, and is not expected to be implemented by actual HTTP servers. The RFC specifies this code should be returned by teapots requested to brew coffee. This HTTP status is used as an Easter egg in some websites, such as Google.com's "I'm a teapot" easter egg. Sometimes, this status code is also used as a response to a blocked request, instead of the more appropriate 403 Forbidden. 421 Misdirected Request The request was directed at a server that is not able to produce a response (for example because of connection reuse). 422 Unprocessable Content The request was well-formed (i.e., syntactically correct) but could not be processed. 423 Locked (WebDAV; RFC 4918) The resource that is being accessed is locked. 424 Failed Dependency (WebDAV; RFC 4918) The request failed because it depended on another request and that request failed (e.g., a PROPPATCH). 425 Too Early (RFC 8470) Indicates that the server is unwilling to risk processing a request that might be replayed. 426 Upgrade Required The client should switch to a different protocol such as TLS/1.3, given in the Upgrade header field. 428 Precondition Required (RFC 6585) The origin server requires the request to be conditional. Intended to prevent the 'lost update' problem, where a client GETs a resource's state, modifies it, and PUTs it back to the server, when meanwhile a third party has modified the state on the server, leading to a conflict. 429 Too Many Requests (RFC 6585) The user has sent too many requests in a given amount of time. Intended for use with rate-limiting schemes. 431 Request Header Fields Too Large (RFC 6585) The server is unwilling to process the request because either an individual header field, or all the header fields collectively, are too large.
451 Unavailable For Legal Reasons (RFC 7725) A server operator has received a legal demand to deny access to a resource or to a set of resources that includes the requested resource. The code 451 was chosen as a reference to the novel Fahrenheit 451. 500 Internal Server Error A generic error message, given when an unexpected condition was encountered and no more specific message is suitable. 501 Not Implemented The server either does not recognize the request method, or it lacks the ability to fulfil the request. Usually this implies future availability (e.g., a new feature of a web-service API). 502 Bad Gateway The server was acting as a gateway or proxy and received an invalid response from the upstream server. 503 Service Unavailable The server cannot handle the request (because it is overloaded or down for maintenance). Generally, this is a temporary state. 504 Gateway Timeout The server was acting as a gateway or proxy and did not receive a timely response from the upstream server. 505 HTTP Version Not Supported The server does not support the HTTP version used in the request. 506 Variant Also Negotiates (RFC 2295) Transparent content negotiation for the request results in a circular reference. 507 Insufficient Storage (WebDAV; RFC 4918) The server is unable to store the representation needed to complete the request. 508 Loop Detected (WebDAV; RFC 5842) The server detected an infinite loop while processing the request (sent instead of 208 Already Reported). 510 Not Extended (RFC 2774) Further extensions to the request are required for the server to fulfil it. 511 Network Authentication Required (RFC 6585) The client needs to authenticate to gain network access. Intended for use by intercepting proxies used to control access to the network (e.g., "captive portals" used to require agreement to Terms of Service before granting full Internet access via a Wi-Fi hotspot).
440 Login Time-out The client's session has expired and must log in again. 449 Retry With The server cannot honor the request because the user has not provided the required information. 450 Blocked by Windows Parental Controls Indicates that Windows Parental Controls block access to the requested webpage. 451 Redirect Used in Exchange ActiveSync when either a more efficient server is available or the server cannot access the users' mailbox. The client is expected to re-run the HTTP AutoDiscover operation to find a more appropriate server.
444 No Response Used internally to instruct the server to return no information to the client and close the connection immediately. 494 Request header too large Client sent too large request or too long header line. 495 SSL Certificate Error An expansion of the 400 Bad Request response code, used when the client has provided an invalid client certificate. 496 SSL Certificate Required An expansion of the 400 Bad Request response code, used when a client certificate is required but not provided. 497 HTTP Request Sent to HTTPS Port An expansion of the 400 Bad Request response code, used when the client has made a HTTP request to a port listening for HTTPS requests. 499 Client Closed Request Used when the client has closed the request before the server could send a response.
520 Web Server Returned an Unknown Error The origin server returned an empty, unknown, or unexpected response to Cloudflare. 521 Web Server Is Down The origin server refused connections from Cloudflare. Security solutions at the origin may be blocking legitimate connections from certain Cloudflare IP addresses. 522 Connection Timed Out Cloudflare timed out contacting the origin server. 523 Origin Is Unreachable Cloudflare could not contact the origin server. 524 A Timeout Occurred Cloudflare was able to complete a TCP connection to the origin server, but the origin did not provide a timely HTTP response.
525 SSL Handshake Failed Cloudflare could not negotiate a SSL/TLS handshake with the origin server. 526 Invalid SSL Certificate Cloudflare could not validate the SSL certificate on the origin web server. Also used by Cloud Foundry's gorouter. 527 Railgun Error (obsolete) Error 527 indicated an interrupted connection between Cloudflare and the origin server's Railgun server. This error is obsolete as Cloudflare has deprecated Railgun. 530 Origin Unavailable Cloudflare was unable to resolve the origin hostname, preventing it from establishing a connection to the origin server. The body of the response contains an 1xxx error.
000 Returned with an HTTP/2 GOAWAY frame if the compressed length of any of the headers exceeds 8K bytes or if more than 10K requests are served through one connection. 460 Client closed the connection with the load balancer before the idle timeout period elapsed. Typically, when client timeout is sooner than the Elastic Load Balancer's timeout. 463 The load balancer received an X-Forwarded-For request header with more than 30 IP addresses. 464 Incompatible protocol versions between Client and Origin server. 561 Unauthorized An error around authentication returned by a server registered with a load balancer. A listener rule is configured to authenticate users, but the identity provider (IdP) returned an error code when authenticating the user.
509 Bandwidth Limit Exceeded The server has exceeded the bandwidth specified by the server administrator; this is often used by shared hosting providers to limit the bandwidth of customers. Also used by cPanel. 420 Method Failure A deprecated response status proposed during the development of WebDAV used by the Spring Framework when a method has failed.
420 Enhance Your Calm Returned by version 1 of the Twitter Search and Trends API when the client is being rate limited; versions 1.1 and later use the 429 Too Many Requests response code instead. The phrase "Enhance your calm" comes from the 1993 movie Demolition Man, and its association with this number is likely a reference to cannabis. 2. System Architecture & Core Working Principles 430 Request Header Fields Too Large A deprecated response used by Shopify, instead of the 429 Too Many Requests response code, when too many URLs are requested within a certain time frame. 430 Shopify Security Rejection Used by Shopify to signal that the request was deemed malicious. 530 Origin DNS Error Indicates that Cloudflare can't resolve the requested DNS record. 540 Temporarily Disabled Indicates that the requested endpoint has been temporarily disabled. 783 Unexpected Token Indicates that the request includes a JSON syntax error.
498 Invalid Token Indicates an expired or otherwise invalid token. 499 Token Required Indicates that a token is required but was not submitted. 508 Resource Limit Is Reached Used instead of 503 when the server's account has exceeded the resources assigned to it, such as CPU/RAM usage or number of concurrent processes.
999 Request denied Related to being blocked/walled or unable to access their webpages without first signing in. Hypertext Transfer Protocol (HTTP) Status Code Registry at the Internet Assigned Numbers Authority MDN status code reference at mozilla.org You can configure throttling and quotas for your APIs to help protect them from being overwhelmed by too many requests.
Both throttles and quotas are applied on a best-effort basis and should be thought of as targets rather than guaranteed request ceilings. API Gateway throttles requests to your API using the token bucket algorithm, where a token counts for a request. Specifically, API Gateway examines the rate and a burst of request submissions against all APIs in your account, per Region. In the token bucket algorithm, a burst can allow pre-defined overrun of those limits, but other factors can also cause limits to be overrun in some cases.
When request submissions exceed the steady-state request rate and burst limits, API Gateway begins to throttle requests. Clients may receive 429 Too Many Requests error responses at this point. Upon catching such exceptions, the client can resubmit the failed requests in a way that is rate limiting. As an API developer, you can set the target limits for individual API stages or methods to improve overall performance across all APIs in your account. Alternatively, you can enable usage plans to set throttles on client request submissions based on specified requests rates and quotas.
Before you configure throttle and quota settings for your API, it's useful to understand the types of throttling-related settings for your API and how API Gateway applies them. AWS throttling limits are applied across all accounts and clients in a Region. These limit settings exist to prevent your APIâIIand your accountâIIfrom being overwhelmed by too many requests. These limits are set by AWS and can't be changed by a customer.
Per-account limits are applied to all APIs in an account in a specified Region. The account-level rate limit can be increased upon request - higher limits are possible with APIs that have shorter timeouts and smaller payloads. To request an increase of account-level throttling limits per Region, contact the AWS Support Center . For more information, see Amazon API Gateway quotas . Note that these limits can't be higher than the AWS throttling limits.
Per-API, per-stage throttling limits are applied at the API method level for a stage. You can configure the same settings for all methods, or configure different throttle settings for each method. Note that these limits can't be higher than the AWS throttling limits. Per-client throttling limits are applied to clients that use API keys associated with your usage plan as client identifier. Note that these limits can't be higher than the per-account limits.
Per-client or per-method throttling limits that you set for an API stage in a usage plan By default, API Gateway limits the steady-state requests per second (RPS) across all APIs within an AWS account, per Region. It also limits the burst (that is, the maximum bucket size) across all APIs within an AWS account, per Region. In API Gateway, the burst limit represents the target maximum number of concurrent request submissions that API Gateway will fulfill before returning 429 Too Many Requests error responses. For more information on throttling quotas, see Amazon API Gateway quotas .
In a usage plan , you can set a per-method throttling target for all methods at the API or stage level. You can specify a throttling rate , which is the rate, in requests per second, that tokens are added to the token bucket. You can also specify a throttling burst , which is the capacity of the token bucket. You can use the AWS CLI, SDKs, and the AWS Management Console to create a usage plan. For more information about how to create a usage plan, see Usage plans and API keys for REST APIs in API Gateway .
You can use the AWS CLI, SDKs, and the AWS Management Console to create stage-level throttling targets. For more information about how to use the AWS Management Console to create stage-level throttling targets, see Modify stage settings . For more information about how to use the AWS CLI to create stage-level throttling targets, see create-stage . You can set additional throttling targets at the method level in Usage Plans as shown in Create a usage plan . In the API Gateway console, these are set by specifying Resource=
Cloud security at AWS is the highest priority. As an AWS customer, you benefit from a data center and network architecture that is built to meet the requirements of the most security-sensitive organizations. Security is a shared responsibility between AWS and you. The shared responsibility model describes this as security of the cloud and security in the cloud: Security of the cloud âII AWS is responsible for protecting the infrastructure that runs AWS services in the AWS Cloud.
AWS also provides you with services that you can use securely. Third-party auditors regularly test and verify the effectiveness of our security as part of the AWS Compliance Programs . To learn about the compliance programs that apply to Amazon API Gateway, see AWS services in scope by compliance program . Security in the cloud âII Your responsibility is determined by the AWS service that you use. You are also responsible for other factors including the sensitivity of your data, your companyâIIs requirements, and applicable laws and regulations.
This documentation helps you understand how to apply the shared responsibility model when using API Gateway. The following topics show you how to configure API Gateway to meet your security and compliance objectives. You also learn how to use other AWS services that help you to monitor and secure your API Gateway resources. An API gateway is where the theoretical neatness of a microservices architecture meets the reality of production traffic. It is the single entry point through which every client request passes before reaching a backend service, which means it carries a significant amount of responsibility: authentication, authorization, rate limiting, load balancing, request routing, logging, and more.
Done well, the gateway becomes a force multiplier. It enforces policies consistently across every service without requiring each team to implement the same logic independently. Done poorly, it becomes a bottleneck that limits throughput and a single point of failure that takes down the entire system when it struggles. 3. Software Implementation, Frameworks & Protocols This guide covers the patterns and implementation decisions that separate a well-designed API gateway from one that creates problems at scale. It is written for backend architects, DevOps engineers, and security engineers who are either building a gateway from scratch or evaluating how to improve an existing one.
Before getting into patterns, it is worth being precise about scope. An API gateway handles concerns that are cross-cutting across services. These are things every service would need to implement on its own if the gateway did not handle them centrally. The core responsibilities fall into three categories. Traffic management covers routing, load balancing, circuit breaking, and retries. Security covers authentication, authorization, SSL termination, and input validation. Observability covers request logging, distributed tracing injection, and metrics collection.
Some teams also use the gateway for request and response transformation, API versioning, and developer portal management. These are valid use cases, but they should be evaluated carefully. The more logic the gateway contains, the heavier the operational burden of maintaining it becomes. A useful mental model: the gateway should handle concerns that are about the request itself, not concerns that are about the business logic of what the request is asking for. Business logic belongs in the services.
The concept of rate limiting is simple. Restrict how many requests a client can make within a time window. The implementation at scale is not. The first challenge is state. Rate limit counters need to be checked and incremented atomically on every request. In a single-instance deployment this is trivial. In a distributed gateway with multiple instances behind a load balancer, counters must be shared across instances, which means a centralized store like Redis becomes a dependency on the hot path.
The second challenge is granularity. Rate limits can be applied at multiple levels: per IP address, per API key, per user account, per endpoint, or per tier of service plan. A well-designed rate limiting system supports all of these simultaneously, because a single abusive user and a DDoS from thousands of IPs require different responses. The token bucket algorithm maintains a bucket of tokens for each client. Tokens are added at a fixed rate up to a maximum.
Each request consumes one token. When the bucket is empty, requests are rejected. This allows short bursts above the average rate, which is the right behavior for most legitimate API consumers who occasionally batch requests. The sliding window algorithm tracks all requests within a rolling time window. It prevents bursts more strictly than token bucket but is more expensive to compute because it requires storing individual request timestamps rather than a single counter.
Redis sorted sets are a common implementation substrate for sliding windows. For most public APIs, token bucket with a per-key and per-IP limit provides the right balance of burst tolerance and abuse prevention. Sliding window is better suited for billing-critical APIs where exact per-period consumption must be enforced. Planning or Scaling Your API Gateway Infrastructure? Askan Technologies Delivers End-to-End Backend Architecture SSL termination at the gateway is standard practice. The gateway decrypts inbound HTTPS traffic and forwards requests to backend services over HTTP within the private network. This offloads cryptographic computation from individual services and centralizes certificate management.
For services that handle sensitive data and require end-to-end encryption even within the cluster, mutual TLS between the gateway and backend services is the correct approach. Service meshes like Istio handle mTLS transparently across services, but if you are running a gateway-only architecture without a service mesh, you need to manage certificates between the gateway and services explicitly.
JSON Web Tokens are the standard authentication mechanism for API gateways in 2026. The gateway validates the JWT signature on every request using a public key from the identity provider. Valid tokens are forwarded to the backend with the decoded claims attached as request headers. Invalid tokens are rejected at the gateway before they reach any service. This model means the backend services can trust the claims passed by the gateway without re-validating the token, which removes a redundant cryptographic operation on the hot path. The trade-off is that the gateway must have access to the public key and must handle key rotation without downtime.
Key rotation is handled cleanly by supporting multiple valid public keys simultaneously during the rotation window. Both the old and new key are accepted until all tokens signed by the old key have expired. For machine-to-machine integrations and third-party access, API keys are simpler than JWTs and easier for external developers to use. The gateway stores a hash of each key (never the key itself) and validates inbound keys against the store.
API keys should be scoped. A key issued for read-only access to a specific resource set should not grant write access or access to other resources. Scope enforcement at the gateway prevents scope creep from becoming a security liability. Authentication, confirming who the requester is, belongs at the gateway. Authorization, deciding what that requester is allowed to do, requires a more careful split.
Coarse-grained authorization, such as confirming that a given API key has access to a particular service or that a user’s token includes a required role, belongs at the gateway. Fine-grained authorization, such as determining whether a specific user can access a specific record, belongs in the service because it requires business context the gateway does not have. Attempting to push fine-grained authorization logic into the gateway results in a gateway that becomes tightly coupled to business rules and difficult to maintain independently of the services it fronts.
Request routing is the most fundamental gateway function. Incoming requests are matched against routing rules and forwarded to the appropriate backend service. Routing rules can be based on path prefix, host header, HTTP method, query parameters, or custom headers. Load balancing distributes traffic across multiple instances of the same service. Round-robin is the default and handles homogeneous instances well. Weighted round-robin is useful during canary deployments when you want to send a percentage of traffic to a new version. Least-connections routing is better for services with variable response times where some requests are significantly more expensive than others.
A circuit breaker prevents a failing backend service from being continuously hammered with requests it cannot handle. When the error rate for a service exceeds a threshold, the circuit opens and subsequent requests fail fast at the gateway instead of waiting for a timeout. After a configured interval, a test request is sent to check whether the service has recovered. Circuit breakers are critical for preventing cascade failures in microservices architectures. When Service A depends on Service B, and Service B starts responding slowly, Service A’s thread pool fills with waiting requests and it too begins failing.
The circuit breaker at the gateway stops this propagation before it reaches the client. Kong, Nginx with Lua extensions, and Envoy all provide circuit breaking configuration. For teams running a managed gateway, AWS API Gateway supports circuit breaking through integration with CloudWatch alarms and Lambda authorizers. Retry logic at the gateway should be applied selectively. Retrying GET requests on temporary failures is generally safe.
Retrying POST or PUT requests risks duplicate operations unless the backend service implements idempotency keys. 4. Practical Deployment, Analysis & Case Studies Timeout configuration requires coordination with backend service SLAs. A gateway timeout that is shorter than the maximum processing time of a legitimate request will cause requests to fail that would have succeeded with more patience. A timeout that is too long holds connections open and reduces the gateway’s capacity to handle concurrent traffic. Start with p99 latency measurements from the backend service and set timeouts at two to three times that value.
Planning or Scaling Your API Gateway Infrastructure? Askan Technologies Delivers End-to-End Backend Architecture The gateway tool choice shapes the operational model significantly. There is no universally correct answer, but there are clear patterns for different contexts. Kong is built on top of Nginx and OpenResty and is the most widely deployed open-source API gateway in production microservices environments. Its plugin architecture allows rate limiting, authentication, logging, and transformation to be configured declaratively without writing custom code.
Kong’s declarative configuration via deck or the Kong Admin API integrates cleanly with GitOps workflows, which is important for teams that manage infrastructure as code. Kong also supports a Kubernetes-native deployment model through the Kong Ingress Controller, making it a natural fit for teams already running on Kubernetes. The primary operational cost of Kong is the datastore dependency. Kong stores configuration in PostgreSQL or in a DB-less mode using declarative YAML. The DB-less mode reduces operational complexity but limits some dynamic configuration capabilities.
Nginx is the foundation of many gateway implementations. Teams with Lua scripting experience can implement sophisticated routing, rate limiting, and authentication logic directly in Nginx configuration. For teams that need precise control over every aspect of gateway behavior and are willing to maintain that configuration, Nginx provides unmatched flexibility. For most teams, however, the operational burden of a custom Nginx gateway exceeds the value. Kong or a managed gateway is a more maintainable starting point.
AWS API Gateway, Google Cloud Apigee, and Azure API Management each provide a fully managed gateway with built-in rate limiting, authentication, developer portal, and monitoring. The trade-off is reduced control and vendor lock-in. For teams that prioritize operational simplicity over fine-grained control, managed gateways significantly reduce the engineering effort required to maintain gateway infrastructure.
A gateway that does not emit rich observability data is an opaque bottleneck. At minimum, every request passing through the gateway should produce a structured log entry and contribute to latency and error rate metrics per service and per endpoint. Kong’s Prometheus plugin, Nginx’s built-in log format with Filebeat forwarding, and Envoy’s native stats emission all provide solid foundations for gateway observability. The important thing is consistency: every request goes through the gateway, so every request should be represented in your metrics and traces.
For teams building out their observability stack alongside their gateway, the monitoring architecture patterns covered in our piece on building observable systems with metrics, logs, and traces provide useful context for connecting gateway telemetry to a broader distributed tracing setup. The gateway sits on the critical path of every request in the system. Its availability and performance directly determine the availability and performance of everything behind it.
Horizontal scaling is the right model. Run multiple gateway instances behind a cloud load balancer. Because the gateway is designed to be stateless (all state lives in Redis for rate limiting or in the identity provider for authentication), adding instances is straightforward. Rate limit state in Redis introduces a dependency. If Redis becomes unavailable, the gateway must decide whether to fail open (allow all requests) or fail closed (reject all requests). Failing open preserves availability but removes rate limiting protection. Failing closed is safe but causes a complete outage. Most teams configure a grace mode that allows requests through for a short period during Redis unavailability while alerting on the degradation.
Cache gateway configuration aggressively. Route definitions and API key lookups that require a datastore read on every request are a common performance bottleneck. In-memory caching of configuration with a TTL that is short enough to reflect changes within seconds eliminates this bottleneck without compromising consistency. The Kong documentation at docs.konghq.com covers the full plugin configuration reference for rate limiting, authentication, and load balancing, and is the most reliable reference for teams implementing Kong-based gateways in production.
Before pushing a gateway configuration to production, these are the checks that prevent the most common failure modes: These steps are not exhaustive, but they cover the failure modes that cause the most production incidents in gateway deployments. A gateway that handles authentication, rate limiting, and traffic management correctly is largely invisible during normal operation, which is exactly what it should be.
Planning or Scaling Your API Gateway Infrastructure? Askan Technologies Delivers End-to-End Backend Architecture Ask a developer why a page feels slow, and the honest answer is often sitting right in the middle of it. A single unoptimised... Microservices have dominated architecture conversations for years, to the point where choosing a monolith can feel like admitting you're behind the times. In practice,...
Magento has a reputation for being resource-heavy, and while some of that is inherent to running a full-featured enterprise commerce platform, a large share... Ask a developer why a page feels slow, and the honest answer is often sitting right in the middle of it. A single unoptimised... Microservices have dominated architecture conversations for years, to the point where choosing a monolith can feel like admitting you're behind the times. In practice,...
Magento has a reputation for being resource-heavy, and while some of that is inherent to running a full-featured enterprise commerce platform, a large share... Every microservices architecture eventually needs a front door. The API gateway is that door — and if you design it poorly, it becomes a single point of failure, a performance bottleneck, or a security gap. A well-designed gateway handles routing, rate limiting, authentication, circuit breaking, and observability so that individual services can focus on business logic. Here is a hands-on guide to the core patterns, trade-offs, and implementation strategies for building resilient API gateways.
The API gateway is a reverse proxy with intelligence . It sits between clients and backend services, centralizing cross-cutting concerns that would otherwise be duplicated in every service. The key insight is that not every concern belongs in the gateway: business logic should stay in services, but authentication, rate limiting, and routing are gateway responsibilities. 5. Performance Evaluation & Extended Technical Observations Routing decisions should be stateless and deterministic so that any gateway instance can handle any request. Session affinity (sticky sessions) should be avoided; if you need it, prefer consistent hashing over IP-based stickiness. Rate limiting must be distributed in a multi-instance gateway deployment; local in-memory counters are insufficient because a client can round-robin across instances and bypass limits.
Circuit breakers prevent cascading failures. When a service is struggling, the gateway should fail fast rather than queue requests that will timeout. This protects both the struggling service and the caller. The half-open state allows gradual recovery: after a cooldown, a limited number of requests are allowed through to test if the service has recovered. Use path-based versioning: /v1/users, /v2/users. The gateway routes to different services or versions of the same service.
Keep v1 running while v2 is in use. Schedule v1 deprecation with a response header: Sunset: Sat, 31 Dec 2026 23:59:59 GMT. Document changes between versions. Never break v1 without 6 months notice. One gateway is simpler but becomes a bottleneck and a single point of failure. Most organizations eventually split by concern: a public gateway for external clients, an internal gateway for service-to-service communication, and possibly a B2B gateway for partner APIs. The rule of thumb: split when your gateway configuration exceeds 1,000 lines or when different clients need fundamentally different authentication schemes.
WebSockets require connection-aware routing . The gateway must maintain the TCP connection and route subsequent frames to the same upstream instance. Not all gateways support this natively. Envoy and Nginx do; AWS API Gateway v2 supports WebSockets with Lambda or HTTP integrations. For high-scale WebSocket workloads, consider a dedicated WebSocket gateway separate from your HTTP API gateway.
A well-tuned gateway adds 0.5–2ms latency per hop for simple routing. SSL termination can actually improve total latency because services no longer do TLS handshakes. The biggest risk is misconfiguration: overly complex regex routing, synchronous blocking I/O, or excessive request/response transformation. Benchmark your gateway independently using tools like k6 or vegeta before deploying to production.
A practical guide to microservices: benefits, trade-offs, common patterns, and when to choose them over monoliths. Covers decomposition strategies and operational complexity. A practical guide to decomposing monoliths: strangler fig, branch by abstraction, and incremental extraction patterns that reduce risk and preserve business continuity.
A thorough security checklist for APIs: authentication, authorization, input validation, rate limiting, encryption, logging, and deployment hardening. A practical guide to API rate limiting: token bucket, leaky bucket, sliding window algorithms, choosing limits, and implementing resilient throttling for APIs.
In this tutorial, you'll learn about Cloud API Security. We cover key concepts, practical examples, and best practices to help you understand and apply this topic effectively. Cloud API security protects REST and GraphQL APIs from abuse, injection attacks, and unauthorized access using API gateways with authentication, Rate Limiting, request validation, and threat detection across AWS, Azure, and GCP.
How to secure APIs using cloud-native gateways, implement OAuth 2.0 and API key authentication, apply Rate Limiting and throttling, and protect against common API attacks. APIs are the primary attack surface for modern applications. Gartner predicts that API abuses will become the most frequent attack vector by 2027. Every public API needs authentication, throttling, and input validation.
DodaTech's public API handles 10 million requests daily through AWS API Gateway. Each request requires a valid OAuth 2.0 token, requests over 100 per second per client are throttled, and request bodies are validated against a JSON schema before reaching the backend. API Gateway supports multiple authentication methods including IAM, Cognito, Lambda authorizers, and API keys.
Azure API Management provides a full API Gateway with built-in policies for authentication, Rate Limiting, and transformation. Apigee provides enterprise-grade API management with security policies, analytics, and developer portals. Validate request sizes, block SQL Injection patterns, and verify content types before they reach backend services. Create a secure API for a payment processing service. Use AWS API Gateway with Cognito user pool authentication, 50 requests per second Rate Limiting per client, JSON schema validation on the request body, and request size limiting to 1 MB.
Deploy the API and test with a valid token (getting rate limited) and an invalid token (getting 401). Write the equivalent configuration for Azure API Management. The practice of protecting cloud-hosted APIs through authentication, Rate Limiting, input validation, and threat detection. API Gateway can use IAM roles, Cognito user pools, Lambda authorizers, or API keys to verify the identity of API callers.
Rate Limiting restricts the number of API calls a client can make within a time window, preventing abuse and ensuring fair usage. Yes. Apigee provides built-in OAuth 2.0 policies for authorization code, implicit, client credentials, and resource owner password grant types.
Request validation ensures that only well-formed payloads reach backend services, blocking injection attacks, malformed data, and oversized requests. 2026-03-13 · 14 min read · #architecture #api-gateway #rate-limiting #authentication #bff #microservices As microservices architectures proliferate, it becomes impractical for clients to communicate directly with dozens or hundreds of backend services. An API Gateway serves as a single entry point between clients and backend services, centralizing cross-cutting concerns such as routing, authentication/authorization, rate limiting, load balancing, and protocol translation.
This article covers the core concepts of the API Gateway pattern, followed by an in-depth comparison of Rate Limiting algorithms (Token Bucket, Sliding Window, Fixed Window, Leaky Bucket), JWT/OAuth2-based authentication strategies, BFF (Backend for Frontend) architecture design, load balancing and circuit breaker configurations, and production implementation examples using Kong and Apache APISIX. We conclude with real-world failure scenarios and an operational checklist for production environments.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Cilium%20%28computing%29 • https://en.wikipedia.org/wiki/Oblivious%20HTTP • https://en.wikipedia.org/wiki/List%20of%20HTTP%20status%20codes • https://docs.aws.amazon.com/apigateway/latest/developerguide/api-gateway-request-throttling.html • https://docs.aws.amazon.com/apigateway/latest/developerguide/security.html • https://www.askantech.com/api-gateway-patterns-rate-limiting-authentication-traffic-management-scale/ • https://stackpractices.com/guides/api-gateway-design-guide/ • https://tutorials.dodatech.com/cloud-security/cloud-api-security/ • https://labhub.hopto.org/blog/architecture/2026-03-13-api-gateway-pattern-rate-limiting-auth-bff-design?lang=en
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for API Gateway With Security Rate Limiting In Cloud.
[*] Initializing Burp Suite Spider & Vulnerability Engine for API Gateway With Security Rate Limiting In Cloud... [✓] Burp Extender / Macro Automation Hook Synced ──────────────────────────────────────────────────────────────────────── [11:42:01.104] AUDIT Crawled dynamic endpoints | Injecting input vectors [11:42:01.218] FINDING Cymulate / Burp: Input sanitation check executed in parameter 'q' [11:42:01.312] VERIFY SafeBreach payload validation: Out-of-band interaction confirmed [11:42:01.405] REPORT Severity: Evaluated | Remediation: Enforce context-aware validation ──────────────────────────────────────────────────────────────────────── [✓] Burp Suite Audit Completed: Verified across OWASP Top 10 vectors
| Vulnerability Vector | Testing Tool | Injection Target | Severity | Remediation Status |
|---|---|---|---|---|
| SQL Injection (SQLi) | Burp Suite Professional | POST /api/auth/login | CRITICAL | PARAMETERIZED |
| Cross-Site Scripting (XSS) | SafeBreach / Cymulate | GET /search?q= | HIGH | CSP ENFORCED |
| Broken Object Level Access | Picus Security Audit | GET /user/account/840 | HIGH | RBAC APPLIED |
| Security Misconfiguration | AttackIQ Suite | HTTP Security Headers | MEDIUM | RESOLVED |