Complete Technical Paper Content — Application Layer DDoS Attack Detection Using Deep Learning
Overview & System Context
Application Layer Ddos Attack Detection Using Deep Learning: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9536 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Distributed Denial of Service attacks represent an active cybersecurity research problem. Recent research shifted from static rule-based defenses towards AI-based detection and mitigation. This comprehensive survey covers several key topics.
Preeminently, state-of-the-art AI detection methods are discussed. An in-depth taxonomy based on manual expert hierarchies and an AI-generated dendrogram are provided, thus settling DDoS categorization ambiguities. An important discussion on available datasets follows, covering data format options and their role in training AI detection methods together with adversarial training and examples augmentation. Beyond detection, AI based mitigation techniques are surveyed as well.
Finally, multiple open research directions are proposed. DoS (Denial of Service) and DDoS (Distributed Denial of Service) represent a major cybersecurity threat. DDoS attacks increased by 55% between January 2020 and March 2021 ( Shroff et al., 2022 ) , a phenomenon that was accentuated starting from the second half of 2021 and continued until the first half of 2022, when the total number of attacks increased by 75.60% ( Mustapha et al., 2023 ) .
According to Markets&Markets 1 1 1 https://www.marketsandmarkets.com/Market-Reports/ddos-protection-mitigation-market-111952874.html , the global DDoS security and protection market size was valued at USD 3.9 billion in 2022 and is expected to reach USD 7.3 billion by 2027, with a CAGR of 13.2% from 2022 to 2027. Cloud-based DDoS security and protection services can effectively handle volumetric DDoS attacks, as well as layer 3 and 7 attacks. Thus, to optimize operations and costs, companies are rapidly adopting cloud-based anti-DDoS solutions. At the same time, due to the increasing adoption of 5G technology, a survey by the American mobile operator A10 showed that 63% of respondents believe that advanced DDoS security and protection solutions are needed to protect 5G networks. Therefore, we consider DDoS detection and mitigation an important global topic where modern AI techniques are necessary to fight off attacks, while, at the same time, helping the victim in maintaining a functioning infrastructure.
In this work, we use machine learning and artificial intelligence interchangeably to describe learning-based methods. Where appropriate, we will use the terms shallow and deep learning to separate classical machine learning methods from deep neural networks. We follow the classification of DDoS attacks according to the Cybersecurity and Infrastructure Security Agency guide provided by the Federal Bureau of Investigation ( Cybersecurity and Infrastructure Security Agency, 2024 ) .
There, DDoS categories are separated into volumetric ( Najafimehr et al., 2023 ) , protocol ( Senthil et al., 2022 ; Najafimehr et al., 2023 ) , and application ( Tripathi and Hubballi, 2021 ; Senthil et al., 2022 ; Najafimehr et al., 2023 ) level attacks ( Singh and Gupta, 2022 ) . Volumetric attacks are most common, often involving bot networks that bombard the victim with a large number of connections that do not have to maintain state, like UDP packets, for example. Protocol attacks are more sophisticated, as they exploit defects found in specific protocol implementations to employ both network floods, but also computational burden on the target. Reflection and amplification ( Rahef Nuiaa et al., 2022 ; Najafimehr et al., 2023 ) are commonly-used DDoS techniques meant to widen volumetric and protocol attacks. Application attacks target high-level services, such as web applications and database management systems, and mostly inflict large computational loads on the victims.
DDoS defenses are of special interest for IoT networks which are more susceptible and represent a large part of the bot infrastructure mounted during volumetric and protocol attacks ( Kadri et al., 2024 ; Pakmehr et al., 2024 ) . SDN is another particular context where anti-DDoS methodologies were studied ( Musa et al., 2024 ; Su et al., 2024 ) . As these represent dynamic network architectures often used in cloud environments, their configuration usually includes recent DDoS defenses which take advantage of the known software-defined topology.
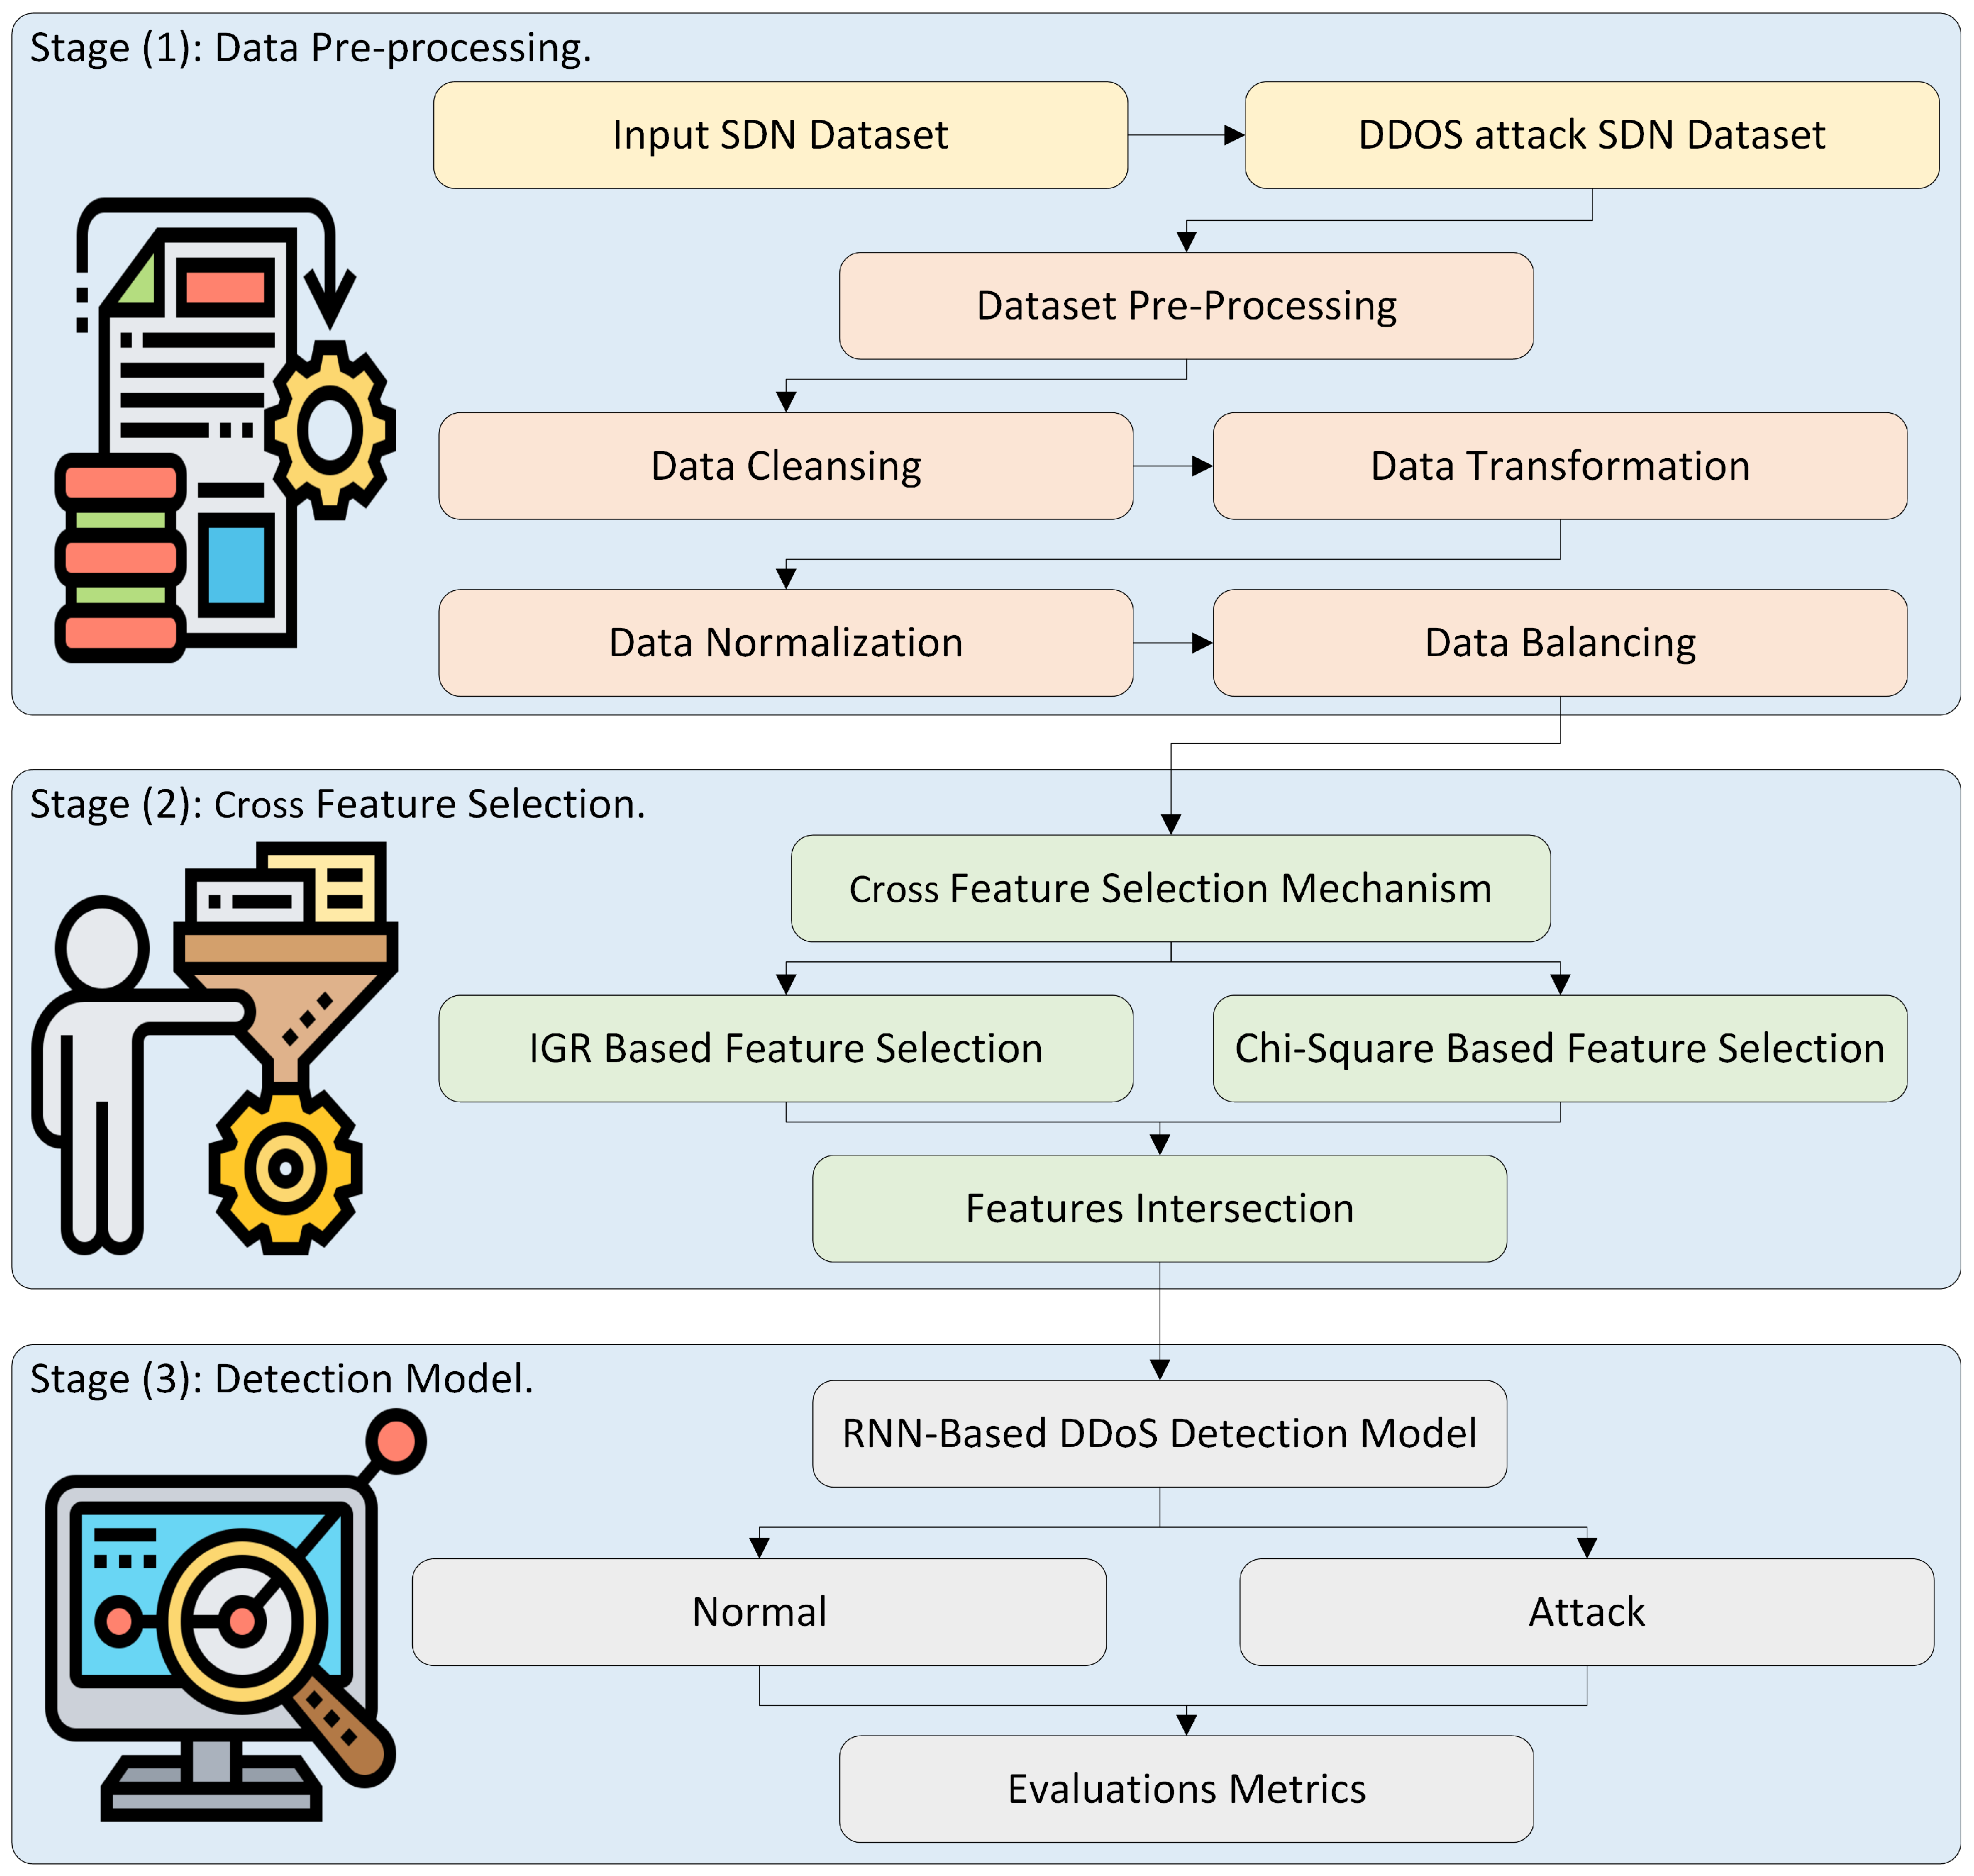
Figure 1: Systems | Free Full-Text | Deep Learning-Based Approach for Detecting ... AI-based detection is often treated in the literature as a binary classification task ( Salahuddin et al., 2021 ; Rios et al., 2024 ) performed on available datasets ( Sharafaldin et al., 2019 ; Sharafaldin et al., 2018 ; Alzahrani and Hong, 2018 ) containing raw labeled traffic recordings of normal and attack traffic. The attacks are usually mixed ( Kayacik et al., 2005 ; Moustafa and Slay, 2015 ) as the datasets are designed for IDS ( Sharafaldin et al., 2018 ) or IoT networks ( Koroniotis et al., 2019 ; Alsaedi et al., 2020 ) , and not specifically for the DDoS case. That is why, among the datasets that do contain DDoS attacks, most focus on volumetric floods or web application attacks. Recent trends show an interest in the use of adversarial training and adversarial attacks and examples ( Alatwi and Morisset, 2021 ; He et al., 2023 ) as a means to provide more robust detection models.
Once detected, the next critical step for anti-DDoS methods is attack mitigation ( Alatwi and Morisset, 2021 ) . Mitigation represents the set of measures taken to block the attack and permit normal traffic to pass through. These often resume to manual firewall rules, custom made for the current attack. Unfortunately, AI literature on the topic is limited to DTs ( Zadnik and Carasec, 2023 ; Coscia et al., 2024 ) and a few specific cases, such as DNS Floods ( Wang, 2012 ; Hitesh Ballani, 2008 ) . Only recently, we started to see an interest in specializing deep learning methods in general, and LLM in particular, to automatically generate firewall rules ( Louro et al., 2024 ; Wang et al., 2024 ; Yin et al., 2024 ) .
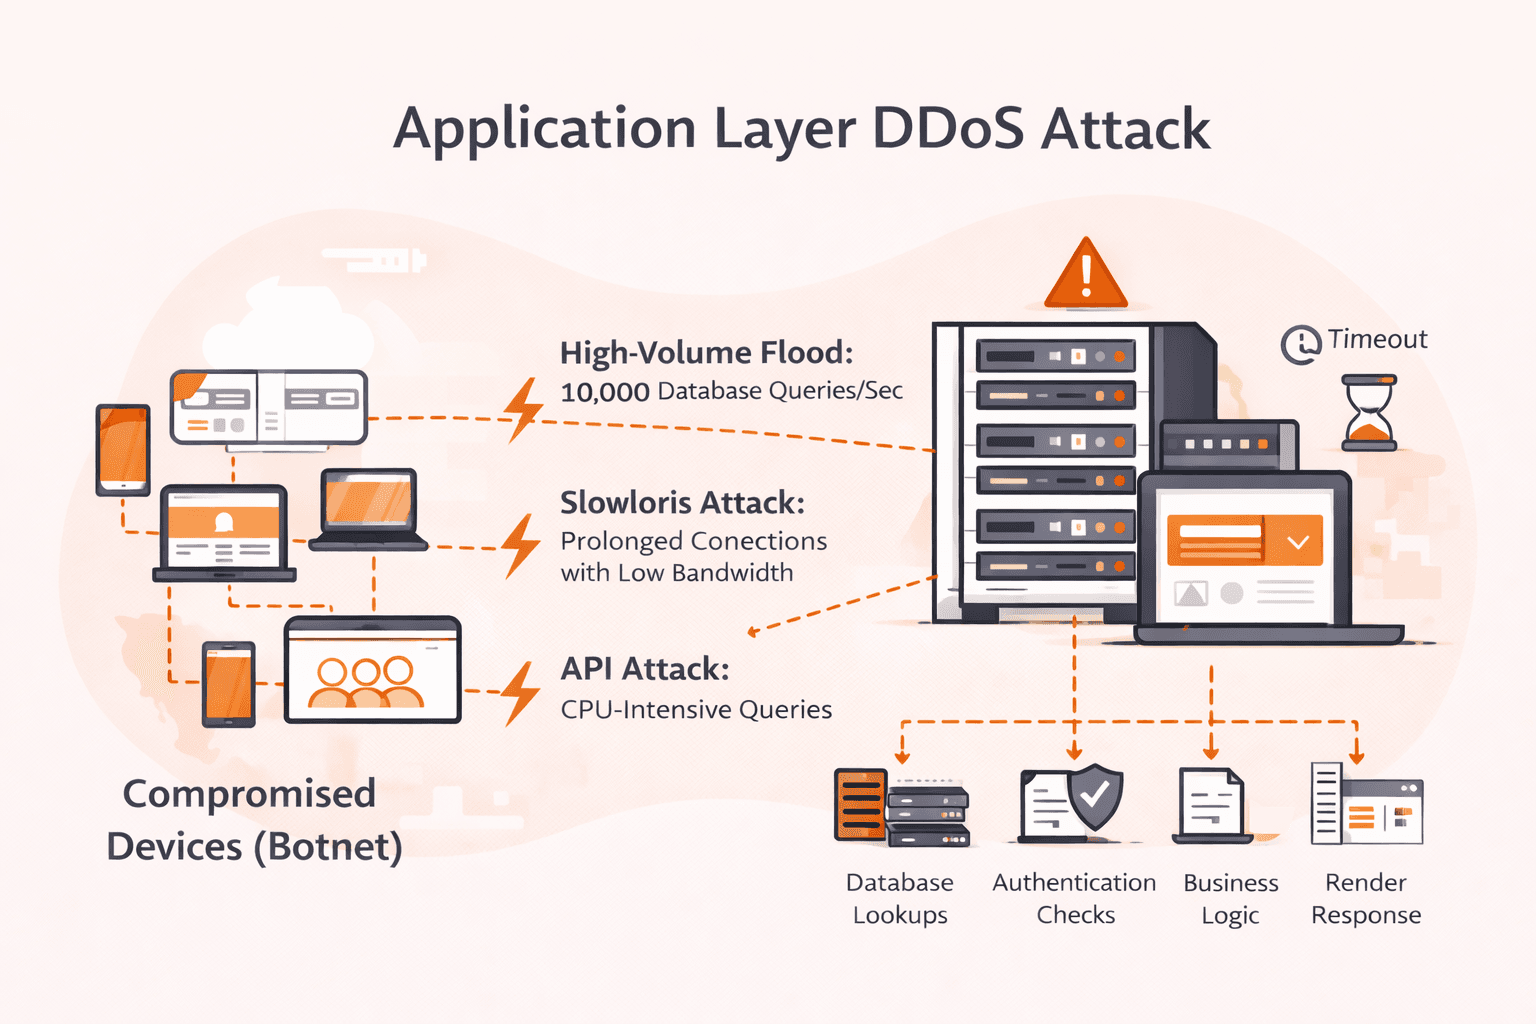
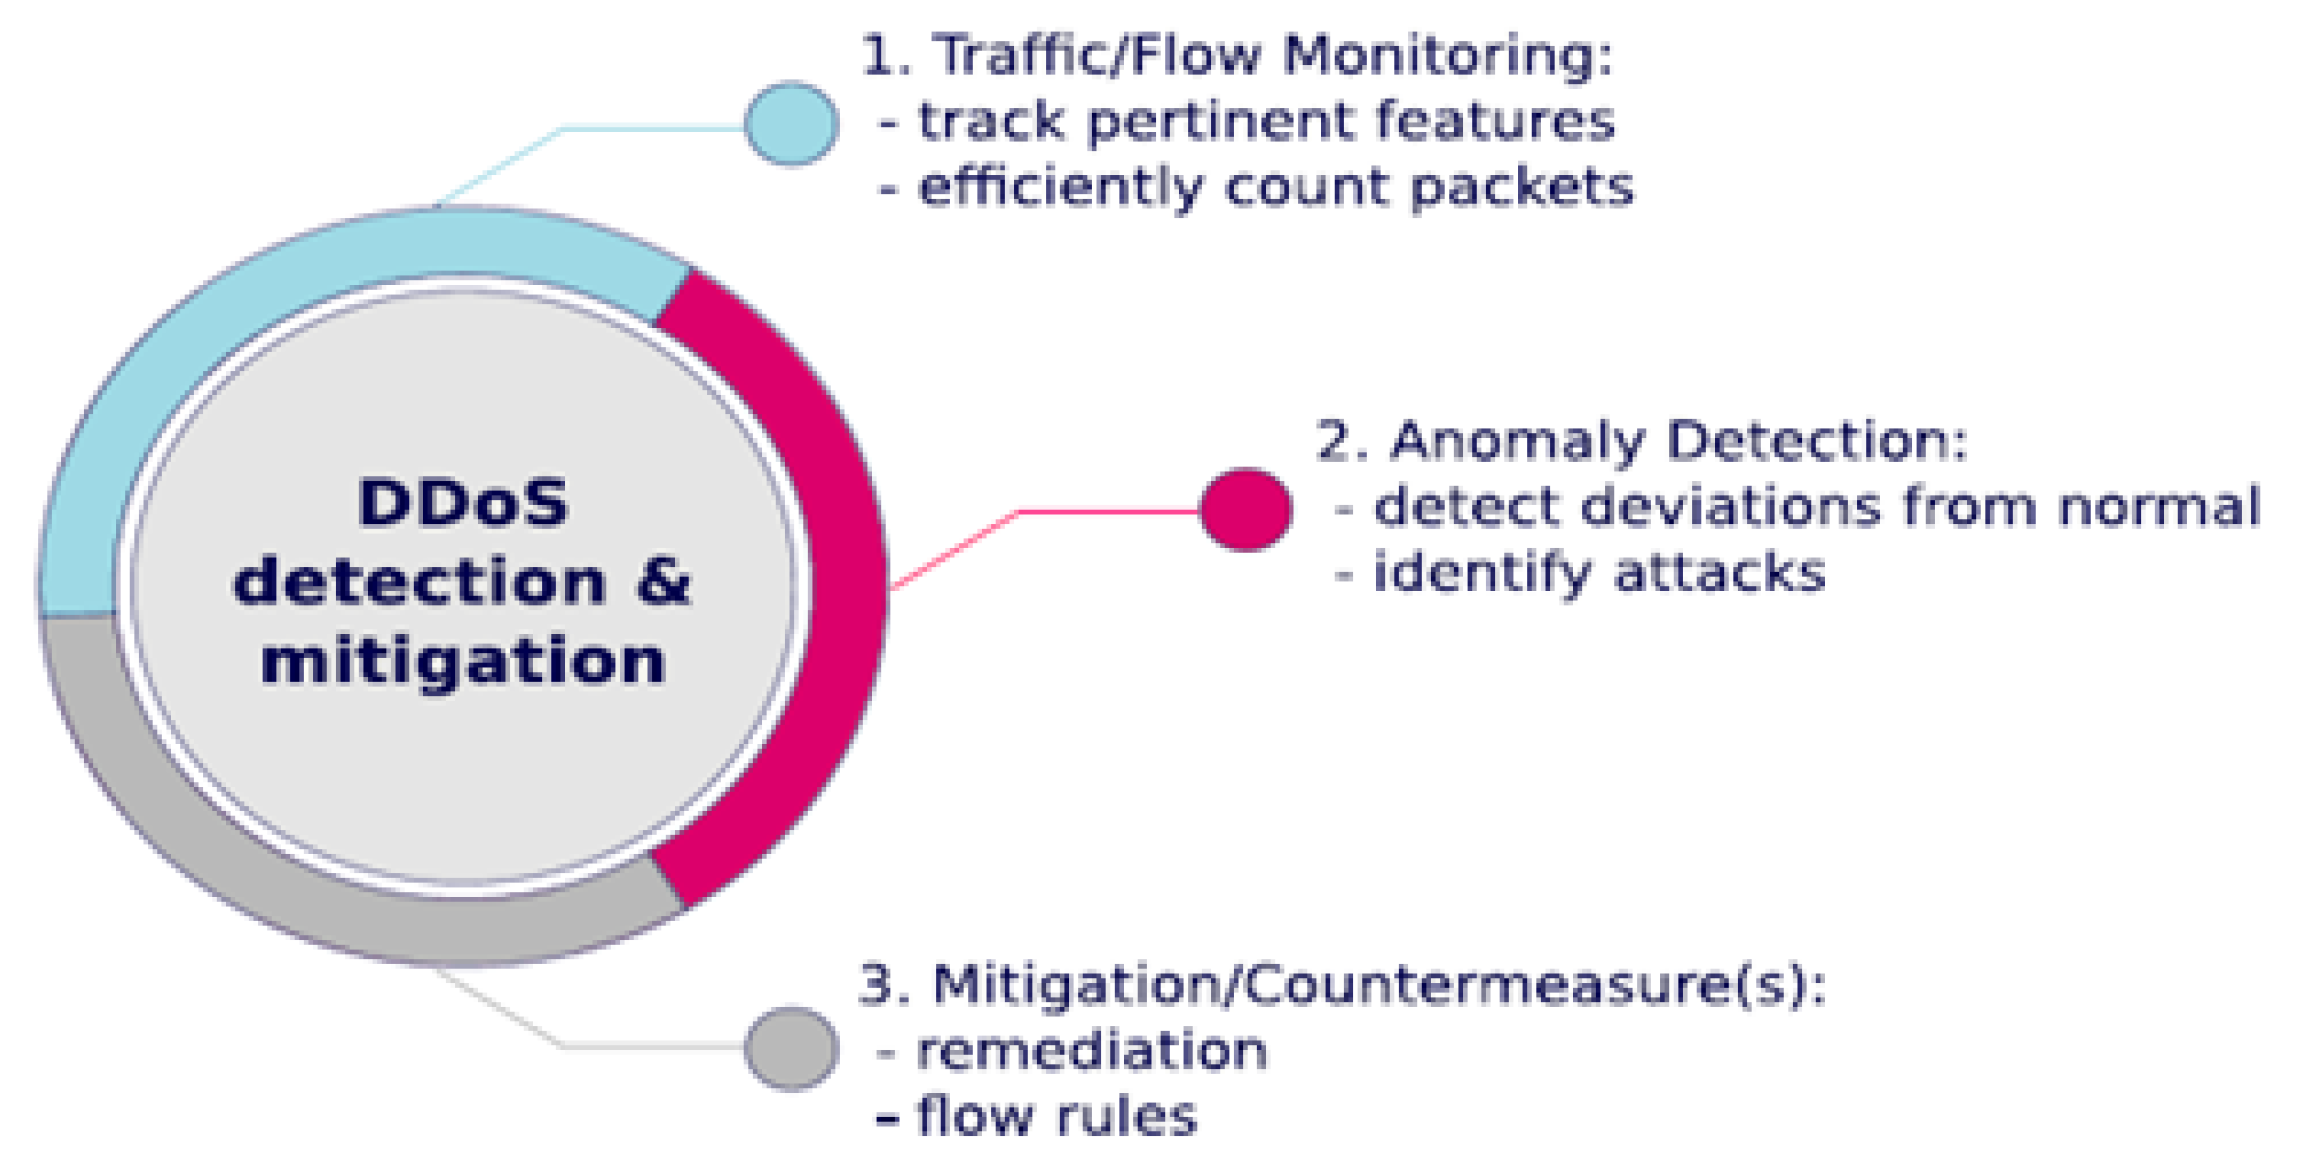
In this paper, we present a clear and structured survey covering all attack categories and attack types, with a special focus on their detection and mitigation through machine learning methods. To our knowledge, this undertaking has not been addressed in the literature, so far. As such, we would like to underline the following important contributions that our study provides: Taxonomy. (a) We provide a thorough hierarchical grouping of the surveyed research papers from the perspective of their main contribution; (b) we identify four different attack categories in an attempt to settle existing overlaps and ambiguity found in the literature, especially between protocol and application attacks; (c) we introduce an automatic taxonomy based on an agglomerative clustering algorithm, which we discuss and compare; Figure 2: What is Application Layer DDoS Data format. As far as we are aware, our work is the first to discuss and analyze upfront data formatting and preprocessing options for the machine learning algorithms; starting from the raw network traffic, we discuss data representation as topological graph data for traffic structure information, timeseries data for aggregate traffic evolution, and tabular data for individual packets and coalesced flow information; Detection. (a) We provide an in-depth discussion for each of the four attack categories including all attack types within; (b) we include an important discussion and analysis regarding the time delay between the moment that an attack is mounted and the moment when it is detected and then mitigated; Mitigation. As far as we are aware, we are the first to survey papers dealing with mitigation, after the DDoS attack is detected, where mitigation is achieved trough AI methods whose task is to emit efficient firewall blocking rules; AI-generated DDoS traffic. This is the first survey to include the topic of (a) adversarial training and (b) adversarial examples and attacks – these generative AI techniques can help to improve detection and mitigation; Figure 3: Effective and Efficient DDoS Attack Detection Using Deep Learning ...
Research directions. We identify and provide clear and direct ways of improving the field of DDoS detection and mitigation using AI; although the literature consists of a vast amount of work on this topic, we notice a lack of specialized anti-DDoS machine learning methods, while practical tasks, such as minimizing detection delays together with providing efficient mitigation techniques, are just beginning to be explored.
The survey is organized in multiple sections with the list of terms and abbreviations collected in Table 1 . Section 2 discusses existing surveys by comparing our work with them and motivating the need for the current manuscript. In Section 3 , we carefully define and describe the attack categories and attack types within each category in order to group the selected papers from this survey through the use of both manual and automatic taxonomies. Section 4 discusses available datasets and, more importantly for machine learning algorithms, the data formats and preprocessing techniques that are used by recent learning algorithms. Next, we delve into the details regarding DDoS detection, in Section 5 , and AI-based mitigation, in Section 7 . The detection section includes all the attack categories included in the taxonomy (volumetric, protocol and application), but also a dedicated subsection for reflection and amplification techniques. In Section 6 , we discuss how to further improve existing algorithms, models and datasets through adversarial training and adversarial examples. Finally, in Section 8 , we discuss future research opportunities for the directions described above along with conclusion after our intensive survey activity.
While existing literature contains plenty survey papers on the DDoS topic, most are centered on the attacks and few on the detection and mitigation tasks. Out of the latter, even fewer include learning based approaches, as can be seen in Table 2 : only the three papers at the top employ a general study of the field, while the ones at the bottom focus on specific tasks and testbeds.
Anti-DDoS surveys studying the general problem from a machine learning perspective focus exclusively on the detection task, without discussing learning-based mitigations. Also, these generic surveys discuss only a share of existing DDoS categories, mostly involving a subset of volumetric, protocol or application attacks, but never all of them together. Malliga et al. ( Senthil et al., 2022 ) cover mainly protocol-based attacks consisting of a table of 66 research papers on the use of deep machine learning methods for DDoS detection and a table of 12 of the most popular datasets used in simulations. The article gives a good tabular description of the field, but does not detail the methods analyzed and does not discuss the methods of generating DDoS attacks. Volumetric attack detection and mitigation strategies are completely missing. Interested readers can continue with application-level attacks from the work of Tripathi et al. ( Tripathi and Hubballi, 2021 ) , who provide a thorough survey regarding exclusively these types of attacks and detection mechanisms, while also including existing turnkey solutions from the industry. Unfortunately, the authors tackle few existing learning-based detection techniques, most of which are shallow. Further on, Najafimehr et al. ( Najafimehr et al., 2023 ) present a detailed taxonomy of DDoS attack detection methods which includes the missing volumetric attack types. The survey is centered around pairings between general detection methods and existing databases with a bias towards shallow learning approaches. Detecting specific attacks is not treated as a separate topic nor the particularities of each task; the algorithms are expected to detect with high accuracy any type of DDoS attack present in the dataset.
It is worth mentioning that some of the DDoS attack surveys also include a small section dedicated to learning-based detection of these attacks. We mention here the work of Singh et al. ( Singh and Gupta, 2022 ) , which enumerates the list of machine and deep learning papers dealing with some protocol and application based attacks, and that of Nuiaa et al. ( Rahef Nuiaa et al., 2022 ) , which analyzes solely DDoS attacks against the DNS protocol focusing on distributed methods with reflection (and amplification) that includes a small discussion about using AI for the attack detection task.
2. System Architecture & Core Working Principles Moving on towards specialized surveys, we note that reflection, amplification, mitigation and attack generation techniques are not discussed in these works. The IoT domain is presented by Kadri et al. ( Kadri et al., 2024 ) , who discuss floods and TCP-based attacks analyzing detection and validation methods used in the literature. The paper talks little about the performance of these methods in simulations and practical applications. The work of Pakmehr et al. ( Pakmehr et al., 2024 ) picks-up on this and presents several tables with advantages and disadvantages for shallow and deep learning methods; these tables are not very well connected to the survey text or the particularities of the attacks exploited by the detection methods. The paper covers a wider area of attacks, including a brief mention of modern GAN-based learning strategies.
Nonetheless, techniques for generating AI-based DDoS attacks are not discussed. SDNs are a hot topic in the DDoS field, and indeed, we also find two attack detection surveys specializing on it. The work of Musa et al. ( Musa et al., 2024 ) tackles the detection task with an in-depth and wide coverage across the DDoS attack classes describing recent learning methods (both classical and deep) including Adversarial AI approaches. The article laments the simplistic scenarios discussed in the research articles and the need to test more complex scenarios that integrate with already existing security systems. While the authors provide a thorough review of the SDN literature on the topic, the survey does not provide insights and connections between the selected papers employing instead a list of abstracts approach.
The mitigation task is not covered here nor in other SDN surveys. Even though Su et al. ( Su et al., 2024 ) conduct a study of most mitigation methods for SDN DDoS attacks, learning methods are used solely in the detection process. These range from statistical to shallow and deep learning methods together with hybrid variants. While significant progress has been made in the field, there are still some major obstacles, especially regarding the quality of the datasets and the adaptability of the defense systems. Even though not DDoS-centric, Alatwi et al. ( Alatwi and Morisset, 2021 ) focus on three main issues: classifying studies from the existing literature that deal with generating adversarial examples, evaluating deep learning-based detection systems, and proposing defense mechanisms against such attacks. The authors state that approaches such as adversarial training, although effective in areas like computer vision, fail to perform as well in network IDS because of the complex structure of traffic characteristics. While making some interesting observations, the survey of Alatwi et al. ( Alatwi and Morisset, 2021 ) covers a narrow domain, adversarial learning, dealing with a generic problem, network intrusion detection.
Supported by the views in ( Alatwi and Morisset, 2021 ) , He et al. ( He et al., 2023 ) talk about the vulnerabilities and limitations of machine learning-based methods in network IDS in the context of adversarial attacks. As noted by previous research, these systems are vulnerable to attacks that manipulate network traffic to avoid detection. Still, He et al. ( He et al., 2023 ) argue that many of these attacks lack adaptability to the data structure of the network. They conclude that the literature still needs more representative and diverse datasets, along with more robust defense mechanisms such as adversarial training and feature reduction strategies. The survey of He et al. ( He et al., 2023 ) is focused on a specific area related to adversarial attack generation.
We start by introducing a set of clear definitions for the DDoS attack categories that are meant to easily and unambiguously separate existing attack types. Next, we provide a manual hierarchical grouping (taxonomy) of existing research on AI-based DDoS detection methods, together with an automatic clustering-based taxonomy, and compare the two. In Figure 1 , we provide an overview of the four general categories of DDoS attacks, which we describe individually next.
The most common attacks in real-world are volumetric DDoS attacks, in which an attacker coordinates bot networks to send a large number of UDP packets to a target victim. This increased traffic affects network and compute infrastructures, which now have to appropriately handle the increased fake traffic in detriment of traffic from legitimate users. Next, protocol DDoS attacks exploit weaknesses in protocols themselves (mostly network layer protocols, such as TCP/IP/ICMP) and their software implementations and usually target the compute infrastructure of the victim operating system. This leads to an increase in the consumption of hardware resources to the point where the service becomes unable to handle legitimate requests.
Many of the attacks described in the volumetric and protocol categories can be further enhanced by reflection/amplification DDoS techniques. In this case, the attacker uses a bot network to take advantage of the connectionless nature of UDP to send requests with a spoofed IP address to multiple legitimate UDP-based services. The responses from these so-called reflectors, which are usually also amplified by a certain factor, overwhelm the target victim, further exacerbating the disruption of both network and compute capabilities.
Finally, application DDoS attacks target specific higher-level network services, including HTTP, web applications, and database management systems. In this scenario, an attacker sends a large number of well-crafted malicious requests to a network application that cannot properly handle the requests. This leads to increased consumption of hardware resources that ultimately make the application nonresponsive or outright crash the application, and thus denying the services to legitimate users. In this scenario, the network infrastructure is mostly unaffected and the main target is the victim application stack on top of the operating system.
In Table 3 , we provide a list of the most common DDoS attacks, grouped into each of the four main attack categories, together with a brief description and highlighting the main attack target: network infrastructure and/or computational resources. A hierarchical grouping of the surveyed articles according to their main innovative contribution. There are five major groups: "Detection Algorithm", "Data and Preprocessing", "Other Optimizations", "System Design and Evaluation" and "Adversarial Training", each one with several subgroups. Each subgroup contains a clickable list of the articles.
In an attempt to help the reader quickly navigate the state-of-the-art landscape and identify key affinities, we group the research papers according to their main innovative contribution, e.g., whether they focus on a particular detection algorithm, a new data preprocessing method, or building and evaluating a full DDoS mitigation system, etc. The resulting classification is presented in Figure 2 , and contains five major groups. We acknowledge that research articles differ widely in breadth, scope, and innovative content, and it is sometimes difficult to assign them to a single category. The grouping simply means that we judged that particular aspect of the article as the most relevant in the overall context of the literature, which may help the reader grasp the main directions.
As illustrated in Figure 2 , the largest group focuses on the actual algorithm for detecting DDoS attacks. The majority of the proposed approaches rely on deep neural networks, the autoencoder being a particularly popular architecture, thanks to its ability to detect deviations and abnormal patterns. However, several other custom architectures have been proposed, e.g., using bidirectional GRU layers with self-attention ( Guo and Gao, 2022 ) . Of particular interest is study of Anley et al. ( Anley et al., 2024 ) , which also investigates how well the detection results transfer to other datasets than the ones used for training.
Besides neural networks, various other algorithms are investigated, including classic supervised solutions (e.g., RFs), graph-based kernels ( Liu et al., 2021 ) , various modelings of traffic patterns, and even bio-inspired heuristic classification algorithms. The second group contains papers with novelties related to data and preprocessing, ahead of the actual classification stage.
A typical example of these custom methods is the approach of Wei et al. ( Wei et al., 2023 ) , which uses LSTM coupled with an autoencoder to extract time-varying features of the data, identifying anomalies using the autoencoder reconstruction error. Another example is the method of Das et al. ( Das et al., 2022 ) , which restricts the data used in the detection process only to port statistics, without any flow-related data, unlike the vast majority of related approaches.
Several articles, grouped under the “Other Optimizations” label, focus on collateral optimizations which may be highly relevant for the efficiency of DDoS solutions in practice. Thus, Dimolianis et al. ( Dimolianis et al., 2021 ) and Zhao et al. ( Zhao et al., 2024 ) consider the problem of consolidating attack signatures or mitigation rules, to detect and block several types of attacks simultaneously, with few rules. This also increases the robustness against new, unseen variants of the attacks. An adaptive federated learning approach is proposed in ( Doriguzzi-Corin and Siracusa, 2024 ) , facilitating cooperation between entities while avoiding the risk of exposing sensitive information.
The “System Design and Evaluation” group contains papers that, without focusing on a single particular aspect, are relevant to evaluations of DDoS detection pipelines. We differentiate here between articles focusing only on the detection, e.g. ( Khashab et al., 2021 ) , and articles that also consider the mitigation process, e.g. ( Park et al., 2021 ) . 3. Software Implementation, Frameworks & Protocols The last group gathers articles involving adversarial data and training, as a way of increasing the robustness of anti-DDoS solutions. Since these articles typically use specific algorithms, rarely encountered in other articles (e.g., GAN architectures), we group all of them into a separate category. We further subgroup the articles according to whether they focus primarily on the actual data generation or the adversarial training process, with a separate note for the study of Zhang et al. ( Zhang et al., 2020 ) , who investigate strategies against adversarial attacks (e.g., ensemble voting).
Dendrogram with Data Points on the y-axis and distance from 2.25 to 0.00 on the x-axis with 0.00 in the right-hand corner. The y-axis on the right contains the clustered papers. The main clusters are "Adversarial Training, SDN", "Amplification, NTP", "SYN Flood", "AE", "Detection", "HTTP Flood", "Adversarial Training", "IDS", "DNS Flood". The dendrogram presented in Figure 3 is generated by applying an agglomerative clustering algorithm based on Ward’s linkage over the TF-IDF representation of article titles and abstracts.
The TF-IDF representation is an extension of the simple bag-of-words model, which combines two components: term frequency (TF) and inverse document frequency (IDF). TF measures how often a word appears in a document, while IDF demotes common words by assigning lower importance to terms that appear in many documents. The result is a weighted vector representation that emphasizes unique and meaningful words for distinguishing documents.
Agglomerative clustering based on Ward’s linkage is a hierarchical clustering algorithm that groups data points by iteratively merging clusters to minimize the total within-cluster variance. It starts with each TF-IDF vector as its own cluster and merges pairs of clusters, step by step. Ward’s method chooses the pair of clusters to merge based on the smallest increase in variance within all clusters: where C i C_{i} and C j C_{j} are two clusters, and the variance of a cluster is computed as follows: where x x is a TF-IDF vector representing one of the surveyed articles, µ C i \mu_{C_{i}} is the mean vector of cluster C i C_{i} , and ∆ l 2 \Delta_{l_{2}} is the ED. Formally, the optimization criterion used to select the pair of clusters to be merged is defined as: This approach ensures that the resulting clusters are as compact and similar as possible, making it particularly effective for detecting spherical or evenly distributed clusters.
We manually labeled the resulting clusters after automatically obtaining the taxonomy, by investigating the grouped papers and finding the commonality from the point of view of a human expert. Next, we briefly walk from the outer clusters towards the inward labeled clusters and provide a few comments. We found that the first level splits between DNS, HTTP, and SYN flood attacks and also creates a clear split between Adversarial Training in normal and SDN contexts. Another fine line was the separation between Detection, a large cluster, and IDS focused research, a niche topic. Going deeper inside the Detection cluster, we find clusters separating shallow and deep learning, and also a cluster that grouped attack detection and attack classification papers. There is another shallow learning cluster within DNS Floods that was accurately separated from the general detection cluster. In the final clustering level, the manual labels provide a specialized view of the resulting dendrogram. For example, we have DNS Flood cache-based mitigation papers and adversarial training in SDNs employing active learning techniques.
It is interesting to compare these clustering results with the manually defined groups in Figure 2 , in an attempt to discover common traits. A major similarity is that the “Detection” cluster in Figure 3 is almost completely included in the “Detection Algorithm” group in Figure 2 , suggesting a clear and well-defined focus on detection methods. In addition, the two clusters of “Adversarial Training” in Figure 3 overlap greatly with that in Figure 2 , which is to be expected given the specific algorithms and keywords used in this approach. Some other small similarities are visible as well, for specific niches, as in “timeseries forecasting/prediction”.
Beyond these similarities, there are few shared insights. The main reason is that the criteria discovered in the automatic clustering process are diverse, including specific targeted protocols (HTTP, ICMP, DNS, SYN floods), generic approaches (Detection, Classification, Clustering), or network environments (e.g., IoT, SDN). On the contrary, in Figure 2 , there is a single generic criterion considered, namely the technical approach proposed in each article. It is therefore natural that they lead to fairly different hierarchies. This, however, is not detrimental; it only helps the reader to obtain a more nuanced understanding of the surveyed literature.
We next discuss the various forms DDoS training data can take before being processed by learning algorithms. Most IDS analyze the traffic at various network layers. The first step in data processing covers the capture and storage of network traffic data. This step is essential for reaching high DDoS detection quality. Existing public databases are gathered in Table 4 . We can see that, except for KDD, all data are presented in the raw packet ( pcap ) format. Apart from CIC-DDoS2019, these datasets do not focus on DDoS attacks and instead include other types of attacks, besides normal traffic. Among DDoS traffic, flood attacks seem to be the most common, while TCP and HTTP come in second; each of these belong to the volumetric, protocol, and application attack classes, respectively. We also include, for brevity, the TUIDS database, which is not currently available to the public, although it was in the past and is often discussed in literature. Apart from raw traffic, some databases also provide preprocessed data in the form of flows or timeseries. We add this information in the table where available, and proceed to discuss these and other preprocessing formats.
In the network traffic structure, a packet is a data unit composed of header fields and the proper message ( payload ) to be transferred. Each field from the the headers stack, that belongs to a different TCP/IP layer, is necessary for the proper management and routing of the packet toward the destination. Capturing tools such as tcpdump are often used to monitor and store packet-level information of the network. When a capturing tool stores and inspects the traffic among multiple machines, the complexity of packet analysis is highly dependent on the number of monitored devices and on the common growing networking speeds. Additionally, the detection of real collective attacks (such as DDoS) usually requires a periodic inspection of very large low-level packet sets. For this reason, collection, inspection and management of low-level packet traffic remains a challenge for this format. Therefore, grouping packets into sets that have some shared characteristics becomes a natural idea.
A flow represents a packet collection related through a common set of attributes. The attributes include header fields corresponding to transport and application layers (IP addresses, IP protocol, source ports, etc.), as well as various information related to local packet management (e.g. input-output physical port). Despite the wide interval of attributes, collection and computation of flow records is an increasingly common capability of usual network devices. The flow records computed on the export device are transferred towards a collector that stores them. Each record has basic flow information and other fields: timestamp for flow start and stop, byte length over the packets in the flow, etc. This way, the flow format will eventually be much more compact than the packet data format.
Regardless of the primary traffic format, three dominant data models allow the diversity of anomaly detection techniques to be applied for detecting network intrusions: tabular, timeseries, and graph models. Identifying important traffic attributes over each flow (or packets group) is a widely adopted preprocessing step that converts raw flow data into a new tabular dataset. After this conversion, many authors proceed to apply particular outlier detection techniques and provide specific interpretations of the results. Some common traffic attributes, retained from the raw traffic, are promoted by many papers to facilitate the prevention of multiple DDoS attacks. Thus, we further exemplify some of the most common features (that we found in the surveyed papers) organized over the class of DDoS attacks they address: 4. Practical Deployment, Analysis & Case Studies Volumetric: source IP, destination IP, source port, protocol, source packet, destination packet, packet number (identifier), total number of bytes transferred, ToS values, duration of established connections, statistics from counting source MAC and IP address combinations, channel and socket properties.
Protocol: source IP, source and destination IP combinations, IP identifier and fragmentation properties (DF field), TTL values, source and destination TCP port combinations, window size for TCP packets, maximum/minimum packet length, average packet size, maximum/minimum packet forward length. Application: incoming IP addresses, TCP source/destination port numbers, maximum number of sessions, web page access count, number of HTTP request packets per unit time.
By taking into account the timestamp of each flow, a temporal order can be established over the network traffic and the raw data takes the form of a timeseries . With a relevant encoding of the attributes, the DDoS attack detection problem becomes a timeseries analysis problem. Among the main flow attributes that prove to be worth tracking over time are: new flow record creations per second, average flow duration, average number of bytes per flow, average number of packets per flow ( Hofstede et al., 2013 ) ; DNS query rate ( Verma et al., 2016 ) ; statistics based on counting MAC and IP addresses combinations ( Mirsky et al., 2018 ) ; number of packets, entropy of IP addresses and ports list ( Lent et al., 2024 ) ; number of received packets, received bytes, number of sent packets, sent bytes, port keep alive duration, drop rate for received packets, number of errors for received and transmit packets, etc. ( Das et al., 2022 ) .
The analysis of inherent relations between the flow attributes naturally leads to the third data model based on graphs . In general, DDoS attacks are prominently reflected/amplified in particular subgraph patterns where a single node has a high input degree compared with its neighborhood. Even a simple feature table of the flows, that includes a timestamp, source and destination IPs for each flow, can be easily converted into a basic static graph structure where the nodes are the IP addresses and the links are the connections within the network (see Figure 4 ).
We next delve into a detailed literature review of state-of-the-art AI-powered detection methods and solutions against DDoS attacks. Based on their specifics, we group attacks into volumetric, protocol-based, reflection and amplification, and application (Layer 7) attacks. We also summarize the reported detection time of the proposed methods from the papers that include this information.
Volumetric attacks are conectionless floods in which an attacker uses networks of bots to send a large number of, usually, UDP packets towards an intended victim, disrupting mainly their network infrastructure, but potentially also their network stacks. In the vast majority of cases, volumetric attacks are treated in a unified manner, just as the other DDoS attacks. This is because well-established datasets, such as CIC-DDoS2019 ( Sharafaldin et al., 2019 ) , have recorded traffic from various types of DDoS attacks. As stated in ( Cil et al., 2021 ) , given the CIC-DDoS2019 dataset, there are two main approaches: (1) detect that a DDoS attack is happening and (2) establish which kind of DDoS attack it is. In general, when discussing synthetic datasets, such as CIC-DDoS2019, the results published in the literature are excellent, exceeding 99% precision 2 2 2 All other metrics, such as accuracy, recall or F1 have similarly high values over 99%. for detecting DDoS attacks using only relatively simple AI algorithms. Most probably, these almost perfect results stem from the synthetic nature of the employed datasets, since these were generated in synthetic lab conditions, not real-world situations.
Most research papers obtain similar near-perfect accuracy results. For example, Wei et al. ( Wei et al., 2021 ) use a mixed architecture composed of an autoencoder and a multi-layered perceptron. In this case, the autoencoder performs dimensionality reduction, while the perceptron performs the actual classification task. A few-shot model is one that aims to recognize attacks after only seeing very few examples during training. If there are no training examples at all, the model is called zero-shot. This scenario is very useful in the real world because new types of attacks (or variations of the existing ones) appear all the time. Because of that, an important characteristic of an AI model is its ability to detect and respond to new types of attacks. For instance, Shieh et al. ( Shieh et al., 2021 ) propose a human-in-the-loop, semi-supervised solution. New types of attacks are detected in a zero-shot manner. The relevant data samples are sent for validation and manual classification to a human operator. If what is detected is indeed a new type of attack, the information is added to the system, such that, in the future, the AI system will be able to automatically perform the correct classification for this type of attack. The implementation is based on a combination of deep learning, BiLSTM, and GMM techniques.
In most solutions, traffic is modeled using network flow models, making explicit use of the structure of the network. For example, in ( Liu et al., 2021 ) , the traffic is modeled through a time-varying network graph model. The regular network traffic is modeled as a fixed set of normalized graphs. An extra element of novelty is that, to measure the divergence from the regular traffic, the authors use a Weisfeiler-Lehman kernel. Compared with previous solutions, the proposed AI system performs better in real-time scenarios and for the classification of various DDoS attacks. In another graph-based approach ( Abu Bakar et al., 2024 ) , a two-stage aggregation technique is proposed, resulting in the construction of graph models for the packet-level and the flow-level traffic. The authors analyze this traffic using CNNs, and obtain state-of-the-art results (especially in terms of the F1 score). The accuracy of the model is proportional to the past traffic window size, a parameter that is important in establishing the topology of the traffic information, but whose increase leads to significantly larger inference times.
Detection of DDoS attacks plays a crucial role in many practical situations. For example, smart camera surveillance systems are critical because disabling them via a DDoS attack allows an on-the-ground operation to proceed undetected. Hence, the network robustness of such systems is essential. The DDoS robustness of surveillance systems is analyzed in the study of Mirsky et al. ( Mirsky et al., 2018 ) , which is based on a set of serially connected autoencoders. Their role is to encode the traffic characteristics and prepare them for anomaly detection methods. For training, the authors use custom datasets encapsulating a set of relevant cyberattacks including recon, man-in-the-middle, and DDoS (SYN flood, SSDP flood, and SSL renegotiation). The proposed solution is highly applicable and focuses on many practical considerations.
Protocol-based DDoS attacks generally exploit specific characteristics of network protocols or their software implementation (e.g., TCP, ICMP). In general, the main target of these attacks is the victim’s network stack, but the network hardware infrastructure might also be significantly affected. Among the earliest work in protocol based DDoS detection using ML techniques includes the detection of SIP flood attacks over VoIP networks. First, the work in ( Nassar et al., 2008 ) uses an SVM approach and 38 features grouped into four categories to detect telephony flooding and spam attacks. The features are constructed from time-sliced statistics of the signaling messages usually used in SIP for VoIP (especially INVITE messages). Then, the work in ( Akbar and Farooq, 2014 ) uses ML techniques such as NB and DT on a dataset composed of both spatial and temporal engineered features extracted from raw network packets. In this setting, temporal features are variations in the number of INVITE, ACK, and BYE messages captured in traffic while spatial features are computed by the entropy of caller IDs in a time window. The results reported in both papers are above 90% in terms of detection accuracy.
As mentioned in previous sections, many solutions in the scientific literature jointly handle many DDoS attacks, developing general detection and protection methods working with multiple attacks. This is also reflected in the databases used for training and validation ( Sharafaldin et al., 2018 ; Sharafaldin et al., 2019 ) . More precisely, even if individual attacks differ, technically depending on the specifics of the protocol exploited, the types of extracted features and the used detection methods are usually generic, and can be applied to a wide range of attacks. For example, in ( Zhao et al., 2024 ) , the datasets used for evaluation contain 89 different variations of DDoS attacks. Even though some works explicitly refer only to certain types of attacks, usually TCP or TCP-SYN floods ( Dimolianis et al., 2021 ; Guo and Gao, 2022 ; Das et al., 2022 ) , this is largely due to the test environment and the datasets used for evaluation, and not to the methods themselves being specialized for certain types of attacks. In contrast, specializing on certain types of attacks can be inherently problematic, since several types of attacks are not represented well enough in the current databases to be properly modeled and analyzed ( Das et al., 2022 ) .
Most of the works analyzed in this section start from features extracted from flows, such as the number of packets, number of bytes, and duration ( Khashab et al., 2021 ) , together with identification elements (source address, source port, destination address, destination port, and protocol). The values are taken at periodic intervals to monitor their evolution in time. Several works mention the particular relevance of these differential parameters: Khashab et al. ( Khashab et al., 2021 ) use the number of flows to the same host and the same port, respectively, from the last 5 seconds; Das et al. ( Das et al., 2022 ) take the differences between the number of packets and bytes at successive intervals of 5 seconds; Zhao et al. ( Zhao et al., 2024 ) use a set of 5 sliding time windows, ranging from 0.1 0.1 to 10 10 seconds. The papers above use manually defined features, but other approaches use automatic methods for extracting relevant features, such as those based on autoencoders ( Ko et al., 2020 ) , feed-forward networks ( Liang et al., 2021 ) or attention mechanisms ( Guo and Gao, 2022 ) .
A special case is the work of Das et al. ( Das et al., 2022 ) , which uses only parameters collected from the ports in the network infrastructure, without considering features extracted from flows. This is considered an advantage, as flow-level statistics are dependent on the network topology, and the associated traffic, which could impact the generalization of the results ( Das et al., 2022 ) . In this case, once an attack is detected, the origin of the attack is identified through a localization process, which analyzes traffic on all ports and identifies the switches most affected, considered to be the closest to the source of the attack.
5. Performance Evaluation & Extended Technical Observations The methods used for detection are varied, but most of them are based on supervised learning algorithms: SVM, RF, DT, neural networks with MLP or CNN architectures ( Das et al., 2022 ; Daoud et al., 2023 ; Khashab et al., 2021 ; Zhao et al., 2024 ) . Along the same lines, the work in ( Tripathi and Hubballi, 2018 ) uses a simple OC-SVM classifier to detect particular types of DHCP starvation attacks. The approach is rather simple and uses four features extracted from DHCP traffic: the number of DISCOVER, REQUEST, and DECLINE DHCP messages and the total number of ARP messages in a fixed time quanta. These statistics are enough to reach near-perfect detection accuracy. The majority of works use and compare several types of classifiers, with sometimes extremely different results, without a consensus on the best method (for example, Das et al. ( Das et al., 2022 ) report an accuracy of 51% with MLP networks). An exception to this is the articles in which the classification method is linked with the feature extraction method, such as ( Ko et al., 2020 ) , which uses autoencoders for feature extraction simultaneously with classification. Most classification methods are traditional feature-based approaches, in different flavors. An exception is the approach of Guo et al. ( Guo and Gao, 2022 ) , which uses bidirectional GRU models, coupled with a hierarchical attention mechanism.
Many of the works that use supervised methods report detection accuracy values of over 99%, often over 99.9%, for example ( Dimolianis et al., 2021 ; Zhao et al., 2024 ; Das et al., 2022 ; Doriguzzi-Corin et al., 2020 ; Guo and Gao, 2022 ) . It is not clear to what extent these performance levels transfer to real test environments, or are just a consequence of using the limited set of publicly available databases, or of using certain software tools for simulating attacks in tests. However, we note that many works mention evaluating the results on real, private datasets recorded from ISPs ( Zhao et al., 2024 ; Dimolianis et al., 2021 ) , which increases the level of confidence in the proposed solutions.
The concept of “DDoS attack family” is proposed in ( Zhao et al., 2024 ) , aggregating attacks that allow similar defense strategies. This is done by evaluating the differences between signatures of different attacks, representing the relationships between them as graphs, followed by partitioning them into sub-communities with specific algorithms. The approach also allows for adaptation to new types of attacks, not encountered in the design phase. The analysis of the authors shows that 89 types of attacks can be grouped into just four families, namely: i) attacks to network Layer 4 or higher; ii) TCP attacks without a response from the victim; iii) TCP attacks with a response from the victim, and; iv) connectionless attacks. As proof of the efficiency of this solution, to counter all attacks in category iii), only two rules are needed, which are based on counting RST packets and packets having both fields SYN and ACK set.
The possibility of adapting to new types of attacks is also addressed in the work of Doriguzzi-Corin et al. ( Doriguzzi-Corin and Siracusa, 2024 ) , who investigate a federated learning approach to incorporate data and models from multiple clients, while avoiding data centralization. In ( Liang et al., 2021 ) , a semi-supervised learning method is introduced, which is appropriate in situations where attacks are poorly labeled or even unknown. The method is based on clustering the data and then projecting it into a reduced space, aiming to preserve the cluster membership for data with available labels.
As mentioned above, even though most methods do not specialize on a specific attack, some do specialize. In the following, we address these specialized methods. For TCP Connection/SYN Flood, in addition to the articles presented in the previous section, those using the CIC-DDoS2019 dataset ( Sharafaldin et al., 2019 ) implicitly address SYN Flood. Thus, the works of Salahuddin et al. ( Salahuddin et al., 2021 ) , Wei et al. ( Wei et al., 2021 ) , and Shieh et al. ( Shieh et al., 2021 ) , described in Section 5.1 , are relevant to the subject. PoD attacks are characterized by packets having, after reassembly, a size greater than the maximum size of 65535 allowed by the protocol. This attack is explicitly addressed in ( Abdollahi and Fathi, 2020 ) , which detects it using a threshold for the number of packets in a time window with a size greater than a certain limit. Next, the BGP attack exploits the vulnerabilities of the BGP protocol, and is based on sending malicious routing updates. In ( McGlynn et al., 2019 ) , these attacks are detected using two autoencoders to extract the essential features from the AS-specific information. Finally, Smurf DDoS attacks involve spoofing the source IP addresses of ICMP packets sent to broadcast addresses, which causes a large number of responses to be sent to the devices holding the spoofed IP addresses.
Nowadays, this type of attack is simply avoided by disabling the broadcasting option on network devices. For this reason, there are few works addressing this attack in the literature, and most of them use relatively simple approaches, such as ( Bouyeddou et al., 2018 ) , which harnesses the Kullback-Leibler divergence to identify anomalies. Instead, when it comes to the ICMP protocol, interest in Ping Floods have resurfaced recently in the context of IoT networks ( Almorabea et al., 2023 ) .
RA-DDoS attacks enhance the previously described volumetric and protocol DDoS attacks. Historically, reflection and amplification attacks represented a subset of the broad class of volumetric attacks and are characterized by an attacker who can selectively use a relatively small amount of traffic employing bots, vulnerable protocols and services to generate a considerable amount of traffic toward an intended victim. These types of attacks usually target services such as DNS and NTP, as well as both standard transport protocols: mostly UDP, but also TCP. An attacker could just reflect traffic toward a victim, but by far, the most dangerous attacks are those where the attack volume is amplified manyfold. Although RA-DDoS attacks were initially based exclusively on UDP, subsequent advances ( Kührer et al., 2014b ; Bock et al., 2021 ) showed how TCP can also be used to reflect and amplify malicious traffic. Due to these characteristics, reflection and amplification attacks are sometimes treated separately in the DDoS volumetric attack literature ( Mirkovic and Reiher, 2004 ) .
Most classic techniques used to detect and mitigate RA-DDoS attacks rely on changing the network’s configuration parameters or the targeted services. This mitigation technique bears the name System and Network Hardening ( Rossow, 2014 ; Kührer et al., 2014a ; Kührer et al., 2014b ; Bock et al., 2021 ) . Anticipating AI-based techniques, a particular line of work ( Verma et al., 2016 ; Quadir et al., 2020 ; Wagner et al., 2021 ) follows the idea of collecting simple statistics about network traffic to detect and then suggest mechanisms to stop RA-DDoS attacks.
Among the first papers to use AI techniques to detect RA-DDoS attacks, we mention here works ( Meitei et al., 2016 ; Chen et al., 2017 ) that use several machine learning techniques such as DT, MLP, NB, and SVM to detect DNS RA-DDoS attacks. In the following decade, Anley et al. ( Anley et al., 2024 ) turned to modern AI techniques, such as deep CNNs together with transfer learning, to enhance the generalization capabilities of AI models by combining data from multiple freely available DDoS datasets. The recent literature views the problem of generating realistic RA-DDoS attacks as a central one in the development of reliable detection methods. For this reason, the work of Mathews et al. ( Mathews et al., 2022 ) proposes a robust RA-DDoS method that uses neural networks and adversarial learning techniques, such as EAD and TextAttack, to generate counterexamples for the AI model, which will not be correctly labeled as attacks. Such enhancements lead to better generalization in practical datasets. In the same spirit, a method that uses a GAN-based discriminator for anomaly detection is proposed in ( Lent et al., 2024 ) . This uses GRU-type neurons, analyzing traffic as a time series. Features such as the number of transmitted packets, the number of bits and entropy of IP addresses and ports are extracted for each one-second time window, and are aggregated into overlapping 10-second time series for analysis. The generator network learns to synthesize normal traffic flows with features very similar to those from the training set, while the discriminator improves the anomaly detection capability. In addition to the detection module, the authors also design a mitigation module that identifies a victim as the IP address that receives the largest number of flows in a time window detected as an anomaly, and subsequently blocks the IP addresses that send traffic towards it.
Regarding the features used in the detection process, several approaches are possible. One of them involves selecting a subset of features through different methods, as in ( Shurman et al., 2020 ; Wei et al., 2023 ) . Another option, found in ( Lyu et al., 2021 ; Lent et al., 2024 ) , is to build new features from a time window containing a variable number of packets or flows. The former option allows for inference as soon as the information about a flow is stored in the database, whereas the latter requires building new features only after all the flows corresponding to a time window are available and stored. Amaizu et al. ( Amaizu et al., 2021 ) use the Pearson correlation coefficient for feature selection and then jointly train two neural networks with different architectures to predict the type of attack for the flows in the CIC-DDoS2019 dataset. The attack classes are not limited to RA-DDoS types, as they also include general volumetric attacks.
As with other types of attacks, RA-DDoS attacks are usually addressed collectively in the scientific literature. A notable exception is the work of Lyu et al. ( Lyu et al., 2021 ) , who develop detection methods for RA-DDoS attacks based on the DNS protocol. They propose a hierarchical graph structure with a dynamic retention policy to model traffic at three different levels: host, subnet, and AS. Then, two different methodologies are used to detect traffic anomalies at each level. The first method uses static detection rules for each scenario, while the second uses IF and OC-SVM models to detect anomalies based on the following time-windowed features: variance of packet size, number of internal hosts queried by each external entity, average number of packets sent in queries to each internal host, and variance of the number of packets sent in queries to them. The authors further used two of these features to separate anomalous hosts in scanners and flooders.
Because of the time-dependent nature of monitoring network traffic quantities, recurrent neural structures have been used with great success for RA-DDoS detection. Shurman et al. ( Shurman et al., 2020 ) proposed two approaches to detect RA-DDoS attacks. The first one is a simple framework consisting of a database with known attack signatures and an anomaly-based detector. Here, the signature database is updated when a packet whose characteristics deviate from the normal ones is analyzed by the anomaly-based detector. The second approach uses LSTM-based networks with varying number of LSTM layers to detect RA-DDoS attacks from the CIC-DDoS2019 dataset. An RF classifier is used together with the GINI impurity to select a subset of features for training the LSTM-based model. Another LSTM-based architecture is proposed in ( Wei et al., 2023 ) to detect RA-DDoS attacks as time series anomalies within a time window containing a configurable number of data flows. The training process uses a subset of the features from legitimate data flows, and then a threshold on the reconstruction errors obtained by the LSTM autoencoder is derived. The proposed architecture contains an encoder, in which the output of each LSTM cell component is ignored, followed by a decoder, where the outputs of the component cells represent the reconstructions of the input data. The authors reported separate results for RA-DDoS attacks based on DNS, LDAP and SNMP. A similar LSTM autoencoder is used in ( Said Elsayed et al., 2020 ) , but here, latent representations are used to train an OC-SVM model, because the simple threshold-based approach did not achieve satisfactory performance. In both papers, only instances labeled as normal are used in the training process. While the work of Wei et al. ( Wei et al., 2023 ) was used to detect three types of RA-DDoS attacks, Said et al. ( Said Elsayed et al., 2020 ) presented a model trained to detect several types of attacks, including DDoS.
A recent survey ( Ismail et al., 2021 ) focuses particularly on RA-DDoS attacks, and yet another one ( Wabi et al., 2024 ) showcases the recent work in studying RA-DDoS attacks in the context of SDNs. We provide an overview of the current state of research as well as some possible future research directions concerning application-level DDoS attacks. Alongside the information present in the surveys section and the works concerned with Layer 7 Application attacks, we can distinguish three broad types of attacks, each of them having multiple subtypes. More precisely, we discuss detecting HTTP attacks, especially flooding attacks, followed by detecting slow HTTP attacks (Slowloris and R.U.D.Y.). Lastly, we discuss hierarchical DNS server attacks.
As compared with previous DDoS attacks, application layer DDoS usually targets the operating system, software stack and hardware compute resources of the target victim machines. The network infrastructure is under some strain, but it is usually not the main target of the attack. In many application layer DDoS attacks, the issue is not necessarily the large number of packets transferred, but the compute burden due to the malicious content of the messages and how these are interpreted and processed by the victim’s software.
HTTP flood attacks refer to the scenario where an attacker uses malicious HTTP requests to target an HTTP server with the goal of making it unresponsive to legitimate traffic. Because the HTTP requests involved in this class of attacks are perfectly normal requests, those attacks are difficult to tell apart from the legitimate user traffic. Wang et al. ( Wang et al., 2014 ) propose a method to classify HTTP flood attacks into two types: random and perfect knowledge. In perfect knowledge ones, the attackers know the structure of the website and attempt to mimic the behavior of a legitimate user. For the random ones, this assumption does not apply. This difference is important for the proposed solution, because it uses the learned distribution of the requests to identify the legit users. The solution, named HTTP-SoLDiER, is based on the correspondence between the individual clicks generated by users with the general distribution of the users of the site. Based on deviation theory, the solution can differentiate legitimate users from attackers by computing the probability of navigation, with respect to general interest and popularity. The critical point of the paper is the fact that, because the content of the pages and the structure of the site can change, the probability must be dynamically adjusted. To prevent the corruption of statistics during an attack, the authors propose a correction algorithm. This algorithm, called EWMA, estimates the popularity of pages in real-time, based on current state and historical data, thereby reducing the bias introduced by the attack itself. A noteworthy observation, also mentioned in previous literature, is that the general distribution of page popularity follows a Zipf law ( Piantadosi, 2014 ) . Because the complexity of their proposed solution is computationally O I ( M ) O(M) , where M M is the number of pages, the computation requirements are not significant. Alongside the correction algorithm, the success rate in detecting malicious traffic is 99% for random HTTP floods and 77. 9% for perfect-knowledge attacks. The downside of this solution is that some websites only have a single page/URL and the so-called circular perfect-knowledge attacks, where the attackers mimic the behavior of a legitimate user by rotating several pages, are significantly harder to detect.
Harvested Online Documentation & Reference Sources • https://arxiv.org/html/2503.17867v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Application Layer DDoS Attack Detection Using Deep Learning.
[*] Metasploit Scan Running on Target Subnet for Application Layer DDoS Attack Detection Using Deep Learning... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |