Complete Technical Paper Content — Automated Cyber Insurance Risk Calculation Tool
Overview & System Context
Automated Cyber Insurance Risk Calculation Tool: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9193 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Life insurance (or life assurance, especially in the Commonwealth of Nations) is a contract between an insurance policy holder and an insurer or assurer, where the insurer promises to pay a designated beneficiary a sum of money upon the death of an insured person. Depending on the contract, other events such as physical complications or illness can also trigger payment.
The policyholder typically pays a premium, either regularly or as one lump sum. The benefits may include other expenses, such as funeral expenses. Life policies are legal contracts and the terms of each contract describe the limitations of the insured events. Often, specific exclusions written into the contract limit the liability of the insurer; common examples include claims relating to suicide, fraud, war, riot, and civil commotion. Difficulties may arise where an event is not clearly defined, for example, the insured knowingly incurred a risk by consenting to an experimental medical procedure or by taking medication resulting in injury or death. Modern life insurance bears some similarity to the asset-management industry, and life insurers have diversified their product offerings into retirement products such as annuities. Life-based contracts tend to fall into two major categories: Protection policies: designed to provide a benefit, typically a lump-sum payment, in the event of a specified occurrence. A common form of a protection-policy design is term insurance. Investment policies: the main objective of these policies is to facilitate the growth of capital by regular or single premiums. Common forms (in the United States) are whole life, universal life, and variable life policies.
An early form of life insurance dates to Ancient Rome; "burial clubs" covered the cost of members' funeral expenses and assisted survivors financially. In 1816, an archeological excavation in Minya, Egypt (under an Eyalet of the Ottoman Empire) produced a Nerva–Antonine dynasty-era tablet from the ruins of the Temple of Antinous in Antinoöpolis, Aegyptus that prescribed the rules and membership dues of a burial society collegium established in Lanuvium, Italia in approximately 133 AD during the reign of Hadrian (117–138) of the Roman Empire. In 1851, future U.S. Supreme Court Associate Justice Joseph P. Bradley (1870–1892), once employed as an actuary for the Mutual Benefit Life Insurance Company, submitted an article to the Journal of the Institute of Actuaries detailing an historical account of a Severan dynasty-era life table compiled by the Roman jurist Ulpian in approximately 220 AD during the reign of Elagabalus (218–222) that was included in the Digesta seu Pandectae (533) codification ordered by Justinian I (527–565) of the Eastern Roman Empire. The earliest known life insurance policy was made in Royal Exchange, London on 18 June 1583. A Richard Martin insured a William Gybbons, paying thirteen merchants 30 pounds for 400 if the insured dies within one year. The first company to offer life insurance in modern times was the Amicable Society for a Perpetual Assurance Office, founded in London in 1706 by William Talbot and Sir Thomas Allen. Each member made an annual payment per share on one to three shares with consideration to age of the members being twelve to fifty-five. At the end of the year a portion of the "amicable contribution" was divided among the wives and children of deceased members, in proportion to the number of shares the heirs owned. The Amicable Society started with 2000 members. The first life table was written by Edmund Halley in 1693, but it was only in the 1750s that the necessary mathematical and statistical tools were in place for the development of modern life insurance. James Dodson, a mathematician and actuary, tried to establish a new company aimed at correctly offsetting the risks of long-term life assurance policies, after being refused admission to the Amicable Life Assurance Society because of his advanced age. He was unsuccessful in his attempts at procuring a charter from the government. His disciple, Edward Rowe Mores, was able to establish the Society for Equitable Assurances on Lives and Survivorship in 1762. It was the world's first mutual insurer and it pioneered age based premiums based on mortality rate laying "the framework for scientific insurance practice and development" and "the basis of modern life assurance upon which all life assurance schemes were subsequently based".
Mores also gave the name actuary to the chief official—the earliest known reference to the position as a business concern. The first modern actuary was William Morgan, who served from 1775 to 1830. In 1776 the Society carried out the first actuarial valuation of liabilities and subsequently distributed the first reversionary bonus (1781) and interim bonus (1809) among its members. It also used regular valuations to balance competing interests. The Society sought to treat its members equitably and the Directors tried to ensure that policyholders received a fair return on their investments. Premiums were regulated according to age, and anybody could be admitted regardless of their state of health and other circumstances. The sale of life insurance in the U.S. began in the 1760s. The Presbyterian Synods in Philadelphia and New York City created the Corporation for Relief of Poor and Distressed Widows and Children of Presbyterian Ministers in 1759; Episcopalian priests organized a similar fund in 1769. Between 1787 and 1837 more than two dozen life insurance companies were started, but fewer than half a dozen survived. In the 1870s, military officers banded together to found both the Army (AAFMAA) and the Navy Mutual Aid Association (Navy Mutual), inspired by the plight of widows and orphans left stranded in the West after the Battle of the Little Big Horn, and of the families of U.S. sailors who died at sea.
The beneficiary receives policy proceeds upon the insured person's death. The owner designates the beneficiary, but the beneficiary is not a party to the policy. The owner can change the beneficiary unless the policy has an irrevocable beneficiary designation. If a policy has an irrevocable beneficiary, any beneficiary changes, policy assignments, or cash value borrowing would require the agreement of the original beneficiary. In cases where the policy owner is not the insured (also referred to as the celui qui vit or CQV), insurance companies have sought to limit policy purchases to those with an insurable interest in the CQV. For life insurance policies, close family members and business partners will usually be found to have an insurable interest. The insurable interest requirement usually demonstrates that the purchaser will actually suffer some kind of loss if the CQV dies. Such a requirement prevents people from benefiting from the purchase of purely speculative policies on people they expect to die. With no insurable interest requirement, the risk that a purchaser would murder the CQV for insurance proceeds would be great. In at least one case, an insurance company that sold a policy to a purchaser with no insurable interest (who later murdered the CQV for the proceeds), was found liable in court for contributing to the wrongful death of the victim (Liberty National Life v. Weldon, 267 Ala.171 (1957)).
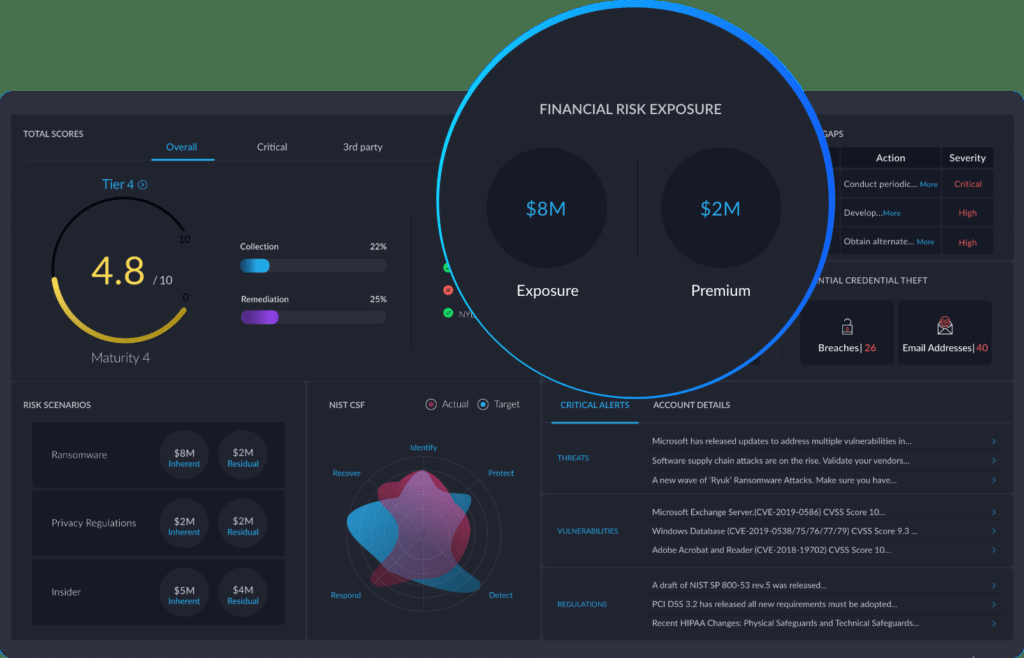
Figure 1: Cyber Insurance Risk Management for Carriers - Centraleyes Personal medical history; Family medical history; Driving record; Height and weight matrix, otherwise known as BMI (Body Mass Index). Based on the above and additional factors, applicants will be placed into one of several classes of health ratings which will determine the premium paid in exchange for insurance at that particular carrier. Life insurance companies in the United States support the Medical Information Bureau (MIB), which is a clearing house of information on persons who have applied for life insurance with participating companies in the last seven years. As part of the application, the insurer often requires the applicant's permission to obtain information from their physicians. Automated Life Underwriting is a technology solution which is designed to perform all or some of the screening functions traditionally completed by underwriters, and thus seeks to reduce the work effort, time and data necessary to underwrite a life insurance application. These systems allow point of sale distribution and can shorten the time frame for issuance from weeks or even months to hours or minutes, depending on the amount of insurance being purchased. The mortality of underwritten persons rises much more quickly than the general population. At the end of 10 years, the mortality of that 25-year-old, non-smoking male is 0.66/1000/year. Consequently, in a group of one thousand 25-year-old males with a $100,000 policy, all of average health, a life insurance company would have to collect approximately $50 a year from each participant to cover the relatively few expected claims. (0.35 to 0.66 expected deaths in each year × $100,000 payout per death = $35 per policy.) Other costs, such as administrative and sales expenses, also need to be considered when setting the premiums. A 10-year policy for a 25-year-old non-smoking male with preferred medical history may get offers as low as $90 per year for a $100,000 policy in the competitive US life insurance market. Most of the revenue received by insurance companies consists of premiums, but revenue from investing the premiums forms an important source of profit for most life insurance companies. Group insurance policies are an exception to this. In the United States, life insurance companies are never legally required to provide coverage to everyone, with the exception of Civil Rights Act compliance requirements. Insurance companies alone determine insurability, and some people are deemed uninsurable.
The policy can be declined or rated (increasing the premium amount to compensate for the higher risk), and the amount of the premium will be proportional to the face value of the policy. Many companies separate applicants into four general categories. These categories are preferred best, preferred, standard, and tobacco. Preferred best is reserved only for the healthiest individuals in the general population. This may mean, that the proposed insured has no adverse medical history, is not under medication, and has no family history of early-onset cancer, diabetes, or other conditions. Preferred means that the proposed insured is currently under medication and has a family history of particular illnesses. Most people are in the standard category.
People in the tobacco category typically have to pay higher premiums due to higher mortality. Recent US mortality tables predict that roughly 0.35 in 1,000 non-smoking males aged 25 will die during the first year of a policy. Mortality approximately doubles for every additional ten years of age, so the mortality rate in the first year for non-smoking men is about 2.5 in 1,000 people at age 65. Compare this with the US population male mortality rates of 1.3 per 1,000 at age 25 and 19.3 at age 65 (without regard to health or smoking status).
Term assurance provides life insurance coverage for a specified term (usually 10–30 years). Term life insurance policies do not accumulate cash value, but are significantly less expensive than permanent life insurance policies with equivalent face amounts. Policyholders can save to provide for increased term premiums or decrease insurance needs (by paying off debts or saving to provide for survivor needs). Mortgage life insurance insures a loan secured by real property and usually features a level premium amount for a declining policy face value because what is insured is the principal and interest outstanding on a mortgage that is constantly being reduced by mortgage payments. The face amount of the policy is always the amount of the principal and interest outstanding that are paid should the applicant die before the final installment is paid.
The endowment policy is a life insurance contract designed to pay a lump sum after a specific term (on its 'maturity') or on death. Typical maturities are ten, fifteen, or twenty years up to a certain age limit. Some policies also pay out in the case of critical illness. Policies are typically traditional with-profits or unit-linked (including those with unitized with-profits funds). Endowments can be cashed in early (or surrendered) and the holder then receives the surrender value which is determined by the insurance company depending on how long the policy has been running and how much has been paid into it.
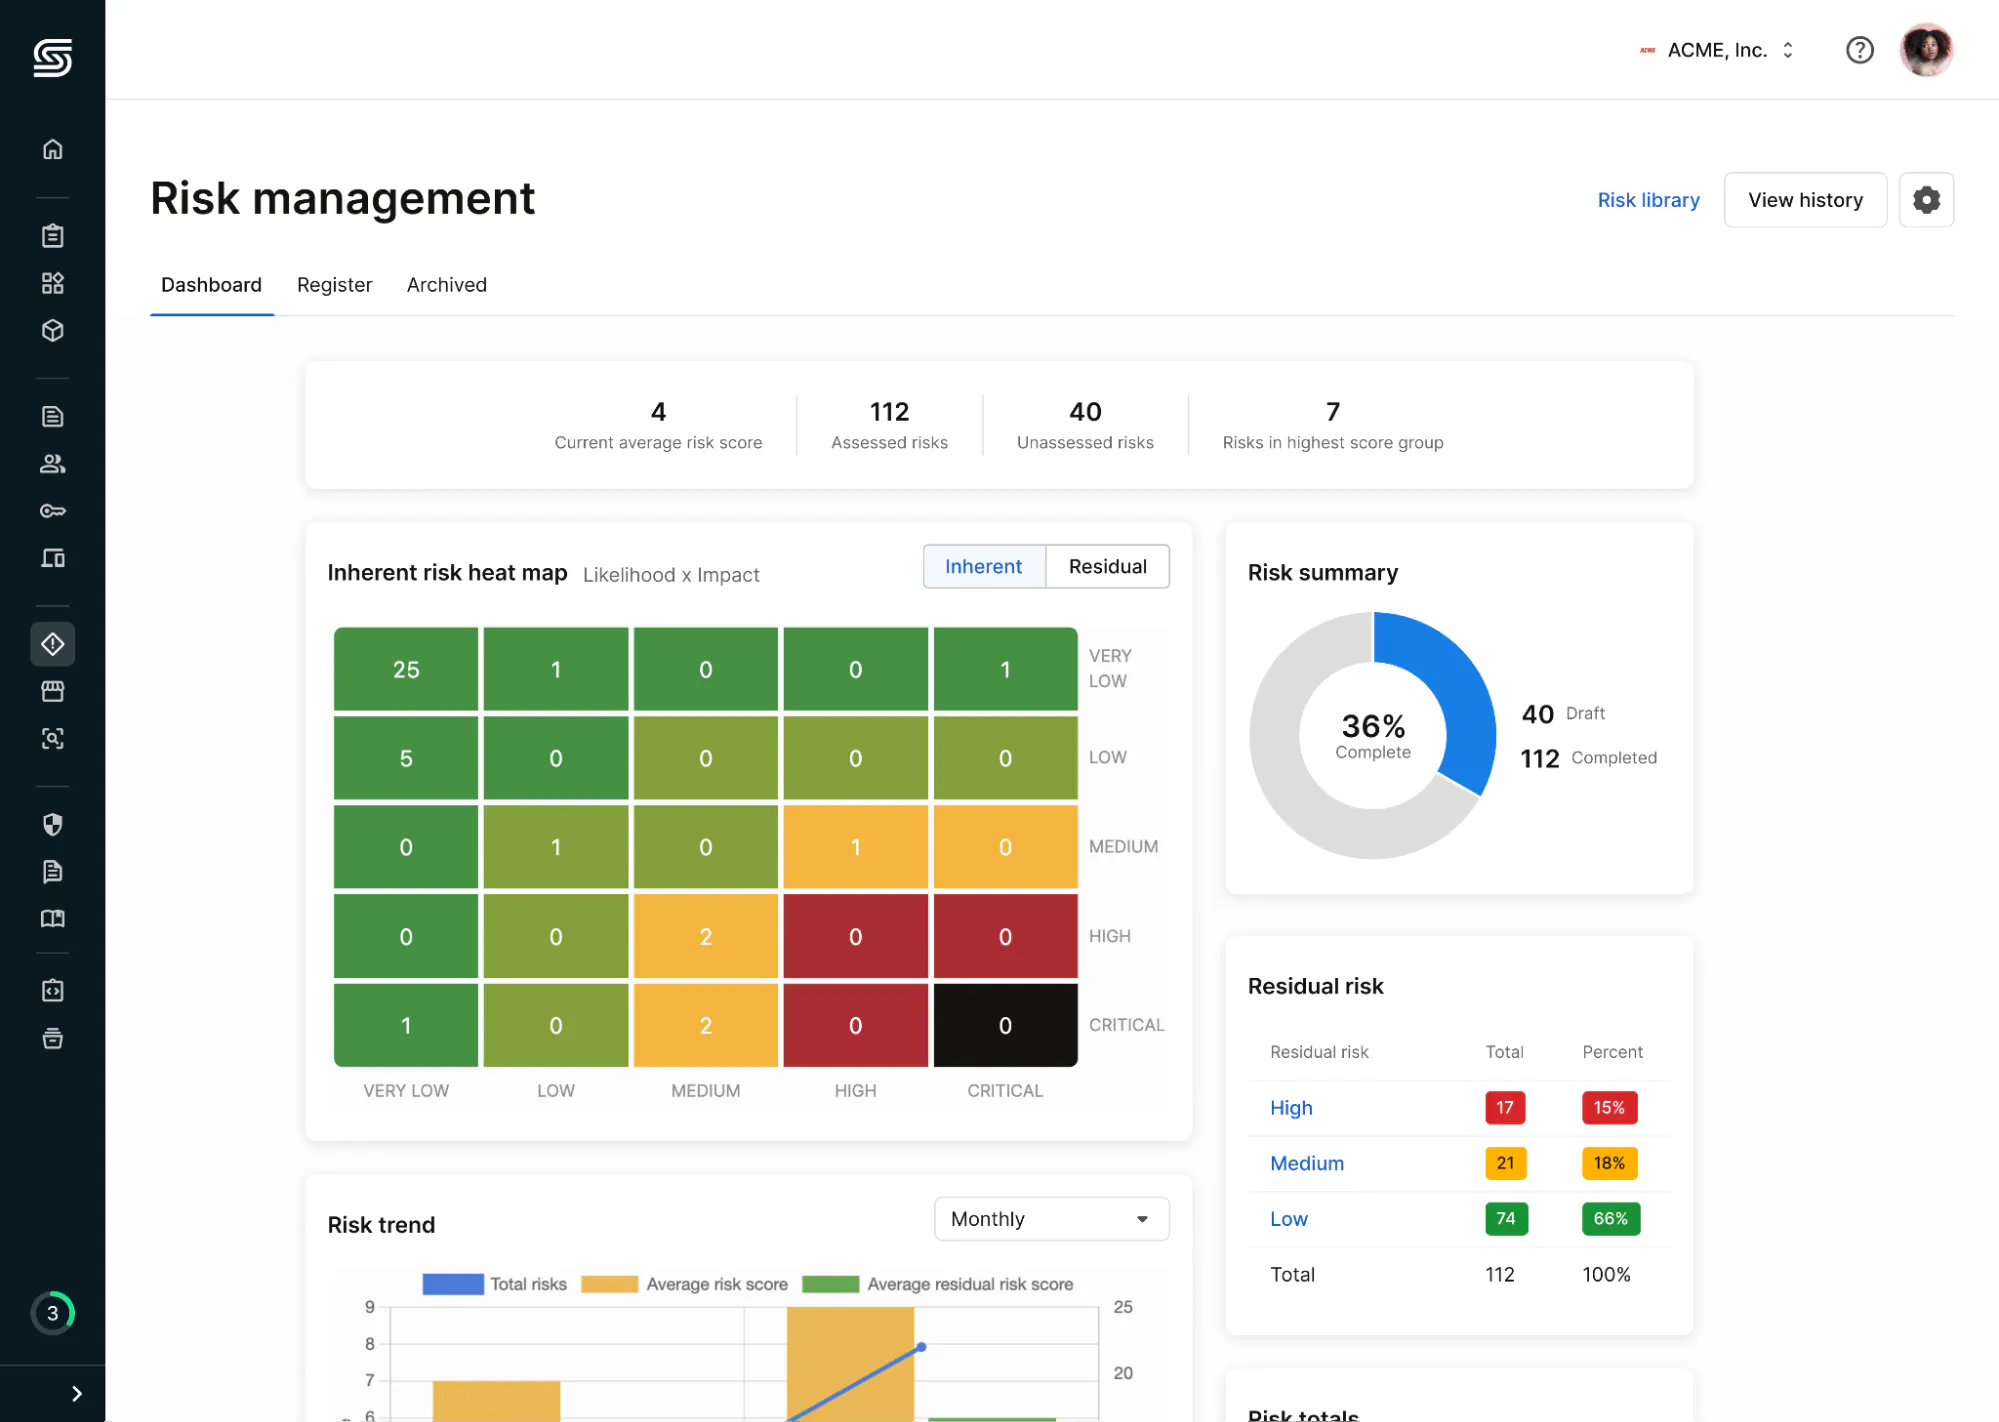
Unit-linked insurance plans are unique insurance plans which are similar to mutual funds and term insurance plans combined as one product. The investor does not participate in the profits of the plan per se but gets returns based on the returns on the chosen funds. Figure 2: Risk Analysis Calculations: 7 Ways to Determine Cybersecurity Risk Scores Some policies afford the policyholder a share of the profits of the insurance company—these are termed with-profits policies.
Other policies provide no rights to a share of the profits of the company—these are non-profit policies. With-profit policies are used as a form of collective investment scheme to achieve capital growth. Other policies offer a guaranteed return not dependent on the company's underlying investment performance; these are often referred to as without-profit policies, which may be construed as a misnomer.
Although some aspects of the application process (such as underwriting and insurable interest provisions) make it difficult, life insurance policies have been used to facilitate exploitation and fraud. In the case of life insurance, there is a possible motive to purchase a life insurance policy, particularly if the face value is substantial, and then murder the insured. Usually, the larger the claim or the more serious the incident, the larger and more intense the ensuing investigation by police and insurer investigators. Multiple fictional and non-fictional works, including books, films, television series and podcasts have featured the scenario as a plot device or actually occurring as a true crime. There was also a documented case in Los Angeles in 2006 where two elderly women were accused of taking in homeless men and assisting them. As part of their assistance, they took out life insurance for the men. After the contestability period ended on the policies, the women are alleged to have had the men killed via hit-and-run vehicular homicide. On April 17, 2016, a report by Lesley Stahl on 60 Minutes claimed that life insurance companies do not pay significant numbers of beneficiaries. This is because many people named as beneficiaries never submit claims to the insurance companies upon the death of the insured, and are unaware that any benefit exists to be claimed, though the insurance companies have full knowledge. The amounts of such benefits are often small, but the numbers of would-be beneficiaries are quite large. These unclaimed benefits eventually become sources of profit.
Artificial intelligence (AI) and its subfields have been used in applications throughout industry and academia. Machine learning has been used for various scientific and commercial purposes, including language translation, image recognition, decision-making, credit scoring, and e-commerce. Since the 2020s, massive advancements have been made in the field of generative AI (GenAI) as a result of the 2017 inception of Transformer Model architecture. GenAI has the ability to create text, images, voice, music, videos, and other forms of data from chat-based prompting.
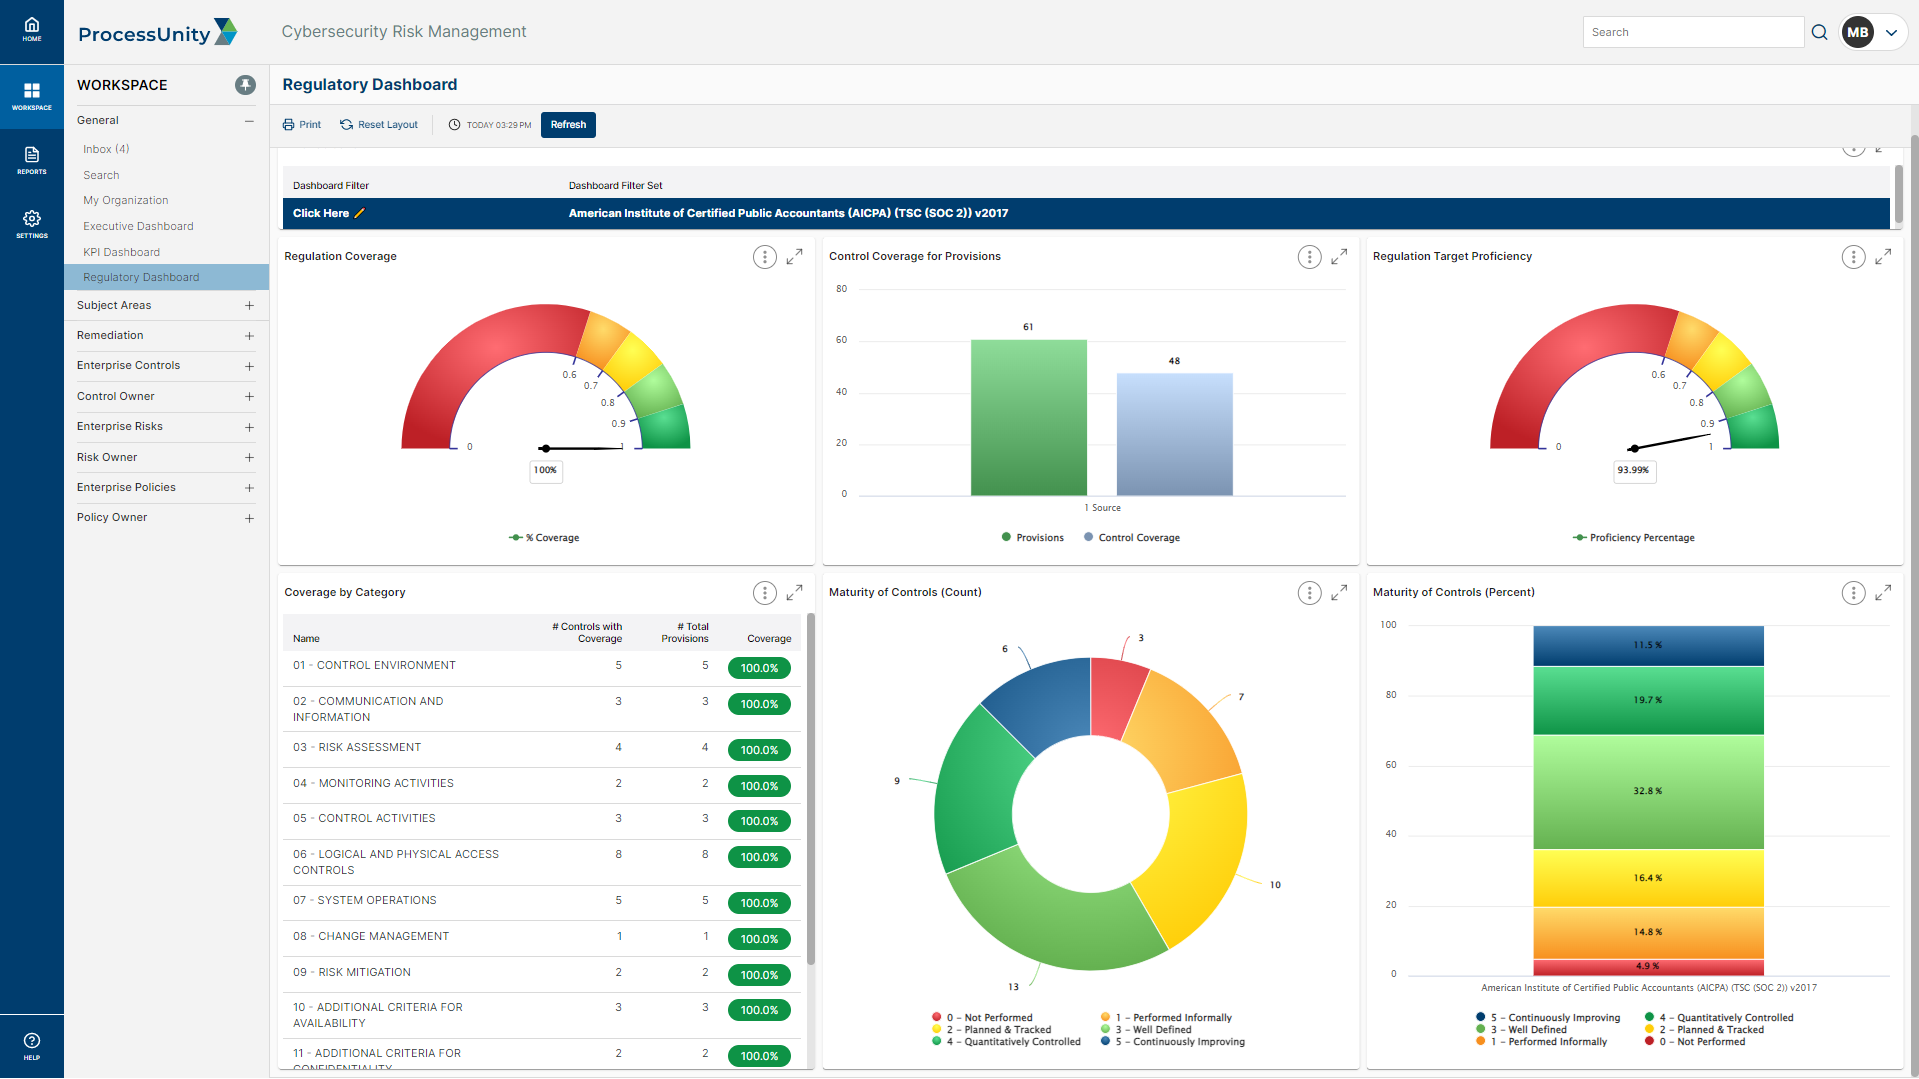
In agriculture, AI has been proposed as a way for farmers to identify areas that need irrigation, fertilization, or pesticide treatments to increase yields, thereby improving efficiency. AI has been used to attempt to classify livestock pig call emotions, automate greenhouses, detect diseases and pests, and optimize irrigation. Figure 3: Information Security Risk Assessment Software A 2019 study found that generative AI increased productivity by 15% in contact centers. Another 2019 study found it increased productivity by up to 40% for writing tasks. An August 2025 review by MIT found that of surveyed companies, 95% did not report any improvement in revenue from the use of AI. In September 2025, a Harvard Business Review article described how increased use of AI does not automatically lead to increases in revenue or actual productivity. Referring to "AI generated work content that masquerades as good work, but lacks the substance to meaningfully advance a given task", the article coined the term workslop. Per studies done in collaboration with the Stanford Social Media Lab, workslop does not improve productivity and undermines trust and collaboration among colleagues. In telehealth, agentic AI is reportedly facilitating the creation of large business models (millions in annual profit) with 1–2 employees, such as MEDVi, which as of August 2025 only had 2 employees and ~$75M in annual profit for GLP-1 weight-loss telehealth services.
Research and development of quantum computers has been performed with machine learning algorithms. For example, there is a prototype, photonic, quantum memristive device for neuromorphic computers (NC)/artificial neural networks and NC-using quantum materials with some variety of potential neuromorphic computing-related applications. The use of quantum machine learning for quantum simulators has been proposed for solving physics and chemistry problems.
Artificial intelligence and machine learning are used in electronic design automation to assist with integrated circuit design, including floorplanning, placement, routing, functional verification, and optimization of power, performance, and chip area. Time sharing Interactive interpreters Graphical user interfaces and the computer mouse Rapid application development environments The linked list data structure Automatic storage management Symbolic programming Functional programming Dynamic programming Object-oriented programming Optical character recognition Constraint satisfaction AI programs have been used in hiring processes to screen resumes and rank candidates based on their qualifications, predict a candidate's likelihood of success in a given role, and automate repetitive communication tasks using chatbots. Studies on these programs have identified tendencies for gender bias, favoring male names and male-coded characteristics, as well as bias against disabled candidates and racial minorities.
AI underlies avatars (automated online assistants) on web pages. It can reduce operation and training costs. In 2016, Pypestream automated customer service for its mobile application to streamline communication with customers. A Google app analyzes language and converts speech into text. The platform can identify angry customers through their language and respond appropriately. Amazon uses a chatbot for customer service that can perform tasks like checking the status of an order, cancelling orders, offering refunds, and connecting the customer with a human representative.
2. System Architecture & Core Working Principles In educational institutions, AI has been used to automate routine tasks such as attendance tracking, grading, and marking. AI tools have also been used to monitor student progress and analyze learning behaviors, with the goal of facilitating timely interventions for students facing academic challenges. As of 2025 and 2026, respectively, about 80% of high school students and nearly 60% of college students were also using AI. Some schools and universities proposed restrictions on students' usage due to issues with increased cheating, over-reliance on AI tools, and widening of digital inequities.
The U.S. Department of Energy wrote in an April 2024 report that AI may have applications in modeling power grids, reviewing federal permits with large language models (LLMs), predicting levels of renewable energy production, and improving the planning process for electrical vehicle charging networks. Other studies have suggested that machine learning can be used for energy consumption prediction and scheduling (e.g., to help with renewable energy intermittency management).
The late 1980s and early 1990s saw expert systems used in technical and environmental domains. For example, researchers built a fishway design advisor to recommend fish passage structures under varying hydraulic and biological conditions using the VP-Expert shell. Transportation researchers applied the same shell to balance airport capacity with noise-mitigation plans. In agriculture, a potato insect expert system (PIES) supported pest management decisions for Colorado potato beetle. The U.S. Environmental Protection Agency's CORMIX system for modeling pollutant discharges combined rules with Fortran hydrodynamic models. Autonomous ships that monitor the ocean, AI-driven satellite data analysis, passive acoustics or remote sensing and other applications of environmental monitoring make use of machine learning. For example, "Global Plastic Watch" is an AI-based satellite-monitoring platform for analysis/tracking of plastic waste sites to help with the prevention of plastic pollution—primarily ocean pollution—by helping identify who mismanages plastic waste and where dumping into oceans occurs.
AI applications analyze media content such as movies, TV programs, advertisement videos, and user-generated content. The solutions often involve computer vision. Typical scenarios include the analysis of images using object recognition or facial recognition techniques, or the analysis of video for recognizing scenes, objects, or faces. AI-based media analysis can facilitate media search, the creation of descriptive keywords for content, content policy monitoring (such as verifying the suitability of content for a particular TV viewing time), speech to text for archival or other purposes, and the detection of logos, products, or celebrity faces for ad placement.
Motion interpolation Pixel-art scaling algorithms Image scaling Image restoration Photo colorization Film restoration and video upscaling Photo tagging Text-to-image models (such as DALL-E, Midjourney, and Stable Diffusion) Image to video Text to video (such as Make-A-Video from Meta, Imagen video and Phenaki from Google) Text to music with AI models (such as MusicLM) Text to speech (such as ElevenLabs and 15.ai) Motion capture AI has been used to compose music of various genres. David Cope created an AI called Emily Howell that became well known in the field of algorithmic computer music. The algorithm behind Emily Howell is registered as a US patent. In 2012, AI Iamus created the first complete classical album. AIVA (Artificial Intelligence Virtual Artist), composes symphonic music, mainly classical music for film scores. It became the first virtual composer to be recognized by a musical professional association. Melomics creates computer-generated music for stress and pain relief. The Watson Beat uses reinforcement learning and deep belief networks to compose music on a simple seed input melody and a select style. The software was open sourced, and musicians such as Taryn Southern collaborated with the project. South Korean singer Hayeon's debut song, "Eyes on You", was composed using AI which was supervised by real composers, including NUVO.
Narrative Science sells computer-generated news and reports. It summarizes sporting events based on statistical data from a game. It also creates financial reports and real estate analyses. Automated Insights generates personalized recaps and previews for Yahoo Sports Fantasy Football. Yseop uses AI to turn structured data into natural language comments and recommendations. It writes financial reports, executive summaries, and personalized sales or marketing documents in multiple languages, including English, Spanish, French, and German. TALESPIN made up stories similar to the fables of Aesop. The program started with a set of characters who wanted to achieve certain goals. Mark Riedl and Vadim Bulitko asserted that the essence of storytelling was experience management, or "how to balance the need for a coherent story progression with user agency, which is often at odds". While AI storytelling focuses on story generation (character and plot), story communication also received attention. In 2002, researchers developed an architectural framework for narrative prose generation. They faithfully reproduced text variety and complexity on stories such as Little Red Riding Hood. In 2016, a Japanese AI co-wrote a short story and almost won a literary prize. South Korean company Hanteo Global uses a journalism bot to write articles. Literary authors are also exploring uses of AI. An example is David Jhave Johnston's work ReRites (2017–2019), where the poet created a daily rite of editing the poetic output of a neural network to create a series of performances and publications.
In video games, AI is routinely used to generate behavior in non-player characters (NPCs). In addition, AI is used for pathfinding. Games with less typical AI include the AI director of Left 4 Dead (2008) and the neuroevolutionary training of platoons in Supreme Commander 2 (2010). In the 21st century, AIs have beaten human players in many games, including chess (Deep Blue), Jeopardy! (Watson), Go (AlphaGo), poker (Pluribus and Cepheus), E-sports (StarCraft), and general game playing (AlphaZero and MuZero). Kuki AI is a set of chatbots and other apps which were designed for entertainment and as a marketing tool.
The first AI art program, AARON, was developed by Harold Cohen in 1968 with the goal of being able to code the act of drawing. It started by creating simple black and white drawings, and later to painting using special brushes and dyes chosen by the program without mediation from Cohen. AI platforms such as DALL-E, Stable Diffusion, Imagen, and Midjourney have been used for generating visual images from inputs such as text or other images. Some AI tools allow users to input images and output changed versions, such as to display an object or product in different environments. AI image models can also attempt to replicate the specific styles of artists, and can add visual complexity to rough sketches. AI has been used to generate quantitative analysis of existing digital art collections. Two computational methods, close reading and distant viewing, are typical approaches used to analyze digitized art. While distant viewing includes the analysis of large collections, close reading involves one piece of artwork.
Banks use AI to organize operations for bookkeeping, investing in stocks, and managing properties. AI can adapt to changes during non-business hours. The use of AI in applications such as online trading and decision-making has changed major economic theories. For example, AI-based buying and selling platforms estimate personalized demand and supply curves, thus enabling individualized pricing.
AI systems reduce information asymmetry in the market and thus make markets more efficient. The application of AI in the financial industry can help alleviate financing constraints of non-state-owned enterprises, especially for smaller and more innovative enterprises. Large financial institutions use AI to assist with their investment practices. BlackRock's AI engine, Aladdin, is used both within the company and by clients to help with investment decisions. Its functions include the use of natural language processing to analyze text such as news, broker reports, and social media feeds. It then gauges the sentiment on the companies mentioned and assigns a score. Banks such as UBS and Deutsche Bank use SQREEM (Sequential Quantum Reduction and Extraction Model) to mine data to develop consumer profiles and match them with wealth management products.
AI in healthcare is often used for classification, such as to evaluate a CT scan or electrocardiogram or to identify high-risk patients for population health. Additional potential applications like robot-assisted surgery, virtual nursing assistants, and dosage error reductions could create billions in annual savings for U.S. health care. For certain disorders and diseases, AI algorithms can aid in diagnosis, recommended treatments, outcome prediction, and patient progress tracking. Early detection of diseases like cancer is made possible by AI algorithms, which diagnose diseases by analyzing complex sets of medical data. For example, Microsoft's AI project Hanover helps doctors choose cancer treatments from among the more than 800 medicines and vaccines. Studies have shown AI capable of identifying skin cancers and diagnosing eye conditions, similar to an ophthalmologist, and recommending treatment referrals via transfer learning. Another project monitors multiple high-risk patients by asking each patient questions based on data acquired from doctor/patient interactions. Artificial neural networks are used as clinical decision support systems for medical diagnosis, such as in concept processing technology in electronic medical record (EMR) software. Other healthcare tasks thought suitable for an AI that are in development include: Screening Companion robots for elder care Drug creation (e.g. by identifying candidate drugs and by using existing drug screening data such as in life extension research) Clinical training Identifying genomic pathogen signatures of novel pathogens or identifying pathogens via physics-based fingerprints (including pandemic pathogens) Helping link genes to their functions, otherwise analyzing genes and identification of novel biological targets Help development of biomarkers Help tailor therapies to individuals in personalized medicine/precision medicine AI-enabled chatbots decrease the need for humans to perform basic call center tasks, and machine learning in sentiment analysis can spot fatigue to prevent overwork. Decision support systems can potentially prevent industrial disasters and make disaster response more efficient. For manual workers in material handling, predictive analytics has been proposed to reduce musculoskeletal injury. AI can attempt to process workers' compensation claims. AI has been proposed for detection of accident near misses, which are underreported.
Speech translation technology attempts to convert one language into another. This could potentially reduce language barriers in global commerce and cross-cultural exchange, enabling speakers of various languages to communicate. AI has been used to automatically translate spoken language and textual content in products like Microsoft Translator, Google Translate, and DeepL Translator. Also, research and development are in progress to decode and conduct animal communication. Meaning is conveyed not only by text, but also through usage and context (see semantics and pragmatics). As a result, the two primary categorization approaches for machine translations are statistical machine translation (SMT) and neural machine translations (NMTs). The old method of performing translation was to use statistical methodology to forecast the best probable output with specific algorithms. However, with NMT, the approach employs dynamic algorithms to achieve better translations based on context.
AI facial recognition systems are used for mass surveillance, notably in China. In 2019, Bengaluru, India deployed AI-managed traffic signals that uses cameras to monitor traffic density and adjust signal timing based on the interval needed to clear traffic. AI tools have been used to translate mathematical proofs into formal proofs to automatically verify them.
AI systems have also been used to search for improved algorithms and computational routines. AlphaTensor, AlphaDev, and AlphaEvolve have been applied to matrix multiplication algorithms, sorting routines, and broader scientific and algorithmic discovery. 3. Software Implementation, Frameworks & Protocols Various countries are deploying AI military applications. Research is targeting intelligence collection and analysis, logistics, cyber operations, information operations, and semiautonomous and autonomous vehicles. AI has been used in military operations in Iraq, Syria, Israel, and Ukraine.
AI is used in robotics to help robots perceive their surroundings, plan actions, navigate, manipulate objects, and adapt to changing environments. AI systems are used to connect sensor data with physical action, especially in systems operating outside controlled factory settings. Intelligent personal assistants use AI to attempt to respond to natural language requests. Siri, released in 2010 for Apple smartphones, popularized the concept. Bing Chat has used AI as part of its search engine.
Machine learning can be used to combat spam, scams, and phishing. It can scrutinize the content of spam and phishing attacks to attempt to identify malicious elements. Some models built via machine learning algorithms have over 90% accuracy in distinguishing between spam and legitimate emails. These models can be refined using new data and evolving spam tactics. Machine learning also analyzes traits such as sender behavior, email header information, and attachment types, potentially enhancing spam detection.
AI has been used in facial recognition systems. Some examples are Apple's Face ID and Android's Face Unlock, which are used to secure mobile devices. China has used facial recognition and AI technology in Xinjiang. In 2017, reporters visiting the region found surveillance cameras installed every hundred meters or so in several cities, as well as facial recognition checkpoints at areas like gas stations, shopping centers, and mosque entrances. Human rights groups have criticized the Chinese government for using AI facial recognition technology for use in political suppression. The Netherlands has deployed facial recognition and AI technology since 2016. As of 2019, the database of the Dutch police contained over 2.2M pictures of 1.3M Dutch citizens. This accounts for about 8% of the population. In The Netherlands, face recognition is not used by the police on municipal CCTV. Image labeling has been used by Google Image Labeler to detect products in photos and allow people to search based on a photo. Image labeling has also been demonstrated to generate speech to describe images to blind people.
Machine learning can help to restore and attribute ancient texts. It can help to index texts, e.g., to enable better and easier searching and classification of fragments. AI can also be used to investigate genomes to uncover genetic history, such as interbreeding between archaic and modern humans by which, e.g., the past existence of a ghost population, not Neanderthal or Denisovan, was inferred. It can also be used for "non-invasive and non-destructive access to internal structures of archaeological remains".
A deep learning system was reported to learn intuitive physics from visual data (of virtual 3D environments) based on an unpublished approach inspired by studies of visual cognition in infants. Other researchers have developed a machine learning algorithm that could discover sets of basic variables of various physical systems and predict the systems' future dynamics from video recordings of their behavior. In the future, it may be possible that such can be used to automate the discovery of physical laws of complex systems.
Machine learning is used in diverse types of reverse engineering. For example, machine learning has been used to reverse engineer a composite material part, enabling unauthorized production of high quality parts, and for quickly understanding the behavior of malware. It can be used to reverse engineer AI models. It can also design components by engaging in a type of reverse engineering of not-yet existent virtual components, such as inverse molecular design for particular desired functionality or protein design for pre-specified functional sites. Biological network reverse engineering could model interactions in a human understandable way, e.g., based on time-series data of gene expression levels. The open-source Reverse Engineer Anything (REA) project connects AI coding agents with reverse-engineering tools such as Ghidra, Hopper, and IDA to inspect compiled binaries and trace application behavior.
AI is used in astronomy to analyze increasing amounts of available data and applications, mainly for "classification, regression, clustering, forecasting, generation, discovery, and the development of new scientific insights" e.g., for discovering exoplanets, forecasting solar activity, and distinguishing between signals and instrumental effects in gravitational wave astronomy. It could also be used for space exploration, including analysis of data from space missions, real-time science decisions of spacecraft, space debris avoidance, and more autonomous operation. In the search for extraterrestrial intelligence (SETI), machine learning has been used in attempts to identify artificially generated electromagnetic waves in available data—such as real-time observations—and other technosignatures, e.g. via anomaly detection. In ufology, the SkyCAM-5 project headed by Prof. Hakan Kayal and the Galileo Project headed by Avi Loeb use machine learning to attempt to detect and classify types of UFOs. The Galileo Project also seeks to detect two further types of potential extraterrestrial technological signatures with the use of AI: 'Oumuamua-like interstellar objects, and non-manmade artificial satellites.
Machine learning can also be used to produce datasets of spectral signatures of molecules that may be involved in the atmospheric production or consumption of particular chemicals—such as phosphine possibly detected on Venus—which could prevent miss assignments and, if accuracy is improved, be used in future detection and identification of molecules on other planets.
There is research about which types of computer-aided chemistry would benefit from machine learning. A deep learning AI-based process has been developed that uses genome databases to design novel proteins based on evolutionary algorithms. Machine learning has also been used for protein design with pre-specified functional sites, predicting molecular properties, and exploring large chemical/reaction spaces. Using drug discovery AI algorithms, researchers generated 40,000 potential chemical weapon candidates, helping in the regulation of such chemicals to prevent synthesizing them for real harm.
Applications for machine learning in decoding human biology include helping to map gene expression patterns to functional activation patterns or identifying functional DNA motifs. It is widely used in genetic research. There is some use of machine learning in synthetic biology, disease biology, nanotechnology (e.g., nanostructured materials and bionanotechnology), and materials science.
Network protection: Machine learning has been used to improve intrusion detection systems by broadening the search beyond previously identified threats. Application security: AI has been used to assist in counterattacks, such as server-side request forgery, SQL injection, cross-site scripting, and distributed denial-of-service. Suspect user behavior: Machine learning can attempt to identify fraud or compromised applications as they occur.
Due to transportation's complexity, training AI in a real-world driving environment is impractical in most cases, and is instead achieved through simulator-based testing. AI-based systems control functions such as braking, lane changing, collision prevention, navigation and mapping. Some autonomous vehicles do not allow human drivers (they have no steering wheels or pedals). There are prototypes of autonomous automotive public transport vehicles such as autonomous rail transport in operation, electric mini-buses, and autonomous delivery vehicles, including delivery robots. Autonomous trucks are in the testing phase. The UK government passed legislation to begin testing of autonomous truck platoons in 2018. A group of autonomous trucks follow closely behind each other. German corporation Daimler is testing its Freightliner Inspiration. AI has been used to optimize traffic management, which can reduce wait times, energy use, and emissions. In 2026, AI tools were in development for hurricane recovery, with the goal of helping transportation officials assess damage more efficiently, improve traffic signal restoration, and better understand transportation needs.
Prediction markets, also known as betting markets, information markets, decision markets, idea futures, or event derivatives, are open markets that enable the prediction of specific outcomes using financial incentives. They are exchange-traded markets established for trading bets in the outcome of various events. The most common form of a prediction market is a binary option market, which will expire at the price of 0 or 100%. Prediction markets can be thought of as belonging to the more general concept of crowdsourcing which is specially designed to aggregate beliefs on particular topics of interest, where the market price can indicate what the crowd thinks the probability of the event is. Traders with different beliefs trade on contracts whose payoffs are related to the unknown future outcome and the market prices of the contracts are considered as the aggregated belief. Prediction markets are considered gambling by many governments, and are banned in some locations.
Some users and researchers have reported that prediction markets are similar to gambling and can cause addiction. Steven Gjerstad (Purdue), in his paper "Risk Aversion, Beliefs, and Prediction Market Equilibrium", has shown that prediction market prices are very close to the mean belief of market participants if the agents are risk averse and the distribution of beliefs is spread out (as with a normal distribution, for example). Justin Wolfers (Wharton) and Eric Zitzewitz (Dartmouth) have obtained similar results to Gjerstad's conclusions in their paper "Interpreting Prediction Market Prices as Probabilities". Lionel Page and Robert Clemen have looked at the quality of predictions for events taking place sometime in the future and provide evidence for a favourite-longshot bias. They found that predictions are better when the event predicted is close in time. For events which take place further in time (e.g., elections in more than a year), prices are biased towards 50%. This bias comes from the traders' "time preferences" (their preferences not to lock their funds for a long time in assets). Due to the accuracy of the prediction market, it has been applied to different industries to make crucial decisions. Some examples include: Prediction markets can be utilized to improve forecasting and have a potential application to test lab-based information theories based on their feature of information aggregation. Researchers have applied prediction markets to assess unobservable information in Google's IPO valuation ahead of time. In healthcare, predictive markets can help forecast the spread of infectious diseases. In a pilot study, a statewide influenza outbreak in Iowa was predicted by these markets 2–4 weeks in advance with clinical data volunteered from participating health care workers. Some corporations have harnessed internal predictive markets for decisions and forecasts. In these cases, employees can use virtual currency to bet on what they think will happen for this company in the future. The most accurate guesser will win a monetary prize as a payoff. For example, Best Buy once experimented with using the predictive market to predict whether a Shanghai store could open on time. The virtual dollar drop in the market successfully forecasted the lateness of the business and prevented the company from extra money loss. Although prediction markets are often fairly accurate and successful, there are many times the market fails in making the right prediction or making one at all. Based mostly on an idea in 1945 by Austrian economist Friedrich Hayek, prediction markets are "mechanisms for collecting vast amounts of information held by individuals and synthesizing it into a useful data point". One way the prediction market gathers information is through James Surowiecki's phrase, "The Wisdom of Crowds", in which a group of people with a sufficiently broad range of opinions can collectively be cleverer than any individual. However, this information-gathering technique can also lead to the failure of the prediction market. Oftentimes, the people in these crowds are skewed in their independent judgments due to peer pressure, panic, bias, and other breakdowns developed out of a lack of diversity of opinion. One of the main constraints and limits of the wisdom of crowds is that some prediction questions require specialized knowledge that the majority of people do not have. Due to this lack of knowledge, the crowd's answers can sometimes be very wrong. The second market mechanism is the idea of the marginal-trader hypothesis. According to this theory, "there will always be individuals seeking out places where the crowd is wrong". These individuals, in a way, put the prediction market back on track when the crowd fails, and values could be skewed. The effects of manipulation and biases are also internal challenges that prediction markets need to deal with, i.e., liquidity or other factors not intended to be measured are taken into account as risk factors by the market participants, distorting the market probabilities. Prediction markets may also be subject to speculative bubbles. For example, in the year 2000, IEM presidential futures markets, seeming "inaccuracy" comes from buying that occurred on or after Election Day, 11/7/00, but, by then, the trend was clear. There can also be direct attempts to manipulate such markets. In the Tradesports 2004 presidential markets, there was an apparent manipulation effort. An anonymous trader sold short so many Bush 2004 presidential futures contracts that the price was driven to zero, implying a zero percent chance that Bush would win. The only rational purpose of such a trade would be an attempt to manipulate the market in a strategy called a "bear raid". If this were a deliberate manipulation effort, it failed, however, as the price of the contract rebounded rapidly to its previous level. As more press attention is paid to prediction markets, it is likely that more groups will be motivated to manipulate them. However, in practice, such attempts at manipulation have always proven to be very short-lived. In their paper entitled "Information Aggregation and Manipulation in an Experimental Market" (2005), Hanson, Oprea, and Porter (George Mason U), show how attempts at market manipulation can in fact end up increasing the accuracy of the market because they provide that much more profit incentive to bet against the manipulator. Using real-money prediction market contracts as a form of insurance can also affect the price of the contract. For example, if the election of a leader is perceived as negatively impacting the economy, traders may buy shares of that leader being elected, as a hedge.
In October 2024, prediction market Kalshi won a lawsuit against its regulator, the Commodity Futures Trading Commission, with a federal appeals court in Washington allowing it to revive the first fully regulated election prediction markets in the United States. Kalshi's court victory over the CFTC opened the market for election markets. In late 2025, MetaMask integrated Polymarket into its wallet interface, expanding user access to blockchain-based prediction markets through a self-custodial application.
Video of Robin Hanson's Combinatorial Prediction Markets lecture at the 'Uncertainty in Artificial Intelligence' conference in Helsinki, 2008 Journal of Prediction Markets 4. Practical Deployment, Analysis & Case Studies A blueprint for a custom workflow that automates real-time cybersecurity posture evaluation for insurance underwriting, replacing manual questionnaires and static scans.
Manual cyber risk assessment creates a critical bottleneck, delaying quote turnaround and limiting underwriting capacity. A custom agentic workflow automates this by orchestrating API calls to an applicant's security tools (like CrowdStrike or Qualys), ingesting external attack surface data from vendors like Bitsight, and scoring findings against your proprietary underwriting framework. This architecture eliminates weeks of back-and-forth, enabling real-time, data-driven risk evaluation and binding for a rapidly evolving exposure class.
Implementation requires building a LangGraph-based orchestrator that manages specialized agents for data collection, a rules engine for scoring, and secure integration with PAS and CRM systems like Guidewire or Salesforce. Critical controls include confidence scoring for automated decisions, exception routing to human underwriters with full context, and immutable audit logging for compliance. The result is a 70%+ reduction in assessment cycle time and more consistent, defensible risk selection.
A custom agentic workflow for cyber insurance risk scoring transforms a manual, weeks-long evaluation into a real-time, data-driven process, directly improving underwriting economics and market responsiveness. Manual cyber risk assessments involve sequential questionnaires, third-party report procurement, and manual scoring, creating a 2-4 week bottleneck. A custom workflow automates data collection via API integrations (e.g., with security scanning tools like Tenable, CrowdStrike) and external attack surface databases, enabling real-time scoring and immediate preliminary terms. This accelerates binding for qualified risks and captures more submissions before brokers seek alternatives.
Manual scoring is subjective and inconsistent across underwriters, leading to mispriced risks. An agentic workflow applies a unified, rules-based framework to interpret technical security posture data (e.g., patch cadence, MFA adoption, incident response readiness) against actuarial models. This ensures every application is evaluated against the same objective criteria, reducing adverse selection and creating a more predictable, profitable portfolio.
The labor-intensive process of reviewing security questionnaires and vendor reports consumes high-cost underwriting and engineering resources. Automating data ingestion, analysis, and summary generation with specialized AI agents reallocates senior staff to exception handling and complex risk structuring. This shifts the operating model from high-touch, low-volume to scalable, high-throughput underwriting.
Static annual reviews cannot capture the rapid evolution of a company's cyber risk. A custom workflow architecture supports continuous monitoring via integrated APIs, allowing for dynamic premium adjustments or coverage recommendations based on deteriorating or improving security posture. This creates a more accurate, responsive product and provides insureds with actionable insights to reduce their risk, aligning insurer and client incentives.
Manual processes lack defensible audit trails for pricing decisions, creating regulatory and governance risk. A production-grade workflow automatically logs every data source queried, scoring logic applied, and decision rationale. This creates an immutable, explainable record for internal audits, model risk management (MRM) validation, and regulatory examinations, turning compliance from a retrospective burden into a built-in feature.
Insurers with slow, manual cyber underwriting cannot scale or adapt to new threat vectors. A custom, modular agentic architecture allows for rapid integration of new data sources (e.g., AI supply chain risk, quantum computing readiness) and underwriting frameworks. This future-proofs the operation, enabling faster product innovation and positioning the carrier as a leader in a high-growth, specialty line.
This architecture details a custom multi-agent orchestration layer that automates the ingestion, analysis, and scoring of cybersecurity risk for insurance underwriting, replacing manual questionnaires and point-in-time audits. This workflow automates the most labor-intensive bottleneck in cyber underwriting: manually correlating disparate security signals into a consistent risk score. It ingests real-time data from applicant APIs (e.g., vulnerability scanners, EDR platforms), external attack surface intelligence, and completed security questionnaires. The operational upside comes from reducing risk assessment cycles from weeks to minutes, enabling insurers to quote more accurately and bind policies faster in a volatile risk class, directly improving underwriter throughput and portfolio quality.
Implementation requires building agents on a framework like LangGraph, with strict controls for data quality and exception routing. The API Ingestion Agent handles OAuth flows and normalizes data from tools like CrowdStrike or Tenable. The Scoring Agent applies underwriting frameworks (e.g., NIST CSF) against the fused data, generating a score with rationale. All decisions route through a governance layer that logs rationale and routes low-confidence or high-limit cases to human review in systems like Salesforce or ServiceNow, ensuring auditability.
A production-grade workflow for real-time cyber risk assessment, where specialized agents orchestrate external data ingestion, security posture analysis, and underwriting logic to bind policies in hours, not weeks. This primary agent interacts with the applicant's environment via API or guided questionnaire to pull live configuration data (e.g., MFA status, patch cadence, endpoint protection). It normalizes findings against frameworks like CIS Controls or NIST CSF, generating a structured hygiene score. The agent handles authentication, data mapping, and fallback logic for partial or unavailable data, routing incomplete assessments for manual follow-up.
Operating in parallel, this agent queries third-party APIs (e.g., BitSight, SecurityScorecard, Shodan) and open-source intelligence to analyze the applicant's external attack surface. It evaluates exposed services, known vulnerabilities, domain reputation, and historical breach data. The agent fuses these signals into a composite external risk score, flagging high-severity findings like open RDP ports or compromised credentials for immediate underwriter alert.
The central orchestrator (built on LangGraph or similar) ingests scores from the hygiene and threat agents. It executes a rules engine against the carrier's cyber underwriting guidelines, applying logic for industry, revenue, and coverage limits. This agent calculates a final risk tier, generates a preliminary premium, and determines if the submission qualifies for straight-through processing or requires escalation due to complexity or high-risk signals.
A critical control layer that manages all cases failing automated rules or scoring thresholds. This component presents the underwriter with a consolidated risk dossier, agent reasoning, and specific decision points (e.g., 'MFA not enforced for all users'). It captures underwriter overrides and rationales, feeding them back into the system to refine future automated decisions and maintain a defensible audit trail for compliance.
5. Performance Evaluation & Extended Technical Observations This technical layer handles all synchronous and asynchronous communication between the agentic workflow and enterprise systems. It writes bound policies and quotes to the Policy Administration System (e.g., Guidewire), fetches historical loss data from the data warehouse, and logs all activities to the Document Management System (DMS) for compliance. It uses resilient patterns like retries and dead-letter queues to ensure reliability with external vendor APIs.
The monitoring layer tracks operational and model performance. It monitors agent accuracy, scoring distribution drift, and straight-through processing rates. It alerts engineers to API failures and provides underwriters with insight into portfolio risk concentration. This dashboard is essential for model risk management (MRM), providing evidence for validation and demonstrating that automated decisions remain fair and effective over time.
A phased implementation strategy for deploying a custom agentic workflow for cyber insurance risk scoring, designed to deliver measurable ROI while controlling technical and operational risk. Phase 1 establishes the core data ingestion and scoring engine. We implement agents to orchestrate API calls to external attack surface scanning tools (e.g., Bitsight, SecurityScorecard) and internal vulnerability management platforms, normalizing the data into a unified risk profile. A rules-based scoring model is deployed against this profile, generating initial risk tiers and clear exceptions for human review. This MVP delivers immediate value by automating manual data aggregation and providing a consistent baseline assessment, reducing initial evaluation time from days to hours.
Subsequent phases introduce intelligence and scale. Phase 2 layers in LLM agents to interpret scan results, generate underwriting narratives, and justify scores, while a dynamic engine produces tailored coverage recommendations. Phase 3 focuses on production integration, connecting the workflow to the Policy Administration System and broker portals for straight-through processing of low-risk submissions. Each phase includes parallel work on governance: implementing model monitoring, bias testing, and immutable audit logging to ensure the system remains explainable and compliant as it scales.
Comparison of manual versus custom agentic workflow for cyber insurance risk scoring, focusing on operational efficiency, accuracy, and compliance. Implementing a production-grade, automated cyber risk scoring system involves real architectural and operational considerations. Below are answers to common buyer questions about controls, integrations, and rollout.
The workflow is designed with validation and fallback logic. Initial API calls to security tools (e.g., vulnerability scanners, EDR platforms) are monitored for timeouts or error codes. For questionnaire-based inputs, agents use confidence scoring on extracted answers and can trigger follow-up clarification requests. Low-confidence or missing critical data (like evidence of endpoint protection) automatically routes the submission to an exception queue for human underwriter review, preventing garbage-in, garbage-out decisions. Data quality metrics are logged for continuous monitoring.
Implementing Governance, Controls, and Phased Rollout for Cyber Insurance Risk Scoring A custom agentic workflow for cyber risk scoring delivers value only when it operates within a controlled, auditable, and incrementally deployable architecture. This section details the governance layers, approval gates, and phased rollout strategy required to manage risk and ensure operational reliability.
Effective governance starts with immutable audit trails. Every agent action—data query, analysis step, and scoring decision—must be logged with timestamps, input data hashes, and model versioning. This creates a defensible record for compliance (e.g., model risk management, anti-bias regulations) and post-incident analysis. Controls are embedded as approval gates: high-risk scores, ambiguous external data, or deviations from underwriting guidelines trigger automated holds and route cases to human underwriters with full context via a dedicated exception queue in the PAS.
Phased rollout mitigates implementation risk. Start with a shadow mode, where the workflow runs in parallel with manual processes, scoring submissions without binding policies, to validate accuracy and calibrate thresholds. Next, implement a pilot for low-limit, standardized commercial cyber policies, enabling straight-through processing for clear-cut cases while routing exceptions. Final phases expand to complex risks and integrate with reinsurance placement systems. Each phase requires monitoring for scoring drift, exception rates, and underwriter feedback to iteratively refine agent logic and control parameters.
Building a custom cyber risk scoring workflow requires tight coordination between technical, business, and security teams to ensure the architecture delivers ROI while managing operational and regulatory risk. Owns the business case for faster quote turnaround and improved risk selection. Defines the scoring framework, acceptable risk appetite, and final decision authority. Must approve the logic for automated referrals and the thresholds for straight-through processing versus human escalation.
Provides the domain expertise to translate technical security posture (e.g., MFA adoption, patch cadence, EDR coverage) into quantifiable underwriting risk scores. Validates the data sources (e.g., external attack surface scans, questionnaire responses) and defines the weighting for critical control failures. Architects the multi-agent system (e.g., using LangGraph or CrewAI) that orchestrates data ingestion, scoring logic, and system writes. Responsible for integrating with external scanning APIs, core Policy Admin Systems (PAS), and internal underwriting workbenches. Implements observability and logging.
Develops and validates the predictive scoring models that combine technical signals with historical loss data. Implements bias testing and performance monitoring to meet Model Risk Management (MRM) requirements. Ensures model outputs are explainable for underwriters and regulatory scrutiny. Governs data usage (especially for external scanning), ensures adherence to state-specific regulations, and approves automated communication templates. Mandates the audit trail architecture that logs every data point, decision rationale, and model inference for regulatory examinations and dispute resolution.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Life%20insurance • https://en.wikipedia.org/wiki/Applications%20of%20artificial%20intelligence • https://en.wikipedia.org/wiki/Prediction%20market • https://inferensys.com/automate/agentic-underwriting-orchestration/agentic-workflow-for-cyber-insurance-risk-scoring • https://github.com/SecurityHero/AI-Cyber-Insurance-Calculator • https://developerlinkai.com/solutions/ai-developer-solutions-by-category-and-industry/ai-in-cybersecurity-solutions-by-industr y/ai-in-cybersecurity-solutions-in-the-insurance-industry/predictive-analytics-for-cyber-risk-modeling-and-premium-calculation/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Automated Cyber Insurance Risk Calculation Tool.
[*] Metasploit Scan Running on Target Subnet for Automated Cyber Insurance Risk Calculation Tool... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |