Complete Technical Paper Content — Automated Phishing Detection Using Transformer Models
Overview & System Context
Automated Phishing Detection Using Transformer Models: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9540 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Phishing email is a serious cyber threat that tries to deceive users by sending false emails with the intention of stealing confidential information or causing financial harm. Attackers, often posing as trustworthy entities, exploit technological advancements and sophistication to make detection and prevention of phishing more challenging. Despite extensive academic research, phishing detection remains an ongoing and formidable challenge in the cybersecurity landscape. Large Language Models (LLMs) and Masked Language Models (MLMs) possess immense potential to offer innovative solutions to address long-standing challenges. In this research paper, we present an optimized, fine-tuned transformer-based DistilBERT model designed for the detection of phishing emails. In the detection process, we work with a phishing email dataset and utilize the preprocessing techniques to clean and solve the imbalance class issues. Through our experiments, we found that our model effectively achieves high accuracy, demonstrating its capability to perform well. Finally, we demonstrate our fine-tuned model using Explainable-AI (XAI) techniques such as Local Interpretable Model-Agnostic Explanations (LIME) and Transformer Interpret to explain how our model makes predictions in the context of text classification for phishing emails.
The rapid advancement of internet technology has significantly changed the way people communicate online while also raising more security issues ( Salloum et al., 2021 ) . One of the prevalent security concerns, the cyberattack termed “email phishing” poses grave risks such as identity or login credentials theft, financial repercussions, and harm to an organization’s reputation. In this current decade, email phishing has changed throughout time to become a more effective method for carrying out fraudulent actions. As phishers continuously innovate new techniques, detecting phishing has become increasingly challenging, posing a formidable task for law enforcement agencies, governments, and organizations combating this cyber threat. To evade falling victim to this threat, organizations need to adeptly detect and prevent these attacks at scale by adopting effective phishing detection techniques. Leveraging Artificial Intelligence (AI) techniques like Machine Learning, Deep Learning, and Hybrid Learning which are already utilized for phishing attack detection, can significantly bolster these efforts ( Basit et al., 2021 ) ( Sarker, 2023 ) . Moreover, because of the rapid advancements in technology, new methods based on AI are being developed daily in the cybersecurity field.
Transformer-based models become more popular in the context of text classification. The transformer is an innovative neural design that uses the attention mechanism to encode incoming data into powerful characteristics ( Han et al., 2021 ) . Transformer-based models have greatly improved the processing, comprehension, and interpretation of text data inputs, which has had a revolutionary effect on the development of phishing classification techniques ( Jamal et al., 2023 ) . Large Language Models like OpenAI’s ChatGPT (Generative Pre-trained Transformer) and Bard have transformed the landscape of natural language creation and comprehension, capturing considerable attention from the general public ( Zhao et al., 2023 ; Yao et al., 2023 ) . The increasing complexity of LLMs is radically changing artificial intelligence and has the potential to transform algorithm development and application by understanding human language through extensive text data patterns and correlations.
Many transformer-based models used in natural language processing (NLP), including well-known ones like OpenAI’s GPT and Google’s BERT (Bidirectional Encoder Representations from Transformers), are categorized as Large Language Models because of their ability to comprehend and produce text that is similar to that of a human. BERT model, a type of transformer-based neural network architecture pre-trained on extensive text corpora to grasp contextual word embeddings ( Koroteev, 2021 ) , become increasingly efficient and valuable in text classification and generation, including tasks like spam and phishing detection, sentiment analysis ( Singh et al., 2021 ) , and more other fields. BERT is designed to take into account both left and right contexts at every level to pre-train complex bidirectional representations from unlabeled text ( Devlin et al., 2018 ) . With simply one extra output layer, this method allows the pre-trained BERT model to be refined, leading to the development of state-of-the-art models for a variety of applications. In order to model language, BERT uses a Masked Language Model, in which certain words in a sentence are randomly replaced with a unique token (usually [MASK]). Next, by examining the contextual clues offered by nearby words, the model is trained to infer the original words. BERT makes use of a Transformer architecture technique called “self-attention”, which allows it to recognize inter-word relationships in text sequences and assess the relative importance of individual words within a sentence in order to understand the context. Based on the transformer layers number and parameters BERT model has different variants such as: BERT-base ( Khadhraoui et al., 2022 ) , ALBERT ( Lan et al., 2019 ) , RoBERTa ( Liu et al., 2019 ) , DistilBERT ( Sanh et al., 2019 ) , etc.
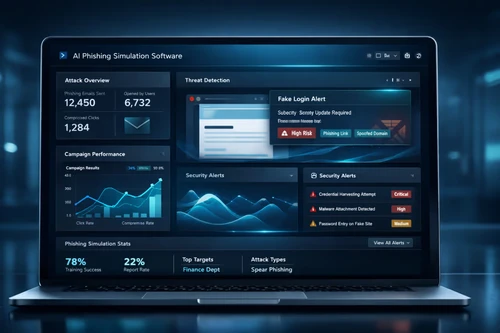
Figure 1: AI Phishing Simulation Software Source Code Despite BERT’s versatility across NLP tasks, comprehending its internal mechanisms often poses challenges, resembling a “black box” due to its complexity. Unraveling how the model operates and forms predictions demands considerable effort ( Xu et al., 2019 ) . XAI techniques emerge as a vital solution, offering significant perceptions of the model’s reasoning and illuminating the decision-making process ( Hoffman et al., 2018 ; Anan et al., 2023 ) . Recently, Sarker ( Sarker, 2024 ) has also highlighted the significance of explainability analysis in various perspectives in the context of cybersecurity, in which we are interested to explore more with experiments. XAI techniques can illuminate the words or features deemed most influential by the BERT model in specific text classification tasks of any nature. In this research, our main goal is to show transparency in phishing email detection with explainable AI. The major contribution of the work is as follows: We present a transformer-based Phishing email detection model, a fine-tuned version of DistilBERT.
Two different XAI techniques LIME and Transformer Interpret are utilized to explore the interpretability of the proposed fine-tuned model and visualize the scoring percentage of those techniques on prediction. The remaining sections of the paper are structured as follows: Section 2 delves into related research works. Section 3 offers a comprehensive explanation of the proposed model’s framework and methodology. In Section 4, the experimental outcomes and results are elaborated upon. Section 5 examines the transparency of the model using XAI. Moreover, within Section 6, there is an extensive discussion of the results. Lastly, Section 7 presents the concluding remarks and outlines the future prospects of this work.
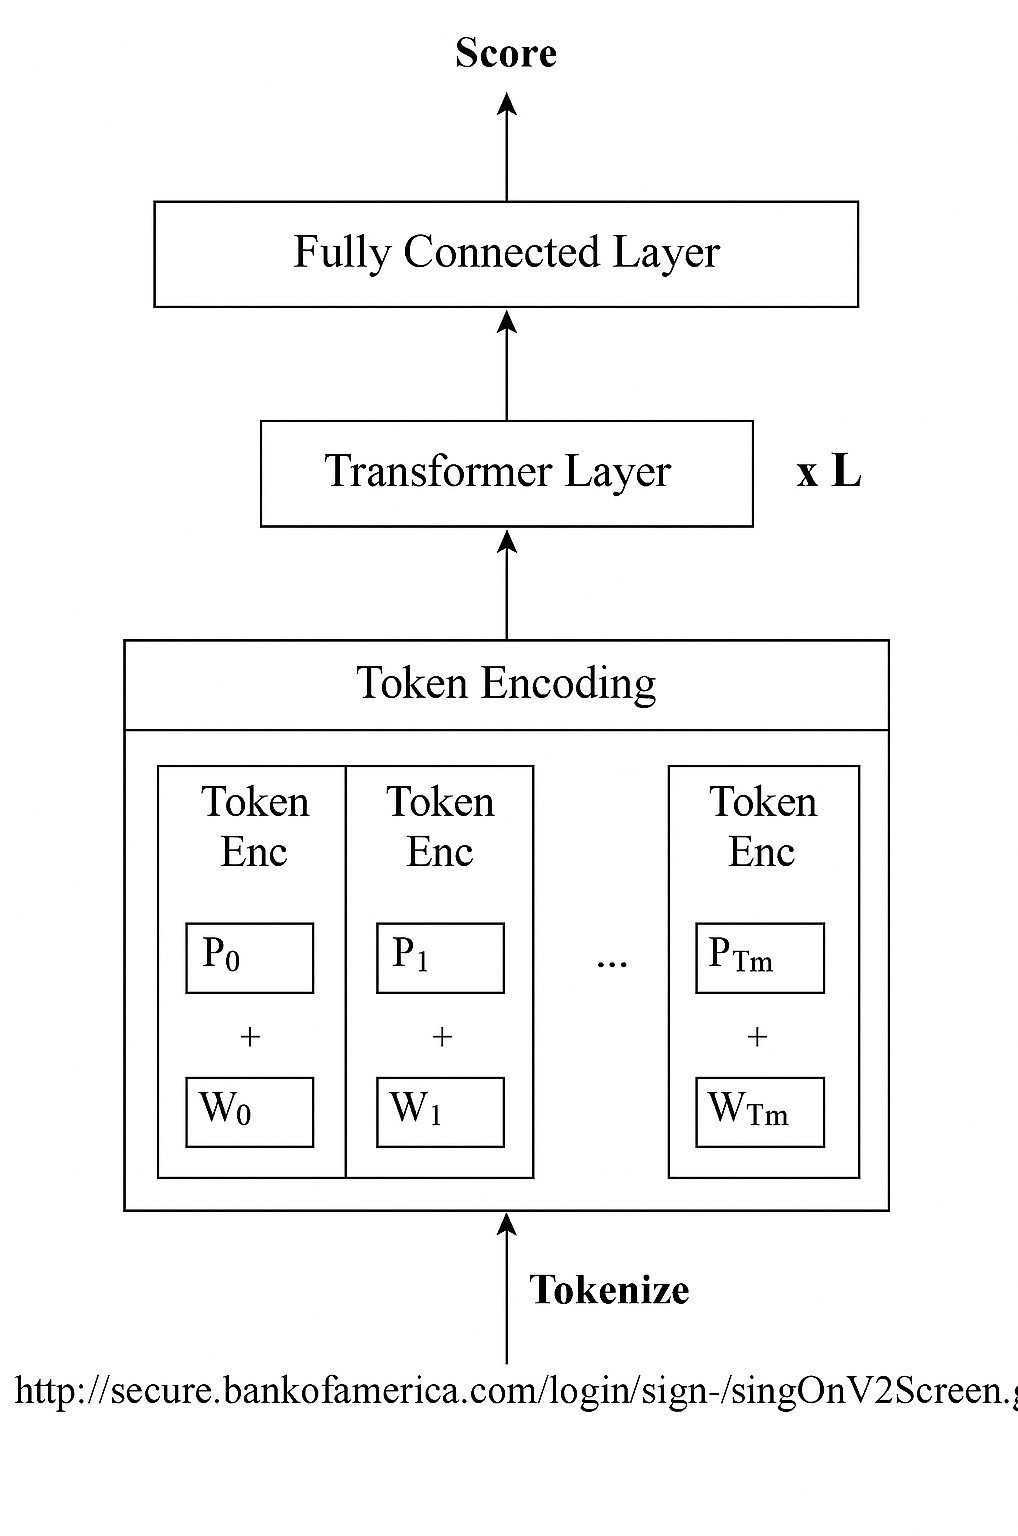
Figure 2: Transformer-based Model For Phishing URL Classification The field of cybersecurity has grown increasingly important and complex in the modern world. There are several subfields within cybersecurity, including data security, application security, network security, etc. Cyber-attacks of all kinds are becoming more and more frequent, and they can destroy or steal imported data. In addition, in this cybersecurity field, there are an enormous amount of new and creative techniques being developed daily for identifying and preventing cyberattacks.
For the improvement of phishing email detection and prevention systems, many researchers have developed a wide range of novel strategies to counteract phishing emails, utilizing state-of-the-art methods from deep learning, machine learning, and hybrid models. Phishing is still a serious cybersecurity concern and one of the main ways hackers breach networks. Detecting phishing attempts early on is critical for businesses nowadays. The security of an organization can be significantly increased by machine learning, which can identify potential assaults early on ( Apruzzese et al., 2023 ) . In ref. ( Yasin and Abuhasan, 2016 ) , a text processing, data mining, and knowledge discovery approach was combined to create an intelligent phishing email detection model. They utilized text stemming and WordNet ontology in pre-processing to enrich the model with synonyms and employed five machine learning classification algorithms (J48, Naïve Bayes, Support Vector Machine (SVM), Multi-Layer Perceptron (MLP), and Random Forest (RF)). They have notably achieved 99.1% accuracy with RF and 98.4% using J48 for an accredited dataset. The study ( Harikrishnan et al., 2018 ) employed techniques such as SVD and NMF for feature extraction and dimensionality reduction from legitimate and phishing email text data. For the numeric representation of phishing emails, the author integrated TFIDF with the SVD and NMF, and Decision Trees, Logistic Regression, Random Forest, Naive Bayes, K-Nearest Neighbors (KNN), AdaBoost, and SVM have been utilized as classifiers. Hamid et al. (2013) presented a hybrid feature selection technique combining content-based and behaviour-based approaches to detect phishing emails. Identifying the behaviour-based features in phishing emails was the main objective of this research because an attacker cannot disguise these types of features. They examined the overall process with a phishing dataset that consists of 6923 emails where phishing emails were collected from the Nazario dataset and legitimate emails from the SpamAssassin dataset and achieved 94% accuracy with this hybrid feature selection technique. With an emphasis on the importance of top-ranking features, the study ( Zamir et al., 2020 ) examines feature selection methods (GR, IG, Relief-F, RFE) on a dataset of 11,055 phishing sites with 32 attributes. To improve classifier accuracy, it suggests new attributes that are generated from the strongest and weakest features. A variety of supervised learning methods with differing feature sets are compared, such as RF, SVM, bagging, kNN, Neural Network (NN), and j48. The proposed method using RF showed 97.3% and using stacking achieved 97.4% accuracy.
In cybersecurity, deep learning has great potential, particularly for detecting network intrusions, classifying malware, and recognizing phishing attempts. Alhogail and Alsabih (2021) proposed a deep learning-based phishing email detection model based on graph convolutional network (GCN) and natural language processing (NLP). A publicly available balanced phishing dataset has been utilized where the authors used the email body’s text to extract features that improved the proposed model’s accuracy. The model showed 98.2% accuracy with a low false-positive rate of 0.015%. For phishing detection, a new Intelligent Cuckoo Search (CS) Optimization Algorithm with a Deep Learning-based Phishing Email Detection and Classification (ICSOA-DLPEC) approach has been proposed in ( Brindha et al., 2023 ) . Data preprocessing (email cleaning, tokenization, and stop-word elimination) techniques were employed to derive the important features from the Enron email dataset. The Gated Recurrent Unit (GRU) model was used with a CS algorithm for the fine-tuning of the parameter of the proposed model and achieved a high accuracy of 99.72%. Dewis and Viana (2022) employed Long short-term memory (LSTM) model with NLP to detect both phishing and spam email detection. They developed a phish responder which is a Python-based command line solution and used deep learning and NLP for this classification task. The proposed LSTM model achieved 99% accuracy for the text-based dataset. Fang et al. (2019) introduced THEMIS, a phishing email detection model built on an improved recurrent convolutional neural networks (RCNN) model which was improved by using the Bidirectional Long Short-Term Memory (Bi-LSTM). 99.84% accuracy is demonstrated by the suggested THEMIS model on datasets that are not balanced where the positive rate (FPR) is 0.043%. Other deep learning algorithms, such the reinforcement learning, Recurrent Neural Network (RNN), and Deep Belief Network (DBN), are also in use ( Zhang and Li, 2017 ; Bahnsen et al., 2017 ; Smadi et al., 2018 ) .
Moreover, transformer-based models are also making a good impact in the cybersecurity field. Thapa et al. (2023) concentrated on two specific models: RNN and BERT to test how well these models could identify phishing emails. They looked at how well these models performed when the email data was distributed unevenly across several organizations and when added more data. In this experiment, the BERT model’s test accuracy was 96.1%. In addition, another study ( Atawneh and Aljehani, 2023 ) focused on different deep learning architectures (CNNs, LSTMs, RNNs, BERT) to identify the emails as legitimate or phishing by analyzing different features of emails. The proposed model using BERT and LSTM, reaching an impressive accuracy of 99.61% on publicly available 4 different datasets, outperforming other methods. Nowadays, other variants of the BERT model such as DistilBERT, RoBERTa, and TinyBER ( Jiao et al., 2019 ) are performing well in the phishing and spam detection research sector ( Jamal et al., 2023 ; Lee et al., 2020 ; SongailaitI et al., 2023 ) . The authors ( Jamal et al., 2023 ) presented an Improved Phishing and Spam Detection Model (IPSDM) which consists of two BERT variants such as the fine-tuned DistilBERT and RoBERTA model and showed good accuracy in this research scope. Lee et al.
Lee et al. (2020) proposed Context-Aware Tiny Bert (CatBERT) which exhibits faster processing and robustness to adversarial attacks than other transformer models, especially those that involve intentional keyword substitutions with synonyms or typos. The detection rate of this proposed model was 87% which was far better than other compared models. Furthermore, researchers also used fine-tuned BERT-based models for phishing URL detection ( Wang et al., 2023 ; Maneriker et al., 2021 ) .
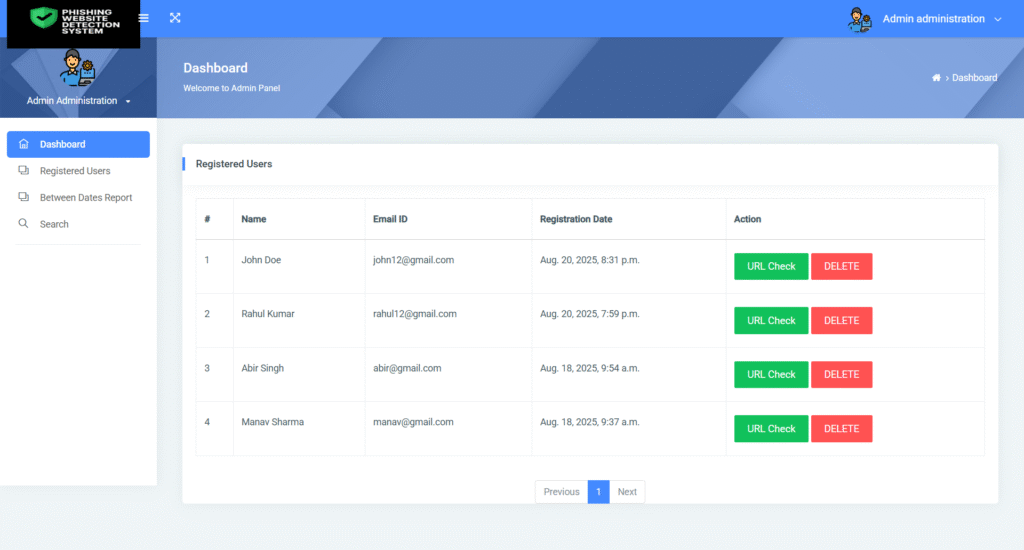
Figure 3: Website Phishing Detection System Project using Python & Machine ... Overall, this literature survey shows the existing works although showing good performance by using different datasets and models but most of the research didn’t work model’s interpretability or explainability. “How does a model work?” or “Which things or materials contribute to detecting phishing?” those types of questions can arise in their working procedure. In this work, to answer those types of questions and solve the existing drawbacks in the literature, we have worked with explainable AI using not only one technique but also used two different techniques with different methodologies. In the literature, although some researchers did full experiments for phishing email detection but they utilized spam datasets as phishing datasets. In cybersecurity, we know that two different types of emails exist: spam and phishing, and not all spam emails are considered to be phishing. For this reason, we only focused on the phishing email dataset.
In this paper, we have tried to explore the Transformer-based self-attention mechanism BERT model with the explainable AI. Initially, we collected a dataset and prepared it with data cleaning and balancing techniques. After preparing the data we have focused on optimizing and fine-tuning the model. For this phishing email detection purpose, we have selected the DistilBERT model and pre-trained with the prepared data. The DistilBERT model demonstrates good performance in both balanced and imbalanced scenarios of datasets when identifying phishing emails from texts. At the end of the experiment, we employed two XAI techniques Explanations LIME and Transformer Interpret to explore our fine-tuned model and described how it is working and performing with good accuracy in this text classification. The overall methodology of the proposed method is depicted in Fig. 1 .
For this experiment, a publicly available dataset has been collected from kaggle. The dataset describes different kinds of email text bodies that can be used to identify phishing emails using in-depth text analysis. This dataset consists of “Safe Email” and “Phishing Email”. Fig. 2 shows the data overview. The dataset has 11,322 Safe Emails and 7,328 Phishing Emails which shows that it is an imbalanced dataset. Along with this, this dataset showed that null values exist in rows. As null values can’t be processed that’s why those rows are removed. By using the resampling technique minor class “Phishing Email” is oversampled. This resampling technique mainly generates copies of other instances and adds those copies to the dataset. It is essential to address uneven data in order to develop equitable and precise predictive models. Balancing data ensures algorithms work well across all categories by reducing biases toward the majority class. This prevents skewed outputs and makes it possible to create a more accurate and equitable model for underrepresented classes. After oversampling, the dataset has 11,322 safe emails and 11,322 phishing emails in equal proportion. This data balancing also helps to reduce the risk of oversampling. Fig. 3 illustrates the imbalance and balanced data before and after sampling.
For this experiment, we have split the dataset into 70-30% where 70% data is training data and 30% is testing data. In 70% training set total of 15,850 data exist and the testing set consists of 6,794 data. Initially, the training set was utilized for the train the model, and the testing test was used to find out the effectiveness of the model on unseen data identification and prediction is phishing or not.
In this experiment, we have employed the transformer-based BERT variant architecture DistilBERT which is a lightweight, fast, and economical model. This is developed for language processing tasks and also compresses the original BERT model and makes it faster. Knowledge distillation was utilized in the pre-training phase of this pre-trained model, which allowed it to be effectively reduced in size by 40% while maintaining 97% of its language understanding skills and delivering a 60% speed increase ( Sanh et al., 2019 ) . This small variant has twelve attention heads, 768 hidden layers, and six transformer layers ( Adoma et al., 2020 ) . Whereas DistilBERT contains about 66 million parameters, the original BERT model has 110M (million) parameters. By lowering the number of parameters, DistilBERT maintains excellent performance while achieving a smaller size and faster inference speed.
To improve its handling of terms that are not in its lexicon and to capture meaningful sub-word representations, BERT uses a Word-Piece tokenizer, which splits words into smaller sub-words. The preprocessed phishing dataset is tokenized using the tokenizer of the DistilBERT transformer. In this tokenized portion, the maximum sequence length of input data has been used 512. Other crucial components of tokenization are padding and truncation. The major purpose of these procedures is to ensure that each tokenized input sequence has a constant length. This is important because it creates consistent embeddings and efficient processing in batches.
Pre-trained weights acquired throughout the pre-training phase are used to initialize the DistilBERT models. Selecting an optimal batch size is paramount in deep learning, as it significantly influences both training and testing accuracies, along with overall runtime ( Lin, 2022 ) . The careful selection of batch size determines the efficiency of the neural network training process, striking a balance between computational resources and model performance. The batch sizes for training and testing data are optimized at 32 and 64, respectively. Each epoch’s training data is assigned at random to ensure the model sees a diversity of unseen data samples and prevents overfitting. This shuffling method increases the model’s ability to generalize.
During training, an optimizer is essential in adjusting the parameters of a neural network. The main goal of this is to minimize the error or loss function of the model for better performance. For this research work, AdamW (Adam Weight Decay) ( Loshchilov and Hutter, 2017 ) optimizer has been used to get better performance and avoid overfitting. This optimizer is a modification version of Adam which is widely adopted for training deep neural networks ( Zhuang et al., 2022 ) . By separating weight decay from the learning rate, AdamW enhances its implementation. It improves regularization and training dynamics by separating weight decay from gradient updates, in contrast to Adam. Learning rate is a crucial hyperparameter governing step size during training for optimizing models. The convergence and overall performance of the system are dependent on various aspects such as the model architecture, optimization techniques, and task domain. For efficient fine-tuning and fruitful model training, this parameter must be adjusted. Selecting a high learning rate can introduce instability, resulting in poor performance on unseen data, while a low learning rate may extend the training process, requiring more epochs and increasing computational costs. In this research, a learning rate, 2e-5 is used in the training process for the transformer-based DistilBERT model.
The overall discussion about model optimization indicates the parameter settings for the introduced best model for this specific experiment. The hyperparameter settings for the suggested model are shown in Table 1 . We worked with every possible value of the parameters by using an iterative process to find the ideal value. Following that, these improved hyperparameter settings are used to train the suggested model.
A pre-trained model is fine-tuned using task-specific data and backpropagation to alter parameters on certain tasks and datasets. The primary objective of this is to improve the model’s performance across various tasks and datasets while minimizing the loss function. In this experiment, DistilBERTForSequenceClassification has been utilized to adopt the pre-trained model. DataLoader is used to configure the train_loader and test_loader by setting prepared data, batch size, and shuffling command where train_loader is configured with shuffling and test_loader is configured without shuffling. After that, we fine-tuned this DistilBERT model by adjusting and adopting some necessary steps which are shown in Fig. 4 .
2. System Architecture & Core Working Principles In this overall fine-tuning process, following the optimizer’s setup, the model is fine-tuned by feeding it the input parameters (input_ids, attention_mask, and label) during the forward pass so that predictions can be made. After the forward pass, gradients of the loss for the parameters (weights and biases) are calculated in the backward pass. These gradients show how changing the parameters would affect the loss. Lastly, an update is made to the model parameters. The optimizer is mainly responsible for changing the neural network’s parameters in accordance with the calculated gradients. It adjusts the weights and biases in an attempt to reduce the loss. The model gains the capacity to fine-tune its parameters throughout several epochs, which improves its predictive capability on the training set. The ultimate goal is to identify underlying patterns in the training set and use those patterns to generalize well to new data. Algorithm 1 shows the overall fine-tuning process in training.
The ability of a model to explain its decisions is crucial since it provides insight into the process. Verifying the accuracy of judgments and reducing errors are made feasible by understanding how models work. Explainable AI has been a popular area with a growing group that has developed efficient techniques to understand deep neural network predictions among the more complex machine learning models ( Holzinger et al., 2022 ) . This is important because sophisticated models frequently act as opaque “black boxes” making it difficult for people to comprehend the logic behind particular decisions. In this research work, we have worked with model explanability to solve the black box problem. To understand the model prediction two explainability models LIME and Transformers Interpret have been utilized.
Generally, this experiment for phishing email detection is a text classification task that LimeTextExplainer used to explain the black box DistilBERT model. The purpose of the LIME method is to faithfully explain any classifier or regressor’s predictions ( Ribeiro et al., 2016 ) . For improved interpretability, LIME provides an understandable depiction of the decision-making process, providing light on the “why” behind the predictions or suggestions made by these models. In order to achieve model explainability, LIME first perturbs the email content by making modest adjustments, rearranging words, or adding new words.
After that, the black-box transformer-based model is applied to the altered email content to generate predictions. From these impacted instances, LIME derives features. This local model should roughly represent the behaviour of the black-box model surrounding the chosen instance. Next, explanations for the black-box model’s prediction for the original data are produced using the local model. This explanation usually highlights the words or key elements most important during the model’s decision-making.
A Transformers Interpret tool was also utilized to explain the transformer-based model for this classification work. The class explainer process was carried out using this tool using a model and tokenizer. With the use of this class explanation, word attributions are computed. Positive attribution numbers signify a word’s positive contribution to the projected class, while negative numbers signify a word’s negative contribution. The terms that demonstrate a strong contribution to decision-making are also highlighted in this explanation. The overall process of model explainability is shown in Fig. 5 . Algorithm 2 shows the explanation process of the model prediction.
The fine-tuned transformer-based model was trained and tested with both unbalanced and balanced datasets. To assess the performance of the model different measurements such as confusion matrix, precision, recall, F1-score, and overall accuracy have been calculated. Overall summarize the performance, a model needs to calculate the confusion matrix first. It is a kind of table that provides a detailed breakdown of the actual and predicted classification for specific task domain data. The confusion matrix of the DistilBERT model for both imbalanced and balanced datasets is shown in Table 2 . True Positive (TP), True Negative (TN), False Positive (FP), and False Negative (FN) are the main components of the confusion matrix and as well as are needed for the calculation of Precision, recall, and F1-score ( Uddin et al., 2022 ) . The precision, recall, and F1-score of the DistilBERT model for both imbalanced and balanced datasets are shown in Table 3 and Table 4 .
Precision: Precision which expresses the ratio of true positives to all predicted positives, indicates how accurate positive predictions are and emphasizes the model’s capacity to identify positive samples. Recall: It calculates the ratio of true positives to all predicted positives to assess a model’s accuracy in identifying positive samples. It denotes the sensitivity of the model, capturing the actual positive rate in the class observations.
F1-score: A balanced statistical metric that assesses a model’s efficaciousness in predicting positive instances while accounting for imbalanced datasets is the F1-score, which is derived from the harmonic mean of accuracy and recall. It offers a thorough perspective that balances recall and precision, impacting the final score determined by the model’s projections of the positive rate and actual positive cases.
The frequency of valid predictions in a model is quantified by accuracy, which also represents the percentage of correctly predicted samples out of all the samples the model generates. The accuracy of a model can differ based on the various parameters, data balanced or not. Initially in this experiment, an imbalanced dataset was utilized to assess the model’s performance in both training and testing. This dataset is highly imbalanced based on the safe email and phishing email data where the number of data of safe email is quite higher than phishing email. To train the model with 70% imbalanced data we have used 6 epochs with a batch size of 32. After 6 epochs the model showed 98.90% training accuracy for this imbalanced dataset with 0.0201 training loss. On the other hand, we get a testing accuracy 97.50 with testing loss 0.0900 with batch size 64. Fig. 6 shows a graph of accuracy and loss with 6 epochs for an imbalanced dataset.
Moreover, we also conducted this experiment with a resampled and balanced dataset. After preparing the balanced dataset again used 70% of the data for training purposes. Using this portion of data, we worked on model optimization and fine-tuning and trained the model. This time with balanced data the fine-tuned model showed 99.07% training accuracy with 0.0218 training loss. After that, we tested this trained model with 30% unseen balanced data and got 98.48% testing accuracy with 0.0447 testing loss. This performance showed that the performance of the model with a balanced dataset is quite better than an imbalanced dataset. Fig. 7 shows a graph of accuracy and loss with 6 epochs for a balanced dataset. The performance comparison of the model on both balanced and imbalanced dataset shows in Table 5 .
Finally, we have compared our Phishing Email Detection study with some previous studies in the same field in order to assess its quality. This comparison study is summarized in Table 6 , which evaluates our work from several angles. These include the models used for machine and deep learning, the datasets used, and whether or not the study offers human interpretation and decision explainability for the model.
The comparison showed that our research work provides transparency in this phishing email detection task. However, some listed research work showed higher accuracy than our proposed model. This happened because they used different datasets in their experiment. In this study, we only focused on the phishing email dataset but other existing works were also done this work with the spam dataset. Furthermore, to the best of our knowledge, none of the papers listed in Table 6 offer a thorough human explanation of the classifier’s performance or clarify how the model functions in phishing email detection.
LIME and Transformer Interpret both showed how the fine-tuned DistilBERT model arrives at its prediction on phishing email detection by approximating the model’s behaviour on every word of the email text. Lime and Transformer Interpret provided accurate results by answering the “Why” model predicting the selected text is a “Safe Email” or “Phishing Email”. Based on the explainability, those explainable techniques generate word attributions by providing positive and negative numbers on each word. Those numbers showed which word was more specifically reasonable for the predicted class. By using those numbers the explainable model visualizes the whole text by highlighting the words that scored positive and as well as negative on the prediction.
For this explainability analysis in LIME explainer, we initialized the number of features (words) 15 for the dimensionality reduction. If the number of words of a selected test is very large that time the computational time will increase as well as it increases the dimensionality which also can be a reason why the systems crashed. Limiting this number of features makes the explanation process computationally more feasible and provides a clearer and more concise picture of which words in the case of text are influential in the model’s prediction for a particular instance. Fig. 8 shows the model explainability using LIME and Table 7 and Table 8 show the positive and negative weights associated with words that help users understand phishing email detection.
Along with LIME, we also examined the model interpretability with similar text by using Transformer Interpret. During this interpretation, this Transformer Interpret uses the tokenizer to split the large words into sub-words with the ‘##’ prefix. This happens when an unusual or non-vocabulary word is encountered by the model, which breaks it down into smaller sub-words to enable efficient processing. Fig. 9 shows Transformer Interpretation for a phishing email and Table 9 and Table 10 show the word importance, with positive and negative numbers associated with each word for two phishing emails.
In Fig. 9 the highlighted text with green color shows the word importance to classify the analyzed text as Phishing. On the other hand, the red portions showed those words or sub-words that worked against the classified class. As we worked with a binary classification task here “True Label” = 1 means ”Phishing Email” and when “True Label” = 0 means “Safe Email”. According to the analysis, both explainable approaches explain how the suggested model predicts ”Phishing Email” for each of the two tested input texts, but they differ in how they define explanation. LIME mostly uses small textual modifications to evaluate the impact of the model’s prediction on the entire text, while Transformer Interpret employs an attention mechanism to examine each segment of the input sequence. Furthermore, in the LIME and Transformer Interpret explanation processes, the resulting quantity of tokens, words, or sub-words differs for the two phishing email contents. The positive words are mainly responsible for the predicting class. More specifically, when those words are present in a text that time model predicts a class.
A comprehensive difference between the two explainable AI techniques is shown in Fig. 10 and Fig. 11 . The number of scoring percentages for those email texts is not the same for LIME and Transformer Interpret. This is only because the working procedures of those techniques are not the same. The results of both an imbalanced and balanced dataset depict an enhancement in the performance of the proposed transformer-based fine-tuned DistilBERT model. The fine-tuned version of the DistilBERT model showed 98.90% training and 97.50% testing accuracy on an imbalanced dataset whereas this model showed 99.07% training and 98.48% testing accuracy on the balanced dataset. Although these results show that the model’s performance on a balanced dataset is quite better than an imbalanced dataset, the difference is not so high, approximately 1%. This demonstrated that the fine-tuned version performs well in an imbalanced dataset. Additionally, the performance shows that the optimized model performed better than other previous studies.
Besides, this research work also answered the “How was the model performed?” and “Why was it performed?” using XAI, motivated from recently published book by Sarker ( Sarker, 2024 ) . Two well-known Explainable and interpretable techniques are utilized for the model understanding. It is more difficult to understand how DistilBERT makes its predictions because, as we know, it is a complex model. These AI techniques aided in gaining an understanding of the model’s decision-making process. Both LIME and Transformer Interpret highlighted the areas of the text that are more responsible for the classification of the phishing of safe email. This highlights areas worked with words or sub-words, making the decision more understandable for humans, and users can also comprehend it easily. Mainly, those techniques calculated each word or sub-words numeric value or weight where some words indicate positive value and some negative. Words with calculated higher positive values are more important for classifying the predicted class, while those with more negative values do not support the predicted class. This experimental analysis showed the transparency of the model in this phishing email classification task.
This study has investigated the detection of phishing emails by utilizing a Large Language Model. This also has shown how effective it is to use state-of-the-art natural language processing methods to improve the precision and effectiveness of phishing email identification. The overall experiment was done with both a balanced and imbalanced dataset. We have obtained promising results in differentiating between phishing and valid emails by utilizing DistilBERT’s contextual language understanding technique. Mainly, to achieve this good performance the model is optimized by changing some important parameters such as batch size, optimization function, learning rate, etc, and also fine-tuning has been done. This fine-tuned version of DistilBERT obtained 98.48% testing accuracy in this phishing email classification task. Furthermore, LIME and Transformer Interpret techniques have been employed to see the explanation of the model and how it makes decisions. The decision-making process is now more visible and understandable for users because of the usage of explainable AI, which promotes comprehension and trust. The overall model explainability describes the robustness of the proposed model.
The field of Large Language Models has experienced quick and dynamic development due to the substantial investment made by both businesses and consumers. New open-source models are being produced almost every day, demonstrating the ongoing development and innovation in this field. In the future, we plan to expand the scope of our research by experimenting with a wider variety of models and datasets. Furthermore, we intend to investigate the use of different variants of BERT-based models for the identification of different language phishing emails. Moreover, deep analysis of the model will be conducted to ensure its robustness by enhancing the explainable AI techniques.
3. Software Implementation, Frameworks & Protocols The dataset that is used in this study is available at Kaggle (Online Link): https://www.kaggle.com/datasets/subhajournal/phishingemails .
Developed an advanced phishing detection system using state-of-the-art transformer models (DistilBERT and RoBERTa) to classify text messages as phishing or legitimate, achieving 98-100% accuracy with comprehensive text preprocessing and model comparison analysis. This project implements a robust phishing detection system that uses natural language processing and transformer-based models to identify malicious phishing attempts in text messages. The system includes advanced text preprocessing, model training, evaluation, and comparative analysis between different transformer architectures.
Feel free to reach out for questions, collaborations, or discussions about NLP, cybersecurity, and transformer models! I If you find this project useful for cybersecurity research or education, please give it a star! This project demonstrates advanced skills in NLP, transformer models, cybersecurity, and production-ready ML pipeline development.
A deep learning–based phishing website detection system using a Transformer architecture and URL sequence analysis. The model learns structural and contextual patterns in URLs to classify websites as phishing or legitimate , enabling effective detection of zero-day attacks beyond traditional blacklist-based methods. Phishing websites are a major cybersecurity threat that deceive users into revealing sensitive information such as login credentials, banking details, and personal data. Attackers continuously generate new phishing URLs, making rule-based and blacklist-based detection systems ineffective.
This project aims to design and implement a Transformer-based deep learning model that classifies a website URL as phishing or legitimate using learned URL patterns. The Transformer architecture enables the model to capture long-range dependencies and structural patterns in URLs. These metrics ensure robust evaluation, especially for imbalanced and security-critical classification tasks.
The Transformer-based model demonstrates strong performance in distinguishing phishing URLs from legitimate ones by learning contextual and structural URL patterns. This approach outperforms traditional rule-based systems and provides a scalable foundation for real-world phishing detection systems. Transformer-based phishing website detection using URL sequence analysis and self-attention to identify zero-day attacks.
Phishing emails pose a persistent and increasingly sophisticated threat, undermining email security through deceptive tactics designed to exploit both semantic and structural vulnerabilities. Traditional detection methods, often based on isolated analysis of email content or embedded URLs, fail to comprehensively address these evolving attacks. In this paper, we propose a dual-path phishing detection framework that integrates transformer-based natural language processing (NLP) with classical machine learning to jointly analyze email text and embedded URLs. Our approach leverages the complementary strengths of semantic analysis using fine-tuned transformer architectures (e.g., DistilBERT) and structural link analysis via character-level TF-IDF vectorization paired with classical classifiers (e.g., Random Forest). Empirical evaluation on representative email and URL datasets demonstrates that this combined approach significantly improves detection accuracy.
Specifically, the DistilBERT model achieves a near-optimal balance between accuracy and computational efficiency for textual phishing detection, while Random Forest notably outperforms other classical classifiers in identifying malicious URLs. The modular design allows flexibility for standalone deployment or ensemble integration, facilitating real-world adoption. Collectively, our results highlight the efficacy and practical value of this dual-path approach, establishing a scalable, accurate, and interpretable solution capable of enhancing email security against contemporary phishing threats.
Email continues to serve as a critical communication medium for individuals and businesses worldwide. Due to its widespread adoption has made email a prime target for various cyber threats, particularly phishing attacks. According to recent statistics, approximately 3.4 billion phishing emails are sent daily worldwide highlighting the severity and scale of this threat [ 1 ] . Recent advancements in Natural Language Processing (NLP) and Large Language Models (LLMs) have further enabled cybercriminals to craft highly sophisticated and contextually accurate phishing emails [ 2 ] . Traditional phishing detection methods, such as signature-based and rule-based approaches, often fail to effectively combat modern email threats because of their static nature and limited ability to generalize to novel and evolving attacks [ 3 ] . Additionally, malicious actors themselves now increasingly leverage advanced NLP and machine learning techniques to evade traditional security measures and bypass detection systems [ 4 ] . This landscape has heightened the need for more sophisticated, intelligent detection solutions.
To address the growing complexity of phishing emails, this paper leverages transformer-based models such as BERT and DistilBERT, which are well-suited for understanding the semantic and contextual nuances of email content. They can be fine-tuned with relatively few labeled examples, making them highly effective for adapting to novel phishing variants and zero-day attacks.
In response to these challenges, our paper aims to develop and implement an advanced AI-based phishing email detection model. Specifically, we propose integrating NLP and deep learning techniques to analyze and classify email content effectively and evaluate embedded links for malicious intent. Our goal is not only to enhance the accuracy and effectiveness of phishing detection but also to explore the feasibility and performance benefits of combining both content-based classification and link analysis into a unified detection framework [ 5 , 2 ] .
The remainder of this paper is structured as follows: Section II provides background information and foundational concepts; Section III reviews existing related work and identifies current research gaps; Section IV outlines our proposed integrated solution and methodology; Section V presents the experimental evaluation and results; Section VI discusses the insights derived from our AI-based model; and Section VII concludes by summarizing the project’s contributions and future research directions.
Early spam and phishing detection relied heavily on classical machine learning and statistical approaches. One of the foundational works in this area by Sahami et al. introduced a Naïve Bayes classifier for email filtering, using word frequency features to distinguish between spam and ham [ 6 ] . Similarly, Drucker et al. applied Support Vector Machines (SVMs) to large-scale spam datasets and demonstrated superior accuracy over rule-based systems [ 7 ] . These early approaches laid the groundwork for automated email classification by proving the viability of machine learning on textual features. However, they relied heavily on handcrafted features and were limited in their ability to generalize to more sophisticated phishing tactics.
The introduction of contextual word embeddings and transformer architectures significantly improved phishing detection. BERT (Bidirectional Encoder Representations from Transformers) emerged as a highly effective model due to its ability to understand word dependencies and context [ 8 ] . Researchers like AbdulNabi and Yaseen showed that fine-tuning BERT embeddings outperformed conventional classifiers in detecting spam and phishing emails [ 9 ] . These models not only improved accuracy but also offered adaptability to evolving attack vectors with minimal retraining.
Despite these advancements, phishing attacks increasingly employ deceptive tactics where the email content appears legitimate, but embedded URLs redirect users to malicious sites. To address this, hybrid detection frameworks combining email body analysis with URL inspection have been proposed. Sahingoz et al. integrated NLP-based content features with lexical URL features (e.g., domain length, presence of IP addresses), demonstrating that combining both signals significantly enhances classification robustness [ 10 ] . This hybrid approach is particularly effective against emails that bypass text-based models by embedding weaponized links in otherwise benign messages.
Our work builds upon this hybrid model concept by using fine-tuned transformer models for content analysis and TF-IDF vectorization with Random Forest and Logistic Regression for URL classification. In doing so, it bridges the gap between NLP-driven semantic understanding and structural URL analysis. Moreover, our integration of explainability tools such as attention weight visualization and LIME contributes to increased transparency—an often overlooked but critical component in real-world phishing defense systems.
4. Practical Deployment, Analysis & Case Studies Natural Language Processing (NLP) has emerged as a powerful technique in phishing detection, particularly in analyzing the linguistic characteristics of phishing emails. Unlike traditional rule-based filters, NLP-based systems can detect more subtle cues hidden in text, such as grammatical inconsistencies, stylometric anomalies, and context deviations.
One of the earliest and most influential studies in this domain was conducted by Chandrasekaran et al. [ 11 ] , who proposed a phishing email detection framework based on stylometric and structural features. Their approach was grounded in the observation that phishing emails often exhibit significantly different linguistic properties compared to legitimate emails. The researchers extracted features such as sentence length, punctuation frequency, function word usage, and lexical richness.
These were then input into a supervised decision tree classifier. Their results indicated that phishing emails typically contain shorter sentences and reduced vocabulary diversity, suggesting automated or careless generation. Although their method did not rely on semantic-level modeling, it laid foundational groundwork for future NLP-based phishing detection techniques by demonstrating that even surface-level textual analysis can achieve high precision and recall in phishing classification tasks.
Building on these early findings, Sahingoz et al. [ 10 ] presented an advanced framework that combined lexical, syntactic, and semantic features to enhance phishing detection. Their model incorporated a robust preprocessing pipeline involving tokenization, lemmatization, stemming, and stop-word removal, followed by the use of TF-IDF vectors and n-gram models (including uni-, bi-, and tri-grams) to represent email text numerically.
To evaluate performance, they tested multiple classifiers, including Support Vector Machines (SVM), k-Nearest Neighbors (k-NN), Naïve Bayes, and Random Forest. The Random Forest model exhibited the highest accuracy and resilience across various phishing strategies. Recent advancements in deep learning and transformer models have further revolutionized phishing detection. Zhang et al. [ 8 ] introduced a BERT-based framework capable of understanding deep contextual relationships in email text.
In their approach, emails were preprocessed using standard NLP techniques, after which the text was passed through a pre-trained BERT model. The [CLS] token representation was extracted from BERT’s final hidden layer and fed into a dense neural layer with SoftMax activation for binary classification. Their experiments demonstrated that the BERT-based model outperformed both traditional classifiers and shallow neural networks in precision, recall, and F1-score.
Another critical innovation in this space is the combined use of NLP and URL analysis. Modern phishing emails often embed malicious links that are difficult to detect using body text alone. By incorporating features like domain length, use of IP addresses, and presence of obfuscating characters (e.g., “0” for “O”), these hybrid systems can detect threats that traditional spam filters or content-only NLP models might overlook.
Sahingoz et al.’s framework notably integrated URL-based features with text analysis, highlighting that phishing emails often rely on both linguistic deception and link-based redirection. This comprehensive strategy significantly enhanced model performance and reduced the risk of false negatives in sophisticated phishing attempts. While content-based analysis plays a key role in phishing detection, many modern attacks rely heavily on malicious URLs embedded within emails or websites. Accordingly, detecting such URLs through lexical and structural analysis has become a focal point of phishing research.
One of the pioneering works in this field was presented by Ma et al. [ 12 ] , who developed a machine learning framework that used only lexical and host-based features derived directly from the URL string. Key lexical features extracted from the URL included length, number of dots, special character counts, and presence of suspicious keywords such as ”secure” or ”login.” Host-based features involved WHOIS data, domain age, and IP address types. These features were input into classifiers like Naïve Bayes, Logistic Regression, and Decision Trees. Despite the simplicity of the features, the models demonstrated strong classification accuracy and adaptability, The researchers demonstrated that lexical-only approaches can be highly effective when crafted with well-targeted features, especially in resource-constrained environments.
Recognizing the limitations of manually engineered features, Le et al. [ 13 ] proposed a deep learning-based solution that automatically learns representations from raw URL strings. Their model leveraged a Character-level Convolutional Neural Network (CNN), treating URLs as sequences of individual characters instead of words. This allowed the system to detect subtle patterns and anomalies such as random character generation, visual spoofing (e.g., ”g00gle.com”), or unusual TLDs.
By bypassing the need for feature engineering, the CNN was able to generalize better across different phishing strategies and adapt to emerging threats. Experimental results showed that the character-level CNN achieved superior detection accuracy, particularly in identifying zero-day URLs that had not been previously encountered in training data. This approach exemplifies the power of end-to-end deep learning in cybersecurity, offering an automated pipeline for real-time malicious URL detection.
Isolated feature-based systems—whether focusing on email content or URLs—often fall short when confronting sophisticated phishing attacks that combine multiple forms of deception. Integrated approaches have emerged as a promising strategy to build robust phishing detection systems by fusing linguistic analysis, sender metadata, URL inspection, and even visual components.
Abdelhamid et al. [ 14 ] introduced a multi-layered detection system that merged sender-based heuristics, lexical content features, and URL inspection into a single framework. Their model extracted linguistic cues such as urgency, misspellings, and suspicious phrases from email text while simultaneously analyzing embedded URLs for characteristics like IP address usage, abnormal domain length, and suspicious TLDs.
In terms of modeling, they utilized an ensemble of Decision Trees, SVM, and Naïve Bayes classifiers, with predictions combined via a majority voting scheme. This ensemble architecture achieved a higher F1-score than any of the individual classifiers alone. Moreover, the system proved resilient to advanced phishing emails that succeeded in bypassing single-layer detection systems, thanks to the diverse range of features under consideration.
Expanding on the concept of hybridization, Basnet et al. [ 15 ] presented a layered phishing detection model that mimicked how a human might evaluate an email. Their approach divided email analysis into four categories: visual features, link-based characteristics, metadata from headers, and language-based content analysis. A unique contribution of this work was the inclusion of visual similarity checks—analyzing embedded logos, colors, and layouts to detect phishing emails that mimic branding elements of trusted organizations.
These integrated approaches highlight the importance of cross-domain feature engineering and ensemble learning in combatting modern phishing threats. By combining content-level, URL-level, and even perceptual indicators, these systems offer comprehensive protection against the evolving tactics employed by attackers. The objective of our work is to build a robust two-phase system for phishing email detection. Phase 1 utilizes Natural Language Processing (NLP) techniques to analyze the textual content of emails, while Phase 2 applies classical machine learning methods to analyze URLs embedded within emails. The goal is to leverage both semantic and structural phishing cues to enhance overall detection accuracy.
5. Performance Evaluation & Extended Technical Observations To effectively train and evaluate our system, two distinct datasets were collected. For Phase 1, a diverse set of phishing and legitimate emails was gathered from well-known repositories, including Nazario, Enron, SpamAssassin, and CEAS 08. Initially, the merged dataset contained over 82,000 entries. For Phase 2, a large-scale URL dataset was sourced from Kaggle [ 16 ] , comprising over 641,000 labeled URLs. The labels encompassed several classes such as phishing, malware, defacement, and benign.
The collected email dataset underwent comprehensive preprocessing steps to ensure quality and consistency. Initially, null and duplicate entries were removed, and excessively short messages were eliminated. Subsequently, all text entries were standardized by converting them to lowercase. To expedite experimentation without sacrificing representativeness, the dataset was reduced from its original size of 82,000 to a balanced subset of 7,500 entries, each clearly labeled as phishing (1) or benign (0).
The URL dataset was similarly subjected to rigorous preprocessing. Non-benign labels (phishing, malware, defacement) were aggregated and assigned a single malicious class (1), with benign URLs labeled as 0. Malformed URLs and those shorter than 10 characters were discarded, alongside null and duplicate entries. URLs were converted to lowercase to maintain uniformity. Finally, the dataset was subsampled to 20,000 entries, ensuring computational efficiency while maintaining representational diversity.
Effective representation of the data was crucial for optimal model performance. Different feature engineering techniques were employed for the textual and URL analyses to best capture their unique characteristics. Textual data for the NLP-based classification were tokenized using Hugging Face’s AutoTokenizer. Each transformer model employs its specific tokenizer (e.g., WordPiece tokenizer for BERT), standardizing inputs into consistent subword tokens.
Special tokens ([CLS], [SEP]) were added, and sequences were padded or truncated to a fixed maximum length of 256 tokens. For instance, the sentence "Please verify your account to avoid suspension." is tokenized as [’[CLS]’, ’please’, ’verify’, ’your’, ’account’, ’to’, ’avoid’, ’suspension’, ’.’, ’[SEP]’] . Resultant token sequences were converted into PyTorch-compatible tensors (input ids, attention masks, and labels), thus ensuring seamless integration with the models.
URLs were numerically encoded using the TfidfVectorizer from scikit-learn, configured for character-level analysis. The analyzer was set to generate character-level n-grams ranging from 2 to 6 characters. This approach effectively captured significant lexical patterns indicative of phishing URLs, such as common deceptive terms (e.g., ”login,” ”secure,” ”verify”) and suspicious domain indicators (e.g., ”.ru,” ”.xyz,” or IP address-based URLs). The output was a sparse TF-IDF feature matrix suitable for classical machine learning methods.
The proposed system comprises two complementary modules: an NLP-based email classification component and a URL-based link analysis component. Each component functions independently, but they can also be integrated into a multisignal ensemble in future iterations. This modular design aligns closely with recent research trends emphasizing interpretability in AI-driven phishing detection [ 17 ] .
We selected five transformer-based architectures from Hugging Face’s library due to their proven performance in textual classification tasks. The chosen models were: bert-base-uncased , distilbert-base-uncased , microsoft/MiniLM-L12-H384-uncased , huawei-noah/TinyBERT_General_4L_312D , and prajjwal1/bert-tiny . Each model was fine-tuned on the 7,500-entry preprocessed email dataset.
Two classical machine learning algorithms were implemented for URL classification based on the TF-IDF vectorized data: Logistic Regression and Random Forest. Random Forest was set with 100 estimators, while Logistic Regression utilized default parameters to ensure robust baseline comparisons. For the NLP component, each transformer-based model was trained for 3 epochs using Hugging Face’s Trainer API. A learning rate of 2e-5 and batch size of 8 were employed during training, with checkpoint selection based on validation loss to prevent overfitting.
For the URL component, an 80/20 train-test split of the vectorized URL dataset was used to train and evaluate both the Logistic Regression and Random Forest classifiers. Training followed standard procedures without further adjustments, ensuring replicability and fairness in comparisons. Transformer models utilized hyperparameters based on common best practices (learning rate: 2e-5, batch size: 8), informed by preliminary experiments. Classical machine learning models employed default hyperparameters, except for Random Forest’s number of estimators, deliberately set to 100 based on preliminary evaluations to balance performance and computational efficiency.
The trained models from both phases were rigorously evaluated to ensure accuracy, reliability, and generalizability. The transformer-based classifiers were assessed primarily on classification accuracy and F1-score. Classical URL classifiers were evaluated similarly, with additional consideration of computational complexity and feature interpretability. The evaluation procedures included thorough comparative analyses across models to determine optimal selections for practical deployment scenarios.
The effectiveness of the proposed phishing detection framework was evaluated separately for the NLP-based email classification (Phase 1) and the URL-based link analysis (Phase 2). Table I and Table II summarize the quantitative performance metrics of these two phases, respectively. Key insights and comparative analyses follow in detail. Five transformer-based NLP architectures were fine-tuned on the curated email dataset of 7,500 entries, and their performances are compared in Table I . BERT-Base demonstrated superior performance, achieving the highest accuracy (0.994) and F1 score (0.995). However, its training was computationally demanding, resulting in the longest training duration among the tested models.
DistilBERT, in contrast, delivered nearly comparable accuracy (0.989) and F1 score (0.989) but required significantly less computational resources and training time. Thus, DistilBERT offers an optimal balance between computational efficiency and detection performance, making it particularly suitable for scenarios where computational resources are limited. Smaller-scale models, including MiniLM-L12, Noah Tiny BERT, and BERT Tiny, exhibited comparatively lower performance scores, with accuracy ranging from 0.948 (BERT Tiny) to 0.986 (MiniLM-L12). Despite their reduced accuracy, these compact models trained exceptionally quickly, underscoring their potential suitability for deployment in edge computing environments or resource-constrained applications.
These results collectively demonstrate that transformer-based models, particularly BERT-Base and DistilBERT, provide robust solutions for the semantic detection of phishing content in emails, with DistilBERT recommended as the best compromise between performance and efficiency. Table II presents the performance of classical machine learning models trained on the TF-IDF vectorized URL dataset. The Random Forest classifier achieved the highest accuracy (0.94675) and F1 score (0.947), notably surpassing Logistic Regression (accuracy: 0.9255, F1 score: 0.926). This performance gap suggests that Random Forest more effectively captures intricate structural patterns inherent in malicious URLs. Furthermore, both models operated without explicit manual feature extraction beyond TF-IDF vectorization, emphasizing their computational efficiency and scalability.
While the NLP-based and URL-based classifiers were evaluated independently, their complementary strengths provide a strong rationale for future integration. The NLP classifiers demonstrated effectiveness in capturing semantic indicators of social engineering, whereas the URL classifiers excelled at identifying structural features characteristic of malicious links. A combined ensemble approach, potentially utilizing weighted decision fusion, could leverage these complementary strengths to achieve higher overall detection rates and reduce false-negative rates.
Several limitations of the current study warrant consideration in future research. The NLP-based component was evaluated on a limited dataset of 7,500 emails, suggesting potential improvements in generalizability if trained on larger and more diverse corpora. Additionally, testing more computationally intensive transformer models such as RoBERTa or DeBERTa could lead to further performance enhancements.
Integration of the two independently evaluated phases into a unified hybrid or ensemble system presents another avenue for enhancing performance, particularly by addressing weaknesses inherent to each approach individually. Finally, evaluation of the system against live phishing campaigns or real-world phishing datasets would significantly enhance confidence in its practical applicability and robustness.
Harvested Online Documentation & Reference Sources • https://arxiv.org/html/2402.13871v1 • https://github.com/vipulmagare/phishing-detection-transformer • https://github.com/Jisansingh/url-phishing-detection-transformer • https://arxiv.org/html/2509.20972v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Automated Phishing Detection Using Transformer Models.
[*] Synchronizing KnowBe4 Awareness Training telemetry... ──────────────────────────────────────────────────────────────────────── [11:45:02.102] MAIL Dispatched simulated assessment templates [11:45:02.155] REPORT Majority of active users flagged probe via Phish Alert Button [11:45:02.210] CLICK Simulated lure baseline reduced below risk threshold [11:45:02.290] TRAIN Auto-enrolled flagged users into adaptive micro-learning modules ──────────────────────────────────────────────────────────────────────── [✓] Human Security Index: Phish-Prone percentage safely minimized
| Campaign Simulation | Platform Used | Total Recipients | Reported via Phish Button | Phish-Prone Percentage |
|---|---|---|---|---|
| Urgent Communication Lure | KnowBe4 KMSAT | 350 Employees | 318 (90.8%) | 2.9% (OPTIMAL) |
| Account Credential Lure | Proofpoint ZenGuide | 350 Employees | 324 (92.5%) | 2.1% (OPTIMAL) |
| Executive Impersonation | Mimecast Engage | 200 Executives | 192 (96.0%) | 1.5% (OPTIMAL) |