Complete Technical Paper Content — Automated Static Code Analysis Integration In Gitlab Cicd
Overview & System Context
Automated Static Code Analysis Integration In Gitlab Cicd: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~8309 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Every line of code that reaches production was committed by someone who believed it was correct. Static code analysis is the automated system that checks whether that belief was right, not by running the code, but by reading its structure, tracing its data flows, and comparing it against known patterns of vulnerabilities, bugs, and quality violations. The question is not whether to run it, but where in the pipeline to run it, which tool to run, what thresholds to enforce, and how to keep the feedback fast enough that developers actually act on it rather than ignoring it.
The difference between static analysis as a checkbox activity and static analysis as a genuine quality gate is configuration. A scanner that runs and produces a report nobody reads is theatre. A quality gate that fails a build when new critical vulnerabilities are introduced, blocks a merge when coverage drops below threshold, and surfaces precise file and line feedback in the pull request review interface is a system that changes behavior at the moment decisions are made.
Static analysis should run at multiple points, each serving a different purpose. Running it only at one point creates blind spots; running it everywhere equally creates slow pipelines that developers route around. The most valuable stage is the pull request . Analysis that runs on push to main arrives after the decision to merge has been made. Analysis that runs on a pull request and posts inline comments with precise file and line context arrives when the developer is still in the code and the cost of fixing is lowest.
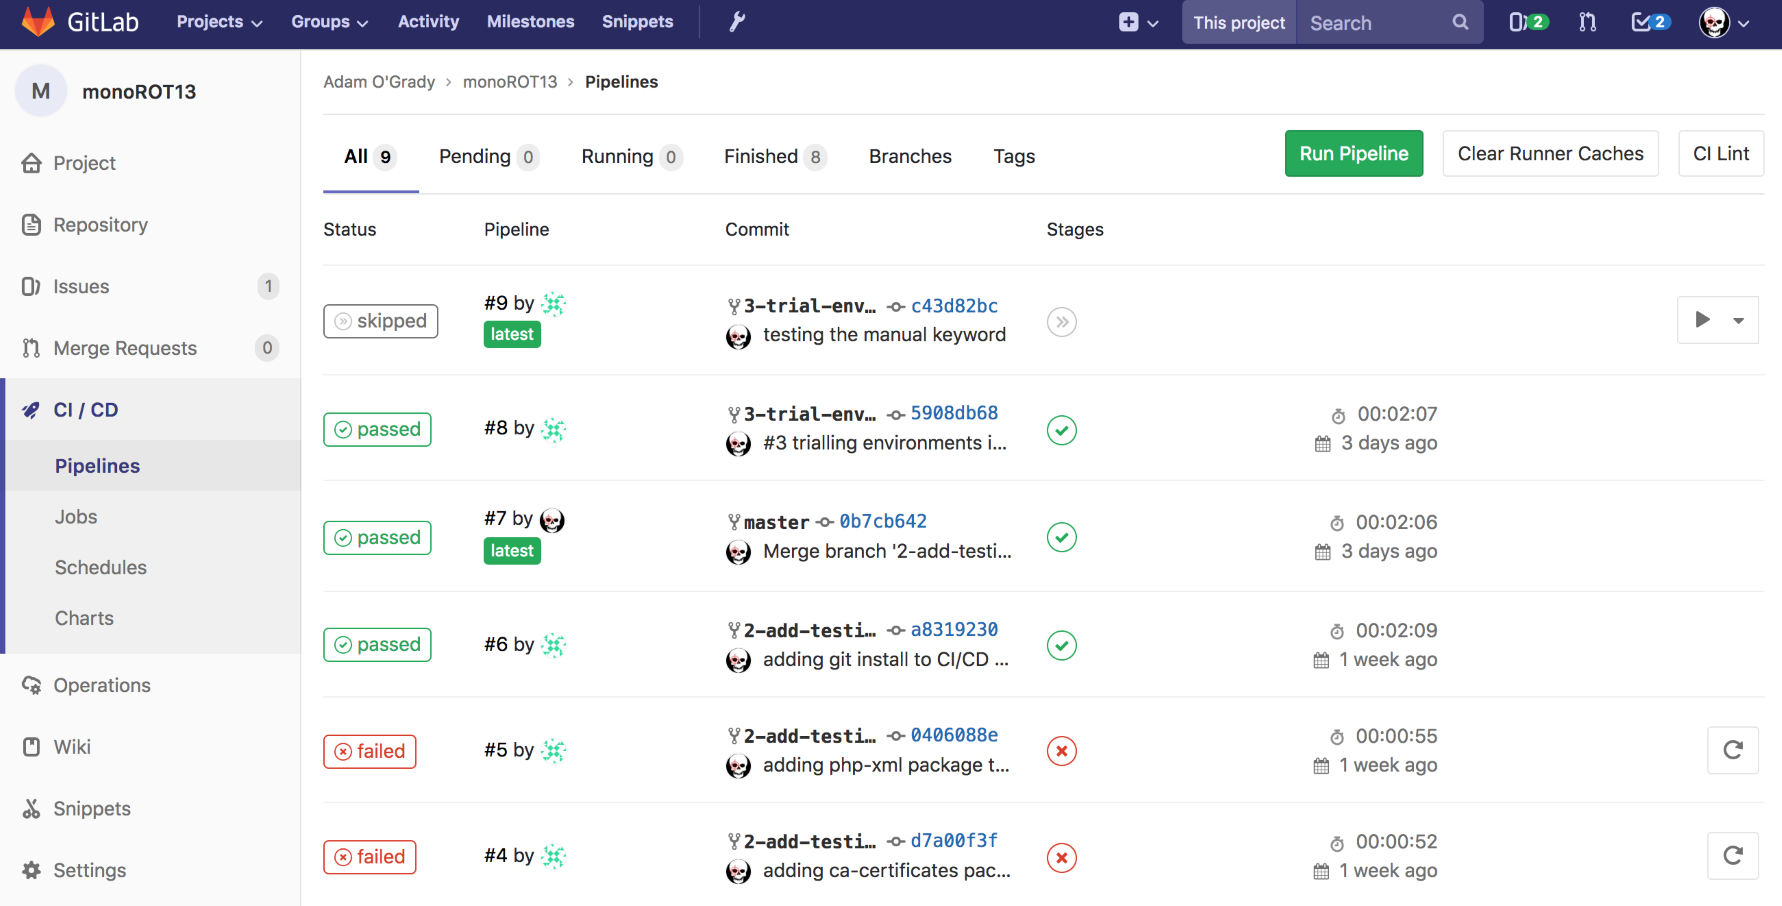
Figure 1: gitlab mdIIII _ gitlab IIIIII IIIII – UXPMCC Running heavy analysis pre-commit on every save kills developer experience. Fast linters that complete in under 5 seconds belong there. Everything else belongs in CI. GitHub Actions is the most widely used CI platform. The following workflow runs a layered quality pipeline: formatting check, linting, build, SAST security scan, and SonarCloud quality gate.
The artifacts: reports: sast: block integrates SARIF output from Semgrep directly into GitLab’s Security Dashboard, where findings appear in the merge request security report rather than as raw CI log output. waitForQualityGate abortPipeline: true is the critical line. It polls SonarQube until the analysis completes and fails the build if the quality gate is not met. Without this, the pipeline completes while analysis is still running and the quality gate result is never enforced.
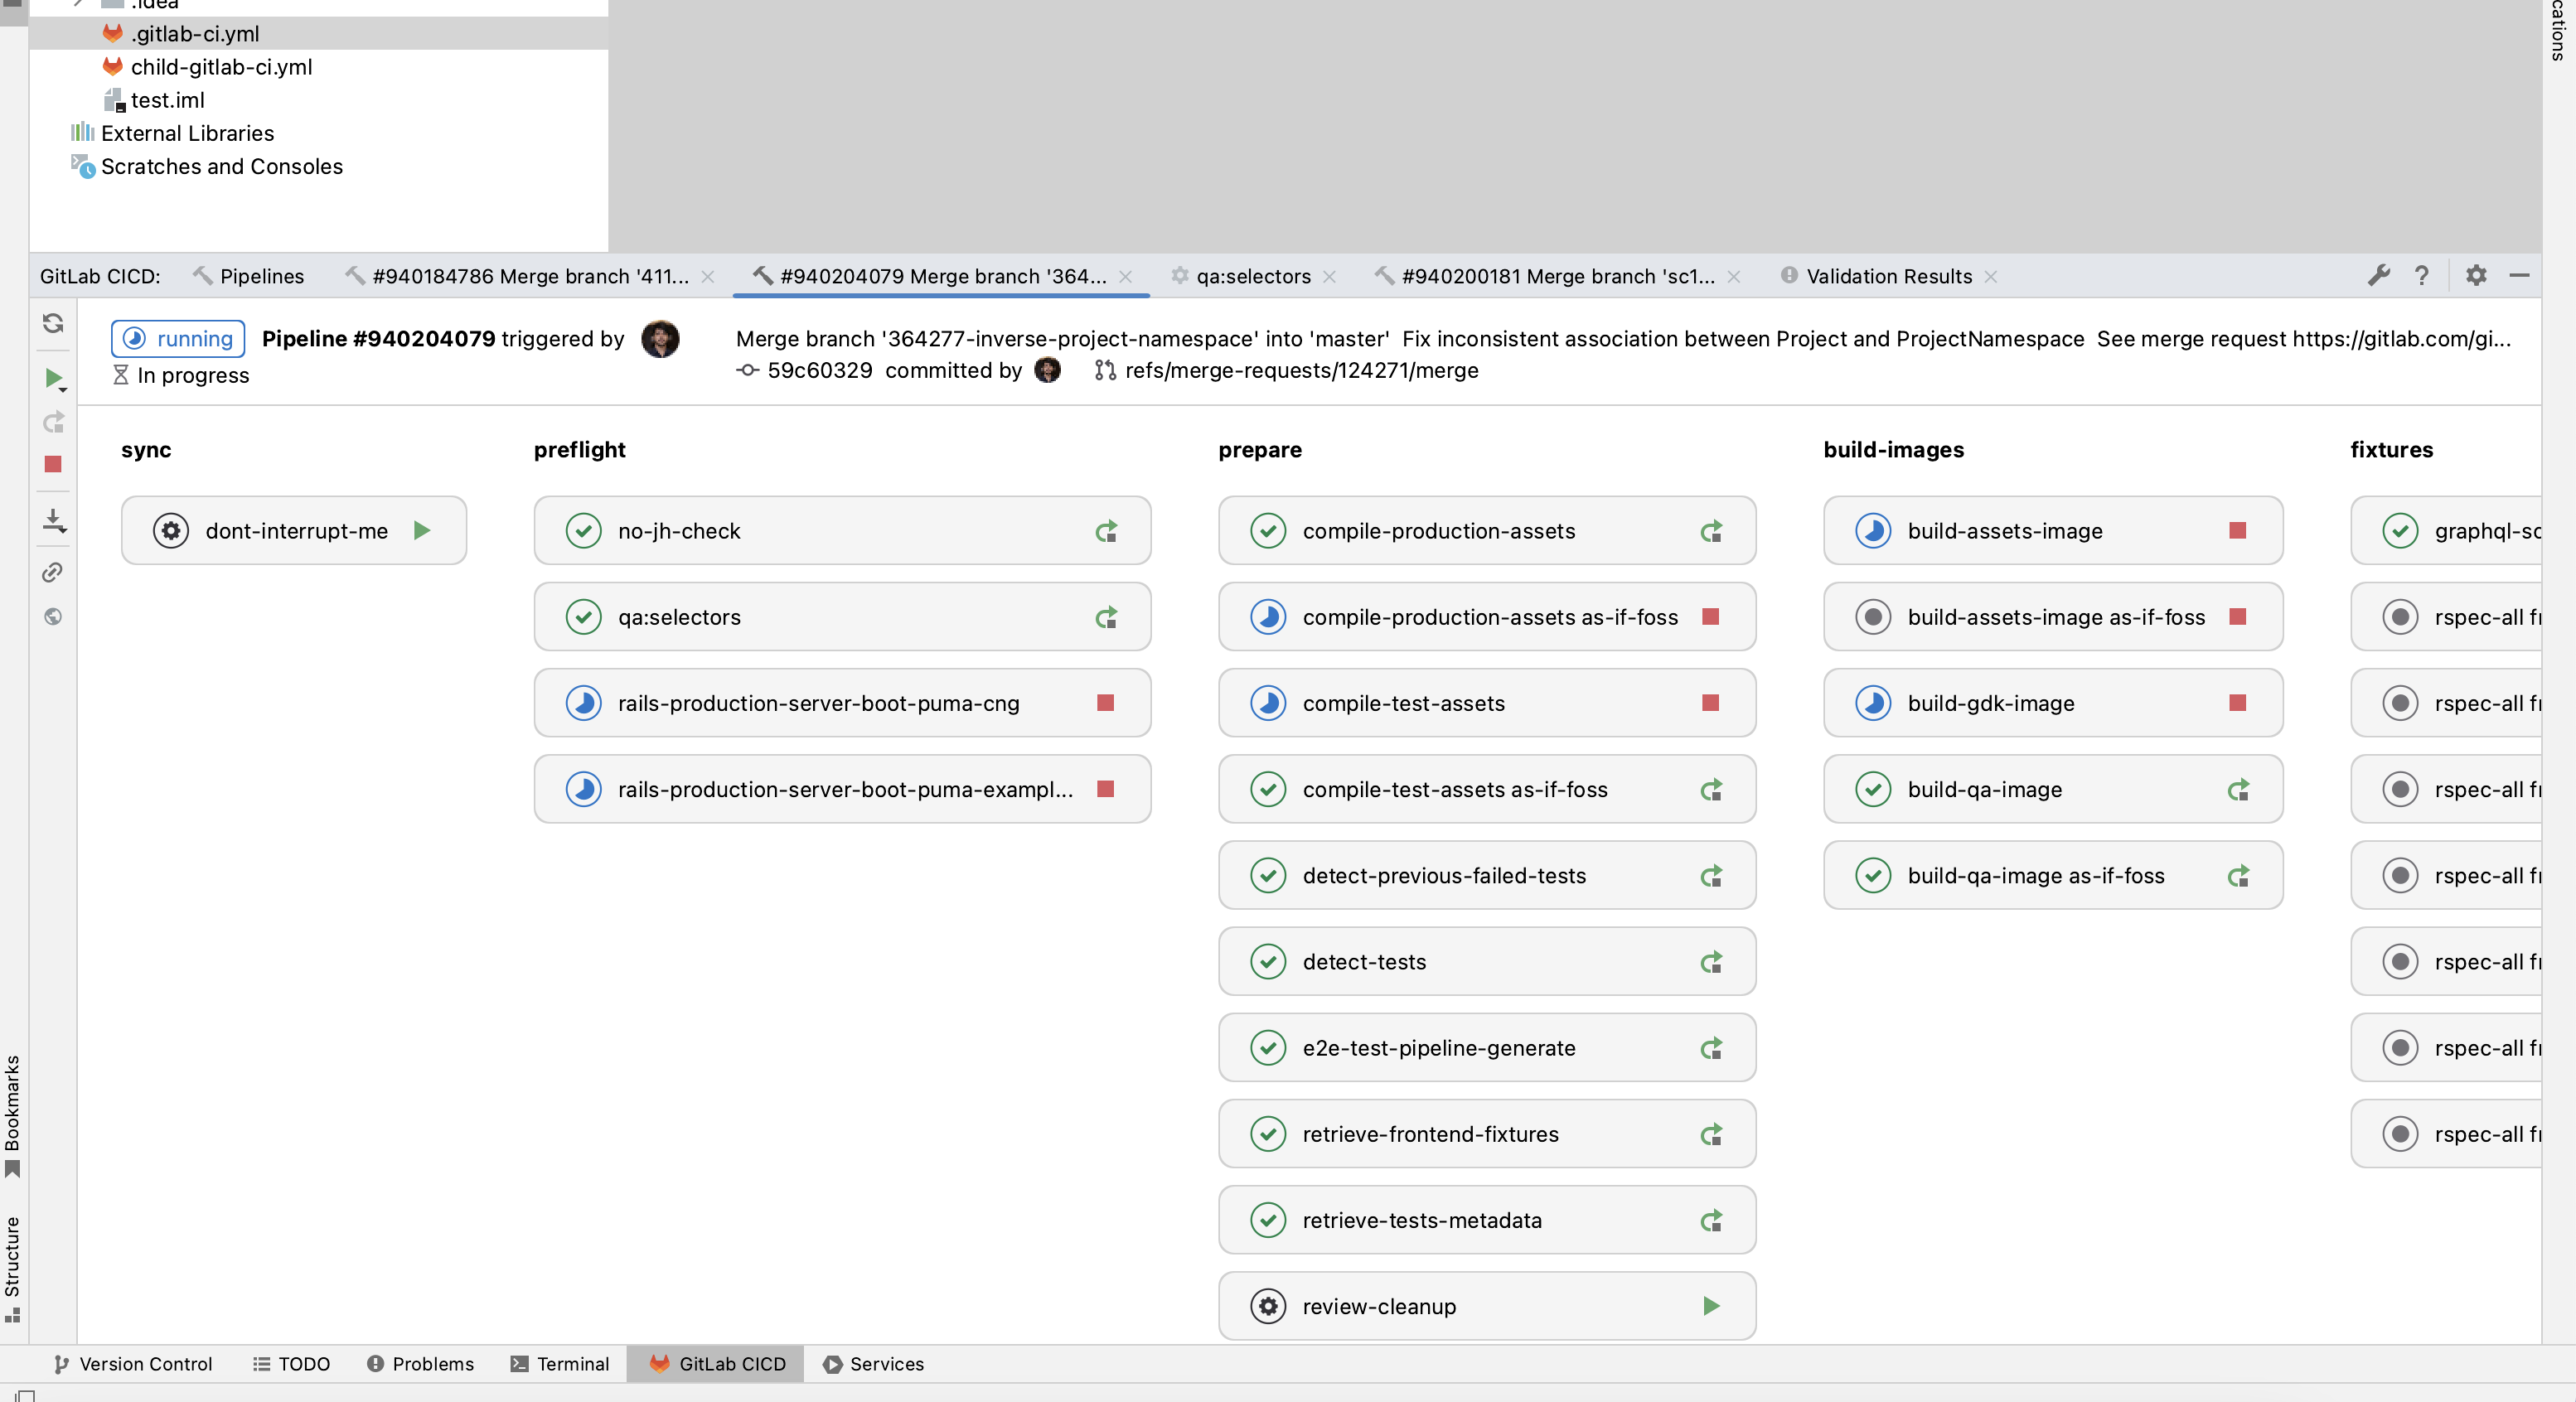
Figure 2: GitLab CICD plugin for IntelliJ - GitLab CI/CD - GitLab Forum A quality gate that fails on every commit because thresholds are set too aggressively gets disabled. One that never fails because thresholds are too permissive provides no value. The goal is a gate calibrated to the actual risk profile of the project. Apply these thresholds to new code only (the “new code” period in SonarQube). Do not apply them to the full codebase on a legacy project, failing every build because of technical debt accumulated over five years causes teams to disable the gate entirely. The new-code approach lets you stop the bleeding while the existing debt is addressed separately.
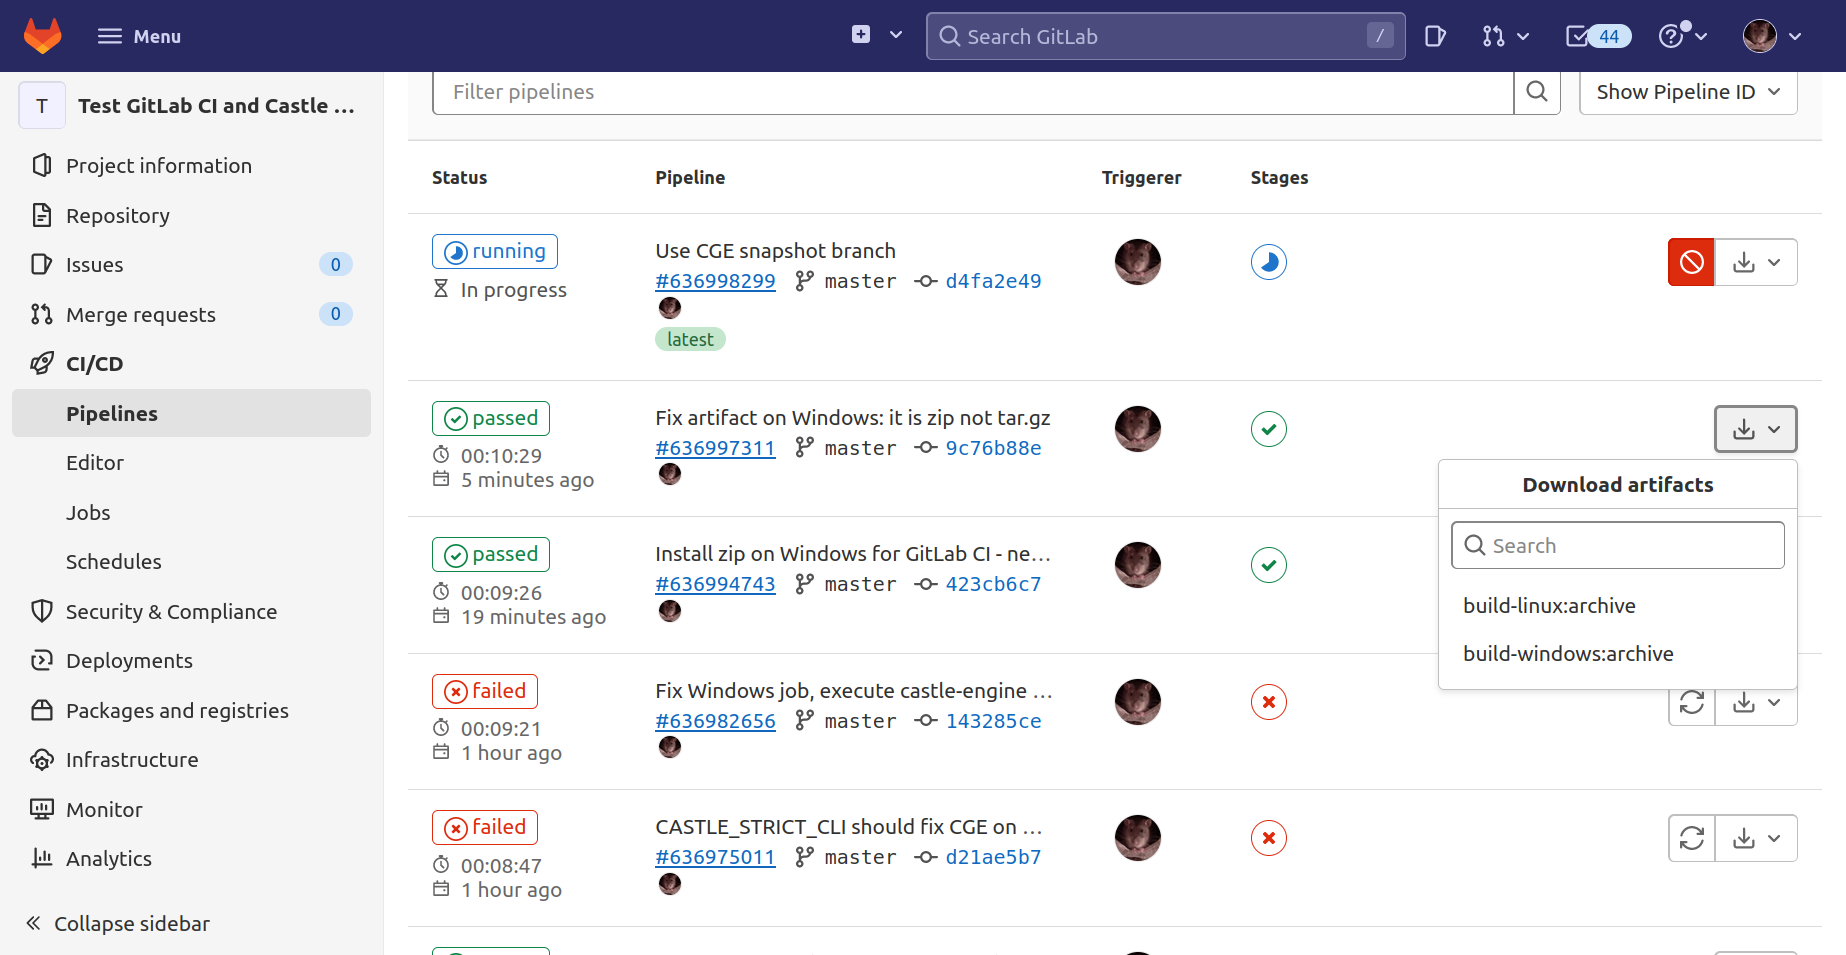
Ratchet thresholds over time. Start with conservative thresholds, then tighten them each quarter as the team clears its backlog. A gate that passes today with 75% coverage can be updated to 80% once the baseline is comfortably above that. Incremental tightening is more sustainable than jumping to perfection. The most common reason teams disable or route around static analysis in CI is that it makes pipelines too slow. A 15-minute quality scan on every push to a feature branch kills developer flow. Several strategies keep analysis fast: Figure 3: GitLab CI/CD | Manual | Castle Game Engine Incremental analysis (new code only). SonarQube and most enterprise static analysis tools support analyzing only the changed files in a pull request rather than the full codebase. Configure sonar.pullrequest.base , sonar.pullrequest.branch , and sonar.pullrequest.key parameters to enable PR-specific incremental scanning. Full analysis still runs on merge to main; PR scanning runs in under 2 minutes on most codebases.
Caching. The most expensive part of many static analysis runs is downloading the tool and its rule definitions. Cache the scanner binary, the rule database, and any resolved dependencies between runs: Parallelism. Linting, security scanning, and quality gate analysis are independent concerns. Run them in parallel jobs rather than sequentially. The pipeline total time is determined by the slowest job, not the sum of all jobs.
Selective tool activation. Not every tool needs to run on every branch. Full security scanning and compliance checks can run on pull requests and main while pre-merge branches run only fast linters. Use branch filters in the CI configuration to apply different analysis profiles. Security-focused pipelines add two layers beyond standard quality analysis: SAST (Static Application Security Testing) for application code vulnerabilities, and dependency scanning for known CVEs in third-party libraries.
SAST tools (Semgrep, CodeQL, Snyk Code, Checkmarx) analyze how untrusted data flows through application code to reach sensitive operations. They find SQL injection, XSS, command injection, insecure deserialization, and hardcoded credentials that standard quality linters cannot detect. Dependency scanning checks package.json , pom.xml , requirements.txt , and equivalent manifest files against vulnerability databases: The layered security model places fast pattern-based SAST (Semgrep) on every PR for immediate developer feedback and deep semantic SAST (CodeQL) on a scheduled basis for thorough coverage. Dependency scanning runs on every build because new CVEs are published daily.
Running analysis only on the main branch. The value of static analysis is catching issues before they merge, not after. Analysis that runs only after merge serves as a report, not a gate. Setting quality gates to warn instead of fail. A warning that does not block the pipeline is a notification that developers learn to ignore. Gates that do not fail build no quality culture.
Not excluding test files from coverage thresholds. Testing code testing other testing code produces inflated coverage numbers. Exclude test directories from coverage calculations to get accurate measurements of production code coverage. Ignoring the analysis backlog on legacy codebases. Turning on SonarQube for the first time on a million-line legacy codebase and getting 40,000 issues is demotivating and counterproductive. Use the new-code baseline approach: define a “new code” start date, apply gates only to code written after that date, and treat the existing issue backlog as a separate technical debt reduction program.
Not wiring results into pull request comments. Analysis results posted to a separate dashboard that developers must visit are ignored. Analysis results posted as inline comments on the specific lines that introduced issues, inside the pull request review interface, are addressed. Configure sonar.pullrequest.* parameters for GitHub, GitLab, or Bitbucket integration so findings appear where code review happens.
Most static analysis tools in CI/CD pipelines see one language at a time. ESLint sees JavaScript. SonarQube sees Java, Python, JavaScript, and C#. None of them see COBOL, JCL, RPG, or the cross-language dependencies that connect a mainframe batch program to the Java microservice that consumes its output, which connects to the JavaScript frontend that displays it.
SMART TS XL integrates into CI/CD pipelines as a cross-language static analysis layer that covers every language in the enterprise environment simultaneously. When a Java service is modified, SMART TS XL’s impact analysis traces the dependency graph to identify which COBOL programs, database schemas, and downstream services are affected by that change, before the change is deployed. When a COBOL copybook is modified, it identifies every program across the full application portfolio that includes that copybook and would need validation.
This cross-language dependency awareness is the capability that makes SMART TS XL’s CI/CD integration different from adding another language to SonarQube. It is not just about analyzing the code in the changed file. It is about understanding what else in the system that change will affect, which is the architectural analysis that determines the true scope of a change before it is made.
For enterprise development teams operating across legacy and modern stacks, SMART TS XL’s DevOps integration capability embeds this structural analysis into the pipeline review workflow, providing the architectural visibility that language-specific tools cannot deliver. The result is quality gates that enforce standards not just within a language boundary but across the full system, ensuring that a change in any component does not introduce unexpected failures in the components that depend on it.
The teams that get static analysis right treat it the same way they treat testing: not as a phase to pass but as a continuous practice embedded in every commit. Analysis runs on every pull request. Quality gate results appear inline with code review. Thresholds tighten as the codebase improves. New categories of analysis are added as the team’s security and quality maturity grows.
The pipeline configuration templates in this article are starting points. The specific tools, thresholds, and gate conditions should be calibrated to the project’s language stack, risk profile, and team maturity. What should not vary is the principle: analysis that does not gate merges does not change behavior, and behavior is what code quality programs are trying to change.
Code Quality identifies maintainability issues before they become technical debt. The automated feedback that occurs during code reviews can help your team write better code. The findings appear directly in merge requests, making problems visible when they’re most cost-effective to fix. Code Quality works with multiple programming languages and integrates with common linters, style checkers, and complexity analyzers. Your existing tools can feed into the Code Quality workflow, preserving your team’s preferences while standardizing how results are displayed.
Different features are available in different GitLab tiers , as shown in the following table: Code Quality is an open system that supports importing results from many scanning tools. To find violations and surface them, you can: You can capture results from multiple tools in a single pipeline. For example, you can run a code linter to scan your code along with a language linter to scan your documentation, or you can use a standalone tool along with CodeClimate-based scanning. Code Quality combines all of the reports so you see all of them when you view results .
Many development teams already use linters, style checkers, or other tools in their CI/CD pipelines to automatically detect violations of coding standards. You can make the findings from these tools easier to see and fix by integrating them with Code Quality. To see if your tool already has a documented integration, see Integrate common tools with Code Quality .
Now, after the pipeline runs, the quality tool’s results are processed and displayed . This feature was deprecated in GitLab 17.3 and is planned for removal in 19.0. Integrate the results from a supported tool directly instead. Code Quality also includes a built-in CI/CD template, Code-Quality.gitlab-ci.yaml . This template runs a scan based on the open source CodeClimate scanning engine.
The CodeClimate engine uses a customizable set of analysis plugins. Some are on by default; others must be explicitly enabled. The following integrations are available to replace the built-in plugins: Code quality analysis results display in the merge request Reports tab. Multiple code quality findings with identical fingerprints display as a single entry. To determine which findings are new or resolved, GitLab compares them with the findings from a baseline pipeline on the target branch.
Code Quality results display in the merge request Changes view. Lines containing Code Quality issues are marked by a symbol beside the gutter. Select the symbol to see the list of issues, then select an issue to see its details. The full list of Code Quality violations generated by a pipeline is shown in the Code Quality tab of the pipeline’s details page. The pipeline details view displays all Code Quality findings that were found on the branch it was run on.
The project quality view displays an overview of the code quality findings. The view can be found under Analyze > CI/CD analytics , and requires project_quality_summary_page feature flag to be enabled for this particular project. You can import Code Quality results from any tool that can output a report in the following format. This format is a version of the CodeClimate report format that includes a smaller number of fields.
The file you provide as Code Quality report artifact must contain a single JSON array. Each object in that array must have at least the following properties: Although the CodeClimate report format supports more properties, Code Quality only processes the fields listed previously. The GitLab parser does not allow a byte order mark at the beginning of the file. Some tools add a UTF-8 byte order mark to their output by default, particularly tools that originate from a Windows or .NET environment. To check for and remove a UTF-8 byte order mark, run: 2. System Architecture & Core Working Principles Many tools natively support the required report format to integrate their results with Code Quality. They may call it a “CodeClimate report”, “GitLab Code Quality report”, or another similar name.
Other tools can be configured to create JSON output by providing a custom template or format specification. Because the report format has only a few required fields, this output type might work for a Code Quality report. If you already use a tool in your CI/CD pipeline, you should adapt the existing job to add a Code Quality report. Adapting the existing job prevents you from running a separate job that may confuse developers and make your pipelines take longer to run.
If you don’t already use a tool, you can write a CI/CD job from scratch or adopt the tool by using a component from the CI/CD Catalog . If you already have an ESLint job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: You can also use or adapt the ESLint CI/CD component to run the scan and integrate its output with Code Quality.
If you already have a Stylelint job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: For more details and an example CI/CD job definition, see the documentation for @studiometa/stylelint-formatter-gitlab . If you already have a MyPy job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: Add a step to your job script to reprocess the file into the required format by using mypy-gitlab-code-quality . For example: You can also use or adapt the MyPy CI/CD component to run the scan and integrate its output with Code Quality.
If you already have a Flake8 job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: You can also use or adapt the Flake8 CI/CD component to run the scan and integrate its output with Code Quality. If you already have a Pylint job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: You can also use or adapt the Pylint CI/CD component to run the scan and integrate its output with Code Quality.
If you already have a Ruff job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: You can also use or adapt the documented Ruff GitLab CI/CD integration to run the scan and integrate its output with Code Quality.
If you already have a golangci-lint job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: You can also use or adapt the golangci-lint CI/CD component to run the scan and integrate its output with Code Quality. The PMD Copy/Paste Detector (CPD) requires additional configuration because its default output doesn’t conform to the required format.
You can use or adapt the PMD CI/CD component to run the scan and integrate its output with Code Quality. Using SwiftLint requires additional configuration because its default output doesn’t conform to the required format. You can use or adapt the SwiftLint CI/CD component to run the scan and integrate its output with Code Quality. Using RuboCop requires additional configuration because its default output doesn’t conform to the required format.
You can use or adapt the RuboCop CI/CD component to run the scan and integrate its output with Code Quality. Using Roslynator requires additional configuration because its default output doesn’t conform to the required format. You can use or adapt the Roslynator CI/CD component to run the scan and integrate its output with Code Quality. You can use Code Quality to scan any file stored in a repository, even if it isn’t code.
If you already have a Vale job in your CI/CD pipelines, you should add a report to send its output to Code Quality. To integrate its output: You can also use or adapt an open source job definition to run the scan and integrate its output with Code Quality, for example: If you already have a markdownlint-cli2 job in your CI/CD pipelines, you should add a report to send its output to Code Quality.
To integrate its output: Add markdownlint-cli2-formatter-codequality as a development dependency in your project. If you don’t already have one, create a .markdownlint-cli2.jsonc file at the top level of your repository. Declare a codequality report artifact that points to the location of the report file. By default, the report file is named markdownlint-cli2-codequality.json .
For more details and an example CI/CD job definition, see the documentation for markdownlint-cli2-formatter-codequality . Connect your GitLab account with Codiga, add your repository and inspect your codebase. Configure your rules and get feedback on your code in a few minutes. About the Codiga Static Analysis Engine Get real-time feedback on your merge requests in minutes! Codiga highlights bugs, security, and maintainability issues within seconds on each merge request on GitLab.
Get statistics about your team and individual performance Number of code reviews/merge requests over time Most common code violations Most modified files that cause merge conflicts Lightning fast feedback on each code reviews that highlights bugs, security and maintainability issues within seconds. Support 1800+ rules across 12 languages with specific analysis for the most popular frameworks (React, Vue, Next).
Check your code quality in CircleCI, Travis-CI, GitHub action, GitLab or any other CI pipeline tool. Using code to deploy your infrastructure with languages such as Terraform? We detect potential security issues. Static application security testing (SAST) discovers vulnerabilities in your source code before they reach production. Integrated directly into your CI/CD pipeline, SAST identifies security issues during development when they’re easiest and most cost-effective to fix.
Security vulnerabilities found late in development create costly delays and potential breaches. SAST scans happen automatically with each commit, giving you immediate feedback without disrupting your workflow. SAST scanners can generate false positives that create noise in your vulnerability reports. GitLab Duo assists with vulnerability management.
GitLab Duo false positive detection automatically analyzes critical and high severity SAST vulnerabilities to identify likely false positives. This helps your security team focus on genuine vulnerabilities and reduces time spent on manual triage. For Ultimate tier customers with a GitLab Duo add-on, false positive detection runs automatically after each security scan and provides confidence scores with explanations for each assessment.
Agentic SAST Vulnerability Resolution automatically generates merge requests with context-aware code fixes for High and Critical severity SAST vulnerabilities. This agentic approach uses multi-shot reasoning to resolve vulnerabilities with minimal human intervention. For Ultimate tier customers, agentic vulnerability resolution runs automatically after each security scan when vulnerabilities meet specific conditions.
Enable SAST in your project by using either the UI or editing your project’s GitLab CI/CD configuration file. 3. Software Implementation, Frameworks & Protocols By default, SAST runs only in branch pipelines. To run SAST in merge request pipelines, see use security scanning tools with merge request pipelines .
You can enable and configure SAST by using the UI, either with the default settings or with customizations. The method you can use depends on your GitLab license tier. The UI configuration method works best with minimal or no existing .gitlab-ci.yml file. If you have a complex configuration, the tool might fail to parse it. In that case, edit the CI/CD file instead.
If the latest pipeline for the default branch of the project has completed and produced valid SAST artifacts, select Configure SAST , otherwise select Enable SAST in the static application security testing (SAST) row. Custom values are stored in the .gitlab-ci.yml file. For CI/CD variables not in the SAST configuration page, their values are inherited from the GitLab SAST template.
Pipelines now include a SAST job. If supported source code is present, the appropriate analyzers and default rules automatically scan for vulnerabilities when a pipeline runs. The corresponding jobs appear under the test stage in the project’s pipeline. Pipelines now include a SAST job. If supported source code is present, the appropriate analyzers and default rules automatically scan for vulnerabilities when a pipeline runs. The corresponding jobs appear under the test stage in the project’s pipeline.
Select the Start a new merge request with these changes checkbox, then select Commit changes . Complete the fields according to your standard workflow, then select Create merge request . Review and edit the merge request according to your standard workflow, then select Merge . Pipelines now include a SAST job. If supported source code is present, the appropriate analyzers and default rules automatically scan for vulnerabilities when a pipeline runs. The corresponding jobs appear under the test stage in the project’s pipeline.
SAST vulnerabilities are named according to the primary Common Weakness Enumeration (CWE) identifier for the discovered vulnerability. Read the description of each vulnerability finding to learn more about the specific issue that the scanner has detected. For more information on SAST coverage, see SAST rules . Findings are generated on feature branches. When they are merged into the default branch, they become vulnerabilities. This distinction is important when evaluating your security posture.
A pipeline consists of multiple jobs, including SAST and DAST scanning. If any job fails to finish for any reason, the security dashboard does not show SAST scanner output. For example, if the SAST job finishes but the DAST job fails, the security dashboard does not show SAST results. On failure, the analyzer outputs an exit code. SAST results display in the merge request Changes view. Lines containing SAST issues are marked by a symbol beside the gutter. Select the symbol to see the list of issues, then select an issue to see its details.
Create a .gitlab/sast-ruleset.toml file at the root of your project if one does not already exist. Use the rule ID to disable the rule. For example, to disable gosec.G107-1 , add the following in .gitlab/sast-ruleset.toml : To exclude files or paths from being scanned, for example test or temporary code, set the SAST_EXCLUDED_PATHS variable. For example, to skip rule-template-injection.go , add the following to your .gitlab-ci.yml : After you are confident in the SAST results for a single project, you can extend its implementation to additional projects: For more information about language support plans in SAST, see the category direction page .
These languages are supported by both GitLab Advanced SAST (Ultimate) and standard analyzers (all tiers): These languages are supported by standard analyzers (all tiers) but not by GitLab Advanced SAST: These languages are supported by GitLab Advanced SAST (Ultimate) in beta , but not by the standard analyzers: Analysis runs in a separate gitlab-advanced-sast-ext CI/CD job, which is enabled together with GitLab Advanced SAST by the GITLAB_ADVANCED_SAST_ENABLED CI/CD variable. For more information, see GitLab Advanced SAST .
The SAST CI/CD template also includes an analyzer job that can scan Kubernetes manifests and Helm charts; this job is off by default. See Enabling Kubesec analyzer or consider IaC scanning , which supports additional platforms, instead. To learn more about SAST analyzers that are no longer supported, see Analyzers that have reached End of Support . Source code is volatile; as developers make changes, source code may move in the same file or between files. Security analyzers may have already reported vulnerabilities that are being tracked in the vulnerability report. These vulnerabilities are linked to specific problematic code fragments so that they can be found and fixed. If the code fragments are not tracked reliably as they move, vulnerability management is harder because the same vulnerability could be reported again.
GitLab SAST uses an advanced vulnerability tracking algorithm to more accurately identify when the same vulnerability has moved in the same file due to refactoring or unrelated changes. Support for advanced vulnerability tracking depends on the language and analyzers used. Languages supported by both GitLab Advanced SAST analyzers and Semgrep-based analyzers: For more information, see the confidential project https://gitlab.com/gitlab-org/security-products/post-analyzers/tracking-calculator . The content of this project is available only to GitLab team members.
To help you focus on the vulnerabilities that are still relevant, GitLab SAST automatically resolves vulnerabilities when: Automatic resolution is available only for findings from the Semgrep-based analyzer . The Vulnerability Management system leaves a comment on automatically-resolved vulnerabilities so you still have a historical record of the vulnerability. The default scanner images are built on a base Alpine image for size and maintainability.
GitLab offers an image version, based on the Red Hat UBI base image, that uses a FIPS 140-validated cryptographic module. To use the FIPS-enabled image, you can either: A FIPS-compliant image is only available for the GitLab Advanced SAST and Semgrep-based analyzer. To use SAST in a FIPS-compliant manner, you must exclude other analyzers from running . If you use a FIPS-enabled image to run Advanced SAST or Semgrep in a runner with a non-root user , you must update the run_as_user attribute under runners.kubernetes.pod_security_context to use the ID of the gitlab user created by the image , which is 1000 .
Each SAST analyzer outputs a JSON report as a job artifact. The file contains details of all detected vulnerabilities. You can download the file for processing outside GitLab. GitLab SAST is designed to be used in its default configuration. However, you can change configuration variables or customize detection rules to suit your needs.
SAST offers a stable template, used by default for production use, and a latest template for testing cutting-edge features. For details on the differences and when to use each, see template editions . Override SAST jobs when you want to customize properties such as variables , dependencies , and rules . Place this new job after the template inclusion and specify any additional keys under it.
In the following example, the CI/CD variable FAIL_NEVER is enabled for the spotbugs analyzer: Pin the image version when you want to use a specific analyzer image version in the pipeline. The GitLab-managed CI/CD template specifies a major version and automatically pulls the latest analyzer release within that major version. In some cases, you may need to use a specific version. For example, you might need to avoid a regression in a later release.
Only set this variable within a specific job. If you set it at the top level , the version you set is used for all SAST analyzers. In the following example, a specific minor version of the semgrep analyzer and a specific patch version of the brakeman analyzer are set: Some analyzers require downloading the project’s dependencies to perform the analysis. In turn, such dependencies may live in private Git repositories and thus require credentials like username and password to download them. Depending on the analyzer, such credentials can be provided to it by using custom CI/CD variables .
If your private Maven repository requires login credentials, you can use the MAVEN_CLI_OPTS CI/CD variable. You need to set SCAN_KUBERNETES_MANIFESTS to "true" to enable the Kubesec analyzer. In .gitlab-ci.yml , define: You can customize the Semgrep-based SAST analyzer to scan languages that are not supported by a GitLab-managed ruleset. However, because GitLab does not provide rulesets for these other languages, you must replace or add to the default rules to cover them. You must also modify the rules of the semgrep-sast CI/CD job so that the job runs when the relevant files are modified.
4. Practical Deployment, Analysis & Case Studies Provide a custom ruleset for OCaml. Create a file named sast-ruleset.toml in a .gitlab/ directory at the root of your repository. Version 6 of the SpotBugs analyzer adds support for JDK21 and removes JDK11. The default version remains at 5 as discussed in issue 517169 .
To use version 6 , pin the analyzer version. For details, see pin analyzer image version . The SpotBugs-based analyzer scans compiled bytecode for Groovy projects. By default, it automatically attempts to fetch dependencies and compile your code so it can be scanned. To resolve these issues, skip the analyzer’s compilation step and directly provide artifacts from an earlier stage in your pipeline instead. This strategy is called pre-compilation.
To share precompiled artifacts, make the following changes to your project’s .gitlab-ci.yml file: Use a compilation job (typically named build ) to compile your project and store the compiled output as a job artifact by using the CI/CD artifacts: paths variable. Disable automatic compilation by setting the COMPILE: "false" CI/CD variable in the spotbugs-sast job.
Ensure the spotbugs-sast job depends on the compilation job by setting the dependencies keyword. This allows the spotbugs-sast job to download and use the artifacts created in the compilation job. The following example pre-compiles a Gradle project and provides the compiled bytecode to the analyzer: If your project requires external dependencies to be recognized by the analyzer and you’re using Maven, you can specify the location of the local repository by using the MAVEN_REPO_PATH variable.
Specifying dependencies is only supported for Maven-based projects. Other build tools (for example, Gradle) do not have an equivalent mechanism for specifying dependencies. In that case, ensure that your compiled artifacts include all necessary dependencies. To specify Maven dependencies make the following changes to your project’s .gitlab-ci.yml file: The following example pre-compiles a Maven project and provides the compiled bytecode along with the dependencies to the analyzer: When the GitLab SAST template is used, all standard SAST configuration CI/CD variables and custom variables are propagated to the underlying SAST analyzer images.
All customization of GitLab security scanning tools should be tested in a merge request before merging these changes to the default branch. Failure to do so can give unexpected results, including a large number of false positives. The following example includes the SAST template to override the SEARCH_MAX_DEPTH variable to 10 in all jobs. The template is evaluated before the pipeline configuration, so the last mention of the variable takes precedence.
Support for a custom Certificate Authority (CA) was introduced in the following analyzer versions. For example, to configure this value in your project’s .gitlab-ci.yml file, use the following: SAST can be configured to exclude code based on file paths and search depth. The following CI/CD variables control which files are scanned and how thoroughly the analyzer searches your codebase.
You might need to exclude temporary directories used by your build tool as these can generate false positives. To exclude paths, copy and paste the default excluded paths, then add your own paths to be excluded. If you don’t specify the default excluded paths, the defaults are overridden and only the paths you specify are excluded from SAST scans. For these analyzers, SAST_EXCLUDED_PATHS is implemented as a pre-filter , which is applied before the scan is executed.
The analyzer skips any files or directories whose path matches one of the comma-separated patterns. For these analyzers, SAST_EXCLUDED_PATHS is implemented as a post-filter , which is applied after the scan is executed. Patterns can be globs (see doublestar.Match for supported patterns), or file or folder paths (for example, doc,spec ). Parent directories also match patterns.
The post-filter implementation of SAST_EXCLUDED_PATHS is available for all SAST analyzers. Some SAST analyzers such as those with superscript 2 implement SAST_EXCLUDED_PATHS as both a pre-filter and post-filter. A pre-filter is more efficient because it reduces the number of files to be scanned. For analyzers that support SAST_EXCLUDED_PATHS as both a pre-filter and post-filter, the pre-filter is applied first, then the post-filter is applied to any vulnerabilities that remain.
For this variable, Path patterns can be globs (see doublestar.Match for supported patterns). Directories are excluded from the build process if the path pattern matches a supported build file: For example, to exclude building and scanning a maven project containing a build file with the path project/subdir/pom.xml , pass a glob pattern that explicitly matches the build file, such as project/*/*.xml or **/*.xml , or an exact match such as project/subdir/pom.xml .
Passing a parent directory for the pattern, such as project or project/subdir , does not exclude the directory from being built, because in this case, the build file is not explicitly matched by the pattern. The SAST CI/CD template searches the repository to detect the programming languages used, and selects the matching analyzers. Then, each analyzer searches the codebase to find the specific files or directories it should scan. Set the value of SEARCH_MAX_DEPTH to specify how many directory levels the analyzer’s search phase should span.
SAST analyzers internally use OSS security scanners to perform the analysis. GitLab sets the recommended configuration for the security scanner so that you need not to worry about tuning them. However, there can be some rare cases where our default scanner configuration does not suit your requirements. To allow some customization of scanner behavior, you can add a limited set of flags to the underlying scanner. Specify the flags in the SAST_SCANNER_ALLOWED_CLI_OPTS CI/CD variable. These flags are added to the scanner’s CLI options.
Maximum size for a file to be scanned. Any input program larger than this is ignored. Set to 0 or a negative value to disable this filter. Bytes can be specified with or without a unit of measurement, for example: 12.5kb , 1.5MB , or 123 . Defaults to 1000000 bytes. Note: You should keep this flag set to the default value. Also, avoid changing this flag to scan minified JavaScript, which is unlikely to work well, DLLs , JARs or other binary files because binary files are not scanned.
You can mark individual lines, or blocks, of code to be excluded from being analyzed for vulnerabilities. You should manage all vulnerabilities through Vulnerability Management, or adjust the scanned file paths using SAST_EXCLUDED_PATHS before using this method of finding-by-finding comment annotation. Ignore a line of code - add // nosemgrep: comment to the end of the line (the prefix is according to the development language).
Ignore a line of code for specific rule - add // nosemgrep: RULE_ID comment at the end of the line (the prefix is according to the development language). The //nosemgrep comment can alternatively be added to the line immediately preceding the detection. No other lines (including other comments) should be between the ignore comment and the detected code.
Ignore a file or directory - create a .semgrepignore file in your repository’s root directory or your project’s working directory and add patterns for files and folders there. GitLab Semgrep analyzer automatically merges your custom .semgrepignore file with GitLab built-in ignore patterns . The Semgrep analyzer does not respect .gitignore files. Files listed in .gitignore are analyzed unless explicitly excluded by using .semgrepignore or SAST_EXCLUDED_PATHS .
For instances in an environment with limited, restricted, or intermittent access to external resources through the internet, some adjustments are required for the SAST job to run successfully. For more information, see Offline environments . GitLab Runner has a default pull_policy of always , meaning the runner tries to pull Docker images from the GitLab container registry even if a local copy is available. The GitLab Runner pull_policy can be set to if-not-present in an offline environment if you prefer using only locally available Docker images. However, keep the pull policy setting to always if not in an offline environment. This setting enables the use of updated scanners in your CI/CD pipelines.
For SAST with all supported languages and frameworks, import the following default SAST analyzer images from registry.gitlab.com into your local Docker container registry : The process for importing Docker images into a local offline Docker registry depends on your network security policy. Consult your IT staff to find an accepted and approved process by which external resources can be imported or temporarily accessed.
These scanners are periodically updated with new definitions, and you may be able to make occasional updates on your own. For details on saving and transporting Docker images as a file, see the Docker documentation on: The SAST job should now use local copies of the SAST analyzers to scan your code and generate security reports without requiring internet access.
If a SAST job invokes a package manager, you must configure its certificate verification. In an offline environment, certificate verification with an external source is not possible. Either use a self-signed certificate or disable certificate verification. Refer to the package manager’s documentation for instructions. By default SAST analyzers are supported in GitLab instances hosted on SELinux. Adding a before_script in an overridden SAST job may not work as runners hosted on SELinux have restricted permissions.
All tiers. Uses Semgrep analyzer with GitLab-managed rules unless otherwise specified. II 5. Performance Evaluation & Extended Technical Observations GitLab Advanced SAST support for Swift and Objective-C is in beta . Analysis runs as a separate gitlab-advanced-sast-ext job, which is enabled together with GitLab Advanced SAST by the shared GITLAB_ADVANCED_SAST_ENABLED variable.
For more information, see Swift and Objective-C configuration . II II All tiers. Uses Semgrep analyzer with GitLab-managed rules unless otherwise specified. II SpotBugs with the find-sec-bugs plugin. Supports Gradle, Maven, and SBT. It can also be used with variants like the Gradle wrapper, Grails, and the Maven wrapper. However, SpotBugs has limitations when used against Ant-based projects. You should use the GitLab Advanced SAST or Semgrep-based analyzer for Ant-based Java or Scala projects. II Sonar tightly integrates with GitLab enabling your team to consistently and efficiently deliver code of the highest quality and static code analysis tools that's free of issues.
Elevate your GitLab experience with Sonar and ensure only Code Quality is added to the code base. With just a few clicks immerse yourself in a setup where code review and quality control become a breeze. Sonar automatically decorates code quality metrics directly on your merge request & feature branches. Resolve issues before you merge, making code reviews more effective and streamlined. Ensure your GitLab pipelines halt when the quality of code doesn't meet your defined standards, making static code analysis a crucial step in your development process. Code Quality becomes the norm! Review and prioritize security issues remediation during code reviews directly from GitLab, fostering a proactive approach towards code quality enhancement.
Configure multiple Quality Gates and receive project-labeled messages in your GitLab mono repository, ensuring code quality standards are met across all projects. Sonar supports authentication delegation - if you're logged into your GitLab account, you're all set to start improving the quality of your code! Native Git data support so issues are automatically assigned and tracked, streamlining the code review process.
Configure your CI chain to automatically analyze merge requests and branches and publish the Quality Gate results in the build summary, making static code analysis a seamless part of your CI/CD pipeline. Sonar CI/CD workflow integration helps you review and prioritize security vulnerabilities directly from your repository during your code reviews, making your codebase more secure and robust.
With its tight coupling to GitLab, Sonar static code analyzes your projects and provides code health metrics at the right time and in the right place Non-disruptive code quality analysis overlays your workflow so your team only produces clean builds. Your projectâIIs Quality Gate status is clearly decorated right in GitLab Pipelines along with code coverage and duplication metrics. Live updating keeps everyone aligned on code quality objectives.
With fresh code to review and analyze, the onboarding wizard simplifies your startup, guiding you in adding all your projects and setting up quality auto-detection of branches and Pull Requests. SonarâIIs GitLab CI/CD integration supports dozens of popular languages, development frameworks and IaC platforms Integrating SonarQube with GitLab enables automated inspection of your codebase to ensure consistent quality and reduce potential issues before they reach production. The process involves connecting your GitLab repository to SonarQube, configuring the necessary permissions, and creating a pipeline script that triggers SonarQube analysis on each commit or merge request. YouâIIll need to set up environment variables in your GitLab CI/CD pipeline to securely pass your SonarQube authentication token and specify the correct project key, and server address for seamless communication. If youâIIre using SonarQube Cloud, youâIIll also need your organization key.
Once set up, each push or pull request to your GitLab repository will automatically run SonarQube's analysis, providing valuable insights into code quality, bugs, vulnerabilities, and technical debt directly within your GitLab pipeline results. This continuous feedback loop helps development teams adopt quality at the source, catching issues in new code and ensuring codebase health over time. Advanced configuration allows for tailored reports and gating rules to maintain quality code standards across projects.
Connecting GitLab to SonarQube streamlines quality code management by automating the detection of bugs, vulnerabilities, and code smells throughout the development lifecycle. Integration ensures that every change is evaluated according to best practice standards, leading to improved software maintainability and reduced deployment risks. By leveraging SonarQubeâIIs scalable infrastructure and advanced analysis engine, teams benefit from a unified view of code quality across all GitLab-hosted repositories.
Another key advantage is enhanced collaboration and accountability. Developers receive instant feedback on their contributions with actionable insights and recommendations, making it easy to prioritize fixes on new code. The integration supports quality gates, which block merges unless specific quality thresholds are met, ensuring high standards without bottlenecks. This focus on quality at the source fosters a culture of excellence and streamlines release cycles.
A quality gate in SonarQube represents a set of predefined criteria that software projects must meet before code changes are merged or promoted. Common conditions include thresholds for bugs, vulnerabilities, code coverage, and duplications. When integrating with GitLab CI/CD pipelines, SonarQube performs analysis on each code change, and the resulting quality gate status is exposed in pipeline results or as a merge request comment.
If the code passes the quality gate, the pipeline proceeds, ensuring quality code is delivered and maintained from the start. If it fails, developers are notified instantly, allowing rapid remediation and re-analysis within the same pipeline run. Organizations can customize quality gates to focus on new code quality, enforce security compliance, and promote best practices, all while maintaining productivity and preventing technical debt accumulation.
SonarQube for IDE deeply integrates with popular development environments to provide developers with real-time guidance and feedback while coding. By analyzing code as itâIIs written, SonarQube for IDE promotes quality at the source by catching bugs, vulnerabilities, and compliance issues before code changes are even committed to GitLab. This leads to cleaner merge requests, fewer review cycles, and a stronger focus on new code quality.
For teams using GitLab, this workflow improvement is significant. Developers can confidently submit code knowing potential issues have already been addressed, and reviewers spend less time on low-level fixes. SonarQube for IDEâIIs recommendations complement automated checks in the GitLab pipeline, creating a comprehensive security net that supports code quality and developer productivity.
The SonarQube Community Build is the free and open-source edition of SonarQube, providing core code quality and security analysis features. ItâIIs a reliable choice for small teams and individual projects seeking to integrate automated code inspection into their GitLab CI/CD workflows. The Community Build covers common programming languages and highlights code issues, technical debt, and compliance gaps, making it suitable for most modern software development pipelines.
While the Community Build supports essential quality code practices, organizations with advanced requirements or larger codebases may benefit from SonarQubeâIIs premium editions or SonarQube Cloud. These paid offerings include features like enhanced security rules, portfolio management, and expanded language support, enabling more extensive integration and greater flexibility within enterprise GitLab environments.
SonarQube Cloud and SonarQube Server both deliver automated code quality analysis for GitLab, but their hosting and management models differ. SonarQube Cloud is a SaaS platform managed by Sonar, offering easy setup, automatic updates, and hosted storage for analysis results. It eliminates infrastructure overhead and delivers instant scalability, which is ideal for distributed or remote teams integrating with GitLab.
SonarQube Server, on the other hand, refers to the self-hosted platform, giving organizations complete control over configuration and data privacy. This flexibility makes it popular for teams with specific security, compliance, or integration needs. Both solutions seamlessly plug into GitLab pipelines to provide feedback on new code quality, but the choice between them depends on scalability, compliance requirements, and operational preferences.
Yes, SonarQube Cloud is designed for seamless compatibility with GitLabâIIs CI/CD pipelines. Users can connect their GitLab repositories directly to SonarQube Cloud, configure access tokens, and set up pipeline scripts to invoke automated analysis on every code change. The results are easily accessible within GitLab's interface, providing clear indicators of code quality status and actionable feedback for developers.
SonarQube Cloud supports advanced features such as quality gates, pull request decoration, and reporting on key metrics like code coverage and vulnerabilities. This integration allows teams to focus on new code quality, enforce standards, and accelerate their development processes without worrying about maintaining on-premises infrastructure. Documentation and support resources are available to walk users through the setup process step-by-step.
To configure a GitLab pipeline to trigger SonarQube analysis, you must add SonarQube-specific commands to your pipeline script. Typically, this means installing the SonarScanner CLI tool and creating a dedicated pipeline job that runs the analysis, passing in project and authentication details as variables. The pipeline should be set up to run this job on every push, merge request, or scheduled event as needed.
This configuration ensures automated enforcement of quality code standards and gives development teams early feedback during code reviews. Advanced options include parallel analysis of multiple projects, conditional execution based on branch or file type, and integration with GitLabâIIs notification system. A streamlined pipeline lowers the risk of technical debt and prioritizes quality at the source in every development cycle.
SonarQube analyzes code for a broad range of quality issues, including bugs, security vulnerabilities, code smells, technical debt, and compliance gaps. By scanning code stored in GitLab repositories, SonarQube provides detailed findings categorized by type, severity, and impacted files, helping teams prioritize improvements. Regular analysis highlights trends and recurring issues, informing best practices and architectural decisions.
The tool's flexibility supports rules for common languages and frameworks, and can be customized to fit the unique standards of each project. For teams using quality gates, SonarQube ensures critical issues are fixed before code can be merged, driving new code quality across the organization. Its reports and dashboards empower teams to monitor progress and address risks proactively.
SonarQube supports integration with both public and private GitLab repositories, making it a versatile solution for open-source contributors, freelancers, and enterprise teams alike. Users simply connect SonarQube with their GitLab account, grant necessary repository access, and configure analysis settings according to the privacy requirements of each project. Secure token-based authentication ensures analysis results and repository data remain protected.
With flexible access controls and granular permissions, SonarQube can enforce quality code standards in any type of GitLab repository. This enables organizations to adopt quality at the source and focus on new code quality regardless of the projectâIIs visibility or commercial sensitivity. SonarQubeâIIs compatibility with diverse GitLab workflows makes it a trusted partner for code excellence.
This course demonstrates how to set up automated code scanning in your GitLab repositories by integrating GitLab CI/CD with SonarQube. You'll learn to identify issues early in the development workflow to maintain high quality and security standards for your codebase. As engineering teams scale and software complexity grow, having a robust, automated CI/CD pipeline is no longer a luxury; it's a necessity. In this article, I’ll take you through the complete journey of setting up a fully private, self-hosted CI/CD pipeline using GitLab CI/CD, Docker-based runners, and SonarQube for code quality analysis.
This isn't another theoretical guide. Everything here is built in a real-world scenario, inside an isolated internal network with zero reliance on public SaaS. Sometimes the cloud isn’t an option. Whether due to security policies, compliance, or architecture decisions, many teams must operate entirely within internal infrastructure.
If this job fails (e.g., scanner fails or SonarQube is unreachable), the pipeline will stop at this stage. GitLab Runner is a background service that polls GitLab for jobs. Once it picks up a job: We use the Docker executor mode, which isolates each job in a clean container environment. Tip: For internal domains, configure Docker runner with extra_hosts to resolve local services like git.internal or sonarqube.internal.
SonarScanner reads this config and sends data to the SonarQube server over HTTP. The token ensures it’s authenticated. Building a self-hosted CI/CD + SonarQube pipeline taught me more than any cloud-based service ever could. From Docker networking to GitLab internals to Sonar’s scanning engine it’s been a true DevOps deep dive. Whether you're starting fresh or replacing legacy scripts, this setup will help your team build faster, safer, and with confidence.
If you found this useful, follow me for future deep dives into CI/CD, DevOps tooling, infrastructure, and open-source pipelines. Use GitLab CI/CD to test changes in feature branches. You can display test reports and link to important information directly in merge requests . Harvested Online Documentation & Reference Sources • https://www.in-com.com/blog/how-do-i-integrate-static-code-analysis-into-ci-cd-pipelines/ • https://docs.gitlab.com/ci/testing/code_quality/ • https://www.codiga.io/static-code-analysis/gitlab/ • https://docs.gitlab.com/user/application_security/sast/ • https://www.sonarsource.com/integrations/gitlab/ • https://www.sonarsource.com/learn/course/sonarqube-server/50bf1108-183d-4b05-9b4d-5afc0b933dce/configuring-code-an alysis-for-sonarqube-server-with-gitlab-cicd • https://dev.to/arious/building-a-fully-private-cicd-pipeline-with-gitlab-sonarqube-a-real-world-guide-2mpi • https://docs.gitlab.com/ci/testing/ • https://arxiv.org/abs/2609.00676v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Automated Static Code Analysis Integration In Gitlab Cicd.
[*] Metasploit Scan Running on Target Subnet for Automated Static Code Analysis Integration In Gitlab Cicd... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |