Complete Technical Paper Content — Broken Access Control Detection System In Web Applications
Overview & System Context
Broken Access Control Detection System In Web Applications: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9504 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Application security (AppSec) includes all tasks that introduce a secure software development life cycle to development teams. Its final goal is to improve security practices and, through that, to find, fix and preferably prevent security issues within applications. It encompasses the whole application life cycle from requirements analysis, design, implementation, verification as well as maintenance. Web application security is a branch of information security that deals specifically with the security of websites, web applications, and web services. At a high level, web application security draws on the principles of application security but applies them specifically to the internet and web systems. The application security also concentrates on mobile apps and their security which includes iOS and Android Applications. Web Application Security Tools are specialized tools for working with HTTP traffic, e.g., Web application firewalls.
Design review. Before code is written the application's architecture and design can be reviewed for security problems. A common technique in this phase is the creation of a threat model. White-box testing, or code review. Critical examination of internal structure, architecture, design, etc. Black-box testing. Tests functionality rather than internal structure. Automated Tooling. Many security tools can be automated through inclusion into the development or testing environment. Examples of those are automated DAST/SAST tools that are integrated into code editor or CI/CD platforms. Coordinated vulnerability platforms. These are hacker-powered application security solutions offered by many websites and software developers by which individuals can receive recognition and compensation for reporting bugs.
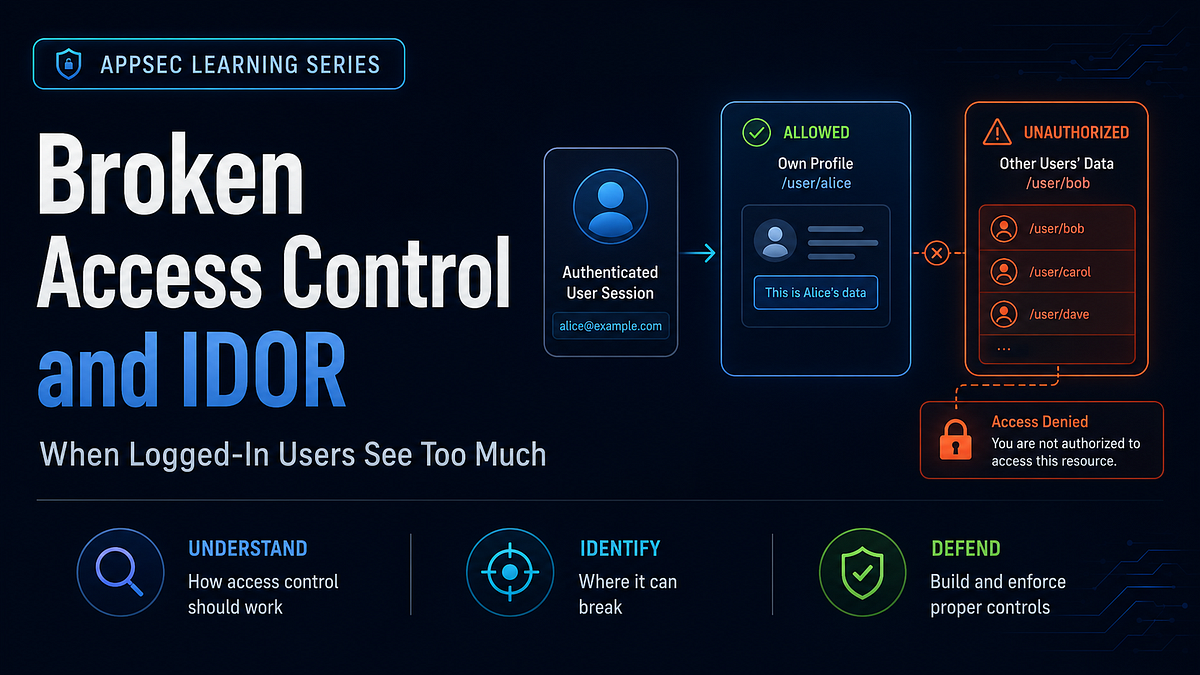
Broken access control Cryptographic failures Injection Insecure design Security misconfiguration Vulnerable and outdated components Identification and authentification failures Software and data integrity failures Security logging and monitoring failures* Server-side request forgery (SSRF)* Implement access control Use cryptography the proper way Validate all input & handle exceptions Address security from the start Secure by default configurations Keep your components secure Implement digital identity Use browser security features Implement security logging and monitoring Stop server-side request forgery Figure 1: Broken Access Control and IDOR: When Logged-In Users See Too Much | by ...
Static application security testing (SAST) analyzes source code for security vulnerabilities during an application's development. Compared to DAST, SAST can be utilized even before the application is in an executable state. As SAST has access to the full source code it is a white-box approach. This can yield more detailed results but can result in many false positives that need to be manually verified. Dynamic application security testing (DAST, often called vulnerability scanners) automatically detects vulnerabilities by crawling and analyzing websites. This method is highly scalable, easily integrated and quick. DAST tools are well suited for dealing with low-level attacks such as injection flaws but are not well suited to detect high-level flaws, e.g., logic or business logic flaws. Fuzzing tools are commonly used for input testing. Industry application security research highlights increasing risks related to insecure APIs, client-side code tampering, and runtime exploitation, reinforcing the importance of comprehensive dynamic and runtime security testing. Interactive application security testing (IAST) assesses applications from within using software instrumentation. This combines the strengths of both SAST and DAST methods as well as providing access to code, HTTP traffic, library information, backend connections and configuration information. Some IAST products require the application to be attacked, while others can be used during normal quality assurance testing. Runtime application self-protection augments existing applications to provide intrusion detection and prevention from within an application runtime. Dependency scanners (also called software composition analysis) try to detect the usage of software components with known vulnerabilities. These tools can either work on-demand, e.g., during the source code build process, or periodically.
ASP.NET Web Forms is a web application framework and one of several programming models supported by the Microsoft ASP.NET technology. Web Forms applications can be written in any programming language which supports the Common Language Runtime, such as C# or Visual Basic. The main building blocks of Web Forms pages are server controls, which are reusable components responsible for rendering HTML markup and responding to events. A technique called view state is used to persist the state of server controls between normally stateless HTTP requests. Web Forms was included in the original .NET Framework 1.0 release in 2002 (see .NET Framework version history and ASP.NET version history), as the first programming model available in ASP.NET. Unlike newer ASP.NET components, Web Forms is not supported by ASP.NET Core.
In-process mode The session variables are maintained within the ASP.NET process. This is the fastest way; however, in this mode the variables are destroyed when the ASP.NET process is recycled or shut down. State server mode ASP.NET runs a separate Windows service that maintains the state variables. Because state management happens outside the ASP.NET process, and because the ASP.NET engine accesses data using .NET Remoting, ASPState is slower than In-Process. This mode allows an ASP.NET application to be load-balanced and scaled across multiple servers. Because the state management service runs independently of ASP.NET, the session variables can persist across ASP.NET process shutdowns.
However, since session state server runs as one instance, it is still one point of failure for session state. The session-state service cannot be load-balanced, and there are restrictions on types that can be stored in a session variable. SQL Server mode State variables are stored in a database, allowing session variables to be persisted across ASP.NET process shutdowns. The main advantage of this mode is that it allows the application to balance load on a server cluster, sharing sessions between servers. This is the slowest method of session state management in ASP.NET. ASP.NET session state enables you to store and retrieve values for a user as the user navigates ASP.NET pages in a Web application. HTTP is a stateless protocol. This means that a Web server treats each HTTP request for a page as an independent request. The server retains no knowledge of variable values that were used during previous requests. ASP.NET session state identifies requests from the same browser during a limited time window as a session, and provides a way to persist variable values for the duration of that session. By default, ASP.NET session state is enabled for all ASP.NET applications. Alternatives to session state include the following: Application state, which stores variables that can be accessed by all users of an ASP.NET application. Profile properties, which persists user values in a data store without expiring them. ASP.NET caching, which stores values in memory that is available to all ASP.NET applications. View state, which persists values in a page. Cookies. The query string and fields on an HTML form that are available from an HTTP request.
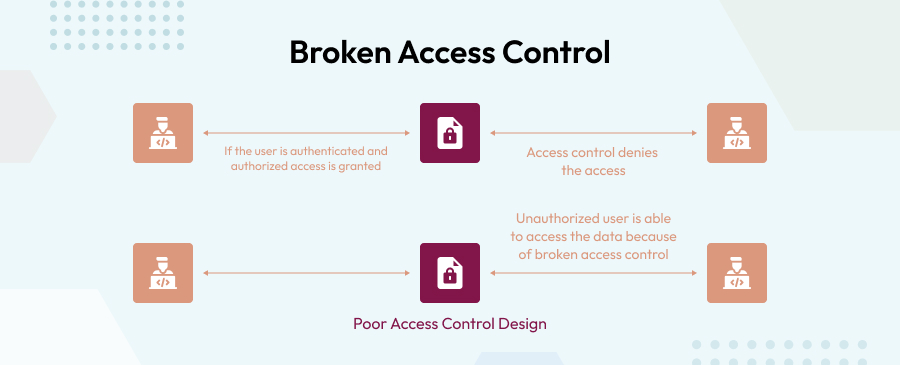
Figure 2: What is Web Application Security? - eTatvaSoft App_Code This is the "raw code" directory. The ASP.NET server automatically compiles files (and subdirectories) in this folder into an assembly accessible in the code of every page of the site. App_Code is typically used for data access abstraction code, model code and business code. Also any site-specific http handlers and modules and Web service implementation go in this directory. As an alternative to using App_Code the developer may opt to provide a separate assembly with precompiled code. App_Data The App_Data ASP.NET Directory is the default directory for any database used by the ASP.NET Website.
These databases might include Access (mdb) files or SQL Server (mdf) files. The App_Data is the only directory with Write Access enabled for the ASP.NET web application.: App_GlobalResources Holds resx files with localized resources available to every page of the site. This is where the ASP.NET developer typically stores localized messages, etc. used on more than one page. App_LocalResources E.g., a file called CheckOut.aspx.fr-FR.resx holds localized resources for the French version of the CheckOut.aspx page. When the UI culture is set to French, ASP.NET automatically finds and uses this file for localization. App_Offline.htm A file (not a directory) that disables the application by returning the contents of the file for any application request. App_Themes Adds a folder that holds files related to themes, which is a new ASP.NET feature that helps ensure a consistent appearance throughout a Web site and makes it easier to change the Web site's appearance when necessary. App_WebReferences holds discovery files and WSDL files for references to Web services to be consumed in the site. Bin Contains compiled code (.dll files) for controls, components, or other code that you want to reference in your application. Any classes represented by code in the Bin folder are automatically referenced in your application.
Compiled code means applications run faster with more design-time errors trapped at the development stage. Significantly improved run-time error handling, making use of exception handling using try-catch blocks. Similar metaphors to Microsoft Windows applications such as controls and events. An extensive set of controls and class libraries, as well as user-defined controls, allow the rapid building of applications. Layout of these controls on a page is easier because most of it can be done visually in most editors. ASP.NET uses the multi-language abilities of the .NET Common Language Runtime, allowing Web pages to be coded in VB.NET, C#, F#, Delphi.NET, etc. Ability to cache the whole page or just parts of it to improve performance. Ability to use the code-behind development model to separate business logic from presentation. Ability to use true object-oriented design for programming pages and controls If an ASP.NET application leaks memory, the ASP.NET runtime unloads the AppDomain hosting the erring application and reloads the application in a new AppDomain. Session state in ASP.NET can be saved in a Microsoft SQL Server database or in a separate process running on the same machine as the Web server or on a different machine. That way session values are not lost when the Web server is reset or the ASP.NET worker process is recycled. Versions of ASP.NET prior to 2.0 were criticized for their lack of standards compliance. The generated HTML and JavaScript sent to the client browser would not always validate against W3C/ECMA standards. In addition, the framework's browser detection feature sometimes incorrectly identified Web browsers other than Microsoft's own Internet Explorer as "downlevel" and returned HTML/JavaScript to these clients with some of the features removed, or sometimes crippled or broken. In version 2.0 however, all controls generate valid HTML 4.0, XHTML 1.0 (the default) or XHTML 1.1 output, depending on the site configuration. Detection of standards-compliant Web browsers is more robust and support for Cascading Style Sheets is more extensive. Web Server Controls: these are controls introduced by ASP.NET WebForms for providing the UI for the Web form. These controls are state-managed controls and are WYSIWYG controls.
Official documentation Web Forms on www.asp.net Introduction to ASP.NET and Web Forms (an early 2001 document) In data analysis, anomaly detection (also referred to as outlier detection and sometimes as novelty detection) is generally understood to be the identification of rare items, events or observations which deviate significantly from the majority of the data and do not conform to a well defined notion of normal behavior. Such examples may arouse suspicions of being generated by a different mechanism, or appear inconsistent with the remainder of that set of data. Anomaly detection finds application in many domains including cybersecurity, medicine, machine vision, statistics, neuroscience, law enforcement and financial fraud to name only a few. Anomalies were initially searched for clear rejection or omission from the data to aid statistical analysis, for example to compute the mean or standard deviation. They were also removed to better predictions from models such as linear regression, and more recently their removal aids the performance of machine learning algorithms.
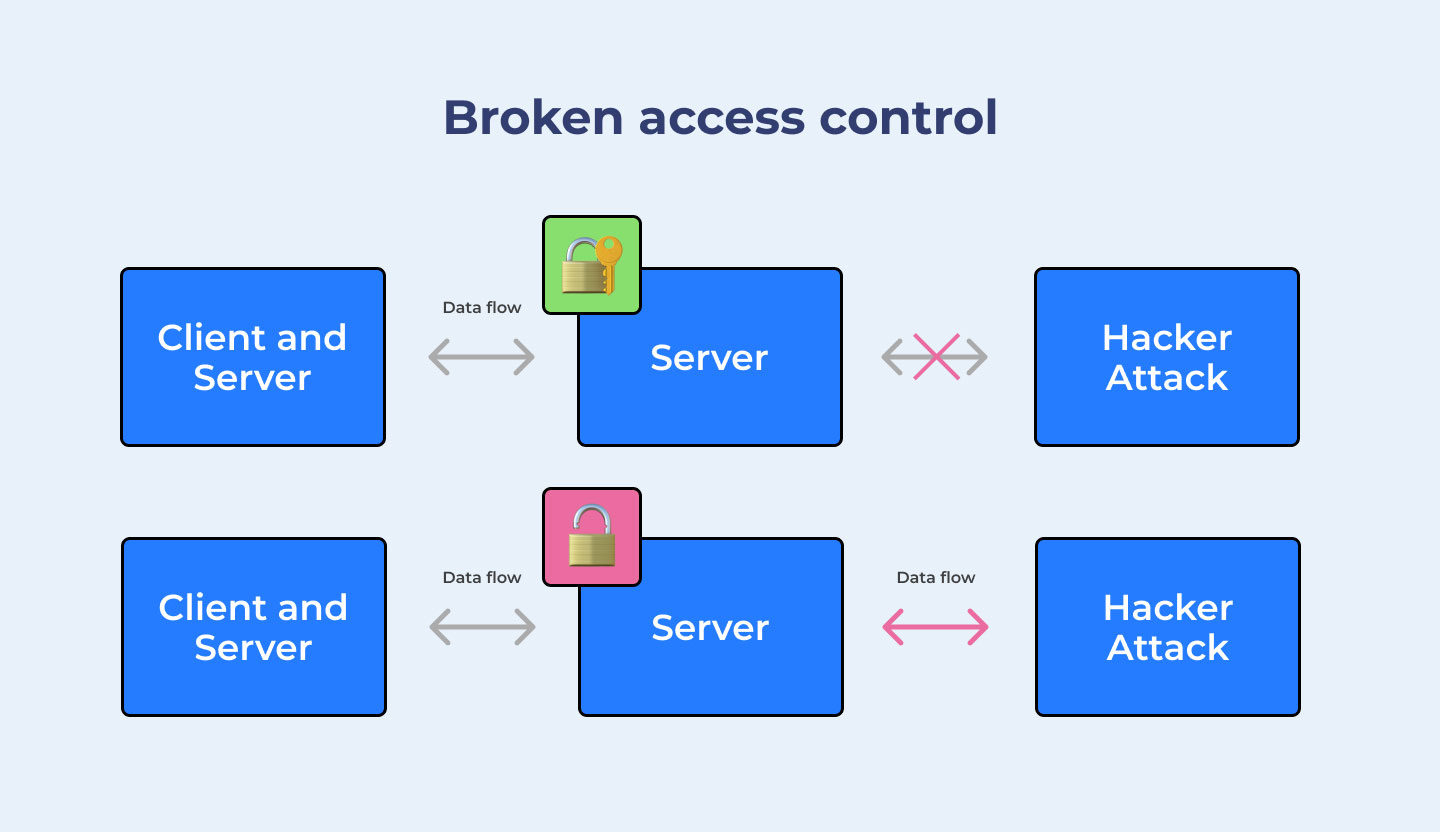
However, in many applications anomalies themselves are of interest and are the observations most desirous in the entire data set, which need to be identified and separated from noise or irrelevant outliers. Three broad categories of anomaly detection techniques exist: Figure 3: What Are The Attacks Of Access Control at Sarah Bugarin blog Supervised anomaly detection techniques require a data set that has been labeled as "normal" and "abnormal" and involves training a classifier. However, this approach is rarely used in anomaly detection due to the general unavailability of labelled data and the inherent unbalanced nature of the classes. Semi-supervised anomaly detection techniques assume that some portion of the data is labelled. This may be any combination of the normal or anomalous data, but more often than not, the techniques construct a model representing normal behavior from a given normal training data set, and then test the likelihood of a test instance to be generated by the model. Unsupervised anomaly detection techniques assume the data is unlabelled and are by far the most commonly used due to their wider and relevant application.
A point anomaly is an individual observation that is considered anomalous relative to the rest of the data e.g., an unusually large transaction may be anomalous when compared with the other transactions in a dataset. A contextual anomaly, also called a conditional anomaly, is anomalous only within a particular context. An observation may therefore be normal under one set of circumstances but anomalous under another e.g., a particular temperature may be normal in summer but unusual in winter. Context may be temporal, spatial, demographic, or otherwise defined by the application. A collective anomaly is a related collection of observations that is anomalous as a whole, even when its individual observations are not anomalous by themselves e.g., an unusual subsequence in a time series or an unexpected pattern of activity in a computer network. The appropriate category depends partly on the structure of the data. Point-anomaly methods may be sufficient for independent observations, whereas time series, spatial data, sequences, and graphs often require contextual or collective relationships to be modelled explicitly.
The Subspace Outlier Degree (SOD) identifies attributes where a sample is normal, and attributes in which the sample deviates from the expected. Correlation Outlier Probabilities (COP) compute an error vector of how a sample point deviates from an expected location, which can be interpreted as a counterfactual explanation: the sample would be normal if it were moved to that location.
Access control refers to the permissions structure that should be defined by the application. For example, your application may have separate roles for regular users and administrators. Regular users should not be able to obtain priviledged access, but administrators should! When the access control of an application is broken, a regular user may be able to access functionality that is meant to be reserved for administrators, or perhaps they can access data that does not belong to them.
In this lesson, you will learn about how broken access control vulnerabilities work and how to protect your applications against them. We will step into the shoes of a devious college student who exploits one of their university web applications to award themselves an unearned high distinction. Broken access control has recently taken the top spot in the venerable 2021 OWASP Top 10 list, knocking "injection" out of first place for the first time in the listâIIs history. This is a sign that broken access control is highly prevalent and presents very significant risks to organizations today.
"Authorization" and "authentication" are similar words that are often confused. It is important to know the difference between them. Authentication is the process of determining who someone is, while authorization is the process of determining what that person is allowed to do, or what they have access to. When people talk about broken access control, they are referring to authorization, not authentication.
In our example, your name is Ezra. You're a particularly intelligent college student with a penchant for hacking, and a willingness to break the law for personal gain ðIII. This semester, you really need to pass a Statistics class in order to graduate with a Computer Science degree. The thing is, your exam was today, and you slept through it because you were up late hacking last night. You could pay thousands of dollars and wait six months to retake the exam or you could put those hacking skills to work? It wouldn't hurt to just take a look...
You sign into the web application that allows you to check your grades, https://grades.patch.edu . You passed every subject except Statistics. It currently shows an F for Fail. Let's see if the following website is secure and protects against broken access control. We'll need our proxy interceptor but let's start the attack! If you're really observant, you may have noticed that the GET /grades route also does not contain any access control restrictions. This means that an attacker could easily view the grades of other students by guessing a valid student ID instead of their own. For example, your student ID is 20223948, so sending this request would return your grade: But if we simply change the student ID to 20223949, then we would return the grade of the student with the id 20223949! With a few minutes of coding, this process could be automated to download the grades of thousands of students, for example: What you just witnessed was a classic instance of broken access control. Of course, a student should not be able to edit their own grades, but the API did not properly enforce role-based restrictions on the server-side. While students do not see any method of updating their own grades within the UI of the application, they are still able to send specially crafted raw HTTP requests directly to the API to make these changes.
2. System Architecture & Core Working Principles The underlying code might look something like this, using the popular Falcon framework: The underlying code might look something like this, using the popular Sinatra framework: As you can see, the GET and PATCH handlers contain no access control restrictions. As a result, anyone who can send requests to the web server is able to view and update grades in the database.
As you can see, there are no access control restrictions. As a result, anyone who can send requests to the web server can view the grades of all students. As you can see, the updateGrade() function contains no access control restrictions. As a result, anyone who can send requests to the web server is able to update grades.
As you can see, the update_grade handler contains no access control restrictions. As a result, anyone who can send requests to the web server is able to update grades. Did you know you can use Snyk for free to verify that your code doesn't include this or other vulnerabilities? In recent years, application frameworks have come a long way. Unfortunately, frameworks do not yet have the capability of automatically implementing permissions structures. Permissions structures still need to be implemented by the developer, because every application has specific, custom requirements.
In most cases, the reason that access control is broken is simply because it has not been implemented, in which case, of course, the mitigation is to implement it! If we were to implement some rudimentary access control on the GET endpoint in the code above, it might look something like this: In this case, the getCurrentUser() function would return the details of the currently authenticated user. If the user's ID is not the same as the ID they are requesting, then it will return a 403 status code instead of the grade details.
The PATCH endpoint presents a different problem, because we want teachers to be able to upgrade the grades, but not students. In this instance, we need to implement role-based permissions. A rudimentary example may look like this: In this case, the getCurrentUser() function would return the details of the currently authenticated user. If the user's ID is not the same as the ID they are requesting, then it will return an "Access Denied" message instead of the grade details.
The PATCH endpoint presents a different problem, because we want teachers to be able to upgrade the grades, but not students. In this instance, we need to implement role-based permissions. A rudimentary example may look like this: In this case, the get_student_id() function would return the student ID of the currently authenticated user, based on their session token. If the user's ID is not the same as the ID they are requesting, then it will return a "Access Denied" message instead of the grade details.
Giving teachers the ability to upgrade grades is another feature of the application that might be vulnerable. We want teachers to be able to upgrade the grades, but not students. In this instance, we need to implement role-based permissions. A rudimentary example may look like this: In this case, the getCurrentUser() function would return the details of the currently authenticated user. If the user's ID is not the same as the ID they are requesting, then it will return an "Access Denied" message instead of the grade details.
Giving teachers the ability to upgrade grades is another feature of the application that might be vulnerable. We want teachers to be able to upgrade the grades, but not students. In this instance, we need to implement role-based permissions. A rudimentary example may look like this: In this case, the get_current_user_from_request() function would return the details of the currently authenticated user. If the user's ID is not the same as the ID they are requesting, then it will return an "Access Denied" message instead of the grade details.
The PATCH endpoint presents a different problem, because we want teachers to be able to upgrade the grades, but not students. In this instance, we need to implement role-based permissions. A rudimentary example may look like this: The code above will return a 403 status code unless the user's role is set to "teacher". The code above will return an "Access Denied" message unless the user's role is set to "teacher".
Which of the following best represents a secure approach to access control in applications? You have taken your first step into learning what broken access control is, how it works, what the impacts are, and how to protect your own applications. We hope that you will apply this knowledge to make your applications safer. Also, make sure to check out our lessons on other common vulnerabilities.
Access control refers to the permissions structure that should be defined by the application. When the access control of an application is broken, a regular user may be able to access functionality that is meant to be reserved for administrators, or perhaps they can access data that does not belong to them. Broken access control has recently taken the top spot in the 2021 OWASP Top 10 list, knocking "injection" out of first place for the first time in the listâIIs history. This is a sign that broken access control is highly prevalent and presents very significant risks to organizations today.
When designing a permissions structure for your application, it is best to implement a "deny by default" mentality. That is, we should deny all requests to all endpoints by default, and require allowlisting specific users/roles for any interaction to occur with that endpoint. Authorization and authentication are similar words that are often confused. Authentication is the process of determining who someone is, while authorization is the process of determining what that person is allowed to do, or what they have access to.
3. Software Implementation, Frameworks & Protocols Broken access control is the flaw where an application lets you do things it should have stopped you from doing: reading another user's data, hitting an admin page you were never granted, or editing a record that belongs to someone else. It sits at number one on the OWASP Top 10 because it is both everywhere and easy to miss. The fastest way to understand it is to break one yourself, so open HackerDNA's IDOR Explorer lab and change an ID or two as you read.
This risk earned the top slot in the OWASP Top 10 and kept it in the 2025 edition, which even folded Server-Side Request Forgery in as a sub-case. This guide covers what broken access control is, the main types you will meet (including IDOR), how the attack works step by step, how to test for it, and how to shut it down in your own code. TL;DR: Broken access control happens when an app authenticates a user but never checks whether that user is authorized for the specific action or record they requested. The most common form is IDOR: swap id=1043 for id=1044 and read a stranger's invoice. The fix is not a better filter, it is a server-side authorization check on every request, tied to the logged-in user, denying by default. You learn to spot it by exploiting it, so practice in a browser lab before you try to defend against it.
Broken access control is a web vulnerability where an application does not correctly enforce what an authenticated user is permitted to see or do. The user logs in fine, but the app then trusts them with data or actions that should be restricted, because the authorization check is missing, weak, or applied in the wrong place. The key distinction is authentication versus authorization. Authentication answers "who are you?" and most apps get it right.
Authorization answers "are you allowed to do this specific thing?" and that is where they fail. An app can know exactly who you are and still hand you the admin dashboard because nobody wrote the check that says you are not an admin. That gap is why this class is so common. Login systems get hammered on by every developer and every scanner. The per-object, per-action permission checks are scattered across hundreds of endpoints, and it only takes one endpoint that forgot to ask "does this record belong to the caller?" to leak the whole table. OWASP's data backs this up: broken access control was found in more tested applications than any other category, which is exactly why it ranks first.
A broken access control attack has three moving parts: a valid session, a reference or action you are not supposed to control, and a server that checks identity but not permission. The flow is short. Consider an app that serves your profile at GET /api/user/2001/details . The server confirms you are logged in, then returns whatever user ID is in the path. Send GET /api/user/2002/details and, on a vulnerable app, you get the next person's details.
You never broke the login, you just asked for something you should not have been allowed to have, and the server said yes. When testing real applications, the first thing worth doing is capturing two accounts. Log in as user A, record a request that touches A's data, then replay it with A's session but B's identifier. If A can read or change B's resources, you have a confirmed access control flaw with a clean, repeatable proof, which is exactly what a report needs.
Broken access control is a category, not a single bug. These are the forms you will actually run into, roughly in order of how often they turn up in real testing. An IDOR exposes an internal reference (a database ID, filename, or key) and lets a user swap it for one they do not own. It is the poster child of this category and gets its own section below because it is so common.
This is a low-privilege user reaching high-privilege functions. A regular account that can load /admin/users or call an admin-only API is escalating vertically, moving up the permission ladder to actions reserved for a higher role. Here you stay at the same privilege level but reach a peer's data. User A reading user B's messages is horizontal escalation. Most IDORs are horizontal: same role, different owner, no check that the owner is you.
Some apps hide a page by simply not linking to it, assuming nobody will find the URL. That is security by obscurity, and it fails the moment someone guesses /admin , reads it in JavaScript, or finds it in the sitemap. If the server does not check the role when the page loads, the hidden link was the only lock. Access decisions built on client-controlled data break when the client changes that data. A JWT with "role":"user" that the server trusts without verifying the signature, a X-Original-URL header that reroutes around a path check, or an endpoint that blocks POST but not PUT are all access control failures dressed up in protocol details.
Insecure Direct Object Reference (IDOR) is a broken access control flaw where an application uses a user-supplied value to fetch an object directly, without checking that the requester is allowed to access that object. Change the value, get a different object. It maps to CWE-639 and is the single most reported form of access control failure in bug bounty programs. Our IDOR vulnerability guide covers the hunting workflow and the fixes in far more depth.
The classic case is the invoice. You view your own at /invoice?id=1043 , change the number to 1044 , and the app hands you someone else's, because it verified you were logged in but never verified that invoice 1044 was yours. The same shape appears with usernames ( /profile/alice becomes /profile/bob ), filenames ( /download?file=report_2024.pdf ), and API paths ( /api/orders/58210 ).
IDOR is dangerous precisely because it is boring to exploit. There is no clever payload, no encoding trick, no race condition. You increment a number. That low bar is why automated ID enumeration through a tool like Burp Intruder can pull thousands of records from a single vulnerable endpoint in minutes, and why an IDOR on a sensitive object is often triaged as high or critical severity.
A common defense you should not trust is swapping sequential IDs for UUIDs. Random identifiers make guessing harder, which raises the bar, but they are not authorization. If a UUID leaks through a referrer header, an export, or a shared link, and the server still does not check ownership, the IDOR is intact. UUIDs are a speed bump, not a control. How do you test for broken access control? Log in with two separate accounts, capture the requests one account makes to its own resources, then replay those requests using the other account's session and someone else's identifiers. If the server returns data or performs actions it should have blocked, access control is broken. Automated scanners miss most of these, because only a human knows which record should have belonged to whom.
In practice, the finding that surprises teams most is the "hidden" admin API. The front end never shows the control to a normal user, so everyone assumes it is safe, but the endpoint answers a direct request from any logged-in account. The UI was doing the access control the server forgot to do. That is the everyday face of this vulnerability. How do you prevent broken access control? Enforce authorization on the server for every request, deny by default, and tie each access decision to the authenticated session rather than to any value the client sends. Never rely on hiding a link or disabling a button, because the client is fully under the attacker's control.
The mitigation teams most often get wrong is checking access at the wrong layer. A gateway that confirms you are logged in is not the same as a service that confirms you own the record, and putting the only check at the edge leaves every internal call unguarded. Validate ownership where the data is served, tied to the session, and the whole class largely closes. Broken access control has been the number one entry since the 2021 edition and held that position in the OWASP Top 10 2025 . It ranks first on the data: OWASP found some form of access control weakness in a larger share of tested applications than any other category, and the impact ranges from reading one extra record to full administrative takeover.
The 2025 revision made the category broader. Server-Side Request Forgery, which had its own tenth slot in 2021, was reclassified as a sub-case of broken access control, on the reasoning that SSRF is fundamentally the server making a request it was never authorized to make. If you want the SSRF angle specifically, our SSRF attack guide covers the cloud-metadata and internal-service targets that make it dangerous.
For the full map of where this risk sits among the ten and what shifted between the 2021 and 2025 lists, our OWASP Top 10 guide walks every category with a worked example. Access control failures also overlap with injection flaws in practice, so it is worth reading alongside our SQL injection tutorial , where a single query can dump records no user should reach. Critical reminder: Always get explicit written authorization before testing any system for broken access control. Changing an ID to read another user's data on a target you do not own is unauthorized access under the Computer Fraud and Abuse Act (US), the Computer Misuse Act (UK), and equivalent laws worldwide, even when the change is as small as typing a different number.
4. Practical Deployment, Analysis & Case Studies Broken access control is when an app lets a logged-in user do something they should not be allowed to do, like viewing another person's account or reaching an admin page. The app checks who you are but forgets to check whether you are permitted to perform that specific action, so it hands over data or powers that should be restricted.
Broken access control is the broad category of authorization failures. IDOR (Insecure Direct Object Reference) is one specific type within it, where changing a reference like an ID or filename gives you access to an object you do not own. Every IDOR is a broken access control flaw, but not every access control flaw is an IDOR. OWASP ranks it first because its data showed some form of access control weakness in a larger share of tested applications than any other category, and the impact is high. A single missing authorization check can expose every record in a table or grant full administrative control, and these checks are spread across so many endpoints that one is almost always forgotten.
Enforce authorization on the server for every request, deny access by default, and base each decision on the authenticated session rather than on values the client sends. Check that the logged-in user owns the specific object before returning it, centralize the logic in one layer, and never rely on hidden links or disabled buttons, which the client can bypass. No. Replacing sequential IDs with random UUIDs makes references harder to guess, which slows enumeration, but it is not an authorization check. If a UUID leaks through a link, export, or referrer header and the server still does not verify ownership, the IDOR remains exploitable. UUIDs are a speed bump, not a control.
Broken access control clicks the moment you exploit one yourself: change a single number, watch a stranger's data load, and the reason it tops the OWASP Top 10 stops being abstract. Reading that authorization should be checked server-side is one thing, seeing an app forget to and hand you the admin panel is another. Reach files that were never meant for you in the IDOR Explorer lab . When you want access control in the context of the full attack surface, the Web Attacks course walks through it alongside SQL injection, XSS, and the rest of the OWASP Top 10 in guided browser labs. Start with HackerDNA's free tier, no credit card required. Learn to spot the missing check, then go write the one that stops it.
Written by the HackerDNA team - cybersecurity professionals building hands-on hacking labs and educational content to help you develop real-world security skills. Broken access control is the single highest-ranked risk in the OWASP Top 10 — and has been for every revision of the list since 2021. The reason is not subtle: access control is the hardest of the major security categories to get right, the most stack-specific, and the category where the failure mode is almost always a quiet "an authenticated user reached data or operations they should not have" rather than a dramatic exploit. Broken access control owasp — A01 — shows up as IDOR in API responses, as privilege-escalation holes in admin panels, as forgotten role checks in newly added endpoints, as JWT claims that are trusted when they should be verified, as forced-browsing attacks that succeed because the authorization check was forgotten. This guide walks what broken access control actually is, the patterns every 2026 pentest report finds variants of, concrete examples of each in modern web and API stacks, the testing methodology that catches the issues before production, and the engineering playbook that turns authorization from a recurring incident category into a property of the architecture.
Access control is the mechanism that decides whether an authenticated user is allowed to perform a specific operation on a specific resource. Authentication is "who are you"; access control — also called authorization — is "what are you allowed to do." Broken access control is the vulnerability class that arises when the authorization check is missing, incorrect, or bypassable. The authenticated user reaches a resource they should not reach, performs an operation they should not perform, or obtains privileges they should not have — not because the authentication was bypassed, but because the authorization layer on top of authentication failed.
The distinction matters because the mitigations are different. Authentication failures are fixed with stronger auth protocols, MFA, session management, and credential hygiene. Access control failures are fixed with architectural choices about how authorization decisions are expressed, where in the request path they are enforced, and how the application's data model enables or frustrates the checks. A system with perfect authentication and broken authorization is catastrophically insecure — every logged-in user can potentially do every operation — and the authentication layer, however well-engineered, does not save it. For an end-to-end view of how the authentication and authorization layers interact on real API surfaces — token formats, scope design, propagation across services — see our API authentication and authorization developer guide .
The OWASP Top 10 has ranked access control as A01 — the top risk — since the 2021 revision, and the 2025 list keeps the ranking. The data justifying the ranking is consistent: access control findings appear in the majority of pentest reports, account for a disproportionate share of bug bounty payouts, and show up in nearly every major breach post-mortem that involves data exposure rather than infrastructure compromise. The ranking reflects prevalence, severity, and the difficulty of remediation — the three properties that make a vulnerability category operationally expensive.
The formal OWASP definition of owasp broken access control enumerates a specific list of failure conditions. Every pentest report, every automated scanner, and every compliance audit will reference this list, so understanding each is worth the paragraph. Each of these failure modes has a specific remediation pattern, and a mature program addresses each explicitly. The failure mode that dominates in practice, however, is IDOR — insecure direct object reference — which accounts for the single largest share of access-control findings in both pentest data and bug-bounty leaderboards. The other failure modes show up frequently enough to be named, but IDOR is the category that every reviewer looks for first.
The OWASP enumeration above is formal. The patterns that engineering teams meet in production collapse to a smaller set of five recurring shapes. Each is preventable; each recurs when the prevention is not institutional. 1. IDOR — Insecure Direct Object Reference. An endpoint accepts an identifier as input (a user ID, a document ID, an order ID) and returns the resource corresponding to that identifier without checking whether the authenticated user is authorized to access it. An attacker modifies the identifier in the request — from GET /api/orders/1001 to GET /api/orders/1002 — and reads a resource belonging to another user. IDOR is the single most common access control vulnerability in 2026, and its prevalence traces to a specific architectural mistake: the application trusts the identifier in the request rather than deriving the accessible resource from the authenticated session.
2. Missing function-level access control. A newly-added endpoint lacks the authorization check that exists on comparable older endpoints. The endpoint is an admin operation but is accessible to any authenticated user because the route was created, shipped, and forgotten by the authorization layer. The pattern is especially common when authorization checks are implemented per-endpoint rather than centrally — each endpoint's author has to remember to add the check, and any one forgetting breaks the system.
3. Vertical privilege escalation. A regular user is able to perform an operation reserved for users with a higher role — admin, moderator, staff. The escalation can happen through a missing function-level check (see pattern 2), through metadata tampering (changing a role claim in a JWT), through a race condition during role transitions, or through a feature that was designed to be role-restricted but whose restriction was implemented on the client side only.
4. Horizontal privilege escalation. A user is able to perform operations that are authorized at their role level but scoped to a different user's resources. User A edits User B's profile, reads User B's messages, or cancels User B's order. The failure is that the application correctly checks "is the user authorized for this operation class" but fails to check "is the user authorized for this specific resource." IDOR is typically a horizontal escalation; the distinction between "IDOR" and "horizontal escalation" is semantic rather than operational.
IDOR earns its own section because its share of real-world findings is so large. The pattern is consistent: an endpoint accepts a resource identifier as input, looks up the resource, and returns it — without checking that the authenticated user has a relationship to the resource that justifies access. The classic pattern. An API endpoint GET /api/users/{userId}/orders/{orderId} takes a user ID and an order ID and returns the order. The application validates that the caller is authenticated, looks up the order by orderId , and returns it. The caller's own user ID is never compared against the userId in the URL, and the order's owner is never compared against the caller. An attacker sets userId and orderId to values that belong to another user; the query succeeds; the response leaks.
The architectural fix. The application does not accept the resource identifier from the URL as trusted input. Instead, the authenticated session identifies the user, and the query derives the accessible resources from the session. An endpoint GET /api/orders/{orderId} still looks up the order by ID, but the lookup is constrained by the authenticated user: SELECT * FROM orders WHERE id = ? AND user_id = ? . If the order does not belong to the user, the query returns no rows, and the application returns 404 (or 403, with tradeoffs discussed below). The identifier is still in the URL, but the authorization is derived from the session, not the URL.
The 404 vs 403 decision. When an IDOR attempt is blocked, should the response be 404 (resource not found) or 403 (forbidden)? The tradeoff: 404 avoids confirming to the attacker that the resource exists (which is itself information leakage — username enumeration, order-ID enumeration); 403 is more honest about the failure mode but leaks the information. The prevailing recommendation in 2026 is 404 for resources where existence is itself sensitive (payment records, medical data, private documents) and 403 for resources where existence is public but access is restricted (published articles with private edit operations). The decision is context-dependent and should be documented in the API's security conventions.
UUIDs are not a fix. A common misunderstanding is that using UUIDs instead of sequential integers for resource IDs prevents IDOR. UUIDs make enumeration harder but do not make it impossible — references leak through logs, API responses, shared links, and bug reports. Treating UUID adoption as an IDOR mitigation is the classic security-through-obscurity mistake. Use UUIDs for the unrelated reason that they are database-friendly; fix IDOR through authorization checks, not identifier choice.
GraphQL and batch endpoints. GraphQL APIs and batch-request endpoints have a pattern-specific IDOR risk: the request includes a list of identifiers, and the resolver iterates over them and returns the matched resources. If the authorization check is per-request rather than per-identifier, the attacker can include arbitrary IDs in the list and receive data for all of them. The mitigation is to apply the authorization check inside the resolver for each identifier, or to express the query such that the database-level filter includes the user constraint for every lookup.
Where IDOR fails horizontally (user accessing user's resources), function-level failures fail vertically (regular user accessing admin functions). The pattern's prevalence traces to a specific anti-pattern: decentralized per-endpoint authorization enforcement. The decentralized pattern. Each endpoint's author is responsible for including the appropriate authorization check at the start of the handler. The admin-delete-user endpoint starts with if (!user.isAdmin) return 403; . The admin-view-audit-log endpoint starts with the same check. The admin-billing-export endpoint starts with the same check. The new endpoint added last week for admin-feature-flag — shipped by a developer who did not notice that the convention exists — has no such check, and every authenticated user can toggle feature flags.
The centralized alternative. Authorization is expressed declaratively at the route level — a middleware, a decorator, or a framework-level policy that maps routes to required permissions. The developer declares the route's requirement ( @require_permission("admin:feature-flags") ); the framework enforces it. The developer cannot ship an endpoint without a declared permission because the framework rejects it; the default behavior on a missing declaration is deny, not allow. This pattern turns "forgot the check" from a security incident into a compile-time or startup-time error.
5. Performance Evaluation & Extended Technical Observations RBAC vs ABAC vs ReBAC. Three competing models for expressing authorization. Role-Based Access Control (RBAC) assigns roles to users and permissions to roles — simple, widely understood, but struggles with fine-grained or context-dependent authorization. Attribute-Based Access Control (ABAC) evaluates policies against user attributes, resource attributes, and environmental attributes at request time — more expressive, more operationally complex. Relationship-Based Access Control (ReBAC), popularized by Google's Zanzibar and its open-source descendants (SpiceDB, OpenFGA, Permify), models authorization as relationships between subjects and objects and answers queries like "does user X have permission Y on object Z" — well-suited to applications with complex sharing semantics (documents shared with teams, projects with members, folders with inherited permissions).
The 2026 pattern. Most greenfield applications in 2026 start with RBAC and migrate to ReBAC when sharing semantics become complex enough to justify the investment. ABAC is less common in general-purpose applications but remains the standard for regulated environments (finance, healthcare) where context-dependent policies (time-of-day restrictions, location-based access, data-classification-driven access) are material.
Vertical escalation. A regular user reaches a higher-privilege role. The vectors include: (a) missing function-level access control on admin endpoints; (b) JWT claims that encode the role but are not verified or are verified with a weak algorithm; (c) session fixation where the session's role claim can be set by the client; (d) race conditions during role promotion or demotion; (e) self-service role requests that are inadvertently granted without approval; (f) indirect paths through features that delegate privilege (a shared admin token, a webhook that executes with elevated privileges).
The primary defense against vertical escalation is centralized, declarative authorization at the endpoint level — discussed above — combined with secure role storage. Roles should be stored server-side, referenced from the session, and never trusted when they arrive as a client-supplied claim. Systems that encode roles in JWTs must verify the JWT signature with a secure algorithm and reject tokens with disabled algorithm fields (the "alg: none" attack).
Horizontal escalation. A user at a given role reaches another user's resources at the same role. IDOR is the primary vector, but horizontal escalation also occurs through shared session keys, insufficient resource ownership checks on update operations, and flows that pass resources between users where the receiving user's ownership is not properly established. The primary defense against horizontal escalation is resource-ownership verification on every access — the authorization check not only confirms the user's role but also the user's relationship to the specific resource being accessed. The pattern scales best when the ownership constraint is pushed into the data-access layer (query-level filters, row-level security in the database) rather than added as an ad-hoc check in each handler.
JWTs have become the default session and authorization token format for 2026 web and API stacks, and their flexibility has created a family of access control vulnerabilities that are specific to the token-based model. The "alg: none" attack. A JWT's header specifies the signature algorithm. Some libraries historically accepted alg: none — meaning "no signature" — and treated the token as valid. An attacker crafted a token with alg: none and arbitrary claims, and the server accepted it. The remediation is to configure JWT verification with an explicit allowlist of algorithms and reject any token that specifies an algorithm outside the list. Modern libraries default to safe behavior, but configuration mistakes still occur in the wild.
Algorithm confusion attacks. A JWT issuer signs tokens with RS256 (asymmetric, private-key signing). A misconfigured verifier accepts HS256 (symmetric, shared-key signing) and uses the public key as the symmetric key. An attacker obtains the public key (typically from a JWKS endpoint) and signs an arbitrary token with it; the verifier accepts the token. The remediation is the same algorithm allowlist — explicitly require RS256 or whatever the expected algorithm is.
Trusting unverified claims. A service downstream of the JWT-issuing service extracts claims from the token and uses them for authorization decisions, but does not verify the signature. The assumption is that "the token was already verified upstream." The assumption fails when the service is reached through a path that bypasses the upstream verification — directly, through a misconfigured service mesh, or through a tunnel that legitimate internal traffic uses. Every service that makes authorization decisions from a token must verify the token itself.
Revocation and refresh failures. JWTs are typically valid until their expiration; a token stolen one minute after issuance is usable until expiration even if the user has logged out or had their role changed. The mitigation patterns — token revocation lists, short access-token lifetimes with refresh rotation, server-side session stores — each have tradeoffs, and the right combination depends on the system's risk tolerance. Systems that use long-lived JWTs without a revocation mechanism accept the risk that a compromised token remains usable until expiration.
Claim injection. An attacker adds arbitrary claims to a JWT (role, tenant, scope) that the issuer did not include. If the verifier trusts any claim that is present in the token — rather than trusting only claims the issuer is expected to include — the attacker can escalate privileges. The remediation is that the verifier's policy explicitly names which claims are authoritative from which issuer.
Access control is notoriously difficult to test automatically because the correct authorization decision depends on the application's data model and business logic, neither of which a generic scanner can infer. The testing patterns that work combine automated coverage with disciplined manual review. Two-user testing. The baseline method: create two test users (or two test admins, and so on for each role), perform every operation as each, and verify that cross-user operations fail. For an API endpoint GET /api/orders/{id} , log in as User A, create an order, record the ID; log in as User B, attempt to retrieve the order by ID; verify the response is 404 or 403. This two-user pattern, extended to cover every endpoint and every role combination, catches the majority of IDOR and horizontal-escalation findings.
Automated authorization testing in CI. Integration tests that encode the authorization model as a test matrix — for each endpoint, for each role, for each ownership condition, assert the expected allow/deny behavior. Tools like ZAP and Burp Suite Pro can extend this with automated fuzzing of authorization parameters, but the test matrix itself has to come from the authorization model; a fuzzer without the model can only find trivial cases. The test matrix scales with the endpoints times roles times resource-ownership dimensions, which is substantial for a mature application but manageable with code-generation from the authorization declarations.
Manual testing during threat modeling. The threat modeling session is where access control should get structured attention during design. For each endpoint or operation in the design, walk STRIDE's "Elevation of privilege" category and ask: what authorization check enforces this, where is it enforced, how is it tested, what happens when the check is absent? Access control issues found at design time cost a fraction of what they cost to fix after ship.
Code review with an authorization lens. Every pull request that adds or changes an endpoint includes review for authorization — the check is present, the check is correct, the check uses the centralized mechanism rather than an ad-hoc re-implementation, the check covers both vertical (role) and horizontal (resource ownership) dimensions. Code review without an authorization lens consistently misses the class; review with an explicit authorization checklist consistently catches it.
Pentest and bug bounty. External testing captures the cases that internal testing misses — especially business-logic edge cases and multi-step flows where the authorization check is present at each step but the flow as a whole produces an unauthorized outcome. The findings from external testing should feed back into the test matrix so that the next pentest does not find the same class again.
Injection has a generic fix (parameterized queries) that works across contexts. Broken access control has no generic fix — the correct authorization decision depends on the application's data model, its sharing semantics, and its role structure. That specificity is exactly why language- and context-specific training beats generic awareness content for this category. SecureCodingHub builds the stack-aware, authorization-aware fluency that turns A01 from a recurring pentest finding into something developers catch at code-review time. If you're tired of every pentest producing another IDOR report, we'd be glad to show you how our program changes that input.
The patterns above converge on a specific engineering discipline. Access control is not a tool you buy; it is an architectural decision that shapes how authorization is expressed, where it is enforced, and how it is tested. Deny by default. The default for every route, every resource, every operation is deny. Access is granted by explicit declaration — a permission attached to a route, a policy evaluated at request time, a relationship recorded in the authorization store. A missing declaration means denial, not access. This inverts the common failure mode (forgot the check → open access) into its safe version (forgot the check → startup error or 403).
Centralize authorization enforcement. The authorization check runs in one place — a middleware layer, a decorator system, a service-mesh policy, or a dedicated authorization service — rather than being re-implemented per-endpoint. Centralization has two properties: every request is subject to the check, and changes to the authorization model propagate to every enforcement point automatically.
Derive resources from the session, not from the request. For IDOR-prevention specifically, the application's data access layer should take the authenticated session as a primary input and return only the resources the session is authorized to access. A developer who writes a query without the session filter is writing a query that can leak across tenants; pushing the filter into the data layer (query helpers that require the session, row-level security in the database) makes the safe path the default.
Verify tokens at every service. Every service that makes authorization decisions from a token verifies the token itself, with an explicit algorithm allowlist and an explicit list of trusted issuers. Token verification is not the upstream service's responsibility alone; it is every downstream service's responsibility. Write the authorization model as code. The application's authorization model — what roles exist, what permissions they have, what resource-ownership relationships govern access — is expressed in version-controlled code, not in a diagram or a wiki page. The code is the authoritative source; any deviation in the deployed behavior is a bug in the code, not a policy ambiguity.
Test the authorization matrix. A test matrix of (endpoint × role × ownership-condition) with expected allow/deny outcomes runs in CI. The matrix can be generated from the authorization declarations themselves, which keeps it in sync with the model as the model evolves. New endpoints that do not appear in the matrix fail CI. Train developers on the category's specificity. Access control does not reduce to a generic fix; it requires developers to reason about the application's data model and the user's relationship to each resource. Language- and stack-specific training that walks authorization patterns in the actual framework the developer uses produces stronger outcomes than generic awareness content that explains "check authorization" in the abstract.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Application%20security • https://en.wikipedia.org/wiki/ASP.NET%20Web%20Forms • https://en.wikipedia.org/wiki/Anomaly%20detection • https://learn.snyk.io/lesson/broken-access-control/ • https://hackerdna.com/blog/broken-access-control • https://www.securecodinghub.com/blog/broken-access-control-owasp-explained
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Broken Access Control Detection System In Web Applications.
[*] Initializing Burp Suite Spider & Vulnerability Engine for Broken Access Control Detection System In Web Applications... [✓] Burp Extender / Macro Automation Hook Synced ──────────────────────────────────────────────────────────────────────── [11:42:01.104] AUDIT Crawled dynamic endpoints | Injecting input vectors [11:42:01.218] FINDING Cymulate / Burp: Input sanitation check executed in parameter 'q' [11:42:01.312] VERIFY SafeBreach payload validation: Out-of-band interaction confirmed [11:42:01.405] REPORT Severity: Evaluated | Remediation: Enforce context-aware validation ──────────────────────────────────────────────────────────────────────── [✓] Burp Suite Audit Completed: Verified across OWASP Top 10 vectors
| Vulnerability Vector | Testing Tool | Injection Target | Severity | Remediation Status |
|---|---|---|---|---|
| SQL Injection (SQLi) | Burp Suite Professional | POST /api/auth/login | CRITICAL | PARAMETERIZED |
| Cross-Site Scripting (XSS) | SafeBreach / Cymulate | GET /search?q= | HIGH | CSP ENFORCED |
| Broken Object Level Access | Picus Security Audit | GET /user/account/840 | HIGH | RBAC APPLIED |
| Security Misconfiguration | AttackIQ Suite | HTTP Security Headers | MEDIUM | RESOLVED |