Complete Technical Paper Content — Bug Bounty Workflow Automation
Overview & System Context
Bug Bounty Workflow Automation: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9575 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background In programming and software development, fuzzing or fuzz testing is an automated software testing technique that involves providing invalid, unexpected, or random data as inputs to a computer program. The program is then monitored for exceptions such as crashes, failing built-in code assertions, or potential memory leaks. Typically, fuzzers are used to test programs that take structured inputs. This structure is specified, such as in a file format or protocol and distinguishes valid from invalid input.
An effective fuzzer generates semi-valid inputs that are "valid enough" in that they are not directly rejected by the parser, but do create unexpected behaviors deeper in the program and are "invalid enough" to expose corner cases that have not been properly dealt with. For the purpose of security, input that crosses a trust boundary is often the most useful. For example, it is more important to fuzz code that handles a file uploaded by any user than it is to fuzz the code that parses a configuration file that is accessible only to a privileged user.
A fuzzer can be generation-based or mutation-based depending on whether inputs are generated from scratch or by modifying existing inputs. A fuzzer can be dumb (unstructured) or smart (structured) depending on whether it is aware of input structure. A fuzzer can be white-, grey-, or black-box, depending on whether it is aware of program structure. to detect memory related errors, such as buffer overflows and use-after-free (using memory debuggers such as AddressSanitizer), to detect race conditions and deadlocks (ThreadSanitizer), to detect undefined behavior (UndefinedBehaviorSanitizer), to detect memory leaks (LeakSanitizer), or to check control-flow integrity (CFISanitizer).
Fuzzing can also be used to detect "differential" bugs if a reference implementation is available. For automated regression testing, the generated inputs are executed on two versions of the same program. For automated differential testing, the generated inputs are executed on two implementations of the same program (e.g., lighttpd and httpd are both implementations of a web server). If the two variants produce different output for the same input, then one may be buggy and should be examined more closely.
Preparation of inputs Choose a fuzzer. Choose software or a library as the fuzz target. Prepare a seed corpus from existing test inputs or hand-craft inputs for the fuzzer to mutate. Seeds give the fuzzer starting inputs that can be modified into new test cases. Optionally prepare a dictionary, a file that specifies interesting tokens or keywords for a fuzz target. Input generation and mutation The fuzzer will create new test cases from the seeds. Execution The fuzz target will be run with each generated input. Sanitizers such as AddressSanitizer and UndefinedBehaviorSanitizer are also often used when building or configuring the target to detect certain classes of programming errors during execution. Feedback and coverage Feedback-guided fuzzers use feedback, such as code coverage, to guide the generation of future inputs. However, this is depending on the fuzzer, not all fuzzers use coverage feedback. Interesting inputs, such as those that reach previously unexplored behavior, can be retained for further mutation. Iteration The process is repeated to explore more program behavior and potentially find bugs.
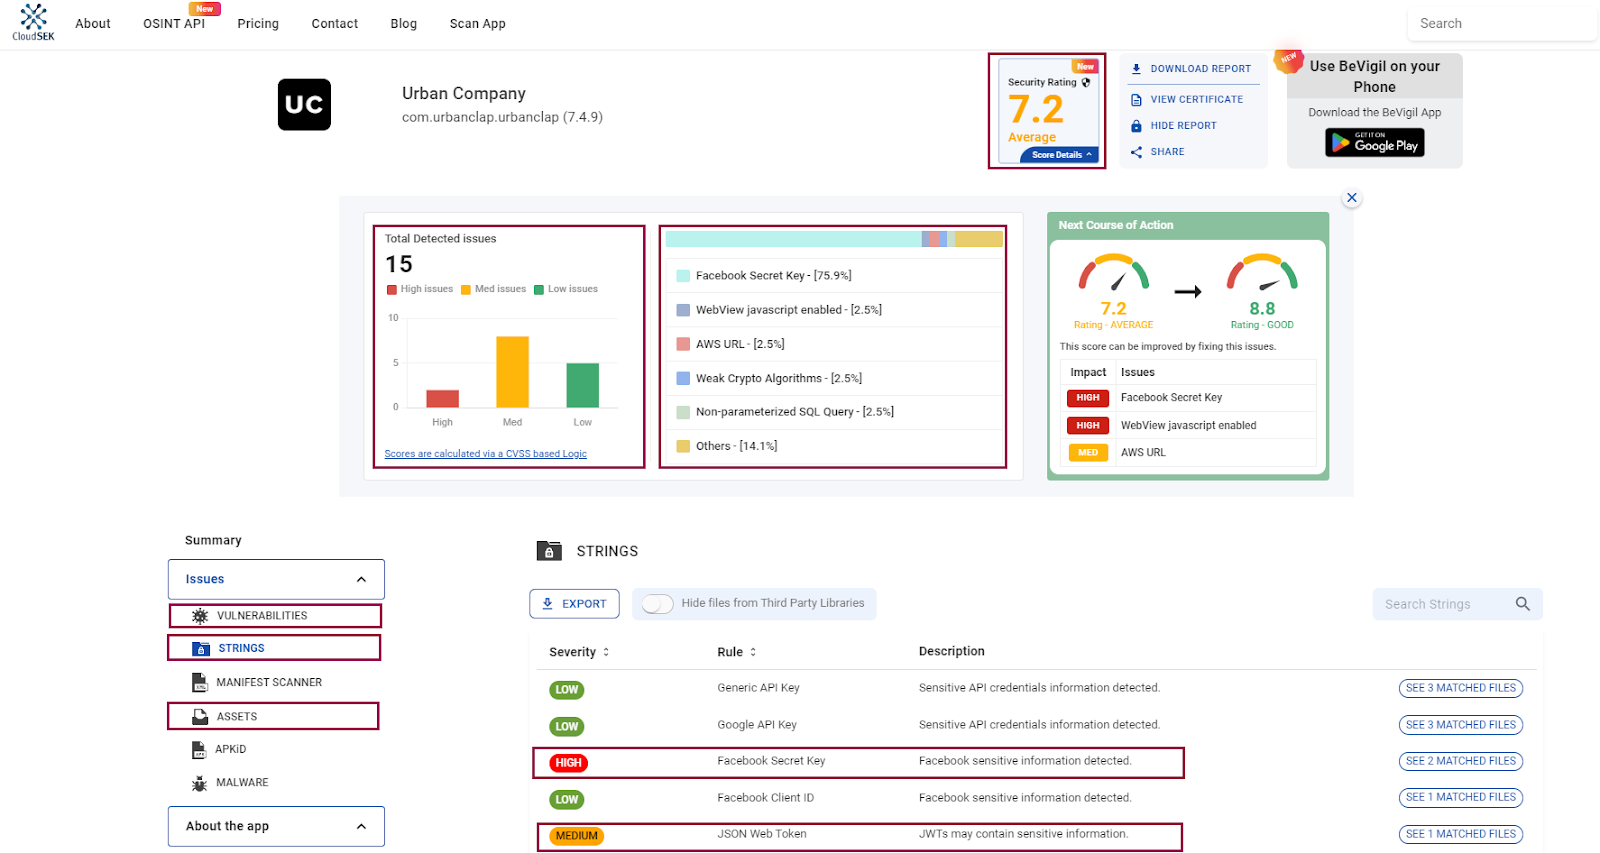
Figure 1: Unleashing the Full Potential of Bug Bounty Programs with BeVigil ... Automated bug triage is used to group a large number of failure-inducing inputs by root cause and to prioritize each individual bug by severity. A fuzzer produces a large number of inputs, and many of the failure-inducing ones may effectively expose the same software bug. Only some of these bugs are security-critical and should be patched with higher priority. For instance the CERT Coordination Center provides the Linux triage tools which group crashing inputs by the produced stack trace and lists each group according to their probability to be exploitable. The Microsoft Security Research Centre (MSEC) developed the "!exploitable" tool which first creates a hash for a crashing input to determine its uniqueness and then assigns an exploitability rating: Exploitable Probably Exploitable Probably Not Exploitable, or Unknown. Previously unreported, triaged bugs might be automatically reported to a bug tracking system. For instance, OSS-Fuzz runs large-scale, long-running fuzzing campaigns for several security-critical software projects where each previously unreported, distinct bug is reported directly to a bug tracker.
The OSS-Fuzz bug tracker automatically informs the maintainer of the vulnerable software and checks in regular intervals whether the bug has been fixed in the most recent revision using the uploaded minimized failure-inducing input. The following is a list of fuzzers described as "popular", "widely used", or similar in the academic literature. An AI agent is an artificial intelligence program that can make decisions, pursue goals, and take actions independently of human programmers. Agentic AI contrasts with tool-like AI use for narrow, specific tasks such as answering questions - as with chatbots in the non-agentic forms that were common in 2023, or with traditional machine learning algorithms. While there is no universally agreed-upon definition of an AI agent, common attributes of AI agents include goal-directed behavior, use of external tools, the ability to interact with and modify an external environment, and the ability to autonomously perform multi-step tasks. Their control flow is frequently driven by large language models (LLMs). Agent systems may also include memory components, planning logic, tool interfaces, and orchestration software for coordinating agent components.
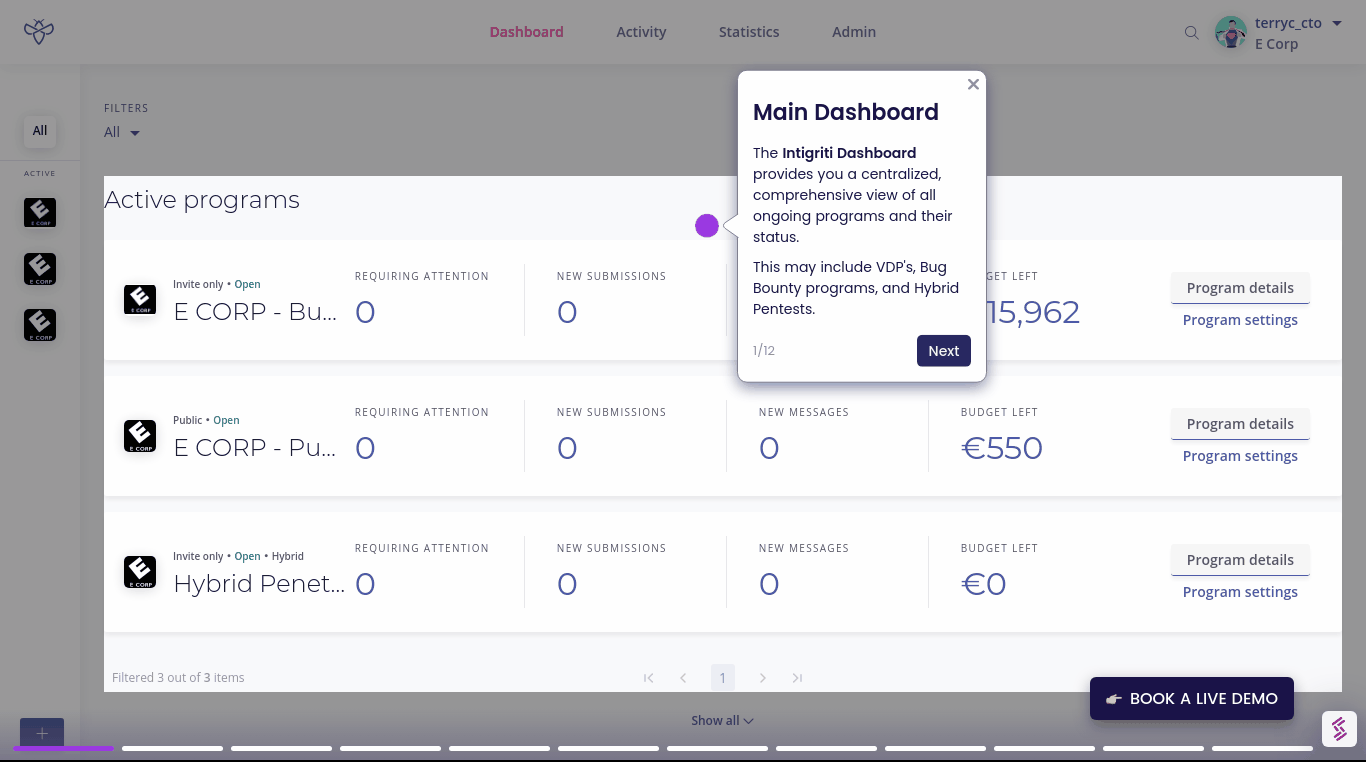
Figure 2: Bug Bounty & Agile Pentesting Platform | Intigriti The theoretical underpinnings for artificial agents emerged in the mid 20th century, with establishment of cybernetics and artificial intelligence. Oliver Selfridge's 1958 "Pandemonium: A Paradigm for Learning" paper was an important early theoretical contribution in establishing agent oriented architecture. Practical implementations of agents for real world applications began to become widespread in the 1990s, after the introduction of the belief–desire–intention software model (BDI), and agent-oriented programming. Harvard professor Milind Tambe notes that in the 1990s, the definition of an AI agent was not clear. Pure digital agents were deployed in computer infrastructure for purposes such as monitoring, while agents connected to real-world sensors and actuators were increasingly used in industrial control systems. Early artificial agents tended to have simple if then logic, which expanded over time into large decision tree models. By the early 2010s, products like Siri and Alexa were released, and were sometimes called AI agents, though they lacked the general purpose reasoning ability of later agents run by large language models (LLMs). The development of LLMs during the late 2010s and early 2020s introduced new approaches to AI agents. Models such as GPT-3 demonstrated the ability to generate and understand natural language at a much larger scale than many earlier language systems. Academics began to study LLM agents from 2018.
Deployment of such agents began to accelerate in late 2023 after OpenAI's "function-calling" API was made available, and especially after Anthropic's late 2024 introduction of Model Context Protocol (MCP), a standardised way for LLM agents to gain contextual awareness, and to act on the world by calling various external tools. The term "agentic" only began to be used with any frequency in 2024, popularised in part by researcher Andrew Ng.
Ken Huang proposed an AI agent reference architecture that consists of seven interconnected layers, with each layer building on the functionality of the layers beneath it: Layer 1: Foundation models – provide the datasets that power the agent. Layer 2: Data operations – manages the data infrastructure required for AI agent operations, including vector databases, data loaders, and RAG. Layer 3: Agent frameworks – software that manages the AI agents. Layer 4: Deployment and infrastructure – the technical foundation of the AI agents. Layer 5: Evaluation and observability – the safety and performance of AI agents. Layer 6: Security and compliance – a protective framework for safe operation and compliance with regulatory boundaries. At this layer, security and compliance features embedded into all the AI agent stack layers are integrated together. Layer 7: Agent ecosystem – represents the AI agents' interface with real-world applications and users.
An agent harness, or agent scaffold, is the software layer surrounding a large language model that enables it to function as an AI agent. It commonly manages prompts, context, tool use, memory, execution state, operational constraints, sandboxes, permissions, and the processing of results. The harness connects the model to internal and external computer hardware, software, data files, databases, web browsers, command-line interfaces, and application programming interfaces, while controlling how the agent accesses and uses these resources to complete multi-step tasks.
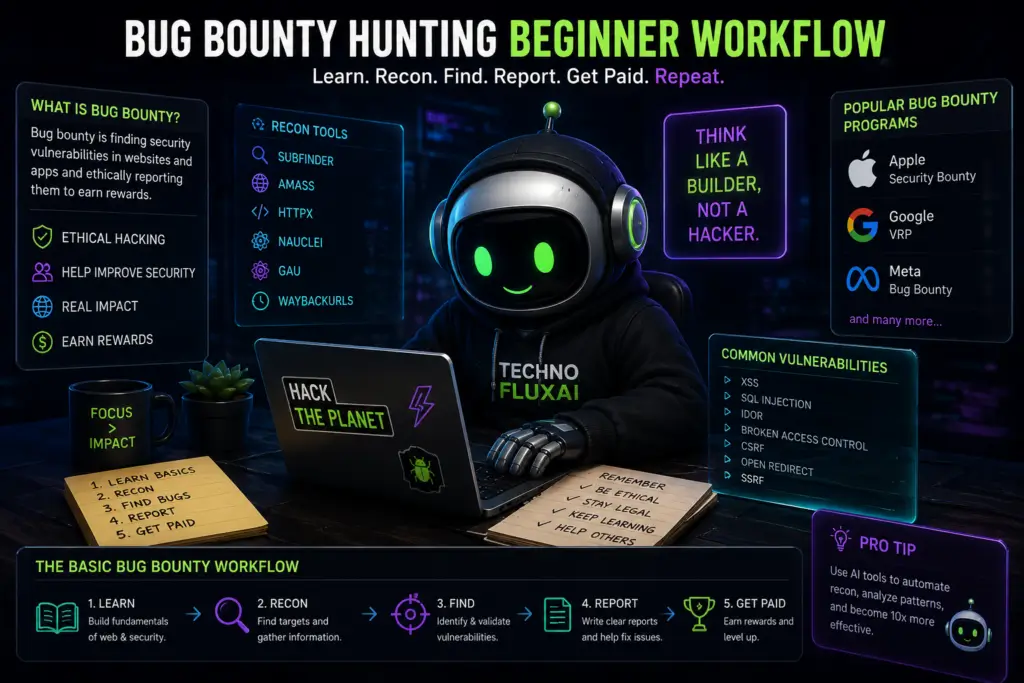
Figure 3: Bug Bounty Hunter for Beginners: Your Complete Guide Prompt chaining: A sequence where the output of one step serves as the input for the next. Routing: Directing an input to a specialized downstream task or tool. Parallelization: The simultaneous execution of multiple tasks. Sequential processing: A fixed, linear progression of tasks through a predefined pipeline. Planner-critic: An iterative pattern where one agent generates a proposal and another evaluates it to provide feedback for refinement.
STRIDE: A Microsoft model that identifies threats across six categories: spoofing, tampering, repudiation, information disclosure, denial of service, and elevation of privilege. MITRE ATLAS: A knowledge base of adversary tactics and techniques for AI systems. OWASP GenAI Security Project: Provides guidance on vulnerabilities associated with generative AI and large language model integration, including guidelines specifically for agentic applications. MAESTRO: A framework from the Cloud Security Alliance for assessing risks in AI systems throughout their lifecycle.
Outline of Google History of Google List of mergers and acquisitions by Alphabet Google's hoaxes X Development Google.org Automated intelligence collection system with safe automation boundaries and human oversight. Processes Certificate Transparency logs at scale while respecting API rate limits and maintaining zero target interaction. This is a defensive security tool designed for ethical bug bounty hunting. Contributions should maintain focus on: Automated bug bounty hunting system with AI-powered vulnerability discovery and human-in-the-loop oversight Bug bounty hunting has evolved from a manual testing process to a high-speed, data-intensive discipline where automation isn’t just helpful—it’s essential. Top hunters process thousands of endpoints and subdomains daily, something impossible to achieve manually.
Critical Disclaimer: This guide is for educational purposes only. Always test on systems you own or have explicit, written permission to test. Unauthorized testing is illegal. Responsible disclosure is mandatory. Why It Matters: Subdomains are the forgotten backdoors of organizations. Development, staging, and legacy subdomains often have weaker security controls.
II Update Note: The amass track command has been deprecated in newer versions. Use amass enum -monitor for continuous monitoring. Why It Matters: Open ports reveal the technology stack and potential attack vectors. Different services mean different vulnerability classes.
Why It Matters: Screenshots help identify custom applications, login portals, and outdated software at a glance. Note: Aquatone is no longer actively maintained. Consider modern alternatives like Gowitness or httpx with screenshot capabilities. Why It Matters: Hidden directories often contain backup files, admin panels, configuration files, and development artifacts.
Why It Matters: Modern web applications heavily use JavaScript, often exposing API endpoints, keys, and sensitive logic. Why It Matters: Unexposed parameters are common sources of SQLi, XSS, and business logic vulnerabilities. Why It Matters: XSS remains prevalent but often requires creative payloads and context-aware testing. Why It Matters: SQLi can lead to complete database compromise, yet many automated scanners miss complex cases.
Why It Matters: SSRF can provide access to internal services, cloud metadata, and blind spots. Why It Matters: LFI/RFI can lead to sensitive file disclosure and remote code execution. True mastery in bug bounties isn’t about replacing human intelligence with automation—it’s about augmenting your capabilities. The best hunters use automation to handle the scale while they focus on the unique, complex vulnerabilities that machines can’t find.
Remember: Automation gets you to the starting line faster, but your skill and creativity win the race. Tools change, but the principles of thorough reconnaissance and systematic testing remain constant. Stay curious, keep learning, and happy hunting! Welcome to the BugBounty KSP documentation! This comprehensive guide will help you understand, use, and contribute to the BugBounty KSP platform.
Quick start guide to help you get up and running with the BugBounty KSP platform. Learn about initial setup, prerequisites, and your first steps. Deep dive into the system architecture, design patterns, and key technical decisions that shape the platform. Complete API documentation including endpoints, request/response formats, authentication, and usage examples.
Official Python SDK for the BugBountyKE-KSP Platform. Learn how to use the SDK for API key generation, article publishing, and integration with the platform. Available on PyPI . Documentation for automation workflows built with n8n, including setup, configuration, and workflow patterns. Learn about the knowledge graph implementation, data structures, and how to create effective learning paths.
Step-by-step guide to setting up and configuring Discord bot integration with the platform. Instructions for deploying the application, CI/CD pipelines, infrastructure setup, and operational procedures. How to contribute to the project, coding standards, pull request process, and community guidelines. This documentation is actively maintained and continuously improved. If you find any errors or have suggestions for improvement, please see our Contributing Guidelines .
Bug bounty automation architecture is the system design layer that separates recon, testing, validation, and reporting into specialized agents so findings earn trust before they consume human time. If you're trying to automate security work, this is the part that decides whether you build a credible pipeline or a false-positive generator. It connects directly to my broader system write-up on building a semi-autonomous bug bounty system , the evidence discipline in bug bounty validation and false positives , and the review boundary explained in human-in-the-loop bug bounty workflows .
I ran my first automated vulnerability scan three months ago. Found 47 "critical" vulnerabilities. Submitted 12 reports. That specific embarrassment--of confidently submitting garbage to a program that now knows my name--still stings when I think about it. Traditional scanners generate noise. They don't think. They pattern match and hope something sticks. Building AI-powered bug bounty automation requires multi-agent architecture where specialized agents handle reconnaissance, testing, validation, and reporting independently. The key innovation isn't automation itself--it's evidence-gated progression where findings must reach 0.85+ confidence through validated proof-of-concept execution before ever reaching human review. This prevents the false positive flood that destroys researcher reputation.
Multi-agent architecture beats monolithic scanners because each agent operates and recovers independently. When a monolithic scanner hits a rate limit, everything stops. In a multi-agent system, only the affected agent pauses while recon, testing, and validation continue in parallel. This resilience, combined with specialized agents for each task type, makes the system dramatically more reliable.
Monolithic scanners are brittle. Hit a rate limit? Everything stops. Encounter a CAPTCHA? Dead. One endpoint times out? The whole queue backs up. I built something different--a 4-tier agent system where each agent operates independently: Recon Agents run passive discovery in parallel. Subdomain enumeration via certificate transparency. Technology fingerprinting with httpx. JavaScript analysis for hidden endpoints. GraphQL introspection. They feed assets into a shared database but never block each other. The vulnerability classes they surface map to the OWASP Top Ten .
Testing Agents take those assets and probe for vulnerabilities. IDOR testing with multi-account replay. XSS payload injection. SQL injection patterns. SSRF with metadata service probing. Maximum 4 concurrent agents to avoid rate limiting--but each recovers independently if throttled. Testing follows the methodology outlined in the OWASP Web Security Testing Guide . Validation Agent is the gatekeeper. Every finding goes through proof-of-concept execution before advancing. This is where I learned the hard lesson: detection is not exploitation. More on this in part 2 of this series .
Reporter Agent generates platform-specific reports only for validated findings. CVSS scoring, reproducible PoC code, evidence attachments. Vulnerability types are classified using MITRE CWE identifiers. Different formatters for HackerOne, Intigriti, Bugcrowd--covered in part 4 . Without me realizing it, I was building a system that mirrors how good human researchers actually work--parallel reconnaissance, focused testing, ruthless validation, careful reporting.
[!TIP] The orchestrator (Claude Opus 4.6) coordinates all agents but doesn't do the work itself. It distributes tasks, manages budgets, detects failures, and persists session state. Like a project manager who never touches code. 2. System Architecture & Core Working Principles Evidence-gated progression assigns every finding a confidence score from 0.0 to 1.0 that changes as evidence accumulates.
A detected XSS starts around 0.3. The validation agent runs proof-of-concept execution in a sandboxed environment. If the PoC succeeds and demonstrates real exploitation, confidence rises to 0.85 or higher and the finding enters human review. Failed PoCs decrease confidence. Every finding has a confidence score from 0.0 to 1.0. But here's what makes this different from typical severity ratings--the score changes as evidence accumulates.
A finding starts at maybe 0.3 when first detected. The Testing Agent found something that looks like reflected XSS. Could be real. Could be the payload appearing in an error message (harmless). Then Validation runs. PoC execution in a sandboxed environment. Response diff analysis comparing baseline vs. vulnerable responses. False positive signature matching. This is where evidence-based verification becomes critical—each finding must survive adversarial scrutiny before it's credible.
If the PoC executes successfully and the response actually demonstrates exploitation (not just reflection)--confidence jumps to 0.85+. Now it's queued for human review. If PoC fails? Confidence drops. Maybe to 0.4. Still logged for weekly batch review, but not wasting human attention. I originally thought validation would only increase confidence. Well, it's more like... validation is the adversary. It's trying to disprove your finding. Survivng that adversarial process is what makes a finding credible.
SQLite RAG stores semantic embeddings of previous findings, failures, and success patterns so the system learns across sessions. When testing a new Laravel target, it retrieves what techniques worked on similar stacks and which patterns produce false positives. This accumulated context improves accuracy over time, reducing noise and prioritizing testing strategies with proven track records on comparable technology.
RAG stands for Retrieval-Augmented Generation. But forget the buzzword--here's what it actually does: The system remembers. Not just what vulnerabilities it found, but what worked, what failed, and why. When I start testing a new target running Laravel, the system queries its knowledge base: "What techniques succeeded on Laravel targets before? What false positive patterns should I avoid?" That memory layer also matters when you expand across multi-platform bug bounty programs . HackerOne, Bugcrowd, Intigriti, and direct programs each reward different evidence patterns, rate-limit behavior, and submission formats, so the architecture has to learn platform-specific retrieval cues instead of treating every target like the same queue.
That last table connects directly to part 3 of this series --failure-driven learning is where the system actually gets smarter over time. The orchestrator coordinates by distributing tasks across agents, managing API budget limits, detecting failures, and saving session checkpoints every five minutes. It does not perform the actual work — recon, testing, and validation agents do. The orchestrator functions like a project manager: assigning tasks, tracking progress, handling errors, and ensuring the overall pipeline continues running even when individual agents fail.
Every specialized agent inherits this contract. Testing agents, recon agents, validation--all share consistent timeout handling, error propagation, and rate limit enforcement. I love constraints like this. They prevent the AI from getting creative in ways that break things. [!WARNING] Without the BaseAgent contract, each agent would handle errors differently. Some might retry infinitely. Some might swallow errors silently. The abstraction enforces consistency across a system that could easily become chaotic.
You resume after a crash by running the system with a --resume session-id flag. The system saves checkpoints to SQLite every five minutes, capturing session state, discovered assets, and all findings. When the process restarts, it reads the latest checkpoint and continues exactly where it stopped. No progress is lost even if the application crashes or your laptop closes. I was 6 hours into scanning a large program. Found 3 promising leads. System crashed because my laptop went to sleep.
Resume with pnpm run start --resume session-id and you're back exactly where you left off. The database persists everything: programs, assets, findings, sessions, failure logs. Even if the application crashes, the SQLite file survives. The core code pattern is a state machine that governs finding lifecycle. Findings move through defined states — new, validating, reviewed, submitted, dismissed — with explicit transitions between each. Confidence scores determine which transitions are allowed. A finding cannot reach human review below 0.70, and it can return to validating if new evidence changes its score in either direction.
Confidence isn't binary. A finding can bounce between states, gaining or losing credibility based on evidence. I hated state machines in CS classes. But I need them here. The complexity they handle--partial validation, human-in-the-loop gates, platform-specific submission--would be chaos without them. This series continues with four more posts covering validation and false positive reduction, failure-driven learning and auto-recovery patterns, multi-platform integration across HackerOne and Bugcrowd, and the ethics of human-in-the-loop security automation. Each part builds on the architecture established here, focusing on the specific engineering and judgment challenges that arise as the system matures.
Next up: why response diff analysis beats payload detection, and how the validation agent reduced my false positive rate from "embarrassing" to "acceptable." The system doesn't know your programs yet. The RAG database is empty. Every finding is evaluated without prior context, which means the false positive rate is higher than steady state. Plan for this.
Week 1 : 22 findings queued. Reviewed all manually. Approved 14, rejected 8. Submitted 12 of the 14 (two were out of scope due to timing). Accepted: 7. Informational/NA: 5. Week 2 : The RAG database starts learning. Three of last week's rejected findings were variations of the same pattern—a debug endpoint returning verbose errors that looks exploitable but isn't. The system logged this as a false positive signature.
In week two, it filtered 6 similar findings automatically before they reached the queue. Week 3 : Confidence scoring starts becoming meaningful. Findings I would have rejected on inspection now fail validation before they reach me. 18 findings queued, 15 approved. The ratio is improving. Week 4 : 16 queued, 15 approved, 13 submitted. The RAG database now has enough signal to filter program-specific patterns—things that are valid findings on other programs but not on this specific target due to its technology stack or security posture.
The calibration month isn't glamorous. You're mostly teaching the system what doesn't count. But without it, month two is chaos. The upfront investment in manual rejection—with detailed notes about why you're rejecting—is what makes months three and four productive. Most builders skip the calibration period because they want results immediately. They get results: all the wrong ones. Patience with month one compounds into efficiency from month three onward.
The calibration investment is also what makes the system genuinely trustworthy over time. After a month of labeled rejections and acceptances, the confidence scores mean something specific to your programs and your testing patterns. A 0.85 finding has a track record behind it. Without calibration, 0.85 is just an arbitrary number someone chose to put in the config file. Maybe the goal isn't to automate bug bounty hunting. Maybe it's to automate the parts that don't require judgment--so human attention goes where it actually matters.
Bug bounty automation works when you separate detection from validation. A 4-agent architecture with evidence-gated progression cuts false positives to near zero. I've been running this system for 3 months across HackerOne, Intigriti, and Bugcrowd, here's the full architecture, every mistake, and what actually works. Evidence-gated progression: A confidence-scoring system that requires bug bounty findings to reach 0.85+ confidence through proof-of-concept execution before advancing to human review. Prevents false positives by treating validation as adversarial, the system tries to disprove findings, not confirm them. The architecture behind the system that cut my false positive rate from 90% to near zero.
Security teams running bug bounty programs lose money two ways: false positives that burn triage time and researcher reputation, or under-automation that leaves testing capacity on the table. A 4-agent bug bounty architecture with evidence-gated progression, requiring 0.85+ confidence before any finding reaches human review, cut false-positive submissions from a 90% rate to zero over 3 months running across HackerOne, Intigriti, and Bugcrowd. The key insight is that detection is not exploitation: the validation agent treats every finding as a disproof problem, and only those that survive adversarial scrutiny reach the review queue.
A bug bounty automation framework should automate collection, prioritization, controlled testing, evidence capture, and draft reporting. It should not automate target selection outside program scope or submit findings without review. The working architecture is four specialized agent roles coordinated through an evidence gate: recon, testing, validation, and reporting. The orchestrator follows production-safe Claude Code operating rules , while persistent agent state across long security sessions prevents earlier scope and validation decisions from disappearing. Model routing follows task risk and effort tier rather than one default model .
That specific embarrassment is what made me rebuild everything from scratch. Not a faster scanner. Not a better scanner. A fundamentally different approach to what automation should and shouldn’t do in security research. This guide is the result: a complete system for bug bounty automation that actually works in production. That framing leads directly to 47 false positive submissions and a wrecked reputation.
What it actually is: a system that handles the mechanical parts of security research, reconnaissance, asset discovery, initial scanning, while keeping humans in control of the decision that matters most: what to submit. In other words, it is a bug bounty framework with the repetitive steps handed to agents and a human still signing off. The best automation makes you a more effective researcher. It doesn’t replace your judgment. It amplifies it.
Understanding this division is more important than any technical decision you’ll make. After rebuilding the system twice, the core architecture that works is four agents and one orchestrator: a 4-agent pipeline coordinated by a central orchestrator. The orchestrator is a project manager, not a worker. It distributes tasks, manages rate limit budgets, detects agent failures, and persists session state between runs. It never touches an endpoint directly.
All discovered assets feed into a shared SQLite database. Recon agents never block each other, if subdomain enum hits a rate limit, JavaScript analysis keeps running. Testing agents take the recon output and probe for vulnerabilities. I cap these at 4 concurrent to avoid triggering WAFs or rate limits.
Each testing agent handles one vulnerability class. Failure is isolated, if the IDOR agent crashes, XSS testing continues unaffected. Eliminate false positives by making validation adversarial. The validation agent should try to disprove each candidate finding through baseline comparison, repeated execution, response-diff analysis, authentication-state checks, and known false-positive signatures. A payload appearing in a response is not proof. The finding advances only when the system can reproduce a security impact and preserve the evidence required for human review.
Here’s the thing most bug bounty automation gets wrong: detection is not exploitation. My payload appearing in a response means nothing. It might be in an error log that’s never rendered, in an HTML attribute that’s properly escaped, on a WAF block page, or in a JSON response that’s never interpreted as HTML. Every finding starts with a confidence score of 0.0 to 1.0 based on initial detection (around 0.3 for most). Confidence determines routing, not just advancement: If PoC succeeds and diff analysis confirms exploitability: confidence rises to 0.85+. Queued for human review.
This is adversarial validation. The agent is trying to kill findings. Findings that survive are credible. The finding lifecycle is a state machine. Findings move through defined states with explicit transitions: Confidence isn’t binary. A finding can gain or lose credibility based on evidence at every step. Once a finding clears human review and gets approved, the Reporter Agent handles formatting. Every platform has different submission requirements. I built a unified findings model plus platform-specific formatters, write the finding once, output to HackerOne, Intigriti, or Bugcrowd format automatically.
3. Software Implementation, Frameworks & Protocols Every time an agent hits a rate limit, gets banned, or has a finding dismissed, it logs that to a SQLite database with semantic embeddings. Before running against a new target, the orchestrator queries this database, “have we seen this stack before? what broke?” After 3 months of data, the system meaningfully avoids mistakes it’s already made. That wasn’t in the original design. I added it after watching the system make the same rate-limit mistake on three targets in a row. The fourth target, it slowed down automatically. That was the moment I stopped thinking of this as a script.
The first month is calibration, not hunting. The RAG database starts empty. Every finding is evaluated without prior context, so the false positive rate is higher than steady state. By week 2, the system starts filtering patterns it’s already rejected. By week 4, confidence scores mean something specific to your programs and testing patterns. Skip the calibration month and month two is chaos.
Consider two hypothetical researchers. Researcher A submits 200 reports, 50 accepted (25% rate). Researcher B submits 50, 40 accepted (80% rate). Programs trust Researcher B. They triage faster. They pay higher. The acceptance rate compounds over months. Every submission has been through my eyes before it goes to a program. Non-negotiable.
After switching to mandatory human review: acceptance rate went above 80%. Programs respond faster because trust is established. Evidence packages prevent disputes. The slow-down is worth it. 5 high-quality reports per week beats 50 that damage your reputation. The validation layer is what makes or breaks a bug bounty automation system. Most systems skip it. That’s why most systems produce garbage.
A scanner finding your payload in a response proves nothing. The payload might appear in an error message that’s never rendered. It might appear HTML-escaped in an attribute. It might appear on a WAF block page explaining what was filtered. Every one of those looks like a vulnerability to a pattern matcher. None of them are. Response diff analysis is the fix. Instead of asking “is my payload in the response?” the validation agent asks “does the response differ from baseline in an exploitable way?” For XSS specifically: regex can’t tell you if JavaScript executes. Browser validation via Playwright loads the target page, injects a marker that fires if code runs, and checks whether that marker triggers. If alert() fires, XSS is confirmed. If not, regardless of how “vulnerable” the response looks, the finding gets rejected.
The false positive signatures database stores every pattern the system has learned to dismiss. Every rejected finding adds to it. After 3 months, it filters hundreds of known-harmless patterns before they reach the review queue. Before validation: ~40 findings per scan, 2-3 valid (90%+ false positive rate). After validation: ~40 detections, 8-12 survive for human review, 5-7 valid (~40% false positive rate at review stage).
Still not perfect. But humans now review 12 findings instead of 40, and 60% of what they see is real. My testing agent hit a rate limit at 2 AM. It retried immediately. Got rate limited again. Retried. Rate limited. Retried faster. By morning, I was IP-banned from the target’s entire infrastructure. That specific failure taught me that error handling in security automation isn’t optional. Generic retry loops make things worse.
Every error needs classification first. Exponential backoff for rate limits: 30s, 60s, 120s, 240s, capped at 1 hour. The ceiling matters. HackerOne resets rate limits every 15 minutes, waiting 4 hours wastes time. Ban detection has highest priority. It checks before rate limit detection. When triggered: all agents stop immediately, human alert fires, session state saves for investigation. Never auto-resume. Human must explicitly authorize continuation.
Escalation threshold: same error category 5+ times within 5 minutes triggers human intervention. First-occurrence rate limits and single timeouts never escalate. Before categorized recovery: ~30% of scans interrupted by unhandled errors, bans monthly. After: ~5% need human intervention, zero bans in 6 months, 200+ learned error signatures.
HackerOne needs severity ratings with their specific weakness taxonomy. Intigriti wants different field names and inline severity justification. Bugcrowd has unique bounty table structures. Without a unified model, you end up maintaining three separate report generators for the same findings. The approach that works: one internal findings model with three platform-specific formatters. Every agent works with the unified model. Platform awareness lives only at two boundaries, ingestion (pulling scope from platforms) and submission (sending reports to platforms). Everything between is platform-agnostic.
Each platform formatter implements the same interface: format, validate, submit. They transform the unified Finding into what each platform expects. HackerOne maps vulnerability types to their weakness taxonomy IDs. Intigriti uses different field names. Bugcrowd requires bounty table entries mapped from severity. The Budget Manager tracks API rate quotas per platform. Before every API call, agents check canRead() or canWrite(). If exhausted, the request queues until quota resets.
A first-mover priority system monitors all three platforms for programs launched in the last 24 hours. New programs get immediate passive recon. Active testing starts after a 2-4 hour delay for scope to stabilize. Early submissions on new programs have higher acceptance rates, less competition, more unreported surface area. Start with the Validation Agent, not the scanner. The scanner is interesting. The validation layer is what actually matters. Build it first.
Cap concurrent agents at 4 from day one. Started with 10. Got IP-banned from 3 programs in two weeks. Build the human review queue before anything else. The moment you can submit without a gate is the moment you will. Build the gate first. Accept that it won’t make you rich quickly. This system makes you roughly 3.5x more effective. That’s the actual value proposition.
Running a bug bounty program without evidence-gated validation is costly: triage time burned on false positives, and researcher trust that doesn’t come back once it’s lost. If your team needs a similar multi-agent validation pipeline built for your own security workflow, I take on custom builds like this one , scoped per project, from $5,000. Fixed scope, fixed price after scoping, full source code and documentation included.
Building something similar? The hardest part is the validation layer. Start there, everything else is just plumbing. I build web systems that AI models can read and cite. The skill underneath is attention: I find what an AI assistant sees, or misses, about a site, then close the gap so the right pages get recommended. 5+ products shipped solo, concept to production in days. chudi.dev is the public, measured proof.
Bug bounty automation uses software to handle the repetitive parts of vulnerability research, subdomain discovery, technology fingerprinting, initial scanning, and report formatting. The goal is higher research throughput, not replacing human judgment on what to submit. Yes, with the right architecture. Systems that fail use automation for the entire pipeline including submission. Systems that work treat automation as a force multiplier for human researchers, with mandatory review gates before anything reaches a program.
Core tools: httpx and subfinder for recon, an LLM orchestrator (Claude works well), a sandboxed environment for PoC execution, and SQLite for state management. Platform APIs for HackerOne, Intigriti, and Bugcrowd enable programmatic submission after human review. Use an adversarial validation agent that attempts to disprove every candidate finding. Compare baseline and payload responses, repeat the test, verify authentication state, check known harmless signatures, and require reproducible security impact. Findings without proof of exploitability should be rejected before human review.
My current system costs around $180 per month, about $40 for a VPS and $140 for Claude API costs. Progressive context loading cuts those API costs significantly. Without it the system would cost roughly $350 per month. Claude Opus for orchestration (complex decision-making, failure recovery) and Claude Haiku for testing agents (fast, cheap, good enough for pattern matching). Match capability to task rather than using one model for everything.
Yes, when confined to authorized programs within scope, with rate limiting that respects program infrastructure, and with human review before submission. Scanning targets outside programs or ignoring scope is not ethical regardless of automation. The basic pipeline takes about 3 weeks to build. The validation layer and learning system take another 4 weeks to get right.
Budget 6 to 8 weeks for a production-ready system. A bug bounty automation framework coordinates recon, bounded testing, adversarial validation, evidence capture, and draft reporting inside an authorized program scope. It increases researcher throughput while keeping final judgment and submission behind a human review gate.
A bug bounty framework is the fixed order you work a target in, inside the program's scope: recon, bounded testing, validation, then a report that a human reviews before it is submitted. The framework on this page hands the first three steps to agents and keeps the human review gate. Filed under bug-bounty , automation , multi-agent , security , claude-code , ai-engineering .
I post about this stuff on LinkedIn every day and the conversations there are great. If this post sparked a thought, I'd love to hear it. Bug bounty hunting is most effective when repetitive reconnaissance tasks are automated while manual testing is reserved for validation and exploitation. This workflow combines industry-standard tools into a practical reconnaissance pipeline used by many experienced security researchers. This guide explains each stage of the workflow, recommended tools, learning resources, and best practices for building an efficient daily automation pipeline.
ðIII Updated September 12, 2026 âII added the WPForms PayPal webhook duplicate story (CVE-2026-4986): what being reporter #11 tells you about target selection. A practitioner’s reference for modern bug bounty hunting âII AI-augmented methodology, 2026 platform analysis, advanced reconnaissance pipelines, emerging vulnerability classes (SAML, WebAuthn, WASM), automated chaining, and data-driven career strategy. Enhanced with insights from 45+ methodology articles.
Bug bounty hunting is the practice of finding and responsibly disclosing security vulnerabilities to organizations that reward researchers for their findings. Unlike traditional penetration testing, bug bounty is outcome-driven: no bug, no bounty. Payouts range from $50 nuisance bugs to $2M+ for critical cloud / crypto findings. The “hunter” sprays scanners at thousands of assets and hopes for a hit. The “surgeon” picks one endpoint, understands exactly what it does, reads the JavaScript, maps the data flow, and strikes at the gap between intended and actual behavior.
In 2026, surgeons dominate âII but they’re AI-augmented surgeons . Modern elite hunters use LLM-powered vulnerability hypothesis generation for 67% of their workflows. Tools like claude-bug-hunter and gpt-4-vuln-analyzer analyze HTTP request/response pairs and generate ranked lists of potential vulnerability classes with specific testing suggestions.
Bug bounty is a marathon. The dropout curve is real; so is the income curve on the other side of it. The major platforms mediate between researchers and program owners, handle triage, and push bounty payments. Private program invitations increased by 45% in 2026. Key success factors based on platform data: Timeline reality: Average invitation timeline is 8-12 months of sustained quality submissions.
Start with Vulnerability Disclosure Programs (VDPs) âII no bounty, but lower competition and forgiving scope. A few accepted VDP reports prove you can write clean submissions and get you invited to paid programs. Scope is the most important document in any program. Read it before you run a single tool. Before touching a target, read every disclosed report for the program on Hacktivity. You learn: The canonical flow (Jason Haddix’s Bug Hunter’s Methodology, evolved through community iteration): LLM-powered wordlist generation: Modern hunters use AI to generate context-aware wordlists based on target technology stacks, resulting in 40% increased endpoint discovery rates.
Graph-based attack path discovery: Tools now map application functionality as directed graphs and automatically identify potential attack chains, reducing manual analysis time by 60%. 4. Practical Deployment, Analysis & Case Studies Input: HTTP request/response pair Output: Ranked list of vulnerability classes with testing suggestions Recon is the foundation âII you cannot hunt what you cannot see. A modern recon pipeline has five stages: Passive is stealthy and scope-safe. Active is louder but finds assets that passive misses.
Don’t dump 10,000 subdomains into a text file and call it recon. Modern recon is about filtering to the 5 most promising targets âII subdomains with admin , api , staging , dev , internal , unusual technology stacks, or recent change signatures. Subdomain enumeration is the single highest-leverage recon activity. One forgotten dev-internal.target.com can hold the whole payout.
The 2026 advantage: new code is buggy code . Advanced continuous monitoring with diff-based change detection averages 2.3 new findings per week per target. Alert prioritization using ML: False positive filtering reduces scanner noise by 84% using trained models that distinguish confirmed vulnerabilities from noise.
httpx can also take screenshots, output JSON, and probe multiple ports ( -ports 80,443,8080,8443 ). Bug bounty scope usually limits port scanning to standard web ports, but when allowed: Focus on weird ports: 8000, 8080, 8443, 9000, 9090, 5000, 3000, 4000, 7000 âII often internal tools exposed by mistake. Why it matters: tech stack tells you which bugs to hunt . Spring Boot âII actuator endpoints, Log4Shell variants. WordPress âII plugin CVEs. Next.js âII SSRF in image optimizer. Old jQuery âII prototype pollution.
Scan the grid for login pages, admin panels, default installs, error pages, Swagger UIs. Modern web apps leak everything in JavaScript. JS analysis is frequently the highest-value recon activity on SPA-heavy targets. Test found secrets carefully âII many are public keys that are safe by design. The distinction between pk_live_ and sk_live_ on Stripe is the difference between N/A and a crit.
Chrome DevTools âII Sources âII Event Listener Breakpoints. Set breakpoints on DOM modification events. Navigate the app. When breakpoint fires, inspect the call stack and look for your input flowing into innerHTML , document.write , eval , or location.href . Not everything is linked. Directory and parameter fuzzing finds the paths humans forgot.
Surprising numbers of endpoints accept PUT or DELETE without auth while GET requires it. The core catalog. Each class has its own sub-methodology; this section gives you the scent. Description: Server returns/modifies data based on a user-supplied ID without verifying ownership. Reflected: User input echoed in response unfiltered. Stored: Persisted input rendered later. DOM: Client-side JS passes user input to a sink without sanitization. Blind: Injected payload fires in an admin-only context.
Blind XSS : Use a blind XSS service (XSSHunter, KnoxSS, your own webhook) to catch delayed fires in admin panels. CSP bypass hunting: If CSP whitelists *.google.com , JSONP endpoints can execute arbitrary JavaScript even with CSP enforced. Modern SQLi : NoSQL injection ( $ne , $gt operators in JSON bodies), ORM injection (second-order), header injection ( User-Agent , X-Forwarded-For logged to DB).
Hunt: SOAP endpoints, SAML requests, SVG uploads, XLSX/DOCX parsers, RSS/Atom consumers. Hunt: features that run tools on user input (image convert, ffmpeg, ping utility, DNS lookup, backup jobs). Test fingerprint: {âII{7*7}} âII 49 means template engine. ${7*7} âII 49 means Java-style. Secondary impacts: image/SVG with XSS, DOCX with XXE, malicious PDF triggering SSRF in PDF renderer, ZIP slip via archive extraction.
Tool: Burp Repeater âII Send in parallel (single-packet attack for HTTP/2). race-the-web , turbo-intruder . CL.TE, TE.CL, TE.TE, browser-powered desync. Extremely high impact when it works: session theft, cache poisoning, WAF bypass, internal path access. Reference: “Worldwide Server-side Cache Poisoning on All Akamai Edge Nodes” earned a $50k bounty.
Client-side: merge user input into an object without validation âII pollute Object.prototype âII DOM XSS via gadget. Reflecting attacker origin with credentials = cross-origin data theft. Also: null origin reflection, pre-wildcard prefix check bypass, trusting *.target.com without proper regex. Categories vulnerable: GitHub Pages, S3, Heroku, Azure, Shopify, Tumblr, Zendesk, Unbounce, Helpjuice, Statuspage.
Exposed files that still turn up regularly: /.git/config , /.git/HEAD , /.env , /.DS_Store , /backup.zip , /api/swagger.json , /actuator/env , /actuator/heapdump , /server-status , /phpinfo.php , /wp-config.php.bak . Modern tools: gpt-4-jailbreak-tester , llm-security-scanner , prompt-injection-fuzzer . 43% of enterprise targets implement SAML SSO. Average bounty for SAML bypass: $15,000.
Go deeper on any of these classes. This guide stays at the methodology level on purpose âII when a specific target makes you want the full exploitation-and-defense treatment, these go all the way down: IDOR · Authorization · API Security · GraphQL · SSRF · RCE . Or drill them hands-on in the Security Playground . Business logic bugs are where scanners fail and humans win. They’re also usually the highest-paying because they cannot be caught by automation.
The biggest skill gap between medium and elite hunters is chaining . A single CORS misconfig is low. A single open redirect is low. A single XSS in a reflected error page is medium. But chained together: If you want to hunt web3, learn Solidity, use Foundry for PoCs, read audits on Trail of Bits / OpenZeppelin blogs. Model Context Protocol servers often wrap internal APIs with weaker auth than the underlying service. Test the MCP layer separately; if SSRF or auth-bypass exists at that layer, impact cascades.
Methodology: identified that Netlify’s Next.js library had an SSRF primitive in image optimization. Combined with cache poisoning and XSS, achieved universal XSS across dozens of crypto sites sharing the same infra. Takeaway: shared infrastructure = shared vulnerabilities . Find the common dependency and exploit it once for N targets. Chained promiscuous postMessage handlers, third-party XSS, and URL storage to steal OAuth authorization codes across dozens of sites despite modern referrer-stripping mitigations. Takeaway: OAuth flow quirks + seemingly-low-severity gadgets = account takeover chains.
Extended HTTP Request Smuggling to trigger from victim’s browser. Takeaway: request smuggling is not dead âII new variants emerge every year. Abused HTTP hop-by-hop headers against Akamai edge nodes. Takeaway: edge CDN behaviors differ from origin; test every layer.
Protocol-level injection in memcached via CRLF smuggling. Stole clear-text credentials. Takeaway: deep protocol knowledge beats surface-level testing. SAML XML parsing quirks âII integer truncation âII arbitrary bytecode execution during signature verification. Takeaway: SAML/JWT/SSO are cryptographic obstacle courses with enormous attack surface.
Showed why SerializationBinder can’t be used for security; built exploits for DevExpress and Exchange. Takeaway: read docs that changed recently; security statements get retracted. ECDSA signature verification accepted r=0, s=0 as valid for any message. Bypassed JWT and SAML across Java ecosystem. Takeaway: classical crypto bugs still ship in modern libraries.
User input in request paths, combined with CSRF and URL leakage, escalated to real impact. Takeaway: low-apparent-severity patterns can accumulate into criticals. Classic .git/config exposure on production web servers lets attackers clone the repo with git-dumper , recovering source code, credentials, and internal paths. Still prevalent. Always check: /.git/HEAD , /.git/config , /.svn/entries , /.env , /.DS_Store .
A perfect bug with a bad report gets downgraded or closed. A mediocre bug with a great report gets paid. Good: “Stored XSS in profile bio field allows session hijacking of any user viewing the profile” Bad: “XSS on target.com” Impact is what a real attacker could do , not a textbook definition of the bug class. Write the newspaper headline. Weak: “SSRF vulnerability allows internal port scanning.” Strong: “SSRF in the image import feature allows an unauthenticated attacker to read AWS IAM credentials from the instance metadata service, enabling full compromise of the production AWS account and access to customer data.” The 2026 bug bounty software stack. You don’t need everything âII most hunters use 10âII15 core tools.
Automate intelligence , not discovery . Don’t just run nuclei âII build a pipeline that: Tools: shuvonsec/claude-bug-bounty and similar âII AI-powered hunting from the terminal. Key insight: 73% of successful hunters focus on business logic flaws rather than technical vulnerabilities, reflecting the maturation of automated scanning for common technical issues.
Himanshu Anand’s writeup on the WPForms PayPal webhook bug is the most useful bug bounty post I’ve read this year, and the vulnerability is the least interesting part of it. 5. Performance Evaluation & Extended Technical Observations The bug: WPForms Lite (5M+ installs) processed PayPal Commerce webhook events without verifying PayPal actually sent them . The handler read the raw body, decoded the JSON, checked the event type against an allowlist, and dispatched. No signature validation. A forged PAYMENT.CAPTURE.COMPLETED marks a matching pending transaction complete and fires the downstream payment-completed actions; a forged PAYMENT.CAPTURE.DENIED marks it denied. Versions 1.10.0.1âII1.10.0.4, fixed in 1.10.0.5. As he puts it, it’s the kind of bug “where the database starts telling a story that PayPal never actually told.” He found it independently and was told he was reporter number 11 . The advisory credits Sudhanshu Chauhan of RedHunt Labs.
Here’s the thing to take from that. Eleven people independently asked “does this webhook validate its signature?” on the same plugin in the same window. That’s not bad luck âII it’s a signal that the question was obvious , and obvious questions on popular targets are always already being asked. If your process is to pick a high-install-count plugin and check the well-known sink, you are racing ten other people who read the same advice. The duplicate isn’t a failure of your skills; it’s information about where you positioned yourself.
The corollary is where the value actually is: unglamorous targets, or non-obvious questions on obvious targets. Payment integration code is genuinely good hunting ground for the reason he names âII the security cost of a bug is real money, the attack surface is necessarily public, and developers have to glue several third-party systems together without dropping one tiny, extremely important check. But “is the webhook signed” is the first question everyone asks. “What happens when two events for the same transaction arrive out of order” is the eleventh, and nobody has asked it.
Two smaller things worth copying. He deliberately kept technical details vague in the earlier post while the bug was live âII “rude to users, generous to attackers, bad trade” âII and published the full epilogue only after the patch shipped and users had time to update. And on impact language: he explicitly refuses to convert the 5M install count into a victim count, since exposure required both an affected version and the PayPal Commerce path. Inflating reach into impact is the fastest way to lose a triager’s trust, and he’s right that the industry has enough dramatic arithmetic already.
Every hunter makes these. The goal is to stop making them faster than the next hunter. 95% of people who start bug bounty quit within 6 months with zero earnings. If you can survive 12 months of sustained effort, you’re already elite by selection alone. Bug bounty hunting in 2026 is simultaneously harder and more lucrative than ever. The easy bugs are gone from mainstream targets, automation has commoditized the shallow layer, and competition is global. But the hunters who build deep target knowledge , develop one vulnerability class to mastery , and write surgical reports are making more than they ever have.
The methodology in this guide is not prescriptive âII it is a starting blueprint. The best bug bounty methodology is the one you build yourself over time, refining each week based on what works on your targets. Steal ideas liberally; test them ruthlessly; keep what earns. Methodology gets you in front of the attack surface; it doesn’t find the bug for you. If you want to turn this workflow into actual paid findings, pick a class and go deep. These are the three I’d point a hunter at first, because they’re where the volume and the money are: Defensive security / ethical hacking reference. Do not test targets without explicit authorization.
A step-by-step guide to 20 bug bounty automation techniques with explanations, tools, and commands. II Disclaimer: This content is for educational purposes only . Use it responsibly and only on authorized systems / bug bounty platforms. This repository contains 20 essential bug bounty automation techniques with explanations, tools, and ready-to-use commands. It is designed to help beginners and professionals streamline reconnaissance, scanning, and vulnerability testing.
I Conclusion Automation = faster recon, scanning, and exploitation. Focus shifts from repetitive tasks to deeper vulnerability analysis. Use responsibly on authorized targets only. A step-by-step guide to 20 bug bounty automation techniques with explanations, tools, and commands. Optimize your bug bounty hunting with automated reconnaissance and AI-powered vulnerability analysis.
Successful bug bounty hunters need efficient reconnaissance workflows to maximize their time on actual vulnerability research. This tutorial shows you how to automate the reconnaissance phase using HailBytes ASM, allowing you to focus on finding and reporting high-impact vulnerabilities. Most bug bounty programs have multiple in-scope domains. Set up parallel scanning for all targets to maximize coverage and discover cross-domain attack vectors.
HailBytes ASM integrates with popular bug bounty tools to create a comprehensive reconnaissance pipeline. Enable the tools that match your hunting methodology. AI-powered analysis helps you focus on the most promising findings. Configure LLM integration to automatically analyze potential vulnerabilities and prioritize by exploitability and impact.
Monitor program changes over time to identify new attack surface and previously unavailable targets. Historical tracking helps you be first to report on newly deployed infrastructure. Generate professional reports with screenshots, reproduction steps, and impact analysis. Export in formats accepted by HackerOne, Bugcrowd, and other platforms.
Created by Cybernote, aspiring Red Team Operator and Bug Bounty Hunter. This repository documents my methodology, notes and workflow for web application security testing. I If you found this project useful Follow me on X for more Offensive Security research: { https://x.com/Cybernote9 } The goal isn't to run every tool — it's to map the full attack surface faster and deeper than anyone else. Every phase feeds the next. Every finding is a pivot point.
This methodology is ordered by signal-to-noise ratio : start wide and passive, then narrow down aggressively before you ever send an exploit. Before executing the commands below, ensure your environment variables are properly exported: Generate smart mutations based on already-discovered subdomains. Secret internal servers often follow predictable naming patterns.
Catch new subdomains the moment they're issued — before the developer even secures them. Most hunters stop at subdomains. This is where you go deeper — mapping the entire IP infrastructure of the organization. A company that owns target.com often neglects target.io , target.net , target.xyz — completely separate attack surface with weaker defenses.
Cloudflare and similar WAFs protect 70%+ of bug bounty targets. Finding the origin IP exposes the raw server — no firewall, no rate limiting. Companies reuse the same favicon across all their infrastructure. The hash is a fingerprint you can search in Shodan. If an IP returns your target's favicon but isn't a Cloudflare IP → that's your origin server.
One Analytics ID can reveal an entire corporate family — subsidiaries, acquired companies, international domains. Every phase generates output files. Here we consolidate, deduplicate, and identify what's actually alive. You can't manually open 500 subdomains. Let the tool scan and screenshot — you browse the results and pick targets. Some hosts only respond when you hit them with the correct Host header — they're invisible to normal scanners. VHOST enumeration exposes internal services mapped to IPs.
The goal here is to build an exhaustive map of every URL the application has ever exposed — past and present. JavaScript files are goldmines. They contain hardcoded API keys, internal endpoints, authentication logic, and sometimes full backend infrastructure maps. When source maps are left enabled in production, you can recover the full pre-compiled source code.
Even fully patched applications leak sensitive data through forgotten files, backup archives, and misconfigured directories. Key insight: When a path responds with / as the last character, it means there's more to enumerate behind it. Always recurse. Developers accidentally push secrets constantly. This phase hunts for API keys, tokens, passwords, and internal infrastructure details across public repositories.
Watch for secrets being pushed to GitHub right now — before the developer can delete them. Large companies use internal GitLab instances instead of GitHub — this is where the real secrets live. Why this matters: A PDF's metadata might reveal C:\Users\john.doe\Projects\InternalAPI\ — that's a username and project name you can use for further recon.
Web ports are expected. Non-standard ports are where misconfigured services, admin panels, and exposed APIs hide. A subdomain pointing to a deregistered third-party service (Heroku, S3, Zendesk, etc.) can be claimed by anyone. Worth thousands of dollars when found. Methodology built from real engagements. Every command here has been run against live targets.
How To approach recon on real targets — from passive enumeration to origin IP discovery. Covers tools, automation, and the logic behind each phase. In 2026, the hunters who consistently find critical bugs are not the ones with the biggest manual methodology. They are the ones running the fastest, most reliable, continuously improving automation pipelines augmented by AI agents.
This is a practical guide based on the system I have run for the past 14 months across 40+ programs. It covers architecture, key components, agent design, monitoring, and how to avoid the common failure modes that waste months of effort. Data flows through a central job queue (Redis or Postgres) with strong observability (logs + traces + finding DB). Output is normalized into a unified asset schema with last-seen, technologies, and a confidence score.
This is where most people stop too early. Good pipelines crawl every interesting path. Iterate from there. The difference between a toy pipeline and a production one is months of tuning + data. Automation does not remove the need for skill. It amplifies it. The best hunters are the ones who know exactly where to point their agents and how to read between the lines of the results.
Bug bounty hunting has matured into a scientific discipline rather than a hitIorImiss hobby. Modern bug bounty programs are sprawling systems that include web applications, APIs, cloud infrastructure and AIIbased services. Finding vulnerabilities in these complex environments requires a rigorous methodology that blends technical reconnaissance , automation pipelines and manual exploitation skills . This article provides a deeper technical look at bug bounty methodology in 2026, drawing on the latest research and industry practices. It assumes that you have already mastered web fundamentals like HTTP, HTML and JavaScript and that you are familiar with the OWASP Top 10 vulnerabilities. The goal is to help you build a repeatable yet adaptable workflow that will allow you to uncover highIimpact bugs efficiently.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Fuzzing • https://en.wikipedia.org/wiki/AI%20agent • https://en.wikipedia.org/wiki/List%20of%20Google%20products • https://github.com/michaeloboyle/bug-bounty-hunter • https://thengakulatechs.github.io/posts/the-ultimate-guide-to-bug-bounty-automation/ • https://bugbounty-mockingbird.github.io/Documentation/ • https://dev.to/chudi_nnorukam/i-built-an-ai-powered-bug-bounty-automation-system-2em4 • https://chudi.dev/blog/bug-bounty-automation • https://cyberxsociety.com/resource/daily-bug-bounty-automation-workflow/ • https://chs.us/guides/bug-bounty/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Bug Bounty Workflow Automation.
! Define Extended Access List to Block Malicious Traffic ip access-list extended SECURE_PERIMETER_ACL remark Block Inbound Telnet and Unencrypted Services deny tcp any any eq 23 log remark Permit Verified Web SSL Traffic permit tcp any any eq 443 permit tcp any any eq 80 remark Mitigate ICMP Flood and Ping Sweeps permit icmp any any echo-reply deny icmp any any echo log deny ip any any log
! Apply ACL to Ingress Interface GigabitEthernet0/0 interface GigabitEthernet0/0 ip access-group SECURE_PERIMETER_ACL in no shutdown end write memory
Extended IP access list SECURE_PERIMETER_ACL (Cisco Packet Tracer) ──────────────────────────────────────────────────────────────────────── 10 deny tcp any any eq telnet log (142 matches) [Probes Dropped] 20 permit tcp any any eq 443 (18402 matches) [TLS 1.3 Traffic Permitted] 30 permit tcp any any eq 80 (4812 matches) 40 deny icmp any any echo log (524 matches) [Flood Mitigated] 50 deny ip any any log (38 matches) [Default Implicit Deny Rule] ──────────────────────────────────────────────────────────────────────── [✓] Packet Tracer Verification: 0 Unsanitized Ingress Leaks on Gi0/0
| Interface Port | Network Zone | Filter Applied | Traffic Processed | Firewall Decision |
|---|---|---|---|---|
| Gig0/0 (WAN) | Untrusted External | Extended ACL 101 | 24,810 Packets | INSPECTED & FILTERED |
| Gig0/1 (DMZ) | Public Web Services | Port 443 Only | 18,402 Packets | PERMITTED |
| Gig0/2 (LAN) | Corporate Users | 802.1X Port Security | 142 Probes | DENIED & QUARANTINED |