Complete Technical Paper Content — Captcha Based Automated Bot Prevention System In Python
Overview & System Context
Captcha Based Automated Bot Prevention System In Python: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9170 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background No technique is a complete solution to the spam problem, and each has trade-offs between incorrectly rejecting legitimate email (false positives) as opposed to not rejecting all spam email (false negatives) – and the associated costs in time, effort, and cost of wrongfully obstructing good mail. This leads to combinations of the many techniques to achieve the best protection against spam and the potential harms that may come with it, while keeping the emails that should be seen intact. Anti-spam techniques can be broken into four broad categories: those that require actions by individuals (end-user techniques), those that can be automated by email administrators, those that can be automated by email senders and those employed by researchers and law enforcement officials. They are often used in conjunction with one another.
Email addresses posted on webpages, Usenet or chat rooms are vulnerable to e-mail address harvesting. Address munging is the practice of disguising an e-mail address to prevent it from being automatically collected in this way, but still allow a human reader to reconstruct the original: an email address such as, "no-one@example.com", might be written as "no-one at example dot com", for instance. A related technique is to display all or part of the email address as an image, or as jumbled text with the order of characters restored using CSS.
Many modern mail programs incorporate web browser functionality, such as the display of HTML, URLs, and images. Avoiding or disabling this feature does not help avoid spam. It may, however, be useful to avoid some problems if a user opens a spam message: offensive images, obfuscated hyperlinks, being tracked by web bugs, being targeted by JavaScript or attacks upon security vulnerabilities in the HTML renderer. Mail clients which do not automatically download and display HTML, images or attachments have fewer risks, as do clients who have been configured to not display these by default.
An email user may sometimes need to give an address to a site without complete assurance that the site owner will not use it for sending spam. One way to mitigate the risk is to provide a disposable email address — an address which the user can disable or abandon which forwards email to a real account. A number of services provide disposable address forwarding. Addresses can be manually disabled, can expire after a given time interval, or can expire after a certain number of messages have been forwarded. Disposable email addresses can be used by users to track whether a site owner has disclosed an address, or had a security breach.
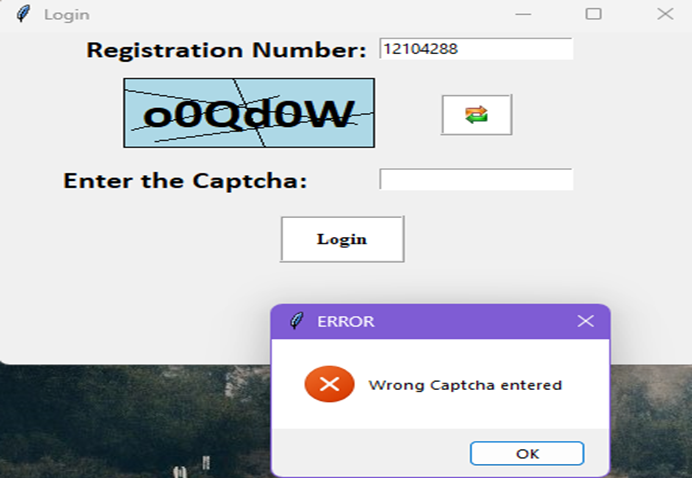
Figure 1: GitHub - sqladitya/Captcha-Generator-Python-Mini-Project: MiniPython ... Tracking down a spammer's ISP and reporting the offense can lead to the spammer's service being terminated and criminal prosecution. Some online tools such as SpamCop and Network Abuse Clearinghouse are potentially helpful but not always accurate. Historically, such reports have not played a large part in abating spam, since the spammers generally move their operation to another URL, ISP or network of IP addresses. In many countries consumers may also report unwanted and deceptive commercial email to government agencies. In the US, the Federal Trade Commission (FTC), an agency of the Department of Commerce, has taken action against spammers. Similar agencies exist in other countries.
There are now a large number of applications, appliances, services, and software systems that email administrators can use to reduce the load of spam on their systems and mailboxes. In general, these attempt to reject (or "block") the majority of spam email outright at the SMTP connection stage. If they do accept a message, they will typically then analyze the content further and may decide to "quarantine" any categorized as spam.
A number of systems have been developed that allow domain name owners to identify email as authorized. Many of these systems use the DNS to list sites authorized to send email on their behalf. After many other proposals, SPF, DKIM and DMARC are all now widely supported with growing adoption. While not directly attacking spam, these systems make it much harder to spoof addresses, a common technique of spammers also used in phishing and other types of fraud via email. Using any combination of these will help prevent emails from being mislabeled as spam or junk.
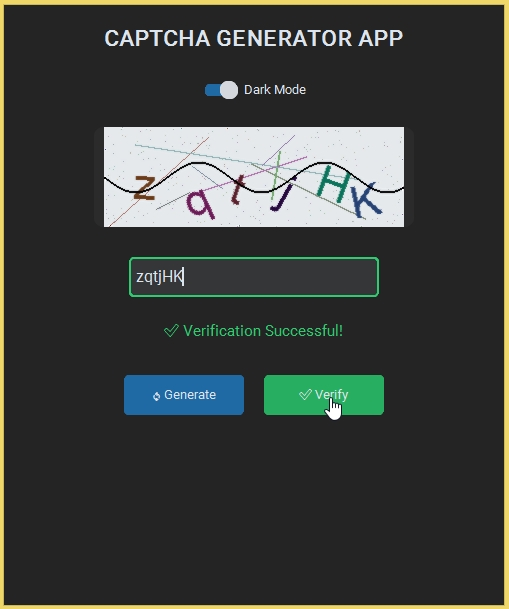
A method which may be used by internet service providers, by specialized services or enterprises to combat spam is to require unknown senders to pass various tests before their messages are delivered. These strategies are termed "challenge/response systems". Figure 2: Captcha Generator App Using Tkinter in Python with Source Code ...
There are a large number of free and commercial DNS-based Blacklists, or DNSBLs which allow a mail server to quickly look up the IP of an incoming mail connection - and reject it if it is listed there. Administrators can choose from scores of DNSBLs, each of which reflects different policies: some list sites known to emit spam; others list open mail relays or proxies; others list ISPs known to support spam. This method can unfortunately result in false positives, potentially blocking real mail if a blacklisted IP is linked with spammers but is also shared by authentic users. Virtual private networks and other methods of fronting with a false IP address can allow spammers to get around these established blacklists.
Most spam/phishing messages contain a URL that they entice victims into clicking on. Thus, a popular technique since the early 2000s consists of extracting URLs from messages and looking them up in databases such as Spamhaus' Domain Block List (DBL), SURBL, and URIBL. Many spammers use poorly written software or are unable to comply with the standards because they do not have legitimate control of the computer they are using to send spam (zombie computer). By setting tighter limits on the deviation from RFC standards that the MTA will accept, a mail administrator can reduce spam significantly - but this also runs the risk of rejecting mail from older or poorly written or configured servers. Greeting delay – A sending server is required to wait until it has received the SMTP greeting banner before it sends any data. A deliberate pause can be introduced by receiving servers to allow them to detect and deny any spam-sending applications that do not wait to receive this banner. Temporary rejection – The greylisting technique is built on the fact that the SMTP protocol allows for temporary rejection of incoming messages.
Greylisting temporarily rejects all messages from unknown senders or mail servers – using the standard 4xx error codes. All compliant MTAs will proceed to retry delivery later, but many spammers and spambots will not. The downside is that all legitimate messages from first-time senders will experience a delay in delivery. HELO/EHLO checking – RFC 5321 says that an SMTP server "MAY verify that the domain name argument in the EHLO command actually corresponds to the IP address of the client. However, if the verification fails, the server MUST NOT refuse to accept a message on that basis." Systems can, however, be configured to Refuse connections from hosts that give an invalid HELO – for example, a HELO that is not an FQDN or is an IP address not surrounded by square brackets. Refusing connections from hosts that give an obviously fraudulent HELO Refusing to accept email whose HELO/EHLO argument does not resolve in DNS Invalid pipelining – Several SMTP commands are allowed to be placed in one network packet and "pipelined". For example, if an email is sent with a CC: header, several SMTP "RCPT TO" commands might be placed in a single packet instead of one packet per "RCPT TO" command. The SMTP protocol, however, requires that errors be checked and everything is synchronized at certain points. Many spammers will send everything in a single packet since they do not care about errors and it is more efficient. Some MTAs will detect this invalid pipelining and reject email sent this way. Nolisting – The email servers for any given domain are specified in a prioritized list, via the MX records. The nolisting technique is simply the adding of an MX record pointing to a non-existent server as the "primary" (i.e.
that with the lowest preference value) – which means that an initial mail contact will always fail. Many spam sources do not retry on failure, so the spammer will move on to the next victim; legitimate email servers should retry the next higher numbered MX, and normal email will be delivered with only a brief delay. Quit detection – An SMTP connection should always be closed with a QUIT command. Many spammers skip this step because their spam has already been sent and taking the time to properly close the connection takes time and bandwidth. Some MTAs are capable of detecting whether or not the connection is closed correctly and use this as a measure of how trustworthy the other system is.
Figure 3: Python Beautiful Soup + CaptchaAI: Handling CAPTCHA-Protected Pages ... 2. System Architecture & Core Working Principles Another approach is simply creating an imitation MTA that gives the appearance of being an open mail relay, or an imitation TCP/IP proxy server that gives the appearance of being an open proxy. Spammers who probe systems for open relays and proxies will find such a host and attempt to send mail through it, wasting their time and resources, and potentially revealing information about themselves and the origin of the spam they are sending to the entity that operates the honeypot. Such a system may simply discard the spam attempts, submit them to DNSBLs, or store them for analysis by the entity operating the honeypot that may enable identification of the spammer for blocking.
Most email mail transfer agents (mail servers) use a forward-confirmed reverse DNS (FCrDNS) verification and if there is a valid domain name, put it into the "Received:" trace header field. Some email mail transfer agents will perform FCrDNS verification on the domain name given in the SMTP HELO and EHLO commands. See Strict enforcement of RFC standards § HELO/EHLO . To check the domain names in the rDNS to see if they are likely from dial-up users, dynamically assigned addresses, or home-based broadband customers. Since the vast majority of email that originates from these computers is spam, many mail servers also refuse email with missing or "generic" rDNS names. A Forward Confirmed reverse DNS verification can create a form of authentication that there is a valid relationship between the owner of a domain name and the owner of the network that has been given an IP address. While reliant on the DNS infrastructure, which has known vulnerabilities, this authentication is strong enough that it can be used for whitelisting purposes because spammers and phishers cannot usually bypass this verification when they use zombie computers to forge the domains.
Content filtering techniques rely on the specification of lists of words or regular expressions disallowed in mail messages. Thus, if a site receives spam advertising "herbal Viagra", the administrator might place this phrase in the filter configuration. The mail server would then reject any message containing the phrase. This could lead to real accounts being blocked from emailing mistakenly if the words or phrases that are restricted are fairly common. Many spammers may purposefully misspell words to get around this, along with some having different native languages that could result in spelling errors. This leads to alternative spellings of blocked words also being added to the list to better defend against spam. Heuristic filters can take this further and attribute points to certain words or phrases much like the standard rule-based filtering. These phrases can be worth more points than others, and when added will determine whether or not it is spam based on a threshold that is put into place. Depending on how low it is, this can lead to false positives. Header filtering looks at the header of the email which contains information about the origin, destination and content of the message. Although spammers will often spoof fields in the header to hide their identity, or to try to make the email look more legitimate than it is, many of these spoofing methods can be detected, and any violation of, e.g., RFC 5322, 7208, standards on how the header is to be formed can also serve as a basis for rejecting the message.
Since a large percentage of spam has forged and invalid sender ("from") addresses, some spam can be detected by checking that this "from" address is valid. A mail server can try to verify the sender address by making an SMTP connection back to the mail exchanger for the address, as if it were creating a bounce, but stopping just before any email is sent. Callback verification has various drawbacks: (1) Since nearly all spam has forged return addresses, nearly all callbacks are to innocent third-party mail servers that are unrelated to the spam; (2) When the spammer uses a trap address as his sender's address. If the receiving MTA tries to make the callback using the trap address in a MAIL FROM command, the receiving MTA's IP address will be blacklisted; (3) Finally, the standard VRFY and EXPN commands used to verify an address have been so exploited by spammers that few mail administrators enable them, leaving the receiving SMTP server no effective way to validate the sender's email address.
SMTP proxies allow combating spam in real time, combining sender's behavior controls, providing legitimate users immediate feedback, eliminating the need for quarantine. Spamtrapping is the seeding of an email address so that spammers can find it, but normal users can not. If the email address is used then the sender must be a spammer and they are black listed. As an example, if the email address "spamtrap@example.org" is placed in the source HTML of a website in a way that it isn't displayed on the web page, human visitors to the website would not see it. Spammers, on the other hand, use web page scrapers and bots to harvest email addresses from HTML source code - so they would find this address. When the spammer later sends to the address the spamtrap knows this is highly likely to be a spammer and can take appropriate action.
Statistical, or Bayesian, filtering once set up requires no administrative maintenance per se: instead, users mark messages as spam or nonspam and the filtering software learns from these judgements. Thus, it is matched to the end user's needs, and as long as users consistently mark/tag the emails, can respond quickly to changes in spam content. Statistical filters typically also look at message headers, considering not just the content but also peculiarities of the transport mechanism of the email. In particular statistics may be collected on transmission volume charts of the originating IP addresses - massive volume spikes in short time intervals are predictive of spamming activity. In more recent times with the use of artificial intelligence and machine learning, these forms of filters have been able to go more in depth and overall improve upon their performance in combating spam. Software programs that implement statistical filtering include Bogofilter, DSPAM, SpamBayes, ASSP, CRM114, the email programs Mozilla and Mozilla Thunderbird, Mailwasher, and later revisions of SpamAssassin.
A tarpit is any server software which intentionally responds extremely slowly to client commands. By running a tarpit which treats acceptable mail normally and known spam slowly or which appears to be an open mail relay, a site can slow down the rate at which spammers can inject messages into the mail facility. Depending on the server and internet speed, a tarpit can slow an attack by a factor of around 500. Many systems will simply disconnect if the server doesn't respond quickly, which will eliminate the spam. However, a few legitimate email systems will also not deal correctly with these delays. The fundamental idea is to slow the attack so that the perpetrator has to waste time without any significant success. An organization can successfully deploy a tarpit if it can define the range of addresses, protocols, and ports for deception. The process involves a router passing the supported traffic to the appropriate server while those sent by other contacts are sent to the tarpit.
Examples of tarpits include the Labrea tarpit, Honeyd, SMTP tarpits, and IP-level tarpits. The measures may consume resources, both in the server and on the network. When a mail server rejects legitimate messages, the sender needs to contact the recipient out of channel. When legitimate messages are relegated to a spam folder, the sender is not notified of this. If a recipient periodically checks his spam folder, that will cost him time and if there is a lot of spam it is easy to overlook the few legitimate messages. Measures that impose costs on a third-party server may be considered to be abuse and result in deliverability problems.
A malicious person can easily attempt to subscribe another user to a mailing list — to harass them, or to make the company or organisation appear to be spamming. To prevent this, all modern mailing list management programs (such as GNU Mailman, LISTSERV, Majordomo, and qmail's ezmlm) support "confirmed opt-in" by default. Whenever an email address is presented for subscription to the list, the software will send a confirmation message to that address. The confirmation message contains no advertising content, so it is not construed to be spam itself, and the address is not added to the live mail list unless the recipient responds to the confirmation message.
Email senders typically now do the same type of anti-spam checks on email coming from their users and customers as for inward email coming from the rest of the Internet. This protects their reputation, which could otherwise be harmed in the case of infection by spam-sending malware. 3. Software Implementation, Frameworks & Protocols If a receiving server initially fully accepts an email, and only later determines that the message is spam or to a non-existent recipient, it will generate a bounce message back to the supposed sender. However, if (as is often the case with spam), the sender information on the incoming email was forged to be that of an unrelated third party then this bounce message is backscatter spam. For this reason it is generally preferable for most rejection of incoming email to happen during the SMTP connection stage, with a 5xx error code, while the sending server is still connected. In this case then the sending server will report the problem to the real sender cleanly.
By monitoring spam reports from sources such as SpamCop, AOL's feedback loop, Network Abuse Clearinghouse, the domain's abuse@ mailbox, and others, ISPs can often learn of problems before they seriously damage the ISP's reputation and the ISP's mail servers are blacklisted. From 2000 onwards, many countries enacted specific legislation to criminalize spamming, and appropriate legislation and enforcement can have a significant impact on spamming activity. Where legislation provides specific text that bulk emailers must include, this also makes "legitimate" bulk email easier to identify. Increasingly, anti-spam efforts have led to co-ordination between law enforcement, researchers, major consumer financial service companies and Internet service providers in monitoring and tracking email spam, identity theft and phishing activities and gathering evidence for criminal cases. Analysis of the sites being spamvertised by a given piece of spam can often be followed up with domain registrars with good results.
Since spamming is facilitated by the fact that large volumes of email are very inexpensive to send, one proposed set of solutions would require that senders pay some cost in order to send email, making it prohibitively expensive for spammers. Anti-spam activist Daniel Balsam attempts to make spamming less profitable by bringing lawsuits against spammers. One group of researchers have been looking at a model that homes in on establishing a stark defense; this would increase the cost needed to make the spam effective. They are doing this through the lens of game methodology and strategy, by deploying the strict defensive measures at times of high volume, the spammer would have to spend more money. This would in turn decrease the amount of spam and possibly eliminate it in its entirety. In their experiments testing out this model it was shown to operate as intended, limiting spam overall.
MediaWiki is wiki software written in PHP, initially released in 2002 for its use by Wikipedia. It powers several wiki hosting websites across the Internet, as well as most websites hosted by the Wikimedia Foundation, including Wikipedia, Wiktionary, Wikimedia Commons, Wikiquote, Wikivoyage, Meta-Wiki and Wikidata, which define a large part of the set requirements for the software. Besides its usage on Wikimedia sites, MediaWiki has been used as a knowledge management and content management system on websites such as Fandom, wikiHow and major internal installations like Intellipedia and Diplopedia.
MediaWiki is written in the PHP programming language and stores all text content into a database. The software is optimized to efficiently handle large projects, which can have terabytes of content and hundreds of thousands of views per second. Because Wikipedia is one of the world's largest and most visited websites, achieving scalability through multiple layers of caching and database replication has been a major concern for developers. Another major aspect of MediaWiki is its internationalization; its interface is available in more than 400 languages. The software has hundreds of configuration settings and more than 1,000 extensions available for enabling various features to be added or changed. It was originally developed by Magnus Manske and later further enhanced by Lee Daniel Crocker, after which development has been coordinated by the Wikimedia Foundation.
Due to the strong emphasis on multilingualism in the Wikimedia projects, internationalization and localization has received significant attention by developers. The user interface has been fully or partially translated into more than 400 languages on translatewiki.net, and can be further customized by site administrators (the entire interface is editable through the wiki). MediaWiki handles user-facing interface text through system messages, which can be customized for different languages and locales. For broader multilingual support, the MediaWiki Language Extension Bundle provides a curated set of extensions for adding language-related features to MediaWiki installations. Several extensions, most notably those collected in the MediaWiki Language Extension Bundle, are designed to further enhance the multilingualism and internationalization of MediaWiki.
Installation of MediaWiki requires that the user have administrative privileges on a server running both PHP and a compatible type of SQL database. Some users find that setting up a virtual host is helpful if the majority of one's site runs under a framework (such as Zope or Ruby on Rails) that is largely incompatible with MediaWiki. Cloud hosting can eliminate the need to deploy a new server. An installation PHP script is accessed via a web browser to initialize the wiki's settings. It prompts the user for a minimal set of required parameters, leaving further changes, such as enabling uploads, adding a site logo, and installing extensions, to be made by modifying configuration settings contained in a file called LocalSettings.php. Some aspects of MediaWiki can be configured through special pages or by editing certain pages; for instance, abuse filters can be configured through a special page, and certain gadgets can be added by creating JavaScript pages in the MediaWiki namespace. The MediaWiki community publishes a comprehensive installation guide.
MediaWiki's default page-editing tools have been described as somewhat challenging to learn. A survey of students assigned to use a MediaWiki-based wiki found that when they were asked an open question about main problems with the wiki, 24% cited technical problems with formatting, e.g. "Couldn't figure out how to get an image in. Can't figure out how to show a link with words; it inserts a number." To make editing long pages easier, MediaWiki allows the editing of a subsection of a page (as identified by its header). A registered user can also indicate whether or not an edit is minor. Correcting spelling, grammar or punctuation are examples of minor edits, whereas adding paragraphs of new text is an example of a non-minor edit.
Sometimes while one user is editing, a second user saves an edit to the same part of the page. Then, when the first user attempts to save the page, an edit conflict occurs. The second user is then given an opportunity to merge their content into the page as it now exists following the first user's page save. MediaWiki's user interface has been localized in many different languages. A language for the wiki content itself can also be set, to be sent in the "Content-Language" HTTP header and "lang" HTML attribute. VisualEditor has its own integrated wikitext editing interface known as 2017 wikitext editor, the older editing interface is known as 2010 wikitext editor.
Interwiki links function much the same way as namespaces. A set of interwiki prefixes can be configured to cause, for instance, a page title of wikiquote:Jimbo Wales to direct the user to the Jimbo Wales article on Wikiquote. Unlike internal wikilinks, interwiki links lack page existence detection functionality, and accordingly there is no way to tell whether a blue interwiki link is broken or not.
Interlanguage links are the small navigation links that show up in the sidebar in most MediaWiki skins that connect an article with related articles in other languages within the same Wiki family. This can provide language-specific communities connected by a larger context, with all wikis on the same server or each on its own server. Previously, Wikipedia used interlanguage links to link an article to other articles on the same topic in other editions of Wikipedia. This was superseded by the launch of Wikidata.
Page tabs are displayed at the top of pages. These tabs allow users to perform actions or view pages that are related to the current page. The available default actions include viewing, editing, and discussing the current page. The specific tabs displayed depend on whether the user is logged into the wiki and whether the user has sysop privileges on the wiki. For instance, the ability to move a page or add it to one's watchlist is usually restricted to logged-in users. The site administrator can add or remove tabs by using JavaScript or installing extensions. Each page has an associated history page from which the user can access every version of the page that has ever existed and generate diffs between two versions of his choice.
Users' contributions are displayed not only here, but also via a "user contributions" option on a sidebar. In a 2004 article, Carl Challborn and Teresa Reimann noted that "While this feature may be a slight deviation from the collaborative, 'ego-less' spirit of wiki purists, it can be very useful for educators who need to assess the contribution and participation of individual student users." MediaWiki provides many features beyond hyperlinks for structuring content. One of the earliest such features is namespaces. One of Wikipedia's earliest problems had been the separation of encyclopedic content from pages pertaining to maintenance and communal discussion, as well as personal pages about encyclopedia editors. Namespaces are prefixes before a page title (such as "User:" or "Talk:") that serve as descriptors for the page's purpose and allow multiple pages with different functions to exist under the same title. For instance, a page titled "[[The Terminator]]", in the default namespace, could describe the 1984 movie starring Arnold Schwarzenegger, while a page titled "[[User:The Terminator]]" could be a profile describing a user who chooses this name as a pseudonym. More commonly, each namespace has an associated "Talk:" namespace, which can be used to discuss its contents, such as "User talk:" or "Template talk:". The purpose of having discussion pages is to allow content to be separated from discussion surrounding the content. Namespaces can be viewed as folders that separate different basic types of information or functionality. Custom namespaces can be added by the site administrators. There are 16 namespaces by default for content, with two pseudo-namespaces used for dynamically generated "Special:" pages and links to media files. Each namespace on MediaWiki is numbered: content page namespaces have even numbers and their associated talk page namespaces have odd numbers.
4. Practical Deployment, Analysis & Case Studies Collaborative tagging systems like del.icio.us and Hierarchical classifications like the Dewey Decimal Classification. If the feature is enabled, users can customize their stylesheets and configure client-side JavaScript to be executed with every pageview. On Wikipedia, this has led to a large number of additional tools and helpers developed through the wiki and shared among users. For instance, navigation popups is a custom JavaScript tool that shows previews of articles when the user hovers over links and also provides shortcuts for common maintenance tasks.
The entire MediaWiki user interface can be edited through the wiki itself by users with the necessary permissions (typically called "administrators"). This is done through the MediaWiki namespace, a special namespace with the prefix "MediaWiki:", where each page title identifies a particular user interface message. Using an extension, it is also possible for a user to create personal scripts, and to choose whether certain sitewide scripts should apply to them by toggling the appropriate options in the user preferences page.
Among the most popular extensions is a parser function extension, ParserFunctions, which allows different content to be rendered based on the result of conditional statements. These conditional statements can perform functions such as evaluating whether a parameter is empty, comparing strings, evaluating mathematical expressions, and returning one of two values depending on whether a page exists. It was designed as a replacement for a notoriously inefficient template called {{Qif}}. Schindler recounts the history of the ParserFunctions extension as follows: In 2006 some Wikipedians discovered that through an intricate and complicated interplay of templating features and CSS they could create conditional wiki text, i.e. text that was displayed if a template parameter had a specific value. This included repeated calls of templates within templates, which bogged down the performance of the whole system. The developers faced the choice of either disallowing the spreading of an obviously desired feature by detecting such usage and explicitly disallowing it within the software or offering an efficient alternative. The latter was done by Tim Starling, who announced the introduction of parser functions, wiki text that calls functions implemented in the underlying software. At first, only conditional text and the computation of simple mathematical expressions were implemented, but this already increased the possibilities for wiki editors enormously. With time further parser functions were introduced, finally leading to a framework that allowed the simple writing of extension functions to add arbitrary functionalities, like e.g. geo-coding services or widgets. This time the developers were clearly reacting to the demand of the community, being forced either to fight the solution of the issue that the community had (i.e. conditional text), or offer an improved technical implementation to replace the previous practice and achieve an overall better performance. Another parser functions extension, StringFunctions, was developed to allow evaluation of string length, string position, and so on. Wikimedia communities, having created awkward workarounds to accomplish the same functionality, clamored for it to be enabled on their projects. Much of its functionality was eventually integrated into the ParserFunctions extension, albeit disabled by default and accompanied by a warning from Tim Starling that enabling string functions would allow users "to implement their own parsers in the ugliest, most inefficient programming language known to man: MediaWiki wikitext with ParserFunctions." MediaWiki comes pre-installed with a standard text-based search. Extensions exist to let MediaWiki use more sophisticated third-party search engines, including Elasticsearch (which since 2014 has been in use on Wikipedia), Lucene and Sphinx.
Various MediaWiki extensions have also been created to allow for more complex, faceted search, on both data entered within the wiki and on metadata such as pages' revision history. Semantic MediaWiki is one such extension. Various extensions to MediaWiki support rich content generated through specialized syntax. These include mathematical formulas using LaTeX, graphical timelines over mathematical plotting, musical scores and Egyptian hieroglyphs. The software supports a wide variety of uploaded media files, and allows image galleries and thumbnails to be generated with relative ease.
There is also support for Exif metadata. MediaWiki operates the Wikimedia Commons, one of the largest free content media archives. For WYSIWYG editing, VisualEditor is available to use in MediaWiki which simplifying editing process for editors and has been bundled since MediaWiki 1.35. Other extensions exist for handling WYSIWYG editing to different degrees. MediaWiki can use either the MySQL/MariaDB, PostgreSQL or SQLite relational database management system. Support for Oracle Database and Microsoft SQL Server has been dropped since MediaWiki 1.34. A MediaWiki database contains several dozen tables, including a page table that contains page titles, page ids, and other metadata; and a revision table to which is added a new row every time an edit is made, containing the page id, a brief textual summary of the change performed, the user name of the article editor (or its IP address the case of an unregistered user) and a timestamp. In a 4½ year period prior to 2008, the MediaWiki database had 170 schema versions. Possibly the largest schema change was done in 2005 with MediaWiki 1.5, when the storage of metadata was separated from that of content, to improve performance flexibility. When this upgrade was applied to Wikipedia, the site was locked for editing, and the schema was converted to the new version in about 22 hours. Some software enhancement proposals, such as a proposal to allow sections of articles to be watched via watchlist, have been rejected because the necessary schema changes would have required excessive Wikipedia downtime.
MediaWiki developers have enacted security standards, both for core code and extensions. As of 2008, SQL queries and HTML output are usually done through wrapper functions that handle validation, escaping, filtering for prevention of cross-site scripting and SQL injection. Many security issues have had to be patched after a MediaWiki version release, and in 2010 MediaWiki.org stated, "The most important security step you can take is to keep your software up to date" by subscribing to the announcement mailing list and installing security updates that are announced.
MediaWiki.org, including the Support Desk. Mailing lists, including the official mailing list, Mediawiki-l. Several books have been written about MediaWiki administration, including some free online books. MediaWiki has an active volunteer community for development and maintenance. MediaWiki developers are spread around the world, though with a majority in the United States and Europe. Face-to-face meetings and programming sessions for MediaWiki developers have been held once or several times a year since 2004. Anyone can submit patches to the project's Git/Gerrit repository. There are also paid programmers who primarily develop projects for the Wikimedia Foundation.
MediaWiki developers participate in the Google Summer of Code by facilitating the assignment of mentors to students wishing to work on MediaWiki core and extension projects. During the year prior to November 2012, there were about two hundred developers who had committed changes to the MediaWiki core or extensions. Major MediaWiki releases are generated approximately every six months by taking snapshots of the development branch, which is kept continuously in a runnable state; minor releases, or point releases, are issued as needed to correct bugs (especially security problems). MediaWiki is developed on a continuous integration development model, in which software changes are pushed live to Wikimedia sites on a regular basis. MediaWiki also has a public bug tracker, phabricator.wikimedia.org, which runs Phabricator. The site is also used for feature and enhancement requests.
5. Performance Evaluation & Extended Technical Observations When Wikipedia was launched in January 2001, it ran on an existing wiki software system, UseModWiki. UseModWiki is written in the Perl programming language, and stores all wiki pages in text (.txt) files. This software soon proved to be limiting, in both functionality and performance. In mid-2001, Magnus Manske—a developer and student at the University of Cologne, as well as a Wikipedia editor—began working on new software that would replace UseModWiki, specifically designed for use by Wikipedia. This software was written in the PHP scripting language, and stored all of its information in a MySQL database.
The new software was largely developed by August 24, 2001, and a test wiki for it was established shortly thereafter. The first full implementation of this software was the new Meta-Wikipedia (now Meta-Wiki) on November 9, 2001. There was a desire to have it implemented immediately on the English-language Wikipedia. However, Manske was apprehensive about any potential bugs harming the nascent website during the period of the final exams he had to complete immediately before Christmas; this led to the launch on the English-language Wikipedia being delayed until January 25, 2002. The software was then, gradually, deployed on all the Wikipedia language sites of that time. This software was referred to as "the PHP script" and as "phase II", with the name "phase I" retroactively given to the use of UseModWiki. Increasing usage soon caused load problems to arise again, and soon after, another rewrite of the software began; this time being done by Lee Daniel Crocker, which became known as "phase III". This new software was also written in PHP, with a MySQL backend, and kept the basic interface of the phase II software, but with the added functionality of wider scalability. The "phase III" software went live on Wikipedia in July 2002. The Wikimedia Foundation was announced on June 20, 2003. In July, Wikipedia contributor Daniel Mayer suggested the name "MediaWiki" for the software, as a play on "Wikimedia". The MediaWiki name was gradually phased in, beginning in August 2003. The name has frequently caused confusion due to its (intentional) similarity to the "Wikimedia" name (which itself is similar to "Wikipedia"). The first version of MediaWiki, 1.1, was released in December 2003.
The old product logo was created by Erik Möller, using a flower photograph taken by Florence Nibart-Devouard, and was originally submitted to the logo contest for a new Wikipedia logo, held from July 20 to August 27, 2003. The logo came in third place, and was chosen to represent MediaWiki rather than Wikipedia, with the second place logo being used for the Wikimedia Foundation. The double square brackets ([[ ]]) symbolize the syntax MediaWiki uses for creating hyperlinks to other wiki pages; while the sunflower represents the diversity of content on Wikipedia, its constant growth, and the wilderness. In a 2006 talk at Google given by Brooke Vibber it was noted by the introducer that Vibber, who had "been with WikiMedia about four years now", was "up until recently [...] the only full-time paid employee for the engineering side of things"; this remark was made to comment on the large amount of volunteer effort that must accompany this. In 2007, Vibber was the chief technical officer of the Wikipedia organization. Major milestones in MediaWiki's development have included: the categorization system (2004); parser functions, (2006); Flagged Revisions, (2008); the "ResourceLoader", a delivery system for CSS and JavaScript (2011); and the VisualEditor, a "what you see is what you get" (WYSIWYG) editing platform (2013). The contest of designing a new logo was initiated on June 22, 2020, as the old logo was a bitmap image and had "high details", leading to problems when rendering at high and low resolutions, respectively. After two rounds of voting, the new and current MediaWiki logo designed by Serhio Magpie was selected on October 24, 2020, and officially adopted on April 1, 2021. Starting in 2020, Wikipedia in concert with MediaWiki started rolling out its biggest UI redesign in a decade.
MediaWiki's most famous use has been in Wikipedia and, to a lesser degree, the Wikimedia Foundation's other projects. Fandom, a wiki hosting service formerly known as Wikia, runs on MediaWiki. Other public wikis that run on MediaWiki include wikiHow and SNPedia. WikiLeaks began as a MediaWiki-based site, but is no longer a wiki. A number of alternative wiki encyclopedias to Wikipedia run on MediaWiki, including Citizendium, Metapedia, Scholarpedia and Conservapedia.
MediaWiki is also used internally by a large number of companies, including Novell and Intel. Notable usages of MediaWiki within governments include Intellipedia, used by the United States Intelligence Community, Diplopedia, used by the United States Department of State, and milWiki, a part of milSuite used by the United States Department of Defense. United Nations agencies such as the United Nations Development Programme and INSTRAW chose to implement their wikis using MediaWiki, because "this software runs Wikipedia and is therefore guaranteed to be thoroughly tested, will continue to be developed well into the future, and future technicians on these wikis will be more likely to have exposure to MediaWiki than any other wiki software." The Free Software Foundation uses MediaWiki to implement the LibrePlanet site.
Users of online collaboration software may be familiar with MediaWiki's functions and layout due to its noted use on Wikipedia. A 2006 overview of social software in academia observed that "Compared to other wikis, MediaWiki is also fairly aesthetically pleasing, though simple, and has an easily customized side menu and stylesheet." A 2006 assessment found Confluence to be preferarble due to its API and ability to better support multiple wikis. Another 2006 assessment found it to be polished and reliable for new users and administrators. InfoWorld recognized MediaWiki in 2008 for ease of maintenance for administrators as well as its look and features. A 2009 study at the University of Hong Kong compared TWiki to MediaWiki.
The authors noted that TWiki has been a collaborative tool mostly for the development of educational papers and technical projects, whereas MediaWiki's most noted use is on Wikipedia. Although both platforms allow discussion and tracking of progress, TWiki has a "Report" part that MediaWiki lacks. Students perceived MediaWiki as being easier to use and more enjoyable than TWiki. When asked whether they recommended using MediaWiki for knowledge management course group project, 15 out of 16 respondents expressed their preference for MediaWiki giving answers of great certainty, such as "of course", "for sure". TWiki and MediaWiki both have flexible plug-in architecture. Another 2009 study in Hong Kong compared students' experience with MediaWiki to that with Google Docs found that students preferred MediaWiki overall for managing information and gave the Google Docs a higher rating on user-friendly layout. A 2021 study conducted by the Brazilian Nuclear Engineering Institute compared a MediaWiki-based knowledge management system against two others that were based on DSpace and Open Journal Systems, respectively. It highlighted ease of use as an advantage of the MediaWiki-based system, noting that because the Wikimedia Foundation had been developing MediaWiki for a site aimed at the general public (Wikipedia), "its user interface was designed to be more user-friendly from start, and has received large user feedback over a long time", in contrast to DSpace's and OJS's focus on niche audiences. A 2025 interview of two maintainers of ArchWiki (which uses MediaWiki) said that the markup language is the main issue of MediaWiki, saying it was 'weird', 'fragile' and difficult to write a parser for a language without a formal specification of the language. Klinkovský recommended new projects that do not like MediaWiki's markup to look at wikis that use Markdown instead. They did praise MediaWiki's wide usage and its API.
List of content management systems List of wiki software BlueSpice Semantic MediaWiki XOWA – for viewing Wikipedia and other wikis offline PHP – a programming language that powers MediaWiki 17 January – A study in Nature finds that the Greenland ice sheet is melting 20% faster than previously estimated, due to the effects of calving-front retreat. The loss of 30m tonnes of ice an hour is "sufficient to affect ocean circulation and the distribution of heat energy around the globe." 18 January NASA reports the end of the Ingenuity helicopter's operation, after 72 successful flights on Mars, due to a broken rotor blade. A potential candidate for the first known radio pulsar-black hole binary is reported by astronomers. The heavier of the two lies in the "mass gap" between neutron stars and black holes. The pair are located in the globular cluster NGC 1851. Two insect-like robots, a mini-bug and a water strider, are reported as being the smallest, lightest, and fastest fully-functional micro-robots ever created. Bottom trawling is found to release 340 million tonnes of carbon dioxide (CO2) into the atmosphere each year, nearly 1 percent of all global CO2 emissions in addition to acidifying oceans. 19 January – Japan becomes the fifth country to achieve a soft landing on the Moon, with its SLIM mission.
21 January – Biologists report the discovery of "obelisks", a new class of viroid-like elements, and "oblins", their related group of proteins, in the human microbiome. 23 January – A viable and sustainable approach for gold recovery from e-waste is demonstrated. 24 January The discovery of 85 exoplanet candidates based on data from the TESS observatory is reported. All have orbital periods of between 20 and 700 days, with temperatures similar to those of Solar System planets. A global analysis of groundwater levels reports rapid declines of over 0.5 meters per year are widespread and that declines have accelerated over the past four decades in 30% of the world's regional aquifers. The study also shows cases in which depletion trends have reversed following interventions such as policy changes. 25 January – The Laser Interferometer Space Antenna (LISA) is given the go-ahead by the European Space Agency (ESA). It will launch in 2035. 26 January – Astronomers report the detection of water vapor in the atmosphere of GJ 9827 d, an exoplanet about twice the size of Earth. 29 January Elon Musk's startup Neuralink implants their first microchip into a human brain. A robotic sensor able to read braille with 87.5% accuracy and at twice the speed of a human is demonstrated. 31 January – NASA reports the discovery of a super-Earth called TOI-715 b, located in the habitable zone of a red dwarf star about 137 light-years away. Promising innovations relating to global challenges are reported: a self-powered solar panel cleaning system using an electrodynamic screen, removing contaminants through high-voltage electric fields, is demonstrated (4 Jan), an atmospheric water generator (WaterCube) for humidity levels above 40% is released (9 Jan). Promising results of health and medical research are reported: mouse-tested novel antibiotics class (including Zosurabalpin) against A. baumannii (3 Jan), small-trialed focused ultrasound for blood–brain barrier opening for better medication (Aducanumab) entry against Alzheimer's disease (3 Jan), a review supports the efficacy of exercise against depression (15 Jan), an available blood test to detect Alzheimer's disease with high accuracy using p-tau217 (22 Jan), one of two small-trialed gene therapies against DFNB9-deafness (24 Jan), phase 3-trialed dengue vaccine effective against at least two of four dengue types (31 Jan) Hazard research is published: ~240.000 particles of microplastic and nanoplastics (~90%) per liter are found in samples of plastic-bottled water (8 Jan), a study estimates harmful chemicals used in plastic materials have caused $249 billion U.S. healthcare system costs in 2018 (11 Jan), a study indicates fungal infections may be causing millions more deaths annually than thought (12 Jan), a study of European plastic waste exports to Vietnam finds a large fraction is dumped in nature and suggests air pollution from melting plastics and untreated wastewater have significant impact on health (18 Jan).
10 February – An analysis of Outer London's Mini-Hollands active transport infrastructures indicates Low Traffic Neighbourhoods are highly effective and cost-efficient measures in terms of health economic benefits. 12 February – The first detection of water molecules on the surface of asteroids is announced, following spectral analysis of 7 Iris and 20 Massalia, two large main-belt objects.
14 February – A study reviews educational content of 18,400 universities worldwide, finding higher education is not transitioning from fossil fuels to renewable energy curricula, failing to meet the growing demand for a clean energy workforce. On 26 February, a study analyzing funding sources and activities of two prominent academic centers delineates animal agriculture industry entrenchment in academia through support of industry-supported research and policy advocacy amid potential unfavorable policies.
17 February – A global review of harms from personal car automobility finds cars have killed 60–80 million people since their invention, with automobility causing roughly every 34th death, and summarises interventions that are ready for implementation to reduce the, largely crash-linked or pollution-mediated, deaths from automobility-centrism and dependency. 19 February Astronomers announce the most luminous object ever discovered, quasar QSO J0529-4351, located 12 billion light-years away in the constellation Pictor. Researchers with the University of Tennessee and University of Missouri publish an academic study about how survivors from the 2011 Joplin tornado recover from "Tornado Brain", a new term for the PTSD of tornado survivors. 20 February – The northern green anaconda (Eunectes akayima), a new species of the giant snake, is described for the first time. 21 February Researchers use artificial intelligence to forecast plasma instabilities in fusion reactors up to 300 milliseconds in advance. The first neuroimaging study that shows flow state-related brain activity during a creative production task, jazz improvisation, is published. Its results support a theory that creative flow represents optimized specialized processing enabled by extensive experience, relaxing conscious control.
22 February – American company Intuitive Machines' Nova-C lander, named Odysseus, becomes the first commercial vehicle to land on the Moon in the IM-1 mission. The lander includes a Lunar Library that contains a version of the English Wikipedia, artworks, selections from the Internet Archive, portions of the Project Gutenberg, and more. It is projected to reside on the Moon in a readable state for billions of years. 23 February Researchers report studies that, for the first time, measured gravity at microscopic levels. Three new moons of the Solar System are discovered, one around Uranus and two around Neptune, bringing their total known satellites to 28 and 16, respectively. 26 February – A small trial suggests prebiotic resistant starch, contained in many foods, can help in weight loss (~2.8 kg in 8 weeks). 28 February A study links ultra-processed foods to 32 negative health impacts, including a higher risk of heart disease, cancer, type 2 diabetes, adverse mental health, and early death. A study reconstructs the genetic event of tail-loss in human ancestors around 25 million years ago. Promising innovations relating to global challenges are reported: LAION releases a first version of BUD-E, a fully open source voice assistant (8 Feb), Minesto's Dragon 12 underwater tidal kite turbines are demonstrated successfully, connected to the Faroe Island's power grid (11 Feb), rice grains as scaffolds containing cultured animal cells are demonstrated (14 Feb), an automatic waste sorting system (ZenRobotics 4.0) that can distinguish between over 500 waste categories is released (15 Feb), researchers describe an AI ecosystem interface of foundation models connected to many APIs as specialized subtask-solvers (16 Feb), precision fermentation-derived beta-lactoglobulin is released as a substitute for whey protein amid growth of a nascent animal-free dairy industry (19 Feb), researchers describe an approach for an optical disk with petabit capacity (21 Feb). Promising results of health and medical research are reported: phase 3-trialed R21/Matrix-M vaccine against Malaria (1 Feb), phase 3-trialed resmetirom as first medication against nonalcoholic steatohepatitis of the liver (7 Feb), a blood test against heart attacks, the top cause of human deaths (12 Feb), a low-cost saliva test against breast cancer (13 Feb), pigs-tested patient repositioning method for magnetic microbot navigation against liver cancer (14 Feb), antibiotic cresomycin against multiple drug-resistant bacterial strains (15 Feb), small-trialed 15 min exposure to 670 nm red light against blood glucose spikes following meals (20 Feb), small-trialed Omalizumab against food allergies (25 Feb), a donor heart is transplanted after 12 hours of preservation and transport using an airplane, small-trialed headgear for gamma stimulation to recruit the glymphatic system to remove brain amyloid against Alzheimer's disease (28 Feb). Hazard research is published: several dietary habits and products including teabags are linked to PFAS intake (4 Feb), an additional three billion people may face water scarcity by 2050 when river pollution is considered, an aspect neglected by prior assessments (6 Feb), HPV infection linked to higher cardiovascular mortality (7 Feb), researchers use simulations to develop an early-warning signal for a potential collapse of the atlantic meridional overturning circulation (AMOC) and suggest it indicates the AMOC is "on route to tipping" (9 Feb), researchers report the H5N1 bird flu virus may be changing and adapting to infect more mammals (12 Feb), researchers report how compounding disturbances could trigger unexpected ecosystem transitions in the Amazon rainforest (14 Feb), harmful chlormequat is found in ~80% of U.S. adult urine samples, rising during 2023, and in oat-based foods widely thought to be healthy (15 Feb), excess amounts of widely-supplemented niacin (B3) are linked to cardiovascular risk (19 Feb), a review concludes available evidence on the use of puberty blockers and cross-sex hormones in minors with gender dysphoria is very limited and based on only a few studies with small numbers which have problematic methodology and quality, warning about their use outside of clinical studies or research projects after careful risk-benefit evaluation (27 Feb).
14 March – SpaceX successfully launches the Starship spacecraft, but loses the rocket upon re-entering the atmosphere. 19 March Scientists demonstrate a wireless network of 78 tiny sensors able to gather data from the brain, with potential to be scaled up to thousands of such devices. Researchers with the National Severe Storms Laboratory, Storm Prediction Center, CIWRO, and the University of Oklahoma's School of Meteorology publish a paper where they state, ">20% of supercell tornadoes may be capable of producing EF4–EF5 damage" and that "the legacy F-scale wind speed ranges may ultimately provide a better estimate of peak tornado wind speeds at 10–15 m AGL for strong–violent tornadoes and a better damage-based intensity rating for all tornadoes" and also put the general 0–5 ranking scale in question. 20 March – The removal of HIV from infected cells using CRISPR gene editing technology is reported. 26 March – A study outlines identified ecological pandemic prevention measures for policy frameworks.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Anti-spam%20techniques • https://en.wikipedia.org/wiki/MediaWiki • https://en.wikipedia.org/wiki/2024%20in%20science
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Captcha Based Automated Bot Prevention System In Python.
[*] Metasploit Scan Running on Target Subnet for Captcha Based Automated Bot Prevention System In Python... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |