Complete Technical Paper Content — Cloud Cost Anomaly Detection Related To Security Breaches
Overview & System Context
Cloud Cost Anomaly Detection Related To Security Breaches: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9513 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background An intrusion detection system (IDS) is a device or software application that monitors a network or systems for malicious activity or policy violations. Any intrusion activity or violation is typically either reported to an administrator or collected centrally using a security information and event management (SIEM) system. A SIEM system combines outputs from multiple sources and uses alarm filtering techniques to distinguish malicious activity from false alarms. IDS types range in scope from single computers to large networks. The most common classifications are network intrusion detection systems (NIDS) and host-based intrusion detection systems (HIDS). A system that monitors important operating system files is an example of an HIDS, while a system that analyzes incoming network traffic is an example of an NIDS. It is also possible to classify IDS by detection approach. The most well-known variants are signature-based detection (recognizing bad patterns, such as exploitation attempts) and anomaly-based detection (detecting deviations from a model of "good" traffic, which often relies on machine learning). Another common variant is reputation-based detection (recognizing the potential threat according to the reputation scores). Some IDS products have the ability to respond to detected intrusions. Systems with response capabilities are typically referred to as an intrusion prevention system (IPS). Intrusion detection systems can also serve specific purposes by augmenting them with custom tools, such as using a honeypot to attract and characterize malicious traffic.
Host intrusion detection systems (HIDS) run on individual hosts or devices on the network. A HIDS monitors the inbound and outbound packets from the device only and will alert the user or administrator if suspicious activity is detected. It takes a snapshot of existing system files and matches it to the previous snapshot. If the critical system files were modified or deleted, an alert is sent to the administrator to investigate. An example of HIDS usage can be seen on mission critical machines, which are not expected to change their configurations.
Network-based intrusion prevention system (NIPS): monitors the entire network for suspicious traffic by analyzing protocol activity. Wireless intrusion prevention system (WIPS): monitor a wireless network for suspicious traffic by analyzing wireless networking protocols. Network behavior analysis (NBA): examines network traffic to identify threats that generate unusual traffic flows, such as distributed denial of service (DDoS) attacks, certain forms of malware and policy violations. Host-based intrusion prevention system (HIPS): an installed software package which monitors a single host for suspicious activity by analyzing events occurring within that host.
Signature-based detection: Signature-based IDS monitors packets in the Network and compares with pre-configured and pre-determined attack patterns known as signatures. While it is the simplest and most effective method, it fails to detect unknown attacks and variants of known attacks. Statistical anomaly-based detection: An IDS which is anomaly-based will monitor network traffic and compare it against an established baseline. The baseline will identify what is "normal" for that network – what sort of bandwidth is generally used and what protocols are used. It may however, raise a False Positive alarm for legitimate use of bandwidth if the baselines are not intelligently configured. Ensemble models that use Matthews correlation co-efficient to identify unauthorized network traffic have obtained 99.73% accuracy. Stateful protocol analysis detection: This method identifies deviations of protocol states by comparing observed events with "pre-determined profiles of generally accepted definitions of benign activity". While it is capable of knowing and tracing the protocol states, it requires significant resources.
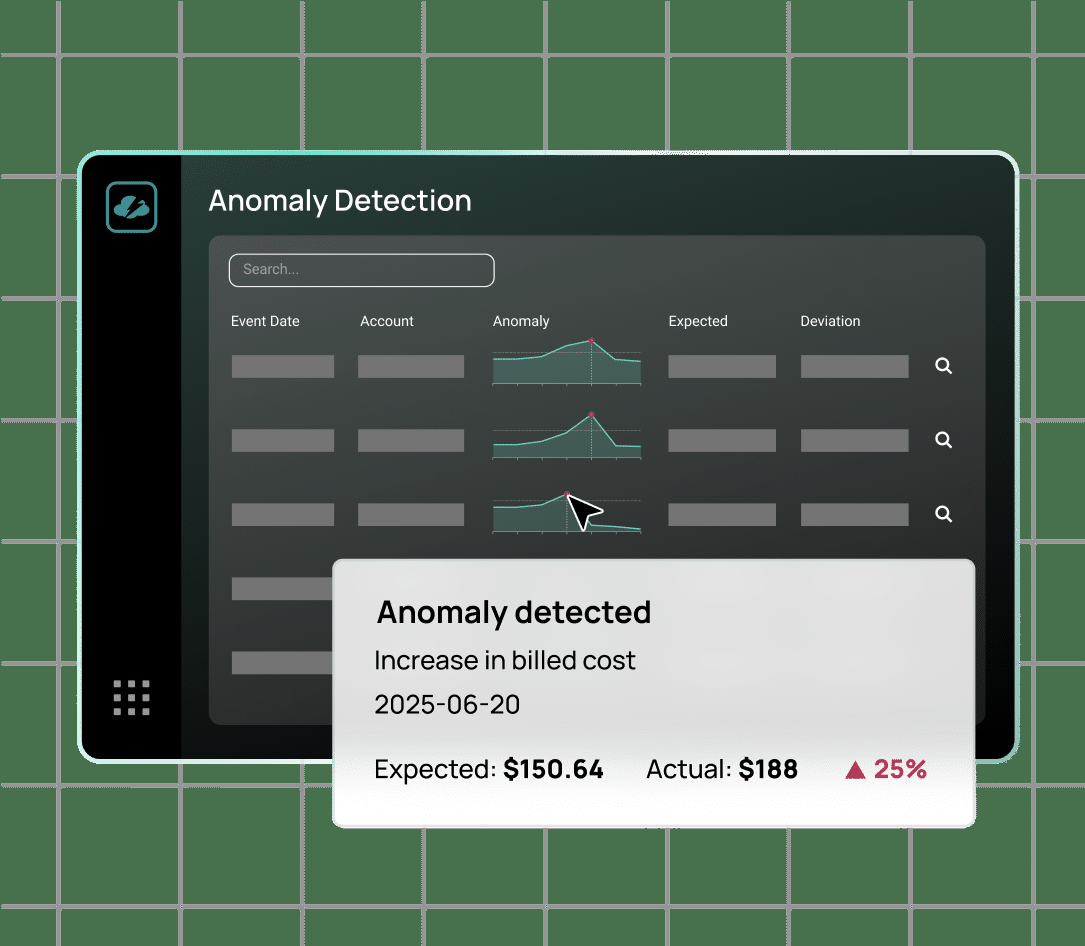
Figure 1: Hybrid Cloud Reporting | CloudBolt There are a number of techniques which attackers are using, the following are considered 'simple' measures which can be taken to evade IDS: Fragmentation: by sending fragmented packets, the attacker will be under the radar and can easily bypass the detection system's ability to detect the attack signature. Avoiding defaults: The TCP port utilised by a protocol does not always provide an indication to the protocol which is being transported. For example, an IDS may expect to detect a trojan on port 12345. If an attacker had reconfigured it to use a different port, the IDS may not be able to detect the presence of the trojan.
Coordinated, low-bandwidth attacks: coordinating a scan among numerous attackers (or agents) and allocating different ports or hosts to different attackers makes it difficult for the IDS to correlate the captured packets and deduce that a network scan is in progress. Address spoofing/proxying: attackers can increase the difficulty of the Security Administrators ability to determine the source of the attack by using poorly secured or incorrectly configured proxy servers to bounce an attack. If the source is spoofed and bounced by a server, it makes it very difficult for IDS to detect the origin of the attack. Pattern change evasion: IDS generally rely on 'pattern matching' to detect an attack. By changing the data used in the attack slightly, it may be possible to evade detection. For example, an Internet Message Access Protocol (IMAP) server may be vulnerable to a buffer overflow, and an IDS is able to detect the attack signature of 10 common attack tools. By modifying the payload sent by the tool, so that it does not resemble the data that the IDS expects, it may be possible to evade detection.
This article incorporates public domain material from Karen Scarfone, Peter Mell. Guide to Intrusion Detection and Prevention Systems, SP800-94 (PDF). National Institute of Standards and Technology. Retrieved 9 July 2025. Snowflake Inc. is an American cloud-based artificial intelligence (AI) data platform company founded in San Mateo, California, and headquartered in Menlo Park. It operates a platform that supports data analysis and simultaneous access to data sets with minimal latency. It operates on Amazon Web Services, Microsoft Azure, and Google Cloud Platform.
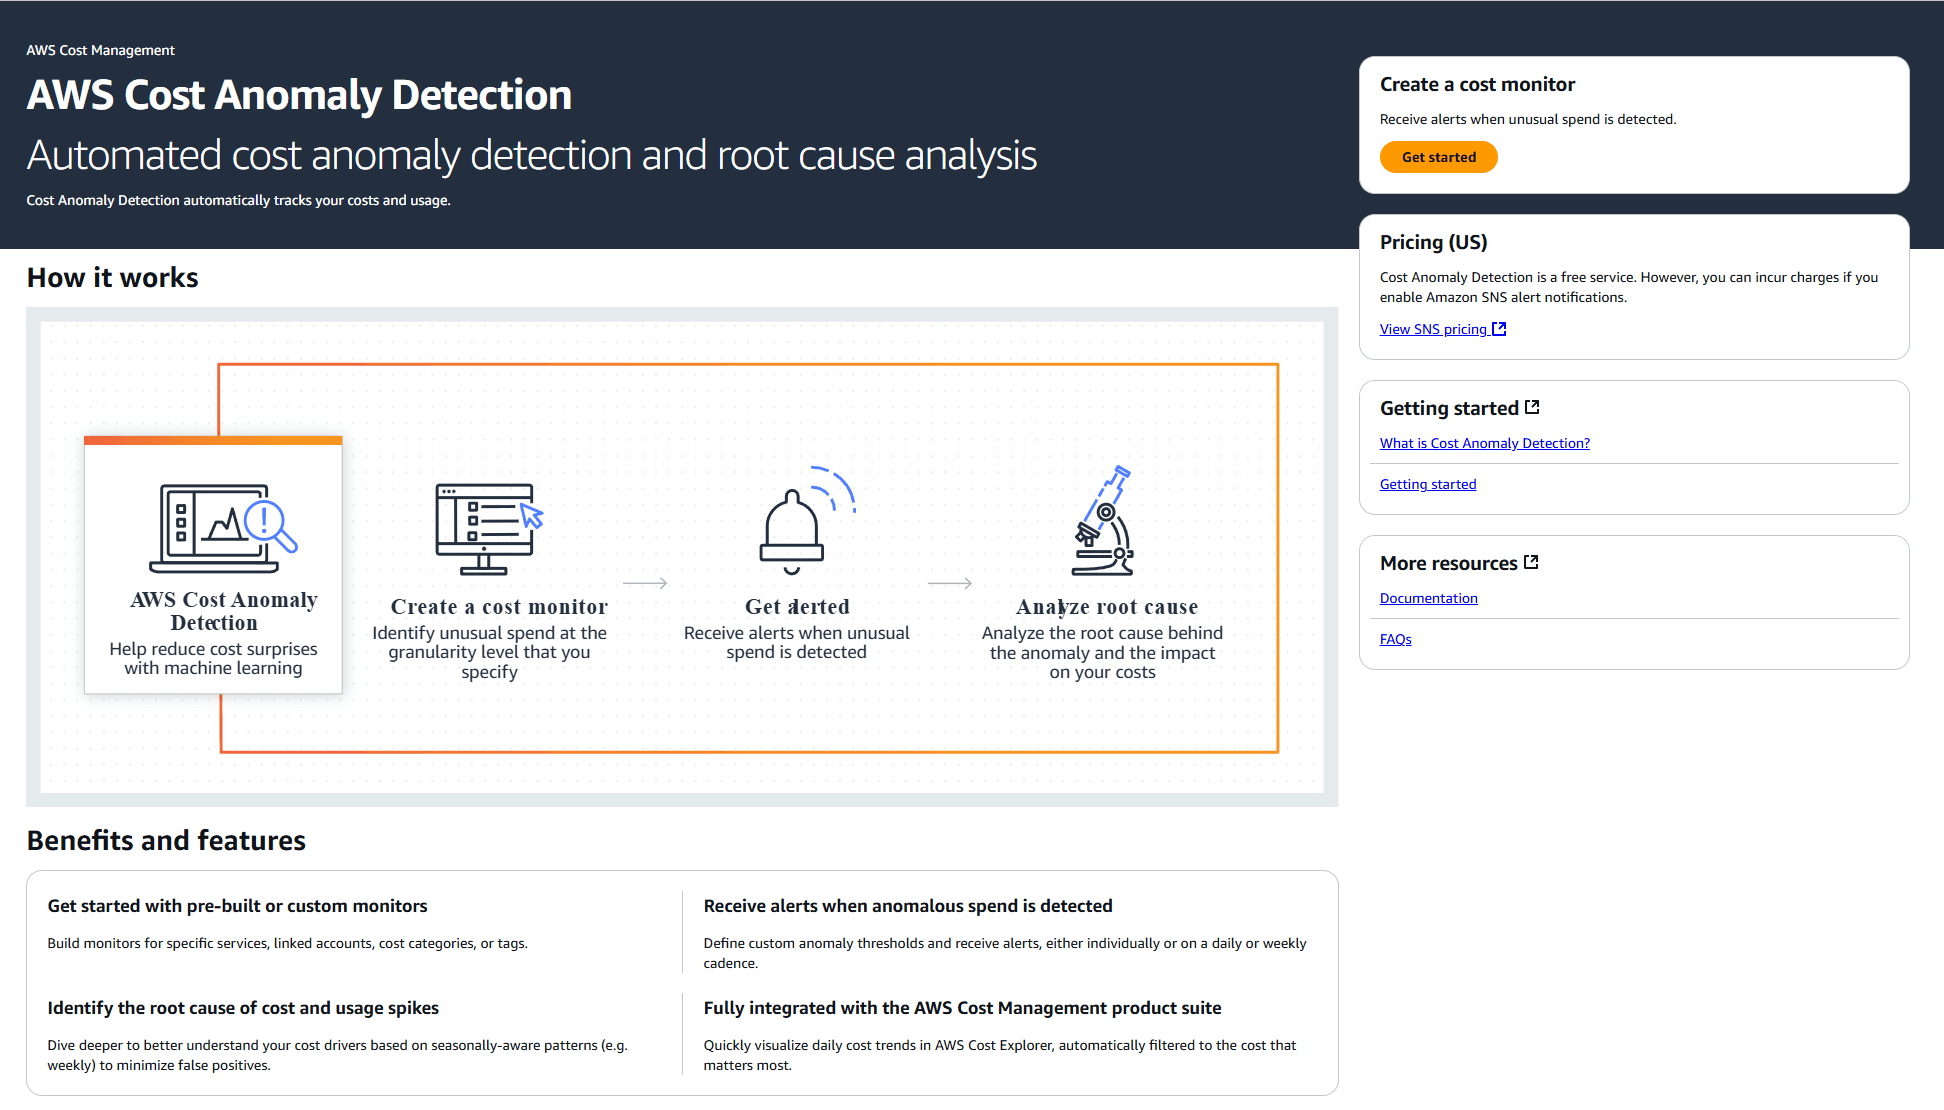
Figure 2: AWS Cost Management: Tools & Best Practices Local differential privacy (LDP) is a model of differential privacy with the added requirement that if an adversary has access to the personal responses of an individual in the database, that adversary will still be unable to learn much of the user's personal data. This is contrasted with global differential privacy, a model of differential privacy that incorporates a central aggregator with access to the raw data. Local differential privacy (LDP) is an approach to mitigate the concern of data fusion and analysis techniques used to expose individuals to attacks and disclosures. LDP is a well-known privacy model for distributed architectures that aims to provide privacy guarantees for each user while collecting and analyzing data, protecting from privacy leaks for the client and server. LDP has been widely adopted to alleviate contemporary privacy concerns in the era of big data.
Facial recognition has become widespread in recent years. Recent smartphones, for example, utilize facial recognition to unlock the users phone as well as authorize the payment with their credit card. Though this is convenient, it poses privacy concerns. It is a resource-intensive task that often involves third party users, often resulting in a gap where the user's privacy could be compromised. Biometric information delivered to untrusted third-party servers in an uncontrolled manner can constitute a significant privacy leak as biometrics can be correlated with sensitive data such as healthcare or financial records.
In Chamikara's academic article, he proposes a privacy-preserving technique for "controlled information release", where they disguise an original face image and prevent leakage of the biometric features while identifying a person. He introduces a new privacy-preserving face recognition protocol named PEEP (Privacy using Eigenface Perturbation) that utilizes local differential privacy. PEEP applies perturbation to Eigenfaces utilizing differential privacy and stores only the perturbed data in the third-party servers to run a standard Eigenface recognition algorithm. As a result, the trained model will not be vulnerable to privacy attacks such as membership inference and model memorization attacks. This model provided by Chami kara shows the potential solution of this issue or privacy leaks.
Federated learning has the ambition to protect data privacy through distributed learning methods that keep the data in its storage. Likewise, differential privacy (DP) attains to improve the protection of data privacy by measuring the privacy loss in the communication among the elements of federated learning. The prospective matching of federated learning and differential privacy to the challenges of data privacy protection has caused the release of several software tools that support their functionalities, but they lack a unified vision of these techniques, and a methodological workflow that supports their usage. In the study sponsored by the Andalusian Research Institute in Data Science and computational Intelligence, they developed a Sherpa.ai FL, 1,2 which is an open-research unified FL and DP framework that aims to foster the research and development of AI services at the edges and to preserve data privacy. The characteristics of FL and DP tested and summarized in the study suggests that they make them good candidates to support AI services at the edges and to preserve data privacy through their finding that by setting the value of I {\displaystyle \epsilon } for lower values would guarantee higher privacy at the cost of lower accuracy.
Since spam phone calls are a growing nuisance in the digital world, researchers have been looking at potential solutions in minimizing this issue. Federal agencies such as the US Federal Trade Commission (FTC) have been working with telephone carriers to design systems for blocking robocalls. Furthermore, a number of commercial and smartphone apps that promise to block spam phone calls have been created, but they come with a subtle cost. The user's privacy information that comes with giving the app the access to block spam calls may be leaked without the user's consent or knowledge of it even occurring. In the study, the researchers analyze the challenges and trade-offs related to using local differential privacy, evaluate the LDP-based system on real-world user-reported call records collected by the FTC, and show that it is possible to learn a phone blacklist using a reasonable overall privacy budget and at the same time preserve users' privacy while maintaining utility for the learned blacklist.
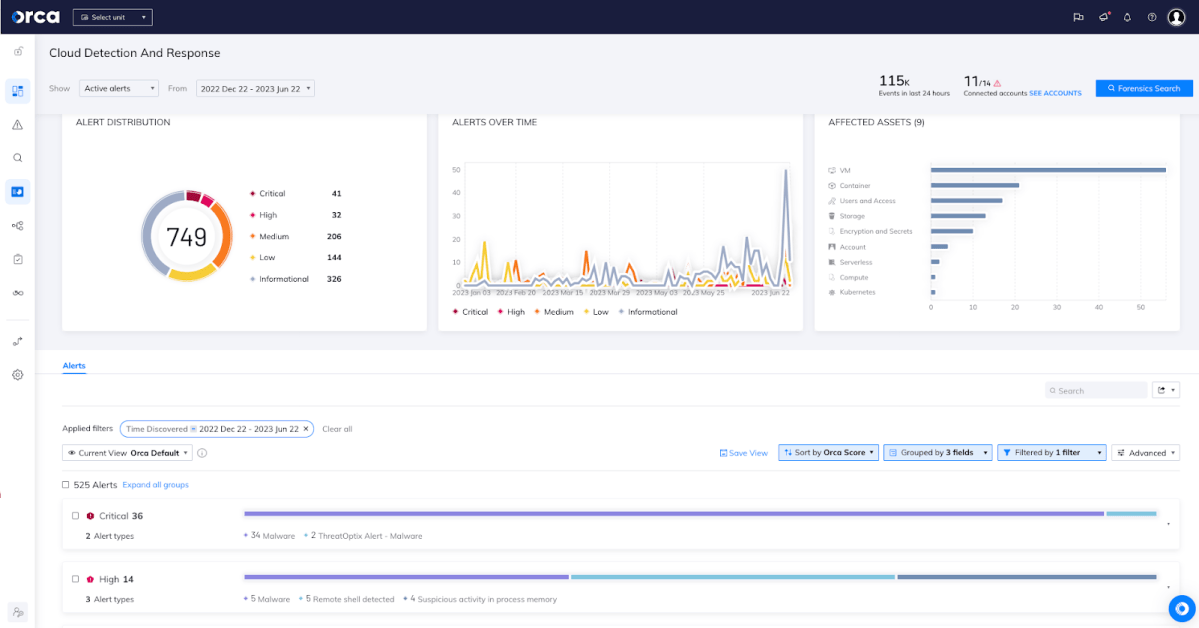
Figure 3: Cloud Anomaly Detection with AI: Supply Chain Attack Example where the probability is taken over the random measure implicit in the algorithm. The main difference between this definition of local differential privacy and the definition of standard (global) differential privacy is that in standard differential privacy the probabilities are of the outputs of an algorithm that takes all users' data and here it is on an algorithm that takes a single user's data. Other formal definitions of local differential privacy concern algorithms that categorize all users' data as input and output a collection of all responses (such as the definition in Raef Bassily, Kobbi Nissim, Uri Stemmer and Abhradeep Guha Thakurta's 2017 paper).
A cloud cost anomaly is an unexpected change in technology cost or usage that deserves investigation. It might be a runaway process, an infrastructure change, a product launch, abusive traffic, a pricing adjustment or delayed billing data. Detection is useful, but the business value comes from knowing which change matters, who can explain it and how quickly the organization can respond.
This is why anomaly detection should be treated as an operating capability rather than a feature that sends email. AWS, Microsoft Azure and Google Cloud all provide native detection and alerting, but none of them can define your ownership model, materiality policy or incident workflow for you. The objective is a reliable control loop: detect unusual movement, establish context, route it to an accountable owner, contain avoidable loss, record the cause and improve the signal.
A service can remain below budget and still generate a serious anomaly. A forgotten GPU experiment may be small relative to the company budget but material to the team that owns it. Conversely, a product launch may create a large increase that is fully expected and economically healthy. The FinOps Foundation defines anomaly management as the ability to detect, identify, clarify, alert and manage unexpected cost or usage events. That definition includes the response, not only the model that spots the change.
Native tools are a sensible starting point, especially before a company has a centralized FinOps platform. The provider experiences are not identical. Their cost basis, data latency, supported scopes and notification mechanisms differ. A multi-cloud operating model should normalize the response process while preserving those provider details. An alert policy needs to represent business impact. One universal percentage produces noise in small services and misses meaningful movement in large ones.
Add context where the data supports it. Production may have a lower tolerance than an experimental sandbox. A customer-facing AI service may need a daily unit-cost threshold. A migration account may need a temporary expected-change window while source and target run together. Create severity levels with explicit consequences. A low-severity anomaly can enter a daily review. A high-severity event may need immediate engineering acknowledgement, temporary containment and leadership notification. Avoid labeling every cost event an incident because the word loses meaning when no urgent action is expected.
Anomaly management depends on allocation. An alert that identifies only a cloud account or subscription often reaches finance, while the cause belongs to an application team. When ownership is missing, route the event to a named FinOps triage owner and create an allocation defect. Do not let an unowned alert sit in a shared mailbox.
The FinOps operating model guide explains how account structure, tags, labels and business metadata support this ownership layer. The first response should establish whether the event is real, expected and controllable. A useful runbook follows a repeatable sequence.
Confirm the time range, cost basis, currency and data freshness. Look for delayed adjustments, credits or changes in amortization before assuming infrastructure changed. Break the movement down by provider service, account, project, Region, usage type, resource and owner. Compare the period with a representative baseline, not only the previous day.
Review deployments, infrastructure changes, traffic, customer activity, data-processing schedules and known launches. Cost telemetry becomes more useful when it can be compared with operational events. Use a stable taxonomy such as expected demand, unplanned demand, deployment defect, inefficient configuration, abandoned resource, abuse, pricing change, allocation change or billing adjustment.
Automatic shutdown may be appropriate for an isolated sandbox with a clear owner. It is rarely appropriate for production based on cost alone. Production containment should account for customer impact, data safety and recovery. Record the cause, financial impact, action, owner and prevention step. Confirm the result in settled billing data. Closing an alert because a resource was changed is not the same as verifying that the cost returned to an acceptable range.
2. System Architecture & Core Working Principles Many preventable anomalies begin with change: a new log source, a retry loop, a larger database tier, a public data path or an autoscaler without a limit. Infrastructure as code and CI/CD can provide valuable context. Record deployment identifiers, service ownership and environment metadata with resources. Send significant cost alerts into the same operational channels teams already monitor. Where possible, attach recent infrastructure changes and links to the provider investigation view.
Automation should begin with enrichment and routing. Once the organization trusts the signal, it can automate low-risk responses such as pausing a development schedule, opening a ticket, applying a predefined quota or requesting approval. Destructive production actions require stronger evidence and a tested exception path. Alert count is not a success measure. Track whether the process reduces risk and improves decisions.
Review thresholds when teams repeatedly dismiss the same class of alert. Review allocation when the FinOps team cannot identify an owner. Review deployment controls when the same technical cause returns. During the first week, identify the five to ten scopes that create the most financial exposure. Document owners, expected business events and current alert coverage.
In the second week, configure native provider monitors and notifications with combined dollar and percentage thresholds. Send test events through the actual routing path. In the third week, introduce the investigation runbook and cause taxonomy. Correlate alerts with deployment, resource and ownership data. Review every event together with the responsible team.
In the fourth week, tune noisy thresholds, publish response measures and automate only the low-risk steps the process has proven. Expand coverage after the first scopes work reliably. CloudForge provides FinOps consulting and managed cloud cost governance across AWS, Azure and Google Cloud. Start with the cloud cost optimization hub when you need provider-specific recommendations, or use the cloud savings calculator to establish an initial opportunity range.
Consider a hypothetical service whose daily cost rises from $600 to $960. The increase is $360, or 60%. If completed orders also rise from 20,000 to 32,000, cost per order stays at $0.03. That is a different investigation from spending $960 to complete the original 20,000 orders, where unit cost rises to $0.048. This simple comparison is a triage step, not proof of efficiency. It assumes comparable orders, the same accounting boundary and no shift in service quality. Product mix, shared costs and fixed commitments can change the conclusion. An unchanged unit cost can still exceed an approved budget.
Download the cloud cost investigation worksheet (CSV) . It contains the two labeled example scenarios above plus a blank investigation row. Record the scope, cost basis, usage window, data freshness, owner and reason for the action. Keep the completed worksheet in your internal system. Before acting, check billing latency and account scope. AWS documents a delay of up to 24 hours for the Cost Explorer data used by Cost Anomaly Detection. Microsoft's investigation guidance and Google Cloud's anomaly documentation describe the provider-specific investigation paths. Use operational telemetry for urgent containment; reconcile the financial result after billing data settles.
For ongoing ownership and escalation, see the FinOps operating model guide . The FinOps consulting service covers implementation with your engineering and finance teams. Example added October 3, 2026. The figures illustrate a calculation and are not a customer result. Send CloudForge your requirements and the company will identify the highest-impact next step for your cost, delivery or reliability goals.
A custom workflow architecture that autonomously monitors cloud spending for unexpected spikes indicative of compromise or operational error, triggering immediate alerts and intervention to prevent runaway costs. This workflow directly protects operating margins by automating the detection of financial anomalies that signal cryptojacking, misconfigured auto-scaling, or data egress attacks. It integrates CloudWatch, Cost Explorer, and third-party billing APIs with an orchestration layer that applies business context—like department budgets and resource tagging—to filter noise. The system prioritizes alerts based on spike velocity, absolute cost, and asset criticality, ensuring security and FinOps teams focus on genuine threats, not routine variance.
Implementation requires building playbooks that execute safe, reversible actions like applying AWS Budgets actions or modifying EC2 security groups to isolate suspect instances. Governance is critical; high-cost interventions should route through a ServiceNow approval gate. The architecture must include detailed audit trails for all automated spend holds and a rollback mechanism. By connecting real-time financial telemetry to security response, this workflow turns cost monitoring from a backward-looking report into a proactive control layer.
A custom workflow for real-time cloud cost anomaly detection transforms reactive finance operations into a proactive financial security layer, preventing budget breaches by automating investigation and containment. Identifies and halts runaway spending from cryptojacking, misconfigured auto-scaling, or developer errors within minutes, not days. By integrating with CloudWatch, Cost Explorer, and budget APIs, the workflow can automatically trigger resource shutdowns or scaling actions, capping potential losses. This moves cost control from monthly reconciliation to real-time intervention.
Eliminates manual, daily log diving for FinOps and cloud engineering teams. Instead of analysts manually correlating billing alerts with resource metrics, autonomous agents perform continuous analysis, enrich anomalies with context (owner, project, resource type), and route only validated, high-severity incidents for review. This reclaims hundreds of engineering hours per quarter.
Treats anomalous spend as a primary indicator of compromise (IoC). A sudden spike in compute costs in a development account may signal cryptojacking long before traditional security tools flag it. By integrating cost anomaly signals with CSPM and SIEM systems, this workflow creates a faster, cost-based detection layer for financial attacks, reducing dwell time and lateral movement risk.
Creates an immutable, automated audit trail for all cost-related events. Every anomaly detection, investigation step, approval request, and remediation action is logged with full context, providing defensible evidence for internal audits and compliance frameworks (e.g., SOC 2, CIS). This turns a chaotic reactive process into a controlled, documented operational procedure. Shifts finance from static forecasting to dynamic modeling. By analyzing anomaly patterns and root causes over time, the system provides actionable intelligence to refine budget forecasts, identify wasteful architectural patterns, and guide engineering teams toward more cost-efficient designs. This creates a feedback loop that continuously optimizes cloud unit economics.
Builds on existing cloud-native services (AWS Cost Anomaly Detection, Azure Cost Management, GCP Recommender) rather than replacing them. The custom workflow layer adds orchestration, multi-cloud correlation, and automated action logic, maximizing ROI on native tooling. Implementation typically uses serverless functions (Lambda, Cloud Functions), message queues (SQS, Pub/Sub), and a lightweight agent framework for a scalable, maintainable system.
This blueprint details a custom multi-agent workflow that autonomously detects unexpected cloud spending spikes—indicative of compromise, misconfiguration, or error—and triggers immediate alerts, budget holds, and investigative actions to prevent runaway costs. This workflow automates the critical financial security task of identifying anomalous spending before it impacts margins. It integrates directly with AWS Cost Explorer, Azure Cost Management, and GCP Billing APIs to ingest granular cost data. A dedicated detection agent applies statistical models and machine learning to baseline normal spend, flagging deviations that exceed predefined thresholds for velocity, service, or region. The operational upside is direct: preventing six- and seven-figure overspend incidents by catching cryptojacking, unapproved resource scaling, or misconfigured data egress within minutes, not months.
Implementation requires an orchestrator, built with LangGraph or Temporal, to sequence agent actions based on anomaly severity and context. The Budget Hold Agent calls native cloud APIs to apply soft or hard spending limits. The Investigation Agent queries CloudTrail, GuardDuty, and VPC Flow Logs to correlate the spike with specific user or resource activity, enriching the alert. All actions are logged for audit, and high-severity interventions require a human-in-the-loop approval gate in ServiceNow or Jira before execution, ensuring governance over automated financial controls.
A custom workflow for real-time cost anomaly detection integrates specialized agents and enterprise systems to autonomously monitor spending, correlate financial spikes with security events, and trigger protective interventions. This core agent ingests live billing data from AWS Cost Explorer, Azure Cost Management, and GCP Billing APIs. It applies statistical models and ML to establish per-account, per-service baselines, flagging deviations (e.g., 200% spike in compute costs in 2 hours) that may indicate cryptojacking, misconfiguration, or a compromised account. It enriches raw spend data with resource metadata for context.
To distinguish between operational spikes and security incidents, this component cross-references cost anomalies with security telemetry from CloudTrail, VPC Flow Logs, and GuardDuty/Security Command Center. It uses graph logic to link a spending spike to new, unauthorized IAM roles or data egress traffic, assigning a composite risk score to prioritize the alert. 3. Software Implementation, Frameworks & Protocols Based on pre-defined playbooks and the risk score, this orchestrator executes tiered responses. For high-risk, high-confidence anomalies, it can trigger immediate API calls to apply budget holds, isolate instances via security group changes, or scale down resources. Lower-risk anomalies are routed to ticketing systems (ServiceNow, Jira) with enriched context for human review.
Critical actions (e.g., shutting down a production-tier resource) are routed through a mandatory approval gateway. This integrates with Slack, Teams, or PagerDuty to notify designated FinOps and SecOps leads, who can approve, modify, or deny the automated action via a simple interaction, ensuring human oversight is preserved for high-stakes decisions. Every detection, correlation, and action is logged with a full chain of evidence (billing queries, security logs, risk scores, approval decisions) into a centralized system like Splunk or a dedicated data lake. This creates a defensible audit trail for compliance (SOC 2, ISO 27001) and supports post-incident reviews and model retraining.
The workflow's operational viability depends on a robust integration layer. This includes authenticated connectors to cloud provider billing and security APIs, webhook integrations to ticketing and communication platforms, and adapters for ERP/Finance systems (like SAP) to map cloud spend to internal cost centers for accountability. A phased implementation strategy for deploying a custom workflow that autonomously detects and responds to anomalous cloud spending, protecting against financial loss and operational compromise.
Phase 1 establishes the detection core, integrating AWS Cost Anomaly Detection, Azure Cost Management, or GCP Recommender APIs with a central orchestrator like AWS Step Functions or Temporal. This layer ingests daily billing feeds, applies baseline models, and triggers alerts for spikes exceeding defined thresholds. The initial focus is on high-confidence, low-risk notifications to a dedicated Slack channel or PagerDuty, building trust in the signal before enabling automated action.
This phase delivers immediate visibility into runaway costs from misconfigurations or potential cryptojacking. Phase 2 introduces human-in-the-loop controls, routing high-value anomalies through ServiceNow or Jira for FinOps team approval before any remediation. Phase 3 enables autonomous action for pre-approved scenarios, such as applying budget alerts via AWS Budgets, tagging resources for investigation, or executing safe remediation playbooks to stop or scale identified resources. Each phase includes rollback procedures and detailed observability into decision logs within Datadog or CloudWatch, ensuring financial controls remain auditable and reversible.
Comparison of manual oversight versus a custom autonomous workflow for real-time cloud cost anomaly detection and alerting, highlighting financial risk reduction and operational efficiency gains. Practical questions about implementing a custom workflow that monitors cloud spending for security and financial anomalies, triggers automated interventions, and integrates with existing FinOps and security operations.
A production implementation requires a multi-stage filtering and scoring logic. Initial anomaly detection from services like AWS Cost Anomaly Detection or Azure Cost Management generates a raw signal. This is enriched with contextual metadata (resource tags, owner, business unit, recent deployment activity) and scored by a secondary agent. Low-confidence anomalies are routed to a human-review queue in Slack or ServiceNow. Only high-confidence, high-severity spikes (e.g., 500% increase in a non-production account) trigger automated holds. We design approval gates where budget blocks or resource shutdowns require a manager or FinOps lead confirmation for critical environments, preventing operational disruption.
This blueprint details a custom autonomous workflow that monitors multi-cloud spending for unexpected spikes indicative of compromise, misconfiguration, or operational error, automatically triggering alerts, budget holds, and investigative actions to prevent runaway costs. This workflow automates the detection of financial anomalies that signal security incidents or wasteful provisioning, directly protecting gross margin. It integrates Cloud Cost Management APIs (AWS Cost Explorer, Azure Cost Management, GCP Billing) with anomaly detection services (AWS Cost Anomaly Detection, Azure Cost Alerts) to identify deviations from baselines. The operational upside comes from preventing six- and seven-figure overspend events before monthly billing closes, reducing mean-time-to-detect (MTTD) for cryptojacking or data exfiltration from days to minutes, and freeing FinOps teams from manual dashboard monitoring.
Implementation requires a serverless orchestrator (AWS Step Functions, Azure Logic Apps) to sequence detection, enrichment, and action. The architecture must include approval gates via ServiceNow or Jira for high-impact actions like resource termination, and integrate with SOAR platforms for automated playbook execution. Key constraints are data freshness from billing pipelines (often 24-hour latency) and the need for business-context enrichment—tagging resources with owner, environment, and criticality—to avoid false positives and ensure safe, targeted remediation. Observability is provided through immutable audit logs in SIEM systems and real-time dashboards in Datadog or Grafana.
Prasad Kumkar is the CEO & MD of Inference Systems and writes about AI systems architecture, LLM infrastructure, model serving, evaluation, and production deployment. Over 5+ years, he has worked across computer vision models, L5 autonomous vehicle systems, and LLM research, with a focus on taking complex AI ideas into real-world engineering systems.
His work and writing cover AI systems, large language models, AI agents, multimodal systems, autonomous systems, inference optimization, RAG, evaluation, and production AI engineering. In the dynamic world of AWS, fluctuating cloud costs are often seen as a normal part of business. However, a sudden and unexpected spike in forecasted spending is rarely just a financial issue; it’s a critical security and operational signal that demands immediate attention. When consumption rates deviate sharply from historical patterns, it can indicate anything from inefficient resource provisioning to a full-blown security breach.
Treating cost data as a simple billing artifact is a missed opportunity. For mature FinOps and security teams, forecasted spending anomalies are a powerful, proactive indicator of underlying problems. A significant cost fluctuation is often the first and most obvious sign of unauthorized resource usage, such as cryptojacking via compromised credentials, or a “denial of wallet” attack designed to inflict financial damage.
By leveraging predictive cost forecasting, organizations can move from reactive, post-mortem analysis of a shocking monthly bill to proactive intervention. This approach bridges the gap between financial governance and security operations, enabling teams to detect and contain threats while they are still in their early stages, minimizing both financial and operational impact. Monitoring forecasted cost fluctuations is a cornerstone of effective FinOps governance in AWS. Ignoring these signals introduces significant business risk that extends far beyond the finance department. The most immediate impact is uncontrolled budget overruns, where a single incident can lead to bills tens or even hundreds of thousands of dollars higher than expected, threatening financial stability.
Operationally, a runaway process or attack can force a difficult choice: let costs spiral or shut down services, potentially causing downtime for legitimate, customer-facing applications. This reactive posture disrupts business continuity and damages customer trust. From a governance perspective, a breach that is only discovered through a massive bill signals a lack of control over the cloud environment. This can lead to failed compliance audits, as frameworks like SOC 2 and ISO 27001 require evidence of anomaly detection and asset management. Ultimately, failing to monitor cost anomalies erodes stakeholder confidence and suggests a reactive, immature approach to cloud management.
In this article, we expand the concept of “idle” to include any resource consumption that results in a significant and unexpected cost anomaly. This is not about low-utilization servers but rather about identifying spending patterns that deviate from established baselines. An attacker scrapes an AWS access key accidentally committed to a public code repository. The attacker immediately begins provisioning dozens of expensive, GPU-intensive EC2 instances in a rarely used region for cryptocurrency mining. Within hours, cost forecasting models detect that the EC2 spend rate will result in a monthly bill thousands of percent higher than the historical norm, triggering an alert long before a static budget threshold is crossed.
A developer deploys an AWS Lambda function designed to process files uploaded to an S3 bucket. Due to a logical error, the function’s output triggers the same function, creating an infinite recursive loop. The cost forecast for Lambda quickly identifies that the invocation count is on a trajectory to exhaust the entire month’s budget in a matter of days, allowing the operations team to disable the function and prevent a massive bill.
A development team provisions a large Amazon RDS database cluster for a short-term performance test. After the test is complete, the team moves on to other projects, forgetting to deprovision the resources. The forecasted cost for the next billing cycle shows a sustained, unexplained increase in RDS spending. This alert prompts a governance review, revealing the orphaned resources and allowing for their timely removal.
The primary risk of ignoring cost forecast anomalies is financial and reputational damage from a security breach or runaway process. However, implementing a monitoring strategy requires balancing sensitivity with practicality. Setting alert thresholds too low can lead to “alert fatigue,” where teams begin to ignore frequent notifications caused by normal business volatility. Conversely, setting thresholds too high may cause you to miss a slow-burning but still significant incident.
A key trade-off involves the speed of response versus the risk of disrupting production. When a cost anomaly is detected, the immediate impulse might be to terminate the responsible resources. However, this action must be weighed against the possibility that the spending is part of a legitimate, albeit poorly communicated, business activity. A well-defined incident response plan is critical to ensure that investigations don’t inadvertently break production workflows.
Effective governance relies on establishing proactive policies, not just reacting to alerts. Implement the following guardrails to manage and mitigate the risks associated with cost anomalies in your AWS environment. AWS provides several native tools that are essential for building a cost anomaly detection strategy. AWS Budgets is the primary service for creating alerts based on actual and forecasted costs. It allows you to set custom thresholds and receive notifications when your spending is projected to exceed them.
For investigation, AWS Cost Explorer enables you to visualize and drill down into your cost and usage data to identify the specific services, regions, or tags driving a spending spike. To correlate cost changes with specific API activity, you can analyze logs in AWS CloudTrail , which records actions taken by users, roles, and AWS services. For preventative controls across your entire organization, you can use Service Control Policies (SCPs) within AWS Organizations to enforce cost-related permissions at the account level.
Binadox Insight: Cost anomalies are the financial footprint of security incidents and operational waste. Treating your AWS billing data as a real-time security log provides a powerful, often overlooked, layer of defense that can detect threats traditional tools might miss. Shifting your perspective on AWS cost data is a critical step toward achieving mature cloud governance. By treating forecasted cost fluctuations as proactive security and operational alerts, you transform your FinOps practice from a reactive accounting function into a strategic partner in risk management.
Start by implementing foundational guardrails like budget forecasting, mandatory tagging, and clear response playbooks. This integrated approach ensures that your organization can harness the power and agility of AWS without falling victim to the significant financial and security risks of uncontrolled consumption. 4. Practical Deployment, Analysis & Case Studies Cost anomaly detection continuously monitors the daily cloud cost and informs you of abnormal usage trends. It minimizes the detection time and negative cost impacts. Cost anomaly alerts proactively notify you about anomaly events. For each detected event, cost anomaly insights help reduce the investigation and remediation efforts by providing thorough root cause analysis.
Create a custom cost monitor with a filter, where Tenancy = Business Entity and other criteria as needed. Tag Namespace = Tag Namespace name , Tag key = Application and Value = Application Name 1 Cost anomaly detection's algorithm uses machine learning considering yearly, weekly, and daily seasonality plus holiday effects to forecast daily cost data and automatically detect anomaly events. It learns from user provided feedback improving its accuracy.
Cost anomaly alerts are available for each cost monitor. If an anomaly is detected, and its cost variance exceeds the alert threshold, then an email alert is sent to the notification group. An email is sent once per day for each anomaly event. A cost anomaly alert subscription, associated with a cost monitor, defines the alert threshold and email addresses to notify. Alert thresholds, set as an absolute value and as a percentage variance between the forecasted and actual costs, define the minimum cost variation required to trigger an alert. For example, if the anomaly's cost impact is $100 and the alert threshold is $500, OCI doesn't trigger an alert. If the expected cost is $100 and the actual cost is $120, an alert threshold of 10% triggers an alert.
To use Oracle Cloud Infrastructure, an administrator must be a member of a group granted security access in a policy by a tenancy administrator. This access is required whether you're using the Console or the REST API with an SDK, CLI, or other tool. If you get a message that you don't have permission or are unauthorized, verify with the tenancy administrator what type of access you have and which compartment your access works in.
If you're new to policies, see Getting Started with Policies and Policy Builder Policy Templates . In a dynamic AWS environment, the line between financial operations and security is blurring. As infrastructure is defined by code and provisioned instantly via APIs, the speed at which an organization’s cloud spend can change has increased dramatically. While often viewed as a financial tool, unexpected cost spikes are frequently the first and most reliable indicators of a serious security compromise or a critical operational misconfiguration.
The practice of monitoring cost anomalies is therefore not just about budget management; it’s a crucial component of a modern, defense-in-depth security strategy. Ignoring a sudden surge in spending is equivalent to ignoring a critical security alert. This article explores how FinOps and engineering teams can use AWS billing data as a powerful detection system to identify threats, reduce waste, and strengthen governance across their cloud estate.
For FinOps practitioners, uninvestigated cost anomalies represent a significant business risk that extends beyond simple budget overruns. When spending deviates from established patterns, it signals a breakdown in governance that can have severe financial, operational, and security consequences. Ignoring these signals leads directly to “bill shock,” where unexpected charges amounting to thousands or even tens of thousands of dollars are only discovered at the end of the billing cycle. This financial loss is often the symptom of a deeper problem, such as unauthorized resource provisioning by attackers (cryptojacking), massive data exfiltration, or “denial of wallet” attacks designed to cripple a business financially. From an operational standpoint, delaying the investigation makes root cause analysis exponentially more difficult, wasting valuable engineering hours trying to decipher historical billing data.
While this article focuses on cost anomalies rather than purely idle resources, the underlying principle is the same: identifying non-productive spend. In this context, an “anomaly” is any significant deviation from your established AWS spending patterns that does not correlate with known business activities. A developer accidentally commits an AWS access key to a public code repository. Automated bots discover the key within minutes and use it to launch dozens of expensive, GPU-intensive EC2 instances in a foreign region to mine cryptocurrency.
Cost Anomaly Detection flags the unusual spike in a new region, triggering an alert that allows the security team to revoke the key and terminate the instances, limiting the financial damage. An engineering team configures a data replication rule for an Amazon S3 bucket but makes a mistake, creating a recursive loop where data is continuously copied back and forth. The system detects a massive anomaly in S3 API request charges and data transfer fees. The FinOps team, guided by the finding’s root cause analysis, identifies the misconfigured rule and helps the engineers correct it before it consumes a significant portion of the monthly budget.
A proof-of-concept project using a large Amazon RDS database cluster is put on hold, but the resources are never de-provisioned. While the steady cost might not trigger an anomaly, a bad actor later discovers and compromises the unpatched, forgotten database. The attacker begins exfiltrating data, causing a sudden spike in data transfer costs. This change in behavior is flagged as an anomaly, alerting the security team to the breach.
The primary risk in managing cost anomalies is finding the right balance between vigilance and alert fatigue. Setting thresholds too low can flood your team with notifications for minor, legitimate spending variations, causing them to ignore all alerts. Conversely, setting them too high means you might miss a developing security incident until the financial damage is substantial.
Another trade-off involves the speed of remediation. Teams may hesitate to terminate resources associated with a cost spike for fear of disrupting a production service (“don’t break prod”). This highlights the need for a clear, well-communicated playbook that defines ownership and empowers teams to investigate and act decisively based on the available data, such as resource tags and deployment logs.
To effectively manage cost anomalies, organizations should move beyond simple detection and implement a robust governance framework. AWS provides a native service, AWS Cost Anomaly Detection , which is part of the AWS Cost Management suite. It uses machine learning to monitor your spending patterns and identify unusual activity. You can configure monitors for all services, specific member accounts within an AWS Organization, or based on cost categories and tags. For deeper analysis, the findings can be explored within AWS Cost Explorer , which helps visualize the impact and pinpoint the root cause service, region, and usage type.
Binadox Insight: Treat your AWS cost and usage data as a critical security telemetry stream. A sudden, unexplained cost spike is often a high-fidelity indicator of a security incident that has bypassed your preventive controls, such as cryptojacking or data exfiltration. Binadox directly tackles the critical challenge of identifying unexpected cloud cost spikes as early indicators of security breaches or operational errors. Our Cost Spikes tool continuously monitors your cloud environment, detecting sudden increases in spending by comparing current usage against established thresholds and historical data. This proactive approach prevents “bill shock” and ensures that potential threats like cryptojacking or data exfiltration are flagged swiftly, allowing for a rapid response before significant financial or security damage occurs.
Beyond initial detection, deep insights are crucial for effective incident response. Cost Explorer provides granular visibility into your cloud spending, collecting and visualizing billing data through intuitive dashboards. This enables FinOps and security teams to quickly pinpoint the exact services, regions, or usage types responsible for an anomaly, significantly reducing the time spent on root cause analysis. By understanding the context of each spike, organizations can differentiate between legitimate operational changes and malicious activity, strengthening their defense-in-depth strategy.
Integrating AWS Cost Anomaly Detection into your FinOps and security practices is no longer optional—it’s essential for maintaining control over your cloud environment. By treating cost data as a vital source of intelligence, you can proactively identify security threats, eliminate financial waste, and foster a culture of accountability. The next step is to move from passive monitoring to active governance. Establish a clear operational playbook, assign ownership for anomaly investigation, and empower your teams to act swiftly. This approach transforms your cost management function from a reactive accounting exercise into a proactive defense mechanism that protects both your budget and your business.
In the world of cloud computing, financial management and security operations are no longer separate disciplines. Every action in your AWS environment, whether legitimate or malicious, generates a billable event. This convergence of cost and security creates a powerful opportunity for FinOps and engineering teams. By treating unexpected cost spikes as high-fidelity security signals, organizations can gain a critical advantage in detecting threats that might otherwise go unnoticed.
AWS Cost Anomaly Detection uses machine learning to establish a baseline of your normal spending patterns, automatically flagging significant deviations. While its primary purpose seems to be financial governance, its true value lies in its ability to act as an early warning system. An unusual surge in spending is often the first and only sign of compromised credentials, resource hijacking, or accidental resource exposure. This article explores how to leverage this capability as a core component of your cloud governance and security strategy.
For FinOps practitioners, mastering AWS cost anomaly detection goes beyond simple budget adherence. It’s about mitigating financial risk, enhancing operational visibility, and strengthening security posture. When cost anomalies are ignored, the business impact can be severe. Unchecked malicious activity, like cryptojacking, can lead to staggering bills in a matter of hours, while “forgotten” resources from shadow IT initiatives create both financial waste and unpatched security vulnerabilities.
Without a proactive anomaly detection strategy, teams are often left reacting to the monthly invoice, long after a breach has occurred or waste has accumulated. This reactive stance leads to operational drag, as engineers must divert time to forensic analysis instead of innovation. By implementing automated cost monitoring, you create a system of governance that not only protects the budget but also provides a clear audit trail of unexpected infrastructure changes, supporting compliance and risk management efforts.
In the context of this article, an “anomaly” is not just any increase in spending but a statistically significant deviation from a machine-learned historical baseline. Unlike static budgets that trigger an alert only after a fixed threshold is crossed, anomaly detection identifies unusual patterns, regardless of the absolute dollar amount. These signals are identified automatically, allowing teams to focus on the “why” behind the spend rather than manually searching for irregularities.
An attacker compromises an IAM user’s access keys that were accidentally exposed in a public code repository. They immediately begin launching hundreds of GPU-intensive EC2 instances in a rarely used region to mine cryptocurrency. The anomaly detection system flags the unprecedented surge in compute costs from this dormant region, triggering an alert to the security team and enabling a swift response to revoke the keys and terminate the idle resources.
A threat actor gains access to a poorly configured S3 bucket containing sensitive customer data. They begin transferring terabytes of data to an external location. While traditional security tools might not flag this activity as malicious, the cost anomaly monitor detects a massive, uncharacteristic spike in “Data Transfer Out” charges, alerting the FinOps team to a potential data breach in progress.
5. Performance Evaluation & Extended Technical Observations A developer provisions a large Amazon RDS database cluster for a short-term performance test and forgets to deprovision it afterward. The idle resources continue to run for weeks, accumulating significant costs. The anomaly detection system identifies that these costs are persisting well beyond the normal pattern for temporary resources, flagging them for review and preventing prolonged financial waste.
Implementing AWS Cost Anomaly Detection is a low-risk, high-reward activity, but its effectiveness depends on proper configuration and operational discipline. The primary trade-off involves alert sensitivity. Setting the alerting threshold too low may lead to “alert fatigue,” where teams begin to ignore frequent notifications for minor, legitimate spending variations. Conversely, setting it too high could cause the system to miss subtle, “low-and-slow” attacks.
The most significant risk is not in the tool itself, but in the response process. When an alert is triggered, the investigation must be handled carefully to avoid disrupting legitimate business operations. An automated response that terminates resources, for example, could inadvertently shut down a critical production workload that was scaling up to meet a real surge in customer demand. A well-defined playbook is essential to ensure that anomalies are investigated safely and effectively.
To integrate cost anomaly detection successfully, establish clear governance guardrails that blend financial oversight with security response. Start by creating a formal policy that defines ownership for investigating and resolving cost alerts. This ensures accountability and prevents alerts from being ignored. Tagging standards are fundamental. A consistent tagging strategy allows you to attribute cost anomalies to the correct team, project, or application, dramatically speeding up root cause analysis. Complement anomaly detection with AWS Budgets to set hard upper limits on spending for non-production environments. Finally, integrate alert notifications directly into your incident management tools (e.g., PagerDuty, Slack) to ensure that anomalies are treated with the same urgency as other operational incidents.
The core capability for this is AWS Cost Anomaly Detection , a feature within the AWS Cost Management suite. It automatically monitors your usage patterns to detect unusual spend. For a deeper investigation, findings can be analyzed in AWS Cost Explorer , which helps you visualize the spending data and pinpoint the root cause. To operationalize this process, configure alerts to be sent to an Amazon SNS (Simple Notification Service) topic. This allows you to route notifications to email, chat applications, or automated remediation workflows. For organizations with multiple accounts, leveraging AWS Organizations is key, as you can create monitors that track spend for individual member accounts, organizational units, or logical cost categories.
Binadox Insight: Your AWS bill is one of the most powerful and underutilized security logs you have. Malicious or wasteful activity almost always leaves a financial trace. By treating cost data as a security signal, you can uncover threats that traditional monitoring tools might miss. The article underscores the critical need for proactive detection of unexpected cloud cost surges, which often signal security threats or wasteful resource usage. Binadox Cost Spikes directly addresses this by continuously monitoring cloud spending patterns. This tool detects sudden increases in usage against defined thresholds and historical data, preventing unexpected cost overruns and acting as an essential early warning system for potential malicious activity like cryptojacking or unauthorized data exfiltration, before they lead to significant financial and security incidents.
Once an anomaly is detected, quickly identifying its source is paramount for effective investigation and remediation. Binadox Tagging enables organizations to assign meaningful labels to cloud resources, organizing infrastructure by owner, project, or department. This capability drastically improves cost allocation and governance visibility, dramatically speeding up root cause analysis when investigating anomalous spend. By providing clear context for unexpected charges, it helps transform chaotic billing data into actionable security and operational intelligence, aligning with the article’s recommended guardrails for effective anomaly response.
Moving beyond traditional budgets and embracing dynamic anomaly detection is a crucial step in maturing your FinOps practice. AWS Cost Anomaly Detection provides a powerful, automated mechanism to turn financial data into actionable security and operational intelligence. It empowers teams to proactively identify cryptojacking, data exfiltration, shadow IT, and other forms of waste before they escalate into major financial or security events.
The next step is to integrate this capability into your daily operations. Start by enabling the service, configuring meaningful alerts, and defining a clear process for investigation and remediation. By doing so, you build a more resilient, efficient, and secure cloud environment. A cost anomaly detection pipeline learns each segment's normal spending pattern and flags the days that break it, so a misconfigured resource is caught within a day rather than on next month's invoice. The build is six steps, and the hard part is keeping false alerts low enough that teams trust it.
To build a cloud cost anomaly detection pipeline, ingest normalized cost data, segment it into the smallest meaningful series, baseline normal behavior accounting for weekly seasonality, score each day against its baseline using both a percentage and a dollar threshold, route alerts with context to the owning team, then tune to control false positives. Run it on a reconciled FOCUS dataset so it fires on real spend changes, not data errors. The point is to catch runaway spend within a day instead of at the end of the month. Alert fatigue, not detection accuracy, is what kills most cost monitoring, so the threshold and routing work matters more than the model.
A cost anomaly detection pipeline is an automated process that watches cloud spend, learns what normal looks like for each part of it, and raises an alert when actual cost departs from the expected baseline by more than a set amount. Built well, it turns a four-week blind spot into a one-day feedback loop, which is the difference between a fifty-dollar surprise and a fifty-thousand-dollar one. This guide is part of our cluster pillar, the complete guide to cloud cost visibility and tooling , and it assumes the data layer described in how to normalize cost data across AWS, Azure, and GCP is already in place.
A cloud cost anomaly detection pipeline is an automated workflow that ingests cost data, models the normal spending pattern for each segment, and flags any segment whose actual spend deviates from its expected baseline beyond a defined threshold. The goal is timing: catching a runaway resource, a forgotten GPU cluster, or a misconfigured data transfer within a day rather than when the invoice arrives weeks later. It is the detection half of the govern step in our See, Cut, Lock, Run method , sitting alongside budgets and guardrails so optimized spend does not quietly drift back up.
The rule is to require both thresholds to trip before alerting, so a service must move by a meaningful percentage and by enough dollars to be worth someone's time. These numbers are starting points; tune them per environment using your own false-positive rate. AWS publishes its own managed version of this logic in AWS Cost Anomaly Detection , which is a good reference for the alerting contract even if you build your own engine.
Our FinOps implementation engagement builds the normalized data layer, stands up anomaly detection with tuned thresholds and owner routing across AWS, Azure, GCP and OCI, and wires alerts into your incident tooling. Fixed fee or performance fee. No savings, no fee. Use the native detector when you are on one cloud and want coverage immediately; build your own when you run multiple clouds or need custom segmentation and routing. AWS Cost Anomaly Detection, Azure Cost Management anomaly alerts, and Google Cloud's cost anomaly features are free, need no infrastructure, and are the fastest path to basic protection. A custom pipeline earns its cost when you want anomalies computed on one cross-cloud normalized dataset, segmentation the native tools do not offer, or alerts routed straight into your own incident system. In practice many teams run both: native detectors for quick per-cloud coverage and a custom pipeline for consistent multicloud reporting, which is also where a working FOCUS billing export ingestion pays off.
Stop alert fatigue by raising the bar to alert, suppressing the predictable, and routing to the right owner. The combined percentage-and-dollar threshold keeps trivial swings on small services quiet, while suppression rules silence known recurring events like a monthly billing true-up or a scheduled batch job. Routing each alert to the team that owns the spend, rather than a single central channel, means the people who can act actually see it. Track precision, the share of alerts that turn out to be real, and treat a falling precision number as a defect. Alert fatigue, not model accuracy, is what kills most cost monitoring efforts, so this tuning loop is the real work.
The Multicloud Visibility and FOCUS Guide includes the anomaly threshold table above, sample baseline models with seasonality, and the alert-routing template our practice uses across client environments. It is an automated process that ingests cost data, learns the normal spending pattern for each segment, and flags days or services where actual spend deviates from the expected baseline beyond a set threshold. Its job is to surface runaway spend, such as a misconfigured resource or a forgotten cluster, within a day rather than at the end of the month.
Use the native detector, such as AWS Cost Anomaly Detection, when you are on a single cloud and want results fast. Build your own when you run multiple clouds and need anomalies on one normalized dataset, custom segmentation, or routing into your own incident tooling. Many teams run both. Combine a percentage threshold with an absolute dollar threshold so trivial swings never alert, suppress known recurring spikes, route each alert to the team that owns the spend, and track precision so you can keep raising the bar. Alert fatigue, not detection accuracy, is what kills most cost monitoring.
Daily granularity per account, service, and region is the practical minimum, with hourly data preferred for fast-moving workloads. Detection at the total-account level is too coarse, because a doubling in one service is invisible inside a large stable bill. Written by Fredrik Filipsson and reviewed by Morten Andersen , applying our See, Cut, Lock, Run method . Independent and vendor neutral.
Cloud pricing and service behavior change frequently. Verify the specifics in this guide against the providers’ own current documentation and the FinOps Foundation: FinOps Foundation Framework I and FinOps Anomaly Management capability I . This article also reflects Cloud Cost Room’s hands-on, vendor-neutral engagement experience. Co-founder of Cloud Cost Room and a FinOps Certified Practitioner, with 20 years in IT and cloud cost optimization across AWS, Azure, Google Cloud and OCI. More about Fredrik → New commitment instruments, FOCUS changes, hyperscaler pricing shifts, and the plays that actually move a bill. No schedule, no filler.
Most cloud compromises generate a financial footprint before they generate a security alert. An attacker who steals AWS credentials and launches a fleet of GPU instances for crypto mining will show up on the billing dashboard within hours. The same is true for data exfiltration (egress bandwidth charges), credential abuse (API call volume charges), and unauthorised storage access (data retrieval fees from S3 Glacier or Coldline). Cost anomaly detection is a detection layer that security teams consistently under-use.
Target systems: AWS (Cost Anomaly Detection, CloudWatch, GuardDuty, Config, Lambda), GCP (Cloud Billing budget alerts, Cloud Monitoring), Azure (Cost Management + Billing, Azure Monitor), Kubernetes (resource quotas, LimitRanges, metrics-server). AWS Cost Anomaly Detection uses machine learning to establish a spending baseline and alerts when actual spend deviates from it. Configure monitors at the service level, not just total spend.
Tag-based monitors give per-team and per-service cost visibility, which is the baseline for detecting anomalies in a single service account: Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Intrusion%20detection%20system • https://en.wikipedia.org/wiki/Snowflake%20Inc.
• https://en.wikipedia.org/wiki/Local%20differential%20privacy • https://www.cloudforgeconsult.com/articles/cloud-cost-anomaly-detection-aws-azure-gcp • https://inferensys.com/automate/cloud-security-posture-management-automation/autonomous-workflow-for-real-time-cost-a nomaly-detection-and-alerting • https://www.binadox.com/blog/binadox-article-cost-fluctuation-forecast/ • https://docs.oracle.com/en-us/iaas/Content/Billing/Concepts/costanomalydetectionoverview.htm • https://www.binadox.com/blog/binadox-article-cost-anomaly-detection-findings/ • https://www.binadox.com/blog/binadox-article-cost-anomaly-detection-monitor/ • https://cloudcostroom.com/blog/how-to-build-a-cost-anomaly-detection-pipeline
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Cloud Cost Anomaly Detection Related To Security Breaches.
[*] Metasploit Scan Running on Target Subnet for Cloud Cost Anomaly Detection Related To Security Breaches... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |