Complete Technical Paper Content — Cloud Data Deduplication System With Privacy Preservation
Overview & System Context
Cloud Data Deduplication System With Privacy Preservation: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~1725 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background In information technology, a backup, or data backup is a copy of computer data taken and stored elsewhere so that it may be used to restore the original after a data loss event. The verb form, referring to the process of doing so, is "back up", whereas the noun and adjective form is "backup". Backups can be used to recover data after its loss from data deletion or corruption, or to recover data from an earlier time. Backups provide a simple form of IT disaster recovery; however not all backup systems are able to reconstitute a computer system or other complex configuration such as a computer cluster, active directory server, or database server. A backup system contains at least one copy of all data considered worth saving. The data storage requirements can be large. An information repository model may be used to provide structure to this storage. There are different types of data storage devices used for copying backups of data that is already in secondary storage onto archive files. There are also different ways these devices can be arranged to provide geographic dispersion, data security, and portability. Data is selected, extracted, and manipulated for storage. The process can include methods for dealing with live data, including open files, as well as compression, encryption, and de-duplication. Additional techniques apply to enterprise client-server backup. Backup schemes may include dry runs that validate the reliability of the data being backed up. There are limitations and human factors involved in any backup scheme.
Regardless of the repository model that is used, the data has to be copied onto an archive file data storage medium. The medium used is also referred to as the type of backup destination. Optical storage uses lasers to store and retrieve data. Recordable CDs, DVDs, and Blu-ray Discs are commonly used with personal computers and are generally cheap. The capacities and speeds of these discs have typically been lower than hard disks or tapes. Advances in optical media may shrink that gap in the future. Potential future data losses caused by gradual media degradation can be predicted by measuring the rate of correctable minor data errors, of which consecutively too many increase the risk of uncorrectable sectors. Support for error scanning varies among optical drive vendors. Many optical disc formats are WORM type, which makes them useful for archival purposes since the data cannot be changed in any way, including by user error and by malware such as ransomware. Moreover, optical discs are not vulnerable to head crashes, magnetism, imminent water ingress or power surges; and, a fault of the drive typically just halts the spinning. Optical media is modular; the storage controller is not tied to media itself like with hard drives or flash storage (→flash memory controller), allowing it to be removed and accessed through a different drive. However, recordable media may degrade earlier under long-term exposure to light. Some optical storage systems allow for cataloged data backups without human contact with the discs, allowing for longer data integrity. A French study in 2008 indicated that the lifespan of typically-sold CD-Rs was 2–10 years, but one manufacturer later estimated the longevity of its CD-Rs with a gold-sputtered layer to be as high as 100 years.
Sony's proprietary Optical Disc Archive can in 2016 reach a read rate of 250 MB/s. Open file backup: Many backup software applications undertake to back up open files in an internally consistent state. Some applications simply check whether open files are in use and try again later. Other applications exclude open files that are updated very frequently. Some low-availability interactive applications can be backed up via natural/induced pausing.
Interrelated database files backup: Some interrelated database file systems offer a means to generate a "hot backup" of the database while it is online and usable. This may include a snapshot of the data files plus a snapshotted log of changes made while the backup is running. Upon a restore, the changes in the log files are applied to bring the copy of the database up to the point in time at which the initial backup ended. Other low-availability interactive applications can be backed up via coordinated snapshots. However, genuinely-high-availability interactive applications can be only be backed up via Continuous Data Protection.
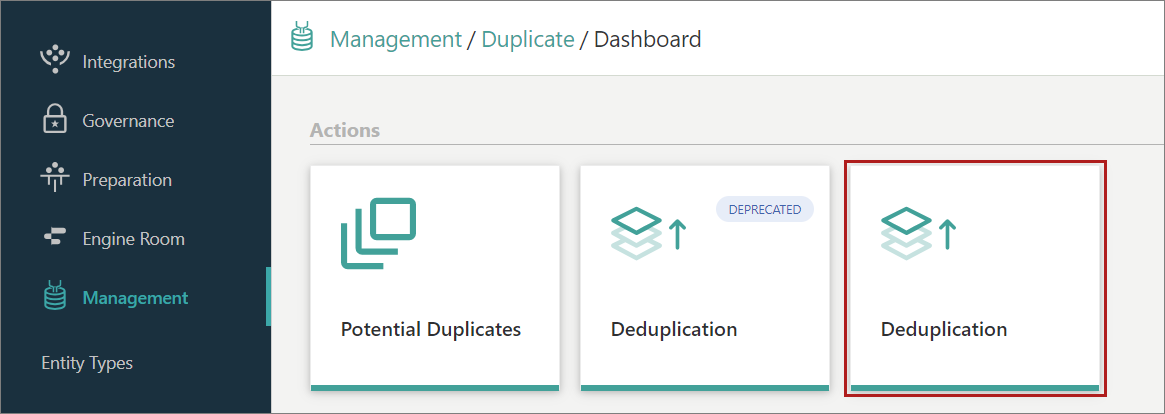
Figure 1: Deduplicate data | CluedIn Documentation System description: System specifications are needed to procure an exact replacement after a disaster. Boot sector: The boot sector can sometimes be recreated more easily than saving it. It usually is not a normal file and the system will not boot without it. Partition layout: The layout of the original disk, as well as partition tables and filesystem settings, is needed to properly recreate the original system. File metadata: Each file's permissions, owner, group, ACLs, and any other metadata need to be backed up for a restore to properly recreate the original environment. System metadata: Different operating systems have different ways of storing configuration information. Microsoft Windows keeps a registry of system information that is more difficult to restore than a typical file.
Backup software and services List of backup software Comparison of online backup services Comparison of backup software Glossary of backup terms Virtual backup appliance Related topics 2. System Architecture & Core Working Principles Data consistency Data degradation Data portability Data proliferation Database dump Digital preservation Disaster recovery and business continuity auditing World Backup Day Data localization or data residency law requires data about a nation's citizens or residents to be collected, processed, and/or stored inside the country, often before being transferred internationally. Such data is usually transferred only after meeting local privacy or data protection laws, such as giving the user notice of how the information will be used, and obtaining their consent. Data localization builds upon the concept of data sovereignty that regulates certain data types by the laws applicable to the data subjects or processors. While data sovereignty may require that records about a nation's citizens or residents follow its personal or financial data processing laws, data localization goes a step further in requiring that initial collection, processing, and storage first occur within the national boundaries. In some cases, data about a nation's citizens or residents must also be deleted from foreign systems before being removed from systems in the data subject's nation.
Azuqua is an American cloud-based integration and automation company headquartered in Seattle, Washington. As such, they integrate SaaS applications and create automations that are designed to eliminate manual work. Azuqua's platform has the ability to set up workflows between multiple applications so disparate teams can stay in the loop. Azuqua's customers include companies such as Charles Schwab, General Electric, General Motors, HubSpot, and Airbnb.
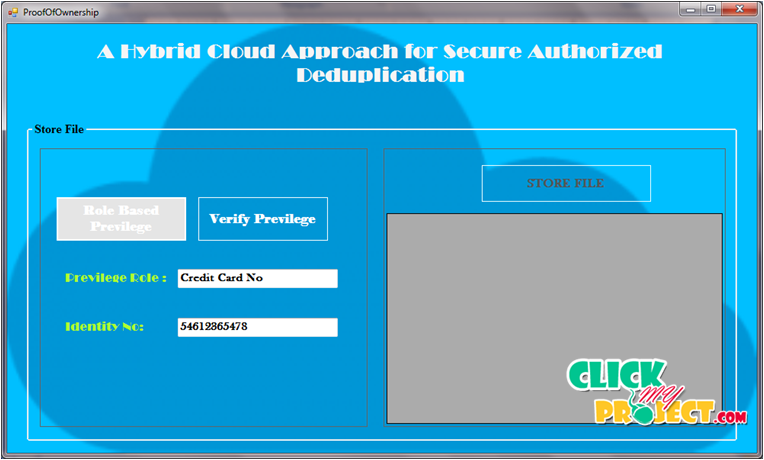
I Project Overview This project aims to optimize cloud storage by removing duplicate data, ensuring better security, efficiency, and cost-effectiveness. By implementing data deduplication combined with encryption and compression, the system guarantees seamless storage management, even in cloud environments like AWS, Azure, and Google Cloud. Figure 2: A HYBRID CLOUD APPROACH FOR SECURE AUTHORIZED DEDUPLICATION ...
Tech Stack: Java, AWT/Swing, MySQL, AWS, Google Cloud Features: Cloud Integration, Deduplication, Encryption, Compression Target Audience: Cloud service providers, system administrators, and developers I User-Friendly Interface Web-based Dashboard: Effortlessly manage your data and track deduplication status. Log Tracking: Monitor the progress and history of deduplicated files. Permissions Management: Easily control user access to different data sets.
3. Software Implementation, Frameworks & Protocols Deduplication Automation: Automatically compares files, identifies blocks for deduplication, and encrypts them with minimal human intervention. Dynamic Ownership Management: Simplifies access revocation and permission updates in the background.
Ensures only authorized users can upload or access data, backed by integration with systems like LDAP or OAuth for secure access. Uses convergent encryption, ensuring data deduplication works even on encrypted files. Only unique blocks are encrypted, optimizing both security and performance.
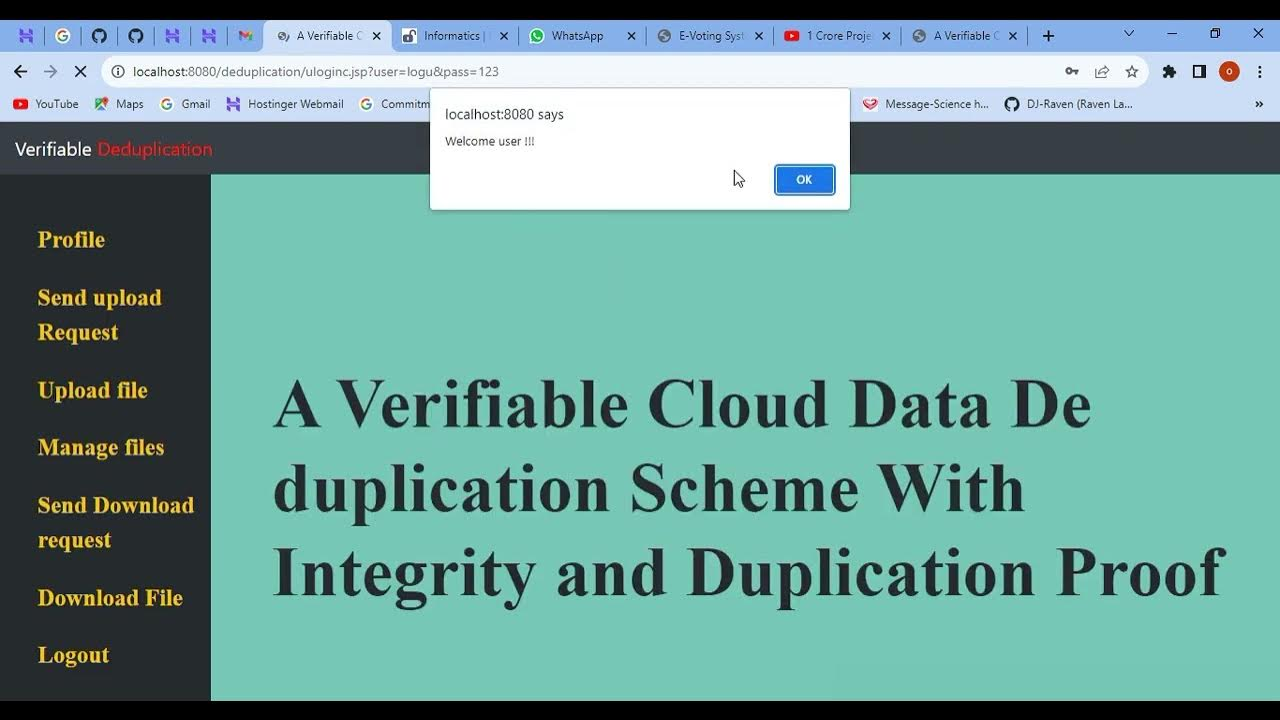
Supports large data uploads without sacrificing performance. Automatically adjusts storage capacity with hybrid cloud architecture, ensuring scalability as storage needs grow. Figure 3: A Verifiable Cloud Data Deduplication Scheme With Integrity and ... Accessible via web, mobile, or desktop platforms. Integrates with AWS, Azure, or Google Cloud for seamless cloud storage management. II Low Maintenance & Self-Monitoring Includes self-monitoring capabilities for automatic alerts about potential issues, reducing the need for manual intervention.
Built-in encryption, collusion resistance, and secure hashing ensure data safety and integrity. 4. Practical Deployment, Analysis & Case Studies Faster uploads with block-level deduplication and pre-upload checks. Bandwidth savings due to storing only unique data blocks.
Operating System: Windows (Recommended) Programming Language: Java (JDK 8 or higher) Frameworks: Java AWT/Swing for front-end, Java-based libraries for encryption and compression Database: MySQL 5.0 Server (For data management) NetBeans IDE 8.0: Integrated Development Environment (IDE) for Java. HeidiSQL: Database management tool for MySQL.
II Getting Started Prerequisites Make sure to install the following software: Java (JDK 8 or higher) NetBeans IDE (Version 8.0) MySQL (Version 5.0) Installation Clone the repository: bash Copy code git clone
Monitor the deduplication process: Track savings and progress. View logs: Check detailed logs for deduplication and access changes. Manage data access: Admins can easily control user permissions. Fork the repository. Create a new branch (git checkout -b feature/feature-name). Commit your changes (git commit -m 'Add new feature'). Push to the branch (git push origin feature/feature-name). Open a Pull Request.
5. Performance Evaluation & Extended Technical Observations Access to this page requires authorization. You can try signing in or changing directories . Windows Server data deduplication is a widely used feature for optimizing disk space by removing redundant data blocks and storing only unique information. Although deduplication offers significant storage savings, it also introduces complexity that can cause a variety of failure modes, such as job failures, space reclamation issues, file access problems, high chunkstore usage, and errors in migration scenarios.
This article provides a methodical approach to diagnosing and resolving common data deduplication problems in Windows Server 2022, 2019, and 2016 across NTFS and ReFS file systems. The following sections detail the most common failure modes and provide step-by-step solutions. Investigate file patterns: Use TreeSize or a similar value to find space hogs not visible in user data.
Before you contact Microsoft Support, you can gather the following information about your issue. Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Backup • https://en.wikipedia.org/wiki/Data%20localization • https://en.wikipedia.org/wiki/Azuqua • https://github.com/Nagashree2003/Data-Deduplication-Strategies-for-secure-and-efficient-cloud-storage/blob/master/READ ME.md • https://learn.microsoft.com/en-us/troubleshoot/windows-server/backup-and-storage/troubleshootwindows-server-data-dedup lication
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Cloud Data Deduplication System With Privacy Preservation.
[*] Metasploit Scan Running on Target Subnet for Cloud Data Deduplication System With Privacy Preservation... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |