Complete Technical Paper Content — Dark Web Crawling And Threat Intelligence Extraction Python
Overview & System Context
Dark Web Crawling And Threat Intelligence Extraction Python: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~8027 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Darkweb_Crawler is an advanced Python-based OSINT (Open-Source Intelligence) tool designed for ethical security research and threat intelligence gathering on the dark web. This tool enables security professionals to safely crawl .onion sites through the Tor network while analyzing content for potential threats and marketplace activities.
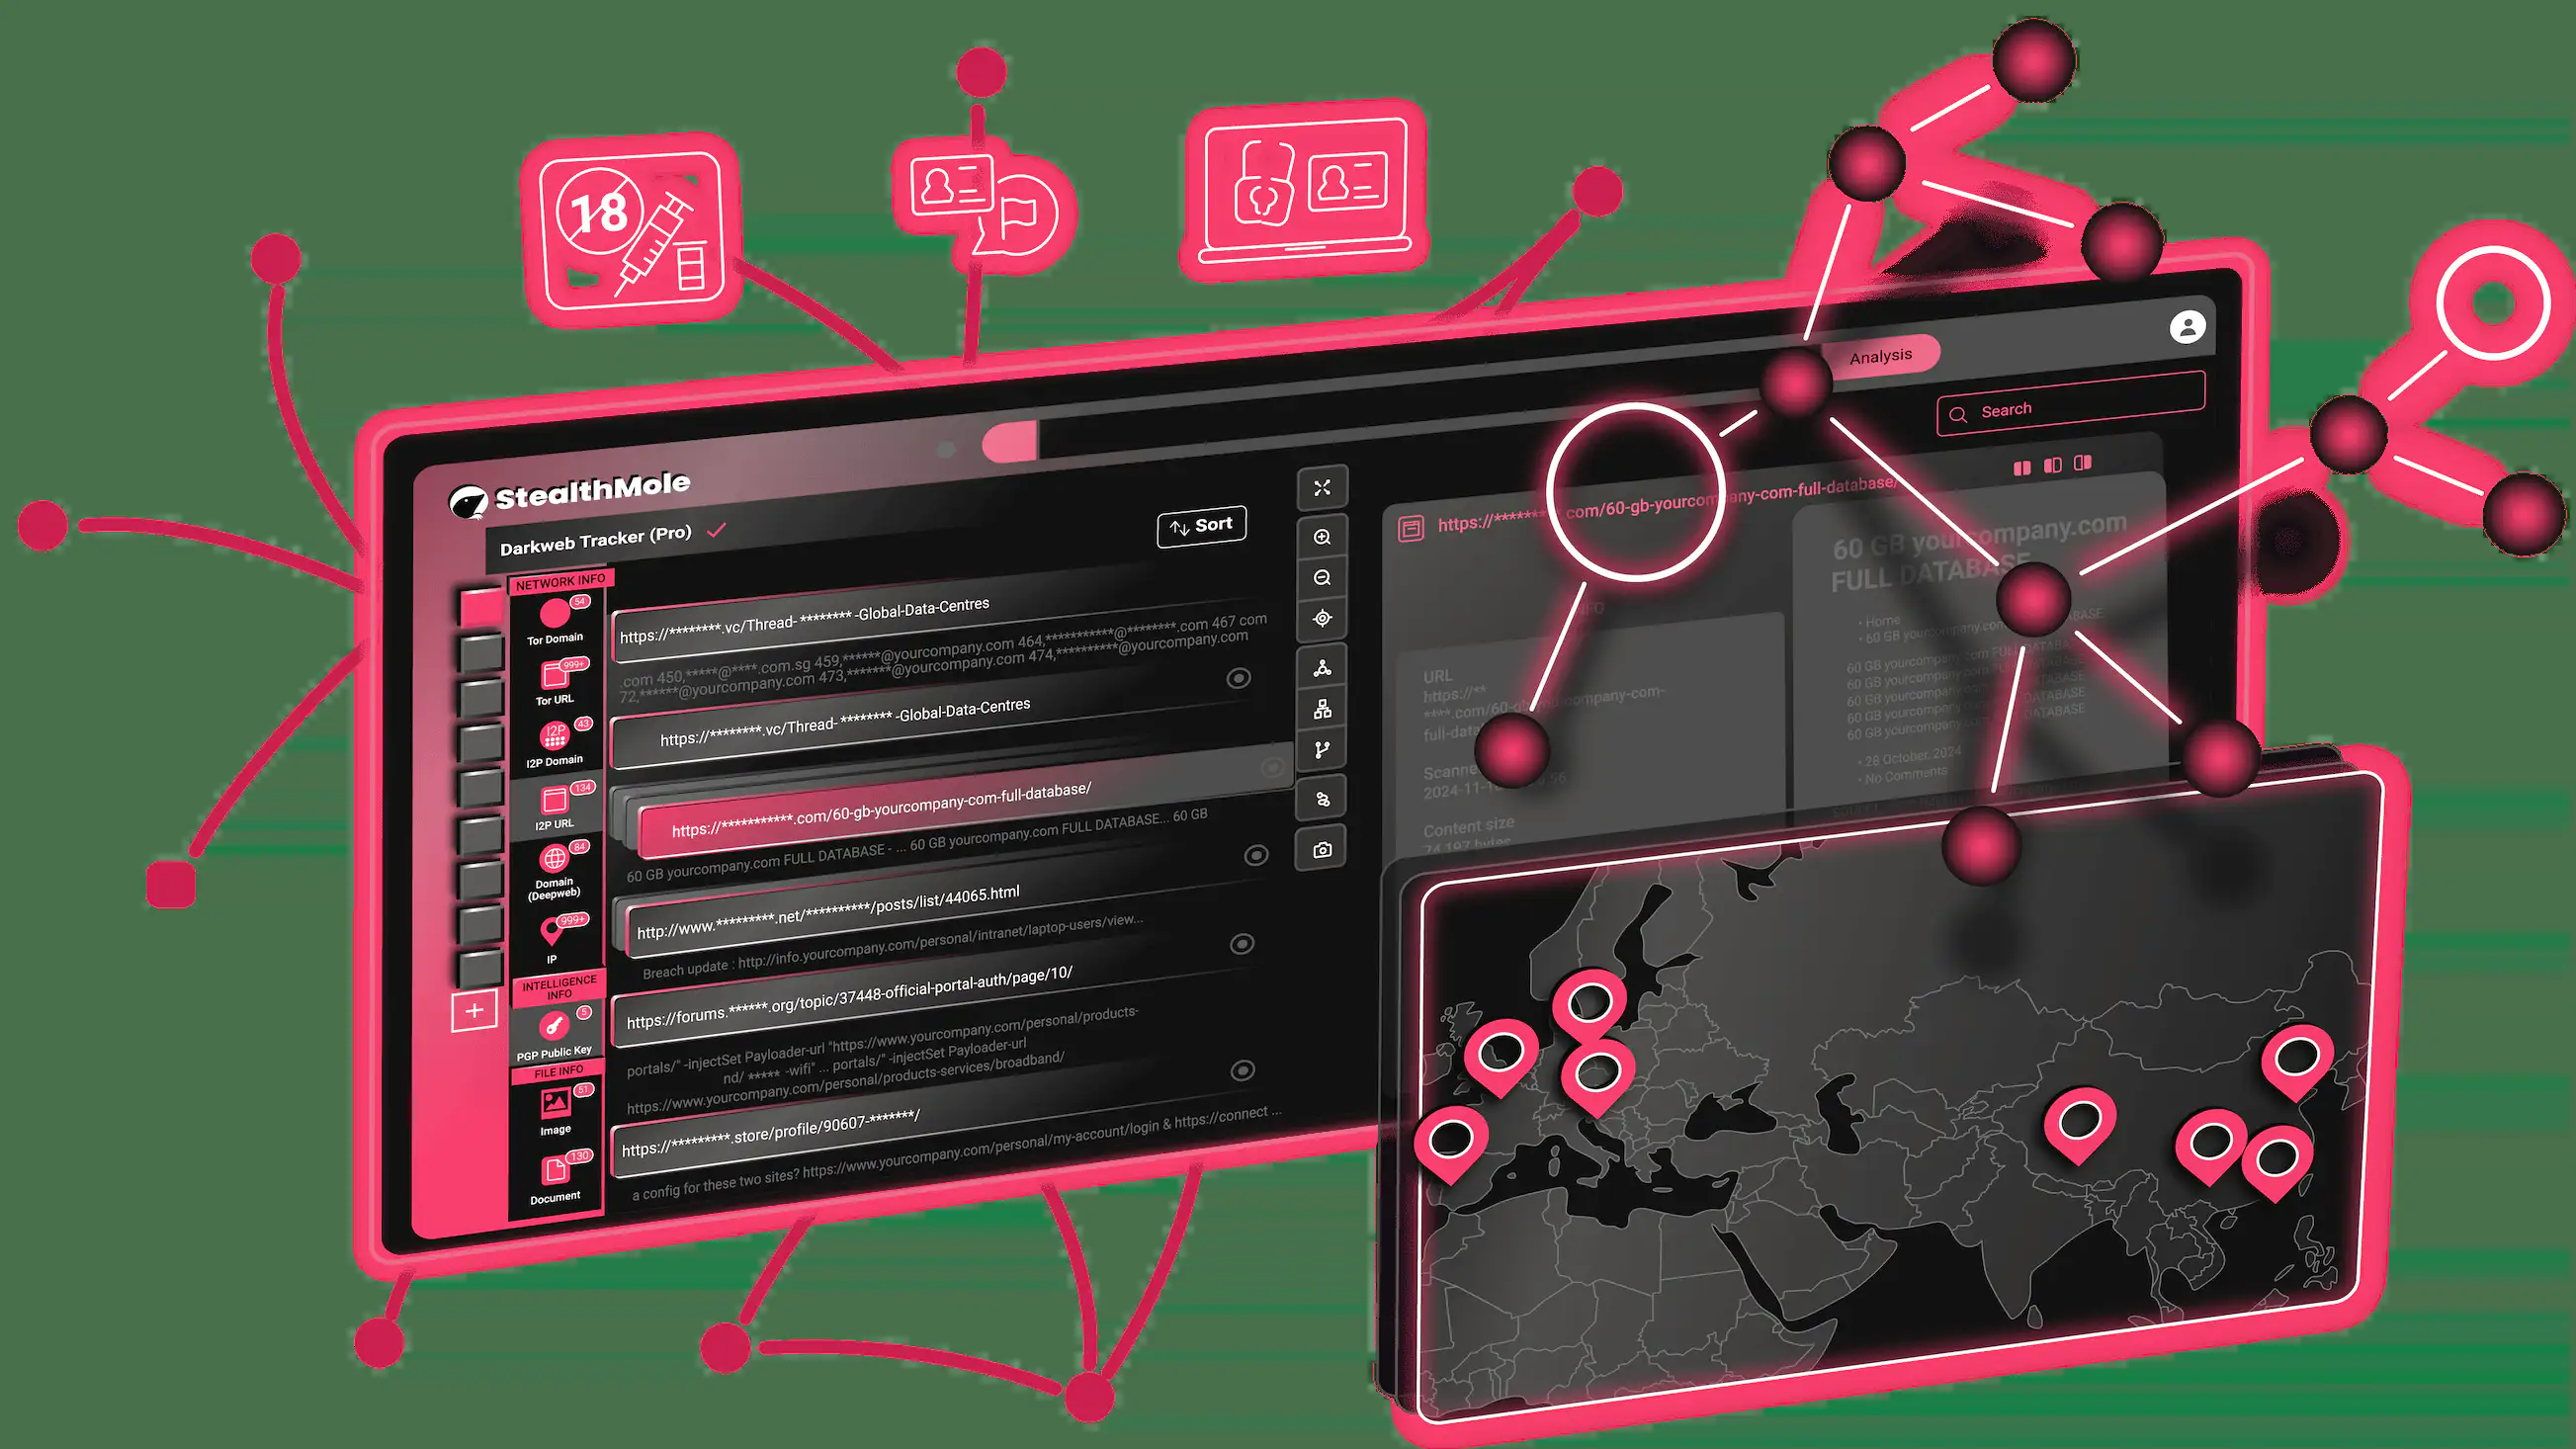
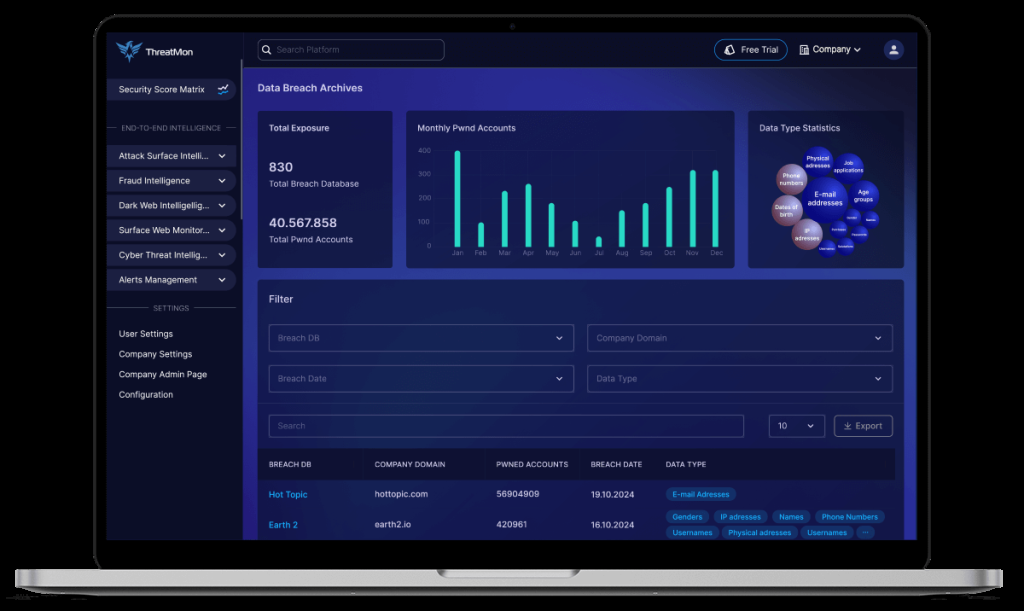
Anonymized Crawling : Routes all traffic through Tor network with regular circuit renewal Threat Intelligence : Identifies emerging threats, malware, and attack services being advertised on dark web markets Brand Protection : Discovers stolen data, credentials, or intellectual property related to your organization Figure 1: Threat Intelligence | Prima Cyber Solusi Incident Respons e: Supports investigations by gathering intelligence about threat actors Compliance Monitoring : Helps organizations meet regulatory requirements for monitoring dark web threats onion_start_urls = [ " http://duckduckgogg42xjoc72x3sjasowoarfbgcmvfimaftt6twagswzczad.onion ", # DuckDuckGo " http://www.nytimes3xbfgragh.onion ", # New York Times " http://facebookwkhpilnemxj7asaniu7vnjjbiltxjqhye3mhbshg7kx5tfyd.onion ", # Facebook ] onion_start_urls = [ " http://examplemarketplace76x7g5j.onion ", # Example marketplace " http://researchforum5tg6c2.onion ", # Example research forum " http://securityblog32vbr3.onion ", # Example security blog ] Figure 2: Dark Web Threat Intelligence - StealthMole { "url": " http://examplemarketplace76x7g5j.onion/products ", "title": "Marketplace Products | Example Marketplace", "text": "Welcome to our marketplace. We offer various digital products... Bitcoin: 1A1zP1eP5QGefi2DMPTfTL5SLmv7DivfNa...
Credit cards available for purchase...", "threats": { "high": ["credit card fraud", "stolen data"], "medium": ["drugs for sale", "fake documents"], "low": ["premium accounts", "bypass security"] }, "marketplace_goods": { "digital_goods": { "credit cards": 5, "accounts": 3 }, "fraud": { "fake documents": 2 }, "drugs": { "weed": 0 }, "weapons": { "firearm": 0 }, "services": { "hacking": 1 } } } URL Title Content Threats Marketplace Goods http://examplemarketplace76x7g5j.onion/products Marketplace Products Welcome to our marketplace. We offer various digital products... Bitcoin: 1A1zP1eP5QGefi2DMPTfTL5SLmv7DivfNa... Credit cards available for purchase... {'high': ['credit card fraud', 'stolen data'], 'medium': ['drugs for sale', 'fake documents'], 'low': ['premium accounts', 'bypass security']} digital_goods: credit cards(5), accounts(3); fraud: fake documents(2); services: hacking(1) http://researchforum5tg6c2.onion/discussion Security Discussions Latest cybersecurity threats and research discussions... Ransomware detection techniques... {'high': [], 'medium': ['ransomware'], 'low': ['hacking tutorial']} services: hacking(2) IIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIII I DARKWEB THREAT INTELLIGENCE REPORT I I I I Generated on: 2024-01-15 14:30:22 I I I I Tool: DarkCrawler Elite v2.2 I I Scan Duration: 2 hours, 15 minutes I I Pages Crawled: 47 I I Threats Detected: 18 I IIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIIII Total threats detected: 18 High severity threats: 5 Medium severity threats: 8 Low severity threats: 5 Figure 3: Dark Web Intelligence - ThreatMon MARKETPLACE GOODS OVERVIEW Total marketplace goods detected: 42 Digital goods: 18 items detected Fraud: 12 items detected Services: 8 items detected Drugs: 3 items detected Weapons: 1 item detected CONTENT EXCERPT : Welcome to our marketplace.
We offer various digital products...
Bitcoin: 1A1zP1eP5QGefi2DMPTfTL5SLmv7DivfNa... Credit cards available for purchase... Database leaks... Premium accounts... THREAT DISTRIBUTION : High Severity: 28% (5/18) Medium Severity: 44% (8/18) Low Severity: 28% (5/18) MARKETPLACE CATEGORY DISTRIBUTION : Digital Goods: 43% (18/42) Fraud: 29% (12/42) Services: 19% (8/42) Drugs: 7% (3/42) Weapons: 2% (1/42) CRYPTO CURRENCY FINDINGS : Bitcoin addresses detected: 3 Payment requests identified: 5 CONTACT INFORMATION : Security Team: security@yourcompany.com Incident Response: ir@yourcompany.com Legal Department: legal@yourcompany.com Law Enforcement Liaison: le@yourcompany.com Scenario: A financial institution suspects customer data has been compromised and is being sold on dark web marketplaces .
onion_start_urls = [ " http://knownmarketplace76x7g5j.onion/credit-cards ", " http://knownmarketplace76x7g5j.onion/data-dumps ", " http://knownmarketplace76x7g5j.onion/bank-accounts " ] Add company-specific keywords to watch for DANGEROUS_KEYWORDS['high'].extend([ 'yourbankname', 'yourbank customers', 'yourbank database' ]) The PDF report becomes crucial evidence for incident response, regulatory compliance reporting, and law enforcement engagement.
ControlPort 9051 HashedControlPassword 16:872860B76453A77D60CA2BB8C1A7042072093276A3D701AD684053EC4C This tool is designed for ethical security research and authorized penetration testing only. Unauthorized Use : Do not use this tool against sites you don't own or have permission to test I am not responsible for misuse of this tool. Users assume all legal responsibility for their actions.
Edit the onion_start_urls list in the main function with actual .onion addresses - Or refer to the V2:0 above for clarification. For additional support, do well to reach out via my email address: preciousvincentct@gmail.com 68 74 74 70 3a 2f 2f 77 62 7a 32 6c 72 78 68 77 34 64 64 37 68 35 74 32 77 6e 6f 63 7a 6d 63 7a 35 73 6e 6a 70 79 6d 34 70 72 37 64 7a 6a 6d 61 68 34 76 69 36 79 79 77 6e 33 37 62 64 79 64 2e 6f 6e 69 6f 6e 2f 0a 0a 68 74 74 70 3a 2f 2f 69 77 67 67 70 79 78 6e 36 71 76 33 62 32 74 77 70 77 74 79 68 69 32 73 66 76 67 6e 62 79 32 61 6c 62 62 63 6f 74 63 79 73 64 35 66 37 6f 62 72 6c 77 62 64 62 6b 79 64 2e 6f 6e 69 6f 6e 2f 0a 0a 68 74 74 70 3a 2f 2f 73 67 61 35 6e 37 7a 78 36 71 6a 74 79 37 75 77 76 6b 78 70 77 73 74 79 6f 68 37 33 73 68 73 74 36 6d 78 33 6f 6b 6f 75 76 35 33 75 6b 73 37 6b 73 34 37 6d 73 61 79 64 2e 6f 6e 69 6f 6e 2f 0a Darkweb_Crawler - an advanced version of DEEPWEBHARVESTER is a Python-based OSINT (Open-Source Intelligence) tool designed for ethical security research and threat intelligence gathering on the dark web.
Dark_Crawler - is an advanced, stealthy Python-based dark web intelligence platform designed for authorized security professionals and ethical researchers. The tool provides comprehensive dark web crawling capabilities with integrated threat detection, marketplace analysis, and professional reporting features. Built with privacy and security in mind, Dark_Crawler routes all traffic through the Tor network while maintaining operational security standards suitable for sensitive intelligence gathering operations.
Modify the DANGEROUS_KEYWORDS dictionary in the script to add custom threat indicators: DANGEROUS_KEYWORDS = { 'high': [ 'your_custom_threat', 'organization_specific_indicators', # Add more high-severity keywords ], 'medium': [ # Medium severity indicators ], 'low': [ # Low severity indicators ] } MARKETPLACE_CATEGORIES = { 'custom_category': [ 'keyword1', 'keyword2', # Add category-specific keywords ] } { "url": " http://target.onion/page ", "title": "Page Title", "text": "Extracted content...", "threats": { "high": ["keyword1"], "medium": ["keyword2"], "low": [] }, "marketplace_goods": { "drugs": {"cocaine": 3}, "weapons": {"firearm": 1} } } 2. System Architecture & Core Working Principles This tool is provided for educational purposes and authorized security research only. The developers assume NO LIABILITY for misuse of this software. Users are SOLELY RESPONSIBLE for: Edit the onion_start_urls list in the main function with actual .onion addresses - Or refer to the V2:0 above for clarification.
For additional support, do well to reach out via my email address: preciousvincentct@gmail.com 68 74 74 70 3a 2f 2f 77 62 7a 32 6c 72 78 68 77 34 64 64 37 68 35 74 32 77 6e 6f 63 7a 6d 63 7a 35 73 6e 6a 70 79 6d 34 70 72 37 64 7a 6a 6d 61 68 34 76 69 36 79 79 77 6e 33 37 62 64 79 64 2e 6f 6e 69 6f 6e 2f 0a 0a 68 74 74 70 3a 2f 2f 69 77 67 67 70 79 78 6e 36 71 76 33 62 32 74 77 70 77 74 79 68 69 32 73 66 76 67 6e 62 79 32 61 6c 62 62 63 6f 74 63 79 73 64 35 66 37 6f 62 72 6c 77 62 64 62 6b 79 64 2e 6f 6e 69 6f 6e 2f 0a 0a 68 74 74 70 3a 2f 2f 73 67 61 35 6e 37 7a 78 36 71 6a 74 79 37 75 77 76 6b 78 70 77 73 74 79 6f 68 37 33 73 68 73 74 36 6d 78 33 6f 6b 6f 75 76 35 33 75 6b 73 37 6b 73 34 37 6d 73 61 79 64 2e 6f 6e 69 6f 6e 2f 0a Darkweb_Crawler - is an advanced, stealthy Python-based dark web intelligence platform designed for authorized security professionals and ethical researchers.
Dark web crawling is a complex process that involves specific methodologies and techniques to navigate the Tor network and extract data from hidden services. This study proposes a general dark web crawler designed to extract pages handling security protocols, such as captchas, efficiently. Our approach uses a combination of seed URL lists, link analysis, and scanning to discover new content. We also incorporate methods for user-agent rotation and proxy usage to maintain anonymity and avoid detection. We evaluate the effectiveness of our crawler using metrics such as coverage, performance and robustness. Our results demonstrate that our crawler effectively extracts pages handling security protocols while maintaining anonymity and avoiding detection. Our proposed dark web crawler can be used for various applications, including threat intelligence, cybersecurity, and online investigations.
The dark web is a part of the internet not indexed by search engines and requires special software, such as the Tor browser, to access [ 1 ] . It is often used for illegal activities, such as selling drugs, weapons, and stolen information. This part of the web is often associated with illicit activities and is known to host various criminal markets, including illegal drug trading, weapons sales, and stolen data [ 2 ] .
Dark web crawling, the act of systematically accessing and collecting data from the dark web, is a complex and challenging task. Unlike the surface web, the dark web lacks structure, making it difficult to discover and navigate its content. Additionally, the anonymity the dark web provides makes it challenging to verify the credibility and authenticity of the information collected. One common objective of a dark web crawler is to gather information. Because the dark web is largely unregulated and anonymous, it can be a source of valuable data that is not easily accessible through other means. For example, a dark web crawler might be used to search for and collect information such as stolen user credentials, sensitive documents, or other confidential information that has been posted or traded on dark web marketplaces. Moreover, due to the illegal activities on the dark web, we can collect information to monitor illicit behaviors by looking for trends on specific drugs, armies, or criminal schemes. Law enforcement agencies may use dark web crawlers to monitor and gather intelligence on criminal activity such as drug trafficking, human trafficking, and other forms of illicit behavior that take place on the dark web. By collecting data on these activities, law enforcement officials can anticipate and mitigate illicit phenomena or identify and seize the criminal gangs. Cybersecurity professionals and companies may also use dark web crawlers to investigate and anticipate potential cyber threats. For example, a dark web crawler could be used to track the activities of hacking groups, monitor the spread of malware or ransomware, or detect data breaches posted on the dark web. This information can then be used to strengthen cybersecurity defenses and protect against future attacks. An additional application entails examining the user behavior on the dark web or analyzing the materials accessible on it, which can furnish valuable understandings into the subterranean market and the methodologies utilized for illicit activities on the internet.
The implementation of a dark web crawler includes several challenges. The dark web is designed to provide anonymity to users, making it challenging to track and identify the source of information. A dark web crawler must be able to navigate this anonymity and still collect relevant data. Moreover, differently from the surface web, the dark web is unstructured and lacks organization, making it challenging to discover and retrieve specific data.
To evaluate the performance and effectiveness of our crawler, we conducted an experimentation in which we compared its performance against ACHE [ 3 ] , a widely used dark web crawler. The comparison was based on various metrics used to evaluate the crawlers’ capabilities. The results clearly indicate that our crawler outperformed ACHE in all the evaluated metrics.
The structure of the paper is organized as follows. In Section 2, we discuss the related works on dark web analysis and dark web crawlers, providing insights into the existing research and its limitations. Section 3 presents the architecture of our crawler in detail, discussing each layer and its functionalities. The evaluation process is described in Section 4, including the metrics used, the dataset employed, and the intended experimentation. Section 5 presents the results of our work, highlighting the performance and effectiveness of our crawler compared to other approaches. In Section 6, we conclude the paper by summarizing the findings, discussing their implications, and outlining potential avenues for future research.
Dark web crawlers are specialized software tools designed to index and collect information from hidden websites and services not accessible through conventional search engines. As the demand for more comprehensive and reliable intelligence on the dark web has increased, several researchers have attempted to develop effective dark web crawlers. In this section, we discuss some of the previous work done in the field of dark web crawling, with a particular focus on the findings of a systematic literature review made by Bergman et al. [ 4 ] .
Bergman et al. conducted a systematic literature review to identify existing dark web crawlers and evaluate their effectiveness. During the review, they identified 34 potential dark web crawlers but found that only four of them had publicly available code repositories. The authors conclude the study by highlighting the absence of open-source crawlers, and that few researchers mention which open-source crawler was used in their study. Moreover, the experiments showed that the Tor crawler managed to scrape 251 pages in 20 minutes and eight minutes to scrape The Guardian’s clear website of 223 pages with an average of circa 6.4 pages.
Narayanan et al. presents TorBot [ 5 ] , an open-source intelligence tool for the dark web that enables users to gather and analyze information from hidden websites and services. TorBot is a Python-based tool that uses the Tor network to crawl the dark web and collect information such as website content, metadata, and links. It has several features, such as keyword-based searching, content analysis, and automated data extraction. The paper discusses the design and implementation of TorBot, including its architecture and components, and provides a detailed evaluation of its performance and capabilities.
Barbosa et al. introduce ACHE [ 3 ] , an adaptive crawler designed to identify entry points to hidden web resources. The hidden web refers to resources that are not accessible through conventional search engines and require specific queries to access. The proposed crawler adapts to the structure of the hidden web by leveraging machine learning techniques to identify entry points and improve its crawling efficiency automatically. The algorithm uses a combination of content-based and link-based analysis to identify hidden web entry points. It continuously updates its search strategy based on the results of previous crawls. The paper describes the design and implementation of the adaptive crawler and evaluates its performance in locating hidden web entry points.
Kalpakis et al. [ 6 ] explores an interactive search engine for Home Made Explosives recipes on the Surface and Dark Web. The hybrid architecture combines a dedicated crawler and domain-specific queries, adapting the widely used web crawler, Apache Nutch [ 7 ] , to operate on the dark web. Celestini et al. [ 8 ] address the need for effective web search and retrieval. It presents a flexible toolkit for structure and content mining on the Web, including the Tor dark Web. The toolkit incorporates web crawling, extraction, indexing, and mining modules. They have customized the well-established web crawler, bUbiNG [ 9 ] , to effectively operate on the dark web. Their adaptation enables the crawler to navigate and retrieve information from the hidden layers of the internet.
In conclusion, we encountered limitations with the availability and suitability of certain crawlers. The TorBot crawler was excluded from our analysis due to outdated external dependencies that rendered it unusable. Additionally, the custom crawlers developed by Kalpakis and Celestini based on Apache Nutch and bUbiNG, respectively, were not publicly released, making their replication challenging. Furthermore, both the crawlers Nutch and bUbiNG were not specifically designed to work with the dark web. Therefore, for our experimentation, we used ACHE (GitHub here [ 10 ] ) as a comparison tool due to the fact that, at the moment is the only available and replicable tool suitable for dark web crawling.
A dark web crawler architecture typically consists of several components that work together to discover hidden web content. Figure 1 shows our dark web crawler architecture, giving an overview of the entire crawling process, from the starting link until the content page storage process. The following is a general description of the key components of the architecture. Firstly, the crawler receives a list of potential links, namely starting links , which it can obtain from public dark web directories or from the user directly. Next, the crawler performs a validity check to ensure that one of these links is accessible. If a valid link is found, it becomes the starting point of the crawling process.
There are various strategies for web crawling, and choosing the right strategy is crucial for the success of a crawler. We decided to adopt a breadth-first crawling strategy because, as proven by Cho et al. [ 11 ] , it provides more high-quality pages than other approaches. They use several metrics to define the concept of ”quality” of a page, like the number of links that appears during the crawling process or pageRank, a metric used to measure the importance or popularity of web pages based on their incoming links. In this strategy, the crawler starts with a specific link and then visits all the links on that page before moving to the next page.
URL reachability check is an important process that ensures that the crawler can access and retrieve the content of a web page before attempting to extract information from it. This check is necessary because not all URLs that are identified for crawling are necessarily valid or accessible. URLs can become broken due to various reasons such as server errors, domain expiration, or page deletion, making them unreachable and causing errors in the crawling process [ 12 ] .
URL reachability check involves sending a request to the URL or onion link using the HTTP or HTTPS protocol, and checking the response status code returned by the server. A response status code of 200 indicates that the URL is reachable and the server has successfully returned the content of the page. On the other hand, a status code of 404 indicates that the page is not found, while a status code of 503 indicates that the server is temporarily unavailable.
If the crawler determines that a URL is not reachable, it marks the URL as broken or invalid, and remove it from the crawling queue. This helps to prevent unnecessary requests to unreachable URLs, which can slow down the crawling process and waste system resources. In addition, the crawler may also check if the URL is a duplicate or a mirror of another page, and avoid crawling such pages to prevent duplication of content.
In many cases, web crawlers need to log in to a website to access restricted content. Automating the login process can save time and effort, especially when crawling multiple websites. To perform an automatic login, a web crawler needs to submit login credentials to the login page of the website. This can be done using HTTP POST requests with the appropriate form data, such as the username and password. The response from the server indicates whether the login was successful or not.
It’s worth noting that some websites may have additional security measures in place, such as CAPTCHAs or two-factor authentication. These can make the automatic login process more challenging and may require additional coding or human intervention. Captcha detection is an important aspect of web crawling, as many websites use captchas to prevent automated bots from accessing their content. Captchas are usually presented as a challenge-response test, where the user is asked to perform a task that is easy for humans but difficult for machines, such as identifying distorted text, selecting images that match a certain criteria, or solving a mathematical problem.
Detecting captchas in a web crawler can be challenging, as captchas can appear in different forms and locations on the page, and can be triggered by various factors, such as the number of requests, the frequency of requests, or the IP address of the crawler. To detect captchas, web crawlers need to analyze the page structure and content, and look for patterns that indicate the presence of a captcha.
In contrast, the dark web operates on a different protocol called Onion Routing [ 13 ] , which uses several layers of encryption to anonymize communication between clients and servers. To make connection requests on the dark web, the crawler must be configured to use the Tor network, which provides a layer of encryption and routing that obscures the origin and destination of requests, and a proxy server. A proxy server acts as an intermediary between the client and the server, forwarding requests and responses and providing an additional layer of anonymity. The proxy server can be either a public or a private one.
A further technique useful to help avoid being detected and blocked by servers is the user agent rotation. A user agent is a string that identifies the type of browser and operating system being used to make the request. By rotating the user agent, a crawler can simulate human-like behavior and avoid being detected as an automated bot. One of the main differences between surface web and dark web requests is the domain resolution process. On the surface web, domain names are translated into IP addresses using a centralized DNS resolution system. However, the dark web uses a decentralized naming system called Tor Hidden Services, which allows websites to have .onion domain names that are not registered with standard DNS servers. Python scripts that are designed to make connection requests on the dark web must be configured to use Tor Hidden Services to resolve domain names and connect to the appropriate servers.
A crawler uses exit conditions to determine when the crawling process should stop. There are several exit conditions that can be used depending on the goals of the crawler and the resources available. Our algorithm employs the following stop criteria: Max depth : the crawler stops if it reaches a certain level of depth. This criteria is useful when you want to limit the amount of resources used during the crawling process.
3. Software Implementation, Frameworks & Protocols Max number of link downloaded : one common exit condition is to stop crawling after a certain number of links have been visited. This approach is useful when you want to limit the amount of data collected or when you are crawling a large website and want to ensure that the process does not continue indefinitely.
Time limit : it is important to stop crawling after a certain amount of time has passed. Considering the dynamic nature of the dark web, where lots of website are frequently updated, having a stop criteria condition ensures that the data collected is up-to-date. Data crawled : the last stop criteria is determined by whether or not the crawler has collected all the targeted links.
In this section, we describe the evaluation criteria and the case scenaario used to evaluate a dark web crawler. For the evaluation of our dark web crawling methodology, we chose to analyze a prominent dark web marketplaces, Cocorico Market . This marketplaces is known for hosting a wide range of illicit activities, including the sale of drugs, weapons, counterfeit items, stolen data, and various other illegal goods and services.
The coverage of a crawler refers to the extent to which it is able to successfully and comprehensively extract all of the desired data from a given set of sources. Measuring the coverage is important for evaluating the effectiveness of the crawler and ensuring that it is meeting its intended goals. One way to measure the coverage of a crawler is by calculating the ratio of the number of downloaded pages to the total number of web pages of a website [ 14 ] . Since the total number of pages of a website is not known a priory, an approach to estimating the coverage of a crawler is to compare the number of pages downloaded by the crawler to the total number of pages downloaded by other crawlers.
Performance is a critical factor in evaluating the effectiveness of a web crawler, and there are several key metrics that can be used to measure its performance. Two common metrics used to evaluate the performance of a crawler are the number of pages downloaded per minute and the execution time of each crawler [ 15 ] . The number of pages downloaded per minute is a measure of how quickly a crawler can traverse the web and retrieve content. This metric is essential for ensuring that the crawler can keep up with the constant stream of new content being added to the web. A high rate of page downloads per minute can be an indication of a well-performing crawler, while a low rate may suggest that the crawler is struggling to keep up with the volume of content.
In evaluating the performance of a dark web crawler, the execution time is a fundamental metric due to its direct correlation with the efficiency and responsiveness of the crawler in retrieving web content. A shorter execution time indicates a more agile and responsive crawler. As web crawling tasks often involve processing vast amounts of data distributed across numerous web pages, minimizing execution time is important to ensure timely data retrieval and processing.
In the context of web crawling, robustness refers to the ability of a crawler to continue operating effectively and efficiently even when faced with unexpected or challenging conditions. A robust crawler is able to handle a variety of situations, including network connectivity issues, site changes, and other potential obstacles, without experiencing significant disruptions or failures. Robustness is an important characteristic of a successful crawler, as it ensures that the crawler is able to continue operating effectively over time, even in the face of changing conditions and challenges. The robustness can be measured by counting the number of error happen during the crawling process [ 14 ] .
To evaluate the effectiveness of our dark web crawler, we conduct experiments comparing our crawler with the dark web crawler ACHE. We select this crawler based on its prominence in the field and their ability to navigate the dark web. The goal of the experimentation is to assess the performance of our crawler in terms of coverage, performance, and robustness. We aim to determine how well our crawler gather data from the dark web, enlightning the strengths and weaknesses of our methodology in capturing data from Cocorico Market. The evaluation metrics provided a comprehensive framework for assessing the performance of the crawlers and determining the suitability of our approach in the context of dark web crawling.
The experimental setup involved running each crawler separately on identical hardware infrastructure, using the same configurations and parameters. To ensure a fair comparison among the crawlers, we established a specific time frame of 10 hours for the crawling process. The experimentation was repeated 10 times for each level of depth, ranging from depth 1 to depth 4. Subsequently, we calculated the mean and standard deviation of each metric involved in the analysis.
In this section, we present the results of the experimentation conducted on both dark web crawlers ACHE and CRATOR . In the analysis of the dark web marketplace Cocorico Market to validate the coverage, we considered two coverage metrics as explained in Section IV-B . Coverage is defined as the number of pages downloaded, while relative coverage is the success rate of a crawler calculated as pages downloaded divided by pages found.
Our tool, CRATOR , demonstrated remarkable effectiveness in downloading all the pages it found. On the other hand, ACHE achieved a maximum coverage of 0.944 with a level of depth 1 (see results in table I ). When considering relative coverage, it seems that CRATOR outperforms ACHE consistently. This metric provides insights into the internal coverage of the tool, as it is based on the links discovered during crawling.
Hence, it lacks knowledge of the real size of the marketplace. By utilizing coverage metrics, we gain a better understanding of the capabilities of both tools in downloading all the pages within the marketplace. From the results presented in table I and the visual representation in fig. 2(a) , it is evident that CRATOR consistently outperforms ACHE across all scenarios (levels of depth 1, 2, 3, 4). Furthermore, the standard deviation outlined in fig. 2(a) indicates that CRATOR exhibits higher reliability across different iterations. The lower standard deviation of CRATOR suggests that the results achieved with different executions are more consistent compared to ACHE .
As outlined in section IV-B , we evaluate our tool regarding the performance metric using two key metrics: execution time and the number of pages downloaded per minute. Figure 3(a) illustrates the execution time of both approaches. It is evident from the figure that CRATOR exhibits lower execution times compared to ACHE for the first three levels of depth. However, ACHE outperforms CRATOR with the last level of depth.
To understand this discrepancy, we analyse the second performance metric. Figure 3(b) presents the pages downloaded per minute by each tool for each level of depth. It is evident that CRATOR consistently outperforms ACHE in every scenario. Thus, despite the higher execution time of CRATOR at level of depth 4, it is clear that CRATOR downloaded more pages, as confirmed by the results presented in table I .
As discussed in section IV-B , we evaluate robustness using the failure rate metric, which is expressed as the number of pages not downloaded over the total number of pages found. Table IV presents the number of pages failed, with the failure rate expressed as a value between 0 and 1. The results obtained from the evaluation highlight the strengths of CRATOR in terms of coverage, performance, and robustness. It exhibited the ability to download a higher number of pages, achieved a higher average of pages per minute, and demonstrated lower error rates.
To validate the effectiveness of our crawler, we conducted an experimentation comparing CRATOR with an established dark web crawler, ACHE . The comparison was based on metrics such as coverage, performance, and robustness. The results demonstrated that CRATOR outperformed ACHE in terms of coverage, downloading a greater number of pages within the specified timeframe. It also exhibited a higher page per minute rate, indicating its efficiency in navigating and retrieving information. Additionally, CRATOR raised fewer errors, highlighting its robustness and ability to overcome common obstacles encountered in the dark web.
As a future work, we plan to conduct a more exhaustive experimentation, focusing on daily analysis of dumps and incorporating different dark web marketplaces with varying security layers. This expanded evaluation will allow us to assess the usability and performance of CRATOR in a broader range of scenarios, further validating its capabilities as a reliable dark web crawler.
Our study demonstrates the potential of CRATOR as an effective tool for dark web crawling, offering improved coverage, performance, and robustness compared to existing approaches. With further research and refinement, CRATOR has the potential to contribute significantly to the exploration and understanding of the dark web ecosystem. Enhance your OSINT toolkit! Learn how to use Python to automate monitoring of dark web forums, leak sites, and marketplaces for actionable threat intelligence.
In this article, we'll explore the power of combining Python's scripting capabilities with Tor's anonymity features to monitor the dark web and gather valuable threat intelligence. We'll create a script that utilizes the requests_ tor library to scrape dark websites and hunt for telltale keywords seamlessly. Here's a script that utilizes the requests_ tor library to scrape dark websites and hunt for those tell-tale keywords seamlessly: * Beautiful Soup Integration: We use the bs4 library to parse the HTML structure of scraped pages, allowing for more refined searches.
* Error Handling: We use a try...except block for more graceful error handling, printing informative messages if scraping fails. * Function-Based Approach: Modularized the scraping and searching logic into a reusable scrape_and_search function. * Structured Data: We employ a list of tuples (`sites`) to hold URL and name pairs, making the code more organized. * Keyword List: Define a keyword list to easily manage the terms you want to search for.
* Concise Output: Set up a clear output indicating the scraped site and any found keywords. * Schedule: Use tools like cron (on Linux) or Task Scheduler (on Windows) to run your script at regular intervals. * Alerts: Integrate with notification services (email, SMS, or messaging platforms) to receive alerts when specific events occur. 4. Practical Deployment, Analysis & Case Studies * Stem Library: Use the stem library for more granular control over Tor circuits and relays.
* Data Storage and Analysis: Store collected data in a structured format (database or CSV) for further analysis and historical tracking. * OpSec: Be mindful of operational security. Avoid leaving sensitive traces on your system and always use a dedicated, isolated environment for dark web monitoring.
* Responsible Engagement: Use dark web intelligence gathering for defensive purposes. Avoid any actions that could put yourself or others at risk. * Respect Privacy: Even when monitoring threat actors, be mindful of the privacy of individuals who may be caught up in these activities.
Combining Python's scripting power with Tor's anonymity features, we've unlocked a powerful tool for monitoring the dark web and gathering valuable threat intelligence. This article has provided a foundation, but the possibilities for customization and refinement are endless. Have you developed your own unique dark web monitoring scripts or techniques? Share your insights within the OSINT and cybersecurity communities – collaboration is key to staying ahead of evolving threats. In future articles, we'll delve deeper into advanced data analysis techniques to extract even more meaningful insights from the dark web data you collect.
As a cybersecurity expert, I know that protecting our digital world requires collaboration and coordination among experts from various fields. Let's work together to create a safer online environment! #Cybersecurity #Teamwork #DigitalSafety In today's fast-paced digital landscape, it's crucial to prioritize human-centered cybersecurity approaches that focus on people, not just technology. Join me in exploring innovative solutions that put users at the forefront.
#HumanCenteredCybersecurity #UserFirst #DigitalWellness As we navigate the ever-evolving cyber threat landscape, it's essential to recognize that cybersecurity is a shared responsibility among individuals, organizations, and governments. Let's work together to create a culture of cybersecurity awareness and vigilance! #CybersecurityAwareness #SharedResponsibility #DigitalCitizenship Artificial intelligence (AI) is revolutionizing the way we detect and respond to cyber threats. Join me in exploring the exciting possibilities of AI-powered threat detection and its potential to transform our industry. #AIinCybersecurity #ThreatDetection #FutureOfCybersecurity As a cybersecurity specialist, I believe that everyone deserves equal access to secure digital experiences. Let's work together to bridge the gap between technology and society, ensuring that cybersecurity is accessible to all. #CybersecurityForAll #DigitalInclusion #Accessibility In today's digitally driven world, it's crucial to equip the next generation with the skills and knowledge needed to navigate the complex cyber landscape. Join me in promoting cybersecurity education as a vital component of our collective future.
#CybersecurityEducation #DigitalLiteracy #FutureOfWork As we face the challenges of the digital age, I believe that cybersecurity can be a catalyst for innovation, driving progress in fields like healthcare, finance, and education. Let's explore the exciting possibilities of cybersecurity-driven innovation! #CybersecurityInnovation #DigitalTransformation #FutureOfTech In today's interconnected world, trust is essential for building strong relationships between individuals, organizations, and governments. Join me in exploring how cybersecurity can play a vital role in fostering trust and confidence online.
#CybersecurityAndTrust #DigitalIntegrity #OnlineSafety As we strive to create a more inclusive digital society, I believe that cybersecurity is a critical component of this effort. Let's work together to ensure that everyone has equal access to secure digital experiences, regardless of their background or location. #DigitalInclusion #CybersecurityForAll #Accessibility As we look to the future, I'm excited to collaborate with like-minded individuals and organizations to shape the next chapter in cybersecurity. Join me on this journey as we work together to create a safer, more secure digital world for all! #CybersecurityCollaboration #FutureOfCybersecurity #DigitalSafety When C developers need to create plugin architectures, implement event-driven callbacks, or build state machines, they… I Mac bez hasIa. Root bez logowania. CVE-2026-65400 jest juI wykorzystywane w realnych atakach.
To nie jest kolejna luka, przy której napastnik najpierw musi zdobyI login, hasIo albo przekonaI uIytkownika do… 1. Mariusz Gralewski – zaIoIyciel i CEO W 2010 roku odkupiI od Marka Wróbla serwis ZnanyLekarz i od razu myIlaI… A real scenario we encounter during our audits at CSSLTD: A marketing intern has a list of 500 high-net-worth clients… Drugi cios w polski sektor energetyczny | GrudzieI 2025 | Ujawnienie: SierpieI 2026 https://zi3lak.github.
To nie jest kolejny kurs, w którym oglIdasz godzinI teorii, a potem przepisujesz Hello World. W NEXUS trafiasz na… AI-Powered Python Tools Transforming Digital Forensics: A Practical Guide for Professionals The DarkWeb Recon & Intelligence Tool is a Python-based security research project designed to perform passive reconnaissance, crawling, scraping, and risk analysis on Tor (.onion) websites.
targets.txt ↓ Onion Validation ↓ Surface Crawling ↓ Deep Crawling (optional) ↓ Web Scraping ↓ Content Analysis ↓ Risk & Intent Classification ↓ Security Posture Evaluation ↓ Database Storage ↓ Reports Darkweb-recon/ III main.py III crawler.py III deep_crawler.py III scraper.py III analyzer.py III recon.py III onion_validator.py III risk.py III explain.py III intent.py III posture.py III priority.py III formatter.py III database.py III view_db.py III tor_check.py III config.py III targets.txt III darkweb_report.csv III README.md Central controller that loads targets, validates onions, runs crawling/scraping, performs analysis, prints output, and stores results.
Detects risk indicators such as credentials, financial data, logs, and vulnerabilities. Collects passive reconnaissance data including headers, server banners, and security headers. This tool is intended strictly for educational and defensive security research. Any misuse is the responsibility of the user. Developed as a Dark Web Recon & Security Intelligence Project focused on VAPT learning.
Dark Web Recon & Intelligence Tool is a Python-based security research project for analyzing onion websites over the Tor network. It performs automated crawling, scraping, and passive reconnaissance to extract technical details, assess risk indicators and evaluate security posture for ethical threat intelligence and learning purposes. DARKMINE is a reproducible research benchmark for dark web threat intelligence, supporting four tasks: criminal organization detection, attack infrastructure attribution, attack campaign prediction (14-day lead), and threat actor collaboration modeling.
The data is programmatically generated to mirror the structure and reported statistics of the corpus described in the associated ISDFS 2026 paper; the original evaluation corpus is restricted and cannot be released publicly due to legal and ethical constraints on dark web data. The benchmark comprises forum posts, marketplace listings, IRC logs, and ground-truth labels for organizations, personas, infrastructure nodes, campaigns, and collaboration edges, distributed as UTF-8 CSV with a fixed train/validation/test split. A seeded Python generator reproduces the full corpus exactly, enabling controlled experimentation without redistributing restricted material.
Files are UTF-8 CSV, one table per entity/relation, each with a header row. Load with pandas ( pd.read_csv ). Build the four benchmark tasks from these labels: Use the fixed splits in splits/ (70/15/15 by post ID) for comparable results. baseline.py runs simple reference baselines for all four tasks. Regenerate the full corpus with python generate_darkmine_dataset.py --full --seed 42 . See data_dictionary.md for the full per-column schema (labels vs features) and PROVENANCE.md for data availability and the relationship to the paper.
Campaign statistics (72.1% prediction rate, 14-day lead, 34% success reduction) are set as generation parameters, so this is a structural analogue for building and testing pipelines, not an independent reproduction of the paper's measurements. 5. Performance Evaluation & Extended Technical Observations Permalink: https://ieee-dataport.org//documents/darkmine-deep-learning-dark-web-threat-intelligence-anonymous-attack-infrastructure The Dark Web is often seen as a hidden, mysterious part of the internet, where illicit activities thrive and criminals operate with anonymity. But for cybersecurity professionals, law enforcement agencies, and ethical hackers, it represents a goldmine of intelligence (OSINT: Open Source Intelligence) that can be used to monitor threats, protect organizations, and prevent cyberattacks.
Monitoring the Dark Web manually is not only time-consuming but also incredibly risky. This is where Python comes into play. With its extensive libraries and ease of use, Python allows you to automate the process of scraping and monitoring dark web data, making it a powerful tool for threat intelligence. In this blog, we’ll dive into how Python can be leveraged for Dark Web OSINT and how to build automated systems to monitor threats effectively.
The Dark Web, a hidden part of the internet that is not indexed by standard search engines, is a hub for cybercriminals, hackers, and other malicious actors. It’s often used for illegal trade, such as selling stolen data, distributing malware, and organizing criminal activities. Open Source Intelligence (OSINT) involves collecting information from publicly available sources, and when applied to the Dark Web, it helps organizations gain insights into emerging threats, such as data leaks, stolen credentials, or ransomware discussions.
Dark Web OSINT allows security analysts to identify threats early by monitoring activities such as: Stolen credentials and PII (Personally Identifiable Information) being sold. Discussions of vulnerabilities that may target specific companies or industries. Ransomware and malware forums where new tools are shared. Black markets selling illegal goods or services that can harm businesses.
However, performing manual searches on the Dark Web is inefficient and poses risks. Automating these tasks with Python makes the process safer and scalable. Python is widely used for web scraping, data analysis, and automation, making it an excellent language for Dark Web OSINT. Here’s why Python is the preferred choice for this task: Ease of Use : Python is beginner-friendly and has a low learning curve. Even if you’re new to programming, you can quickly write scripts for web scraping and automation. Wide Range of Libraries : Python has libraries like Requests for handling HTTP requests, BeautifulSoup and Scrapy for web scraping, Selenium for browser automation, and Twisted or Stem for interacting with the Tor network. Automation : Python makes it easy to set up cron jobs or background services that run regularly, scraping data, and generating alerts when specific criteria are met. Scalability : Python’s flexibility allows you to scale your Dark Web monitoring efforts from tracking a few sites to scraping large forums and marketplaces with minimal changes to your code.
The first challenge in Dark Web OSINT is accessing the content, as these websites are hosted on the Tor network, which anonymizes user activity. Accessing .onion sites requires routing traffic through the Tor network, and Python can automate this process using the Stem library and Tor client. Using the Stem library, you can control Tor and ensure your Python requests go through the Tor network.
This script sets up a connection to the Tor network, routing your requests through a Tor node. Make sure you have the Tor client running in the background. Once you have access to the Dark Web through Python, the next step is scraping the sites for valuable information. This is where Python’s web scraping libraries come into play.
Here’s a sample code that uses BeautifulSoup to scrape content from a Dark Web forum or marketplace: In this example, we scrape posts from a .onion site and print the title and link for each post. The code can be easily adapted to extract other useful information like usernames, timestamps, or content. Now that you can access and scrape Dark Web data, the next step is to automate threat monitoring. You can set up regular tasks to scan for specific keywords or patterns, such as: Let’s set up a system to monitor posts for specific keywords (e.g., your company’s name or a specific malware strain) and send alerts when they are detected.
In this example, when a post contains one of the specified keywords, an email alert is sent to the security team. This automated monitoring system can be scheduled to run at regular intervals using cron jobs or task schedulers. For those looking to take their Dark Web OSINT automation to the next level, machine learning (ML) offers a way to classify, predict, and detect anomalies in scraped data. This is particularly useful when monitoring vast amounts of unstructured data.
By using a machine learning model like a Naive Bayes Classifier or Support Vector Machine (SVM) , you can automatically classify posts as either “potential threat” or “safe.” This can reduce false positives and help security teams prioritize threats. This example shows how you can train a simple classifier to identify threat-related posts. With more data, you can train a model to become highly accurate in detecting threats.
Stay Anonymous : Always use Tor or a similar anonymizing service when accessing the Dark Web to protect your identity and location. Limit Data Collection : Avoid scraping large volumes of data too quickly to minimize the risk of being detected or blocked. Monitor Specific Forums and Marketplaces : Focus your efforts on a few high-traffic forums or marketplaces that are known for hosting illegal activity. Encrypt Your Data : When storing sensitive information from the Dark Web, ensure that the data is encrypted and stored securely. Stay Updated on Legal Regulations : Be aware of the legal boundaries for Dark Web monitoring in your country and ensure that you comply with all relevant laws.
Python provides a powerful and flexible way to automate threat monitoring on the Dark Web. By leveraging libraries like Stem , Requests , BeautifulSoup , and even machine learning tools, you can build scalable systems to identify and alert on potential threats. Automating this process not only saves time but also enhances the ability to stay ahead of cybercriminals who operate in hidden corners of the internet.
As the cyber threat landscape evolves, mastering Dark Web OSINT techniques will become increasingly important for cybersecurity professionals. Start small, automate key processes, and scale your Dark Web monitoring efforts to protect your organization from hidden threats. We are excited to offer promotional opportunities and guest post collaborations on our blog and website, focusing on all aspects of cybersecurity. Whether you’re an expert with valuable insights to share or a business looking to reach a wider audience, our platform provides the perfect space to showcase your knowledge and services. Let’s work together to enhance our community’s understanding of cybersecurity! Vijay Gupta is a cybersecurity enthusiast with several years of experience in cyber security, cyber crime forensics investigation , and security awareness training in schools and colleges. With a passion for safeguarding digital environments and educating others about cybersecurity best practices, Vijay has dedicated his career to promoting cyber safety and resilience. Stay connected with Vijay Gupta on various social media platforms and professional networks to access valuable insights and stay updated on the latest cybersecurity trends.
Introduction
We Just Gave the Internet a New Set of Hands For thirty years, the browser was a window. You looked… Introduction AI coding agents are everywhere now. They read your code, they write your code, they open pull requests… Phishing has been around for almost as long as email itself. For over two decades, it has remained one of the simplest… I’ve been building small AI agents for about a year now. Chatbots, task automators, a couple of internal tools that… If you work anywhere near AI security, you probably felt the ground shift on August 3, 2026. That’s the day OWASP… Why a Bootable USB Drive Still Matters in 2026 If you work in IT support, system administration, or digital forensics… There is a version of my life that looks good on paper. I left a stable job to build my own company, EINITIAL24.
Introduction Synonym
Why I Think Every Cybersecurity Beginner in India Should Learn Digital Forensics First A few months ago, a friend of mine who works in IT support got a call from his company’s security team. Someone inside… Harvested Online Documentation & Reference Sources • https://github.com/IntelEyes/darkweb_crawler • https://github.com/techenthusiast167/DARKWEB_CRAWLER • https://arxiv.org/html/2405.06356v1 • https://www.linkedin.com/pulse/python-dark-web-osint-automate-threat-monitoring-piotr-klepuszewski-tnmne • https://github.com/Paramananthanxy/Dark-web-recon-threat-intelligence- • https://ieee-dataport.org/documents/darkmine-deep-learning-dark-web-threat-intelligence-anonymous-attack-infrastructure • https://www.linkedin.com/pulse/python-dark-web-osint-automate-threat-monitoring-vijay-gupta--sa22c
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Dark Web Crawling And Threat Intelligence Extraction Python.
[*] Initializing Burp Suite Spider & Vulnerability Engine for Dark Web Crawling And Threat Intelligence Extraction Python... [✓] Burp Extender / Macro Automation Hook Synced ──────────────────────────────────────────────────────────────────────── [11:42:01.104] AUDIT Crawled dynamic endpoints | Injecting input vectors [11:42:01.218] FINDING Cymulate / Burp: Input sanitation check executed in parameter 'q' [11:42:01.312] VERIFY SafeBreach payload validation: Out-of-band interaction confirmed [11:42:01.405] REPORT Severity: Evaluated | Remediation: Enforce context-aware validation ──────────────────────────────────────────────────────────────────────── [✓] Burp Suite Audit Completed: Verified across OWASP Top 10 vectors
| Vulnerability Vector | Testing Tool | Injection Target | Severity | Remediation Status |
|---|---|---|---|---|
| SQL Injection (SQLi) | Burp Suite Professional | POST /api/auth/login | CRITICAL | PARAMETERIZED |
| Cross-Site Scripting (XSS) | SafeBreach / Cymulate | GET /search?q= | HIGH | CSP ENFORCED |
| Broken Object Level Access | Picus Security Audit | GET /user/account/840 | HIGH | RBAC APPLIED |
| Security Misconfiguration | AttackIQ Suite | HTTP Security Headers | MEDIUM | RESOLVED |