Complete Technical Paper Content — Differential Privacy Implementation For Sensitive Datasets
Overview & System Context
Differential Privacy Implementation For Sensitive Datasets: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9521 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Differential privacy (DP) is a mathematically rigorous framework for releasing statistical information about datasets while protecting the privacy of individual data subjects. It enables a data holder to share aggregate patterns of the group while limiting information that singles out specific individuals. This is done by injecting carefully calibrated noise into statistical computations such that the utility of the statistic is preserved while provably limiting what can be inferred about any individual in the dataset. Another way to describe differential privacy is as a constraint on the algorithms used to publish aggregate information about a statistical database which limits the disclosure of private information of records in the database. For example, differentially private algorithms are used by some government agencies to publish demographic information or other statistical aggregates while ensuring confidentiality of survey responses, and by companies to collect information about user behavior while controlling what is visible even to internal analysts. Roughly, an algorithm is differentially private if an observer seeing its output cannot tell whether a particular individual's information was used in the computation. Differential privacy is often discussed in the context of identifying individuals whose information may be in a database. Although it does not directly refer to identification and reidentification attacks, differentially private algorithms provably resist such attacks.
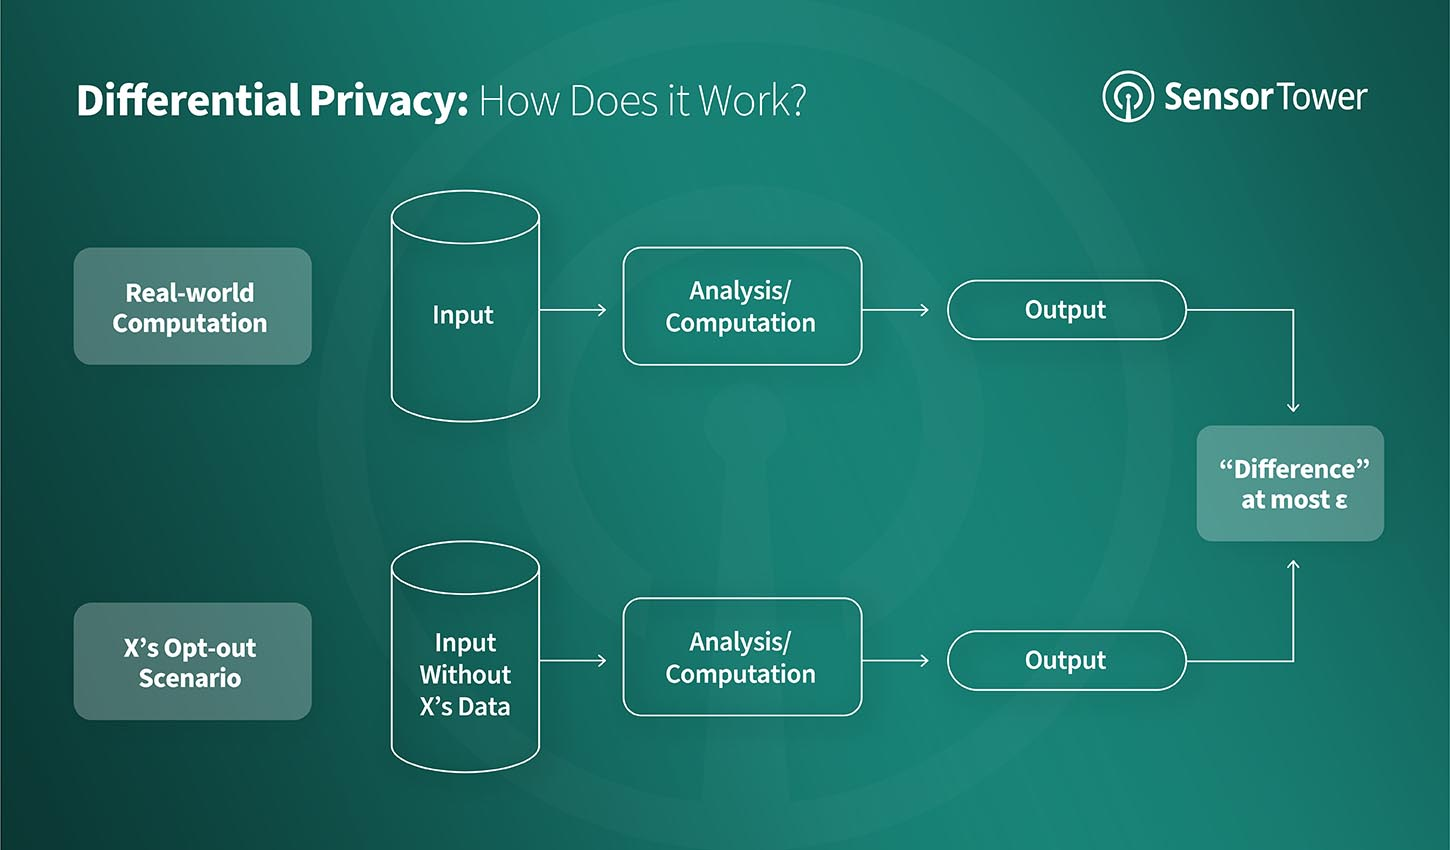
The 2006 Cynthia Dwork, Frank McSherry, Kobbi Nissim, and Adam D. Smith article introduced the concept of ε-differential privacy, a mathematical definition for the privacy loss associated with any data release drawn from a statistical database. (Here, the term statistical database means a set of data that are collected under the pledge of confidentiality for the purpose of producing statistics that, by their production, do not compromise the privacy of those individuals who provided the data.) The definition of ε-differential privacy requires that a change to one entry in a database only creates a small change in the probability distribution of the outputs of measurements, as seen by the attacker. The intuition for the definition of ε-differential privacy is that a person's privacy cannot be compromised by a statistical release if their data are not in the database. In differential privacy, each individual is given roughly the same privacy that would result from having their data removed. That is, the statistical functions run on the database should not be substantially affected by the removal, addition, or change of any individual in the data. How much any individual contributes to the result of a database query depends in part on how many people's data are involved in the query. If the database contains data from a single person, that person's data contributes 100%. If the database contains data from a hundred people, each person's data contributes just 1%. The key insight of differential privacy is that as the query is made on the data of fewer and fewer people, more noise needs to be added to the query result to produce the same amount of privacy. Hence the name of the 2006 paper, "Calibrating Noise to Sensitivity in Private Data Analysis." where the probability is taken over the randomness used by the algorithm. This definition is sometimes called "approximate differential privacy", with "pure differential privacy" being a special case when δ = 0 {\displaystyle \delta =0} . In the latter case, the algorithm is commonly said to satisfy ε-differential privacy (i.e., omitting δ = 0 {\displaystyle \delta =0} ). Differential privacy offers strong and robust guarantees that facilitate modular design and analysis of differentially private mechanisms due to its composability, robustness to post-processing, and graceful degradation in the presence of correlated data.
Now suppose a malicious user (often termed an adversary) wants to find whether Chandler has diabetes or not. Suppose he also knows in which row of the database Chandler resides. Now suppose the adversary is only allowed to use a particular form of query Q i {\displaystyle Q_{i}} that returns the partial sum of the first i {\displaystyle i} rows of column X {\displaystyle X} in the database. In order to find Chandler's diabetes status the adversary executes Q 5 ( D 1 ) {\displaystyle Q_{5}(D_{1})} and Q 4 ( D 1 ) {\displaystyle Q_{4}(D_{1})} , then computes their difference. In this example, Q 5 ( D 1 ) = 3 {\displaystyle Q_{5}(D_{1})=3} and Q 4 ( D 1 ) = 2 {\displaystyle Q_{4}(D_{1})=2} , so their difference is 1. This indicates that the "Has Diabetes" field in Chandler's row must be 1. This example highlights how individual information can be compromised even without explicitly querying for the information of a specific individual. Continuing this example, if we construct D 2 {\displaystyle D_{2}} by replacing (Chandler, 1) with (Chandler, 0) then this malicious adversary will be able to distinguish D 2 {\displaystyle D_{2}} from D 1 {\displaystyle D_{1}} by computing Q 5 − Q 4 {\displaystyle Q_{5}-Q_{4}} for each dataset. If the adversary were required to receive the values Q i {\displaystyle Q_{i}} via an ε {\displaystyle \varepsilon } -differentially private algorithm, for a sufficiently small ε {\displaystyle \varepsilon } , then they would be unable to distinguish between the two datasets.
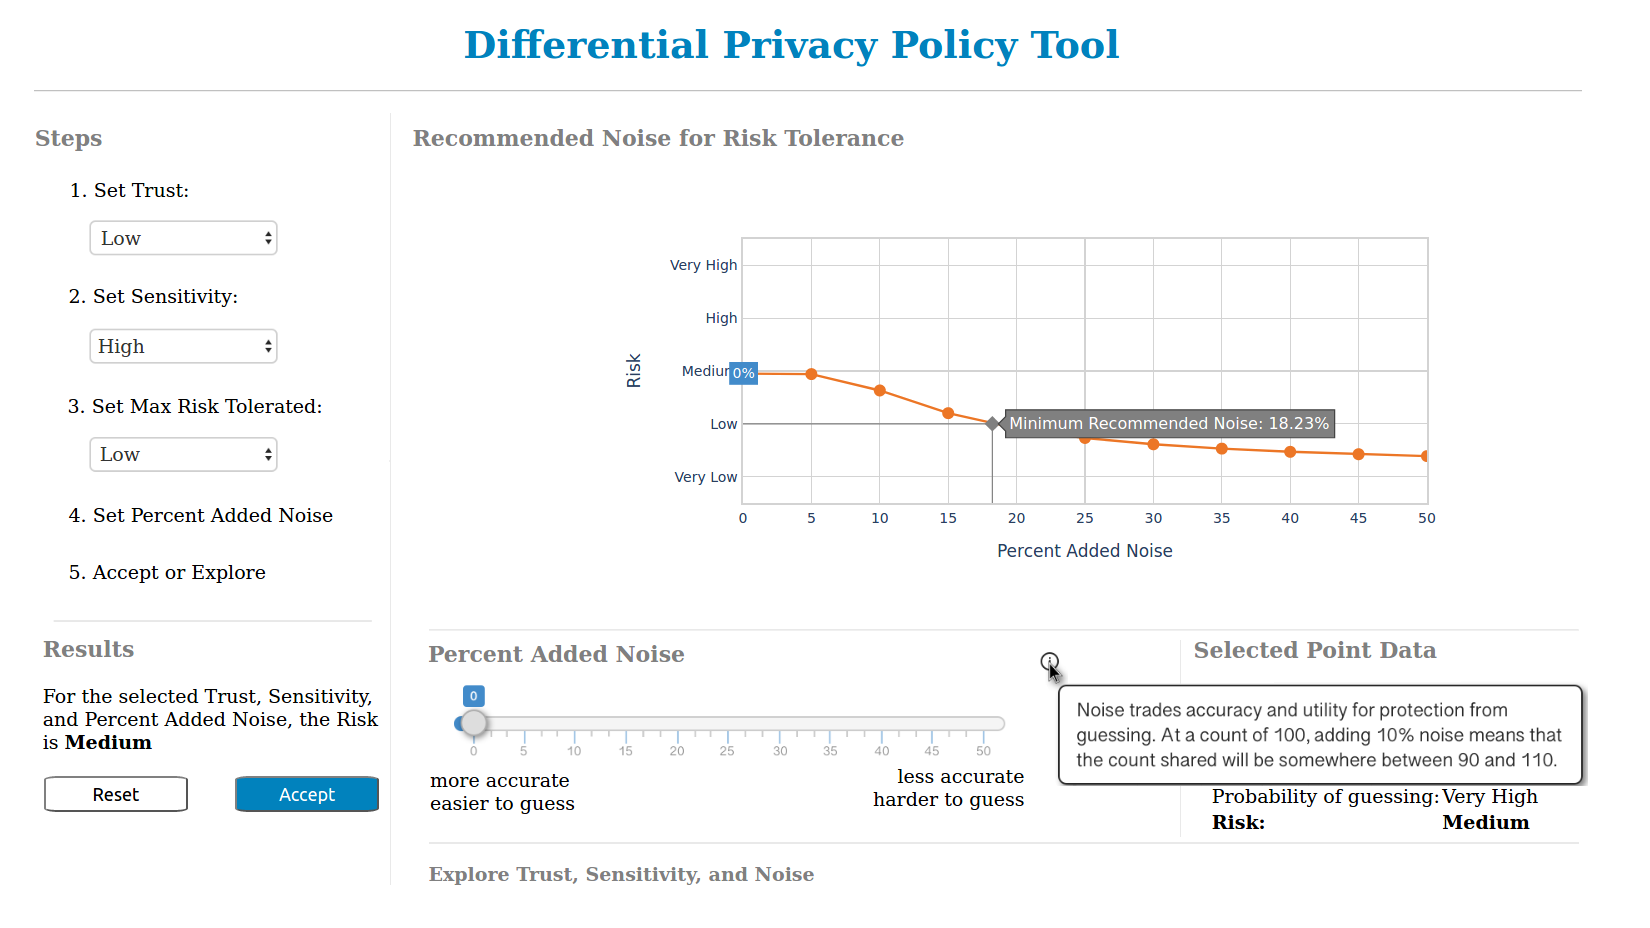
Figure 1: IEEE VIS 2021 Virtual: Decision Support for Sharing Data Using ... Sequential composition. If we query an ε-differential privacy mechanism t {\displaystyle t} times, and the randomization of the mechanism is independent for each query, then the result would be ε t {\displaystyle \varepsilon t} -differentially private. In the more general case, if there are n {\displaystyle n} independent mechanisms: M 1 , … , M n {\displaystyle {\mathcal {M}}_{1},\dots ,{\mathcal {M}}_{n}} , whose privacy guarantees are ε 1 , … , ε n {\displaystyle \varepsilon _{1},\dots ,\varepsilon _{n}} differential privacy, respectively, then any function g {\displaystyle g} of them: g ( M 1 , … , M n ) {\displaystyle g({\mathcal {M}}_{1},\dots ,{\mathcal {M}}_{n})} is ( ∑ i = 1 n ε i ) {\displaystyle \left(\sum \limits _{i=1}^{n}\varepsilon _{i}\right)} -differentially private. Parallel composition. If the previous mechanisms are computed on disjoint subsets of the private database then the function g {\displaystyle g} would be ( max i ε i ) {\displaystyle (\max _{i}\varepsilon _{i})} -differentially private instead. The other important property for modular use of differential privacy is robustness to post processing. This is defined to mean that for any deterministic or randomized function F {\displaystyle F} defined over the image of the mechanism A {\displaystyle {\mathcal {A}}} , if A {\displaystyle {\mathcal {A}}} satisfies ε-differential privacy, so does F ( A ) {\displaystyle F({\mathcal {A}})} . The property of composition permits modular construction and analysis of differentially private mechanisms and motivates the concept of the privacy loss budget. If all elements that access sensitive data of a complex mechanisms are separately differentially private, so will be their combination, followed by arbitrary post-processing.
H 0 {\displaystyle H_{0}} : The individual's data is not in the dataset. H 1 {\displaystyle H_{1}} : The individual's data is in the dataset. Then, there are two error rates: False Positive Rate (FPR): P FP = Pr [ Adversary guesses H 1 I H 0 is true ] . {\displaystyle P_{\text{FP}}=\Pr[{\text{Adversary guesses }}H_{1}\mid H_{0}{\text{ is true}}].} Figure 2: Inside Data: Why Differential Privacy Matters for Security False Negative Rate (FNR): P FN = Pr [ Adversary guesses H 0 I H 1 is true ] . {\displaystyle P_{\text{FN}}=\Pr[{\text{Adversary guesses }}H_{0}\mid H_{1}{\text{ is true}}].} Ideal protection would imply that both error rates are equal, but for a fixed (ε, δ) setting, an attacker can achieve the following rates: { ( P FP , P FN ) I P FP + e ε P FN ≥ 1 − δ , e ε P FP + P FN ≥ 1 − δ } {\displaystyle \{(P_{\text{FP}},P_{\text{FN}})\mid P_{\text{FP}}+e^{\varepsilon }P_{\text{FN}}\geq 1-\delta ,\ e^{\varepsilon }P_{\text{FP}}+P_{\text{FN}}\geq 1-\delta \}} The Laplace mechanism adds Laplace noise (i.e. noise from the Laplace distribution, which can be expressed by probability density function noise ( y ) ∝ exp I ( − | y | / λ ) {\displaystyle {\text{noise}}(y)\propto \exp(-|y|/\lambda )\,\!} , which has mean zero and standard deviation 2 λ {\displaystyle {\sqrt {2}}\lambda \,\!} ). Now in our case we define the output function of A {\displaystyle {\mathcal {A}}\,\!} as a real valued function (called as the transcript output by A {\displaystyle {\mathcal {A}}\,\!} ) as T A ( x ) = f ( x ) + Y {\displaystyle {\mathcal {T}}_{\mathcal {A}}(x)=f(x)+Y\,\!} where Y ∼ Lap ( λ ) {\displaystyle Y\sim {\text{Lap}}(\lambda )\,\!\,\!} and f {\displaystyle f\,\!} is the original real valued query/function we planned to execute on the database. Now clearly T A ( x ) {\displaystyle {\mathcal {T}}_{\mathcal {A}}(x)\,\!} can be considered to be a continuous random variable, where Figure 3: Evaluation of Open-Source Tools for Differential Privacy p d f ( T A , D 1 ( x ) = t ) p d f ( T A , D 2 ( x ) = t ) = noise ( t − f ( D 1 ) ) noise ( t − f ( D 2 ) ) {\displaystyle {\frac {\mathrm {pdf} ({\mathcal {T}}_{{\mathcal {A}},D_{1}}(x)=t)}{\mathrm {pdf} ({\mathcal {T}}_{{\mathcal {A}},D_{2}}(x)=t)}}={\frac {{\text{noise}}(t-f(D_{1}))}{{\text{noise}}(t-f(D_{2}))}}\,\!} which is at most e | f ( D 1 ) − f ( D 2 ) | λ ≤ e ∆ ( f ) λ {\displaystyle e^{\frac {|f(D_{1})-f(D_{2})|}{\lambda }}\leq e^{\frac {\Delta (f)}{\lambda }}\,\!} . We can consider ∆ ( f ) λ {\displaystyle {\frac {\Delta (f)}{\lambda }}\,\!} to be the privacy factor ε {\displaystyle \varepsilon \,\!} . Thus T {\displaystyle {\mathcal {T}}\,\!} follows a differentially private mechanism (as can be seen from the definition above). If we try to use this concept in our diabetes example then it follows from the above derived fact that in order to have A {\displaystyle {\mathcal {A}}\,\!} as the ε {\displaystyle \varepsilon \,\!} -differential private algorithm we need to have λ = 1 / ε {\displaystyle \lambda =1/\varepsilon \,\!} . Though we have used Laplace noise here, other forms of noise, such as the Gaussian Noise, can be employed, but they may require a slight relaxation of the definition of differential privacy.
A simple example, especially developed in the social sciences, is to ask a person to answer the question "Do you own the attribute A?", according to the following procedure: Toss a coin. If heads, then toss the coin again (ignoring the outcome), and answer the question honestly. If tails, then toss the coin again and answer "Yes" if heads, "No" if tails. (The seemingly redundant extra toss in the first case is needed in situations where just the act of tossing a coin may be observed by others, even if the actual result stays hidden.) The confidentiality then arises from the refutability of the individual responses. But, overall, these data with many responses are significant, since positive responses are given to a quarter by people who do not have the attribute A and three-quarters by people who actually possess it. Thus, if p is the true proportion of people with A, then we expect to obtain (1/4)(1-p) + (3/4)p = (1/4) + p/2 positive responses. Hence it is possible to estimate p. In particular, if the attribute A is synonymous with illegal behavior, then answering "Yes" is not incriminating, insofar as the person has a probability of a "Yes" response, whatever it may be. Although this example, inspired by randomized response, might be applicable to microdata (i.e., releasing datasets with each individual response), by definition differential privacy excludes microdata releases and is only applicable to queries (i.e., aggregating individual responses into one result) as this would violate the requirements, more specifically the plausible deniability that a subject participated or not.
A {\displaystyle A} and B {\displaystyle B} (where A {\displaystyle A} contains the group and B {\displaystyle B} does not). In this case M I T {\displaystyle M\circ T} is ( ε × c × h ) {\displaystyle (\varepsilon \times c\times h)} -differentially private. To date there are over 12 real-world deployments of differential privacy, the most noteworthy being: 2. System Architecture & Core Working Principles 2008: U.S. Census Bureau, for showing commuting patterns. 2014: Google's RAPPOR, for telemetry such as learning statistics about unwanted software hijacking users' settings. 2015: Google, for sharing historical traffic statistics. 2016: Apple iOS 10, for use in Intelligent personal assistant technology. 2017: Microsoft, for telemetry in Windows. 2020: Social Science One and Facebook, a 55 trillion cell dataset for researchers to learn about elections and democracy. 2020: LinkedIn, for its Audience Engagement API, which shares differentially private engagement statistics with advertisers. 2021: The US Census Bureau uses differential privacy to release redistricting data from the 2020 Census. 2022: Google's Plume, an open-source library for scalable differentially private analytics. 2026: Researchers at Harvard's John A. Paulson School of Engineering and Applied Sciences launched a public registry documenting real-world differential privacy deployments, intended to support broader adoption and inform best practices.
Data utility and accuracy. The main concern with differential privacy is the trade-off between data utility and individual privacy. If the privacy loss parameter is set to favor utility, the privacy benefits are lowered (less “noise” is injected into the system); if the privacy loss parameter is set to favor heavy privacy, the accuracy and utility of the dataset are lowered (more “noise” is injected into the system). It is important for policymakers to consider the trade-offs posed by differential privacy in order to help set appropriate best practices and standards around the use of this privacy preserving practice, especially considering the diversity in organizational use cases. It is worth noting, though, that decreased accuracy and utility is a common issue among all statistical disclosure limitation methods and is not unique to differential privacy. What is unique, however, is how policymakers, researchers, and implementers can consider mitigating against the risks presented through this trade-off. Data privacy and security. Differential privacy provides a quantified measure of privacy loss and an upper bound and allows curators to choose the explicit trade-off between privacy and accuracy. It is robust to still unknown privacy attacks. However, it encourages greater data sharing, which if done poorly, increases privacy risk. Differential privacy implies that privacy is protected, but this depends very much on the privacy loss parameter chosen and may instead lead to a false sense of security. Finally, though it is robust against unforeseen future privacy attacks, a countermeasure may be devised that we cannot predict.
Subtle algorithmic or analytical mistakes. Timing side-channel attacks. In contrast with timing attacks against implementations of cryptographic algorithms that typically have low leakage rate and must be followed with non-trivial cryptanalysis, a timing channel may lead to a catastrophic compromise of a differentially private system, since a targeted attack can be used to exfiltrate the very bit that the system is designed to hide. Leakage through floating-point arithmetic. Differentially private algorithms are typically presented in the language of probability distributions, which most naturally lead to implementations using floating-point arithmetic. The abstraction of floating-point arithmetic is leaky, and without careful attention to details, a naive implementation may fail to provide differential privacy. (This is particularly the case for ε-differential privacy, which does not allow any probability of failure, even in the worst case.) For example, the support of a textbook sampler of the Laplace distribution (required, for instance, for the Laplace mechanism) is less than 80% of all double-precision floating point numbers; moreover, the support for distributions with different means are not identical. A single sample from a naïve implementation of the Laplace mechanism allows distinguishing between two adjacent datasets with probability more than 35%. Timing channel through floating-point arithmetic. Unlike operations over integers that are typically constant-time on modern CPUs, floating-point arithmetic exhibits significant input-dependent timing variability. Handling of subnormals can be particularly slow, as much as by ×100 compared to the typical case.
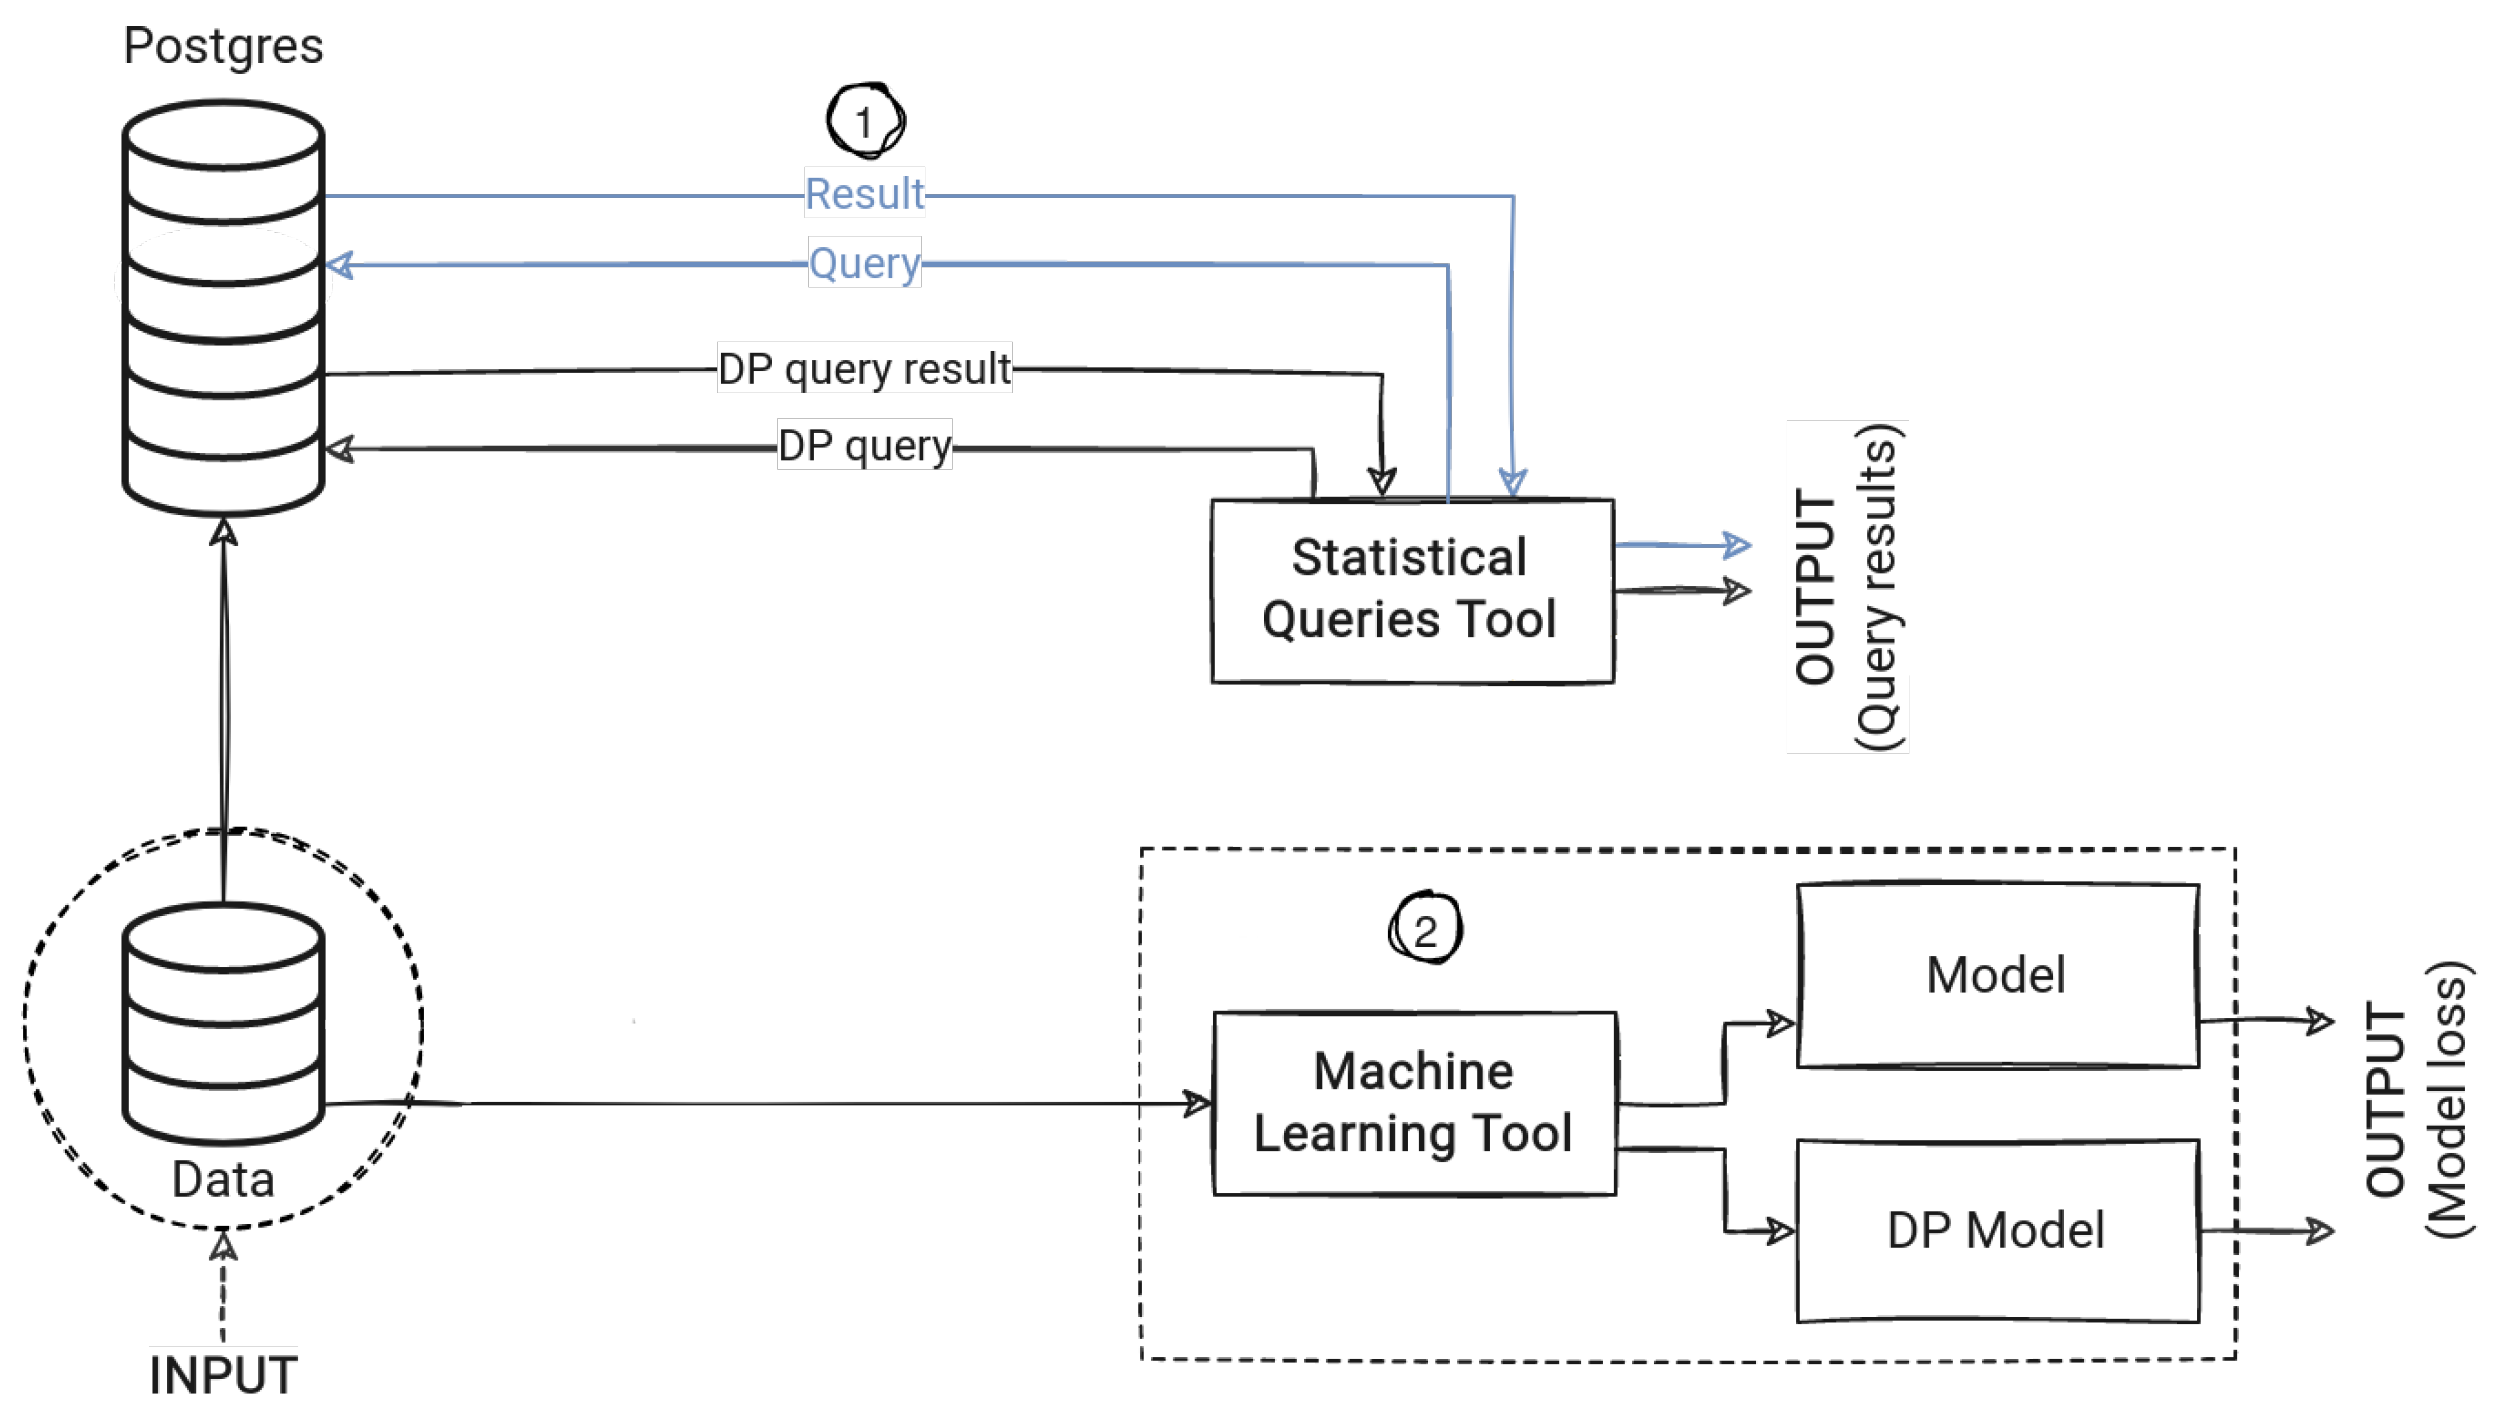
Differentially private stochastic gradient descent (DP-SGD) is an algorithmic technique for learning and a refined analysis of privacy costs within the framework of differential privacy. DP-SGD was introduced by Abadi et al. at the 2016 ACM Conference on Computer and Communications Security, where it addresses a fundamental challenge—the privacy-utility trade-off. Stronger privacy requires more noise or larger privacy budgets, which can reduce model accuracy. DP-SGD has become a de facto standard for privacy-preserving learning from large datasets. It is used in domains with sensitive data, including healthcare and cybersecurity. DP-SGD has been shown to demonstrate that deep neural networks with non-convex objectives can be trained under a modest privacy budget, at a manageable cost in software complexity and model quality. A non-convex objective is one that may have multiple local minima, making optimization more challenging than with convex objectives. Existing approaches require large privacy budgets to train and incur high overheads in computational resources. A privacy budget refers to the total amount of privacy loss allowed over the entire training process. DP-SGD follows the same steps as standard stochastic gradient descent (SGD). However, it also clips the gradients' norm to a threshold and then add Gaussian noise. Gaussian noise is a type of random noise drawn from a normal distribution. Differential privacy is formally defined using the parameters (ε, δ), which bound the privacy loss of any algorithm. DP-SGD tracks privacy loss by a method called the moments accountant. Current implementations use a method called Rényi differential privacy, which provides an even tighter privacy accounting than the original moments accountant. The moments accountant tracks the privacy loss as a random variable at each step. Another privacy-preserving training method is Private Aggregation of Teacher Ensembles (PATE), which uses an ensemble of teacher models to label public data. A teacher model is a model trained on private data that is used to label or provide guidance to another model (the student model).
DP-SGD uses a subsampling method where each mini-batch is formed by sampling each example independently with probability q. This provides privacy amplification by subsampling. Subsampling means selecting a random subset of the data for each training step rather than using the full dataset. The privacy parameters include the clipping norm (C) and the noise scale (σ). The clipping norm is the maximum allowed length of a gradient. Any gradient longer than C is scaled down to length C. The noise scale on the other hand controls how much random noise is added to the gradients. These parameters can determine the privacy-utility trade-off. The noise scale σ is calibrated such that the noise variance is proportional to C²σ².
Unlike standard SGD, DP-SGD's privacy loss accumulates over multiple training steps, and the moments accountant can track this cumulative loss to determine the overall privacy guarantee, usually denoted as ε (epsilon), δ (delta). An ε controls how information about any single example can be leaked. Likewise, a δ is a small probability that the privacy guarantee fails. Hence, it provides tighter estimates on the overall privacy loss. Privacy loss is a measure of how much information an individual training example can be inferred from the algorithm's output.
Information privacy, also known as data privacy or data protection, is the relationship between the collection and dissemination of data, technology, the public expectation of privacy, contextual information norms, and the legal and political issues surrounding them. Various types of personal information often come under privacy concerns. Privacy concerns exist wherever personally identifiable information or other sensitive information is collected, stored, used, and finally destroyed or deleted – in digital form or otherwise. Improper or non-existent disclosure control can be the root cause for privacy issues.
Informed consent mechanisms including privacy policies and dynamic consent are important in communicating to data subjects the different uses of their personally identifiable information. Healthcare records Criminal justice investigations and proceedings Financial institutions and transactions Biological traits, such as genetic material Residence and geographic records Privacy breach Location-based service and geolocation Web surfing behavior or user preferences using persistent cookies Academic research Information about a person's financial transactions, including the amount of assets, positions held in stocks or funds, outstanding debts, and purchases can be sensitive. If criminals gain access to information such as a person's accounts or credit card numbers, that person could become the victim of fraud or identity theft. Information about a person's purchases can reveal a great deal about that person's history, such as places they have visited, whom they have contact with, products they have used, their activities and habits, or medications they have used. In some cases, corporations may use this information to target individuals with marketing customized towards those individual's personal preferences, which that person may or may not approve.
The ability to control the information one reveals about oneself over the internet and who can access that information has become a growing concern. These concerns include whether email can be stored or read by third parties without consent or whether third parties can continue to track the websites that someone visited. Another concern is whether websites one visits can collect, store, and possibly share personally identifiable information about users. The advent of various search engines and the use of data mining created a capability for data about individuals to be collected and combined from a wide variety of sources very easily. AI facilitated creating inferential information about individuals and groups based on such enormous amounts of collected data, transforming the information economy. The FTC has provided a set of guidelines that represent widely accepted concepts concerning fair information practices in an electronic marketplace, called the Fair Information Practice Principles. But these have been critiqued for their insufficiency in the context of AI-enabled inferential information.
On the internet many users give away a lot of information about themselves: unencrypted emails can be read by the administrators of an e-mail server if the connection is not encrypted (no TLS), and also the internet service provider and other parties sniffing the network traffic of that connection are able to know the contents. The same applies to any kind of traffic generated on the Internet, including web browsing, instant messaging, and others. In order not to give away too much personal information, emails can be encrypted and browsing of webpages as well as other online activities can be done anonymously via anonymizers, or by open source distributed anonymizers, so-called mix networks. Nym and I2P are examples of well-known mix nets. With social media and e-commerce sites being used more frequently, there are more potential openings for stealing consumer's data. Companies can see which types of products consumers like to purchase and can use targeted ads to try to make people purchase more items thinking that this is what they will want to purchase.
However, sometimes this type of data is used without explicit consent. Users are unaware of all of the personal information that is collected about them. Cookies track browsing data and location settings show where a person is based out of, and can show shops or products that are physically located near someone. These combined that be a big safety and privacy issue for users if their data is not being stored safely. With laws like the California Consumer Privacy Act (CCPA), people's data can be protected and they asked for explicit consent before using said data. Globally, many nations are trying to implement similar clauses to protect consumers. Email is not the only internet content with privacy concerns. In an age where increasing amounts of information are online, social networking sites pose additional privacy challenges. People may be tagged in photos or have valuable information exposed about themselves either by choice or unexpectedly by others, referred to as participatory surveillance. Data about location can also be accidentally published, for example, when someone posts a picture with a store as a background. Caution should be exercised when posting information online. Social networks vary in what they allow users to make private and what remains publicly accessible. Without strong security settings in place and careful attention to what remains public, a person can be profiled by searching for and collecting disparate pieces of information, leading to cases of cyberstalking or reputation damage. Cookies are used on websites so that users may allow the website to retrieve some information from the user's internet, but they usually do not mention what the data being retrieved is. In 2018, the General Data Protection Regulation (GDPR) passed a regulation that forces websites to visibly disclose to consumers their information privacy practices, referred to as cookie notices. This was issued to give consumers the choice of what information about their behavior they consent to letting websites track; however, its effectiveness is controversial. Some websites may engage in deceptive practices such as placing cookie notices in places on the page that are not visible or only giving consumers notice that their information is being tracked but not allowing them to change their privacy settings. Apps like Instagram and Facebook collect user data for a personalized app experience; however, they track user activity on other apps, which jeopardizes users' privacy and data. By controlling how visible these cookie notices are, companies can discreetly collect data, giving them more power over consumers.
People may not wish for their medical records to be revealed to others due to the confidentiality and sensitivity of what the information could reveal about their health. For example, they might be concerned that it might affect their insurance coverage or employment. Or, it may be because they would not wish for others to know about any medical or psychological conditions or treatments that would bring embarrassment upon themselves. Revealing medical data could also reveal other details about one's personal life. There are three major categories of medical privacy: informational (the degree of control over personal information), physical (the degree of physical inaccessibility to others), and psychological (the extent to which the doctor respects patients' cultural beliefs, inner thoughts, values, feelings, and religious practices and allows them to make personal decisions). Physicians and psychiatrists in many cultures and countries have standards for doctor–patient relationships, which include maintaining confidentiality. In some cases, the physician–patient privilege is legally protected. These practices are in place to protect the dignity of patients, and to ensure that patients feel free to reveal complete and accurate information required for them to receive the correct treatment. To view the United States' laws on governing privacy of private health information, see HIPAA and the HITECH Act. The Australian law is the Privacy Act 1988 Australia as well as state-based health records legislation.
Political privacy has been a concern since voting systems emerged in ancient times. The secret ballot is the simplest and most widespread measure to ensure that political views are not known to anyone other than the voters themselves—it is nearly universal in modern democracy and considered to be a basic right of citizenship. In fact, even where other rights of privacy do not exist, this type of privacy very often does. There are several forms of voting fraud or privacy violations possible with the use of digital voting machines.
The legal protection of the right to privacy in general – and of data privacy in particular – varies greatly around the world. Laws and regulations related to Privacy and Data Protection are constantly changing; it is seen as important to keep abreast of any changes in the law and to continually reassess compliance with data privacy and security regulations. Data protection laws across the globe aim to secure personal information and safeguard individual privacy in a digital era. The European Union's General Data Protection Regulation (GDPR) sets a high benchmark, emphasizing consent, transparency, and robust accountability by imposing strict penalties. Many countries adopt similar principles, mandating that organizations implement effective security measures, respect user rights, and notify breaches. In regions such as North America, Asia, and Oceania, data protection frameworks vary from sector-specific regulations to comprehensive legislation. Globally, these laws balance innovation with privacy, ensuring that personal data is appropriately accessible, managed ethically while mitigating misuse and cyber threats.
The United States Department of Commerce created the International Safe Harbor Privacy Principles certification program in response to the 1995 Directive on Data Protection (Directive 95/46/EC) of the European Commission. Both the United States and the European Union officially state that they are committed to upholding information privacy of individuals, but the former has caused friction between the two by failing to meet the standards of the EU's stricter laws on personal data. The negotiation of the Safe Harbor program was, in part, to address this long-running issue. Directive 95/46/EC declares in Chapter IV Article 25 that personal data may only be transferred from the countries in the European Economic Area to countries which provide adequate privacy protection. Historically, establishing adequacy required the creation of national laws broadly equivalent to those implemented by Directive 95/46/EU. Although there are exceptions to this blanket prohibition – for example where the disclosure to a country outside the EEA is made with the consent of the relevant individual (Article 26(1)(a)) – they are limited in practical scope. As a result, Article 25 created a legal risk to organizations which transfer personal data from Europe to the United States. The program regulates the exchange of passenger name record information between the EU and the US. According to the EU directive, personal data may only be transferred to third countries if that country provides an adequate level of protection. Some exceptions to this rule are provided, for instance when the controller themself can guarantee that the recipient will comply with the data protection rules. The European Commission has set up the "Working party on the Protection of Individuals with regard to the Processing of Personal Data," commonly known as the "Article 29 Working Party". The Working Party gives advice about the level of protection in the European Union and third countries. The Working Party negotiated with U.S. representatives about the protection of personal data, the Safe Harbor Principles were the result. Notwithstanding that approval, the self-assessment approach of the Safe Harbor remains controversial with a number of European privacy regulators and commentators. The Safe Harbor program addresses this issue in the following way: rather than a blanket law imposed on all organizations in the United States, a voluntary program is enforced by the Federal Trade Commission. U.S. organizations which register with this program, having self-assessed their compliance with a number of standards, are "deemed adequate" for the purposes of Article 25. Personal information can be sent to such organizations from the EEA without the sender being in breach of Article 25 or its EU national equivalents. The Safe Harbor was approved as providing adequate protection for personal data, for the purposes of Article 25(6), by the European Commission on 26 July 2000. Under the Safe Harbor, adoptee organizations need to carefully consider their compliance with the onward transfer obligations, where personal data originating in the EU is transferred to the US Safe Harbor, and then onward to a third country. The alternative compliance approach of "binding corporate rules", recommended by many EU privacy regulators, resolves this issue. In addition, any dispute arising in relation to the transfer of HR data to the US Safe Harbor must be heard by a panel of EU privacy regulators. In July 2007, a new, controversial, Passenger Name Record agreement between the US and the EU was made. A short time afterwards, the Bush administration gave exemption for the Department of Homeland Security, for the Arrival and Departure Information System (ADIS) and for the Automated Target System from the 1974 Privacy Act. In February 2008, Jonathan Faull, the head of the EU's Commission of Home Affairs, complained about the US bilateral policy concerning PNR. The US had signed in February 2008 a memorandum of understanding (MOU) with the Czech Republic in exchange of a visa waiver scheme, without concerting before with Brussels.
The tensions between Washington and Brussels are mainly caused by a lesser level of data protection in the US, especially since foreigners do not benefit from the US Privacy Act of 1974. Other countries approached for bilateral MOU included the United Kingdom, Estonia, Germany and Greece. There are techniques to improve privacy, privacy-enhancing technologies, and privacy software tools. People building and updating systems can use privacy by design and privacy engineering strategies and techniques. For example, by converting data into a non-readable format, encryption prevents unauthorized access.
Koopman, Colin (2019). How We Became Our Data: A Genealogy of the Informational Person. Chicago: University of Chicago Differential privacy (DP) is a framework for measuring the privacy guarantees provided by an algorithm. Through the lens of differential privacy, you can design machine learning algorithms that responsibly train models on private data. Learning with differential privacy provides measurable guarantees of privacy, helping to mitigate the risk of exposing sensitive training data in machine learning. Intuitively, a model trained with differential privacy should not be affected by any single training example, or small set of training examples, in its data set. This helps mitigate the risk of exposing sensitive training data in ML.
3. Software Implementation, Frameworks & Protocols The basic idea of this approach, called differentially private stochastic gradient descent (DP-SGD), is to modify the gradients used in stochastic gradient descent (SGD), which lies at the core of almost all deep learning algorithms. Models trained with DP-SGD provide provable differential privacy guarantees for their input data. There are two modifications made to the vanilla SGD algorithm: This tutorial uses tf.keras to train a convolutional neural network (CNN) to recognize handwritten digits with the DP-SGD optimizer provided by the TensorFlow Privacy library. TensorFlow Privacy provides code that wraps an existing TensorFlow optimizer to create a variant that implements DP-SGD.
DP-SGD has three privacy-specific hyperparameters and one existing hyperamater that you must tune: Use the hyperparameter values below to obtain a reasonably accurate model (95% test accuracy): Define the optimizer and loss function for the learning model. Compute the loss as a vector of losses per-example rather than as the mean over a minibatch to support gradient manipulation over each training point.
Perform a privacy analysis to measure the DP guarantee achieved by a training algorithm. Knowing the level of DP achieved enables the objective comparison of two training runs to determine which of the two is more privacy-preserving. At a high level, the privacy analysis measures how much a potential adversary can improve their guess about properties of any individual training point by observing the outcome of the training procedure (e.g., model updates and parameters).
This guarantee is sometimes referred to as the privacy budget . A lower privacy budget bounds more tightly an adversary's ability to improve their guess. This ensures a stronger privacy guarantee. Intuitively, this is because it is harder for a single training point to affect the outcome of learning: for instance, the information contained in the training point cannot be memorized by the ML algorithm and the privacy of the individual who contributed this training point to the dataset is preserved.
In this tutorial, the privacy analysis is performed in the framework of Rényi Differential Privacy (RDP), which is a relaxation of pure DP based on this paper that is particularly well suited for DP-SGD. Tensorflow Privacy provides a tool, compute_dp_sgd_privacy , to compute the value of \(\epsilon\) given a fixed value of \(\delta\) and the following hyperparameters from the training process: The tool reports that for the hyperparameters chosen above, the trained model has an \(\epsilon\) value of 1.18.
In this tutorial, you learned about differential privacy (DP) and how you can implement DP principles in existing ML algorithms to provide privacy guarantees for training data. In particular, you learned how to: code samples are licensed under the Apache 2.0 License . For details, see the Google Developers Site Policies . Java is a registered trademark of Oracle and/or its affiliates.
The increasing availability of personal data has enabled significant advances in fields such as machine learning, healthcare, and cybersecurity. However, this data abundance also raises serious privacy concerns, especially in light of powerful re-identification attacks and growing legal and ethical demands for responsible data use. Differential privacy (DP) has emerged as a principled, mathematically grounded framework for mitigating these risks. This review provides a comprehensive survey of DP, covering its theoretical foundations, practical mechanisms, and real-world applications. It explores key algorithmic tools and domain-specific challenges — particularly in privacy-preserving machine learning and synthetic data generation. The report also highlights usability issues and the need for improved communication and transparency in DP systems. Overall, the goal is to support informed adoption of DP by researchers and practitioners navigating the evolving landscape of data privacy.
Keywords: Differential Privacy, Machine Learning, Synthetic Data, Federated Learning, Cybersecurity, User Expectations Differential Privacy (DP), introduced by Dwork et al. (2006b) ; Dwork and Roth (2014) , is a rigorous mathematical framework for protecting individual privacy in data analysis, including machine learning. At its core, DP ensures that the result of an analysis — or the output of an algorithm — does not significantly change depending on whether any one individual’s data is included or not. This means that someone seeing the result cannot confidently tell if a particular individual’s data was used in the computation. This property makes DP particularly effective against re-identification attacks, even when an adversary has some prior knowledge about the individuals in the dataset. Such background knowledge, known as auxiliary information , may include partial information — such as age, ZIP code, or health condition — or access to other related datasets that, when combined with non-private outputs, could otherwise enable re-identification. As a result, DP is now widely regarded as the ”gold standard” for privacy protection, offering strong, quantifiable, and mathematically proven guarantees — rather than relying on ad-hoc anonymization techniques like removing names or masking values ( Ponomareva et al. (2023) ; Wagh et al.
(2021) ). In what follows, we present an in-depth survey of DP, covering its foundational principles, evolving methodologies, and diverse practical applications. Particular attention is given to challenges in usability and communication, as well as the need for interdisciplinary collaboration to ensure that DP systems are not only secure, but also understandable and adoptable by researchers, developers, and the general public. The document is structured to introduce foundational concepts and progressively explore more advanced techniques and applications, culminating in a discussion of user expectations and future directions in the field.
Section 2 : Motivation gives the motivation for DP by highlighting real-world privacy risks and failures of traditional anonymization methods. It presents examples such as linkage and membership inference attacks on public datasets, and illustrates why stronger guarantees are essential for protecting individual data. Section 3 : Definitions and Properties lays the theoretical foundation for the report, covering formal definitions of DP and core properties such as composition and post-processing. It also introduces different trust models — central, local, and distributed — which reflects different assumptions about trust and control over raw data, and noise mechanisms like the Laplace and Gaussian mechanisms, which form the basis for private data analysis.
4. Practical Deployment, Analysis & Case Studies Section 4 : Differential Privacy in Machine Learning shifts focus to machine learning, explaining how DP can be applied during model training. The chapter discusses the widely used DP-SGD algorithm and explores challenges such as balancing utility and privacy, hyperparameter tuning under privacy constraints, and the privacy accounting methods used to track cumulative privacy loss during training. As machine learning systems increasingly rely on sensitive data, integrating DP into training workflows is a critical step toward building trustworthy and ethically responsible AI models.
Section 5 : Understanding and Defining the Privacy Budget explores how to select and manage the privacy budget. It presents strategies for budgeting in practice, emphasizing the trade-offs between privacy and utility. In addition the chapter presents examples of privacy budgets used in real-world applications. A clear understanding of the privacy budget is essential for designing effective DP systems, as it directly influences both the level of protection offered and the practical usability of the resulting data or models.
Section 6 : Privacy-Preserving Synthetic Data addresses synthetic data generation using DP. It introduces a taxonomy of DP-based methods, including histogram and marginal-based techniques, probabilistic graphical models, and deep generative models. The chapter also examines how to evaluate the utility and privacy of synthetic datasets and highlights key challenges such as representation bias and fairness concerns that may arise when deploying DP-generated synthetic data. Despite these challenges, DP-based synthetic data holds strong potential for enabling safe data sharing and analysis, particularly in domains where direct access to real data is restricted.
Section 7 : Enhancing Differential Privacy examines the combination of DP with complementary technologies to meet both privacy and utility requirements. We focus on three key directions: the integration of DP with cryptographic techniques, the application of DP in federated learning (FL), and hybrid approaches that jointly leverage FL, cryptographic techniques, and DP. These combinations are especially promising, as they open new pathways for building robust, privacy-preserving systems that remain practical and effective in real-world, distributed environments.
Section 8 : Use Cases of Differential Privacy explores a range of scenarios in which DP plays a vital role in enabling privacy-preserving data sharing and computation. The chapter begins with applications in cybersecurity, with a focus on cyber-physical systems (CPS), anomaly detection, and face recognition, where DP reduces risks in sensitive and high-stakes environments. It then turns to the healthcare and finance sectors — both highly data-intensive and privacy-sensitive — and examines how DP supports secure analytics while meeting regulatory and ethical requirements. Collectively, these case studies demonstrate the versatility and growing relevance of DP in real-world systems.
Section 9 : Practicalities and User Expectations examines how users and practitioners perceive and interact with DP in practical contexts. It covers insights from empirical studies on communication strategies, implementation challenges, the risks of creating a false sense of privacy (”privacy theater”), and uncertainties around regulation. The chapter emphasizes the importance of bridging the gap between formal guarantees and real-world deployment to build trust, enhance usability, and support effective, privacy-conscious decision-making.
Section 10 : Future Trends and Research Directions outlines key directions for future research in DP, emphasizing the need for scalable and efficient DP-training methods, especially for complex machine learning models. It highlights emerging areas such as the integration of DP with federated learning and cryptographic techniques, the development of advanced privacy mechanisms and accounting methods, and personalized privacy frameworks. The chapter also identifies challenges in applying DP to modern architectures like transformers and large language models, and stresses the importance of robust privacy auditing, explainability, and fairness-aware design. Together, these themes point toward a more adaptable, transparent, and practically deployable future for DP.
The papers reviewed in this study were primarily collected from Scopus , IEEE Explorer , and Google Scholar using search strings such as ’differential privacy & machine learning’, ’differential privacy & syntetic data’, ’differential privacy & cybersecurity’, and other related keywords. These search terms were chosen to ensure comprehensive coverage of the relevant literature in the field.
In an era defined by data, organizations across all sectors — government agencies, healthcare providers, research institutions, and technology companies — routinely collect and analyze vast amounts of personal information. This data, which includes census and health records, behavioral logs, social media activity, sensor data from connected devices, and cybersecurity telemetry, enables insights that drive innovation, improve services, combat fraud, and inform policy decisions.
However, the abundance of such data brings growing concerns over individual privacy. High-profile data breaches, misuse of personal information, and increasing public awareness have raised questions about how to responsibly extract value from data without compromising the privacy of individuals it represents. At the same time, regulations such as the General Data Protection Regulation (GDPR, The European Union (2016) ) and other data protection laws worldwide have introduced stricter requirements for privacy, transparency, and accountability.
Alongside legal pressures and growing public concern, there is a parallel demand for reproducible science, transparent decision-making, and — in some cases — open or controlled data access, especially in data-driven domains such as healthcare, finance, and machine learning. These goals often conflict with the need to protect privacy, creating a pressing need for techniques that can reconcile utility with confidentiality. As a result, privacy-preserving data analysis is no longer a theoretical luxury — it is a practical necessity. Striking a balance between data utility and individual privacy has become a central challenge for organizations tasked with releasing or analyzing sensitive data.
Traditional approaches to protecting privacy, such as de-identification and access control , have proven inadequate to face modern adversaries equipped with powerful computational tools and vast auxiliary datasets. De-identification typically refers to the removal or masking of direct identifiers (such as names or social security numbers) from datasets in an effort to anonymize them. However, this process often retains quasi-identifiers — like ZIP code, birth date, and gender — that can still be used for re-identification when combined with external data. Access control, by contrast, limits who can view or query a dataset, often through authentication, authorization, or secure data enclaves. While effective in some contexts, access control does not fundamentally mitigate privacy risks once data is released or aggregated statistics are shared. Multiple high-profile re-identification attacks have demonstrated that seemingly anonymous data can be traced back to individuals when combined with publicly available information. These attacks — each illustrated with representative examples — include the following: Linkage Attacks combine anonymized data with external auxiliary information to re-identify individuals. Sweeney (1997) famously re-identified medical records using voter registration data, demonstrating how quasi-identifiers like ZIP code, birth date, and gender can be used to re-link de-identified datasets to individuals. Similarly, the Netflix Prize dataset was shown to be vulnerable to linkage attacks using auxiliary information from IMDb ( Narayanan and Shmatikov (2008) ).
Reconstruction Attacks aim to infer the original sensitive dataset by exploiting the outputs of a data release or model, often by querying it many times. Dinur and Nissim (2003) demonstrated that releasing too many highly accurate statistics allows an adversary to reconstruct a large portion of the original dataset. This foundational result has been further strengthened and generalized in subsequent work, including Dwork et al. (2007) , Dwork and Yekhanin (2008) , and Choromanski and Malkin (2012) . A striking real-world example occurred with the 2010 U.S. Census, where researchers at the Census Bureau were able to reconstruct individual-level records from published statistical summaries, prompting the agency to adopt DP for future data releases ( Garfinkel et al. (2019) ). These examples illustrate what has come to be known informally as the Fundamental Law of Information Recovery ( Dwork and Roth (2014) ) — the principle that overly accurate answers to too many queries can destroy privacy.
Differencing Attacks infer sensitive information by comparing the outputs of aggregate queries that differ by only a single individual. A classic method is the “tracker attack” described by Denning et al. (1979) , where carefully constructed queries bypassed suppression rules to isolate individual values. A modern example was demonstrated on Facebook’s advertising platform, where an attacker could infer sensitive traits — such as sexual orientation or medical conditions — by crafting highly specific target audiences and comparing differences in ad reach statistics ( Korolova (2010) ; Venkatadri et al. (2018) ).
Membership Inference Attacks aim to determine whether a specific individual’s data is included in a dataset or has been used to train a machine learning model. An early example by Homer et al. (2008b) demonstrated that it is possible to identify whether an individual contributed DNA to a mixture used in genetic studies, using statistical distance measures to assess their presence. Since then, membership inference attacks have been observed in a variety of contexts, including genomic research ( Simmons and Berger (2016) ), aggregate location data ( Zang and Bolot (2011) ), and deep learning models ( Shokri et al.
(2017) ). These examples reveal that privacy breaches are not merely theoretical possibilities — they pose concrete threats in real-world systems. Moreover, traditional anonymization techniques and ad hoc privacy safeguards often lack rigorous methods for quantifying cumulative privacy risk across multiple analyses or data releases. They often fail to account for an adversary’s background knowledge and offer limited protection against adaptive or future attacks.
In response to these risks, DP has emerged as a rigorous, future-proof framework for quantifying and controlling privacy loss ( Dwork et al. (2006b) ; Dwork and Roth (2014) ). DP formalizes the idea that the outcome of an analysis should be (nearly) equally likely whether or not any single individual’s data is included. This ensures that no individual can be harmed --- or benefit --- significantly from participating in a dataset, offering a strong form of privacy regardless of auxiliary information available to an adversary 1 1 1 Note that harm may still result from the outcome of the analysis (e.g., increased insurance rates for smokers), but such harm does not depend on whether any particular individual participated in the dataset — a classic example being the ”smoking man” scenario ( Dwork and Roth (2014) ). .
5. Performance Evaluation & Extended Technical Observations DP is particularly well-suited to the challenges of modern data release and machine learning: It provides strong theoretical privacy guarantees , quantifying worst-case disclosure risk in a mathematically rigorous way. It provides composability , allowing the cumulative privacy risk across multiple queries to be formally bounded.
It is resilient to post-processing , meaning that further manipulation of the results does not compromise privacy guarantees. It is future-proof , offering protection even as external datasets grow and attack methods evolve. Due to these properties, DP has been adopted by major organizations such as Google ( Google Research (2023) ), Apple ( Apple Inc. (2017) ; Apple Inc. (2022) ), Microsoft ( Ding et al. (2017) ), and the U.S. Census Bureau ( U.S Census (2021d) ).
These real-world deployments underscore the importance of DP as a practical tool for enabling data analytics and machine learning while safeguarding personal information. However, the path to practical deployment remains challenging, with issues including the privacy-utility trade-off, parameter setting, user understanding, and communication of guarantees. In this section, we present the formal foundations of differential privacy (DP), along with its most important theoretical properties. We begin by introducing the standard definition of DP and then examine several well-established relaxations that extend its applicability in practical settings. The section also introduces the concept of the privacy budget , which quantifies the cumulative privacy loss (and will be further analysed in Section 5 ), and examines various trust models that influence where and how DP mechanisms are deployed within a system. Finally, we discuss commonly used randomization mechanisms that satisfy DP, highlighting their mathematical guarantees.
A differentially private algorithm provides a formal guarantee that limits how much its behavior can change when a single individual’s data is added to or removed from the dataset. This guarantee holds universally for every individual and every dataset. In practice, this means that, under reasonably strong privacy limits, even if a malicious adversary gains access to the output of an algorithm, they cannot determine with high confidence whether a particular individual’s data was included in the dataset. In other words, the presence or absence of any single record has only a bounded impact on the overall output, which provides strong plausible deniability for individuals. An attacker — even with substantial auxiliary information — will find it difficult to infer sensitive details about any one person, because the algorithm’s output remains nearly the same regardless of that person’s data.
At its core, DP provides privacy by process , achieved by introducing randomness into computations. In what follows, we present the relevant notation and formal definitions of DP. Mathematical Notations and Definitions: Let I \mathcal{D} be a potentially infinite universe of datasets and let D ⊂ I D\subset\mathcal{D} be a dataset consisting of n n records. Let f f be a (query) function that takes a dataset as input and outputs a quantity of interest. For example, f f may compute the mean of a specific feature or, more complexly, train a deep neural network and return the network’s weights. We next define the mechanism, neighboring datasets, and the notion of ε \varepsilon -DP. In addition, the notations used in this paper are collected in Table 1 .
Mechanism I : I → I \mathcal{A}:\mathcal{D}\rightarrow\mathcal{R} is a randomized algorithm that approximates the result of the function f f . It operates on a dataset D ⊂ I D\subset\mathcal{D} and returns a value in the range R R . Two datasets D , D ′ ⊂ I D,D^{\prime}\subset\mathcal{D} are said to be neighbors, denoted D ∼ D ′ D\sim D^{\prime} , if D ⊂ D ′ D\subset D^{\prime} and | D ′ | = | D | + 1 |D^{\prime}|=|D|+1 (or vice versa).
This means that D D and D ′ D^{\prime} are neighbors, if D ′ D^{\prime} is a copy of D D with one record added or removed (the add-or-remove criterion). Note that this definition changes the size of the dataset, which may cause some complications when applying it ( Ponomareva et al. (2023) ). Alternatively, some definitions adopt the replace-one criterion ( Vadhan and Lindell (2017) ) — where one record is replaced with a different record — or the zero-out criterion ( Erlingsson et al. (2020) ; Kairouz et al. (2021a) ) — where one record is set to a default ” zero ” value — both of which keep the dataset size unchanged but result in slightly different privacy guarantees. The formal definition of DP works with any of these neighboring relations; here, we adopt the add-or-remove notion for consistency with the original formulation by Dwork et al. (2006b) , and we will return to the implications of the alternative definitions later.
For ε > 0 \varepsilon>0 , a mechanism I : I → R \mathcal{A}:\mathcal{D}\rightarrow R satisfies ε \varepsilon -DP if, for any two neighboring datasets D ∼ D ′ ⊂ I D\sim D^{\prime}\subset\mathcal{D} and any set S ⊆ R S\subseteq R of possible outputs, the following holds: Here, P I [ ⋅ ] P[\cdot] denotes the probability measure over the randomness inherent in the mechanism I \mathcal{A} .
In other words, I \mathcal{A} is ε \varepsilon -differentially private if the inclusion or exclusion of any single individual’s data in the dataset changes the likelihood of any particular output by no more than a multiplicative factor of exp I ( ε ) \exp(\varepsilon) . A smaller ε \varepsilon indicates stronger privacy — meaning that the output of I \mathcal{A} is less sensitive to the data of any individual — while a larger ε \varepsilon implies weaker privacy guarantees ( Dwork and Roth (2014) ). In particular, when ε = 0 \varepsilon=0 , the output becomes completely independent of the input, rendering the analysis meaningless. The optimal choice of ε \varepsilon depends on the application: for common statistical queries (e.g., computing a mean), ε \varepsilon is typically chosen to be less than 1, whereas in deep learning scenarios, this choice is often relaxed to ε = 10 \varepsilon=10 ( Ponomareva et al. (2023) ). We discuss the selection of the privacy budget in Section 5 .
Unit of Privacy: The choice of what constitutes a ” record ” in Definition 2 is central to interpreting Definition 3 . The level at which the privacy guarantee is applied is referred to as the unit of privacy . In example-level ( sample-level or instance-level ) DP , each individual data entry (e.g., a row in the dataset) is treated as sensitive, ensuring that the addition or removal of a single entry does not significantly affect the output of the algorithm.
In contrast, user-level DP (often called client-level privacy in federated learning) protects all data contributed by a single user — even if it consists of multiple entries — by ensuring that the collective impact of that user’s data is limited. This distinction is crucial in scenarios where a user contributes multiple data points, as user-level privacy offers a stronger and more comprehensive protection compared to example-level guarantees.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Differential%20privacy • https://en.wikipedia.org/wiki/Differentially%20private%20stochastic%20gradient%20descent • https://en.wikipedia.org/wiki/Information%20privacy • https://www.tensorflow.org/responsible_ai/privacy/tutorials/classification_privacy • https://arxiv.org/html/2509.03294v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Differential Privacy Implementation For Sensitive Datasets.
[*] Metasploit Scan Running on Target Subnet for Differential Privacy Implementation For Sensitive Datasets... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |