Complete Technical Paper Content — Edge Computing Security And Access Control In IoT
Overview & System Context
Edge Computing Security And Access Control In Iot: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9603 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Edge computing is a distributed computing model that brings computation and data storage closer to the sources of data.
More broadly, it refers to any design that pushes computation physically closer to a user, so as to reduce the latency compared to when an application runs on a centralized data center. The term began being used in the 1990s to describe content delivery networks—these were used to deliver website and video content from servers located near users. In the early 2000s, these systems expanded their scope to hosting other applications, leading to early edge computing services. These services could do things like find dealers, manage shopping carts, gather real-time data, and place ads. The Internet of things (IoT), where devices are connected to the Internet, is often linked with edge computing.
A secure access service edge (SASE) (also secure access secure edge) is technology used to deliver wide area network (WAN) and security controls as a cloud computing service directly to the source of connection (user, device, Internet of things (IoT) device, or edge computing location) rather than a data center. It uses cloud and edge computing technologies to reduce the latency that results from backhauling all WAN traffic over long distances to one or a few corporate data centers, due to the increased movement off-premises of dispersed users and their applications. This also helps organizations support dispersed users. Security is based on digital identity, real-time context, and company and regulatory compliance policies, rather than a security appliance like a firewall. A digital identity may be attached to anything from a person to a device, cloud service, application software, IoT system, or any computing system. The term was coined in 2019 by market analyst, Neil MacDonald of Gartner.
Convergence of WAN and network security functions. A cloud-native architecture delivering converged WAN and security as a service that offers the scalability, elasticity, adaptability and self-healing typical of all cloud services. Globally distributed fabric of PoPs delivering a full range of WAN and security capabilities with low latency, wherever business offices, cloud applications and mobile users are located. To deliver low latency at any location, SASE PoPs have to be more numerous and extensive than those offered by typical public cloud providers and SASE providers must have extensive peering relationships.
Identity-driven services. An identity can be attached to anything from a person or branch office to a device, application, service, IoT device or edge computing location at the source of connection. Identity is the most significant context affecting SASE security policy. However, location, time of day, risk/trust posture of the connecting device and application and data sensitivity will provide other real-time context determining the security services and policies applied to and throughout each WAN session. Support for all edges equally, including physical locations, cloud data centers, users’ mobile devices and edge computing, with placement of all capabilities at the local PoP rather than the edge location. Edge connections to the local PoP may vary from an SD-WAN for a branch office to a VPN client or clientless Web access for a mobile user, to multiple tunnels from the cloud or direct cloud connections inside a global data center. Gartner and others promote a SASE architecture for the mobile, cloud enabled enterprise. Benefits include: SD-WAN is a technology that simplifies wide area networking through centralized control of the networking hardware or software that directs traffic across the WAN. It also allows organizations to combine or replace private WAN connections with Internet broadband, LTE and/or 5g connections. Organizations may also incorporate fixed wireless access and multi-carrier connectivity strategies to improve network resilience and maintain uptime across geographically distributed locations. The central controller sets policies and prioritizes, optimizes and routes WAN traffic, selecting the best link and path dynamically for optimum performance. SD-WAN vendors may offer some security functions with their SD-WAN virtual or physical appliances, which are typically deployed at the data center or branch office. Typically SASE incorporates SD-WAN as part of a cloud service that also delivers mobile access and a full security stack delivered from a local PoP.
Figure 1: Connecting Industrial Iot Devices At The Edge – MPHG NGFW combines a traditional firewall with other security and networking functions geared to the virtualized data center. Security functions include application control, deep and encrypted packet inspection, intrusion prevention, Web site filtering, anti-malware, identity management, threat intelligence and even WAN quality of service and bandwidth management. NGFW offers a subset of the security stack offered by SASE, and typically doesn't include SD-WAN services. NGFW may be deployed on premises or as a cloud service, while SASE is a cloud architecture by definition. While SASE focuses security on WAN connections, a NGFW can be deployed anywhere including internally in the data center.
FWaaS is a firewall offered as a cloud service, rather than on premises as software or hardware. Most FWaaS providers offer NGFW capabilities. Typically, an entire organization is connected to a single FWaaS cloud with no requirement for maintaining its own firewall infrastructure. SASE combines edge FWaaS with other security functions and SD-WAN. SASE and NaaS overlap in concept. NaaS delivers virtualized network infrastructure and services using a cloud subscription business model. Like SASE it offers reduced complexity and management costs. Typically, different NaaS providers offer different service packages, such as a package of WAN and secure VPNs as a service, bandwidth on demand, or hosted networks as a service. By contrast SASE is meant to be a single comprehensive secure SD-WAN solution for branch offices, mobile users, data centers and any other secure enterprise WAN requirement.
Cloud computing is defined by the International Organization for Standardization (ISO) as "a paradigm for enabling network access to a scalable and elastic pool of shareable physical or virtual resources with self-service provisioning and administration on demand". It is commonly referred to as "the cloud". Figure 2: Bridging The Iot Computing Gap: Edge Compute, Iot Gateways, And Aws – DILRF On-demand self-service: "A consumer can unilaterally provision computing capabilities, such as server time and network storage, as needed automatically without requiring human interaction with each service provider." Broad network access: "Capabilities are available over the network and accessed through standard mechanisms that promote use by heterogeneous thin or thick client platforms (e.g., mobile phones, tablets, laptops, and workstations)." Resource pooling: " The provider's computing resources are pooled to serve multiple consumers using a multi-tenant model, with different physical and virtual resources dynamically assigned and reassigned according to consumer demand." Rapid elasticity: "Capabilities can be elastically provisioned and released, in some cases automatically, to scale rapidly outward and inward commensurate with demand. To the consumer, the capabilities available for provisioning often appear unlimited and can be appropriated in any quantity at any time." Measured service: "Cloud systems automatically control and optimize resource use by leveraging a metering capability at some level of abstraction appropriate to the type of service (e.g., storage, processing, bandwidth, and active user accounts). Resource usage can be monitored, controlled, and reported, providing transparency for both the provider and consumer of the utilized service. By 2023, the International Organization for Standardization (ISO) had expanded and refined the list.
The history of cloud computing extends to the 1960s, with the initial concepts of time-sharing becoming popularized via remote job entry (RJE). The "data center" model, where users submitted jobs to operators to run on mainframes, was predominantly used during this era. This period saw broad experimentation with making large-scale computing power more accessible through time-sharing, while optimizing infrastructure, platforms, and applications to improve efficiency for end users. The "cloud" metaphor for virtualized services dates to 1994, when it was used by General Magic for the universe of "places" that mobile agents in the Telescript environment could "go". The metaphor is credited to David Hoffman, a General Magic communications specialist, based on its long-standing use in networking and telecom. The expression cloud computing became more widely known in 1996 when Compaq Computer Corporation drew up a business plan for future computing and the Internet. The company's ambition was to supercharge sales with "cloud computing-enabled applications". The business plan foresaw that online consumer file storage would likely be commercially successful. As a result, Compaq decided to sell server hardware to internet service providers. In the 2000s, the application of cloud computing began to take shape with the establishment of Amazon Web Services (AWS) in 2002, which allowed developers to build applications independently. In 2006 Amazon Simple Storage Service, known as Amazon S3, and the Amazon Elastic Compute Cloud (EC2) were released.
The following decade saw the launch of various cloud services. In 2010, Microsoft launched Microsoft Azure, and Rackspace Hosting and NASA initiated an open-source cloud-software project, OpenStack. IBM introduced the IBM SmartCloud framework in 2011, and Oracle announced the Oracle Cloud in 2012. In December 2019, Amazon launched AWS Outposts, a service that extends AWS infrastructure, services, APIs, and tools to customer data centers, co-location spaces, or on-premises facilities.
Cloud computing can shorten time to market by offering pre-configured tools, scalable resources, and managed services, allowing users to focus on core business value rather than maintaining infrastructure. Cloud platforms can enable organizations and individuals to reduce upfront capital expenditures on physical infrastructure by shifting to an operational expenditure model, where costs scale with usage. Cloud platforms also offer managed services and tools, such as artificial intelligence, data analytics, and machine learning, which might otherwise require significant in-house expertise and infrastructure investment. While cloud computing can offer cost advantages through effective resource optimization, organizations often face challenges such as unused resources, inefficient configurations, and hidden costs without proper oversight and governance. Many cloud platforms provide cost management tools, such as AWS Cost Explorer and Azure Cost Management, and frameworks like FinOps have emerged to standardize financial operations in the cloud. Cloud computing also facilitates collaboration, remote work, and global service delivery by enabling secure access to data and applications from any location with an internet connection. Cloud providers offer various redundancy options for core services, such as managed storage and managed databases, though redundancy configurations often vary by service tier. Advanced redundancy strategies, such as cross-region replication or failover systems, typically require explicit configuration and may incur additional costs or licensing fees. Cloud environments operate under a shared responsibility model, where providers are typically responsible for infrastructure security, physical hardware, and software updates, while customers are accountable for data encryption, identity and access management (IAM), and application-level security. These responsibilities vary depending on the cloud service model—Infrastructure as a Service (IaaS), Platform as a Service (PaaS), or Software as a Service (SaaS)—with customers typically having more control and responsibility in IaaS environments and progressively less in PaaS and SaaS models, often trading control for convenience and managed services.
The decision to adopt cloud computing or maintain on-premises infrastructure depends on factors such as scalability, cost structure, latency requirements, regulatory constraints, and infrastructure customization. Organizations with variable or unpredictable workloads, limited capital for upfront investments, or a focus on rapid scalability benefit from cloud adoption. Startups, SaaS companies, and e-commerce platforms often prefer the pay-as-you-go operational expenditure (OpEx) model of cloud infrastructure. Additionally, companies prioritizing global accessibility, remote workforce enablement, disaster recovery, and leveraging advanced services such as AI/ML and analytics are well-suited for the cloud. In recent years, some cloud providers have started offering specialized services for high-performance computing and low-latency applications, addressing some use cases previously exclusive to on-premises setups. On the other hand, organizations with strict regulatory requirements, highly predictable workloads, or reliance on deeply integrated legacy systems may find cloud infrastructure less suitable. Businesses in industries like defense, government, or those handling highly sensitive data often favor on-premises setups for greater control and data sovereignty. Additionally, companies with ultra-low latency requirements, such as high-frequency trading (HFT) firms, rely on custom hardware (e.g., FPGAs) and physical proximity to exchanges, which most cloud providers cannot fully replicate despite recent advancements. Similarly, tech giants like Google, Meta, and Amazon build their own data centers due to economies of scale, predictable workloads, and the ability to customize hardware and network infrastructure for optimal efficiency. However, these companies also use cloud services selectively for certain workloads and applications where it aligns with their operational needs. In practice, many organizations are increasingly adopting hybrid cloud architectures, combining on-premises infrastructure with cloud services. This approach allows businesses to balance scalability, cost-effectiveness, and control, offering the benefits of both deployment models while mitigating their respective limitations.
Figure 3: Edge computing code for control, surveillance and visualization... One of the primary challenges of cloud computing, compared with traditional on-premises systems, is maintaining data security and privacy. Cloud users entrust their sensitive data to third-party providers, who may not have adequate measures to protect it from unauthorized access, breaches, or leaks. Cloud users also face compliance risks if they have to adhere to certain regulations or standards regarding data protection, such as GDPR or HIPAA. Another challenge of cloud computing is reduced visibility and control. Cloud users may not have full insight into how their cloud resources are managed, configured, or optimized by their providers. They may also have limited ability to customize or modify their cloud services according to their specific needs or preferences. Complete understanding of all technology may be impossible, especially given the scale, complexity, and deliberate opacity of contemporary systems; however, there is a need for understanding complex technologies and their interconnections to have power and agency within them. The metaphor of the cloud can be seen as problematic as cloud computing retains the aura of something noumenal and numinous; it is something experienced without precisely understanding what it is or how it works. Additionally, cloud migration is a significant challenge. This process involves transferring data, applications, or workloads from one cloud environment to another, or from on-premises infrastructure to the cloud. Cloud migration can be complicated, time-consuming, and expensive, particularly when there are compatibility issues between different cloud platforms or architectures. If not carefully planned and executed, cloud migration can lead to downtime, reduced performance, or even data loss.
"Understanding application dependencies" "Comparing on-premise and cloud costs" "Assessing technical feasibility." 2. System Architecture & Core Working Principles Cloud computing poses privacy concerns because the service provider can access the data that is in the cloud at any time. It could accidentally or deliberately alter or delete information. Many cloud providers can share information with third parties if necessary for purposes of law and order without a warrant. That is permitted in their privacy policies, which users must agree to before they start using cloud services. Solutions to privacy include policy and legislation as well as end-users' choices for how data is stored. Users can encrypt data that is processed or stored within the cloud to prevent unauthorized access.
Identity management systems can also provide practical solutions to privacy concerns in cloud computing. These systems distinguish between authorized and unauthorized users and determine the amount of data that is accessible to each entity. The systems work by creating and describing identities, recording activities, and getting rid of unused identities. According to the Cloud Security Alliance, the top three threats in the cloud are Insecure Interfaces and APIs, Data Loss & Leakage, and Hardware Failure—which accounted for 29%, 25% and 10% of all cloud security outages respectively. Together, these form shared technology vulnerabilities. In a cloud provider platform being shared by different users, there may be a possibility that information belonging to different customers resides on the same data server. Additionally, Eugene Schultz, chief technology officer at Emagined Security, said that hackers are spending substantial time and effort looking for ways to penetrate the cloud. "There are some real Achilles' heels in the cloud infrastructure that are making big holes for the bad guys to get into".
Because data from hundreds or thousands of companies can be stored on large cloud servers, hackers can theoretically gain control of huge stores of information through a single attack—a process he called "hyperjacking". Some examples of this include the Dropbox security breach, and iCloud 2014 leak. Dropbox had been breached in October 2014, having over seven million of its users passwords stolen by hackers in an effort to get monetary value from it by Bitcoins (BTC). By having these passwords, they are able to read private data as well as have this data be indexed by search engines (making the information public). There is the problem of legal ownership of the data (If a user stores some data in the cloud, can the cloud provider profit from it?). Many Terms of Service agreements are silent on the question of ownership. Physical control of the computer equipment (private cloud) is more secure than having the equipment off-site and under someone else's control (public cloud).
This delivers great incentive to public cloud computing service providers to prioritize building and maintaining strong management of secure services. Some small businesses that do not have expertise in IT security could find that it is more secure for them to use a public cloud. There is the risk that end users do not understand the issues involved when signing on to a cloud service (persons sometimes do not read the many pages of the terms of service agreement, and just click "Accept" without reading). This is important now that cloud computing is common and required for some services to work, for example for an intelligent personal assistant (Apple's Siri or Google Assistant). Fundamentally, private cloud is seen as more secure with higher levels of control for the owner, however public cloud is seen to be more flexible and requires less time and money investment from the user. The attacks that can be made on cloud computing systems include man-in-the middle attacks, phishing attacks, authentication attacks, and malware attacks. One of the largest threats is considered to be malware attacks, such as Trojan horses. Recent research conducted in 2022 has revealed that the Trojan horse injection method is a serious problem with harmful impacts on cloud computing systems.
The CLOUD Act allows United States authorities to request data from cloud providers, and courts can impose nondisclosure requirements preventing providers from notifying affected users. This framework is in legal tension with Article 48 of the European General Data Protection Regulation (GDPR), which restricts the transfer of personal data in response to foreign court or administrative orders unless based on an international agreement. As a result, cloud service providers operating in both Europe and the U.S. may face competing legal obligations. According to Laura K. Donohue writing for the Harvard Journal of Law and Public Policy, cloud service providers also fall within the broader category of service providers subject to Section 702 of the Foreign Intelligence Surveillance Act (FISA), which has had documented effects on cloud providers and their customers.
The National Institute of Standards and Technology recognized three cloud service models in 2011: Infrastructure as a Service (IaaS), Platform as a Service (PaaS), and Software as a Service (SaaS). The International Organization for Standardization (ISO) later identified additional models in 2023, including "Network as a Service", "Communications as a Service", "Compute as a Service", and "Data Storage as a Service".
Infrastructure as a service (IaaS) refers to online services that provide high-level APIs used to abstract various low-level details of underlying network infrastructure like physical computing resources, location, data partitioning, scaling, security, backup, etc. A hypervisor runs the virtual machines as guests. Pools of hypervisors within the cloud operational system can support large numbers of virtual machines and the ability to scale services up and down according to customers' varying requirements. Linux containers run in isolated partitions of a single Linux kernel running directly on the physical hardware.
Linux cgroups and namespaces are the underlying Linux kernel technologies used to isolate, secure and manage the containers. The use of containers offers higher performance than virtualization because there is no hypervisor overhead. IaaS clouds often offer additional resources such as a virtual-machine disk-image library, raw block storage, file or object storage, firewalls, load balancers, IP addresses, virtual local area networks (VLANs), and software bundles.
The NIST's definition of cloud computing describes IaaS as "where the consumer is able to deploy and run arbitrary software, which can include operating systems and applications. The consumer does not manage or control the underlying cloud infrastructure but has control over operating systems, storage, and deployed applications; and possibly limited control of select networking components (e.g., host firewalls)." IaaS-cloud providers supply these resources on-demand from their large pools of equipment installed in data centers. For wide-area connectivity, customers can use either the Internet or carrier clouds (dedicated virtual private networks). To deploy their applications, cloud users install operating-system images and their application software on the cloud infrastructure. In this model, the cloud user patches and maintains the operating systems and the application software. Cloud providers typically bill IaaS services on a utility computing basis: cost reflects the number of resources allocated and consumed.
The capability provided to the consumer is to deploy onto the cloud infrastructure consumer-created or acquired applications created using programming languages, libraries, services, and tools supported by the provider. The consumer does not manage or control the underlying cloud infrastructure including network, servers, operating systems, or storage, but has control over the deployed applications and possibly configuration settings for the application-hosting environment. PaaS vendors offer a development environment to application developers. The provider typically develops toolkit and standards for development and channels for distribution and payment. In the PaaS models, cloud providers deliver a computing platform, typically including an operating system, programming-language execution environment, database, and the web server.
Application developers develop and run their software on a cloud platform instead of directly buying and managing the underlying hardware and software layers. With some PaaS, the underlying computer and storage resources scale automatically to match application demand so that the cloud user does not have to allocate resources manually. Some integration and data management providers also use specialized applications of PaaS as delivery models for data. Examples include iPaaS (Integration Platform as a Service) and dPaaS (Data Platform as a Service). iPaaS enables customers to develop, execute and govern integration flows. Under the iPaaS integration model, customers drive the development and deployment of integrations without installing or managing any hardware or middleware. dPaaS delivers integration—and data-management—products as a fully managed service. Under the dPaaS model, the PaaS provider, not the customer, manages the development and execution of programs by building data applications for the customer. dPaaS users access data through data-visualization tools.
The capability provided to the consumer is to use the provider's applications running on a cloud infrastructure. The applications are accessible from various client devices through either a thin client interface, such as a web browser (e.g., web-based email), or a program interface. The consumer does not manage or control the underlying cloud infrastructure including network, servers, operating systems, storage, or even individual application capabilities, with the possible exception of limited user-specific application configuration settings. In the software as a service (SaaS) model, users gain access to application software and databases. Cloud providers manage the infrastructure and platforms that run the applications. SaaS is sometimes referred to as "on-demand software" and is usually priced on a pay-per-use basis or using a subscription fee. In the SaaS model, cloud providers install and operate application software in the cloud and cloud users access the software from cloud clients. Cloud users do not manage the cloud infrastructure and platform where the application runs. This eliminates the need to install and run the application on the cloud user's own computers, which simplifies maintenance and support. Cloud applications differ from other applications in their scalability—which can be achieved by cloning tasks onto multiple virtual machines at run-time to meet changing work demand. Load balancers distribute the work over the set of virtual machines. This process is transparent to the cloud user, who sees only a single access-point. To accommodate a large number of cloud users, cloud applications can be multitenant, meaning that any machine may serve more than one cloud-user organization. The pricing model for SaaS applications is typically a monthly or yearly flat fee per user, so prices become scalable and adjustable if users are added or removed at any point. It may also be free. Proponents claim that SaaS gives a business the potential to reduce IT operational costs by outsourcing hardware and software maintenance and support to the cloud provider. This enables the business to reallocate IT operations costs away from hardware/software spending and from personnel expenses, towards meeting other goals. In addition, with applications hosted centrally, updates can be released without the need for users to install new software. One drawback of SaaS comes with storing the users' data on the cloud provider's server. As a result, there could be unauthorized access to the data. Examples of applications offered as SaaS are games and productivity software like Google Docs and Office Online. SaaS applications may be integrated with cloud storage or File hosting services, which is the case with Google Docs being integrated with Google Drive, and Office Online being integrated with OneDrive.
Serverless computing allows customers to use various cloud capabilities without the need to provision, deploy, or manage hardware or software resources, apart from providing their application code or data. ISO/IEC 22123-2:2023 classifies serverless alongside Infrastructure as a Service (IaaS), Platform as a Service (PaaS), and Software as a Service (SaaS) under the broader category of cloud service categories. Notably, while ISO refers to these classifications as cloud service categories, the National Institute of Standards and Technology (NIST) refers to them as service models.
"A cloud deployment model represents the way in which cloud computing can be organized based on the control and sharing of physical or virtual resources." Cloud deployment models define the fundamental patterns of interaction between cloud customers and cloud providers. They do not detail implementation specifics or the configuration of resources. Cloud services are considered "public" when they are delivered over the public Internet, and they may be offered as a paid subscription, or free of charge. Architecturally, there are few differences between public- and private-cloud services, but security concerns increase substantially when services (applications, storage, and other resources) are shared by multiple customers. Most public-cloud providers offer direct-connection services that allow customers to securely link their legacy data centers to their cloud-resident applications. Several factors like the functionality of the solutions, cost, integrational and organizational aspects as well as safety & security are influencing the decision of enterprises and organizations to choose a public cloud or on-premises solution.
Hybrid cloud is a composition of a public cloud and a private environment, such as a private cloud or on-premises resources, that remain distinct entities but are bound together, offering the benefits of multiple deployment models. Hybrid cloud can also mean the ability to connect collocation, managed or dedicated services with cloud resources. Gartner defines a hybrid cloud service as a cloud computing service that is composed of some combination of private, public and community cloud services, from different service providers. A hybrid cloud service crosses isolation and provider boundaries so that it cannot be simply put in one category of private, public, or community cloud service. It allows one to extend either the capacity or the capability of a cloud service, by aggregation, integration or customization with another cloud service. Varied use cases for hybrid cloud composition exist. For example, an organization may store sensitive client data in house on a private cloud application, but interconnect that application to a business intelligence application provided on a public cloud as a software service. This example of hybrid cloud extends the capabilities of the enterprise to deliver a specific business service through the addition of externally available public cloud services. Hybrid cloud adoption depends on a number of factors such as data security and compliance requirements, level of control needed over data, and the applications an organization uses. Another example of hybrid cloud is one where IT organizations use public cloud computing resources to meet temporary capacity needs that can not be met by the private cloud. This capability enables hybrid clouds to employ cloud bursting for scaling across clouds.
Cloud bursting is an application deployment model in which an application runs in a private cloud or data center and "bursts" to a public cloud when the demand for computing capacity increases. A primary advantage of cloud bursting and a hybrid cloud model is that an organization pays for extra compute resources only when they are needed. Cloud bursting enables data centers to create an in-house IT infrastructure that supports average workloads, and use cloud resources from public or private clouds, during spikes in processing demands.
According to ISO/IEC 22123-1: "multi-cloud is a cloud deployment model in which a customer uses public cloud services provided by two or more cloud service providers". Poly cloud refers to the use of multiple public clouds for the purpose of leveraging specific services that each provider offers. It differs from Multi cloud in that it is not designed to increase flexibility or mitigate against failures but is rather used to allow an organization to achieve more than could be done with a single provider.
fragmentation of the digital single market across the EU concerns about contracts including reservations about data access and ownership, data portability, and change control variations in standards applicable to cloud computing The Communication set out a series of "digital agenda actions" which the Commission proposed to undertake in order to support the development of a fair and effective market for cloud computing services.
Client–server model – Client–server computing refers broadly to any distributed application that distinguishes between service providers (servers) and service requestors (clients). Computer bureau – A service bureau providing computer services, particularly from the 1960s to 1980s. Grid computing – A form of distributed and parallel computing, whereby a 'super and virtual computer' is composed of a cluster of networked, loosely coupled computers acting in concert to perform very large tasks. Fog computing – Distributed computing paradigm that provides data, compute, storage and application services closer to the client or near-user edge devices, such as network routers. Furthermore, fog computing handles data at the network level, on smart devices and on the end-user client-side (e.g. mobile devices), instead of sending data to a remote location for processing. Utility computing – The "packaging of computing resources, such as computation and storage, as a metered service similar to a traditional public utility, such as electricity." Peer-to-peer – A distributed architecture without the need for central coordination. Participants are both suppliers and consumers of resources (in contrast to the traditional client-server model). Cloud sandbox – A live, isolated computer environment in which a program, code or file can run without affecting the application in which it runs.
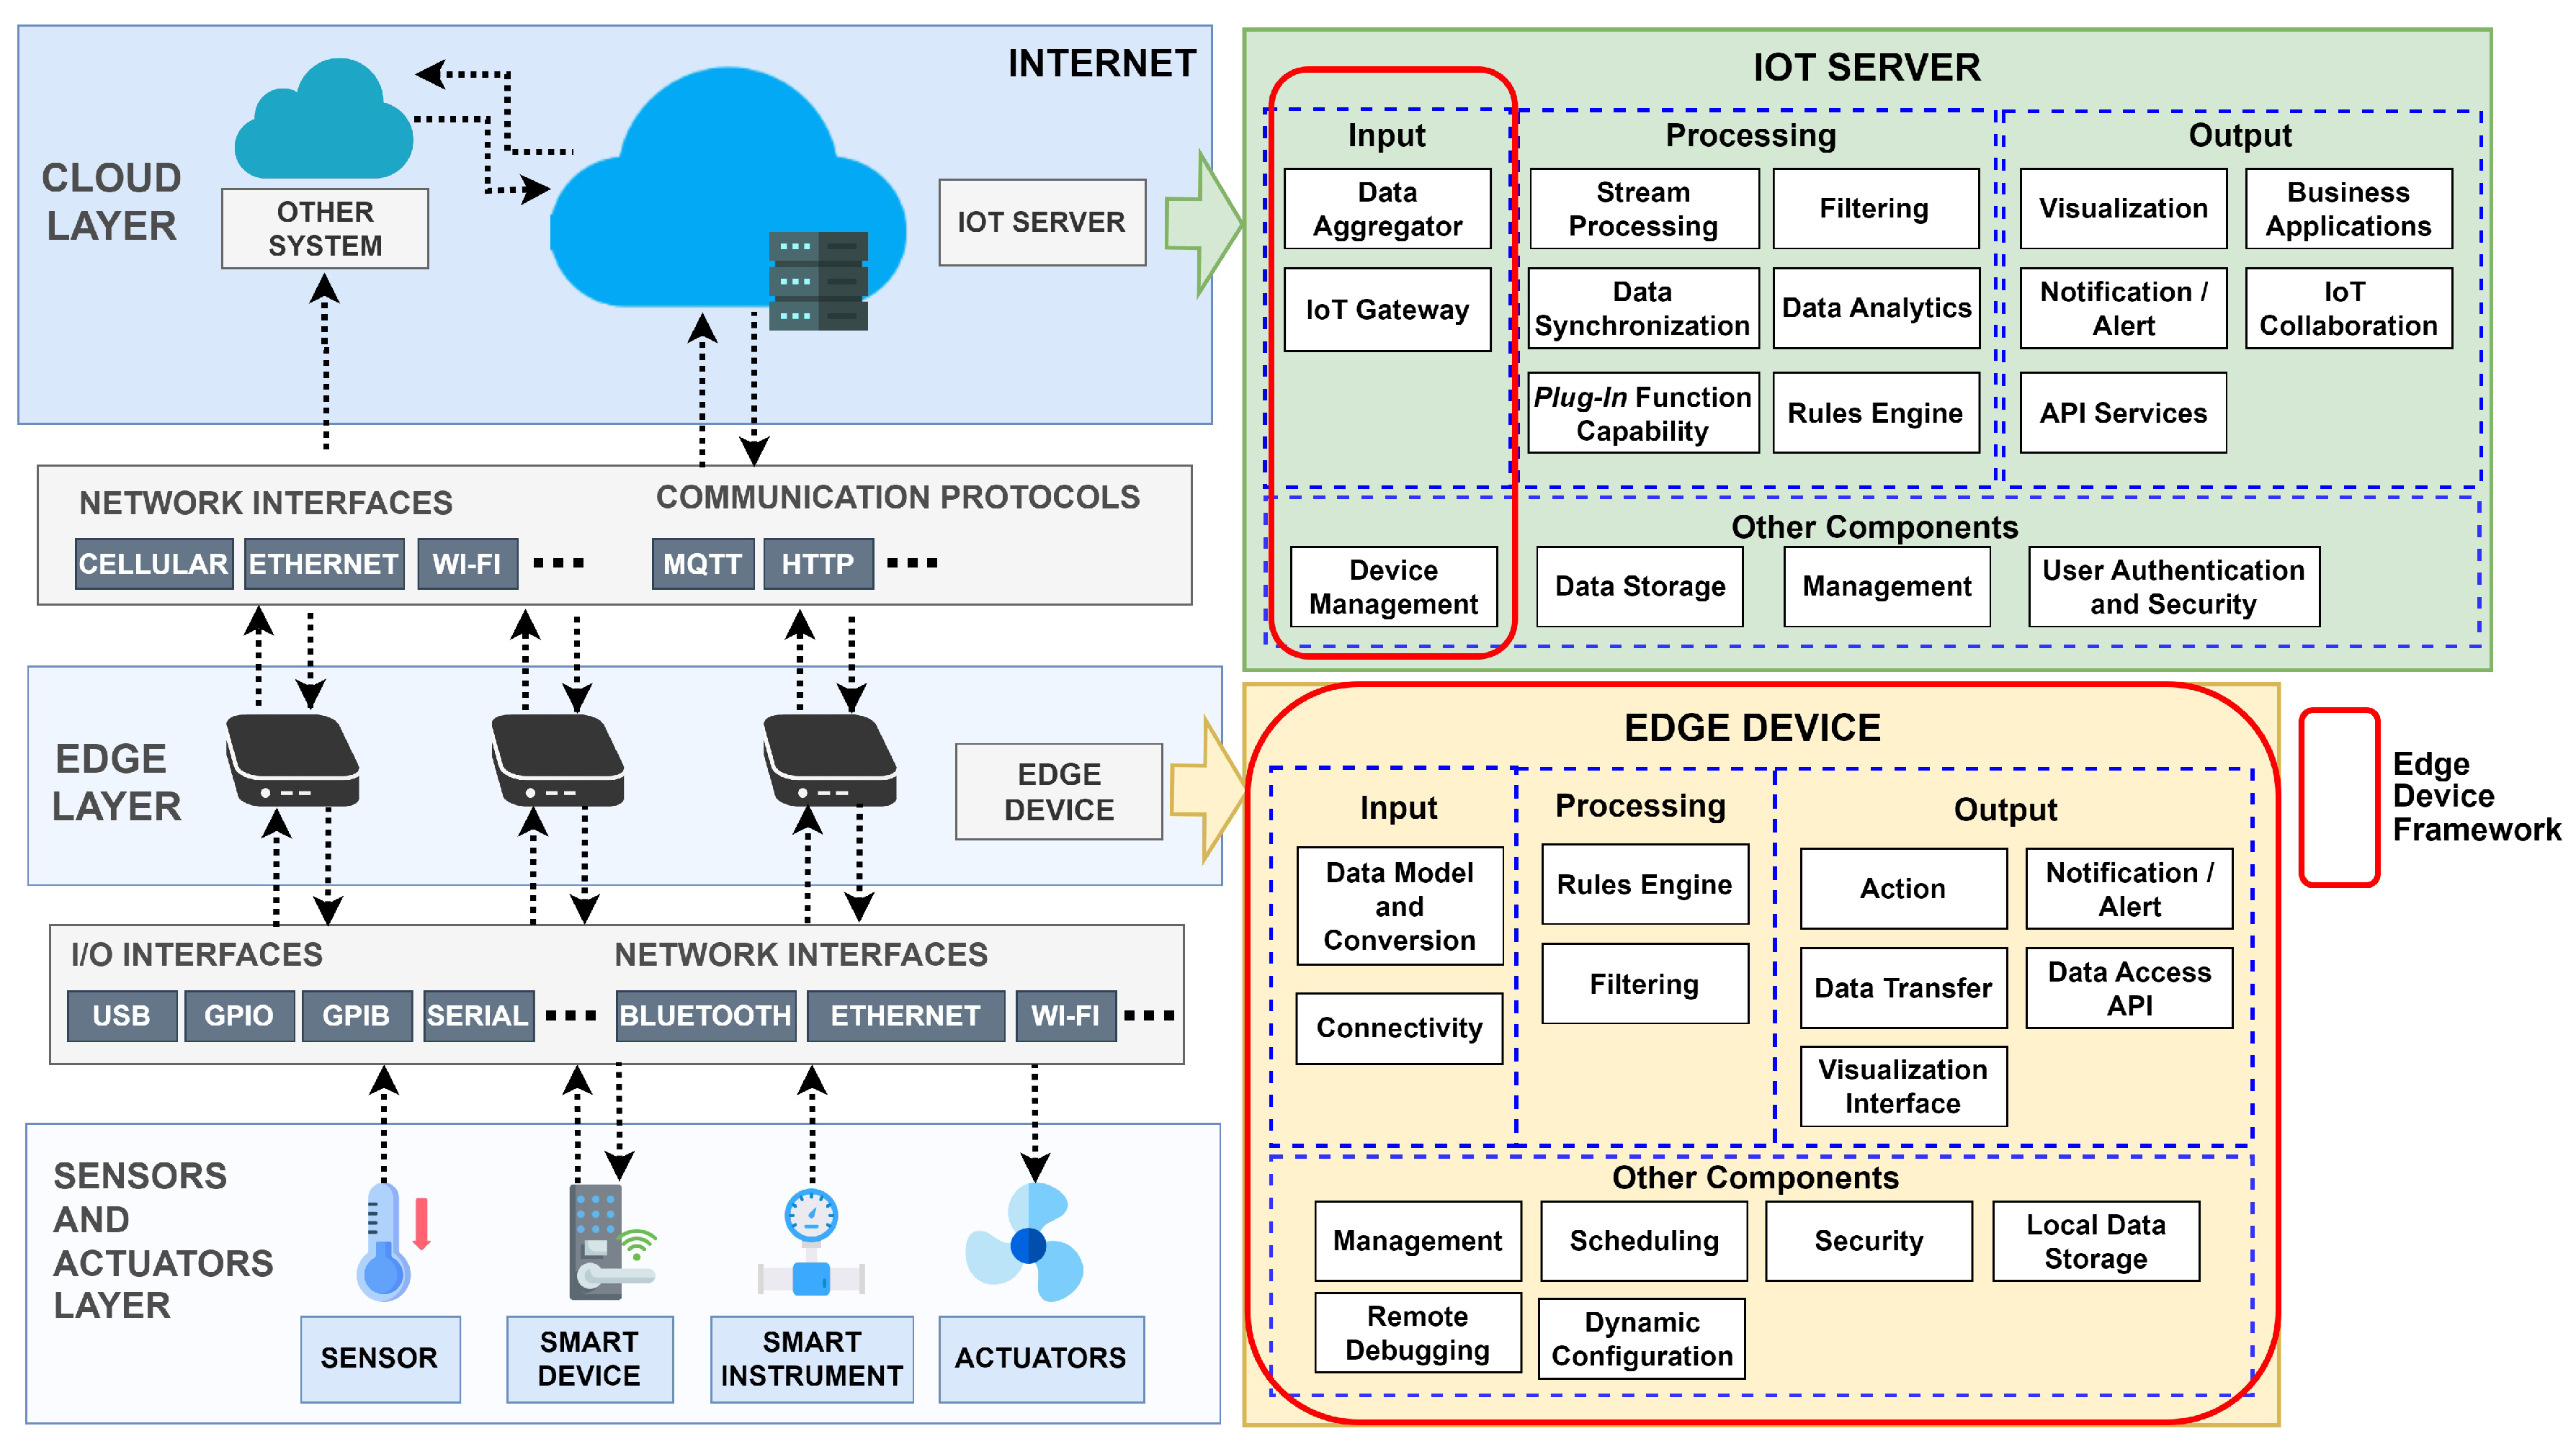
3. Software Implementation, Frameworks & Protocols Influence the future of the AWS Security Reference Architecture (AWS SRA) by taking a short survey . This capability supports best practices 3, 4, and 5 from the AWS SRA best practices for IoT . The AWS shared responsibility model extends to the industrial IoT edge and into environments where devices are deployed.
In the environments where devices are deployed, often called IoT edge locations , customers' responsibilities are much broader than they are in the cloud environment. Security of the IoT edge is the AWS customer's responsibility and includes securing the edge network, the edge network perimeter, and devices in the edge network; securely connecting to the cloud; handling software updates of edge equipment and devices; and edge network logging, monitoring, and auditing, as key examples. AWS is responsible for AWS-provided edge software such as AWS IoT Greengrass and AWS IoT SiteWise Edge, and AWS edge infrastructure such as AWS Outposts.
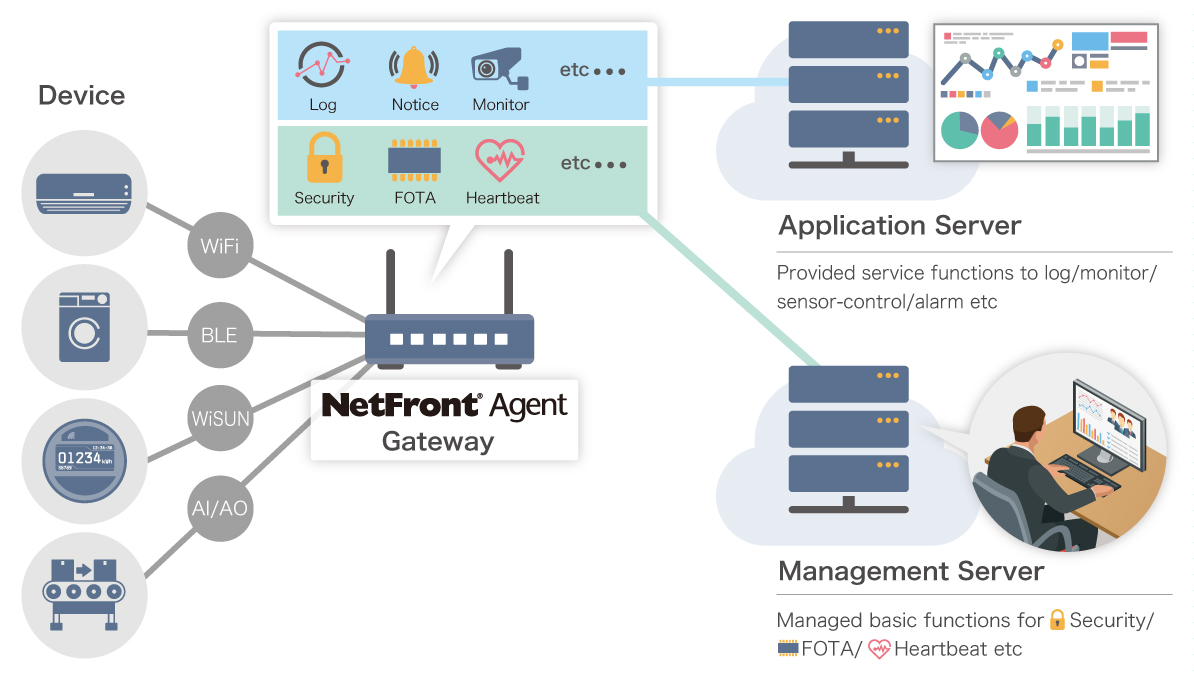
As industrial operations increasingly adopt cloud technologies, there's a growing need to bridge the gap between traditional OT systems and modern IT infrastructure. This capability addresses the necessity for secure, low-latency processing at the edge while also ensuring robust connectivity to AWS Cloud resources. By implementing edge gateways and secure connectivity methods, organizations can maintain the performance and reliability required for critical industrial processes while they take advantage of the scalability and advanced analytics capabilities of cloud services.
This capability is also essential for maintaining a strong security posture in IIoT and OT environments. OT systems often involve legacy devices and protocols that might lack built-in security features and become vulnerable to cyber threats. By incorporating secure edge computing and connectivity solutions, organizations can implement crucial security measures such as network segmentation, protocol conversion, and secure tunneling closer to the data source. This approach helps protect sensitive industrial data and systems and also enables compliance with industry-specific security standards and regulations.
Additionally, it provides a framework for securely managing and updating edge devices, which further enhances the overall security and reliability of IIoT and OT deployments. The implementation of secure edge computing and connectivity in IoT, IIoT, and OT solutions presents a multifaceted risk landscape. Key threats include inadequate network segmentation between IT and OT systems, security weaknesses in legacy industrial protocols, and the inherent limitations of edge devices that have limited resources. These factors create potential entry points and avenues for threat propagation. The transmission of sensitive industrial data between edge devices and cloud services can also introduce risks of interception and manipulation, and insecure cloud connections can expose systems to internet-based threats. Additional concerns include the potential for lateral movement within industrial networks, lack of visibility into edge device activities, physical security risks for remotely located infrastructure, and supply chain vulnerabilities that can introduce compromised components. Collectively, these threats underscore the critical need for robust security measures in edge computing and connectivity solutions for industrial environments.
To address data protection concerns, implement encryption for data in transit and at rest. Use secure protocols such as MQTT over TLS, HTTPS, and WebSockets over HTTPS. For communications with IoT devices, and generally within IoT industrial edge environments, consider using secure versions of industrial protocols such as CIP Security, Modbus Secure, and Open Platform Communications Unified Architecture (OPC UA) with security mode enabled. When secure protocols aren't natively supported, employ protocol converters or gateways to translate insecure protocols into secure ones as close to the data source as possible. For critical systems that require strict data flow control, consider implementing unidirectional gateways or data diodes. Use AWS IoT SiteWise Edge gateways with OPC UA security mode for industrial data sources, and use AWS IoT Greengrass for secure local MQTT broker configurations. When protocol-level security isn't possible, consider implementing an encryption overlay by using VPNs or other tunneling technologies to protect data in transit.
In the context of the AWS SRA for IoT, IIoT, and OT environments, secure protocol usage and conversion should be implemented at multiple levels: Level 1. By using an AWS IoT SiteWise Edge gateway connected to an industrial data source that supports OPC UA with security mode.
Level 2. By using an AWS IoT SiteWise Edge gateway combined with a partner data source that supports legacy protocols to achieve required protocol conversion. Level 3. By using a secure local MQTT broker configuration with MQTT brokers that are supported through AWS IoT Greengrass.
Implement robust identity and access management practices to mitigate unauthorized access risks. Use strong authentication methods, including multi-factor authentication where possible, and apply the principle of least privilege. For edge device management, use AWS Systems Manager for secure access and configuration of edge computing resources. Use AWS IoT Device Management and AWS IoT Greengrass for secure management of IoT devices. When you use AWS IoT SiteWise gateways, employ AWS OpsHub for secure management. For edge infrastructure, consider AWS Outposts as a fully managed service that consistently applies best practices to AWS resources at the edge.
Secure connectivity between the industrial edge and the AWS Cloud is a critical component for the successful deployment of IoT, IIoT, and OT workloads in the cloud. As shown in the AWS SRA, AWS offers multiple ways and design patterns to establish a secure connection to the AWS environment from the industrial edge. These options provide a reliable and encrypted communication channel between the industrial edge and the AWS infrastructure, in alignment with the security guidelines outlined in the National Institute of Standards and Technology (NIST) Guide to Operational Technology (OT) Security (NIST SP 800-82 Rev. 3) which warrants the need to " use secure connections âI¦ between network segments, such as between a regional center and primary control centers and between remote station and control centers." 4. Practical Deployment, Analysis & Case Studies After you establish a secure connection to workloads running in AWS and to AWS services, use virtual private cloud (VPC) endpoints whenever possible. VPC endpoints enable you to connect privately to supported Regional AWS services without using the public IP addresses of these AWS services. This approach further helps enhance security by establishing private connections between your VPC and AWS services, and aligns with NIST SP 800-82 Rev. 3 recommendations for secure data transmissions and network segmentation.
You can configure VPC endpoint policies to control and limit access to only the required resources, applying the principle of least privilege. This helps reduce the attack surface and minimize the risk of unauthorized access to sensitive IoT, IIoT, and OT workloads. If the VPC endpoint for the required service isn't available, you could establish a secure connection by using TLS over the public internet. The best practice in such scenarios is to route these connections through a TLS proxy and a firewall , as shown previously in the Infrastructure OU âII Network account section of the AWS SRA âII core architecture guide.
Some environments might have requirements to send data in one direction to AWS while physically blocking traffic in the opposite direction. If your environment has this requirement, you can use data diodes and unidirectional gateways. Unidirectional gateways consist of a combination of hardware and software. The gateway is physically able to send data in only one direction, so there is no possibility of IT-based or internet-based security events pivoting into the OT networks.
Unidirectional gateways can be a secure alternative to firewalls. They meet several industrial security standards, such as the North American Electric Reliability Corporation Critical Infrastructure Protection (NERC CIP), the International Society of Automation and International Electrotechnical Commission (ISA/IEC) 62443 , the Nuclear Energy Institute (NEI) 08-09 , the U.S. Nuclear Regulatory Commission (NRC) 5.71 , and CLC/TS 50701 . They are also supported by the Industry IoT Consortium's Industrial Internet Security Framework , which provides guidance on protecting safety networks and control networks with unidirectional gateway technology. NIST SP 800-82 states that using unidirectional gateways might provide additional protections associated with system compromises at higher levels or tiers within the environment. This solution enables regulated industries and critical infrastructure sectors to take advantage of cloud services on AWS (such as IoT and AI/ML services) while preventing remote events from penetrating back into protected industrial networks. OT devices that are behind the data diode and unidirectional gateway need to be locally managed. The data diode function is a networking-related function. The data diodes and unidirectional gateways, when deployed into the AWS environment to support the IoT industrial edge, should be deployed into the Industrial Isolation networking account so they are embedded between levels in the OT network.
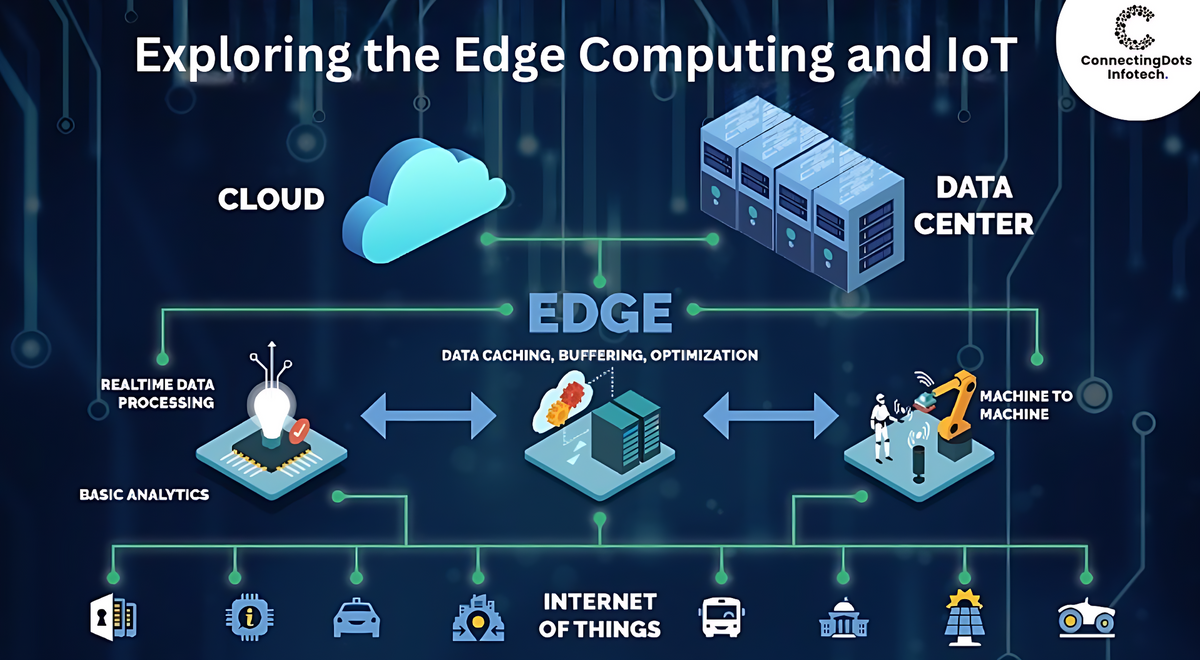
Many contemporary applications, including smart homes and autonomous vehicles, rely on the Internet of Things technology. While cloud computing provides a multitude of valuable services for these applications, it generally imposes constraints on latency-sensitive applications due to propagation delays. Edge computing emerges as a complementary approach, positioning computing resources closer to the data sources to reduce the latency, relieve the bandwidth pressure on the cloud, and enhance data security. However, this introduces notable challenges in access control—a critical aspect of safeguarding data. We survey existing access control models used in edge computing. We begin by introducing various typical models and providing our insights. We then classify these models according to their application in different data lifecycles—data collection, storage, and usage—and assess the role of blockchain technology in enhancing security measures. Through a detailed investigation, we aim to systematically clarify the solutions to these challenges and discuss their implications. Finally, we envisage some potential research directions to further develop access control technologies in edge computing.
In the Internet of Things (IoT) era, massive devices generate enormous data, which is collected, stored, and analyzed for fueling many contemporary applications, such as smart homes and smart cities [ 1 ] . As the pivotal infrastructure, cloud computing is used to harness these data. However, the latency, mainly induced by the geographical distance between data sources and cloud centers, would be unacceptable for some applications, such as virtual realization and connected autonomous vehicles. To address these challenges, edge computing acts as a synergistic technique to cloud computing, so that computing resources are situated closer to data sources and large raw IoT data is processed locally in edge nodes.
Subsequently, the processed data could be transmitted to the cloud for advanced analysis [ 2 ] . Therefore, edge computing can help alleviate network burdens for the cloud, support latency-sensitive applications, and simultaneously enhance data security [ 3 ] . Access control for data security is always accompanied by the development of new technology [ 4 , 3 ] , and edge computing is no exception. Access control ensures that only authorized users and devices can access sensitive data stored at the edge nodes. The number of security incidents caused by internal users or system errors at the edge nodes can be reduced through stringent access control. Access control helps enterprises ensure that their edge computing practices comply with regulations such as GDPR [ 5 ] .
Access control is commonly developed based on many typical and popular access control models, such as Capability-Based Access Control (CapBAC) [ 6 ] , Role-Based Access Control (RBAC) [ 7 ] , Attribute-Based Access Control (ABAC) [ 8 ] , Data Usage Control (DUC) [ 9 , 10 ] , Group-Based Access Control (GBAC) [ 11 ] , Context-Aware Access Control (CAAC) [ 12 ] , Risk-Aware Access Control (RAAC) [ 13 ] , Relationship-Based Access Control (ReBAC) [ 14 ] , and Trust-Based Access Control (TBAC) [ 15 , 16 ] . In this survey, CAAC includes basic CAAC and derived CAAC. Basic CAAC considers raw context data, e.g., location. Derived CAAC considers trust, risk, and relationship (corresponding to TBAC, RAAC, and ReBAC respectively), which should be computed based on raw data. Besides, there are also typical cryptography-based access controls, such as Attribute-Based Encryption (ABE). We will detail these access control models in Section II .
To enhance data protection in edge computing, numerous studies have been dedicated to exploring these access control models to realize their potential improvements/implementations in edge computing scenarios. These studies confront several significant challenges of access control, which edge computing introduces. Firstly, a wide range of IoT devices in edge computing often operate with limited resources like storage, computational power, and communication capabilities. The resource-constrained environments pose challenges for effectively implementing the access control mechanisms that typically require many resources. Secondly, the latency in edge computing results from various factors like task offloading, communication duration, computational expenses, and security measure-induced overheads. To preserve its low latency advantage, the implementation of access control systems must not significantly extend these delays. Thirdly, the mobile nature of data producers and consumers in edge computing scenarios necessitates flexibility in access control mechanisms to accommodate this dynamism. Lastly, the widespread geographical distribution of edge nodes challenges the scalability of centralized access control systems and complicates trust management in such a decentralized environment.
It is important to summarize these studies for the development of access control technologies in edge computing. Several surveys on this topic have been published, usually from a different perspective. Kayes et al. [ 17 ] make the review for CAAC. They systematically review the basic contextual conditions, e.g., temporal, location, and spatial, and the derived ones, e.g., relationship. And, they introduce how CAAC works with RBAC and ABAC for adapting to the dynamic environment in edge computing. Zhang et al. [ 18 ] present CapBAC, ABAC, ABE, RBAC, and DUC in edge computing. However, they do not cover GBAC and CAAC. Alnefaie et al. [ 19 ] survey the CapBAC, ABAC, DUC, and RBAC, meanwhile, introducing CAAC (basic and TBAC), but without ABE, GBAC, RAAC, and ReBAC. Rasori et al. [ 20 ] focus on reviewing suitable ABE for IoT, which assumes that the edge servers are untrusted. To spur the development of DUC, Akaichi et al. [ 21 ] review various DUC proposals for their specification, enforcement, and robustness.
While the aforementioned studies make their reviews with different access control models, they do not consider blockchain-based access control, which is an emerging and widely adopted novel access control technology. Pal et al. [ 22 ] mainly present the studies to use blockchain for enhancing CapBAC, RBAC, TBAC, and ABAC in edge computing. Riabi et al. [ 23 ] present blockchain-based access control for improving ABAC, RBAC, and CapBAC. Khan et al. [ 24 ] classify the existing authorization mechanisms, weaknesses, and loopholes. The CapBAC, ABAC, ABE, TBAC, and their corresponding blockchain-based schemes are involved. Dramé-Maigné et al. [ 25 ] survey the access control solutions from the perspectives of architectures, e.g., centralized, hierarchical, federated, and distributed. The CapABC, ABAC, ABE, RBAC, CAAC, and general blockchain-based access control are analyzed in these architectures.
Moreover, Ravidas et al. [ 26 ] divide the requirements of access control systems into three categories according to policy lifecycles, i.e., policy specification, policy management, and policy evaluation&enforcement. This survey analyzes CapBAC, ABAC, DUC, RBAC, and CAAC according to the above classifications. However, the aforementioned studies do not consider the reviews from the perspective of multiple data lifecycles. In edge computing, data security encompasses multiple stages including data collection, storage, usage, etc. A comprehensive review of access control techniques across multiple data lifecycles can facilitate the holistic technique advancement. Khalid et al. [ 27 ] survey on secure data storage and retrieval in edge computing. It involves ABE and TBAC and discusses the corresponding management issues. Liu et al. [ 28 ] conduct a comprehensive review on secure outsourced data analytics in edge computing.
Secure data collection covers authentication mechanisms and trust management mechanisms. Secure data processing relies on the following techniques: homomorphic encryption, differential privacy, pseudonym technology, etc. Data processing generates computational results, which could be stored and kept protected. Secure data storage usually leverages access control mechanisms (e.g., ABE and RBAC) and searchable encryption (including symmetric and asymmetric methods).
However, this work does not involve CapBAC, DUC, GBAC, and the related blockchain-based schemes. Although there are surveys on edge computing access control according to different data lifecycles, they do not systematically consider those typical access control models in the third paragraph and lack the corresponding blockchain schemes for each model. This motivates us to have a more comprehensive and systematic survey with the following contributions: According to the architecture of edge computing, we analyze the access control requirements from data collection, data storage, and data usage, and the role of blockchain in protecting critical access control data in these data lifecycles. In particular, we show how to use/enhance the CapBAC, ABAC, ABE, DUC, RBAC, GBAC, CAAC (basic, TBAC, RAAC, and ReBAC), and blockchain from the perspective of these data lifecycles.
5. Performance Evaluation & Extended Technical Observations Following the systematic requirements analysis, we present and discuss the recent studies on access control techniques in edge computing, and provide the lessons learned from the involved studies. According to the discussions about the recent research studies, we discuss challenges and research directions of access control in edge computing.
For the reader’s convenience, we classify the related studies to be discussed in this survey in Figure 1 . Our classification does not cover every aspect of access control due to the complexity of access control in edge computing. However, this survey can complement existing surveys, which can help readers understand edge computing access control systematically. Further, the researcher or developer in the field can make systematical selections and innovations based on the related access control techniques. This survey can prompt the development of access control techniques in edge computing under the intricacy of innovations in access control.
The rest of the paper is organized as follows. Section II introduces typical access control models and blockchain technology with meaningful insights. Section III describes background knowledge about edge computing, and then presents our requirements analysis on access control in edge computing. Sections IV & V & VI respectively introduce the recent access control solutions according to the requirements. Further, Section VIII envisages some potential research directions to foster research efforts. Section IX concludes this paper.
The access control model formally defines how subjects, objects, actions, conditions, and authorization policies are represented. And, the authorization policies regulate which object(s) can be accessed by which subject(s) with which action(s) under what condition(s). An access control mechanism is enforced according to an access control model and ensures that the objects can be controlled and used legally by reasonable access control.
Many typical and popular access control models are available in academia and industry, such as, Capability-Based Access Control (CapBAC) [ 6 ] , Role-Based Access Control (RBAC) [ 7 ] , Attribute-Based Access Control (ABAC) [ 8 ] , Data Usage Control (DUC) [ 9 , 10 ] , Group-Based Access Control (GBAC) [ 11 ] , Context-Aware Access Control (CAAC) [ 12 ] , Risk-Aware Access Control (RAAC) [ 13 ] , Relationship-Based Access Control (ReBAC) [ 14 ] , and Trust-Based Access Control (TBAC) [ 15 , 16 ] . To organize this survey, we classify RAAC, ReBAC, and TBAC into CAAC, and we will explain in the following.
Access Control Lists (ACLs) [ 29 ] are the most common access control, where the access right on resources is represented by a sequence of pairs I \langle subject, operations I \rangle . However, the list would become complex with the increment of subjects and resources. To overcome the deficiency, RBAC [ 7 ] introduces the role concept, which decouples the subjects and resources by assigning rights to the role(s) of subjects. Thus, RBAC reduces the efforts to manage access rights.
However, in a large number of resources or cross-organization scenarios, the role explosion still needs lots of effort to be conquered. ABAC [ 8 ] uses properties of subjects, objects (resources), and environment to specify access rights, which exploits more components to manage access rights. This fashion could mitigate the role explosion problem but with the expense of more complex attributes components and access rules. However, the common problem of ACLs, RBAC, and ABAC is that they enforce access control by checking the union of all rights in a request. To avoid unnecessary traversal in the checking, CapBAC [ 6 ] authorizes access rights by subject-oriented linked list, a sequence of pairs I \langle object, rights I \rangle . CapBAC could achieve minimal privilege enforcement by checking the request-specified legal capability. Efficient capability revocations and updating can be easily enforced. However, CapBAC needs to issue capabilities for all subjects by cryptographic techniques.
GBAC is a group-based model, where entities with the same permission requirements are assigned to the same group. Each group has specific access rights and attributes. Administrators can create groups of different levels as needed to achieve finer access control. The inappropriate management of groups likely induces poor access control performance. We can further incorporate context information in access control to enhance access permission management. In CAAC, access permissions are determined based on the combination of the subject, object, and other contextual information. CAAC can utilize this contextual information to adjust access permissions dynamically, thereby better meeting specific requirements and enhancing security. Contextual information may include basic ones, such as time, location, device status, network conditions, etc, and derived ones, such as trust, risk, relationship, etc. We mainly introduce the TBAC, RAAC, and ReBAC for this survey. 1) TBAC: In the era of pervasive computing resources and IoT devices, it is common that trust between entities cannot be established beforehand. TBAC focuses on enforcing access control by evaluating the trust level of the subject or object when trusted identities are not determined mutually. 2) RAAC: In RAAC, the authorization of an access request depends on the risk factors associated with that request. These risk factors may include user behavior patterns, device security status, network security status, etc. The system dynamically adjusts access permissions based on these risk factors to provide appropriate resource access at different risk levels. 3) ReBAC: ReBAC emphasizes the relationship between subjects in authorization decisions. The relationship can be diversified, such as superior-subordinate, cooperative, friendly, etc. Administrators can use the relationship to define access rights.
The above access control models are non-cryptographic access control, which only controls data access according to access control policies. However, the data can be easily leaked if the access control is bypassed. With cryptography for access control, we can control data access according to access control policies while the protected data is encrypted [ 30 ] . The Attribute-Based Encryption (ABE) is a popular scheme in this kind of approach. In an ABE-based system, data decryption is contingent upon the alignment of attributes. Specifically, both ciphertexts and users’ keys carry specific attributes. A user can only decrypt the ciphertext if the user’s attributes (or access policy) match the ciphertext’s access policy (or attributes).
Key-Policy Attribute-Based Encryption (KP-ABE) combines access policy with key and encrypts data with attributes. Ciphertext-Policy Attributes-Based Encryption (CP-ABE) combines attributes with keys and encrypts data with access policy. ABE-based access control has mobility, i.e., each distributed data-hosting party can be a policy enforcement point because the ciphertext of data is combined with the access control. However, as asymmetric encryption technology, ABE requires the extra management of the ciphertext and keys and is generally used for small data volumes.
As shown in Figure 2 , traditional ABE requires the authority to manage keys based on legal attributes. Data owners and data users only interact with the key intermediary. The abnormal key intermediary (e.g., disrupted legal attributes, DOS attack because of hacker intrusion) can affect the whole ABE system. Otherwise, multi-authority ABE (MA-ABE) depends on many related attribute authorities, where we can configure attributes used for encryption and decryption. For example, we can set that decryption can succeed with at least d k d_{k} authorities providing secret keys for data users. As such, we can use the MA-ABE to manage attributes distributedly and resolve the key escrow problem.
The above models have a common drawback: they lose control after the data is granted access. DUC restricts data usage to enforce more flexible control after the data has been granted. For example, a party can use DUC to restrict data usage after it shares its data with another party. The restriction rules are specified by data owners who want to control how their data can be used. DUC can satisfy multiple data sovereignty requirements [ 31 ] . For example, the data usage scope controls that data must be used by trusted nodes or services; the data usage purpose controls that data must be used for specific usage purposes; the living time controls that data must be deleted immediately after data is used. However, DUC needs additional expenditure to accomplish these functions, such as purpose management and recognition.
The blockchain is a kind of distributed ledger technology [ 32 , 33 , 34 ] . The committed transactions are recorded in the block. The linked block has the cryptographic hash summary of the content of the previous block, which enables the blockchain to be tamper-evident and tamper-resistant. Storing data in a distributed blockchain network reduces the risk of a single point of failure. The coded contract in a smart contract on a blockchain can be deployed to and executed by blockchain nodes. And, smart contracts can satisfy the common contract items and the need for trusted intermediaries. The execution results are ensured to be correct due to the consensus mechanism in blockchain so that the verification of calculation results can be avoided.
Blockchain can be divided into permissionless and permissioned blockchains [ 32 ] . Permissionless blockchain allows anyone to join, e.g., the popular public blockchain systems, bitcoin [ 35 ] and Ethereum [ 36 ] . Permissioned blockchain allows legal users of blockchain to participate, e.g., the consortium blockchain, Hyperledger Fabric [ 37 ] . Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Edge%20computing • https://en.wikipedia.org/wiki/Secure%20access%20service%20edge • https://en.wikipedia.org/wiki/Cloud%20computing • https://docs.aws.amazon.com/prescriptive-guidance/latest/security-reference-architecture-iot/secure-edge.html • https://arxiv.org/html/2405.07685v2
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Edge Computing Security And Access Control In IoT.
[*] Metasploit Scan Running on Target Subnet for Edge Computing Security And Access Control In IoT... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |