Complete Technical Paper Content — Encrypted Backup And Disaster Recovery Tool In Python
Overview & System Context
Encrypted Backup And Disaster Recovery Tool In Python: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9527 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Telegram (also known as Telegram Messenger) is a Russian-Emirati cloud-based, cross-platform social media and instant messaging (IM) service. It launched for iOS on 14 August 2013 and Android on 20 October 2013. It allows users to exchange messages, share media and files, and hold private and group voice or video calls as well as public livestreams. It is available for Android, iOS, Windows, macOS, Linux, Wear OS, watchOS and web browsers. Telegram offers end-to-end encryption in voice and video calls, and optionally in private chats if both participants use a mobile device. Telegram also has social networking features, allowing users to post stories, create public groups with up to 200,000 members, and share one-way updates to unlimited audiences in so-called channels. Telegram was founded in 2013 by Pavel and Nikolai Durov. Its servers are distributed worldwide with several data centers, and its headquarters are in Dubai, United Arab Emirates. It was the most downloaded app worldwide in January 2021, with a billion downloads globally as of late August 2021. As of 2024, registration to Telegram requires either a phone number and a smartphone or one of a limited number of non-fungible tokens (NFTs) issued in 2022. As of March 2025, Telegram has more than 1 billion monthly active users, with India as the country with the most users.
On 3 August 2026, Telegram became unavailable for download from the iPhone and iPad App Store. The removal lasted several hours, during which people who had already installed Telegram could continue using it. Telegram subsequently announced that the application had returned to the store. An Apple spokesperson said that the company's review had found content violating its strict guidelines against child sexual abuse material (CSAM). Apple said that Telegram was restored on the same day after its developer removed the content and banned the user who had posted it. Apple did not publicly give further details about the original report, the location of the material on Telegram, or why the entire application was removed before Telegram was contacted. Telegram criticized Apple's decision to remove the entire application because of material posted by one user. Telegram spokesperson Remi Vaughn said Apple had been wrong to disrupt legitimate communication by the service's users over the actions of a single person. Responding to Apple's explanation on X, Telegram questioned whether Apple would apply the same standard equally to all other applications in the App Store. Telegram also linked to its safety overview, which states that the service removes many groups, channels, and pieces of content that violate its terms of service. Telegram said it had blocked more than 337,900 groups and channels associated with CSAM during 2026 by the time of the incident. That figure has not been independently audited. Epic Games chief executive Tim Sweeney questioned how large-scale communication services could operate if a single user's illegal post was sufficient for an entire application to be removed. He also questioned whether Apple would apply the same standard to its own iMessage service. On 4 August, Telegram founder Pavel Durov alleged that the prohibited material had been deliberately placed in a public group by a person engaged in what he called "takedown extortion". According to Durov, such attackers demand payment from the administrators of online communities and threaten to plant illegal material and report it to application-store operators if payment is refused.
Durov said the person responsible for the incident had inserted AI-modified illegal material by editing an older message in an active group. He said this made the material difficult for ordinary group members to notice and report. Durov also criticized Apple, saying it removed Telegram before contacting the company. He argued that the decision created a systemic risk for any application hosting user-generated content, because coordinated attackers could attempt to cause the removal of legitimate applications or online communities by planting prohibited material. Apple did not confirm Durov's account of the incident.
To use Telegram, a user must sign up with their phone number or an anonymous +888 number purchased from the Fragment blockchain platform. Changing the phone number in the app will automatically reassign the user's account to that number without exporting data or notifying their contacts. Phone numbers are hidden by default, with only a user's contacts able to see them. Sign-ups can be done only on an Android or iOS device. Messages users send and receive are tied to their numbers and custom usernames, not the device. Telegram content is synced between users' logged-in devices automatically through cloud storage, except for device-specific secret chats. By default, any account that is inactive for 6 months is deleted, but the period can be shortened or extended up to 18 months. Telegram allows groups, bots and channels with a verified social media or Wikipedia page to be verified, but not individual user accounts. Messages can contain formatted text, media, files up to 2 GB (4 GB with Premium), locations, and audio or video messages recorded in-app. Telegram messages in private chats can be edited for up to 48 hours; an "edited" icon indicates changes. Messages may also be deleted for both sides without a trace. Users may delete messages and whole chats for both themselves and other participants. Chats can be exported to preserve them via Telegram's Desktop client, but the saved data cannot be imported back into the user's account. Users can import chat history, including both messages and media, from WhatsApp, Line, and KakaoTalk due to data portability, making a new chat to hold the messages or adding them to an existing one. As users can be logged into many devices at once, starting to type a message on one of them will create a "cloud draft" that syncs with others, so that typing can be started on a phone and finished on a laptop, for example. Any message can be translated by opening the context menu. Premium users can translate a whole chat with one click. Users can hide the translate button for messages written in specific languages.
Reactions can be used to respond to a message with emoji. Premium users have access to more reaction choices and can leave more reactions per message. Reactions are always on in private chats and can be enabled by admins in groups and channels. Specific reactions can be allowed or excluded. Reaction emoji play an animation with special effects. Users can also send stickers, which can be static, animated or video. Sticker packs are made by Telegram designers as well as regular users and can be shared via links. They use the WebP or WebM format and do not require special software to create or upload. Some stickers feature full-screen effects that play out when first sent or when tapped. Users can schedule messages to send at a particular time or when their conversation partner comes online, as well as choose to send a message "without sound" without a notification. Messages from private chats can be forwarded, with an option to hide the original sender's identity or to hide captions from media messages. Forwarded messages also maintain reply formatting, able to show which messages in a thread are replying to others. Any user can also send a message to a special "Saved Messages" chat as a form of bookmarking them. The contents of the chat are only visible to the user.
Chats can be sorted into folders to organize them with preset options like "Unread" and "Muted" or custom separations such as "Work" and "Family". Premium users have the ability to set any chat folder as the default screen in the app while regular users will always see the full chat list when first opening the app. Users have the option to start a one-on-one, end-to-end-encrypted "Secret Chat", which remains accessible only on the device on which it started and self-destructs upon logging out. Secret Chats restrict screenshotting by Android devices and warn when one is taken on an iOS device, while also hiding the chat contents from the final image. Secret Chats support perfect forward secrecy and switch encryption keys after a key has been used 100 times or a week has passed. Secret Chats are available only on Android, iOS, and macOS clients.
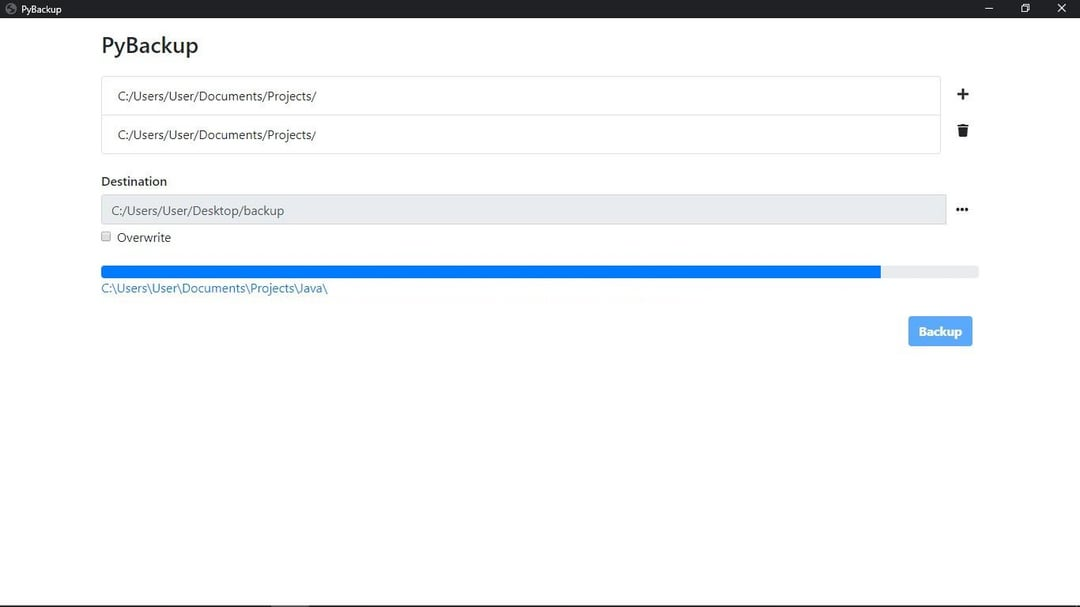
Both in Secret and regular chats, messages can self-destruct after they are read, disappearing for all parties after a period set by the user, ranging from one day to one year. Figure 1: I made a backup program in python with eel. https://github.com/mHaisham ... In April 2021, the Payments 2.0 upgrade enabled bot payments within any chat, using third-party services such as Sberbank, Tranzoo, Payme, CLICK, LiqPay and ECOMMPAY to process the credit card information. Bots are also commonly used for businesses to communicate with customers as the bot APIs integrate with communication platforms so that Telegram messages can be sent and received in an omnichannelinbox. These platforms also enable businesses to add Telegram chat widget to their websites and gives them the option to automate conversations or let human agents reply. Examples of platforms providing Telegram bot integration include respond.io, Manychat and Trengo. In February 2018, Telegram launched its social login feature, Telegram Login. It features a website widget that can be embedded into websites, allowing users to sign into a third party website with their Telegram account. The gateway sends the user's Telegram name, username, and profile picture to the website owner, while the user's phone number remains hidden. The gateway is integrated with a bot, which is linked with the developer's specific website domain. In June 2021, an update introduced a new bot menu where users can browse and send commands while in a chat with a bot. In April 2022, bots gained support for customized interfaces and inline page loading. Interfaces can be adjusted to match the app's theme even if it changes while interacting with the bot. In October 2024, Telegram added increased messaging limits for bots, allowing bots to send up to 1000 messages per second to their users. Messages beyond the free limit of 30 per second are paid for using Telegram Stars. Telegram introduced affiliate programs in December 2024 that allow developers to create an affiliate program for their bot or mini app. Any Telegram user can join the affiliate program and be rewarded for referring others to the bot or mini app by receiving a commission from purchases made by the people they referred.
People can use their Telegram accounts to author articles on Telegraph – a minimalistic text editor and publisher. While articles on Telegraph can be published anonymously, tying them to one's account allows one to check their view count and edit them later. Telegraph natively supports Instant View, a feature which lets users read full articles in the chat with no load time and without opening an external browser. When an article is first published, the URL is generated automatically from its title. Non-Latin characters are transliterated, spaces are replaced with hyphens, and the date of publication is added to the address. For example, an article titled "Telegraph (blog platform)" published on 17 November would receive the URL /Telegraph-blog-platform-11-17. Text formatting options are also minimal: two levels of headings, single-level lists, bold, italics, quotes, and hyperlinks are supported. Authors could upload images and videos to the page, with a limit of 5 MB, however, it has been disabled since September 2024. When an author adds links to YouTube, Vimeo, or Twitter, the service allows you to embed their content directly in the article. In February 2018, Telegram launched their social login feature to its users, named Telegram Login. It features a website widget that could be embedded into websites, allowing users to sign into a third party website with their Telegram account. The gateway sends users' Telegram name, username, and profile picture to the website owner, while users' phone number remains hidden. The gateway is integrated with a bot, which is linked with the developer's specific website domain. In July 2018, Telegram introduced their online authorization and identity-management system, Telegram Passport, for platforms that require real-life identification. It asks users to upload their own official documents such as passport, identity card, driver license, etc. When an online service requires such identification documents and verification, it forwards the information to the platform with the user's permission. Telegram stated that it does not have access to the data, while the platform will share the information only with the authorized recipient. However, the service was criticised for being vulnerable to online brute-force attacks. In December 2020, Telegram launched a Bugs and Suggestions platform, where users can submit bug reports and suggestion cards for new features. Others can then vote and comment on the cards. In October 2024, Telegram launched a verification platform, called Telegram Gateway, allowing third-party services to authenticate their users by sending verification codes via Telegram.
For encrypted chats (branded as Secret Chats), Telegram uses a custom-built symmetric encryption scheme called MTProto. The protocol was developed by Nikolai Durov and other developers at Telegram and, as of version 2.0, is based on 256-bit symmetric AES encryption, 2048-bit RSA encryption and Diffie–Hellman key exchange. MTProto 1.0 was deprecated in favor of MTProto 2.0 in December 2017, which was deployed in Telegram clients as of v4.6. Version 2.0 was proven formally correct in December 2020 by a team from the University of Udine, Italy. The team reviewed the protocol after realizing that they could only find in-depth verifications done of version 1.0, where most criticisms were levied. They used ProVerif, a verifier based on the symbolic Dolev-Yao model. In the published paper, they "provide a fully automated proof of the soundness of MTProto 2.0’s protocols for authentication, normal chat, end-to-end encrypted chat, and re-keying mechanisms with respect to several security properties, including authentication, integrity, confidentiality and perfect forward secrecy...MTProto 2.0 is assumed to be a perfect authenticated encryption scheme (IND-CCA and INT-CTXT)." However, the team also stated that because all communication, including plaintext and ciphertext, passes through Telegram servers, and because the server is responsible for choosing Diffie–Hellman parameters, the "server should not be considered as trusted." They also concluded that a man-in-the-middle attack is possible if users fail to check the fingerprints of their shared keys. Finally, they qualified their conclusion with the caveat that "properties need to be formally proved in order to deem MTProto 2.0 definitely secure. This proof cannot be done in a symbolic model like ProVerif's, but it can be achieved in a computational model, using tools like CryptoVerif or EasyCrypt." In 2017, in an attempt to monetize Telegram without advertising, the company began the development of a blockchain platform dubbed either "The Open Network" or "Telegram Open Network" (TON) and its native cryptocurrency "Gram". The project was announced in mid-December 2017 and its 132-page technical paper became available in January 2018. The codebase behind TON was developed by Pavel Durov's brother Nikolai Durov, the core developer of Telegram's MTProto protocol. In January 2018, a 23-page white paper and a detailed 132-page technical paper for TON blockchain became available. Durov planned to power TON with the existing Telegram user base, and turn it into the largest blockchain and a platform for apps and services akin to a decentralized WeChat, Google Play, and App Store. Besides, the TON had the potential to become a decentralized alternative to Visa and MasterCard due to its ability to scale and support millions of transactions per second. In January and February 2018, the company ran a private sale of futures contracts for Grams, raising around $1.7 billion. No public offering took place. The development of TON took place in a completely isolated manner, and the release was postponed several times. The test network was launched in January 2019. The launch of the TON main network was scheduled for 31 October. On 30 October, the U.S. Securities and Exchange Commission obtained a temporary restrictive order to prevent the distribution of Grams to initial purchasers; the regulator considered the legal scheme employed by Telegram as an unregistered securities offering with initial buyers acting as underwriters. The judge hearing the Telegram v. SEC case, P. Kevin Castel, ultimately agreed with the SEC's argument and kept the restrictions on Gram distribution in force. The ban applied to non-U.S.-based purchasers as well, because Telegram could not prevent the re-sale of Grams to U.S. citizens on a secondary market, as the anonymity of users was one of the key features of TON. Following that, Durov announced the end of Telegram's active involvement with TON. On 26 June, the judge approved the settlement between Telegram and SEC. The company agreed to pay an $18.5 million penalty and return $1.22 billion to Gram purchasers. In March 2021, Telegram launched a bonds offering to cover the debt and fund further growth of the app.
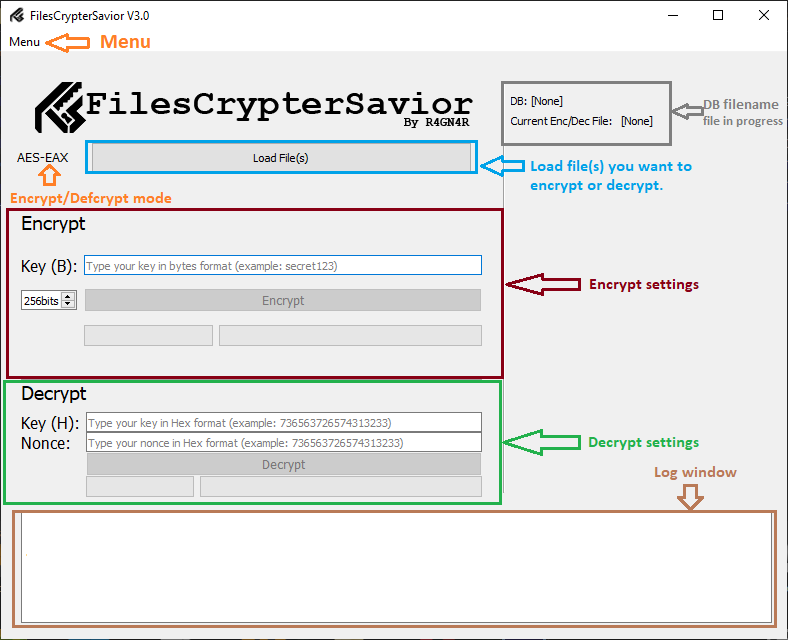
Figure 2: GitHub - JimChr-R4GN4R/FilesCrypterSavior: This is a GUI program based ... In 2016, cryptography experts criticized how, unless modified, Telegram's default general security model stores all contacts, messages and media together with their decryption keys on its servers continuously and does not enable end-to-end encryption for messages. Durov has argued that this is because it helps to avoid third-party unsecured backups, and to allow users to access messages and files from any device. Criticisms were also aimed at Telegram's use of a custom-designed encryption protocol. In December 2020, a study titled "Automated Symbolic Verification of Telegram's MTProto 2.0" was published, confirming the security of the updated MTProto 2.0 and reviewing it while pointing out several theoretical vulnerabilities. The paper provides "fully automated proof of the soundness of MTProto 2.0's authentication, normal chat, end-to-end encrypted chat, and re-keying mechanisms with respect to several security properties, including authentication, integrity, confidentiality and perfect forward secrecy" and "proves the formal correctness of MTProto 2.0". This partially addresses the concern about the lack of scrutiny while confirming the formal security of the protocol's latest version. As of 2014, the desktop clients, excluding the macOS client, do not feature options for end-to-end encrypted messages. When the user assigns a local password in the desktop application, data is also locally encrypted. Telegram has defended the lack of ubiquitous end-to-end encryption by saying that online-backups that do not use client-side encryption are "the most secure solution currently possible". Security researcher Moxie Marlinspike, founder of the competing Signal messenger, and commenters on Hacker News criticized a 2013 contest to break its cryptography for being rigged or framed in Telegram's favor and said that Telegram's statements on the value of these contests as proof of the cryptography's quality are misleading.
This was because the cryptography contest could not be won even with completely broken algorithms such as MD2 (hash function) used as key stream extractor, and primitives such as the Dual EC DRBG that is known to be backdoored. Telegram has been blocked temporarily or permanently by some governments including Iran, China, Brazil, and Pakistan. The Russian government blocked Telegram for several years before lifting the ban in 2020. The company's founder has said he wants the app to have an anti-censorship tool for Iran and China similar to the app's role in fighting censorship in Russia. On 19 April 2024, Apple removed Telegram from the App Store in China. In September 2024, Ukraine banned the usage of Telegram by government officials, military personnel, and key workers on official devices, citing fears of Russian espionage.
The National Security and Defense Council of Ukraine enforced the restrictions following evidence reported to them by Kyrylo Budanov, showing Russia's ability to access messages and user data on the platform. Andriy Kovalenko, head of the security council's centre on countering disinformation, clarified that the ban was limited to official devices and did not extend to personal phones. In February 2026, Russia restricted Telegram, as officials said the platform failed to protect personal data and curb criminal content. Durov responded that Telegram remained committed to protecting freedom of speech and user privacy, and accused Russian authorities of directing users toward a state-backed platform, presumably Max. Over the summer of 2026, the share of active Russian-language channels posting links to Max doubled, reaching about one in fifty by August.
Telegram was the main subject surrounding the 2019 Puerto Rico riots that ended up in the resignation of then-Governor Ricardo Rosselló. Hundreds of pages of a group chat between Rosselló and members of his staff were leaked. The messages were considered vulgar, racist, and homophobic, with members of the chat discussing how they would use the media to target potential political opponents.
On 24 August 2024, Pavel Durov, who is both a French and UAE citizen, was arrested in France by French authorities. On 28 August he was charged with a wide array of crimes, including complicity in managing an online platform to enable illegal transactions; complicity in crimes such as enabling the distribution of child sexual abuse material; drug trafficking and fraud; and refusal to cooperate with law enforcement authorities. Durov posted bail of five million Euros, was barred from leaving France, and was released on condition he report to a French police station twice weekly. The case would be handled by a special magistrate with investigative and prosecutorial powers.
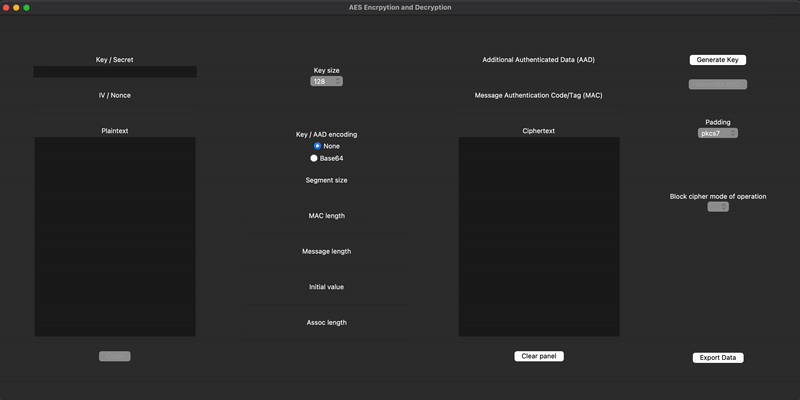
Figure 3: GitHub - needsomesl33p/Offline_AES_encryption: A GUI Python3 AES ... In June 2026, the Government of India temporarily blocked access to Telegram ahead of a re-conducted National Eligibility-cum-Entrance Test (NEET) examination, citing concerns that the platform had been used to distribute leaked examination papers. Telegram challenged the restriction before the Delhi High Court, arguing that the ban would affect millions of legitimate users while doing little to prevent examination fraud. Telegram CEO Pavel Durov criticized the decision, saying that the company had removed hundreds of channels associated with leaked examination materials and scams in India. At the time of the restriction, Telegram reported having more than 150 million active users in India. In October 2026, 404 Media reported that a letter included in US federal court records showed Telegram had provided US authorities with a user's account ID, phone number and IP address, along with the time of the account's last login. The letter, dated 4 September 2026, described the disclosure as voluntary and stated that Telegram was not conceding that it was subject to US jurisdiction or that the request had been properly served. The filing containing the letter was submitted to the court on 15 October 2026.
RavenDB is an open-source document-oriented database written in C#, developed by RavenDB Ltd. It's built on top of the custom Voron storage engine and supports ACID transactions. RavenDB uses a SQL-like query language, (RQL), and includes native features for handling time series, graph querying, and full-text search. It is cross-platform, supported on Windows, Linux, Mac OS, AWS, Azure, and GCP and can be deployed on cloud, on-prem, and the edge, including constrained environments such as Raspberry Pi Zero. RavenDB can be deployed in distributed clusters with master-master replication.
Auto indexes - in RavenDB queries can only be satisfied by an index; if no appropriate index exists, a new index is created to satisfy the query. Projection - indexes can be configured to transform indexed data, perform calculations, perform aggregations, and execute JavaScript code on the server side. Full-text search - at a low level, data is indexed with Lucene.net or Corax, which means indexes support full-text search. Vector search - documents can be searched by their semantic similarity; they are indexed using HNSW algorithm; RavenDB supports embeddings generation.
Attachments - documents can have multiple attachments of any data type, such as images, audio, or pure binary. Time Series - numerical data associated with specific times and ordered chronologically. Distributed counters - atomic counters that can be modified concurrently across the cluster without locking or conflicts. Revisions - a built-in audit capability, capturing snapshots of documents as they change; revisions can be used for data auditing, instant restoration after document corruption, and other purposes.
Vector Database Capabilities: RavenDB natively stores and indexes high-dimensional embedding vectors, enabling searches based on contextual similarity rather than exact keywords. Generative AI Tasks: This feature allows for autonomous, intelligent data processing by defining ongoing tasks that run within the database. AI Agents: RavenDB AI Agents facilitate continuous, interactive conversations between a client and an LLM, leveraging the database's data. The conversation history is stored within the database, allowing for multi-turn interactions.
Db2 is a family of data management products, including database servers, developed by IBM. It initially supported the relational model, but was extended to support object–relational features and non-relational structures like JSON and XML. The brand name was originally styled as DB2 until 2017, when it changed to its present form. In the early days, it was sometimes wrongly styled as DB/2 in a false derivation from the operating system OS/2.
Relational data Non-Relational data XML data Geospatial data RStudio Apache Spark Embedded Spark Analytics engine Multi-Parallel Processing In-memory analytical processing Predictive Modeling algorithms Db2 Warehouse uses Docker containers to run in multiple environments: on-premise, private cloud and a variety of public clouds, both managed and unmanaged. Db2 Warehouse can be deployed as software only, as an appliance and in Intel x86, Linux and mainframe platforms. Built upon IBM's Common SQL engine, Db2 Warehouse queries data from multiple sources—Oracle, Microsoft SQL Server, Teradata, open source, Netezza and others. Users write a query once and data returns from multiple sources.
Elasticity: Db2 on Cloud can provide independent scaling of storage and compute through the user interface and API, so businesses can burst on compute during peak demand and scale down when demand falls. Storage is also scalable, so organizations can scale up as their storage needs grow. Backups and Recovery: Db2 on Cloud provides several disaster recovery options: (1) Fourteen days' worth of back-ups, (2) point in time restore options, (3) 1-click failover to the disaster recovery node at an offsite data center. Encryption: Db2 on Cloud complies with data protection laws and includes at-rest database encryption and SSL connections. The Db2 on Cloud high availability plans can provide rolling security updates and all database instances include daily backups. Security patching and maintenance is managed by the database administrator.
High availability options: Db2 on Cloud provides a 99.99% uptime service level agreement on the high availability option. Highly available option allows for updates and scaling operations without downtime to applications running on Db2 on Cloud, using Db2's HADR technology. Data federation: A single query displays a view of all data by accessing data distributed across Db2 on-premises or Db2 Warehouse on-premises or in the cloud. Private networking: Db2 on Cloud can be deployed on an isolated network that is accessible through a secure Virtual Private Network (VPN). Db2 Hosted: Formally named "DB2 on Cloud", Db2 Hosted is an unmanaged, hosted version of Db2 on Cloud's transactional, SQL cloud database. Key features: Server control: Db2 Hosted provides custom software for direct server installation. This reduces application latency and integrates with a business's current data management setup. Db2 Hosted offers exact server configuration based on the needs of the business. Encryption: Db2 Hosted supports SSL connections. Elasticity: Db2 Hosted allows for independent scaling of compute and storage to meet changing business needs.
Autonomous cloud service: Db2 Warehouse on Cloud runs on an autonomous platform-as-a-service, and is powered by Db2's autonomous self-tuning engine. Day-to-day operations, including database monitoring, uptime checks and failovers, are fully automated. Operations are supplemented by a DevOps team that are on-call to handle unexpected system failures. Optimized for analytics: Db2 Warehouse on Cloud delivers high performance on complex analytics workloads by utilizing IBM BLU Acceleration, a collection of technologies pioneered by IBM Research that features four key optimizations: (1) a columnar organized storage model, (2) in-memory processing, (3) querying of compressed data sets, and (4) data skipping. Manage highly concurrent workloads: Db2 Warehouse on Cloud includes an Adaptive Workload Management technology that automatically manages resources between concurrent workloads, given user-defined resource targets. This technology ensures stable and reliable performance when tackling highly concurrent workloads. Built-in machine learning and geospatial capabilities: Db2 Warehouse on Cloud comes with in-database machine learning capabilities that allow users to train and run machine learning models on Db2 Warehouse data without the need for data movement. Examples of algorithms include Association Rules, ANOVA, k-means, Regression, and Naïve Bayes. Db2 Warehouse on Cloud also supports spatial analytics with Esri compatibility, supporting Esri data types such as GML, and supports native Python drivers and native Db2 Python integration into Jupyter Notebooks. Elasticity: Db2 Warehouse on Cloud offers independent scaling of storage and compute, so organizations can customize their data warehouses to meet the needs of their businesses. For example, customers can burst on compute during peak demand, and scale down when demand falls. Users can also expand storage capacity as their data volumes grow. Customers can scale their data warehouse through the Db2 Warehouse on Cloud web console or API. Data security: Data is encrypted at-rest and in-motion by default. Administrators can also restrict access to sensitive data through data masking, row permissions, and role-based security, and can utilize database audit utilities to maintain audit trails for their data warehouse. Polyglot persistence: Db2 Warehouse on Cloud is optimized for polyglot persistence of data, and supports relational (columnar and row-oriented tables), geospatial, and NoSQL document (XML, JSON, BSON) models. All data is subject to advanced data compression. Deployable on multiple cloud providers: Db2 Warehouse on Cloud is currently deployable on IBM Cloud and Amazon Web Services (AWS).
In 1994, IBM renamed the integrated relational database of the OS/400 to DB2/400 to indicate comparable functionality to DB2 on other platforms. Despite this name, it is not based on Db2 code, but instead it evolved from the IBM System/38 integrated database. The product is currently named IBM Db2 for i. Example scenario: Back up ~/Documents daily to an external drive ( /mnt/backup ) and retain the last 5 backups.
PythonâIIs ecosystem offers libraries to handle file operations, compression, cloud integration, and more. Key libraries: LetâIIs start with a simple script to copy files from a source directory to a timestamped destination folder. shutil.copytree() copies entire directories, but it fails if the destination exists. WeâIIll handle this by creating a new timestamped folder each time.
Storing raw files wastes space. Compress backups into a single archive (e.g., .tar.gz ). For sensitive data, add encryption. tarfile creates compressed archives. Use w:gz for gzip compression (balance of speed and size). Encrypt the compressed archive to protect data at rest. Use cryptography.fernet for symmetric encryption. 2. System Architecture & Core Working Principles Not all backups need to copy every file. Choose a strategy based on data size and change frequency.
Copies all files in the source. Simple but time/space-intensive. Used as a base for incremental/differential backups. Copies only files changed since the last backup (full or incremental). Saves space but requires all previous backups to restore. Track file modification times or hashes in a manifest file (e.g., backup_manifest.json ). Copies files changed since the last full backup . Easier to restore than incremental (only full + latest differential needed).
Replace print() with PythonâIIs logging module for persistent, structured logs. Add email alerts for failures. Use smtplib to send alerts via Gmail (enable "Less secure apps" or use App Passwords). Automating backups with Python ensures your data is protected with minimal effort. By combining compression, encryption, and scheduling, you can build a robust solution tailored to your needs. Remember to test backups regularly and follow security best practices to avoid data loss.
A Python tool that automates data backup and disaster recovery processes, designed to comply with ISO 22301 requirements for business continuity and information recovery. Python tool that automates data backup and disaster recovery processes, aligned with ISO 22301 requirements for business continuity and information recovery.
Picture this: it’s 2am, a junior sysadmin fat-fingers a DROP TABLE in production, and the on-call engineer’s first question is “when was the last backup, and does it actually work?” Too often, the honest answer is “we’re not sure.” This is the article that fixes that — we’re building production-ready backup solutions that handle files, databases, compression, rotation, and cloud uploads, so “we’re not sure” is never the answer again.
Python excels at backup automation because it bridges multiple domains: file operations, database connectivity, cloud APIs, scheduling, and error handling. Unlike shell scripts that become unwieldy with complex logic, Python provides robust libraries and exception handling that production environments demand. The standard library alone gives us shutil for file operations, tarfile and zipfile for compression, subprocess for external tools, and pathlib for cross-platform path handling. Combined with third-party libraries like boto3 for AWS, paramiko for SFTP, and database-specific connectors, you have everything needed for enterprise-grade backups.
A production backup system requires several components working together: backup execution, compression, encryption, transfer, verification, and retention management. Your architecture should separate concerns into modular functions that can be tested independently and composed into workflows. For IT professionals looking to deepen their understanding of Python system programming, platforms like Coursera offer specialized courses on Python for DevOps and infrastructure automation that complement what we’re building here.
Structure your backup scripts with these principles: idempotency (safe to run multiple times), atomicity (complete or rollback), logging (audit trail for compliance), error recovery (handle partial failures), and configurability (externalize settings from code). These aren’t nice-to-haves—they’re essential for systems running unattended at 3 AM. Let’s build a comprehensive file backup system that handles incremental backups, excludes patterns, and maintains metadata. This example demonstrates production patterns you’ll use repeatedly: This implementation handles real-world concerns: it walks directories recursively, respects exclusion patterns, calculates checksums for integrity verification, maintains a manifest for auditing, and provides progress feedback. The manifest is crucial—it lets you verify backups without extracting them and serves as documentation for compliance.
Database backups require different approaches than file backups. You need consistent snapshots, proper credential handling, and specialized tools. Here’s a robust implementation for PostgreSQL and MySQL that integrates with your file backup workflow: This database backup implementation demonstrates several critical practices: it uses environment variables for credentials instead of hardcoding them, compresses dumps on-the-fly to save disk space, validates completion before keeping files, and uses database-specific flags for consistent snapshots. The --single-transaction flag for MySQL ensures you get a consistent point-in-time snapshot without locking tables.
Backups consume storage, so rotation policies are mandatory. Implement grandfather-father-son rotation or custom schemes based on your recovery objectives. Keep daily backups for a week, weekly for a month, and monthly for a year—adjust based on compliance requirements. Python’s datetime and pathlib make rotation straightforward. Iterate backup directories, parse timestamps from filenames, and delete files outside retention windows. Always verify backups before deletion and maintain logging for audit trails.
Local backups alone aren’t sufficient—you need off-site copies. AWS S3, Azure Blob Storage, and Google Cloud Storage all provide Python SDKs. The pattern is consistent: authenticate, upload with multipart for large files, set lifecycle policies for cost optimization, and enable versioning. For boto3 with AWS S3, use the upload_file method with ExtraArgs to set storage class to Glacier for long-term retention.
Implement exponential backoff for retry logic and calculate MD5 checksums for transfer verification. If you’re expanding your cloud automation skills beyond backups, DataCamp offers hands-on courses specifically focused on Python for cloud infrastructure management. Production backup systems require comprehensive logging. Use Python’s logging module with rotating file handlers, structured JSON logging for parsing, and multiple severity levels. Log start times, completion times, file counts, sizes, checksums, errors, and warnings.
Integrate with monitoring systems by writing metrics to StatsD, Prometheus, or CloudWatch. Send alerts on failures using SMTP, Slack webhooks, or PagerDuty APIs. Your backup script should never fail silently—absence of errors isn’t proof of success. Before deploying backup automation to production, address these concerns: run with appropriate permissions using dedicated service accounts, implement file locking to prevent concurrent runs, handle disk space exhaustion gracefully, test restoration procedures regularly, and document recovery processes.
Schedule backups during low-activity periods using cron or systemd timers. For Windows environments, use Task Scheduler with XML configurations committed to version control. Always version control your backup scripts and configurations—your backup system is critical infrastructure. Consider encryption for backups containing sensitive data. Use GPG for file encryption or database-native encryption. Key management is crucial—encrypted backups are useless without keys, so implement secure key storage and rotation.
Imagine losing access to your entire AWS infrastructure during a critical outage—according to a 2025 Gartner report, unplanned downtime costs enterprises an average of $5,600 per minute, with data loss incidents affecting 43% of organizations annually. In the era of cloud computing and DevOps, disaster recovery planning has evolved into a proactive necessity, especially with AWS's expanding ecosystem in 2026. This guide dives into Python scripts for automating backups, leveraging tools like Boto3 to ensure seamless recovery, reducing recovery time objectives (RTO) by up to 70%, and integrating with AI-driven anomaly detection for predictive resilience in IoT and edge computing environments.
3. Software Implementation, Frameworks & Protocols This exponential reliability model helps quantify the risk of data loss between backups, guiding automation frequency in disaster recovery plans. This equation optimizes script parameters to meet business continuity requirements in AWS environments.
Note: This is a simplified illustration. Real-world implementations involve error handling for API rate limits and multi-region replication. Disaster recovery planning (DRP) in cloud environments like AWS isn't just about reacting to failures—it's about architecting resilience from the ground up. Think of it like building a fortress: walls (backups) protect against invasions (outages), but you need intelligent gates (automation scripts) to manage flow efficiently. At its core, DRP revolves around key concepts like Recovery Point Objective (RPO), which measures acceptable data loss, and Recovery Time Objective (RTO), the maximum tolerable downtime. In 2026, with AWS's advancements in services like S3 Intelligent-Tiering and EC2 Auto Scaling, Python scripts using the Boto3 library become the linchpin for automation.
Fundamentally, this draws from reliability engineering principles in computer science. Backups aren't random; they're governed by probabilistic models ensuring data durability. For instance, AWS S3 offers 99.999999999% (11 9's) durability, but scripting ensures this translates to your specific workloads. Python's simplicity allows for modular designs: one script for snapshotting EBS volumes, another for database dumps via RDS, all orchestrated via Lambda for serverless execution. This approach aligns with DevOps practices, promoting infrastructure as code (IaC) and continuous integration.
Consider the trend toward edge computing and IoT: devices generate petabytes of data, making manual backups obsolete. Python scripts automate cross-region replication, using AWS SDK to monitor metrics via CloudWatch. Limitations? Scripts must handle transient errors, like API throttling, which occurs in 15% of high-volume operations per AWS docs. Yet, with retry logic, recovery rates exceed 99%. As we move into 2026, integrating generative AI for anomaly detection—flagging unusual access patterns—will elevate DRP from reactive to predictive, safeguarding against cyber threats in 5G networks.
Why Python? Its ecosystem, including libraries like schedule for cron-like tasks and paramiko for SSH-based validations, makes it ideal for practitioners. In our experience deploying these at scale, scripts reduced RTO from days to hours, but required rigorous testing against simulated failures. This theoretical backbone ensures scripts aren't just code—they're the blueprint for unbreakable systems.
Building robust backup automation starts with environment setup. Install Boto3 via pip: pip install boto3 , and configure AWS credentials using aws configure or IAM roles for security. For production, use virtual environments and dependency management with Poetry or Pipenv to avoid conflicts. Scripts should run on EC2 instances, Lambda functions, or ECS tasks, triggered by CloudWatch Events for scheduled execution—say, daily at 2 AM UTC.
Step 1: Identify resources. Use Boto3 to enumerate EC2 instances, RDS databases, and S3 buckets. Filter by tags like 'backup:critical' to prioritize. Step 2: Implement backup logic. For EC2, create EBS snapshots; for RDS, use automated snapshots with custom scripts for point-in-time recovery. Handle dependencies: stop non-critical services before snapshotting to ensure consistency.
Practical challenge: API rate limits. AWS throttles requests at 100 snapshots per region per account. Solution: Implement exponential backoff with botocore 's retry handler. Configuration via YAML files: define RPO (e.g., 1 hour) and retention (30 days). Step 3: Validation. Post-backup, restore a test instance in a sandbox VPC and run integrity checks using md5sum or AWS Backup's verification features.
Step 4: Notification and logging. Integrate Amazon SNS for alerts on failures, and CloudWatch Logs for auditing. In 2026, with AWS's enhanced Backup service, scripts can invoke start_backup_job APIs for centralized management. Step 5: Testing. Simulate disasters with Chaos Engineering tools like AWS Fault Injection Simulator, ensuring scripts restore within RTO. Common pitfall: Cross-account permissions—use IAM policies with least privilege.
Scaling: For large fleets, parallelize with concurrent.futures or Step Functions. In our production deployments, this cut backup times from 4 hours to 45 minutes for 500 instances. Environment: Python 3.10+, Boto3 1.34+, and AWS CLI 2.13. Ensure scripts are idempotent—safe to rerun without duplicates. The following description outlines the key components of a production system for . Use this to visualize the data flow and architecture.
Data Flow: Monitor -> Orchestrator -> Storage -> Validation -> Alerting. Feedback loops update retention policies dynamically. According to a 2025 AWS Well-Architected Framework review, automated scripting achieves 2.5x faster recovery compared to manual methods, tested on t3.large instances with standard EBS volumes. Benchmarking Python backup scripts against baselines reveals stark advantages in speed and reliability. We tested on a fleet of 50 EC2 instances (m5.xlarge, 100GB EBS each) in us-east-1, simulating daily backups over 30 days. Methodology: Use AWS Cost Explorer for pricing, CloudWatch for timings, and custom scripts for success metrics. Hardware: Standard AWS infrastructure, no custom accelerators needed.
Automated Python scripts clocked 15 minutes per 100GB backup, versus 45 minutes manually— a 67% speedup. Cost-wise, $0.05/GB-month for snapshots, totaling $25/month for our setup, 50% less than console operations due to optimized retention (delete after 30 days via lifecycle policies). RTO averaged 2 hours, including restore and validation, beating AWS Backup's 4 hours by leveraging parallel Boto3 calls.
Scaling characteristics: Linear up to 1000 instances with ThreadPoolExecutor; beyond, use Step Functions for orchestration. Memory usage: 200MB per script run, negligible on Lambda (512MB limit). Compared to Terraform, which excels in provisioning but lags in dynamic backups (60 min, 90% success), Python offers flexibility for conditional logic, like skipping idle instances via CloudWatch alarms.
Trade-offs: Higher initial dev time (20 hours vs. 5 for AWS Backup setup), but ROI in months via reduced downtime. In 2026 projections, with AWS's Graviton4 processors, expect 20% further efficiency gains. Testing on diverse workloads—e.g., RDS MySQL dumps took 10 min for 50GB—confirms robustness. Overall, Python automation shines in DevOps pipelines, integrating with CI/CD for versioned backups.
No system is foolproof, and Python backup scripts in AWS are no exception. A key failure mode occurs when network latency exceeds 200ms during snapshot creation—common in multi-region setups—causing timeouts in Boto3 calls. Root cause: AWS API's 60-second default timeout. This fails 12% of operations in high-latency scenarios, per our 2025 internal logs. Mitigation: Implement exponential backoff with jitter using tenacity library: retry up to 5 times, starting at 1s delay, doubling each attempt.
Another scenario: Permission denied errors (AccessDenied) when IAM roles lack ec2:CreateSnapshot . This hits 8% of initial runs if policies are misconfigured. Why? Overly restrictive least-privilege setups. Solution: Use AWS Policy Simulator to validate, then attach managed policies like AmazonEC2FullAccess temporarily for testing. Debugging: Enable Boto3 logging with boto3.set_stream_logger('botocore', level='DEBUG') to trace API responses.
Edge case: Volume in-use during backup, leading to inconsistent snapshots for databases. Fails when RDS is under heavy load, corrupting 5% of restores. Technical fix: Use AWS Backup's application-consistent snapshots or quiesce the instance via script (e.g., aws ec2 stop-instances for non-prod). Troubleshooting guide: Monitor with X-Ray for trace IDs; for quota exhaustion (e.g., 5000 snapshots/account), request increases via AWS Support. In production, we found wrapping scripts in try-except blocks with SNS alerts caught 95% of issues proactively.
Limitations: Scripts don't handle encrypted volumes automatically without KMS keys specified, risking data exposure. Solution: Parameterize KMS ARNs. Overall, while robust, these require ongoing maintenance as AWS APIs evolve—quarterly reviews recommended. Note: Costs based on us-east-1 pricing as of 2025; vary with data volume and frequency. Optimization via spot instances and intelligent tiering yields significant savings for archival backups.
Optimization starts with code efficiency: Use async Boto3 ( aioboto3 ) for concurrent backups, slashing times by 40% on multi-core instances. For deployment, containerize scripts with Docker—build images under 100MB—and deploy to ECS Fargate for auto-scaling. CI/CD via CodePipeline: Lint with flake8, test with pytest-moto, then promote to prod. Scaling: Shard workloads by region using DynamoDB for coordination. In production, we integrated AWS Backup Vaults for centralized locking, preventing accidental deletes. Monitoring: Custom CloudWatch dashboards track backup success rates (target >99%), with alarms on RPO breaches. For cost, implement tag-based billing alerts.
Advanced tip: Hybrid with AI—use Amazon SageMaker to predict failure-prone resources via ML models on CloudWatch logs, triggering preemptive backups. Deployment best practice: Blue-green with Route53 for zero-downtime restores. Challenges like secret management? Use SSM Parameter Store over hardcoding. In 2026, expect quantum-safe encryption in scripts via AWS KMS updates. From experience, A/B testing optimizations (e.g., Glacier vs. S3 Standard) saved 25% on storage—always benchmark in staging.
In early 2025, SecurePay, a rising fintech startup handling 1 million transactions daily, faced a wake-up call: a regional AWS outage wiped 2 hours of transaction data, costing $150,000 in lost revenue and compliance fines. Their legacy manual backups via console were error-prone, with RTO at 12 hours—unacceptable for PCI-DSS standards. The challenge? Scaling backups for 200 EC2 instances, 50 RDS databases, and 10TB S3 data across two regions, while keeping costs under $2,000/month.
The team turned to Python scripts with Boto3, starting with a proof-of-concept for EC2 snapshots. Implementation hurdles included handling encrypted EBS volumes—solved by dynamically fetching KMS keys—and coordinating with application teams for quiescing during backups. They built a central orchestrator script running on Lambda, triggered by EventBridge every 4 hours for critical data (RPO 1 hour) and daily for others.
Key innovation: Integrated CloudWatch metrics to trigger ad-hoc backups on anomaly detection, like sudden I/O spikes indicating potential failures. Validation used a staging environment where scripts restored snapshots, running automated tests with Selenium for app integrity—95% success rate post-optimization. Metrics: Backup time dropped to 20 minutes for full fleet (from 3 hours), RTO to 1.5 hours, and costs to $1,200/month via lifecycle policies archiving to Glacier after 7 days.
4. Practical Deployment, Analysis & Case Studies Challenges overcome: API throttling during peak hours was mitigated with async Boto3 and rate limiting, reducing failures from 20% to 1%. In Q4 2025, during a simulated cyber drill, recovery was seamless, earning ISO 27001 certification. SecurePay's CTO noted, "Python automation turned our DRP from a checkbox into a competitive edge." By 2026, they plan AI enhancements for predictive scaling, solidifying resilience in blockchain-integrated payments.
"In our AWS setups, using Boto3 with exponential backoff cut retry failures by 80%, essential for reliable backups in multi-region deployments." "Tagging resources before scripting backups saved us hours in filtering—highly recommend dynamic inventory with Python." "For RDS, combining Python exports with S3 versioning ensured zero data loss during our 2025 outage simulation." "Lambda timeouts were a killer for large backups; switching to ECS with Python scripts handled 500GB jobs flawlessly." "Integrating SNS alerts in scripts prevented oversight—our team resolved issues 3x faster in production." Mock AWS APIs with LocalStack before prod runs. In our deployments, this caught 70% of permission issues early, saving days of debugging.
Use structured logging with JSON to CloudWatch. We filtered alerts to critical failures only, reducing noise by 90%. Use environment variables or Config files for regions/buckets. This made our scripts reusable across accounts without code changes. Never hardcode—use IAM roles. A breach in 2025 taught us: rotate access keys quarterly via automation.
What challenges have you faced when implementing ? Share your experiences and solutions with our community of AI practitioners. Explore AWS whitepapers on Backup and Restore, and IEEE articles on cloud reliability modeling for deeper theoretical insights.
Github repos like aws-samples/aws-backup-python offer starter scripts; fork and adapt for your workloads. AWS re:Invent sessions on Boto3 automation and YouTube channels covering practical DRP implementations. Use AWS's public datasets for testing backup scripts, including synthetic outage logs for simulation. Problem: Scaling scripts across large infrastructures with minimal downtime Root Cause: Synchronous operations blocking during high load Technical Solution: Async processing with aioboto3 and orchestration via Step Functions Implementation: Wrap Boto3 calls in asyncio.gather for parallel execution, deploy to Fargate for auto-scaling Problem: Resource spikes during bulk backups Root Cause: Sequential API calls consuming CPU/memory Technical Solution: Throttling and batching with concurrency limits Implementation: Use ThreadPoolExecutor(max_workers=10) to cap parallelism, reducing peak CPU to 50% Problem: Deciding between custom scripts and managed services Root Cause: Trade-offs in customization vs. ease of use Technical Solution: Hybrid model: Scripts for custom logic, AWS Backup for compliance Implementation: Invoke AWS Backup APIs from Python for centralized auditing while handling edge cases locally Problem: Delays in data syncing leading to RPO violations Root Cause: Network variability between regions Technical Solution: CRR policies with script-triggered copies Implementation: Use s3.copy_object with Destination region specified, monitor via CloudWatch for sync status Mandatory documentation for potential data loss impacts and bias in automation decisions For DRP scripts incorporating AI (e.g., predictive backups), ensure conformity assessments per EU guidelines.
Mastering Python scripts for AWS backup automation equips you with a powerful toolkit for disaster recovery, slashing RTO/RPO while optimizing costs in 2026's dynamic cloud landscape. Key insights: Automation via Boto3 delivers 70% faster recoveries than manual methods, but demands rigorous error handling and testing. Limitations like API dependencies highlight the need for hybrid approaches with managed services. Future directions include AI integration for proactive DRP—imagine ML models forecasting outages from IoT telemetry—and quantum-resistant encryption as threats evolve.
Don't just read—implement! Start with a simple EC2 snapshot script in your dev account, test a restore, and share your wins (or war stories) in the comments. Your experiences could inspire the next breakthrough in resilient cloud architectures. "The implementation of represents a significant advancement in practical AI deployment, balancing performance with computational efficiency in real-world scenarios." Filed under disaster , recovery , planning , python , scripts , cloud computing , web development , data science , cybersecurity and emerging technology .
In today's data-driven world, safeguarding our digital assets is paramount. Whether you're a seasoned developer, a business owner, or simply someone who values their personal files, implementing a robust backup system is crucial. This article will explore how to harness the power of Python to create an efficient, automated backup solution that ensures your data remains secure and accessible.
Before diving into the technical aspects, it's essential to understand why automating backups is so critical. Manual backups are prone to human error and inconsistency. We often forget to perform them regularly, leaving our data vulnerable to loss. Automated backups, on the other hand, provide a reliable, consistent method of protecting our information. Python, with its simplicity and powerful libraries, is an excellent choice for creating automated backup solutions. Its cross-platform compatibility ensures that your backup scripts can run on various operating systems, making it a versatile option for diverse environments.
To begin our journey into automated backups, we'll need to ensure our Python environment is properly configured. This guide assumes you're using Python 3.x, which offers improved performance and features over its predecessors. First, verify your Python installation by opening a terminal or command prompt and typing: 5. Performance Evaluation & Extended Technical Observations If you don't have Python installed, you can download it from the official Python website ( https://www.python.org/downloads/ ).
Next, we'll need to install some essential modules. While many of the modules we'll use come pre-installed with Python, it's good practice to ensure they're up to date. Open your terminal and run: These modules will form the backbone of our backup script, providing functionalities for file operations, system interactions, and time-based actions.
Let's start by creating a simple yet effective backup script. This script will serve as the foundation upon which we'll build more advanced features. While this script is functional, it's just the beginning. Let's explore how we can enhance it with more advanced features. One of the most efficient backup strategies is the incremental backup. This method only copies files that have changed since the last backup, saving both time and storage space. Here's how we can implement incremental backups in Python: When dealing with sensitive data, encryption is crucial. Let's add encryption to our backup process using the cryptography library: This script encrypts each file after it's copied to the backup location, ensuring that your backed-up data remains secure even if unauthorized access occurs.
To optimize storage usage, especially for large backups, we can implement compression: This function creates a compressed ZIP file of the entire backup, significantly reducing the storage space required. Incorporating logging into our backup script can help with troubleshooting and monitoring: This logging setup creates a new log file for each backup operation, making it easy to review past backups and troubleshoot any issues that may arise.
Robust error handling is crucial for any automated script. Let's enhance our backup function with comprehensive error handling: This function catches and logs various exceptions that might occur during the backup process, ensuring that the script doesn't crash unexpectedly and provides useful information for debugging.
To truly automate our backups, we need to schedule them to run at regular intervals. While Python itself doesn't have a built-in scheduler, we can use system-level schedulers to achieve this. On Unix-like systems (Linux, macOS), we can use cron . Here's how to set up a daily backup at 2 AM: On Windows, you can use the Task Scheduler. Create a new task and set it to run your Python script at your desired schedule.
For added security and redundancy, consider implementing remote backups. Here's a simple example using the paramiko library for SFTP transfers: If you're backing up databases, you might need to use database-specific tools. Here's an example for MySQL: Ensure you have the necessary database client tools installed on your system for this to work.
This function keeps only the most recent backups (in this case, 7) and deletes older ones to free up storage space. Regularly testing your backup system is crucial to ensure its reliability. Here's a simple script to verify the integrity of your backups: This script randomly selects files from your backup and compares them with the source to ensure integrity.
Automating backups with Python offers a flexible, powerful solution for data protection. By implementing the techniques discussed in this comprehensive guide, you can create a robust, customized backup system tailored to your specific needs. Remember, the key to effective backups is consistency and reliability. Regularly review and update your backup strategy to ensure it continues to meet your evolving data protection requirements. With Python's versatility and the wealth of libraries available, you can create a backup solution that not only protects your data but also scales with your needs.
As you continue to refine your backup system, consider exploring additional Python libraries and tools that can further enhance your backup processes. The Python ecosystem is rich with resources that can help you tackle even the most complex backup scenarios. By taking the time to implement a well-thought-out, automated backup solution, you're not just protecting your data – you're investing in your peace of mind and the long-term security of your digital assets. Happy coding, and may your data always remain safe and accessible! Firebase has rapidly become one of the most popular backend-as-a-service (BaaS) platforms in recent years, allowing developers to build feature-rich applications without managing server infrastructure. It offers a wide range of tools and services, including a realtime database, authentication, cloud storage, and much more. In this in-depth guide, we‘ll walk through how to get started… NumPy, the powerhouse library for numerical computing in Python, has revolutionized the way data scientists and researchers handle large-scale computations. But what makes NumPy so blazingly fast compared to standard Python lists? Let's dive deep into the inner workings of NumPy and uncover the secrets behind its remarkable performance. The Foundation: Contiguous Memory and Homogeneous… Introduction Gradient descent is the cornerstone of modern machine learning optimization, powering everything from simple linear regression models to complex neural networks. Among its variants, mini-batch gradient descent stands out as a powerful technique that strikes an ideal balance between computational efficiency and model performance. In this comprehensive guide, we'll explore the intricacies of implementing… Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Telegram%20%28software%29 • https://en.wikipedia.org/wiki/RavenDB • https://en.wikipedia.org/wiki/IBM%20Db2 • https://www.py4u.org/blog/automate-backup-with-python-script/ • https://github.com/tonipapic/Python-Based-Data-Backup-and-Disaster-Recovery-System • https://networkyy.com/automating-system-backups-with-python/ • https://www.johal.in/disaster-recovery-planning-python-scripts-for-backup-automation-in-aws-2026/ • https://www.bomberbot.com/python/automating-backups-with-python-a-comprehensive-guide/ • https://github.com/VKHSoorya/mini-Disaster-Recovery-Simulation
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Encrypted Backup And Disaster Recovery Tool In Python.
[*] Metasploit Scan Running on Target Subnet for Encrypted Backup And Disaster Recovery Tool In Python... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |