Complete Technical Paper Content — Financial Fraud Detection Using Deep Learning Algorithms
Overview & System Context
Financial Fraud Detection Using Deep Learning Algorithms: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9506 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background This paper systematically reviews advancements in deep learning (DL) techniques for financial fraud detection, a critical issue in the financial sector. Using the Kitchenham systematic literature review approach, 57 studies published between 2019 and 2024 were analyzed. The review highlights the effectiveness of various deep learning models such as Convolutional Neural Networks, Long Short-Term Memory, and transformers across domains such as credit card transactions, insurance claims, and financial statement audits. Performance metrics such as precision, recall, F1-score, and AUC-ROC were evaluated. Key themes explored include the impact of data privacy frameworks and advancements in feature engineering and data preprocessing. The study emphasizes challenges such as imbalanced datasets, model interpretability, and ethical considerations, alongside opportunities for automation and privacy-preserving techniques such as blockchain integration and Principal Component Analysis. By examining trends over the past five years, this review identifies critical gaps and promising directions for advancing DL applications in financial fraud detection, offering actionable insights for researchers and practitioners.
Financial fraud encompasses deceptive practices such as credit card fraud, insurance fraud, and money laundering, resulting in significant financial losses and eroding trust in financial systems. Global estimates suggest that organizations lose 5% of annual revenues to fraud, which is equivalent to trillions of dollars. Traditional detection methods, such as manual reviews and rule-based systems, are increasingly inadequate against sophisticated schemes and the surge in digital transactions, which exceeded 2.7 billion in the United States in 2023 [ 22 ] .
Machine learning (ML) offers scalable solutions by analyzing large datasets to detect complex fraud patterns. Advanced techniques, including Convolutional Neural Networks (CNNs), Long Short-Term Memory (LSTM) networks, and Natural Language Processing (NLP), enable real-time anomaly detection and adaptation to evolving threats. These systems also align with regulations like European Union’s General Data Protection Regulation (GDPR) and California Consumer Privacy Act (CCPA), addressing privacy and compliance requirements.
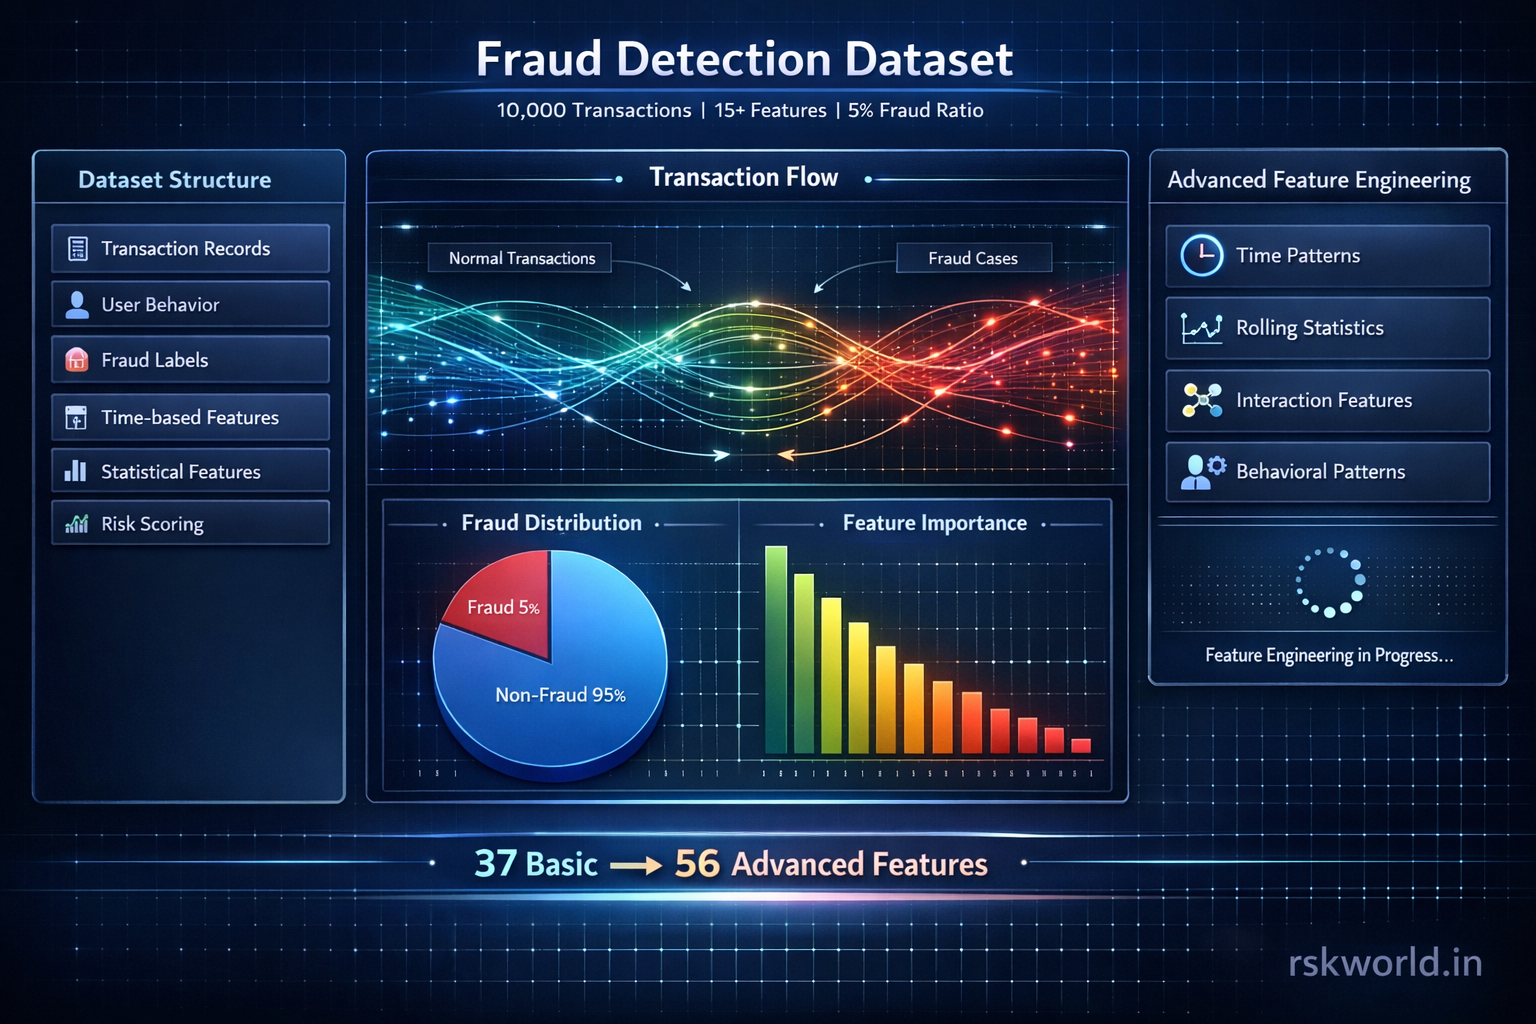
While ML has transformed fraud detection, challenges such as data quality, interpretability, and ethical concerns remain. This study explores recent advancements in ML techniques for fraud detection, focusing on applications, effectiveness, and compliance, and provides insights for future research. Figure 1: RSK World - Fraud Detection Dataset | Financial Fraud ML | Anti-Fraud ...
This study adopts the Kitchenham systematic review framework, known for its structured approach to evaluating advancements in dynamic fields. It facilitates a thorough analysis of literature, uncovering gaps, trends, and challenges in applying deep learning to financial fraud detection. Key stages, including study selection, data extraction, and synthesis, are customized to address the field’s interdisciplinary and algorithmic diversity. Ensuring transparency, replicability, and unbiased results, this framework provides a strong foundation for identifying opportunities and guiding future research.
This review explores critical aspects of applying deep learning to financial fraud detection through the following questions: What trends can be observed in the types of financial fraud addressed using deep learning in recent years? How have advancements in feature engineering, data preprocessing techniques with a focus on handling imbalanced data, and automation leveraging deep learning improved the performance and time-to-detection in financial fraud detection systems? Figure 2: Fraud Detection Algorithm , Fraud detection using machine learning ...
What advancements have been made in deep learning models for financial fraud detection? What trends can be observed in the benchmarks and evaluation metrics used to assess the effectiveness of deep learning models across different financial sectors? How have changes in data privacy, anonymization, and regulatory rules influenced the development and application of deep learning models for financial fraud detection? These questions align with the study’s objectives, offering insights for researchers and practitioners to drive innovation in financial fraud detection.
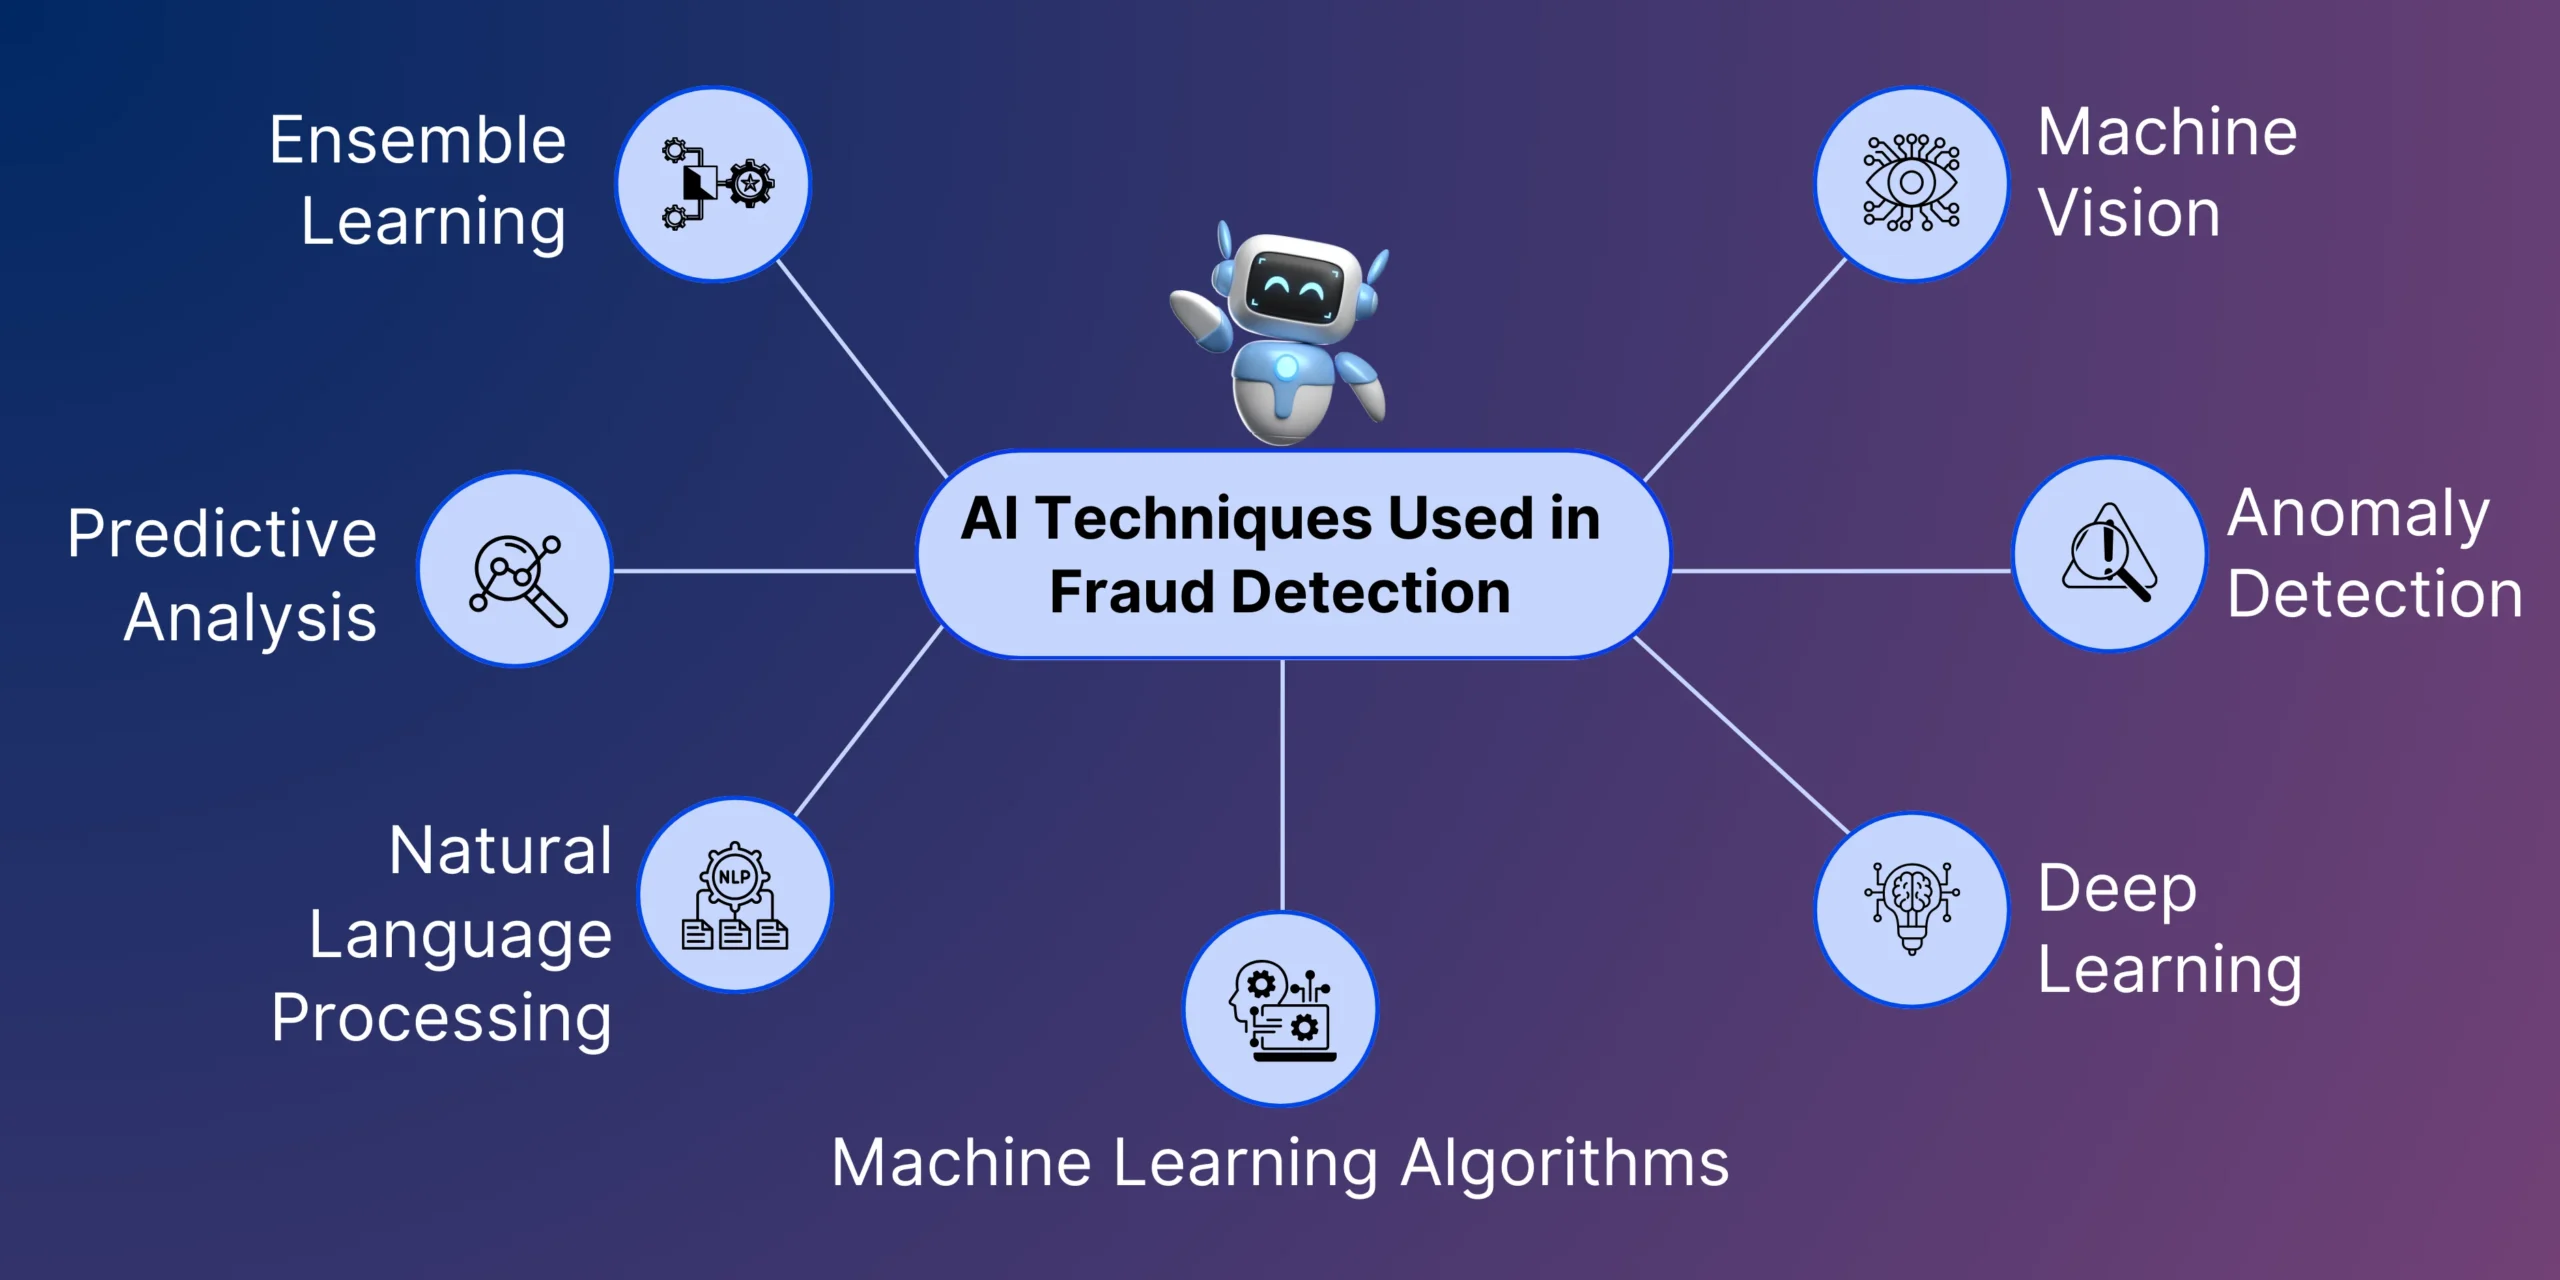
Figure 3: AI/ML Improve Fraud Detection Accuracy in Financial Institutions A comprehensive search strategy was developed to identify relevant studies addressing the research questions. The selected databases are: PubMed, SSRN, IEEE Xplore, ACM Digital Library, ScienceDirect, and Scopus for their interdisciplinary and technical coverage of the subject matter: The search query employed Boolean operators (”AND”, ”OR”) to combine keywords across three key domains: Method Keywords : Machine Learning OR Artificial Intelligence OR Data Mining OR Deep Learning OR Anomaly OR Algorithm Financial Sectors Keywords : bank OR financial OR insurance OR credit OR tax OR investment OR loan OR mortgage OR payment OR money laundering OR crypto OR blockchain OR membership OR subscription Limited subject areas to Computer Science, Business Management and Accounting, Economics Econometrics and Finance, Decision Sciences, and Engineering to target studies at the intersection of technology and finance.
The search process was documented to ensure replicability and transparency, with all queries and results managed using a reference management system to facilitate deduplication and screening. The study ensured relevance and quality by applying rigorous inclusion and exclusion criteria: Deep Learning Focus : Studies employing techniques like CNNs, RNNs, LSTMs, or Transformers in financial fraud detection.
Domain : Studies unrelated to financial services (e.g., banking, insurance, credit card fraud). To ensure consistency and comprehensiveness, a structured data extraction form was developed, standardizing the collection and synthesis of data across studies. This enabled clear comparisons while minimizing subjectivity. Data analysis utilized Python with libraries such as Pandas for data manipulation, Matplotlib for visualization, and Scikit-learn for machine learning and statistical tasks. VOSviewer further enhanced the process by visualizing keyword co-occurrence network graphs, uncovering connections and trends among key terms in the reviewed articles. This integrated approach ensured robust and insightful analysis.
The initial search query across all databases yielded a total of 2,858 papers. After eliminating duplicates and rigorously applying the inclusion and exclusion criteria, 427 relevant papers were identified for further evaluation. To ensure the quality and relevance of the selected studies, the authors conducted a detailed screening process, ultimately narrowing the selection to 57 high-quality papers that met the review’s objectives and standards. The process is shown in Figure 1 below.
What trends can be observed in the types of financial fraud addressed using deep learning in recent years? Figure 2 illustrates the number of peer-reviewed research papers published per year in the field of financial fraud detection using deep learning techniques from 2019 to 2024. From 2019 to 2021 there is a steady increase in the number of relevant papers, which reflects a growing interest in leveraging deep learning techniques in financial fraud detection. A significant increase in the number of papers can be observed starting in 2022. Particularly, there is a steep rise from 2023 to 2024. The yearly trend could be potentially driven by deep learning technologies advancements, increasing concerns related to financial frauds and policy regulation. Investigating the yearly trend by sector, credit card and banking are the major two sectors that contribute to the significant increase.
Figure 3 highlights the distribution of the most relevant research papers across various financial sectors. The noticeable amount of publications is related to credit card sectors [ 35 ] , which reflects the increasing awareness of fraud detection in credit card transactions. Public availability of credit card related datasets, such as the European Credit Card Transactions dataset Kaggle [ 39 ] has likely contributed to this trend, as it provides researchers with clean and standardized data to develop and evaluate state-of-the-art deep learning models.
Further, banking and insurance sectors show high focus in relevant research, emphasizing the growing need to tackle fraud in digital payment [ 55 , 21 , 50 ] , automobile insurance claims [ 40 , 26 ] , health insurance claims [ 53 , 52 ] . Emerging areas like crypto/blockchain and payment systems show a notable number of studies, indicating an increasing focus on fraud prevention in digital currencies [ 47 ] . However, sectors such as tax, mortgage/loan, and money laundering have relatively fewer publications, which could be due to limited access to domain-specific datasets or the complexity of detecting fraud patterns in these areas [ 9 ] .
According to the Consumer Sentinel Network Reports published by the Federal Trade Commission, bank transfers and payments accounted for the highest aggregate losses reported in 2023 ($1.86 billion), followed closely by Cryptocurrency ($1.41 billion), while credit cards were most frequently identified as the payment method in fraud reports. Additionally, insurance fraud saw a notable 26% increase compared to the previous year [ 22 ] . The sheer scale and rapid growth of financial fraud across these sectors have significantly driven the observed surge in research interest and innovation in this field.
How have advancements in feature engineering, data preprocessing techniques with a focus on handling imbalanced data, and automation leveraging deep learning improved the performance and time-to-detection in financial fraud detection systems? Financial fraud detection faces significant challenges due to imbalanced datasets, where fraudulent transactions represent a small fraction of the total [ 13 ] . Of 57 reviewed papers, 48 reported dataset imbalance issues, leading traditional machine learning models to favor the majority class and underperform on fraudulent cases. Addressing this requires advanced preprocessing and automation techniques.
Oversampling methods, such as the Synthetic Minority Oversampling Technique (SMOTE), generate synthetic samples by interpolating minority class instances, effectively enhancing class diversity and model robustness [ 4 , 40 ] . SMOTE has also proven effective for handling imbalanced datasets with missing values [ 30 ] . Stratified sampling, a probabilistic technique, divides data into strata based on timestamps to address non-stationary changes in transaction fraud characteristics. This ensures a higher representation of recent fraudulent transactions while maintaining randomness [ 16 ] .
Advanced approaches like Generative Adversarial Networks (GANs) and Variational Autoencoders (VAEs) produce realistic synthetic data while maintaining the original distribution, further supporting model training in scenarios of extreme class imbalance [ 32 ] . Data imputation techniques, such as k-Nearest Neighbors (kNN), address missing values to improve overall data quality.
Feature transformations, including scaling and normalization, play a critical role in reducing biases and enhancing the detection of fraud patterns. Techniques like Adaptive Synthetic Sampling (ADASYN) focus on harder-to-classify samples, while cluster-based oversampling generates synthetic data tailored to domain-specific contexts, ensuring alignment with real-world complexities.
Automation significantly accelerates fraud detection by reducing manual intervention and enabling substantial cost savings [ 11 ] . Subsampling techniques effectively select representative datasets, minimizing computational costs while preserving feature correlations [ 51 ] . The Very Fast Decision Tree (VFDT) algorithm efficiently processes real-time data streams and achieves exceptional performance when integrated with blockchain technology, ensuring secure and scalable updates [ 19 ] .
Blockchain enables decentralized, secure data sharing and automated fraud detection via smart contracts [ 10 ] , ensuring rapid responses and model adaptability [ 28 , 8 ] . Techniques like Stochastic Gradient Descent (SGD) optimize models incrementally [ 45 ] , while automated parameter tuning [ 60 ] and resampling hybrid techniques [ 48 , 31 ] enhances detection accuracy.
Knowledge distillation transfers insights from complex models to lightweight ones, enabling efficient real-time detection [ 54 ] . Fraud detection pipelines streamline processes, combining preprocessing and model training into cohesive systems. Stacking ensembles improve robustness by combining classifiers [ 59 ] , with methods such as the Random Forest Quantile Classifier optimizing sensitivity and specificity for imbalanced data [ 15 ] . These advancements ensure scalable, adaptable, and accurate fraud detection systems capable of addressing the complexities of financial fraud.
What advancements have been made in machine learning models for financial fraud detection? We have identified the following deep learning models, machine learning models, models, and hybrid models, which are widely used in fraud detection. Convolutional Neural Networks (CNNs) : By analyzing high-dimensional features such as time-series embeddings and transaction heatmaps, CNNs identify anomalies linked to unusual spending patterns or merchant-specific risks. It does not require heavy data preprocessing during training since it inherently captures the key features and performs feature dimension reduction [ 3 ] . It is found that deep features extracted from the CNNs enhance fraud detection when combining CNN with traditional models (SVM, KNN, NB, DT) [ 40 ] .
Recurrent Neural Networks (RNNs) : RNNs process sequential data by retaining context from previous inputs, making them useful for analyzing patterns in transaction histories. However, their capacity is limited by gradient vanishing and exploding gradient issues. Gated Recurrent Unit (GRU) and Long Short-Term Memory (LSTM) are specialized RNN and both GRU and LSTM mitigate the issues of gradient vanishing and exploding gradients in RNNs [ 7 ] .
Multi-Layer Perceptrons (MLPs) : MLPs, composed of interconnected layers, model relationships in structured data. MLP is a competitive choice for fraud detection, particularly in amount-based profiling and scenarios requiring the handling of non-linear relationships in data [ 14 ] . Transformers : Unlike CNNs and RNNs, which process all points in the input sequence step by step, transformers process all points at once. The self-attention mechanism and feed-forward networks of Transformers enable it to model complex relationships and extract meaningful features from sequential data, which is very useful to recognizing patterns in transactional data, user behavior, or network interactions in fraud detection.
Natural Language Processing (NLP) : NLP enhances fraud detection by analyzing unstructured textual data such as financial reports [ 59 ] , tax compliance and financial regulation [ 12 ] , and claims narratives [ 23 ] . Key techniques include sentiment analysis, readability metrics, and feature extraction (e.g., Bag-of-Words, TF-IDF, and word embeddings). These features are integrated with traditional fraud indicators in machine learning models, improving accuracy and recall [ 59 ] .
Variational Autoencoders (VAEs) and Generative Adversarial Networks (GANs) : GANs and VAEs are two popular types of generative models used in deep learning [ 27 ] . GANs excel in generating high-quality, realistic samples but are harder to train due to adversarial dynamics and lack an interpretable latent space. VAEs are better for representation learning and probabilistic modeling, with a well-structured latent space but generate samples of lower quality compared to GANs.
Combining the strengths of both VAEs and GANs can address the limitations of each in handling imbalanced data for fraud detection [ 20 ] . Graph Neural Networks (GNNs) : GNNs are highly effective in fraud detection because they can model complex interactions and relationships between entities (e.g., transactions, reviews) as graphs [ 25 ] . Fraud detection often involves analyzing these relationships to identify patterns and anomalies indicative of fraudulent activity [ 49 ] . GCNs are a specific type of GNN that applies the concept of convolution to graphs. Study shows that GCNs outperform traditional models like Logistic Regression (LR), Random Forest (RF), and Gradient Boosting Machines (GBMs) in detecting fraudulent transactions [ 57 ] .
Deep Belief Networks (DBNs) : DBNs is one of the foundational deep learning methods for fraud detection, valued for their feature extraction and classification capabilities. However, their use is limited compared to more advanced methods such as CNNs, which demonstrate greater accuracy and scalability in handling fraud detection tasks [ 3 ] . The machine learning models can be a baseline or part of a hybrid model: Traditional machine learning algorithms serve as essential benchmarks for financial fraud detection [ 17 ] . Logistic Regression (LR) offers simplicity and interpretability, ideal for binary classification. LinearSVC efficiently handles linear data, while KNN detects anomalies based on proximity, though it lacks scalability for large datasets.
Ensemble methods such as Random Forests and Gradient Boosting (XGBoost, LightGBM) improve accuracy by combining multiple models. Random Forests resist overfitting, while Gradient Boosting handles imbalanced datasets effectively. Adaptive Boosting (AdaBoost) strengthens weak classifiers iteratively for fraud-specific challenges. 2. System Architecture & Core Working Principles Support Vector Machines (SVMs) excel in high-dimensional spaces, identifying outliers effectively. Decision Trees, though prone to overfitting, remain interpretable and foundational for ensemble models.
While less adaptive than deep learning, these algorithms provide valuable benchmarks, offering insights into structured data performance and guiding advancements in fraud detection systems. Hybrid models integrate complementary strengths of different algorithms to address complex tasks like financial fraud detection. Adaptive Sampling and Aggregation-Based Graph Neural Network (ASA-GNN) enhances traditional GNN frameworks by integrating adaptive sampling and entropy-based aggregation, which address the major limitations of standard GNNs in handling fraud detection. By focusing on relevant neighbors and combating oversmoothing, ASA-GNN provides a robust and scalable solution for identifying complex fraud patterns in graph-structured data [ 56 ] .
Reinforcement Learning with Deep Q-Network (RDQN) integrates deep learning (DNN) and reinforcement learning(Q learning). By leveraging Rough Set Theory for feature reduction and employing reinforcement learning, the RDQN model achieves faster processing and higher accuracy, making it a scalable and effective solution for real-world fraud detection problems. RDQN outperforms traditional models like SVM, ANN, and DT, as well as hybrid models such as IFDTC4.5, SAE-GAN, and CNN-SVM-KNN [ 55 ] .
Transformer-LOF-Random Forest model uniquely combines the Transformer’s advanced feature extraction, LOF (local outlier factor) ’s local anomaly detection, and Random Forest’s ensemble learning to effectively detect complex and rare fraudulent patterns. It surpasses state-of-the-art models such as XGBoost, LightGBM, and LSTM by addressing data imbalance, reducing false positives and false negatives, and adapting to emerging fraud techniques [ 38 ] .
ResNeXt-embedded Gated Recurrent Unit (RXT-J) integrates the feature extraction capabilities of ResNeXt and the sequential learning strengths of Gated Recurrent Units (GRU). RXT-J model significantly outperforms existing models, including BERT (Transformer), ANN, and logistic regression [ 7 ] . CatBoost-Deep Neural Networks combines CatBoost and Deep Neural Networks (DNN) to leverage their respective strengths. CatBoost excels at handling categorical features, imbalanced datasets, and complex relationships in structured data [ 36 ] . while DNN focuses on learning patterns in raw features and adapting to sparse data conditions. The hybrid model significantly outperforms others such as random forests and ensemble methods such as LSTM-based AdaBoost [ 44 ] .
Autoencoder-LSTM is a combination of two deep learning models: Autoencoder and LSTM. Autoencoder performs dimensionality reduction while retaining key features and removing noise. LSTM network models temporal dependencies and classifies transactions as fraudulent or legitimate. The combined model demonstrates superior performance over traditional machine learning methods and standalone LSTM models [ 61 ] .
We observe the overall pattern of frequency of application of deep learning models in Figure 4 . LSTM, MLP, CNN and RNN are most widely used. NLP methods such as Bidirectional Encoder Representations from Transformer (BERT) model are moderately applied for textual dataset. Additionally, more specialized methods have been applied to detect fraud, including GNNs, GANs, VAEs. As fraud detection datasets are highly imbalanced, while GANs are moderately applied, their potential in modeling relationships and generating synthetic datasets for fraud detection could drive more research in these areas.
Baseline methods. This study analyzes the yearly trend of deep learning algorithms in fraud detection. As shown in Figure 5 , overall the variability of deep learning models has increased over years. LSTM has the most significant and sustained growth over the years, culminating in a sharp increase from 2022 to 2024. This trend could be driven by the sequential nature of fraud datasets. MLP and CNNs model maintain a steady trend. These models are versatile and effective in learning complex relationships between features in financial datasets.
Deep learning methods across sectors. Figure 8 demonstrates the distribution and frequency of various deep learning algorithms applied to financial fraud detection across different financial sectors. Both the credit card and banking sectors have significant applications of a wide range of deep learning techniques. Particularly, MLP, LSTM, and CNN have been more commonly used. LSTM and GNN show significant application, likely due to the sequential and graph-structured nature of blockchain data, which requires methods that can model relationships between transactions. Sectors such as Tax and Money Laundering show minimal application of deep learning techniques.
To explore the interconnection between various methods and domains, this study conduct a semantic network analysis in Figure 9 : Cluster 1 (colored in red) has 10 keywords related to machine learning models, including Random Forest, Logistic Regression, SVM, Ensemble, Decision Tree, etc. Random forest (with 32 links and 234 link strength) and logistic regression (with 31 links and 191 link strength) are the two most relevant keywords. These two traditional machine learning models are most frequently connected with keywords representing deep learning, indicating the models are often used as baselines or hybrid models.
Cluster 2 (colored in green) has 10 keywords related to deep learning models, including Transformer, BERT, RNN, etc. MLP (with 27 links and 103 link strength) is the most relevant keyword. It is well connected with CNN, LSTM, SVM and Random Forest. Cluster 3 (colored in blue) has 7 keywords related to lightweight models, including Naive Bayes, KNN, decision trees. This smaller cluster represents lightweight models used for simple datasets.
Cluster 4 (colored in yellow) has 6 keywords related to both financial sectors and deep learning models. Credit card is the most relevant node with 30 links and 160 link strength. It also includes deep learning algorithms such as CNN and GAN, indicating the popular trend of CNN and GNN in fraud detection, especially in credit card and banking. Cluster 5 (colored in purple) has 4 keywords related to more specialized deep learning models such as GAN, VAE. It shows an emerging trend of applying GAN for generating synthetic data to address imbalanced datasets.
In summary, classical ML methods (e.g., Random Forest, SVM) remain foundational for structured data fraud detection. Techniques like LSTM, Transformers, and BERT show increasing adoption for analyzing sequential and text-based fraud data. GNNs and GANs are gaining traction in specialized fraud domains like blockchain and synthetic data generation. Different algorithms are tailored to the needs of specific financial sectors (e.g., CNN for credit card fraud, GNN for blockchain).
What trends can be observed in the benchmarks and evaluation metrics used to assess the effectiveness of deep learning models across different financial sectors? Traditional metrics face limitations in handling imbalanced datasets where fraud cases are rare. Metrics like Accuracy often mislead, favoring the majority class and overlooking fraud. Precision minimizes false positives but may reduce Recall , which identifies actual fraud cases. High Recall, while critical, can increase the False Positive Rate (FPR) and operational costs. The F1 Score balances Precision and Recall but does not address economic impacts.
Metrics such as False Negative Rate (FNR) and FPR highlight specific challenges, like losses from undetected fraud or inefficiencies from false alarms. AUC-PR (Precision-Recall Curve) is more relevant than AUC-ROC for imbalanced datasets, focusing on fraud detection effectiveness. The metrics and their formulas are shown in Table 1 below. Economic metrics, such as the Cost of False Positives and Cost of False Negatives , assess operational and financial impacts, helping organizations optimize detection strategies. For instance, Precision is prioritized in cryptocurrency fraud to minimize compliance costs, while Recall is critical in tax fraud to prevent revenue losses.
In conclusion, effective fraud detection increasingly relies on tailored metrics that address imbalanced datasets, operational costs, and sector-specific needs, complementing foundational metrics like Accuracy and F1 Score with domain-specific benchmarks. How have changes in data privacy, anonymization, and regulatory rules influenced the development and application of deep learning models for financial fraud detection? Of the 57 papers reviewed, 36 of them have publicly available datasets and 24 non-public dataset. 19 of the papers addressed the issue regarding privacy.
Principal Component Analysis (PCA) enhances data privacy in fraud detection by reducing high-dimensional data into lower-dimensional representations, preserving critical information while minimizing information loss [ 3 ] . This transformation anonymizes transactional data, removing identifiable personal information and enabling secure sharing across institutions without exposing sensitive details. Additionally, PCA aids compliance with data protection regulations by mitigating re-identification risks and retaining only essential features needed for fraud detection, reducing unnecessary exposure of sensitive transaction details. However, by altering the original features, PCA can reduce model interpretability, potentially limiting insights into the relationships between variables [ 6 ] . Despite this, its ability to balance privacy and performance makes it a valuable tool for secure data processing.
Blockchain enhances data privacy in financial fraud detection through its decentralized and immutable nature, eliminating the need for centralized intermediaries. [ 18 , 41 ] Sensitive data, such as personal identities and financial transactions, is securely distributed across an encrypted ledger, preventing unauthorized access. Pseudonymity is ensured by cryptographic addresses, further safeguarding personal information [ 29 ] .
Both the General Data Protection Regulation (GDPR) and the California Consumer Privacy Act (CCPA) significantly impact the application of machine learning in financial fraud detection by enforcing strict data privacy, security, and transparency requirements. GDPR mandates organizations to obtain consent, anonymize sensitive data, and adhere to ethical standards, emphasizing transparency, accountability, and data minimization [ 42 ] . Similarly, CCPA grants individuals the right to access, delete, or opt out of data usage, requiring ML models to anonymize or pseudonymize data to protect identities.
A critical GDPR mandate is the ”right to explanation,” which ensures AI decisions, such as fraud detection outcomes, are interpretable [ 34 ] . This presents a challenge for complex models like deep neural networks, prompting the development of explainability techniques to balance compliance and performance. CCPA similarly emphasizes consumer control and data minimization, posing challenges for ML systems reliant on extensive datasets. To comply with both regulations, techniques like data anonymization, federated learning, and secure multiparty computation have become essential. Non-compliance risks penalties under both frameworks, driving organizations to invest in secure, transparent, and privacy-preserving ML systems, which ultimately enhance trust, scalability, and effectiveness in fraud detection.
The Cooperative Council for Health Insurance (CCHI) regulates private health insurance in Saudi Arabia, ensuring fraud prevention, data integrity, and healthcare accessibility. Under Saudi Vision 2030, CCHI mandates detailed records of fraud, fostering transparency and accountability among insurers and providers [ 43 ] . CCHI’s initiatives, like the National Platform for Health and Insurance Exchange Services (NPHIES), enhance data security and interoperability. Leveraging advanced technologies, including machine learning, the platform improves fraud detection and processing efficiency, aligning with goals to reduce fraud costs and comply with data protection and ethical standards in health insurance.
Fraud detection using advanced techniques is critical in the financial sector due to increasingly sophisticated fraudulent activities. This study examines the use of deep learning across financial domains, highlighting shared techniques and sector-specific challenges. The following sections discuss key applications and advancements in credit card fraud detection, insurance fraud, blockchain integration, and banking systems.
Credit card fraud detection has become a widely researched area with deep learning applications. Due to access to publicly available large-scale datasets, applications of state-of-the-art deep learning and machine learning models have achieved significant success. Techniques such as deep neural networks, and data augmentation could play pivotal roles in overcoming data imbalance and improving model performance. Credit card fraud detection often requires real-time or near-real-time decision-making. Deep learning models can process large volumes of transaction data quickly and accurately, making them ideal for these applications [ 46 , 1 ] .
Insurance fraud poses significant challenges due to extensive data exchanges among patients, providers, and insurers, increasing vulnerabilities like data breaches and inaccuracies. Privacy regulations such as HIPAA and GDPR further complicate data sharing by imposing strict safeguards on personal health information [ 18 ] . Deep learning techniques effectively analyze complex datasets to detect anomalies and predict fraud. Federated learning enables collaborative model training among insurers and providers without exposing sensitive data, ensuring compliance with privacy regulations while enhancing detection efficiency [ 29 ] . Combined with smart automation, these innovations address key challenges in fraud prevention and operational complexity.
Blockchain provides a secure, decentralized ledger that ensures data integrity and privacy, with transparency that enhances fraud detection and auditability, particularly in healthcare insurance [ 28 ] . Integrating blockchain with machine learning improves fraud detection by leveraging immutable datasets for anomaly detection and prediction [ 37 ] . Permissioned blockchains enable secure data sharing through distributed ledgers, improving accuracy and transparency [ 19 , 5 ] . In the insurance sector, combining blockchain with ML models, such as XGBoost and VFDT, has increased detection accuracy and reduced error rates by 7% compared to traditional methods [ 19 , 24 ] . Additionally, smart contracts streamline claims processing, reducing errors and processing time [ 5 , 33 ] . Despite challenges like scalability and compliance, these technologies are highly effective in insurance fraud detection and lay the foundation for secure, efficient systems.
The banking sector faces increasingly sophisticated fraud due to the growth of online banking and diverse payment channels, especially in money laundering, which impacts economies at multiple levels. Traditional rule-based systems often fail to adapt to evolving fraud patterns, leading to high false positive rates. Deep learning models, such as LLMs, analyze complex data to identify anomalies in transactions and spending behaviors, flagging potential fraud effectively [ 58 , 46 ] . Key challenges include real-time detection, managing large-scale transnational networks, and integrating diverse data sources like Know Your Customer (KYC) profiles. Addressing these issues requires innovative, scalable solutions to combat financial fraud efficiently [ 57 ] .
This study systematically reviews advancements in deep learning for financial fraud detection but has limitations in its approach. First, the selection of studies between 2019 and 2024 excludes earlier foundational work that may provide additional context. Second, while focusing on publicly available literature ensures transparency, it leaves out proprietary models and industry-specific practices that might offer innovative insights. Third, inconsistencies in data processing and evaluation frameworks across the reviewed studies make cross-comparison of findings challenging. Additionally, the reliance on English-language publications restricts insights from regions where other languages predominate, potentially missing localized advancements or applications.
Future research should prioritize standardization across the Data Science lifecycle to enhance reproducibility and generalizability in financial fraud detection. Key areas of focus include: Data Preparation : Develop unified preprocessing pipelines that address imbalanced datasets through advanced techniques like GANs, SMOTE, and feature scaling to improve model reliability across studies.
Model Development : Encourage collaboration between academia and industry to bridge research and real-world implementation, incorporating state-of-the-art techniques like explainable AI and automated parameter tuning for scalable deployment. Model Evaluation : Establish comprehensive benchmarks tailored to specific financial domains, integrating economic and operational metrics to better reflect real-world costs and impacts.
Operational Deployment : Focus on integrating deep learning models with existing systems, emphasizing robust APIs, real-time fraud detection, and compliance with data privacy regulations. Monitoring and Maintenance : Promote adaptive frameworks that allow ongoing model tuning and retraining, ensuring systems evolve alongside emerging fraud techniques and regulatory changes.
By addressing these directions, future studies can provide more actionable, scalable, and compliant solutions, contributing to the ongoing advancement of deep learning applications in fraud detection. The findings from this systematic literature review underscore the transformative role of deep learning in financial fraud detection. By analyzing recent advancements, it becomes clear that deep learning models, including CNNs, LSTMs, transformers, and ensemble techniques, have significantly enhanced the ability to detect complex fraud patterns across diverse financial sectors. These models, combined with robust preprocessing and feature engineering techniques, address key challenges such as imbalanced datasets and operational scalability, leading to more accurate and efficient fraud detection systems.
Moreover, the integration of privacy-preserving methods, such as blockchain, PCA, and compliance with global regulations like GDPR and CCPA, ensures that these advancements are aligned with ethical and legal standards. These measures not only protect sensitive financial and personal data but also build trust among stakeholders and foster broader adoption of advanced fraud detection solutions. The exploration of automation techniques, including parameter tuning and subsampling, has further accelerated time-to-detection, making real-time fraud mitigation feasible in high-stakes environments.
As fraud detection systems evolve, future research should focus on enhancing model interpretability, addressing emerging fraud schemes, and improving cross-industry collaboration through federated learning and secure data sharing frameworks. This will ensure that deep learning systems remain resilient and adaptable in an ever-changing financial landscape. The insights from this study serve as a foundation for advancing both the technical and operational aspects of fraud detection, fostering a more secure and trustworthy financial ecosystem.
3. Software Implementation, Frameworks & Protocols Access to this page requires authorization. You can try signing in or changing directories . This reference architecture demonstrates how to use Microsoft Fabric Real-Time Intelligence to build comprehensive fraud detection solutions that process real-time transaction data from multiple financial channels. The architecture enables you to ingest continuous transaction streams, integrate Enterprise Resource Planning (ERP) asset data, and apply machine learning models to detect fraudulent activity as it occurs. By using this approach, you can implement intelligent fraud prevention, real-time risk scoring, and automated response systems that protect your organization and customers.
Financial institutions face increasingly sophisticated fraud threats across mobile banking apps, ATMs, e-commerce platforms, and call centers. This architecture provides a unified platform to monitor all these channels simultaneously, correlate suspicious patterns across data sources, and trigger immediate alerts when fraud indicators are detected. By combining streaming analytics with historical pattern analysis, you can reduce fraud losses while minimizing false positives that impact legitimate customers.
The fraud detection reference architecture uses Microsoft Fabric Real-Time Intelligence to create a unified platform that processes real-time transaction data and integrates ERP asset information for intelligent fraud prevention. The following diagram illustrates the four main operational phases of the architecture: Ingest and process, Analyze, Transform and enrich, Train and score, and Visualize & activate.
Eventstreams ingests streaming transaction data from custom API endpoints of mobile banking apps, ATMs, e-commerce sites, and call centers. Eventhouse receives events where streaming transformations are applied to normalize transaction types, filter safe behavior patterns, and aggregate recent transaction spikes per user and device.
Data is streamed in real time, loaded into the raw transaction table, enriched with customer profiles, deduplicated, and analyzed for high-suspicion signals. Data Science ML models compute a fraud risk score for each transaction based on behavioral patterns and historical data. Activator alerts internal fraud teams when a transaction surpasses the fraud risk threshold or matches a known fraud signature.
Fraud analysts use Real-Time Dashboards monitor high-risk transactions and risk trends by region or customer segment. Real-Time Dashboards provide a high-granularity view of the entire financial ecosystem with low latency, enabling drill-down from overall transaction patterns to specific customer transactions. Rich Power BI reports provide a comprehensive business view of transaction data, fraud trends, and operational performance.
The operational phases describe how the architecture delivers end-to-end, real-time fraud detection - from capturing transaction signals across financial channels to activating automated responses and analyst workflows. Each phase builds on the previous one, ensuring that raw events are continuously transformed into actionable fraud intelligence with minimal latency and full cross-channel context.
The ingest and process phase establishes the real-time foundation of the fraud detection architecture by continuously capturing transaction data from all financial touchpoints. By streaming events as they occur, this phase ensures that every user action and transaction signal is immediately available for downstream analysis. This approach enables timely identification of suspicious behavior across the entire financial ecosystem.
Eventstreams seamlessly ingests streaming data from custom API endpoints of mobile banking apps, ATMs, e-commerce sites, and call centers. This continuous data integration captures comprehensive fraud detection information across multiple financial channels, including: Mobile banking transactions with real-time session patterns, geolocation data, and device fingerprinting.
ATM transaction feeds providing cash withdrawal patterns, velocity checks, and geographic distribution analysis. E-commerce platform data including purchase behaviors, merchant correlations, and payment method verification. Call center interactions capturing authentication attempts, account modifications, and dispute reporting. The analyze, transform, and enrich phase converts raw streaming events into high-value fraud intelligence through real-time processing and contextualization. During this phase, the system standardizes, correlates, and enriches events with historical and customer data. With this approach, the system surfaces meaningful patterns, anomalies, and risk indicators across channels.
Events enter Eventhouse , where streaming transformations refine data. These transformations normalize transaction types, filter safe behavior, and aggregate recent transaction spikes per user or device. This real-time processing enables streaming data refinement through: Behavioral filtering - Identifying safe patterns while flagging suspicious activities. âI¯ Data streams in real time, loaded into the raw transaction table, enriched, deduplicated, and analyzed for high-suspicion signals and aggregates. Advanced processing includes: Cleaned data streams into OneLake tables, enabling comprehensive fraud intelligence through: The train and score phase uses advanced machine learning to evaluate transaction risk in real time. This phase uses continuously trained models and adaptive scoring techniques, and assigns fraud risk scores to individual transactions while supporting transparency, explainability, and continuous improvement of detection accuracy.
Fraud detection ML models compute a fraud risk score for each transaction by using Data Science capabilities. Advanced fraud prevention includes: Real-time risk scoring : Evaluates each transaction as it occurs by applying behavioral, device, and location-based signals to determine fraud risk and enable immediate response.
Advanced ML models : Improves fraud detection accuracy through adaptive, multi-model techniques that continuously learn from outcomes, and provide explainable insights for investigation. The visualize and activate phase turns fraud insights into immediate action through dashboards, alerts, and automated responses. This phase empowers fraud analysts with real-time visibility into risk signals while enabling the system to trigger proactive interventions. This approach ensures that emerging threats are investigated, escalated, or mitigated without delay.
Fraud analysts use the Real-Time Dashboard to monitor high-risk transactions and risk trends by region or customer segment. The dashboard provides comprehensive fraud monitoring by using the following features: Activator alerts internal fraud teams when a transaction surpasses the fraud risk threshold or matches a known fraud signature. It includes automated fraud responses such as: Real time dashboards provide a rich, high granularity view of the entire financial ecosystem with low latency and the ability to drill down from overall transaction patterns to specific customer transactions. Features include: By using Copilot , fraud analysts can ask natural language questions, enabling conversational fraud analytics and simplified investigation support.
This architecture delivers measurable technical benefits by combining real-time data ingestion, advanced analytics, and automated response capabilities into a unified fraud detection platform. The outcomes span improved fraud intelligence, faster operational response, deeper analytical insight, and more efficient use of resources. Financial institutions can reduce risk while maintaining operational agility and cost control.
The solution enables real-time, intelligence-driven fraud detection by continuously analyzing transaction activity across all financial channels. By correlating streaming data with customer, device, and behavioral context, the platform provides high-fidelity fraud insights that support rapid detection, proactive prevention, and detailed investigation at transaction-level granularity.
Real-time fraud monitoring continuously analyzes streaming transaction data to enable immediate fraud risk assessment and prevention. Predictive fraud analytics use machine learning models to compute fraud risk scores and identify potential threats before financial loss occurs.
Unified fraud platform integrates transaction data from multiple financial channels with asset information to deliver comprehensive fraud intelligence. High granularity analysis provides real-time dashboards that enable drill-down from system-level views to individual transaction fraud assessment.
Automation transforms fraud detection from a reactive process into a proactive operational capability. By combining real-time risk evaluation with rule-based and model-driven actions, the architecture enables immediate alerts, orchestrated workflows, and dynamic control of fraud response mechanisms. This approach reduces response times and operational friction. Intelligent fraud alerting delivers real-time notifications when fraud risk thresholds are exceeded or known fraud signatures are detected.
Automated fraud workflows trigger fraud investigations, transaction blocking, and customer notification processes without manual intervention. Proactive fraud prevention applies predictive models to detect fraud and initiate automated responses before financial impact occurs.
Dynamic risk management enables real-time adjustments to fraud thresholds, detection rules, and response procedures as risk conditions evolve. This architecture supports advanced analytical workloads by unifying real-time and historical data into a single analytical foundation. It enables deep crossâIIchannel analysis, predictive fraud modeling, and conversational insights. Analysts and stakeholders can explore fraud patterns, optimize detection strategies, and make informed decisions using intuitive BI and AIâIIdriven tools.
Real-time fraud analytics correlate transaction data with customer behavior to enable immediate fraud detection and risk optimization. Cross-channel intelligence delivers deep BI reports with comprehensive fraud analysis across mobile banking, ATMs, e-commerce, and call centers.
Natural language processing enables analysts to query complex fraud scenarios using conversational AI and intuitive investigation interfaces. Predictive and historical analysis combines real-time events with historical patterns to support optimal fraud prevention and risk management.
4. Practical Deployment, Analysis & Case Studies By improving detection accuracy and automating investigation and response processes, the solution helps optimize the cost and efficiency of fraud operations. Predictive analytics reduce financial losses and unnecessary manual effort, while dataâIIdriven insights enable organizations to balance fraud risk, operational overhead, and longâIIterm investment decisions more effectively.
Predictive cost management reduces fraud losses and investigation costs through ML-driven fraud detection and prevention optimization. Fraud prevention efficiency maximizes detection accuracy while minimizing false positives by using predictive analytics and real-time monitoring.
Investigation optimization enhances fraud investigation effectiveness through predictive analytics and automated case management. Strategic decision support enables data-driven decisions for fraud prevention investment, risk tolerance, and operational improvements.
Implementing a realâIItime fraud detection solution requires careful planning across data architecture, security, integration, and operational management. These considerations help ensure that the platform can handle highâIIvolume transaction workloads, meet stringent latency and compliance requirements, and integrate seamlessly with existing financial systems while remaining scalable and costâIIefficient.
A robust data architecture is foundational to effective real-time fraud detection. The platform must support high-throughput ingestion, low-latency processing, and consistent data quality while scaling to accommodate increasing transaction volumes, new channels, and evolving fraud patterns across the organization. High-throughput ingestion processes streaming transaction data from mobile banking, ATMs, and e-commerce platforms while supporting burst capacity during peak transaction periods.
Real-time processing ensures immediate response times for critical fraud alerts, subsecond risk scoring, and continuous fraud detection. Data quality and validation implements real-time validation for transaction accuracy, customer identification, fraud indicators, and risk calculations with automatic error correction.
Scalability planning supports growing transaction volumes, an expanding customer base, new financial channels, and evolving fraud threats. Storage requirements plans for comprehensive fraud data, including real-time events, historical transaction records, and investigation documentation, with appropriate retention policies.
Financial systems integration enables seamless connectivity with banking platforms, payment processors, and fraud prevention systems. Security and regulatory compliance are critical for handling sensitive financial and customer data. The solution must enforce strong access controls, maintain comprehensive auditability, and protect data privacy in alignment with financial regulations and industry standards. Ensure trust and accountability across all fraud detection and investigation workflows.
Access controls implement role-based access aligned with fraud detection responsibilities, enforce multifactor authentication for all system access, and apply privileged access management for administrative functions. Audit trails create comprehensive, immutable logging of fraud detection activities, investigation workflows, and system access to support compliance and automated reporting.
Data privacy ensures compliance with financial regulations, data protection requirements, and customer privacy laws for transaction and fraud investigation data. Effective fraud detection depends on seamless integration with existing enterprise and external systems. The architecture should provide well-defined integration points that enable real-time data exchange with financial platforms, fraud prevention tools, enterprise systems, and external intelligence sources to ensure complete and timely fraud context.
Financial systems integrate with mobile banking platforms, ATM networks, and payment processing systems to ingest real-time transaction data. ERP systems integrate with customer relationship management, asset management, and enterprise resource planning platforms to enrich fraud analysis with enterprise context.
Fraud prevention tools integrate with existing fraud detection systems, risk management platforms, and security information systems to extend and coordinate fraud defenses. External data sources integrate through APIs that provide threat intelligence feeds, regulatory databases, and financial crime information-sharing networks.
Comprehensive monitoring and observability ensure that the fraud detection platform operates reliably, efficiently, and costâIIeffectively. By tracking system health, data quality, performance metrics, and cost signals in real time, organizations can proactively detect problems, optimize resource usage, and continuously improve fraud prevention effectiveness. Operational monitoring focuses on maintaining the reliability, accuracy, and performance of the realâIItime fraud detection pipeline. By continuously observing system health, data validity, and endâIItoâIIend latency, organizations can quickly identify problems, maintain serviceâIIlevel objectives, and ensure that fraud signals and alerts are processed without disruption.
System health dashboards provide real-time monitoring of transaction data ingestion, Eventhouse processing, and Activator fraud alert delivery, with automated alerting for system anomalies. Data quality monitoring continuously validates incoming transaction data and triggers alerts for communication failures, invalid fraud indicators, or corrupted financial information.
Performance metrics track data ingestion latency from financial systems, fraud risk scoring response times, and ML model prediction accuracy with service-level agreement (SLA) monitoring. Cost optimization ensures that fraud detection capabilities scale efficiently as transaction volumes and analytical complexity grow. By actively managing capacity, storage lifecycles, and operational spend, organizations can balance fraud prevention effectiveness with cost control while aligning resource usage with business and regulatory requirements.
Capacity management right-sizes Fabric capacity based on transaction volume and fraud detection complexity, applies autoscaling during peak transaction periods, and optimizes costs during low-activity windows. Data lifecycle management automates archival of older fraud data to lower-cost storage tiers, enforces retention policies aligned with regulatory requirements, and removes nonessential investigation data.
Fraud prevention optimization correlates fraud detection performance with operational costs in real time to minimize investigation expenses and maximize prevention effectiveness. The next steps outline a practical, phased approach for implementing and scaling a realâIItime fraud detection solution using Microsoft Fabric RealâIITime Intelligence. These phases help organizations move from foundational setup to enterpriseâIIscale operations in a controlled and incremental manner, reducing risk while accelerating time to value.
The getting started phase focuses on establishing the core architectural foundation for realâIItime fraud detection. It guides teams through initial planning, service configuration, and baseline integrations needed to ingest, process, and analyze transaction data with low latency and high reliability. Phase 1 establishes the technical baseline required for realâIItime fraud detection. During this phase, teams evaluate platform capabilities, design ingestion and processing pipelines, and configure core services to ensure the architecture can support current transaction volumes and fraud detection requirements.
Review Microsoft Fabric Real-Time Intelligence capabilities and assess capacity requirements based on your fraud detection scale, including transaction volumes, financial channels, and fraud complexity. Plan your Eventstream integration strategy for ingesting transaction data from mobile banking, ATMs, and e-commerce platforms, starting with the highest-risk transaction types and channels.
Design your real-time analytics implementation in Eventhouse to process fraud events with immediate response and low-latency requirements. Configure OneLake to store asset information and support historical fraud analytics with appropriate data retention policies. Phase 2 validates the architecture through a targeted pilot deployment. By starting with a limited set of channels and use cases, teams can confirm performance, integration reliability, and fraud detection effectiveness before expanding to broader transaction coverage.
Start with a subset of financial channels and transaction types to validate the architecture and assess integration performance. Implement core data flows to support fraud monitoring, real-time risk scoring, and basic alerting capabilities. Establish integrations with financial systems and ERP platforms to enable comprehensive fraud detection visibility.
Deploy Real-Time Dashboard to support fraud monitoring with highâIIgranularity transaction analysis and risk assessment. Phase 3 focuses on readiness for production operations. This phase ensures that the system performs reliably under peak loads, meets regulatory requirements, and supports fraud analysts with the tools, dashboards, and workflows needed for effective dayâIItoâIIday operations.
Test system performance during peak transaction volume periods and simulated fraud attack scenarios to validate resilience and responsiveness. Validate Activator rules to ensure correct configuration of fraud threshold alerts and fraud signature detection management. Ensure compliance with applicable financial regulations and industry fraud prevention standards.
Train fraud detection teams on dashboard usage, alert management, and investigation workflows to optimize fraud prevention effectiveness. The advanced implementation phase extends the foundation to support sophisticated automation, advanced analytics, and enterpriseâIIwide scale. These enhancements enable organizations to continuously optimize fraud detection accuracy, operational efficiency, and strategic insight as fraud patterns evolve.
5. Performance Evaluation & Extended Technical Observations This phase introduces advanced machine learning, automation, and AIâIIdriven capabilities to enhance fraud detection and response. By integrating predictive models, automated actions, and conversational analytics, organizations can move toward proactive, intelligenceâIIdriven fraud prevention.
Set up advanced Data Science capabilities to build, train, and score sophisticated fraud detection ML models for risk assessment and prevention optimization. Implement Activator to automate fraud response, including predictive transaction blocking, dynamic risk adjustments, and investigation workflow orchestration.
Deploy Copilot to enable natural language analytics, allowing fraud teams to query complex investigation scenarios through conversational interfaces. Create intelligent fraud detection systems that deliver real-time decision support based on transaction patterns, customer behavior, and fraud intelligence.
EnterpriseâIIscale deployment focuses on expanding the solution across all financial channels, customer segments, and operational teams. This phase emphasizes centralized monitoring, advanced analytics, and enterpriseâIIgrade ML models to support consistent, scalable, and compliant fraud prevention at organizational scale. Scale to full fraud detection operations by expanding transaction coverage and centralizing monitoring across all financial channels and customer segments.
Implement advanced analytics to optimize cross-channel fraud detection, streamline investigation management, and measure prevention effectiveness. Create comprehensive dashboards using DirectQuery capabilities and ../dashboard-real-time-create.md for executive reporting, operational monitoring, and regulatory compliance.
Develop enterprise-grade machine learning models to support fraud prediction, customer behavior analysis, and financial crime prevention. External fraud, often linked to broader financial crime activity, can be difficult to understand and assess. Managing fraud related risk often begins with understanding who you are doing business with during onboarding. It can also involve developing visibility into ownership structures, relationships, and connections that may not be immediately visible.
Reviewing whether individuals and entities appear consistent with the information provided during onboarding is a foundational step in building this understanding. However, risk does not remain static. Fraud related risk can emerge and change over time, making it important for organizations to review relevant information across the lifecycle of a relationship. Moody’s solutions can support a data-driven approach to informing assessments of fraud-related risk.
Fraud risk can emerge at different stages of a relationship, from onboarding through ongoing review. Moody’s data and capabilities can be applied across a range of key fraud risk management use cases. Understanding who you are doing business with at onboarding is a key step in identifying potential fraud-related risk. Building a view of identity, ownership, and associated signals can support more informed initial assessments.
From onboarding to investigations to ongoing monitoring, Moody’s solutions help support fraud risk management use cases, providing customers with access to broad, global data, intelligent screening capabilities, and a case management environment. These capabilities can assist teams in maintaining and reviewing risk profiles across the customer or third-party lifecycle.
Robust due diligence at the onboarding stage can help build a clearer picture of potential risk and may support efforts to identify indicators associated with first party fraud. Moody’s fraud related adverse media data can be paired with applicant information to support faster, more informed decision making. Our solutions also provide access to intelligence via API integrations (link) with a wide range of pre connected partners, helping teams streamline fraud risk management workflows where appropriate.
Integrated intelligence can help provide visibility into ownership structures and support customer analysis of potential relationships between companies in the context of fraud related investigations. Data led insights—such as adverse media associated with fraud, conflicts of interest, or potential links to shell companies—can be incorporated into existing workflows to help inform customer assessments of risk indicators.
Build a risk profile using risk scoring and monitoring capabilities. Customers can generate a profile for a third party and review it for different purposes, including supporting KYC, AML compliance, and broader risk management activities. Teams can conduct due diligence while AIIsupported screening helps surface potential fraudIrelated risk indicators for further human analysis and review.
The regulatory landscape, financial crime risks, and thirdIparty relationships continue to evolve—often faster than internal systems can adapt. Moody’s for Compliance is a solution designed to support a connected, data-driven, riskIbased approach to help organizations better understand and operationalize change across their compliance processes. Through our partnership with GBG , a provider of fraud prevention solutions, Moody’s has integrated identity verification into its platform to help businesses streamline onboarding, support fraud risk mitigation efforts, and assist KYC and KYB processes.
How are fraud prevention teams responding to increasingly sophisticated threats? This paper offers insights and perspectives to help organizations explore this question, highlighting the role of technology, collaboration, and shared responsibility in supporting organizational long-term resilience. Featuring perspectives from the UK’s National Crime Agency, HMRC, ING Bank, and more—you can download the paper today.
From September 1, 2025, the “Failure to Prevent Fraud” offence—introduced under the UK’s Economic Crime and Corporate Transparency Act—is expected to influence how large organizations approach fraud prevention responsibilities. Download Moody’s eBook to explore: Whether you are based in the UK or elsewhere, this eBook offers insights your organization may find useful.
Learn how procure-to-pay fraud often works, where traditional controls fall short, and how continuous digital verification can help organizations protect supplier payments. Fraud is a growing threat to financial integrity—and the UK is responding. In this episode, Moody’s Industry Practice Lead, Ted Datta, joins host Alex Pillow to discuss the UK’s new ‘failure to prevent fraud’ offence, exploring how the legislation could impact corporate accountability and what organizations may want to consider next.
Explore how a single crypto transaction became associated with a $1.5B cybercrime event linked to the Bybit incident—illustrating how deception, digital laundering, and human error can intersect. David Thomas , Head of Product - Global Documents & Biometrics at GBG , and Paul Warren-Tape , Head of Risk and Compliance at IDVerse Greg Richardson, Senior Director of Global Sales at NeuroID , and Kyle Caldwell, Senior Vice President of Fraud Product Management at M&T Bank Common types of fraud include internal fraud, committed by people inside an organization; external fraud, committed by actors outside an organization; and collusion (or hybrid) fraud, which involves internal and external actors working together.
External fraud refers to fraudulent activities committed by individuals or entities outside an organization who exploit vulnerabilities in systems, processes, or relationships to obtain assets, data, or other benefits. Internal fraud involves individuals within an organization, while external fraud originates outside the organization. Each presents different considerations within a fraud risk management framework.
Fraud is commonly considered a predicate offense to money laundering, as it can generate illicit proceeds that bad actors may attempt to disguise as legitimate funds, raising money laundering concerns. A fraudIrelated risk event generally refers to an instance where an individual or organization is associated with alleged or confirmed fraudulent activity, often identified through sources such as adverse media or other independent information, and is considered as part of a broader risk assessment process.
*This content is for informational purposes only and does not constitute legal, financial, or compliance advice. Deepfakes aren’t a fringe internet phenomenon. They are increasingly being embedded in familiar forms of fraud and financial manipulation, reshaping how scams look, sound, and feel. In the ever-evolving world of cybercrime, 2025 has brought a sharp focus to a once-overlooked threat: job scams. While investment and imposter scams continue to dominate headlines, a quieter but equally dangerous fraud trend is emerging—one that not only drains victims financially but also harvests their personal data for more insidious purposes.
This article investigates the current state of fraud risk, the complications of managing those risks across a third-party network, the implications of new regulation, and the proactive measures businesses are taking for active fraud prevention. We would be happy to show you how Moody’s solutions can help support your fraud risk management efforts. Request a demo, or continue exploring how Moody’s can assist your organization Fraud detection and prevention is a critical challenge in the financial and insurance industries. In this project, I developed a Fraud Detection and Prevention System using advanced Machine Learning (ML) and Deep Learning (DL) techniques. The goal of this system is to identify fraudulent activities accurately and promptly to safeguard financial transactions and insurance claims.
This repository contains the implementation of various ML and DL algorithms, including regression, Support Vector Machines (SVM), Random Forest, Convolutional Neural Networks (CNN), Recurrent Neural Networks (RNN), and Deep Neural Networks (DNN). The project focuses on building robust models to classify fraudulent and non-fraudulent transactions and prevent financial and insurance fraud effectively.
The primary objective of this project is to create a machine learning-based fraud detection system capable of: Access to this page requires authorization. You can try signing in or changing directories . This tutorial presents an end-to-end example of a Data Science workflow. The scenario builds a fraud detection model by using machine learning algorithms trained on historical data. It then uses the model to detect future fraudulent transactions.
Switch to Fabric by using the experience switcher on the lower-left side of your home page. To open the sample notebook for this tutorial, follow the instructions in Prepare your system for data science tutorials . To open the accompanying notebook for this tutorial, follow the instructions in Prepare your system for data science tutorials to import the notebook to your workspace.
If you'd rather copy and paste the code from this page, you can create a new notebook . Harvested Online Documentation & Reference Sources • https://arxiv.org/html/2502.00201v1 • https://learn.microsoft.com/en-us/fabric/real-time-intelligence/architectures/fraud-detection • https://www.bing.com/aclick?ld=e86m6W9HmVz9ysaexWIvR8GTVUCUyXyafKu6AjhJxx-AJJtYgVV5Q8U8Q8JlWS1APw2D PX6s64PnbaqNEd98tQpg_GpnmbYOT8em_UY1B9igRHhpBaFIEw7EF9o0YC5WBn7zbSq-6h28KsWKWrMIMueRVEOFGW yiHaxSJ-HQnfst_Yi83TGWOwxtzagCpdtnlEVvRbWg&u=aHR0cHMlM2ElMmYlMmZhZC5kb3VibGVjbGljay5uZXQlMmZzZWF yY2hhZHMlMmZsaW5rJTJmY2xpY2slM2ZsaWQlM2Q0MzcwMDA4MjczMTIwNTk0NyUyNmRzX3Nfa3dnaWQlM2Q1ODcwM DAwODk2MjA2NTQwMCUyNmRzX2FfY2lkJTNkODYyOTI0Nzk0JTI2ZHNfYV9jYWlkJTNkNDgyOTQwNDM5JTI2ZHNfYV9hZ 2lkJTNkMTIzODA1MTA5MjkwNjA3NiUyNmRzX2FfZmlpZCUzZCUyNmRzX2FfbGlkJTNka3dkLTc3Mzc4NDUxMzc3MzIwJTN hbG9jLTEyOSUyNmRzX2FfZXh0aWQlM2QlN2JleHRlbnNpb25pZCU3ZCUyNiUyNmRzX2VfYWRpZCUzZCUyNmRzX2VfbW F0Y2h0eXBlJTNkc2VhcmNoJTI2ZHNfZV9kZXZpY2UlM2RjJTI2ZHNfZV9uZXR3b3JrJTNkbyUyNiUyNmRzX3VybF92JTNkMi UyNmRzX2Rlc3RfdXJsJTNkaHR0cHMlM2ElMmYlMmZ3d3cubW9vZHlzLmNvbSUyZndlYiUyZmVuJTJmdXMlMmZreWMlMm Zzb2x1dGlvbnMlMmZmcmF1ZC1wcmV2ZW50aW9uLmh0bWwlM2ZjaWQlM2Q2MkVGRjk2MEY4QTE3NTAyJTI2Z2Nsc3JjJ TNkM3AuZHMlMjYlMjZtc2Nsa2lkJTNkMzk3ZTZmY2FhMDI2MTRhNGFlNjcwNTFlNDdkZTgzNzYlMjZ1dG1fc291cmNlJTNkY mluZyUyNnV0bV9tZWRpdW0lM2RjcGMlMjZ1dG1fY2FtcGFpZ24lM2RDJTI1MkZHJTI1MjAlMjU3QyUyNTIwS1lDX092ZXJhb GxfU29sdXRpb25zJTI1MjAlMjU3QyUyNTIwUGFpZCUyNTIwU2VhcmNoJTI1MjAlMjU3QyUyNTIwTVNGVCUyNTIwJTI1N0Ml MjUyMExHJTI1MjAlMjU3QyUyNTIwU2VhcmNoJTI1MjAlMjU3QyUyNTIwR2xvYmFsJTI1MjAlMjU3QyUyNTIwVEEtMTk0NyUy NTIwJTI1N0MlMjUyME1DLTI2NDUlMjUyMCUyNTdDJTI1MjBETS0xMzExMiUyNnV0bV90ZXJtJTNkZmluYW5jaWFsJTI1MjB mcmF1ZCUyNTIwZGV0ZWN0aW9uJTI2dXRtX2NvbnRlbnQlM2ROQiUyNTIwLSUyNTIwUmlzayUyNTIwTWFuYWdlbWVudC UyNTIwLSUyNTIwRmluYW5jaWFsJTI1MjBDcmltZQ&rlid=397e6fcaa02614a4ae67051e47de8376 • https://github.com/ALIMAQSOOD1/Fraud-Detection-Using-Machine-Learning • https://learn.microsoft.com/en-us/fabric/data-science/fraud-detection
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Financial Fraud Detection Using Deep Learning Algorithms.
[*] Metasploit Scan Running on Target Subnet for Financial Fraud Detection Using Deep Learning Algorithms... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |