Complete Technical Paper Content — Homomorphic Encryption System For Secure Cloud Computation
Overview & System Context
Homomorphic Encryption System For Secure Cloud Computation: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9595 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Homomorphic encryption is a form of encryption that allows computations to be performed on encrypted data without first having to decrypt it. The result of the computations are left in an encrypted form which, when decrypted, result in an output that is identical to that of the operations performed on the unencrypted data. Homomorphic encryption can be used for privacy-preserving outsourced storage and computation. This allows data to be encrypted and outsourced to commercial cloud environments for processing, all while encrypted. As an example of a practical application of homomorphic encryption: photographs can be scanned for regions of interest (ROI), the encrypted values of which are then compared to precomputed ROI of points of (touristical) interest, without revealing the contents of a photo. However, observation of side-channels can see a photograph being sent to a point-of-interest lookup service, revealing the fact that photographs were taken. Thus, homomorphic encryption eliminates the need for processing data in the clear, thereby preventing attacks that would enable an attacker to access that data while it is being processed, using privilege escalation. For sensitive data, such as healthcare information, homomorphic encryption can be used to enable new services by removing privacy barriers inhibiting data sharing or increasing security to existing services. For example, predictive analytics in healthcare can be hard to apply via a third-party service provider due to medical data privacy concerns. But if the predictive-analytics service provider could operate on encrypted data instead, without having the decryption keys, these privacy concerns are diminished. Moreover, even if the service provider's system is compromised, the data would remain secure.
Partially homomorphic encryption encompasses schemes that support the evaluation of circuits consisting of only one type of gate, e.g., addition or multiplication. Somewhat homomorphic encryption schemes can evaluate two types of gates, but only for a subset of circuits. Leveled fully homomorphic encryption supports the evaluation of arbitrary circuits composed of multiple types of gates of bounded (pre-determined) depth. Fully homomorphic encryption (FHE) allows the evaluation of arbitrary circuits composed of multiple types of gates of unbounded depth and is the strongest notion of homomorphic encryption. For the majority of homomorphic encryption schemes, the multiplicative depth of circuits is the main practical limitation in performing computations over encrypted data. Homomorphic encryption schemes are inherently malleable. In terms of malleability, homomorphic encryption schemes have weaker security properties than non-homomorphic schemes. A cryptosystem that supports arbitrary computation on ciphertexts is known as fully homomorphic encryption (FHE). Such a scheme enables the construction of programs for any desirable functionality, which can be run on encrypted inputs to produce an encryption of the result. Since such a program need never decrypt its inputs, it can be run by an untrusted party without revealing its inputs and internal state. Fully homomorphic cryptosystems have great practical implications in the outsourcing of private computations, for instance, in the context of cloud computing.
RSA cryptosystem (unbounded number of modular multiplications) ElGamal cryptosystem (unbounded number of modular multiplications) Goldwasser–Micali cryptosystem (unbounded number of exclusive or operations) Benaloh cryptosystem (unbounded number of modular additions) Paillier cryptosystem (unbounded number of modular additions) Sander-Young-Yung system (after more than 20 years solved the problem for logarithmic depth circuits) Boneh–Goh–Nissim cryptosystem (unlimited number of addition operations but at most one multiplication) Ishai-Paskin cryptosystem (polynomial-size branching programs) The Brakerski-Gentry-Vaikuntanathan (BGV, 2011) scheme, building on techniques of Brakerski-Vaikuntanathan; The NTRU-based scheme by Lopez-Alt, Tromer, and Vaikuntanathan (LTV, 2012); The Brakerski/Fan-Vercauteren (BFV, 2012) scheme, building on Brakerski's scale-invariant cryptosystem; The NTRU-based scheme by Bos, Lauter, Loftus, and Naehrig (BLLN, 2013), building on LTV and Brakerski's scale-invariant cryptosystem; The security of most of these schemes is based on the hardness of the (Ring) Learning With Errors (RLWE) problem, except for the LTV and BLLN schemes that rely on an overstretched variant of the NTRU computational problem. This NTRU variant was subsequently shown vulnerable to subfield lattice attacks, which is why these two schemes are no longer used in practice. All the second-generation cryptosystems still follow the basic blueprint of Gentry's original construction, namely they first construct a somewhat homomorphic cryptosystem and then convert it to a fully homomorphic cryptosystem using bootstrapping. A distinguishing characteristic of the second-generation cryptosystems is that they all feature a much slower growth of the noise during the homomorphic computations. Additional optimizations by Craig Gentry, Shai Halevi, and Nigel Smart resulted in cryptosystems with nearly optimal asymptotic complexity: Performing T {\displaystyle T} operations on data encrypted with security parameter k {\displaystyle k} has complexity of only T ⋅ p o l y l o g ( k ) {\displaystyle T\cdot \mathrm {polylog} (k)} . These optimizations build on the Smart-Vercauteren techniques that enable packing of many plaintext values in a single ciphertext and operating on all these plaintext values in a SIMD fashion. Many of the advances in these second-generation cryptosystems were also ported to the cryptosystem over the integers. Another distinguishing feature of second-generation schemes is that they are efficient enough for many applications even without invoking bootstrapping, instead operating in the leveled FHE mode.
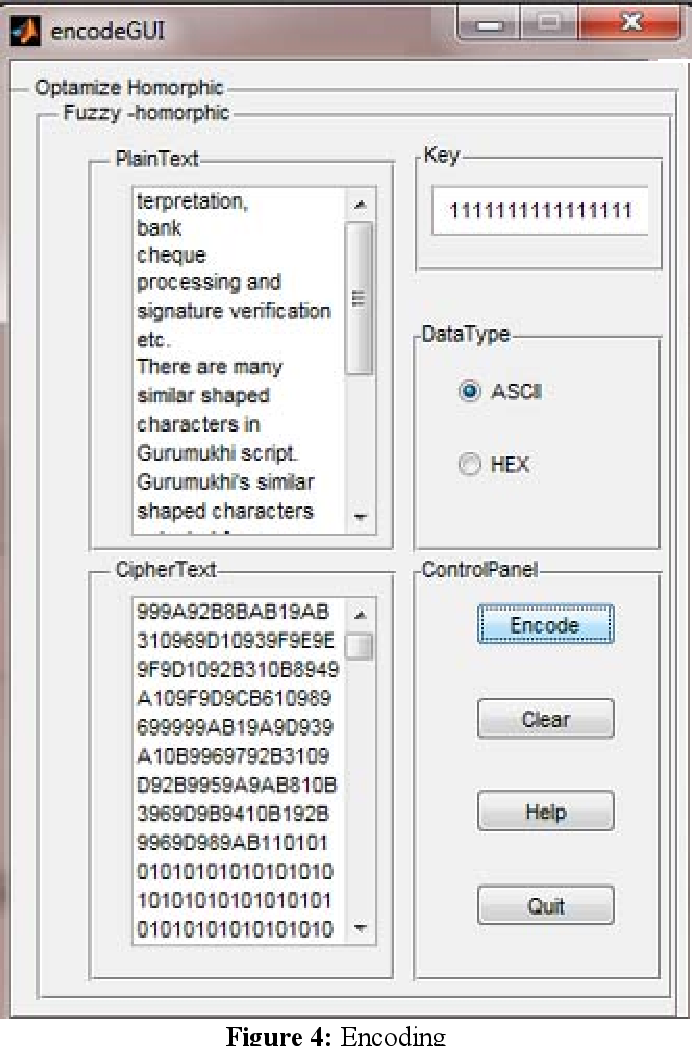
Figure 1: Figure 4 from Fuzzy Based Fully Homomorphic Encryption Scheme for ... Unpadded RSA If the RSA public key has modulus n {\displaystyle n} and encryption exponent e {\displaystyle e} , then the encryption of a message m {\displaystyle m} is given by E ( m ) = m e mod n {\displaystyle {\mathcal {E}}(m)=m^{e}\;{\bmod {\;}}n} . The homomorphic property is then E ( m 1 ) ⋅ E ( m 2 ) = m 1 e m 2 e mod n = ( m 1 m 2 ) e mod n = E ( m 1 ⋅ m 2 ) {\displaystyle {\begin{aligned}{\mathcal {E}}(m_{1})\cdot {\mathcal {E}}(m_{2})&=m_{1}^{e}m_{2}^{e}\;{\bmod {\;}}n\\[6pt]&=(m_{1}m_{2})^{e}\;{\bmod {\;}}n\\[6pt]&={\mathcal {E}}(m_{1}\cdot m_{2})\end{aligned}}} ElGamal In the ElGamal cryptosystem, in a cyclic group G {\displaystyle G} of order q {\displaystyle q} with generator g {\displaystyle g} , if the public key is ( G , q , g , h ) {\displaystyle (G,q,g,h)} , where h = g x {\displaystyle h=g^{x}} , and x {\displaystyle x} is the secret key, then the encryption of a message m {\displaystyle m} is E ( m ) = ( g r , m ⋅ h r ) {\displaystyle {\mathcal {E}}(m)=(g^{r},m\cdot h^{r})} , for some random r ∈ { 0 , … , q − 1 } {\displaystyle r\in \{0,\ldots ,q-1\}} . The homomorphic property is then E ( m 1 ) ⋅ E ( m 2 ) = ( g r 1 , m 1 ⋅ h r 1 ) ( g r 2 , m 2 ⋅ h r 2 ) = ( g r 1 + r 2 , ( m 1 ⋅ m 2 ) h r 1 + r 2 ) = E ( m 1 ⋅ m 2 ) .
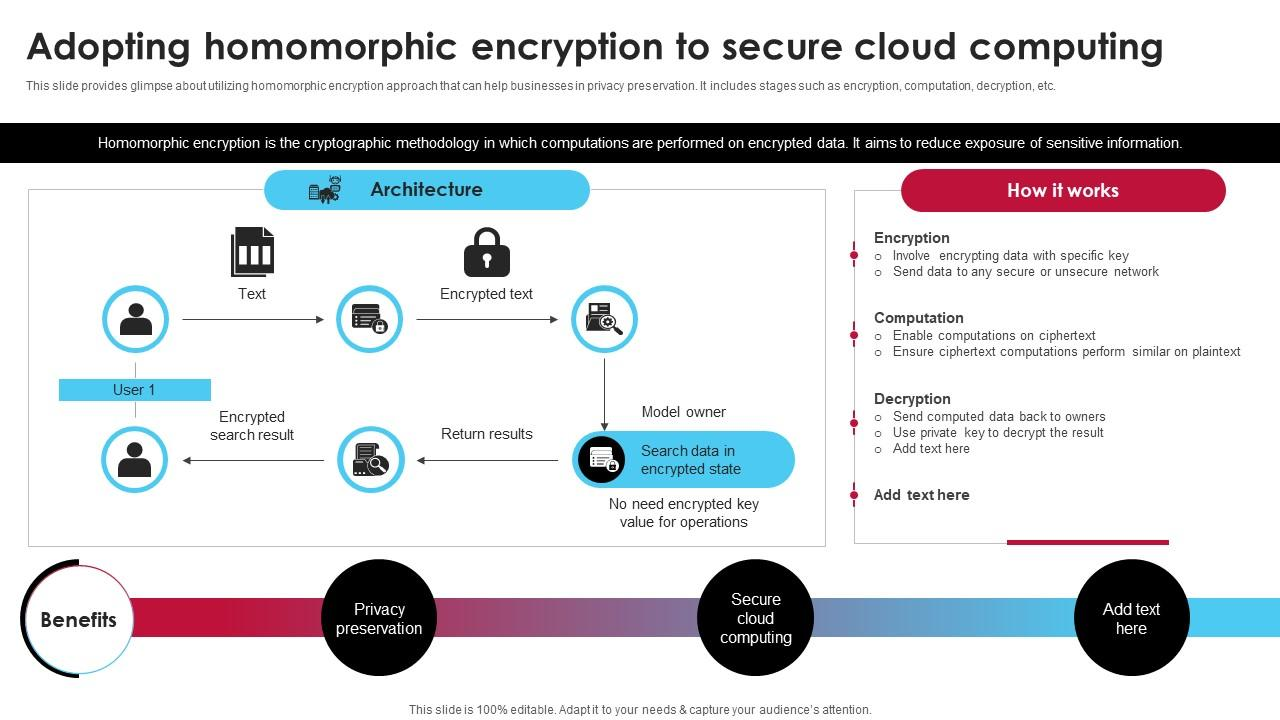
{\displaystyle {\begin{aligned}{\mathcal {E}}(m_{1})\cdot {\mathcal {E}}(m_{2})&=(g^{r_{1}},m_{1}\cdot h^{r_{1}})(g^{r_{2}},m_{2}\cdot h^{r_{2}})\\[6pt]&=(g^{r_{1}+r_{2}},(m_{1}\cdot m_{2})h^{r_{1}+r_{2}})\\[6pt]&={\mathcal {E}}(m_{1}\cdot m_{2}).\end{aligned}}} Figure 2: Adopting Homomorphic Encryption To Secure Cloud Ai Driven Digital ...
Goldwasser–Micali In the Goldwasser–Micali cryptosystem, if the public key is the modulus n {\displaystyle n} and quadratic non-residue x {\displaystyle x} , then the encryption of a bit b {\displaystyle b} is E ( b ) = x b r 2 mod n {\displaystyle {\mathcal {E}}(b)=x^{b}r^{2}\;{\bmod {\;}}n} , for some random r ∈ { 0 , … , n − 1 } {\displaystyle r\in \{0,\ldots ,n-1\}} . The homomorphic property is then E ( b 1 ) ⋅ E ( b 2 ) = x b 1 r 1 2 x b 2 r 2 2 mod n = x b 1 + b 2 ( r 1 r 2 ) 2 mod n = E ( b 1 ⊕ b 2 ) . {\displaystyle {\begin{aligned}{\mathcal {E}}(b_{1})\cdot {\mathcal {E}}(b_{2})&=x^{b_{1}}r_{1}^{2}x^{b_{2}}r_{2}^{2}\;{\bmod {\;}}n\\[6pt]&=x^{b_{1}+b_{2}}(r_{1}r_{2})^{2}\;{\bmod {\;}}n\\[6pt]&={\mathcal {E}}(b_{1}\oplus b_{2}).\end{aligned}}} where ⊕ {\displaystyle \oplus } denotes addition modulo 2, (i.e., exclusive-or).
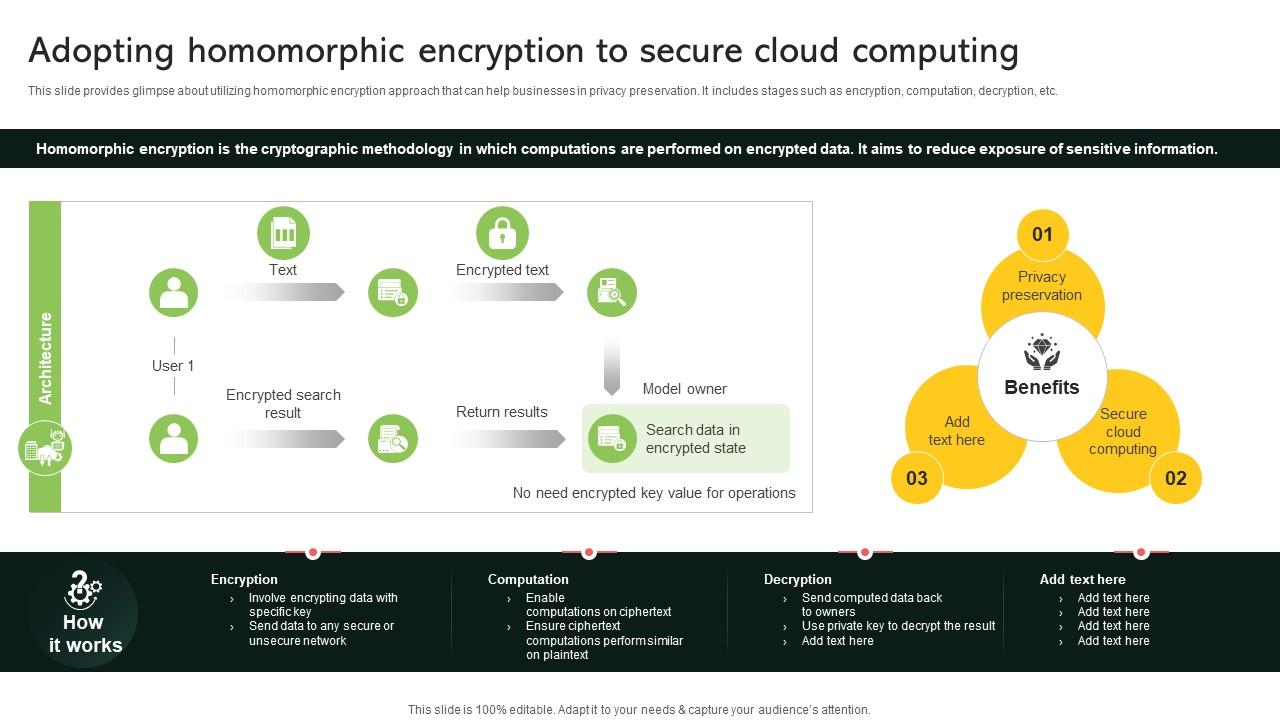
Benaloh In the Benaloh cryptosystem, if the public key is the modulus n {\displaystyle n} and the base g {\displaystyle g} with a blocksize of c {\displaystyle c} , then the encryption of a message m {\displaystyle m} is E ( m ) = g m r c mod n {\displaystyle {\mathcal {E}}(m)=g^{m}r^{c}\;{\bmod {\;}}n} , for some random r ∈ { 0 , … , n − 1 } {\displaystyle r\in \{0,\ldots ,n-1\}} . The homomorphic property is then Figure 3: Adopting Homomorphic Encryption To Secure Cloud Computing Implementing ...
E ( m 1 ) ⋅ E ( m 2 ) = ( g m 1 r 1 c ) ( g m 2 r 2 c ) mod n = g m 1 + m 2 ( r 1 r 2 ) c mod n = E ( m 1 + m 2 mod c ) . {\displaystyle {\begin{aligned}{\mathcal {E}}(m_{1})\cdot {\mathcal {E}}(m_{2})&=(g^{m_{1}}r_{1}^{c})(g^{m_{2}}r_{2}^{c})\;{\bmod {\;}}n\\[6pt]&=g^{m_{1}+m_{2}}(r_{1}r_{2})^{c}\;{\bmod {\;}}n\\[6pt]&={\mathcal {E}}(m_{1}+m_{2}\;{\bmod {\;}}c).\end{aligned}}} Paillier In the Paillier cryptosystem, if the public key is the modulus n {\displaystyle n} and the base g {\displaystyle g} , then the encryption of a message m {\displaystyle m} is E ( m ) = g m r n mod n 2 {\displaystyle {\mathcal {E}}(m)=g^{m}r^{n}\;{\bmod {\;}}n^{2}} , for some random r ∈ { 0 , … , n − 1 } {\displaystyle r\in \{0,\ldots ,n-1\}} . The homomorphic property is then E ( m 1 ) ⋅ E ( m 2 ) = ( g m 1 r 1 n ) ( g m 2 r 2 n ) mod n 2 = g m 1 + m 2 ( r 1 r 2 ) n mod n 2 = E ( m 1 + m 2 ) . {\displaystyle {\begin{aligned}{\mathcal {E}}(m_{1})\cdot {\mathcal {E}}(m_{2})&=(g^{m_{1}}r_{1}^{n})(g^{m_{2}}r_{2}^{n})\;{\bmod {\;}}n^{2}\\[6pt]&=g^{m_{1}+m_{2}}(r_{1}r_{2})^{n}\;{\bmod {\;}}n^{2}\\[6pt]&={\mathcal {E}}(m_{1}+m_{2}).\end{aligned}}} Okamoto–Uchiyama cryptosystem Naccache–Stern cryptosystem Damgård–Jurik cryptosystem Sander–Young–Yung encryption scheme Boneh–Goh–Nissim cryptosystem Ishai–Paskin cryptosystem Joye-Libert cryptosystem Castagnos–Laguillaumie cryptosystem Secure multi-party computation (also known as secure computation, multi-party computation (MPC) or privacy-preserving computation) is a subfield of cryptography with the goal of creating methods for parties to jointly compute a function over their inputs while keeping those inputs private. Unlike traditional cryptographic tasks, where cryptography assures security and integrity of communication or storage and the adversary is outside the system of participants (an eavesdropper on the sender and receiver), the cryptography in this model protects participants' privacy from each other. The foundation for secure multi-party computation started in the late 1970s with the work on mental poker, cryptographic work that simulates game playing/computational tasks over distances without requiring a trusted third party. Traditionally, cryptography was about concealing content, while this new type of computation and protocol is about concealing partial information about data while computing with the data from many sources, and correctly producing outputs. By the late 1980s, Michael Ben-Or, Shafi Goldwasser and Avi Wigderson, and independently David Chaum, Claude Crépeau, and Ivan Damgård, had published papers showing "how to securely compute any function in the secure channels setting".
In an MPC, a given number of participants, p1, p2, ..., pN, each have private data, respectively d1, d2, ..., dN. Participants want to compute the value of a public function on that private data: F(d1, d2, ..., dN) while keeping their own inputs secret. For example, suppose we have three parties Alice, Bob and Charlie, with respective inputs x, y and z denoting their salaries. They want to find out the highest of the three salaries, without revealing to each other how much each of them makes.
Mathematically, this translates to them computing: F(x, y, z) = max(x, y, z) If there were some trusted outside party (say, they had a mutual friend Tony who they knew could keep a secret), they could each tell their salary to Tony, he could compute the maximum, and tell that number to all of them. The goal of MPC is to design a protocol, where, by exchanging messages only with each other, Alice, Bob, and Charlie can still learn F(x, y, z) without revealing who makes what and without having to rely on Tony. They should learn no more by engaging in their protocol than they would learn by interacting with an incorruptible, perfectly trustworthy Tony. In particular, all that the parties can learn is what they can learn from the output and their own input. So in the above example, if the output is z, then Charlie learns that his z is the maximum value, whereas Alice and Bob learn (if x, y and z are distinct), that their input is not equal to the maximum, and that the maximum held is equal to z. The basic scenario can be easily generalised to where the parties have several inputs and outputs, and the function outputs different values to different parties. Informally speaking, the most basic properties that a multi-party computation protocol aims to ensure are: Input privacy: No information about the private data held by the parties can be inferred from the messages sent during the execution of the protocol. The only information that can be inferred about the private data is whatever could be inferred from seeing the output of the function alone. Correctness: Any proper subset of adversarial colluding parties willing to share information or deviate from the instructions during the protocol execution should not be able to force honest parties to output an incorrect result. This correctness goal comes in two flavours: either the honest parties are guaranteed to compute the correct output (a "robust" protocol), or they abort if they find an error (an MPC protocol "with abort"). There are a wide range of practical applications, varying from simple tasks such as coin tossing to more complex ones like electronic auctions (e.g.
compute the market clearing price), electronic voting, or privacy-preserving data mining. A classical example is the Millionaires' Problem: two millionaires want to know who is richer, in such a way that neither of them learns the net worth of the other. A solution to this situation is essentially to securely evaluate the comparison function. A multi-party computation protocol must be secure to be effective. In modern cryptography, the security of a protocol is related to a security proof. The security proof is a mathematical proof where the security of a protocol is reduced to that of the security of its underlying primitives. Nevertheless, it is not always possible to formalize the cryptographic protocol security verification based on the party knowledge and the protocol correctness. For MPC protocols, the environment in which the protocol operates is associated with the Real World/Ideal World Paradigm. The parties can't be said to learn nothing, since they need to learn the output of the operation, and the output depends on the inputs. In addition, the output correctness is not guaranteed, since the correctness of the output depends on the parties’ inputs, and the inputs have to be assumed to be correct. The Real World/Ideal World Paradigm states two worlds: (i) In the ideal-world model, there exists an incorruptible trusted party to whom each protocol participant sends its input. This trusted party computes the function on its own and sends back the appropriate output to each party. (ii) In contrast, in the real-world model, there is no trusted party and all the parties can do is to exchange messages with each other. A protocol is said to be secure if one can learn no more about each party's private inputs in the real world than one could learn in the ideal world. In the ideal world, no messages are exchanged between parties, so real-world exchanged messages cannot reveal any secret information. The Real World/Ideal World Paradigm provides a simple abstraction of the complexities of MPC to allow the construction of an application under the pretense that the MPC protocol at its core is actually an ideal execution. If the application is secure in the ideal case, then it is also secure when a real protocol is run instead. The security requirements on an MPC protocol are stringent. Nonetheless, in 1987 it was demonstrated that any function can be securely computed, with security for malicious adversaries and the other initial works mentioned before. Despite these publications, MPC was not designed to be efficient enough to be used in practice at that time. Unconditionally or information-theoretically secure MPC is closely related and builds on to the problem of secret sharing, and more specifically verifiable secret sharing (VSS), which many secure MPC protocols use against active adversaries. Unlike traditional cryptographic applications, such as encryption or signature, one must assume that the adversary in an MPC protocol is one of the players engaged in the system (or controlling internal parties). That corrupted party or parties may collude in order to breach the security of the protocol. Let n {\displaystyle n} be the number of parties in the protocol and t {\displaystyle t} the number of parties who can be adversarial. The protocols and solutions for the case of t < n / 2 {\displaystyle t
This latter case includes the important case of two-party computation where one of the participants may be corrupted, and the general case where an unlimited number of participants are corrupted and collude to attack the honest participants. Adversaries faced by the different protocols can be categorized according to how willing they are to deviate from the protocol. There are essentially two types of adversaries, each giving rise to different forms of security (and each fits into different real world scenario): 2. System Architecture & Core Working Principles Semi-Honest (Passive) Security: In this case, it is assumed that corrupted parties merely cooperate to gather information out of the protocol, but do not deviate from the protocol specification. This is a naive adversary model, yielding weak security in real situations. However, protocols achieving this level of security prevent inadvertent leakage of information between (otherwise collaborating) parties, and are thus useful if this is the only concern. In addition, protocols in the semi-honest model are quite efficient, and are often an important first step for achieving higher levels of security. Malicious (Active) Security: In this case, the adversary may arbitrarily deviate from the protocol execution in its attempt to cheat. Protocols that achieve security in this model provide a very high security guarantee. In the case of majority of misbehaving parties: The only thing that an adversary can do in the case of dishonest majority is to cause the honest parties to "abort" having detected cheating. If the honest parties do obtain output, then they are guaranteed that it is correct. Their privacy is always preserved. Security against active adversaries typically leads to a reduction in efficiency. Covert security is an alternative that aims to allow greater efficiency in exchange for weakening the security definition; it is applicable to situations where active adversaries are willing to cheat but only if they are not caught. For example, their reputation could be damaged, preventing future collaboration with other honest parties. Thus, protocols that are covertly secure provide mechanisms to ensure that, if some of the parties do not follow the instructions, then it will be noticed with high probability, say 75% or 90%. In a way, covert adversaries are active ones forced to act passively due to external non-cryptographic (e.g. business) concerns. This mechanism sets a bridge between both models in the hope of finding protocols which are efficient and secure enough in practice. Like many cryptographic protocols, the security of an MPC protocol can rely on different assumptions: It can be computational (i.e. based on some mathematical problem, like factoring) or unconditional, namely relying on physical unavailability of messages on channels (usually with some probability of error which can be made arbitrarily small). The model might assume that participants use a synchronized network, where a message sent at a "tick" always arrives at the next "tick", or that a secure and reliable broadcast channel exists, or that a secure communication channel exists between every pair of participants where an adversary cannot read, modify or generate messages in the channel, etc. The set of honest parties that can execute a computational task is related to the concept of access structure. Adversary structures can be static, where the adversary chooses its victims before the start of the multi-party computation, or dynamic, where it chooses its victims during the course of execution of the multi-party computation making the defense harder. An adversary structure can be defined as a threshold structure or as a more complex structure. In a threshold structure the adversary can corrupt or read the memory of a number of participants up to some threshold. Meanwhile, in a complex structure it can affect certain predefined subsets of participants, modeling different possible collusions.
There are major differences between the protocols proposed for two party computation (2PC) and multi-party computation (MPC). Also, often for special purpose protocols of importance a specialized protocol that deviates from the generic ones has to be designed (voting, auctions, payments, etc.) The two party setting is particularly interesting, not only from an applications perspective but also because special techniques can be applied in the two party setting which do not apply in the multi-party case. Indeed, secure multi-party computation (in fact the restricted case of secure function evaluation, where only a single function is evaluated) was first presented in the two-party setting. The original work is often cited as being from one of the two papers of Yao; although the papers do not actually contain what is now known as Yao's garbled circuit protocol. Yao's basic protocol is secure against semi-honest adversaries and is extremely efficient in terms of number of rounds, which is constant, and independent of the target function being evaluated. The function is viewed as a Boolean circuit, with inputs in binary of fixed length. A Boolean circuit is a collection of gates connected with three different types of wires: circuit-input wires, circuit-output wires and intermediate wires.
Each gate receives two input wires and it has a single output wire which might be fan-out (i.e. be passed to multiple gates at the next level). Plain evaluation of the circuit is done by evaluating each gate in turn; assuming the gates have been topologically ordered. The gate is represented as a truth table such that for each possible pair of bits (those coming from the input wires' gate) the table assigns a unique output bit; which is the value of the output wire of the gate. The results of the evaluation are the bits obtained in the circuit-output wires. Yao explained how to garble a circuit (hide its structure) so that two parties, sender and receiver, can learn the output of the circuit and nothing else. At a high level, the sender prepares the garbled circuit and sends it to the receiver, who obliviously evaluates the circuit, learning the encodings corresponding to both his and the sender's output. He then just sends back the sender's encodings, allowing the sender to compute his part of the output. The sender sends the mapping from the receivers output encodings to bits to the receiver, allowing the receiver to obtain their output. In more detail, the garbled circuit is computed as follows. The main ingredient is a double-keyed symmetric encryption scheme. Given a gate of the circuit, each possible value of its input wires (either 0 or 1) is encoded with a random number (label). The values resulting from the evaluation of the gate at each of the four possible pair of input bits are also replaced with random labels. The garbled truth table of the gate consists of encryptions of each output label using its inputs labels as keys. The position of these four encryptions in the truth table is randomized so no information on the gate is leaked.
To correctly evaluate each garbled gate the encryption scheme has the following two properties. Firstly, the ranges of the encryption function under any two distinct keys are disjoint (with overwhelming probability). The second property says that it can be checked efficiently whether a given ciphertext has been encrypted under a given key. With these two properties the receiver, after obtaining the labels for all circuit-input wires, can evaluate each gate by first finding out which of the four ciphertexts has been encrypted with his label keys, and then decrypting to obtain the label of the output wire. This is done obliviously as all the receiver learns during the evaluation are encodings of the bits. The sender's (i.e. circuit creators) input bits can be just sent as encodings to the evaluator; whereas the receiver's (i.e. circuit evaluators) encodings corresponding to his input bits are obtained via a 1-out-of-2 oblivious transfer (OT) protocol. A 1-out-of-2 OT protocol enables the sender possessing of two values C1 and C2 to send the one requested by the receiver (b a value in {1,2}) in such a way that the sender does not know what value has been transferred, and the receiver only learns the queried value. If one is considering malicious adversaries, further mechanisms to ensure correct behavior of both parties need to be provided. By construction it is easy to show security for the sender if the OT protocol is already secure against malicious adversary, as all the receiver can do is to evaluate a garbled circuit that would fail to reach the circuit-output wires if he deviated from the instructions. The situation is very different on the sender's side. For example, he may send an incorrect garbled circuit that computes a function revealing the receiver's input. This would mean that privacy no longer holds, but since the circuit is garbled the receiver would not be able to detect this. However, it is possible to efficiently apply Zero-Knowledge proofs to make this protocol secure against malicious adversaries with a small overhead comparing to the semi-honest protocol.
The two techniques are consequently often combined rather than used in isolation, with MPC used to distribute the trust that DP's central model would otherwise concentrate in a single curator, while DP bounds what the output ultimately reveals about any one participant. Private biometrics is a form of encrypted biometrics, also called privacy-preserving biometric authentication methods, in which the biometric measurement is cryptographically processed such that no data stored in a data base can be (mis-) used to recover information about the human subject. Biometrics, in contrast to user pass words, are noisy data that slightly differ from measurement to measurement. Small variations input data prevent the use of traditional encryption or hashing. The introduction of a fuzzy extractor was a pioneering contribution to nonetheless apply cryptographic techniques to inherently noisy biometric data.
The Private.id feature vector can be used in one of two ways. If the feature vector is stored locally, it may be used to compute 1:1 verification with high accuracy (99% or greater) using linear mathematics. If the feature vector is also stored in a Cloud, the feature vector may also be used as input for a neural network to perform 1:many identification with the same accuracy, speed and privacy as the original plaintext reference biometric (template).
Non-bypassable, as plaintext biometrics cannot use another communication path, including lower level mechanisms, to bypass the security monitor since the original biometric is transient at inception (e.g. the biometric template acquired by the client device exists only for a few seconds at inception and then is deleted or never stored). Evaluable in that the feature vectors are modular, well designed, well specified, well implemented, small and of low complexity. Always-invoked, in that each and every message is always one-way encrypted independent of security monitors. Tamperproof in that the feature vector's one-way encryption prevents unauthorized changes and does not use systems that control rights to the security monitor code, configuration and data.
BioHashing Research into cancelable biometrics moved into BioHashing by 2004. The BioHashing feature transformation technique was first published by Jin, Ling and Goh and combined biometric features and a tokenized (pseudo-) random number (TRN). Specifically, BioHash combined the biometric template with a user-specific TRN to produce a set of non-invertible binary bit strings that were thought to be irreproducible if both the biometric and the TRN were not presented simultaneously. Indeed, it was first claimed that the BioHashing technique had achieved perfect accuracy (equal error rates) for faces, fingerprints and palm prints, and the method gained further traction when its extremely low error rates were combined with the claim that its biometric data was secure against loss because factoring the inner products of biometrics feature and TRN was an intractable problem. By 2005, however, researchers Cheung and Kong (Hong Kong Polytechnic and University of Waterloo) asserted in two journal articles that BioHashing performance was actually based on the sole use of TRN and conjectured that the introduction of any form of biometric become meaningless since the system could be used only with the tokens. These researchers also reported that the non-invertibility of the random hash would deteriorate the biometric recognition accuracy when the genuine token was stolen and used by an impostor (“the stolen-token scenario”).
As machine learning (ML) models become increasingly deployed through cloud infrastructures, the confidentiality of user data during inference poses a significant security challenge. Homomorphic Encryption (HE) has emerged as a compelling cryptographic technique that enables computation on encrypted data, allowing predictions to be generated without decrypting sensitive inputs. However, the integration of HE within large-scale cloud-native pipelines remains constrained by high computational overhead, orchestration complexity, and model compatibility issues.
This paper presents a systematic framework for the design and optimization of cloud-native homomorphic encryption workflows that support privacy-preserving ML inference. The proposed architecture integrates containerized HE modules with Kubernetes-based orchestration, enabling elastic scaling and parallel encrypted computation across distributed environments. Furthermore, optimization strategies—including ciphertext packing, polynomial modulus adjustment, and operator fusion—are employed to minimize latency and resource consumption while preserving cryptographic integrity. Experimental results demonstrate that the proposed system achieves up to 3.2 × \times inference acceleration and 40% reduction in memory utilization compared to conventional HE pipelines. These findings illustrate a practical pathway for deploying secure ML-as-a-Service (MLaaS) systems that guarantee data confidentiality under zero-trust cloud conditions.
The proliferation of Machine Learning (ML) services in cloud environments has transformed modern data analytics, enabling scalable, on-demand intelligence for industries such as healthcare, finance, and government. However, these cloud-hosted ML models often require sensitive user data for inference, posing severe privacy and compliance risks when raw data is transmitted or processed in plaintext. Recent breaches and regulatory mandates such as GDPR and HIPAA have intensified the demand for privacy-preserving inference mechanisms that ensure end-to-end data confidentiality even in untrusted or multi-tenant cloud infrastructures.
Homomorphic Encryption (HE) provides a mathematically rigorous solution to this problem by allowing arithmetic operations to be performed directly on encrypted data without exposing plaintext values. This capability enables secure inference on encrypted inputs, ensuring that neither the model provider nor the cloud operator gains access to the underlying data. Despite its theoretical elegance, the practical deployment of HE-based ML pipelines in cloud environments remains hindered by significant computational costs, memory overhead, and orchestration complexity. Current HE implementations, including libraries such as Microsoft SEAL, HElib, and PALISADE, face challenges when integrated with containerized and distributed ML workflows, where dynamic scaling, model partitioning, and load balancing are essential.
Moreover, existing privacy-preserving ML research predominantly focuses on algorithmic design or cryptographic primitives rather than the cloud-native orchestration layer —the critical bridge that determines real-world scalability, efficiency, and interoperability. A lack of standardized frameworks for integrating HE into microservice architectures leads to redundant encryption overheads, inefficient resource utilization, and complex deployment pipelines. These gaps limit the adoption of HE in real-world ML-as-a-Service (MLaaS) platforms that demand both confidentiality and responsiveness.
This paper addresses these challenges by proposing a cloud-native architecture for deploying and optimizing homomorphic encryption workflows tailored to secure ML inference. The contributions of this research are as follows: Design of a cloud-native HE workflow: A modular architecture that integrates HE modules with Kubernetes-based orchestration for elastic scaling and automated workload distribution.
Optimization strategies: Implementation of ciphertext packing, polynomial modulus switching, and operator fusion to minimize computation latency and memory footprint. Experimental validation: Evaluation of performance trade-offs using benchmark datasets and deep learning models (e.g., logistic regression, CNNs) to demonstrate feasibility for real-time inference.
Scalable privacy-preserving ML framework: [ 1 ] A generalized methodology applicable to hybrid and federated cloud deployments supporting secure MLaaS systems [ 2 ] . Privacy-preserving machine learning (PPML) has gained substantial research attention in the past decade, focusing on methods that protect user data during model training and inference. Approaches such as differential privacy (DP) [ 3 ] introduce calibrated noise to safeguard individual records, while secure multiparty computation (SMC) [ 4 ] enables joint model evaluation without revealing private data. Although DP and SMC provide strong privacy guarantees, they often suffer from degraded model accuracy and increased communication overhead, limiting their feasibility for large-scale ML deployments. In contrast, homomorphic encryption (HE) offers a mathematically complete form of data confidentiality that allows computation directly over ciphertexts, enabling inference without decryption. Recent frameworks like CryptoNets [ 5 ] have demonstrated encrypted inference feasibility but remain constrained by high latency and limited cloud-native integration.
Modern HE schemes—including Brakerski-Gentry-Vaikuntanathan (BGV), Brakerski/Fan-Vercauteren (BFV), and Cheon-Kim-Kim-Song (CKKS)—form the foundation for encrypted computation in ML pipelines [ 6 ] . Libraries such as Microsoft SEAL, HElib, and PALISADE implement these schemes with optimized polynomial arithmetic and batching support. Despite these advances, HE-based inference remains computationally expensive due to large ciphertext sizes, bootstrapping overhead, and limited support for non-linear activation functions. Studies such as emphasize the need for hardware acceleration, parameter tuning, and hybrid encryption models to improve performance. However, the majority of HE frameworks are designed for standalone systems and lack the scalability mechanisms needed for distributed, cloud-native ML workloads.
3. Software Implementation, Frameworks & Protocols Cloud-native computing principles—microservices, containerization, and orchestration—have transformed ML deployment paradigms through scalability and modularity. Frameworks such as TensorFlow Serving, Kubeflow, and MLflow automate model lifecycle management but are not inherently designed to handle encrypted data streams. Integration of cryptographic components like HE into Kubernetes clusters introduces challenges related to container scheduling, load balancing, and encrypted inter-service communication. Prior works such as [ 7 ] explored confidential ML inference using trusted execution environments (TEEs), but these rely on hardware-level isolation and do not support computation over encrypted data. Thus, a scalable orchestration model for fully homomorphic encrypted workloads remains largely unexplored [ 8 ] .
While HE offers strong theoretical privacy guarantees, its adoption in real-world MLaaS pipelines is hindered by performance and orchestration challenges [ 9 ] . Existing studies primarily optimize cryptographic primitives but overlook the integration and scheduling aspects of HE workflows within distributed environments. Furthermore, current benchmarks lack standardized evaluation frameworks for measuring latency, throughput, and scalability in encrypted inference. This work addresses these gaps by proposing an end-to-end cloud-native architecture that unifies HE modules with orchestration-level optimizations, enabling elastic scaling and workload parallelization for privacy-preserving inference at production scale.
The proposed system introduces a modular, cloud-native framework for performing privacy-preserving ML inference using Homomorphic Encryption (HE) [ 10 ] . The architecture is built around three core principles: (1) confidentiality through computation on encrypted data, (2) scalability through containerized microservices, and (3) automation via Kubernetes-based orchestration. The workflow is designed to operate as a secure extension of ML-as-a-Service (MLaaS), supporting inference requests from clients without exposing either model parameters or input data.
The architecture consists of four primary layers— Client Encryption Layer , Homomorphic Inference Engine , Orchestration Layer , and Secure Storage and Logging Layer . The workflow begins when a client encrypts their input data locally using an HE public key and transmits it to the ML inference API endpoint. The encrypted input is then processed by the inference engine, which performs computations directly on ciphertexts using an HE-compatible model. Results are returned in encrypted form and decrypted client-side, ensuring that raw data never leaves the client domain.
Client Encryption Layer: Responsible for local data preprocessing and HE encryption using libraries such as SEAL or PALISADE. Keys are generated per client session to maintain data isolation and revocability. Homomorphic Inference Engine: Executes model computations (e.g., linear layers, convolutions, polynomial activations) on ciphertexts. The engine includes support for ciphertext packing and operator fusion to optimize throughput.
Orchestration Layer: Built atop Kubernetes, it manages containerized HE microservices, enabling auto-scaling, service discovery, and load balancing. A lightweight controller monitors CPU utilization and dynamically distributes encrypted computation tasks across pods. Secure Storage and Logging Layer: Stores encrypted intermediate states, metadata, and audit logs. Integration with cloud key management services (e.g., AWS KMS, Azure Key Vault) ensures secure key lifecycle management.
Fig. 1 illustrates the proposed cloud-native HE workflow for secure ML inference. Each component communicates through encrypted channels and is orchestrated dynamically to maintain confidentiality, scalability, and fault tolerance. When a client initiates an inference request, data is first encrypted locally and transmitted over a secure channel (TLS 1.3). The HE inference engine receives the ciphertext, performs the necessary model computations using bootstrappable HE operations, and generates encrypted predictions. The orchestrator dynamically scales microservices based on the workload queue length and resource metrics. Once the computation is completed, the result of the ciphertext is stored in the secure data layer and returned to the client for decryption. This architecture ensures full data confidentiality, dynamic scalability, and fault isolation under zero-trust cloud conditions.
While homomorphic encryption (HE) enables privacy-preserving computation, its integration into machine learning inference pipelines is hindered by significant computational and memory overhead. In this section, we describe a set of architectural and cryptographic optimization strategies that reduce latency and enhance throughput in encrypted model inference without compromising security guarantees. The proposed techniques—ciphertext packing, polynomial modulus switching, and operator fusion—are implemented at both cryptographic and orchestration layers to achieve a balanced trade-off between security, accuracy, and performance.
Ciphertext packing allows multiple plaintext values to be encoded into a single ciphertext using the Chinese Remainder Theorem (CRT) and the batching feature of schemes such as BFV and CKKS [ 11 ] . This technique enables parallel computation over packed data slots, thus exploiting data-level parallelism in encrypted inference. For a model inference vector I = [ x 1 , x 2 , … , x n ] \mathbf{x}=[x_{1},x_{2},\ldots,x_{n}] , the encoding function E I ( ⋅ ) E(\cdot) transforms it into a ciphertext C = E I ( I ) C=E(\mathbf{x}) such that: where w w is a constant weight vector representing layer parameters. This enables multiple neuron computations to be performed in a single homomorphic multiplication, significantly improving inference throughput. In our implementation, packing 1024 slots per ciphertext achieved an average 2.6 × \times speedup with negligible accuracy loss.
HE computation relies on polynomial rings I q I [ x ] / ( x n + 1 ) \mathbb{Z}_{q}[x]/(x^{n}+1) where q q represents the ciphertext modulus. As ciphertexts undergo repeated homomorphic operations, noise accumulates and may eventually render decryption infeasible. Polynomial modulus switching dynamically adjusts the modulus q q to control noise growth, preserving decryption correctness while maintaining security against lattice attacks. Let C q C_{q} denote a ciphertext under modulus q q , then: This transformation scales both ciphertext and noise proportionally, reducing computational overhead during deep circuit evaluation. The integration of this technique within the inference pipeline reduced average ciphertext size by 38%, thereby improving memory efficiency in containerized HE workloads.
To minimize communication and bootstrapping costs, adjacent arithmetic operations are fused into composite operators that can be executed within a single homomorphic evaluation. For example, consecutive linear transformations and bias additions in a neural layer: are fused into a unified encrypted operation, reducing the number of ciphertext multiplications and additions required. In Kubernetes deployment, operator fusion further reduces inter-container communication latency by minimizing the number of serialized computation calls. Empirical evaluations show that operator fusion yields a 27% decrease in end-to-end inference latency for HE-based CNNs and logistic regression models.
At the orchestration level, a runtime controller monitors resource utilization across pods to balance the distribution of HE computations. A priority-based scheduling policy assigns higher compute nodes to ciphertexts with larger modulus depth or bootstrapping requirements. This ensures that latency-sensitive tasks are offloaded to nodes with optimized vectorized arithmetic libraries (e.g., Intel HEXL). The resulting architecture achieves near-linear scalability under increasing inference loads.
The combination of the above strategies leads to measurable gains in encrypted inference performance. Ciphertext packing provides data-level parallelism, modulus switching mitigates noise propagation, operator fusion minimizes bootstrapping cost, and runtime optimization ensures efficient resource allocation. Collectively, these optimizations establish the foundation for a scalable, cloud-native homomorphic encryption workflow capable of supporting real-world ML inference workloads.
To validate the efficiency and scalability of the proposed cloud-native homomorphic encryption (HE) workflow, extensive experiments were conducted across multiple machine learning inference workloads. This section details the experimental configuration, performance metrics, and comparative analysis of the optimized system against baseline HE implementations. The prototype was implemented using the Microsoft SEAL v4.2 library integrated with a TensorFlow-based inference engine.
The workflow was deployed in a Kubernetes cluster comprising six worker nodes, each equipped with an Intel Xeon 3.0 GHz processor, 32 GB RAM, and Ubuntu 22.04. All communications between services were secured via TLS 1.3 and monitored using Prometheus and Grafana dashboards. Container orchestration leveraged Kubernetes Horizontal Pod Autoscaler (HPA) with a scaling threshold of 70% CPU utilization.
4. Practical Deployment, Analysis & Case Studies Model 1: Logistic Regression for binary classification on the UCI Breast Cancer dataset. Each model was trained using plaintext data and exported to a homomorphically compatible representation via polynomial approximation of activation functions (e.g., square or cubic functions).
Table I compares the proposed system with baseline HE inference workflows without optimization. The optimized pipeline demonstrates notable improvements in both latency and throughput across all evaluated models. Resource-level metrics were captured via Prometheus to evaluate the scalability behavior of the Kubernetes cluster under varying inference loads. Table II summarizes the impact of runtime optimization on resource consumption.
Fig. 2 visualizes the latency trends across scaling cluster sizes. The nearly linear performance improvement confirms the scalability of the proposed orchestration strategy. The experimental findings confirm that the optimized HE workflow achieves significant performance improvements across multiple dimensions. Latency was reduced by up to 69% compared to baseline implementations, primarily due to ciphertext packing and operator fusion. The dynamic scaling feature of the orchestration layer ensures that resource utilization remains below 75% under peak load, maintaining system stability. Furthermore, the workflow achieved consistent inference accuracy with an average deviation of less than 0.2% compared to plaintext inference, confirming that polynomial approximations of activation functions do not substantially degrade model fidelity. These results demonstrate that practical, real-time privacy-preserving ML inference is achievable in modern cloud-native infrastructures.
The experimental evaluation demonstrates that the proposed cloud-native homomorphic encryption (HE) workflow bridges a long-standing divide between cryptographic privacy and practical deployability. By embedding HE operations into a container-orchestrated infrastructure, the system transforms secure inference from a theoretical construct into a scalable production-ready service. The synergy between cryptographic optimization and orchestration logic plays a decisive role: ciphertext packing and operator fusion deliver algorithmic efficiency, while Kubernetes scheduling guarantees elasticity and isolation across multi-tenant workloads.
A salient outcome of this study is the realization that HE overhead, traditionally considered prohibitive, can be mitigated through architectural co-design rather than purely cryptographic tuning. Integrating runtime monitoring and adaptive load balancing permits the inference pipeline to maintain sub-100 ms latency without weakening security parameters. This finding suggests a paradigm shift—from viewing HE as a cryptographic bottleneck to treating it as a parallelizable compute workload that benefits from cloud-native principles. Furthermore, the near-linear scalability observed across pods confirms that encrypted computation can exploit distributed concurrency similar to plaintext inference when orchestrated efficiently.
Despite these advances, several technical constraints remain. First, full-scale bootstrapping operations continue to dominate computational cost, restricting the depth of neural networks that can be homomorphically evaluated. Although batching and modulus switching alleviate some of the burden, real-time inference for deep architectures (e.g., ResNet, BERT) remains infeasible on general-purpose CPUs. Second, ciphertext expansion increases network I/O and storage overhead, necessitating high-bandwidth inter-pod communication and larger memory allocations. Third, polynomial activation approximations introduce small but measurable accuracy deviations in certain nonlinear tasks. Finally, security proofs rely on parameter configurations that balance performance and hardness assumptions; improper tuning may reduce effective security below recommended 128-bit post-quantum levels.
From an operational perspective, integration with existing ML frameworks is still non-trivial. Converting trained models into HE-compatible forms often requires manual graph transformation and coefficient rescaling, impeding automation. Additionally, while Kubernetes offers elasticity, container startup latency can impact response time for burst workloads, suggesting the need for pre-warmed service pools or lightweight serverless extensions.
Future research will focus on several promising directions. The first involves the incorporation of hardware acceleration—leveraging GPUs, FPGAs, or ASICs optimized for lattice arithmetic—to reduce bootstrapping latency by an order of magnitude. The second is the exploration of hybrid secure-computation models that combine HE with trusted execution environments (TEEs) or secure multi-party computation (MPC), enabling context-aware partitioning of encrypted and enclave-based workloads. Third, the development of an auto-tuning compiler capable of selecting optimal HE parameters and packing strategies based on workload profiling could substantially enhance usability.
Moreover, deploying the framework across heterogeneous multi-cloud and federated environments will enable evaluation under diverse trust boundaries, expanding applicability to healthcare, finance, and government analytics. Incorporating explainability mechanisms to trace encrypted inference decisions—without revealing sensitive data—represents another emerging frontier for regulatory compliance and auditability. Ultimately, the convergence of cryptographic rigor, cloud-native design, and intelligent orchestration will shape the foundation of next-generation secure AI infrastructures.
This work presented a comprehensive framework for the design, deployment, and optimization of cloud-native homomorphic encryption (HE) workflows that enable secure machine learning inference. By unifying cryptographic primitives with cloud orchestration principles, the proposed system addresses one of the most persistent challenges in privacy-preserving AI: achieving high performance without compromising data confidentiality. The architecture integrates containerized HE modules within a Kubernetes-managed environment, allowing elastic scaling, fault isolation, and automated workload distribution for encrypted computations.
The results of this study demonstrate that practical, near-real-time inference on encrypted data is achievable under production-like conditions. Through the implementation of ciphertext packing, polynomial modulus switching, and operator fusion, the system reduced inference latency by up to 69% compared to traditional HE baselines, while maintaining accuracy deviations below 0.2%. Furthermore, the integration of runtime scheduling policies allowed resource utilization to remain efficient even under dynamic workloads, validating the scalability of the orchestration strategy. These outcomes collectively confirm that cloud-native design principles—such as microservice modularity, auto-scaling, and continuous monitoring—can effectively complement cryptographic mechanisms to yield deployable, high-performance privacy-preserving ML pipelines.
From a broader perspective, this research bridges the gap between theoretical homomorphic encryption models and their real-world cloud applications. The framework not only advances the state of privacy-preserving ML-as-a-Service (MLaaS) systems but also establishes a foundation for standardized, interoperable HE orchestration models. The proposed workflow aligns with emerging zero-trust and confidential computing paradigms, positioning it as a viable blueprint for secure AI deployment in healthcare analytics, financial modeling, and government intelligence systems. By demonstrating that confidentiality and scalability are not mutually exclusive, this work underscores the transformative potential of integrating HE into the broader ecosystem of secure, decentralized AI infrastructures.
Looking ahead, several avenues for future exploration remain open. Hardware acceleration and hybrid secure-computation models hold the promise of dramatically improving computational efficiency, while automated parameter tuning and federated orchestration could enhance adaptability and portability across diverse cloud platforms. As regulatory demands for privacy-preserving AI intensify, frameworks such as the one presented in this paper will play a crucial role in defining the next generation of trustworthy, quantum-resistant machine learning systems.
The authors would like to express their gratitude to the research mentors and institutional computing center for providing technical resources and valuable feedback during the course of this work. The prototype implementation was supported by the Secure AI Systems Lab, whose infrastructure and expertise enabled large-scale encrypted inference testing. The authors also acknowledge the constructive input from peer reviewers and academic collaborators, which substantially improved the rigor and clarity of this study.
Microsoft SEAL —powered by open-source homomorphic encryption technology—provides a set of encryption libraries that allow computations to be performed directly on encrypted data. This enables software engineers to build end-to-end encrypted data storage and computation services where the customer never needs to share their key with the service. Homomorphic Encryption refers to a new type of encryption technology that allows computation to be directly on encrypted data, without requiring any decryption in the process. The first homomorphic encryption scheme was invented in 2009 and several improved schemes were created over the following years. There were a few notable and publicly available implementations, but their use required extensive understanding of the complicated mathematics underlying homomorphic encryption and were not easily usable by normal software developers.
Our goal was different: making homomorphic encryption easy to use and available for everyone . Today, Microsoft SEAL reaches this goal by providing a simple and convenient API with state-of-the-art performance. Microsoft SEAL comes with several detailed and thoroughly commented examples, demonstrating how the library can be used correctly and securely, and explaining any necessary background material.
In traditional cloud storage and computation solution customers need to trust the service provider to store and manage their data appropriately, e.g., not to share it with third parties without the customer’s consent. Microsoft SEAL replaces this trust with state-of-the-art cryptography, allowing cloud services to provide both encrypted storage and computation capabilities, while still guaranteeing that their customer’s data will never be exposed to anyone in unencrypted form.
5. Performance Evaluation & Extended Technical Observations In traditional cloud storage and computation solutions the cloud need to have unencrypted access to customer data to compute on it, necessarily exposing the data to the cloud operators. Data privacy relies on access control policies implemented by the cloud and trusted by the customer.
With Microsoft SEAL, the cloud operators will never have unencrypted access to the data they are storing and computing on. This is possible through homomorphic encryption technology, that allows computations to be performed directly on encrypted data. Data privacy relies on state-of-the-art cryptography (mathematics) and all information release will be controlled by the customer.
Quick answer: Homomorphic encryption (HE) lets a server compute on encrypted data and return an encrypted result that decrypts to the same answer as plaintext computation. This matters because cloud providers and AI models can process sensitive data without ever seeing it. Recommendation: pilot CKKS or BFV on a narrow use case before committing production workloads to fully homomorphic encryption (FHE).
Published: June 2025. Updated: August 2026. Reviewed by Encryption Consulting’s Encryption Advisory team. Homomorphic encryption (HE) is a class of encryption that allows a party to perform computations directly on ciphertext, without ever decrypting it, such that decrypting the result gives the same answer as running the computation on the original plaintext. It matters because it lets an organization hand sensitive data to a cloud service, an AI model, or a third-party analytics vendor and get a useful answer back, without that party ever seeing the underlying data.
In a typical HE workflow, a client generates a key pair and, for the more advanced schemes, a separate evaluation key. The client encrypts data with the public key and sends only ciphertext to the server. The server uses the evaluation key to run additions and multiplications on that ciphertext, never touching the private key and never recovering plaintext. The client alone decrypts the final result with the private key. As ISACA’s 2024 white paper on privacy enhancing technologies puts it, HE “can be used to obtain insights from computation without revealing the contents of a dataset,” keeping data encrypted “at rest, in transit, and during computation.” This post defines every acronym you need, walks through how to pick a scheme, states plainly how slow FHE actually is today, and tells you where HE genuinely fits against alternatives like secure multi-party computation (MPC) and trusted execution environments (TEEs). For a shorter, plain-language primer on the concept, see our related explainer, Homomorphic Encryption – Basics .
HE comes in three tiers, distinguished by which operations are allowed on ciphertext and how many times. Within FHE, the scheme you choose determines what kind of math your application can actually run. The table below summarizes the four schemes that matter in practice, all of which are implemented in the open-source OpenFHE library and, for BFV and CKKS, in Microsoft SEAL .
Rule of thumb for selection: use BFV or BGV when your result has to be exact, use CKKS when you can tolerate a small approximation error in exchange for speed on machine learning and statistical workloads, and use TFHE when your computation is dominated by comparisons or branching rather than large-integer arithmetic. An ENISA report on data protection engineering summarizes the underlying trade-off well: FHE “has good protection and utility but poor performance,” which is exactly why scheme choice and scope matter more than in ordinary encryption decisions.
HE is designed for an honest-but-curious (semi-honest) compute provider: a party that will run the computation you asked for correctly, but that you do not want to trust with your plaintext. HE removes that trust requirement entirely; the server operates on ciphertext it cannot read, and this holds even if the server’s storage or memory is later breached, because there is never plaintext there to steal.
Getting the threat model right up front is what separates an HE deployment that actually reduces risk from one that just moves computation behind an expensive layer of math without changing who has to be trusted. Plainly: FHE is still orders of magnitude slower than plaintext computation, and any vendor claiming otherwise for general-purpose workloads should be pressed for a specific benchmark. Duality Technologies’ 2026 benchmark write-up puts raw, unoptimized FHE overhead at roughly 10,000 times slower than plaintext on CPU-only hardware, narrowing to roughly 10 to 100 times slower for throughput-oriented workloads once batching and optimized parameters are applied. The same source reports that FHE performance overall has improved by a factor of 1,000 to 10,000 over the past five years, and that with optimized CKKS and batching, encrypted logistic regression inference over 10,000 records can complete in 2 to 10 seconds, while encrypted batch analytics over 1 million records can finish in minutes on GPU-accelerated hardware.
For heavier workloads, the gap is still large. Raluca Ada Popa of UC Berkeley’s MC2 project notes that training a moderate-size neural network such as VGG16 on a dataset like CIFAR-10 under HE or MPC “could range into the years,” which is why full model training under FHE remains impractical for most organizations today; encrypted inference on a small model, or aggregate analytics, is the realistic near-term target. This lines up with the IEEE’s own summary , which calls HE “one of the most powerful” privacy technologies available while acknowledging it is “still in an early phase” for general business use.
What is actually closing the gap: algorithmic improvements (CKKS for approximate arithmetic, TFHE’s fast bootstrapping), compiler tooling (OpenFHE, Zama’s Concrete), and hardware acceleration on GPUs and emerging FHE-specific accelerators. Treat any performance claim you are given the same way: ask for the scheme, the operation, the hardware, and the batch size, because “homomorphic encryption is fast now” without those four details is not a verifiable claim.
HE is one of three practical approaches to computing on data you do not want to expose to the compute provider. The others are secure multi-party computation (MPC), where the data is split into secret shares across parties that must not collude, and trusted execution environments (TEEs), also called confidential computing, where the data is decrypted inside a hardware-isolated enclave. Each trades trust for performance differently.
Choose HE when you cannot trust the underlying hardware or cloud provider at all and the workload is narrow enough to tolerate the overhead. Choose MPC when several distinct organizations each hold a piece of the data and none can be a single point of trust. Choose a TEE when you need near-native performance and can accept a hardware-rooted trust assumption, keeping in mind that enclaves carry their own side-channel history and depend on the cloud provider patching firmware promptly.
HE shifts key management risk rather than removing it. The client’s secret key must never reach the server; only the public key (for encryption) and the evaluation key (for computation) are shared. In practice, that creates a few dependencies most teams underestimate: Because the tooling ecosystem for HE key lifecycle management is far less mature than standard PKI, treat HE key custody, rotation, and inventory as a first-class design decision, not an afterthought bolted onto the cryptography.
Most of these deployments are still narrow and pilot-scale rather than default architecture, which is consistent with the performance picture above: HE earns its cost fastest on specific, high-sensitivity computations, not as a wholesale replacement for standard data processing. HE strengthens the technical safeguards these frameworks already require, but it does not replace the legal and procedural obligations underneath them.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Homomorphic%20encryption • https://en.wikipedia.org/wiki/Secure%20multi-party%20computation • https://en.wikipedia.org/wiki/Private%20biometrics • https://arxiv.org/html/2510.24498v1 • https://www.microsoft.com/en-us/research/project/microsoft-seal/ • https://www.encryptionconsulting.com/homomorphic-encryption/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Homomorphic Encryption System For Secure Cloud Computation.
[*] Metasploit Scan Running on Target Subnet for Homomorphic Encryption System For Secure Cloud Computation... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |