Complete Technical Paper Content — Honeypot For Web Application Attack Monitoring
Overview & System Context
Honeypot For Web Application Attack Monitoring: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~8059 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Honeypots are security devices whose value lie in being probed and compromised. Traditional honeypots are servers (or devices that expose server services) that wait passively to be attacked. Client Honeypots are active security devices in search of malicious servers that attack clients. The client honeypot poses as a client and interacts with the server to examine whether an attack has occurred. Often the focus of client honeypots is on web browsers, but any client that interacts with servers can be part of a client honeypot (for example ftp, email, ssh, etc.). There are several terms that are used to describe client honeypots. Besides client honeypot, which is the generic classification, honeyclient is the other term that is generally used and accepted. However, there is a subtlety here, as "honeyclient" is actually a homograph that could also refer to the first known open source client honeypot implementation (see below), although this should be clear from the context.
HoneyMonkey [3] is a web browser based (IE) high interaction client honeypot implemented by Microsoft in 2005. It is not available for download. HoneyMonkey is state based and detects attacks on clients by monitoring files, registry, and processes. A unique characteristic of HoneyMonkey is its layered approach to interacting with servers in order to identify zero-day exploits. HoneyMonkey initially crawls the web with a vulnerable configuration. Once an attack has been identified, the server is reexamined with a fully patched configuration. If the attack is still detected, one can conclude that the attack utilizes an exploit for which no patch has been publicly released yet and therefore is quite dangerous.
Honeypots are a powerful tool for detecting and analyzing cyber threats. By mimicking real systems, they attract malicious actors, allowing security teams to observe their tactics, techniques, and procedures (TTPs) in a controlled environment. This guide walks you through the process of setting up a honeypot, focusing on open-source solutions. A honeypot is a decoy system or service designed to lure attackers. It serves as a trap that collects valuable information about potential threats, helping organizations improve their cybersecurity posture. Honeypots can mimic a range of assets, including servers, IoT devices, and even entire networks.
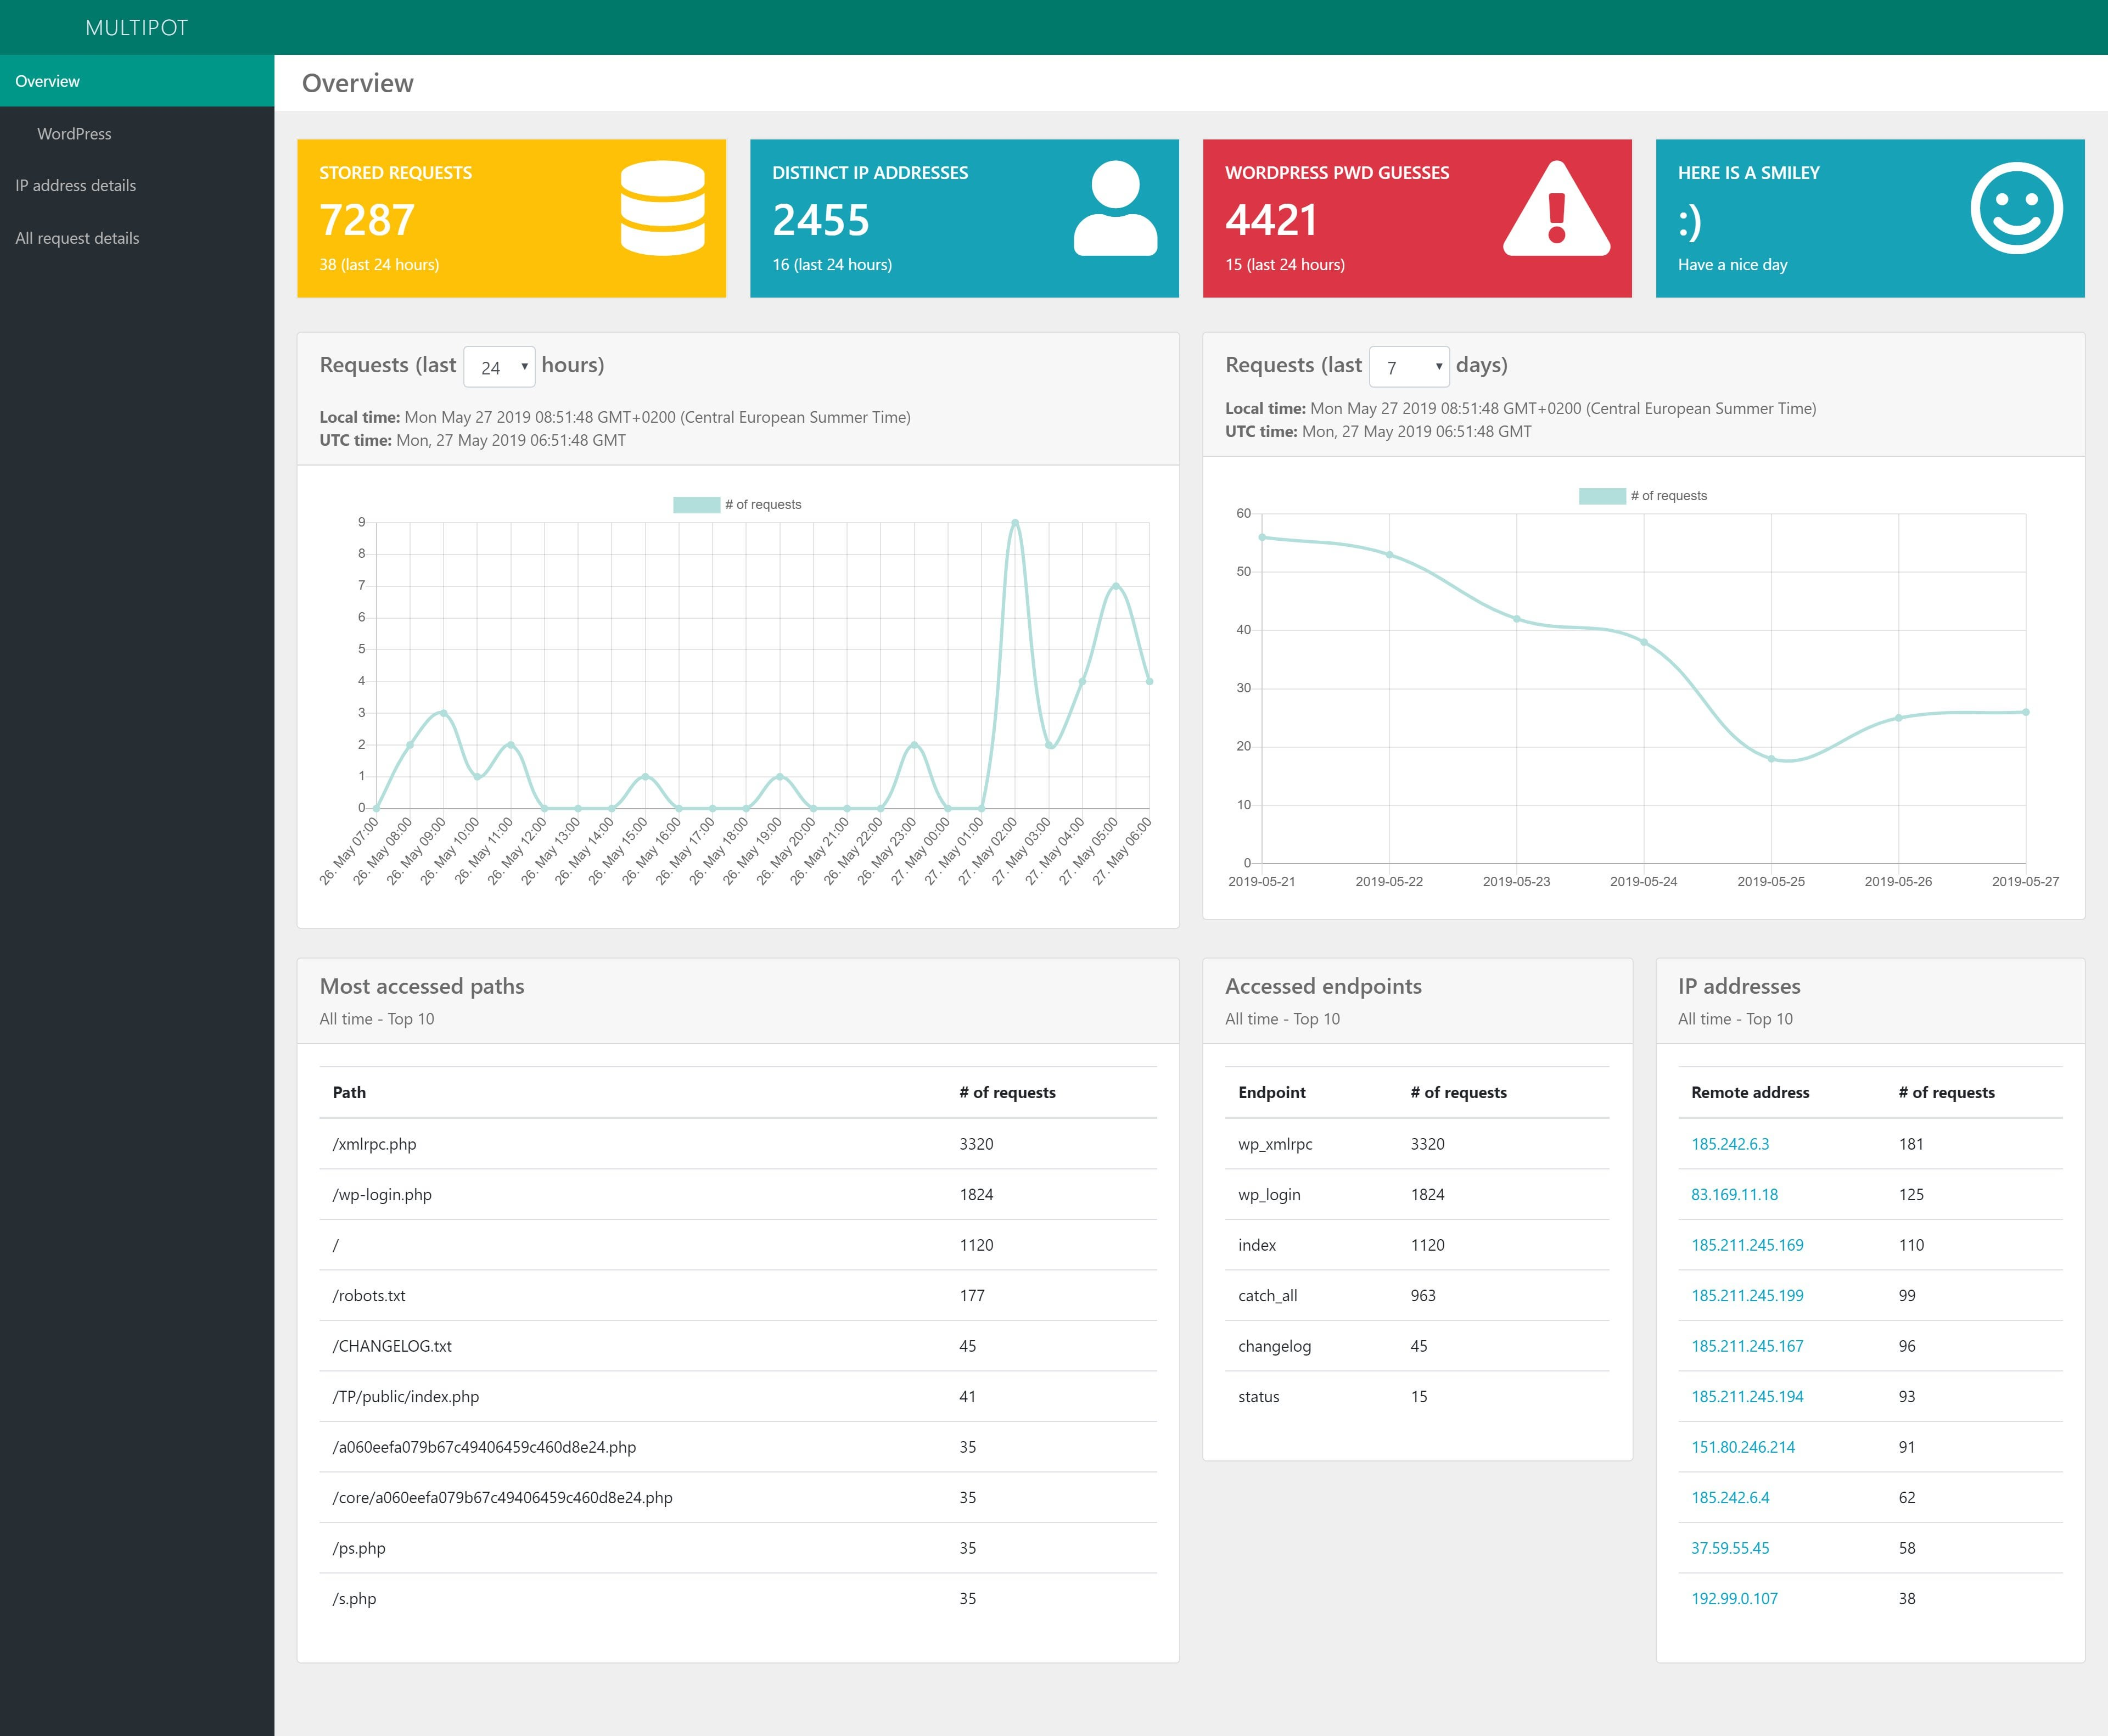
Figure 1: Multipot – a basic web application honeypot with built-in analysis ... Knowing your goals will help determine the type of honeypot you need (low-interaction, high-interaction, etc.) and its configuration. Several open-source tools are available for setting up honeypots. Popular options include: Start the honeypot service and ensure it is reachable by potential attackers. For example, to start Cowrie: Setting up a honeypot is a proactive way to stay ahead of cyber threats. With the right configuration and monitoring, it can provide critical insights into attacker methodologies. By following this guide, you’ll have a functional honeypot ready to defend and inform your cybersecurity efforts.
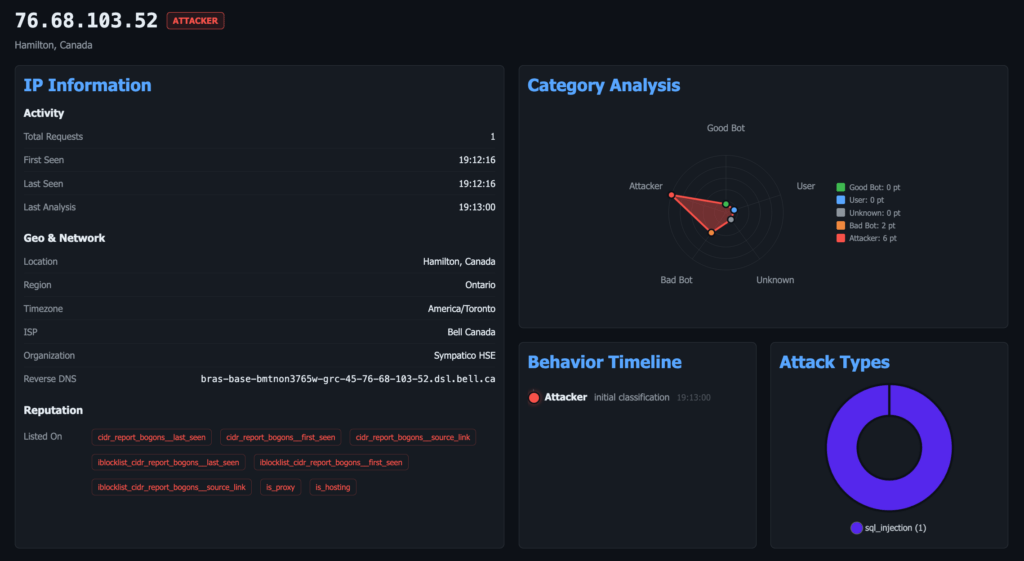
Figure 2: Krawl, un Web Honeypot open-source per attirare attacchi e organizzare ... WordPress Enumeration Before Exploitation: A Step-by-Step Guide for Security Professionals Setting up a honeypot is not about tricking attackers for fun. It is about creating a controlled system that shows how scanners, brute-force tools, and exploit kits behave without putting production assets at risk. A good honeypot setup gives you usable telemetry, clear isolation, and enough realism to attract real interest.
Discover how to think like an attacker, perform professional penetration tests, and produce trusted reports with this comprehensive online CompTIA Pentest+ training. A honeypot setup is a controlled decoy service or system used to attract and analyze cyber attacks without exposing real assets. The safest approach is to define a narrow goal, choose the right honeypot type, isolate it with strict network controls, log everything centrally, and review attacker behavior for intelligence. Done well, it supports detection, threat research, and incident response.
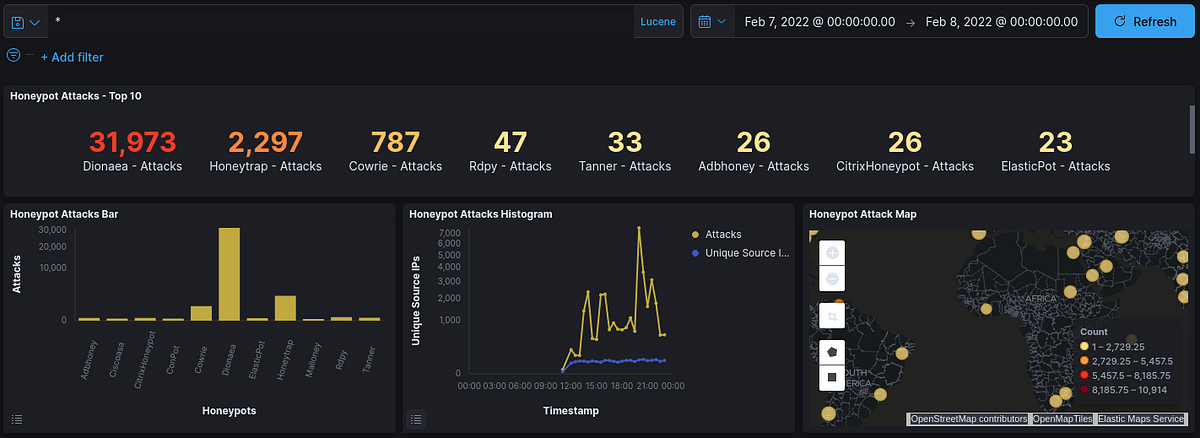
Figure 3: Learning the Prevalent Attacks of the Day with Honeypots | by Isaac ... A honeypot is a decoy system designed to look valuable enough to attract attackers while remaining controlled enough to study safely. In practice, that means you are building a sensor, not a fake production server. The better the honeypot setup, the better your visibility into scanning behavior, credential stuffing, payload delivery, and post-exploitation activity.
This guide walks through a practical honeypot setup, not a toy lab demo. The focus is on safe architecture, realistic lures, full logging, and analysis that supports detection engineering. That aligns well with the hands-on thinking behind the CompTIA Pentest+ Course (PTO-003), because the same attacker mindset helps you understand how adversaries probe, pivot, and persist.
The biggest honeypot mistakes are not technical at first. They are usually scoping mistakes, such as exposing real services, allowing outbound connections, or collecting logs without a plan to use them. The right honeypot type depends on what you want to learn and how much risk you can tolerate. A low-interaction decoy can capture scans and credential guesses with very little exposure. A high-interaction system can reveal more attacker behavior, but it also demands stronger isolation, monitoring, and legal review.
Low-interaction honeypots imitate a narrow service surface, such as SSH, Telnet, or a basic web login page. They are ideal for broad internet noise, brute-force attempts, and simple exploit probes. Tools such as Cowrie are common in this category because they collect useful session transcripts without giving attackers a full operating system to abuse. Medium-interaction honeypots emulate a fuller protocol experience, often enough to capture more convincing payloads and command sequences. These are useful when you need better fidelity for research or detection engineering, but still want containment. A medium-interaction setup is often the best balance for an enterprise team that wants actionable telemetry without the overhead of a live attacker sandbox.
High-interaction honeypots expose a real operating system or near-real service stack. They can reveal advanced post-compromise behavior, malware staging, and lateral movement attempts, but they also create the most risk. A system like this should only exist in a segmented environment with tight egress controls, separate logging, and a clear legal and operational justification.
The best environment depends on the mission. Enterprise networks usually need low- or medium-interaction decoys with strong segmentation. Research labs may justify more realism to study exploit chains. Segmented cloud environments can work well if security groups, flow logs, and outbound restrictions are carefully engineered. For threat modeling and attacker emulation, the NIST Cybersecurity Framework and NIST SP 800 guidance are useful references for structuring detection and response expectations: NIST Cybersecurity Framework and NIST SP 800-61 .
A good honeypot setup starts with one narrow objective. If you try to emulate SSH, web login, SMB, database access, and industrial control protocols at the same time, you usually create noise instead of insight. Pick one service or one attacker behavior and make that the measurement target. Scope is the boundary that tells the honeypot what it must not do. That includes real user data, production integrations, shared authentication systems, and any feature that could help an attacker move laterally. If the decoy service can talk to internal systems, it is no longer a decoy. It is a liability.
Your success criteria should be measurable. For example, you might count unique source IPs, password attempts, malware uploads, command execution attempts, or exploit chains captured in a week. If your goal is detection research, success might mean “we can reliably alert within 60 seconds of a login attempt.” If your goal is intelligence collection, success might mean “we captured one full session transcript and one payload sample with packet evidence.” That documentation matters later when someone asks why the system exists or whether a change request is safe. In a mature environment, your honeypot should map to a known security objective, not a side project. If you are building it to support detection engineering, the CISA Known Exploited Vulnerabilities Catalog is a practical source for understanding what is currently being weaponized in the wild.
Tool selection determines how believable, maintainable, and safe your honeypot setup will be. Some tools specialize in SSH and shell interaction. Others focus on malware capture, protocol emulation, or web lures. The wrong tool can waste time by generating unstructured logs or by exposing behavior that looks fake to attackers. Cowrie is a widely used low-interaction SSH and Telnet honeypot that captures login attempts, command sequences, and malware download activity. Dionaea is often used to trap malware and observe exploit behavior across network services.
Honeyd can emulate multiple hosts on a network. Glastopf was designed for web application attacks, though teams should verify current maintenance status before relying on it. Conpot is commonly used for industrial control system deception, especially when the goal is to observe protocol-specific probing. Platform choice also matters. A container is easy to deploy but may be too lightweight for realistic networking or strong isolation requirements. A virtual machine is usually a better default because it gives clearer boundaries, easier snapshots, and more predictable network controls. Bare metal can be justified for research, but it increases recovery effort and makes rollback slower. If you use a specialized network appliance , make sure it supports the logging and egress controls you need rather than just looking purpose-built.
Before you deploy, check tool maturity, issue history, documentation quality, and logging depth. A mature tool with average realism is often better than a flashy tool that has not been maintained. Also confirm compatibility with your OS, hypervisor, SIEM, and packet capture stack. If your honeypot cannot export data cleanly, it will be harder to analyze and easier to ignore. For official guidance on supported platforms and current features, use vendor and project documentation rather than third-party tutorials. For example, Microsoft documents virtualization and networking behavior in Microsoft Learn , and the Cowrie project documents its capture and logging design. When the goal is attacker analysis, the quality of the logs matters more than the novelty of the decoy.
A safe honeypot setup starts with isolation, not banners. The honeypot should be separated from production networks, sensitive cloud services, and any system that could be damaged by an outbound connection. If the decoy is reachable from the internet, that is fine. If the decoy can reach back into your environment, that is a problem. The strongest pattern is a segmented network with strict firewall rules, separate management access, and no trust relationship with internal systems. Use VLANs or cloud security groups to isolate the decoy. Add egress filtering so the honeypot cannot scan internal ranges or phone home freely. If you need log shipping, send logs one way to a collector that lives outside the honeypot segment.
Deployment decisions should also support recovery. Snapshots, immutable images, and infrastructure-as-code templates make it easier to rebuild the decoy after abuse or corruption. If you are using cloud infrastructure, keep security groups, route tables, and logging policies under version control. The more repeatable the deployment, the easier it is to validate after any change.
A honeypot with open egress can become an attack platform. If it can reach the internet without restriction, it may be used to download tools, beacon to command-and-control infrastructure, or probe internal resources through misconfiguration. For network segmentation, the principles in NIST guidance and the NIST SP 800-207 Zero Trust Architecture are useful. Even if you are not implementing Zero Trust fully, the core idea applies here: assume the decoy is untrusted and keep it boxed in.
Attackers do not spend time on systems that look obviously fake. A realistic decoy needs believable hostnames, service banners, users, files, and error messages. The goal is not perfect simulation. The goal is enough consistency that scanners, credential sprays, and opportunistic attackers keep going long enough for you to capture useful data. Start with the visible surface. Use a hostname that fits your environment, such as a mail relay, admin host, database server, or remote access box. Set banners that match the target service version you are pretending to run. If the service is SSH, make the banner and login flow plausible. If it is a web app, make the title, server headers, and error pages feel ordinary rather than polished.
Then add safe lures. Fake documents, placeholder configuration files, sample credentials, and decoy logs can encourage interaction. A weak-looking password file or a misnamed backup archive may draw more attention than a blank directory. Just make sure none of the lure content exposes real secrets or links to real services. Current attacker behavior still centers heavily on internet-facing services, weak authentication, and simple remote execution paths. That means SSH, RDP-like exposures, web admin panels, file shares, and exposed databases remain attractive decoy candidates. The Verizon Data Breach Investigations Report and MITRE ATT&CK are useful references for understanding common attacker technique patterns: Verizon DBIR and MITRE ATT&CK .
2. System Architecture & Core Working Principles If you cannot log it, you cannot analyze it. A useful honeypot setup records authentication attempts, commands, file writes, request headers, source addresses, timing, and session flow. The logs need to be detailed enough to support reconstruction, not just a yes-or-no alert.
Use both application logging and network telemetry. Application logs tell you what the attacker typed or requested. Packet capture tells you how the payload arrived, what was downloaded, and whether the attacker tried to beacon out. In many cases, the packet trail reveals more than the decoy service itself. Threat Intelligence work gets much easier when the honeypot exports clean, normalized data to a separate collector. Send logs to a SIEM, syslog server, or security data lake outside the honeypot segment. That way, if the decoy is wiped or tampered with, the evidence remains available. Consider adding packet capture with tools like tcpdump or Zeek, depending on the volume you expect and the storage you can support.
When you analyze traffic, preserve timestamps in UTC and include enough context to correlate with firewall, DNS, proxy, and endpoint telemetry. That allows you to see whether a source is just scanning one host or touching multiple assets. If you are building rules or detections, the combination of application logs and packet data is usually far more useful than either alone. For logging and detection design, the SANS Institute and CISA both provide practical guidance on defensive monitoring and incident handling. A honeypot that produces clean evidence is much more valuable than one that only generates noise.
Before you expose a honeypot, verify that it is reachable only where you intend and blocked everywhere else. Validation is where many weak setups fail. A decoy that looks isolated on paper may still route into internal networks, cloud control planes, or shared services through an overlooked rule or default route. Test from at least two perspectives: from the intended attack surface and from trusted internal hosts. The honeypot should answer on the public or segmented network side, but it should not be reachable from production systems, admin networks, or management interfaces. Confirm that outbound traffic is either blocked or tightly limited to the exact destinations needed for logging or updates.
Success is visible in the evidence. You should see session logs, packet captures, and alerts matching the simulated activity. Failure is also visible: missing logs, unexpected outbound traffic, or internal routing to systems that should be off limits. If you are using cloud infrastructure, verify security group flow logs and route tables as part of the launch checklist. The OWASP community is a useful reference when validating web-facing decoys, especially if your lure includes login pages or web forms. The same rule applies regardless of the service: what matters is proving the system behaves as intended before real attackers find it.
Honeypot value comes from analysis, not collection. After the first wave of activity, classify what you saw into scan, brute force, exploit attempt, payload delivery, command-and-control behavior, or post-compromise action. That classification helps you separate background noise from behavior that deserves a response. Look for patterns across sessions. Repeated username attempts can suggest automation. A series of requests from different IPs with the same user agent can indicate distributed probing. One source downloading a payload and immediately trying a second-stage connection is more interesting than a single failed login. You are trying to identify intent, tooling, and follow-on risk.
Incident Response support is one of the strongest use cases for a honeypot. If the activity resembles a real compromise path, compare it with your firewall logs, DNS logs, and endpoint telemetry. That comparison can confirm whether the same attacker is already touching other systems or whether the honeypot is simply seeing generic internet noise. Use the MITRE ATT&CK framework to map observed steps to known techniques when you need consistent language for reporting.
Use the output to improve defenses beyond the honeypot itself. A repeated exploit attempt may justify a detection rule. A common payload path may justify a YARA concept or endpoint alert. A burst of scans may help you prioritize perimeter hardening. That is the real payoff of a solid honeypot setup: it turns attacker behavior into practical security work. If your team is building detections or validating attack paths, the same skills reinforced in the CompTIA Pentest+ Course (PTO-003) are useful because they teach how to think like the person on the other side of the keyboard. That perspective is what makes honeypot data actionable instead of just interesting.
A static honeypot gets stale. Attackers adapt, scanners change, and common targets shift. If you leave a decoy untouched for months, it becomes predictable and less useful. Regular refreshes keep the system believable and improve the odds that new attacker activity will engage with it. Update banners, fake credentials, file names, and exposed versions on a schedule. You do not need constant churn, but you do need enough variation to stay relevant. Review logs weekly or monthly depending on traffic volume, then adjust lure content and alert thresholds based on what you actually captured.
Patch the host, hypervisor, and management plane even if the decoy service itself is intentionally limited. This is a common blind spot. Teams assume the fake service is the only thing that matters, but the underlying platform is still real infrastructure. Keep snapshots, backups, and rebuild scripts current so recovery stays fast. Maintenance also includes deciding when to stop. A honeypot that generates only background noise may not be worth the operational effort. A decoy that creates too much alert fatigue or begins to resemble a real service too closely can be equally problematic. If the system no longer supports a security objective, redesign it or decommission it.
Treat the honeypot like production infrastructure from a maintenance standpoint, even if it is intentionally fake from a service standpoint. That means version control, patching, logging review, and a rollback plan. The most common mistakes are the ones that turn a useful decoy into a risk. The first is connecting the honeypot to production systems or shared identity services. If the decoy can authenticate against real accounts or reach real databases, it is not isolated enough.
The second mistake is assuming fake equals safe. A honeypot can still be used as a pivot point if egress is loose or management access is exposed. The third mistake is collecting data without analyzing it. Raw logs pile up fast, but they do not improve security unless someone reviews them and turns them into detections, tickets, or reports. Another common failure is overexposure. If you make the honeypot too realistic without the ability to contain it, you create a system that is attractive to attackers but hard to defend. That is the wrong tradeoff. In most organizations, a narrower, well-instrumented decoy is better than a broad but fragile one.
For policy and risk framing, the ISACA community and the NIST risk-management publications are useful sources for governance language. A honeypot should fit your security program, not operate outside it. Honeypot findings are most valuable when they feed the rest of the security stack. Use captured indicators in SIEM rules, IDS signatures, endpoint detections, and blocklists when appropriate. A honeypot can give you the exact usernames, request paths, payload hashes, or exploit patterns that defenders need to detect elsewhere.
One practical approach is to turn the honeypot into a validation source. If the decoy shows repeated SSH password spraying, test whether your authentication alerts would catch the same pattern on real assets. If it captures a specific payload path, check whether your proxies or EDR tools would flag the same sequence on an actual host. That makes the honeypot a proving ground for detections, not just a trap.
You can also compare honeypot telemetry with your broader visibility stack. DNS logs may show follow-on infrastructure. Firewall logs may show scan bursts or blocked callbacks. Endpoint telemetry may reveal whether similar binaries ever reached internal endpoints. This cross-correlation is what turns raw deception data into a threat picture. That is where a well-run honeypot pays off. It creates evidence that supports action. The system is not there to impress anyone. It is there to reveal what attackers actually do and help you make better defensive decisions faster.
Discover how to think like an attacker, perform professional penetration tests, and produce trusted reports with this comprehensive online CompTIA Pentest+ training. A strong honeypot setup depends on four things: purpose, isolation, realism, and disciplined monitoring. If you define the goal first, choose the right interaction level, isolate the system properly, and log deeply, the honeypot becomes a reliable sensor instead of a curiosity project.
The safest and most useful approach is simple. Choose one target, expose only what you need, block what you do not, and review the results regularly. That workflow helps you attract attacks without creating unnecessary risk, which is exactly what a production-minded honeypot should do. If you are building or refining your own honeypot setup, use it to improve your detection engineering, validate controls, and sharpen your understanding of attacker behavior. For teams building hands-on defensive and offensive skills, the same mindset is reinforced in the CompTIA Pentest+ Course (PTO-003) through practical attack-path thinking and reporting discipline.
A honeypot is a security mechanism that creates a decoy environment designed to attract cyber attackers. It simulates vulnerable systems or services to lure malicious actors away from critical assets. The importance of honeypots lies in their ability to provide valuable insights into attacker behaviors, techniques, and tools. By analyzing interactions with the honeypot, security teams can better understand emerging threats and develop more effective defense strategies.
Creating realism involves deploying honeypots that mimic genuine systems, including open ports, services, and vulnerabilities that match your organization’s environment. Use common configurations and software versions to increase believability. Regularly updating and maintaining the honeypot to reflect current system states and vulnerabilities enhances its attractiveness. Incorporating fake data and realistic network traffic also helps lure attackers and gather meaningful telemetry.
Isolation is critical to prevent attackers from pivoting to other parts of your network. Use network segmentation techniques such as VLANs, firewalls, and DMZs to separate the honeypot environment from critical assets. Additionally, enforce strict access controls and monitor all interactions with the honeypot. Regularly review logs and traffic to ensure that the honeypot remains contained and does not pose a risk to your operational infrastructure.
Key data includes attack vectors, tools and techniques used, malware samples, and command-and-control communication patterns. Collecting network traffic, system logs, and attacker payloads provides a comprehensive view of the threat landscape. 3. Software Implementation, Frameworks & Protocols This telemetry helps in identifying new vulnerabilities, understanding attacker motives, and developing targeted defensive measures. Proper data collection also facilitates research and sharing insights with the cybersecurity community.
One misconception is that honeypots are only useful for catching hackers; in reality, they also serve as proactive defense tools for understanding attacker behaviors. Another is that honeypots are easy to set up and maintain, but effective deployment requires careful planning and ongoing management. Additionally, some believe honeypots can replace other security measures. However, they should complement traditional defenses like intrusion detection systems and firewalls rather than serve as standalone solutions. Properly managed honeypots can significantly enhance an organization’s security posture.
A honeypot can show you what attackers actually do, not just what your logs say they did. If you are building threat intelligence , improving cyber defense , or adding another layer of attack monitoring to your stack, a well-placed honeypot is one of the most useful cybersecurity tools you can deploy without exposing production assets. Learn essential ethical hacking skills to identify vulnerabilities, strengthen security measures, and protect organizations from cyber threats effectively A honeypot is a decoy system used for cyber threat intelligence, attack monitoring, and cyber defense by attracting suspicious activity in a controlled way. When deployed safely, it reveals scan patterns, login attempts, payloads, and attacker tactics that can improve detection rules, firewall policy, and incident response. The key is isolation, logging, and analysis.
A honeypot is a decoy system designed to attract suspicious activity so defenders can study attacker behavior in a controlled environment. It looks like a real host, application, or service, but its real purpose is observation, not production work. That makes a honeypot useful in three distinct ways. Deception lures attackers away from valuable assets, detection identifies hostile activity through unexpected interactions, and prevention reduces the chances that an attacker will reach real systems by forcing them to interact with a monitored trap.
In a threat intelligence program, the value is in the detail. A honeypot can reveal scan patterns, brute-force login attempts, web shell uploads, command syntax, payload delivery methods, and signs of lateral movement attempts. It can also show timing, repetition, automation patterns, and whether the same source is probing SSH, web apps, or file shares in sequence. Cyber Threat Intelligence becomes more useful when it is based on observed behavior instead of speculation. Honeypot telemetry complements SIEM alerts, firewall events, and commercial threat feeds by giving you direct evidence of what was tried, when it was tried, and how the attacker responded.
“A honeypot is not just bait; it is an evidence source that can turn anonymous noise into repeatable defensive insight.” Low-interaction honeypots simulate a service with limited functionality. They are safer, easier to manage, and better for collecting large volumes of scan and brute-force data, but they usually expose less attacker tradecraft. High-interaction honeypots provide a more realistic environment, often with a real operating system and fuller service behavior. They can capture richer session detail and malware behavior, but they also increase the risk of abuse, escape, or pivoting if isolation is weak.
The practical rule is simple. Use low-interaction systems when you want broad visibility and low operational overhead. Use high-interaction systems only when your team can manage containment, logging, and response with discipline. For ethical and legal boundaries, collect only the data you are authorized to collect, store it according to policy, and never allow the decoy to be used as a launch point against third parties. The NIST SP 800-61 incident handling guidance is a useful reference for handling evidence and response workflow, while the CISA guidance on honeypots and honeynets is a practical starting point for safe use.
A honeypot should be treated as monitored security infrastructure, not an experiment you forget about. If it is not logged, segmented, and reviewed, it is just another unmanaged host with a risky IP address. Start with the question most teams skip: what are you trying to learn? A honeypot designed for early warning will look different from one used for malware collection, attacker profiling, or detection engineering. The objective determines what you expose, how much interaction you allow, and how aggressively you monitor the system.
If your goal is early warning, you want fast alerts and minimal exposure. If your goal is attacker profiling, you may accept more interaction so you can study commands, tool use, and follow-on behavior. If your goal is detection engineering, you need enough fidelity to produce reliable signatures and alert logic without creating a false sense of realism. Cloud , on-premises , DMZ , and isolated lab deployments each serve a different purpose. Cloud deployment is convenient for scaling and remote monitoring, but you must pay close attention to security groups, metadata access, and egress control.
On-premises systems can be easier to isolate from the internet, especially when you want complete network ownership. A DMZ can be appropriate if you want the decoy to resemble an exposed service segment, but only if outbound paths are tightly constrained. An isolated lab is best when the primary goal is analysis and training rather than live collection. For structured role-based planning, the CISA and NIST Cybersecurity Framework references help align monitoring and control objectives.
Define success metrics before launch. Useful metrics include unique source IPs, session count, credentials attempted, payloads captured, file hashes collected, alert volume, and the number of new detections you created from the data. SANS Institute material on incident response and detection can help teams think about measurable outcomes rather than vanity metrics.
The right platform depends on what you want to observe, how much time you can spend maintaining it, and how much risk you can tolerate. A single-purpose tool is usually enough for targeted telemetry, while an integrated deception platform is better when you want centralized management, multiple lures, and broader visibility. Cowrie is a common choice for SSH and Telnet interaction capture. Dionaea is often used for malware collection and service emulation. Honeyd is useful when you want to simulate multiple hosts or services at the network layer. T-Pot packages several components into a unified stack. Thinkst Canary focuses on decoy tokens, services, and alerting.
For official product and project documentation, start with the source itself. Cowrie and Dionaea are maintained in public repositories, T-Pot has documented deployment guidance, and Thinkst Canary provides official product documentation and management information. The Cowrie documentation and Dionaea project are useful references when you need to compare feature depth and maintenance status.
When evaluating tools, look for session replay , command capture , file extraction, timestamp precision, and export formats that fit your SIEM. Also check whether the platform supports JSON logs, syslog forwarding, PCAP export, and integration with sandboxes or malware detonation environments. Support quality matters more than teams admit. A well-documented, actively maintained project will save you time when logs break, dependencies change, or a new attacker pattern requires configuration changes. If the community is stale or the release cadence has stopped, that is a real operational risk.
Safety starts with isolation. A honeypot should never have a straight path into production assets, privileged admin networks, or shared management subnets. Use network segmentation, dedicated security groups, and strict outbound filters so the decoy cannot be abused as a pivot point. Outbound control is just as important as inbound exposure. Block unnecessary egress by default, permit only what the platform truly needs for time sync, log shipping, and administration, and review those rules regularly. If a compromised honeypot can freely scan the internet, send spam, or download tools, your defensive project just became an incident.
Do not deploy a honeypot with unrestricted outbound access. A decoy that can reach the internet with no controls can be turned into an attack source, a malware relay, or a legal problem. Believability matters because obvious fakes get skipped. Use service banners that make sense for the asset you are simulating, keep fake data internally consistent, and match the hostname, IP range, and port profile to the surrounding environment. A Linux SSH decoy named like a Windows file server raises suspicion immediately.
Also monitor for abuse. If the honeypot starts sending unusual traffic, if the source of outbound connections changes, or if logs show repeated process launches that do not fit the expected lure, treat it as suspicious. The MITRE ATT&CK knowledge base is useful for recognizing the tactics and techniques that often follow initial compromise. The setup process should be repeatable, minimal, and observable from the first boot. Keep the base system lean, harden the management interface, and configure logging before you expose the service. If you are using Microsoft Learn or vendor documentation for the underlying OS and network controls, follow the official guidance rather than relying on assumptions.
A practical setup example is to use a dedicated Linux VM, install the honeypot package, bind management access only to a VPN subnet, and forward logs to a central collector. If you also need packet capture, a lightweight tcpdump -i eth0 -w /var/log/honeypot/capture.pcap workflow can help, but only when storage and retention are planned. Deployment is the point where configuration becomes operational reality, so document every port, firewall rule, fake credential, and maintenance dependency. That documentation becomes part of the control history and helps the team rebuild the system if it is replaced later.
You collect useful data by capturing enough context to explain the event, not just enough to say it happened. At minimum, preserve the source IP, destination port, timestamp, user agent or client string, commands entered, files uploaded, hashes, and any payloads written to disk. Enrichment turns raw activity into something analysts can use quickly. Add geolocation, ASN, reputation scores, passive DNS, and known malicious indicators so you can identify repeat actors, commodity scanning, or infrastructure overlaps. This is where Threat Intelligence becomes operational instead of theoretical.
Correlate the honeypot against other telemetry sources. Firewall logs show who touched the host, DNS logs show what the attacker tried to resolve, and SIEM detections show whether the same source touched other assets. If the honeypot data lines up with other alert streams, you can separate isolated noise from coordinated activity. Preserve raw artifacts safely. That means copying binaries, payloads, and suspicious archives into a controlled repository or analysis sandbox, not opening them on the honeypot itself. Use a sandbox or detonation environment for deeper review, and label the artifacts with the exact collection time and source of capture.
4. Practical Deployment, Analysis & Case Studies Repeated behavior matters. If the same IP tries multiple logins, then uploads a script, then attempts command execution, that is a sequence worth tracking. If dozens of sources send the exact same string or payload, automation is likely involved. The answer is to group related activity, identify intent, and convert findings into defensive action. A lone scan is noise, but a repeated pattern of scan, login attempt, file drop, and execution is a chain that tells you something about the attacker’s workflow.
Start by separating noise from meaningful activity. Set thresholds for repeated attempts, cluster by source, user agent, payload hash, or command sequence, and look for patterns that repeat across days or across different decoys. That makes it easier to distinguish random internet background radiation from a targeted campaign. One useful method is to map observed behavior to MITRE ATT&CK . For example, password guessing aligns with credential access behavior, uploads may indicate initial execution or persistence attempts, and repeated probing of adjacent systems may point to discovery or lateral movement. The mapping makes reporting easier for managers and easier to compare across incidents.
Automation leaves traces. Scripts often reuse payload structure, timing intervals, and error handling patterns. Human operators usually pause, try alternate paths, or adjust commands when the first approach fails. If your honeypot captures session replay or command history, those differences can be very revealing. “The value of honeypot analysis is not the single event; it is the repeatable pattern that helps you improve detection, hardening, and response.” Translate findings into action. Add signatures or detections for common user agents, commands, filenames, or source networks. Update firewall rules if a source repeatedly targets exposed services. Use the data in awareness training so administrators understand what real attack attempts look like.
The NIST guidance on detecting and responding to incidents supports that workflow by emphasizing evidence-driven response. In a practical cybersecurity tools stack, the honeypot becomes a sensor that feeds the rest of the program. A good honeypot is maintained like a security control, not like a demo system. Rotate credentials, change decoy content, refresh fake files, and update banners so the environment does not become stale. Attackers notice old artifacts, broken links, and unchanged responses.
Reliability is part of the mission. Watch storage growth, log ingestion errors, CPU and memory usage, and alert fatigue. If your analyst ignores honeypot alerts because they are noisy or poorly tuned, the system is failing even if it is technically online. Have an incident response playbook ready for high-risk events. If the honeypot appears to be compromised, if it starts generating outbound traffic, or if it behaves in a way that conflicts with its expected role, isolate it immediately and preserve the evidence. CISA and NIST both provide useful public guidance for incident handling and control discipline.
Document the limits of the system. Stakeholders should know that a honeypot is a sensor, not a complete defensive solution. It can show attack intent, but it cannot tell you everything about an adversary, and it should never be sold as a substitute for patching, segmentation, or endpoint protection. Privacy, retention, and compliance matter too. If your logs can identify people, accounts, or internal assets, define retention rules and access controls up front. That keeps the program aligned with policy and reduces surprise during audit or legal review.
Many honeypot projects fail for the same predictable reasons. The first mistake is making the decoy so fake that nobody interacts with it. The second is exposing too much functionality and creating unnecessary risk. The third is launching it without any plan for review or response. Another common failure is forgetting that a honeypot needs the same operational care as any other security control. If it is not patched, monitored, and reviewed, it can become a weak point rather than a source of insight. That is especially true when the decoy sits on a public address and starts attracting more attention than expected.
The safest path is to start small. Deploy one lure, validate your controls, and prove that the logs, alerts, and artifacts are useful before expanding to additional services. That is also a good fit for hands-on skills taught in the Certified Ethical Hacker v13 course, where controlled observation and safe testing matter as much as the tools themselves. Honeypot findings become valuable when they change decisions. Feed curated observations into detection engineering, SIEM tuning, firewall policy, and vulnerability prioritization so the intelligence has an operational effect. A decoy that only produces reports is underused.
Share relevant indicators with internal teams first. SOC analysts need the commands, IPs, file hashes, and timestamps. Network teams need source ranges and repeated destination ports. System administrators need the service and credential patterns that attackers are testing. When appropriate, share cleaned indicators with external intelligence communities or trusted partners.
Trend analysis is where the long-term value appears. Over time, you may see changes in the services attackers target, the payloads they reuse, or the hosting providers they prefer. Those patterns can help you spot emerging campaigns earlier and adjust your exposure strategy accordingly. Compare honeypot data with vulnerability management and patching priorities. If attackers repeatedly target a specific service on the decoy, and that same service exists in your environment, it deserves more attention. That comparison turns abstract threat information into practical hardening work.
Build dashboards and recurring reports that summarize top sources, most common commands, repeated hashes, and changes in interaction volume. The reporting should answer one question clearly: what did we learn, and what changed because of it? For workforce alignment and security program maturity, the NICE Workforce Framework is a useful reference for mapping these tasks to analyst and defender roles. Good cyber threat intelligence is repeatable, explainable, and tied to action.
Learn essential ethical hacking skills to identify vulnerabilities, strengthen security measures, and protect organizations from cyber threats effectively A well-run honeypot gives you something most security controls cannot: direct visibility into how attackers behave when they think they found a real target. That makes it one of the most practical ways to improve cyber threat intelligence, attack monitoring, and cyber defense without touching production systems.
The formula is straightforward. Define the goal, deploy safely, monitor continuously, enrich what you collect, and turn the results into action. If you skip the safety controls or fail to analyze the data, the project loses most of its value. Start with a narrow scope, validate the results, and expand only when the process is stable. For teams building skills through ITU Online IT Training and the Certified Ethical Hacker v13 course, honeypots are a strong way to practice ethical observation, defensive thinking, and evidence-driven analysis.
CompTIA®, Cisco®, Microsoft®, AWS®, EC-Council®, ISC2®, ISACA®, and PMI® are trademarks of their respective owners. CEH™, CISSP®, Security+™, A+™, CCNA™, and PMP® are trademarks of their respective owners. A honeypot is a deliberately vulnerable computer system or network resource designed to attract cyber attackers. Its primary purpose is to act as a decoy, enticing malicious actors to engage with it instead of real, valuable assets.
By monitoring interactions with the honeypot, cybersecurity professionals can gain insights into attacker behaviors, techniques, and tools. This information helps organizations understand current threats and develop more effective defenses against real attacks. Setting up a honeypot involves deploying a system that mimics legitimate network services, applications, or systems, making it attractive to attackers. Start by identifying the assets you want to emulate, then install and configure software that replicates those services.
Ensure the honeypot is isolated from your production environment to prevent any potential compromise from affecting your operational systems. Use network segmentation, firewalls, and monitoring tools to control and observe interactions with the honeypot. Continuous and real-time monitoring is essential for extracting valuable intelligence from a honeypot. Use intrusion detection systems, logging tools, and network analyzers to track attacker activity, commands, and techniques.
Establish alerting mechanisms for suspicious activity, and review logs regularly to identify new attack vectors or vulnerabilities. Automate data collection when possible to ensure rapid response and analysis. While honeypots are valuable for gathering threat intelligence, improper setup or management can pose risks. If not isolated properly, an attacker might use the honeypot as a stepping stone to compromise other parts of your network.
To mitigate these risks, always ensure the honeypot is sandboxed from critical infrastructure, and restrict outbound communications. Regularly update and patch the honeypot system to prevent it from becoming a liability. Analyzing honeypot data reveals attacker methodologies, tools, and targets, providing a real-world view of current cyber threats. You can identify common attack patterns, malware types, and exploitation techniques.
This intelligence helps in strengthening defenses, developing targeted mitigation strategies, and understanding evolving threat landscapes. Additionally, it can assist in creating predictive models for future attacks and enhancing incident response plans. A Honeypot is a decoy system or network resource designed to attract, detect, and study cyberattacks by mimicking a legitimate and valuable target.It serves as a trap for attackers, luring them into a controlled environment where security professionals can observe and gather intel.
5. Performance Evaluation & Extended Technical Observations Deploy a production-style T-Pot honeypot instance, validate it’s collecting telemetry, and demonstrate basic analyst workflows: access the Kibana web UI, filter events (by IP/port/service), extract IOCs (IPs, usernames, passwords). Minimum footprint: 8 GB RAM, 4 vCPU, 80 GB disk (use larger if you plan extended capture).
Public IPv4 address (for honeypot visibility). Optional: DNS name that looks legitimate. Root or sudo admin account on the VM. Ability to open/forward TCP ports and reboot the instance. Isolated environment policy: do not run on a host that can access your production network. Use host-only or strictly firewalled environment if local.
Host firewall rules and ability to open the T-Pot web ports (default installer changes SSH port and exposes Kibana/ELK UI). Docker & Docker Compose (T-Pot installer will handle most requirements but ensure the host supports Docker). Time to complete: ~30–90 minutes for installation on a sufficiently provisioned VM; longer if networking/tuning required. Budget note: cloud hourly/monthly costs apply; install may require a reboot and short downtime.
Understand legal/ethical constraints: honeypots attract malicious traffic — do not use them to proxy traffic to other networks, do not host third-party content, and ensure you have the right to expose the VM on the public Internet. You can either make either make this on your virtual machine, or cloud. For cloud choose any platform( DigitalOcean, Vultr , etc) and make an account. You will usually get free credits for some months or so. Use them to complete this project.
For now , I will use a cloud platform called DigitalOcean. Use this link to get a free $200 credit , should be more than enough for this project. https://www.digitalocean.com/?refcode=e2ce5a05f701&utm_campaign=Referral_Invite&utm_medium=Referral_Program&ut m_source=CopyPaste Note : If you opted for the cloud option, don't forget set the hostname name as legit as possible. Eg: WBC-Web-Server2 .
It is important to configure a firewall so that only you and your associated IPs can connect to this machine but since this a Honeypot , you want it to be able to be accessible from anywhere. To access the VM, you can already see the public IPv4 address in the above screenshot. Copy it and open powershell and login via SSH: Once this is done, you must also create a new user. Only one user exist at the moment which is the Root user and it is not best practice to run commands or use the vm with root account.
Also add bill to the sudo group. A sudo group is **a group of superusers that have privileged access to root commands** Change directories to tpotce and run the install script and follow the onscreen instructions: Keep in mind that this installation will change your ssh port to 64295 , shown in the output. That means to log back in with ssh , you mush specify this port This process might take some time , and might also fail if you chose a VM with low ram during the installation. If that happens, select M for mini T-pot installation.
After re-logging in , you can view the status of the tpot service running by running this command : It will throw us on a landing page where you can view the attack map. There are other options as well. Select the "kibana" option from the landing page and you will be presented with a dashboard in Elastic SIEM. You can filter it by IPs , ports , services attacked, passwords used to brute force, users attacked, etc.
There are hundreds of attacks and scans already happening and If you check back the map after a hour or so , you will see a lot more action. A honeypot is a security mechanism set up to detect, deflect, or study cyber attacks by mimicking vulnerable systems. The goal is to trick attackers into interacting with the honeypot, allowing you to monitor their activities without risking critical systems.
In this guide, we'll walk through the steps to set up a basic honeypot for cybersecurity research and defense. Low-interaction honeypots simulate specific services that attackers might interact with (e.g., SSH, HTTP). They are easy to set up but provide limited insight into an attacker's methods. High-interaction honeypots simulate full systems and allow attackers to perform a wide range of activities. These honeypots offer more detailed information but are more complex and risky. For beginners, a low-interaction honeypot is usually the best option to start with.
There are various honeypot software tools available that help you set up your trap. Some popular options include: Dionaea – A low-interaction honeypot aimed at catching malware. Cowrie – An SSH and Telnet honeypot that records all actions of an attacker. Honeyd – A versatile honeypot that can simulate various network services. For this tutorial, we'll use Cowrie, a simple SSH honeypot, to track and log potential attacks.
You'll need a dedicated environment for your honeypot to ensure that your real systems remain safe. Create a virtual machine (VM): Use software like VirtualBox or VMware to create an isolated VM. Honeypots are prone to attacks, so isolating them from your real system is crucial. Choose a lightweight Linux distribution for your VM, such as Ubuntu or Debian.
Step 5: Start Your Honeypot Once configured, you can start Cowrie using the following command: Cowrie logs everything the attacker does once they log into the honeypot. You can view the logs in the log/ directory within the Cowrie folder. Step 7: Stay Safe When setting up a honeypot, always remember the following safety tips: Isolate the honeypot: Use a separate VM or network segment to prevent attackers from breaching your real systems. Regular monitoring: Always monitor the logs to ensure the honeypot isn't being used to attack other systems. Updates: Keep your honeypot software updated to protect against vulnerabilities.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Client%20honeypot • https://rehacktory.com/2024/12/26/step-by-step-guide-to-setting-up-a-honeypot-for-threat-analysis/ • https://www.ituonline.com/how-to/how-to-set-up-honeypots-to-attract-and-analyze-cyber-attacks/ • https://www.ituonline.com/blogs/honeypots-for-cyber-threat-intelligence-how-to-set-up-monitor-and-learn-from-attackers/ • https://chaoneil.github.io/posts/honeypot-project/ • https://dev.to/trixsec/how-to-set-up-a-honeypot-for-cyber-attacks-4c08
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Honeypot For Web Application Attack Monitoring.
[*] Initializing Burp Suite Spider & Vulnerability Engine for Honeypot For Web Application Attack Monitoring... [✓] Burp Extender / Macro Automation Hook Synced ──────────────────────────────────────────────────────────────────────── [11:42:01.104] AUDIT Crawled dynamic endpoints | Injecting input vectors [11:42:01.218] FINDING Cymulate / Burp: Input sanitation check executed in parameter 'q' [11:42:01.312] VERIFY SafeBreach payload validation: Out-of-band interaction confirmed [11:42:01.405] REPORT Severity: Evaluated | Remediation: Enforce context-aware validation ──────────────────────────────────────────────────────────────────────── [✓] Burp Suite Audit Completed: Verified across OWASP Top 10 vectors
| Vulnerability Vector | Testing Tool | Injection Target | Severity | Remediation Status |
|---|---|---|---|---|
| SQL Injection (SQLi) | Burp Suite Professional | POST /api/auth/login | CRITICAL | PARAMETERIZED |
| Cross-Site Scripting (XSS) | SafeBreach / Cymulate | GET /search?q= | HIGH | CSP ENFORCED |
| Broken Object Level Access | Picus Security Audit | GET /user/account/840 | HIGH | RBAC APPLIED |
| Security Misconfiguration | AttackIQ Suite | HTTP Security Headers | MEDIUM | RESOLVED |