Complete Technical Paper Content — Identity Based Encryption Implementation In Python
Overview & System Context
Identity Based Encryption Implementation In Python: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~6841 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Private biometrics is a form of encrypted biometrics, also called privacy-preserving biometric authentication methods, in which the biometric measurement is cryptographically processed such that no data stored in a data base can be (mis-) used to recover information about the human subject. Biometrics, in contrast to user pass words, are noisy data that slightly differ from measurement to measurement. Small variations input data prevent the use of traditional encryption or hashing. The introduction of a fuzzy extractor was a pioneering contribution to nonetheless apply cryptographic techniques to inherently noisy biometric data.
The Private.id feature vector can be used in one of two ways. If the feature vector is stored locally, it may be used to compute 1:1 verification with high accuracy (99% or greater) using linear mathematics. If the feature vector is also stored in a Cloud, the feature vector may also be used as input for a neural network to perform 1:many identification with the same accuracy, speed and privacy as the original plaintext reference biometric (template).
Non-bypassable, as plaintext biometrics cannot use another communication path, including lower level mechanisms, to bypass the security monitor since the original biometric is transient at inception (e.g. the biometric template acquired by the client device exists only for a few seconds at inception and then is deleted or never stored). Evaluable in that the feature vectors are modular, well designed, well specified, well implemented, small and of low complexity. Always-invoked, in that each and every message is always one-way encrypted independent of security monitors. Tamperproof in that the feature vector's one-way encryption prevents unauthorized changes and does not use systems that control rights to the security monitor code, configuration and data.
BioHashing Research into cancelable biometrics moved into BioHashing by 2004. The BioHashing feature transformation technique was first published by Jin, Ling and Goh and combined biometric features and a tokenized (pseudo-) random number (TRN). Specifically, BioHash combined the biometric template with a user-specific TRN to produce a set of non-invertible binary bit strings that were thought to be irreproducible if both the biometric and the TRN were not presented simultaneously. Indeed, it was first claimed that the BioHashing technique had achieved perfect accuracy (equal error rates) for faces, fingerprints and palm prints, and the method gained further traction when its extremely low error rates were combined with the claim that its biometric data was secure against loss because factoring the inner products of biometrics feature and TRN was an intractable problem. By 2005, however, researchers Cheung and Kong (Hong Kong Polytechnic and University of Waterloo) asserted in two journal articles that BioHashing performance was actually based on the sole use of TRN and conjectured that the introduction of any form of biometric become meaningless since the system could be used only with the tokens. These researchers also reported that the non-invertibility of the random hash would deteriorate the biometric recognition accuracy when the genuine token was stolen and used by an impostor (“the stolen-token scenario”).
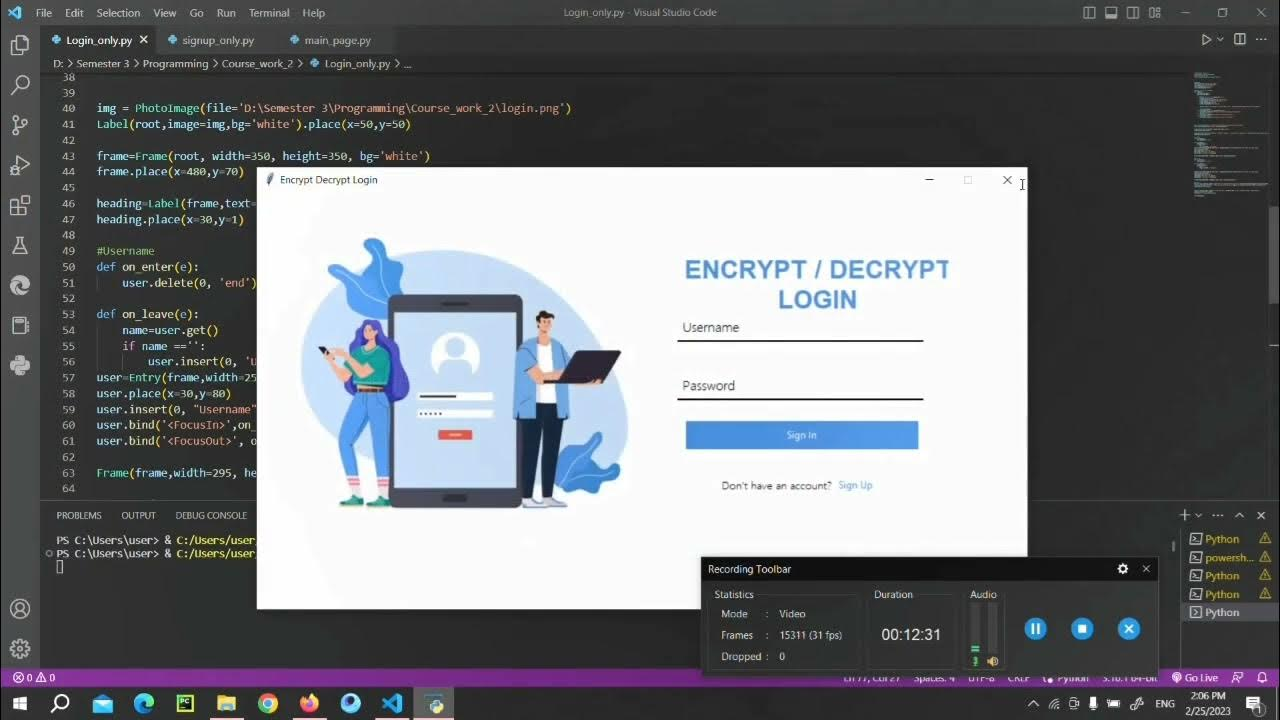
Figure 1: Login system || secret message encryption decryption || python based ... The Secure Remote Password protocol (SRP) is an augmented password-authenticated key exchange (PAKE) protocol, specifically designed to work around existing patents. Like all PAKE protocols, an eavesdropper or man in the middle cannot obtain enough information to be able to brute-force guess a password or apply a dictionary attack without further interactions with the parties for each guess. Furthermore, being an augmented PAKE protocol, the server does not store password-equivalent data. This means that an attacker who steals the server data cannot masquerade as the client unless they first perform a brute force search for the password. In layman's terms, during SRP (or any other PAKE protocol) authentication, one party (the "client" or "user") demonstrates to another party (the "server") that they know the password, without sending the password itself nor any other information from which the password can be derived. The password never leaves the client and is unknown to the server. Furthermore, the server also needs to know about the password (but not the password itself) in order to instigate the secure connection. This means that the server also authenticates itself to the client which prevents phishing without reliance on the user parsing complex URLs. The only mathematically proven security property of SRP is that it is equivalent to Diffie-Hellman against a passive attacker. While mature and widely deployed, SRP is an older design with some variants showing subtle weaknesses; it is not UCIsecure, lacks resistance to all precomputation attacks, has weaker formal proofs, and offers no protection against certain modern attack models. For these reasons, SRP is now largely considered superseded. OPAQUE is the preferred augmented PAKE, while CPace or SPAKE2 are favored for balanced PAKE scenarios where both parties share the password.
q and N = 2q + 1 are chosen such that both are prime (which makes q a Sophie Germain prime and N a safe prime). N must be large enough so that computing discrete logarithms modulo N is infeasible. All arithmetic is performed in the ring of integers modulo N, Z N {\displaystyle \scriptstyle \mathbb {Z} _{N}} . This means that below gx should be read as gxmod N g is a generator of the multiplicative group Z N ∗ {\displaystyle \scriptstyle \mathbb {Z} _{N}^{*}} . H() is a hash function; e.g., SHA-256. k is a parameter derived by both sides; in SRP-6, k = 3, while in SRP-6a it is derived from N and g : k = H(N, g). It is used to prevent a 2-for-1 guess when an active attacker impersonates the server. s is a salt. I is an identifying username. p is the user's password. v is the host's password verifier, v = gx where at a minimum x = H(s, p). As x is only computed on the client it is free to choose a stronger algorithm. An implementation could choose to use x = H(s | I | p) without affecting any steps required of the host. The standard RFC2945 defines x = H(s | H ( I | ":" | p) ). Use of I within x avoids a malicious server from being able to learn if two users share the same password. A and B are random one time ephemeral keys of the user and host respectively. | (pipe) denotes concatenation. All other variables are defined in terms of these. First, to establish a password p with server Steve, client Carol picks a random salt s, and computes x = H(s, p), v = gx. Steve stores v and s, indexed by I, as Carol's password verifier and salt. Carol must not share x with anybody, and must safely erase it at this step, because it is equivalent to the plaintext password p. This step is completed before the system is used as part of the user registration with Steve. Note that the salt s is shared and exchanged to negotiate a session key later so the value could be chosen by either side but is done by Carol so that she can register I, s and v in a single registration request. The transmission and authentication of the registration request is not covered in SRP. Then to perform a proof of password at a later date the following exchange protocol occurs: Carol → Steve: generate random value a; send I and A = ga Steve → Carol: generate random value b; send s and B = kv + gb Both: u = H(A, B) Carol: SCarol = (B − kgx)(a + ux) = (kv + gb − kgx)(a + ux) = (kgx − kgx + gb)(a + ux) = (gb)(a + ux) Carol: KCarol = H(SCarol) Steve: SSteve = (Avu)b = (gavu)b = [ga(gx)u]b = (ga + ux)b = (gb)(a + ux) Steve: KSteve = H(SSteve) = KCarol Now the two parties have a shared, strong session key K. To complete authentication, they need to prove to each other that their keys match. One possible way is as follows: Carol → Steve: M1 = H[H(N) XOR H(g) | H(I) | s | A | B | KCarol]. Steve verifies M1. Steve → Carol: M2 = H(A | M1 | KSteve).
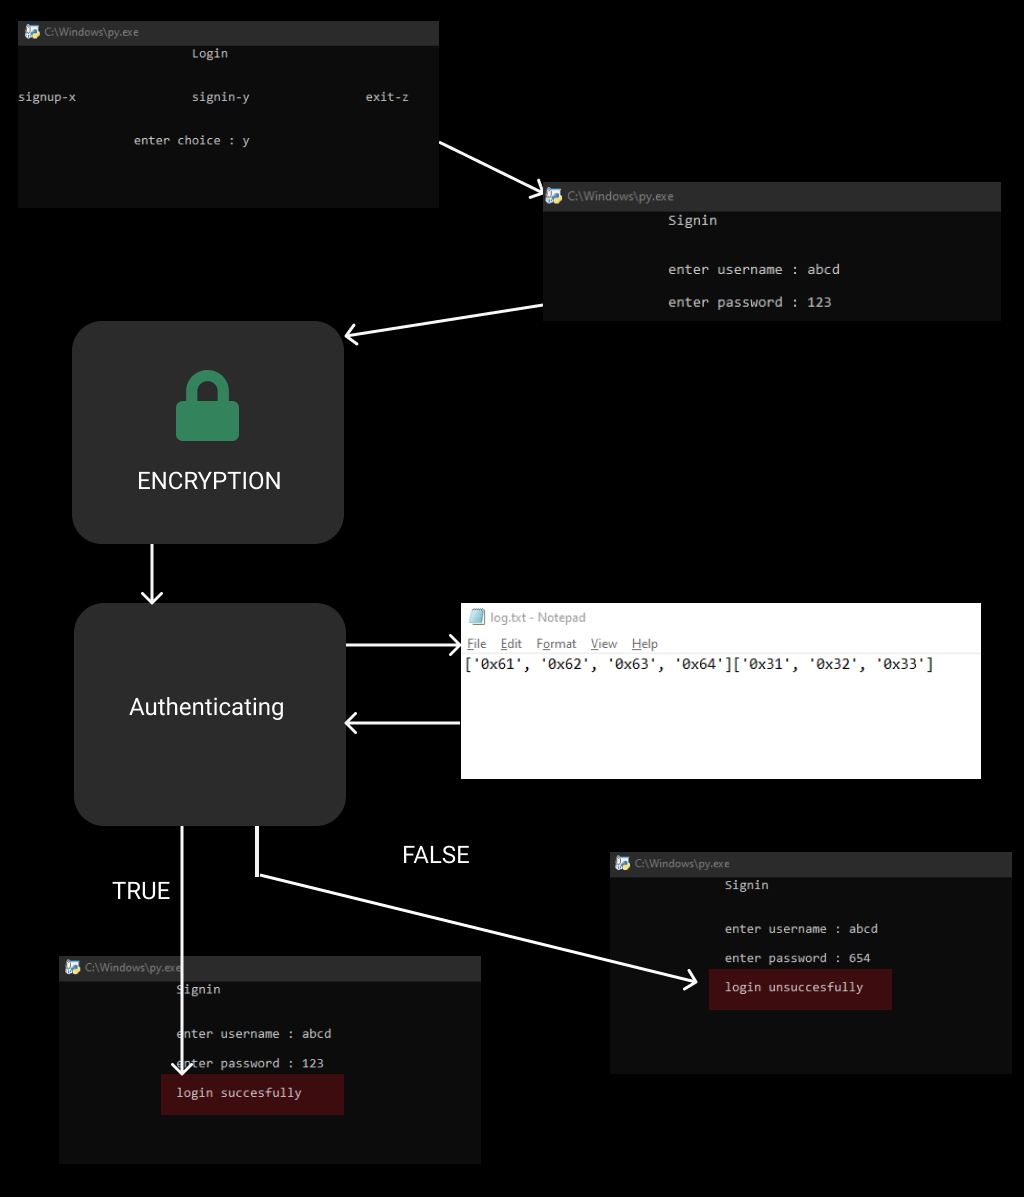
Carol verifies M2. This method requires guessing more of the shared state to be successful in impersonation than just the key. While most of the additional state is public, private information could safely be added to the inputs to the hash function, like the server private key. Alternatively, in a password-only proof the calculation of K can be skipped and the shared S proven with: Figure 2: GitHub - krishnanand654/Authentication-with-encryption-program: Python ...
Carol → Steve: M1 = H(A | B | SCarol). Steve verifies M1. Steve → Carol: M2 = H(A | M1 | SSteve). Carol verifies M2. When using SRP to negotiate a shared key K which will be immediately used after the negotiation, it is tempting to skip the verification steps of M1 and M2. The server will reject the very first request from the client which it cannot decrypt. This can however be dangerous as demonstrated in the Implementation Pitfalls section below. The two parties also employ the following safeguards: Carol will abort if she receives B = 0 (mod N) or u = 0. Steve will abort if he receives A (mod N) = 0. Carol must show her proof of K (or S) first. If Steve detects that Carol's proof is incorrect, he must abort without showing his own proof of K (or S) Carol → Steve: generate random value a; send I and A = ga Steve: u = H(A, B); S=Avu; K=H(S) Steve: generate message m and encrypts it to produce c=ENC(K,m) Steve → Carol: generate random value b; send s, B = kv + gb and c Carol doesn't know x or v. But given any password p she can compute: xp = H(salt, p) Sp = (B - kgxp)(a + uxp) Kp = H(Sp) Kp is the key that Steve would use if p was the expected password. All values required to compute Kp are either controlled by Carol or known from the first packet from Steve. Carol can now try to guess the password, generate the corresponding key, and attempt to decrypt Steve's encrypted message c to verify the key.
As protocol messages tend to be structured, it is assumed that identifying that c was properly decrypted is easy. This allows offline recovery of the password. This attack would not be possible had Steve waited for Carol to prove she was able to compute the correct key before sending an encrypted message. Proper implementations of SRP are not affected by this attack as the attacker would be unable to pass the key verification step.
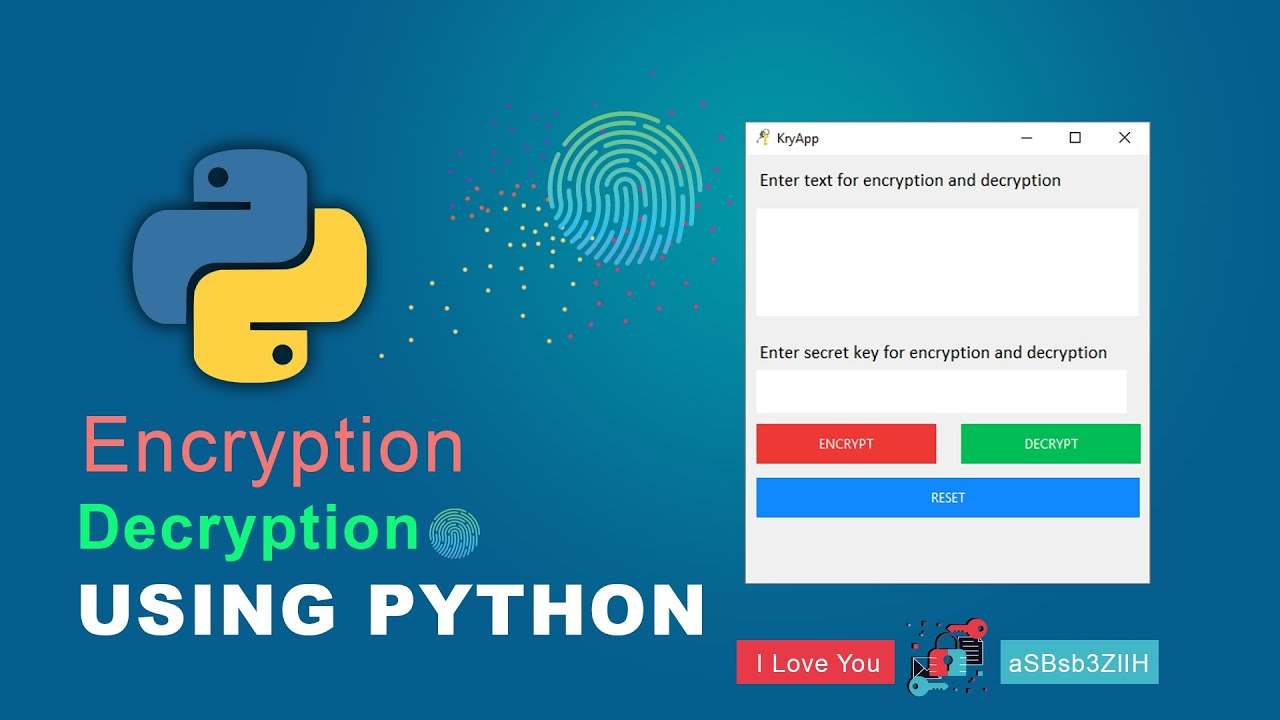
Figure 3: Create Secret Message Encryption and Decryption tool using Python | Gui ... ISO/IEC 11770-4:2006 "Key Agreement Mechanism 2" (calls the method "SRP-6, but has the k calculation of 6a) RFC 5054 TLS-SRP of 2007 (again referred to as "SRP-6", but corrected in erratum) IEEE Std 1363.2-2008 "DLAPKAS-SRP6" (again referred to as "SRP-6") IEEE 1363.2 also includes a description of "SRP5", a variant replacing the discrete logarithm with an elliptic curve contributed by Yongge Wang in 2001. It also describes SRP-3 as found in RFC 2945.
JSON Web Token (JWT, suggested pronunciation , same as the word "jot") is a proposed Internet standard for creating data with optional signature and/or optional encryption whose payload holds JSON that asserts some number of claims. The tokens are signed either using a private secret or a public/private key. For example, a server could generate a token that has the claim "logged in as administrator" and provide that to a client. The client could then use that token to prove that it is logged in as admin. The tokens can be signed by one party's private key (usually the server's) so that any party can subsequently verify whether the token is legitimate. If the other party, by some suitable and trustworthy means, is in possession of the corresponding public key, they too are able to verify the token's legitimacy. The tokens are designed to be compact, URL-safe, and usable, especially in a web-browser single-sign-on (SSO) context. JWT claims can typically be used to pass identity of authenticated users between an identity provider and a service provider, or any other type of claims as required by business processes. JWT relies on other JSON-based standards: JSON Web Signature and JSON Web Encryption.
Payload Contains a set of claims. The JWT specification defines seven Registered Claim Names, which are the standard fields commonly included in tokens. Custom claims are usually also included, depending on the purpose of the token. This example has the standard Issued At Time claim (iat) and a custom claim (loggedInAs). Signature Securely validates the token. The signature is calculated by encoding the header and payload using Base64url Encoding RFC 4648 and concatenating the two together with a period separator. That string is then run through the cryptographic algorithm specified in the header. This example uses HMAC-SHA256 with a shared secret (public key algorithms are also defined). The Base64url Encoding is similar to base64, but uses different non-alphanumeric characters and omits padding.
The three are encoded separately using Base64url Encoding RFC 4648, and concatenated using periods to produce the JWT: (The above json strings are formatted without newlines or spaces, into utf-8 byte arrays. This is important as even slight changes in the data will affect the resulting token) This resulting token can be easily passed into HTML and HTTP. In authentication, when a user successfully logs in, a JSON Web Token (JWT) is often returned. This token should be sent to the client using a secure mechanism like an HTTP-only cookie. Storing the JWT locally in browser storage mechanisms like local or session storage is discouraged. This is because JavaScript running on the client-side (including browser extensions) can access these storage mechanisms, exposing the JWT and compromising security. To make use of the HTTP-only cookie, as you might need it to authenticate with cross-origin APIs, the best approach is to use the credentials property to tell the browser to automatically send the cookies to the external APIs via a fetch call like so: By using this method, the JWT is never exposed to client-side JavaScript; this is the best approach to make use of your JWT while maintaining security best practices. For unattended processes, the client may also authenticate directly by generating and signing its own JWT with a pre-shared secret and passing it to an OAuth compliant service like so:If the client passes a valid JWT assertion the server will generate an access_token valid for making calls to the application and pass it back to the client: When the client wants to access a protected route or resource, the user agent should send the JWT, typically in the Authorization HTTP header using the Bearer schema. The content of the header might look like the following: This is a stateless authentication mechanism as the user state is never saved in server memory. The server's protected routes will check for a valid JWT in the Authorization header, and if it is present, the user will be allowed to access protected resources. As JWTs are self-contained, all the necessary information is there, reducing the need to query the database multiple times.
List of currently registered claim names can be obtained from IANA JSON Web Token Claims Registry. Never let the JWT header alone drive verification Know the algorithms (avoid depending on the alg field alone) Use an appropriate key size Several JWT libraries were found to be vulnerable to an invalid Elliptic-curve attack in 2017. Some have argued that JSON web tokens are difficult to use securely due to the many different encryption algorithms and options available in the standard, and that alternate standards should be used instead for both web frontends and backends.
RFC 7519 jwt.io – specialized website about JWT with tools and documentation, maintained by Auth0 2. System Architecture & Core Working Principles Identity-Based Encryption (IBE) is a type of public key cryptography that allows a person to use a memorable and easy-to-remember identifier, such as an email address or a phone number, as their public key. This eliminates the need for a separate public key infrastructure (PKI) to manage and distribute public keys.
In IBE, a trusted third party called the Private Key Generator (PKG) generates private keys corresponding to an identity. The user simply provides their identity to the PKG, which then generates their private key. Anyone wishing to send encrypted data to the reciever can do so by encrypting using the easy to remember public key and only the user that has the private key corresponding to the identity can decrypt the information.
One of the main advantages of IBE is its simplicity and ease of use. Since the public key is derived from a user's identity, there is no need for users to manage a separate key pair or exchange public keys with other users. This also makes IBE a suitable choice for applications where the users are not technically proficient. In conclusion, IBE is a useful alternative to traditional public key cryptography that eliminates the need for a separate PKI.
While it has its limitations, it offers simplicity and ease of use for applications where users are not technically proficient or where a PKI is not practical. For more information, visit the link for the research paper titled "An Identity based encryption Scheme based on Quadratic Residue" here .
We are using Clifford Cocks IBE scheme as the core protocol. The complete scheme includes 4 phases which are as follow: An RSA modulus n = pq , where p and q are primes and kept secret and follow the below condition. A deterministic Public hash function is chosen, in our case we are using hashlib’s SHA-256 hashing. In the extract phase the users can retrive their private keys corresponding to the identity string provided.
PKG derives a value a such that (a/m) (Jacobi Symbol of a wrt m) is 1 using iterative and deterministic use of hash function until the condition is met. If the user wants to decrypt the ciphertext s for the user’s root, it can be done as follows: We are using Identity based encryption for key exchange only and using symmetric key encryption for the rest of connection as the using Identity based Encryption alone will use a lot of computation power.
This includes self-signed CA certitificates for Transport level security while communicating between user and authority which is sending the private keys. II NOTE : TLS is not a part of the Identity Based Encryption, it is included to make sure that the key transfer between the authority server and the user is safe and secure.
For the demo to start we will first run the authorityServer.py file which will do the following: The Socket uses SSL and hence the communication between the authority and user is safe from intervention by a third party. Connect to the auth server at port 3002 and verify the CA certificates of the authority against the certificates folder. Recieves the Master Public Key of the PKG and sends its own identity string to the authority for getting its secret key.
The Authority then generates the secret key and sends it back to the user. Then the reciever(bob) opens its own socket (PORT 3003) for listening for senders to send him data. This socket does not has TLS and we are going to use our own encryption for security. For the next step we are going to run the sender code (alice.py) which will work as follows: First alice will also connect to auth server only to retrieve the Master Public Key and close the connection after that.
Alice will then ask for the reciever identity using input() and connect to Bob (which is open for connections at PORT 3003 ) and select a random connection key. The connection key will then be sent to bob using identity based encryption. Once the key is sent and decrypted by bob the chat mode will turn on.
Once the keys are exchanged we can use fernet library to encrypt and decrypt messages sent between alice and bob. The connection key can be converted to a fernet key using the bits to bytes conversion. Alice and bob can send and recieve messages by taking turns. 3. Software Implementation, Frameworks & Protocols To verify that the encryption is working and no third party can access the data we will use Wireshark to look at the communication between auth, bob and alice.
This is the encrypted message corresponding to the communcation shown in the terminal below. This repository showcases implementations of three essential cryptographic schemes using the Python Charm-Crypto framework: These implementations are designed for secure data handling in environments where confidentiality, identity binding, and fine-grained access control are required (e.g., eHealth systems).
To install Charm-Crypto on Ubuntu 20.04 LTS, follow the instructions in install-charm.md . Each file includes example functions demonstrating how to use the implemented class. You can import the classes or run the files directly. A Python-based cryptography project implementing AES, Identity-Based Encryption (IBE), and Attribute-Based Encryption (ABE) using the Charm-Crypto library.
Sending encrypted information normally requires obtaining and authenticating the recipient’s public key. In a large organization, maintaining that directory of keys and certificates can itself become a difficult administrative problem. Identity-based encryption offers a different approach: a familiar identifier, such as an email address or organizational label, serves as the public key, while a trusted authority issues the corresponding secret key.
Hierarchical identity-based encryption extends this idea to organizations with several levels of authority. A root authority can delegate key-generation capabilities to departments, which can in turn delegate to teams or individuals. The resulting identity tree mirrors real administrative structure and avoids routing every key request through a single central authority. The cryptographic challenge is to prove security when an adversary adaptively chooses identities, requests secret keys for related nodes, and decides on its challenge only after observing the system. Reductions must preserve delegation while embedding a hardness challenge without answering a prohibited key query. This project studies adaptive security, delegation, and simulation-friendly notions such as non-committing encryption, with the goal of obtaining expressive identity-based systems from standard assumptions.
Identity-based encryption ( IBE ), is an important primitive of identity-based cryptography . As such it is a type of public-key encryption in which the public key of a user is some unique information about the identity of the user (e.g. a user's email address). This means that a sender who has access to the public parameters of the system can encrypt a message using e.g. the text-value of the receiver's name or email address as a key. The receiver obtains its decryption key from a central authority, which needs to be trusted as it generates secret keys for every user.
Identity-based encryption was proposed by Adi Shamir in 1984. [ 1 ] He was however only able to give an instantiation of identity-based signatures . Identity-based encryption remained an open problem for many years. The pairing -based Boneh–Franklin scheme [ 2 ] and Cocks's encryption scheme [ 3 ] based on quadratic residues both solved the IBE problem in 2001.
Identity-based systems allow any party to generate a public key from a known identity value such as an ASCII string. A trusted third party, called the Private Key Generator (PKG), generates the corresponding private keys. To operate, the PKG first publishes a master public key, and retains the corresponding master private key (referred to as master key ). Given the master public key, any party can compute a public key corresponding to the identity by combining the master public key with the identity value. To obtain a corresponding private key, the party authorized to use the identity ID contacts the PKG, which uses the master private key to generate the private key for identity ID .
As a result, parties may encrypt messages (or verify signatures) with no prior distribution of keys between individual participants. This is extremely useful in cases where pre-distribution of authenticated keys is inconvenient or infeasible due to technical restraints. However, to decrypt or sign messages, the authorized user must obtain the appropriate private key from the PKG. A caveat of this approach is that the PKG must be highly trusted, as it is capable of generating any user's private key and may therefore decrypt (or sign) messages without authorization. Because any user's private key can be generated through the use of the third party's secret, this system has inherent key escrow . A number of variant systems have been proposed which remove the escrow including certificate-based encryption , [ 4 ] secure key issuing cryptography [ 5 ] and certificateless cryptography . [ 6 ] Dan Boneh and Matthew K. Franklin defined a set of four algorithms that form a complete IBE system: The most efficient identity-based encryption schemes are currently based on bilinear pairings on elliptic curves , such as the Weil or Tate pairings. The first of these schemes was developed by Dan Boneh and Matthew K. Franklin (2001), and performs probabilistic encryption of arbitrary ciphertexts using an Elgamal -like approach. Though the Boneh-Franklin scheme is provably secure , the security proof rests on relatively new assumptions about the hardness of problems in certain elliptic curve groups.
Another approach to identity-based encryption was proposed by Clifford Cocks in 2001. The Cocks IBE scheme is based on well-studied assumptions (the quadratic residuosity assumption ) but encrypts messages one bit at a time with a high degree of ciphertext expansion . Thus it is highly inefficient and impractical for sending all but the shortest messages, such as a session key for use with a symmetric cipher .
One of the major advantages of any identity-based encryption scheme is that if there are only a finite number of users, after all users have been issued with keys the third party's secret can be destroyed. This can take place because this system assumes that, once issued, keys are always valid (as this basic system lacks a method of key revocation ). The majority of derivatives of this system which have key revocation lose this advantage.
Moreover, as public keys are derived from identifiers, IBE eliminates the need for a public key distribution infrastructure. The authenticity of the public keys is guaranteed implicitly as long as the transport of the private keys to the corresponding user is kept secure ( authenticity , integrity , confidentiality ). Apart from these aspects, IBE offers interesting features emanating from the possibility to encode additional information into the identifier. For instance, a sender might specify an expiration date for a message. He appends this timestamp to the actual recipient's identity (possibly using some binary format like X.509 ). When the receiver contacts the PKG to retrieve the private key for this public key, the PKG can evaluate the identifier and decline the extraction if the expiration date has passed.
Generally, embedding data in the ID corresponds to opening an additional channel between sender and PKG with authenticity guaranteed through the dependency of the private key on the identifier. Libraries and examples for integrating verifiable encrypted threshold keys (vetKeys) into Internet Computer applications Consensus-level Front-running protection mechanism using Threshold Identity-Based Encryption Rust IIIIIIIIIISM2/SM3/SM4/SM9ITLCP/GM-TLSIIIII gm-caIHTTP IIIIIRust crates workspace for Chinese national cryptographic algorithms (SM2/SM3/SM4/SM9, GM-TLS, certificate authority).
4. Practical Deployment, Analysis & Case Studies The most important projects developed during my Master's Degree in Computer Science and Engineering at FCUL. Timelock encryption in Go — messages that cannot be decrypted until a chosen time, enforced by drand beacons and BLS12-381 IBE, not by a server.
Browser-based SM9 identity-based cryptography — signature, key exchange and encryption side by side, with keys extracted from a name by exponent inversion, two master key pairs in mirrored pairing groups, nonce-reuse recovery of a key point rather than a scalar, and the KGC reading everyone's mail Browser-based Boneh-Franklin Identity-Based Encryption demo implementing the 2001 BasicIdent scheme with BLS12-381 pairings via @noble/curves. Setup → Extract → Encrypt → Decrypt with the key-escrow tradeoff shown honestly.
Sigelith Key — key server for beattime-seal-v1 time-sealed envelopes: releases a BLS share only once its beat has arrived. Self-hosted, ~3 MB image, one 32-byte key that never leaves the volume. To associate your repository with the identity-based-encryption topic, visit your repo's landing page and select "manage topics." New developers require a single, framework-independent resource to establish a baseline in secure coding practices.
Python is one of the most widely adopted programming languages in the world, powering everything from web applications and data pipelines to AI/ML systems and cloud infrastructure. Yet adequate secure coding resources for Python to meet these needs of new developers haven’t been available. The OpenSSF Secure Coding Guide for Python closes that gap by providing developers with a practical, example-driven resource for writing more secure Python code. The guide covers over 50 rules across 9 sections, each with working code examples that demonstrate both the vulnerability and its mitigation.
Comprehensive secure coding standards have long existed for languages like Java ( SEI CERT Oracle Coding Standard for Java ), C, and C++. For Python, the available resources were either high-level and language-agnostic, or tied to a single web framework. When onboarding new developers, we needed a baseline of secure coding knowledge that was framework-independent, covered core Python, and could serve as a self-study resource without requiring 40+ hours of training. Nothing like that existed, so we built it ourselves under the OpenSSF Best Practices Working Group .
The result is a guide that focuses on CPython ≥ 3.9 and the standard library, deliberately avoiding dependencies on any specific web framework or third-party module. This keeps the material relevant regardless of which stack a team uses and ensures the secure coding principles transfer across projects. While the guide is primarily for new developers, it can also aid security researchers, AI and analysis tools, and educators as discussed below.
Python’s accessibility is one of its greatest strengths, but it also means that many developers writing Python code may not have formal training in secure software development. Common pitfalls such as OS command injection, deserialization of untrusted data, improper exception handling, and insufficient logging continue to appear in real-world Python applications and libraries. These are not theoretical risks: the guide references prominent CVEs with CVSS scores reaching 9.8, demonstrating the real-world impact of these vulnerabilities.
Existing secure coding standards from OWASP and MITRE CWE Top 25 provide essential high-level guidance, but they are language-agnostic. Developers need to understand how these risks manifest specifically in Python and what idiomatic Python mitigations look like. That is exactly what this guide delivers. Static analysis tools and AI-assisted code review are valuable, but they cannot catch everything. Many security issues stem from design decisions and coding patterns that automated tools struggle to evaluate, such as improper trust boundary handling, missing input neutralization, or subtle operator precedence errors. The guide’s code examples are specifically designed so that noncompliantXX.py files can be used to test and train analysis tools, while compliantXX.py files demonstrate the targeted fix. This makes the guide useful not only for human learners but also for improving the tools themselves (including AI).
The guide is organized into 9 sections covering the most critical areas of secure Python development: Each rule follows a consistent structure: a concise description of the risk, a non-compliant code example showing the vulnerability, a compliant solution demonstrating the fix, automated detection results, and references to related CWE entries and other guidelines. Every rule maps to a specific MITRE CWE weakness.
Many secure coding guides assign risk ratings using numeric scales with labels such as impact=HIGH=4 and probability=LOW=3, which are then multiplied and divided to produce an overall score. We found these approaches too abstract and subjective to be genuinely useful for developers trying to understand real-world risk. Instead, the guide takes an evidence-based approach. The main overview table pairs each rule with a representative CVE from a real-world product, its CVSS score, and its EPSS (Exploit Prediction Scoring System) probability rating. CVSS tells you how severe a vulnerability is if exploited; EPSS tells you how likely it is to be exploited in the wild. Together they give a grounded, data-driven picture of risk that abstract rating matrices cannot provide. This also exposes blind spots: rules with high CVSS but low EPSS may indicate areas where the industry underestimates exploitation likelihood, while high EPSS scores highlight vulnerabilities that attackers actively target.
What sets this guide apart from other secure coding resources is its emphasis on working code. Every rule includes runnable Python examples targeting CPython ≥ 3.9 that developers can clone and execute locally: The non-compliant examples include both the vulnerable code and an exploitation section separated by a clear comment marker, making them suitable for testing security analysis tools. The compliant examples address only the specific risk described, keeping them focused and easy to understand.
Consider a common vulnerability: OS command injection via unsanitized user input passed to subprocess . Our guide provides at least one detailed specific example so developers can understand and apply the guidance. In this case, the non-compliant example shows how an attacker can inject arbitrary commands, while the compliant solution demonstrates proper input handling using shlex and avoiding shell=True . Each example is short, typically around 20 lines, and focuses purely on the security issue at hand.
The documentation uses plain English to cater to an international audience. It is written in an academic style to maximize precision and to support security researchers. The entire guide is designed to be completed in well under 40 hours of self-study. The guide is an active, community-driven project and contributions are welcome. Whether it is fixing a typo, improving readability, adding a new code example, or creating entirely new rules to cover missing material, there are many ways to help.
Contribute on GitHub: https://github.com/ossf/wg-best-practices-os-developers/tree/main/docs/Secure-Coding-Guide-for-Python 5. Performance Evaluation & Extended Technical Observations Join the community on the OpenSSF Slack by searching /join secure-coding-guide-for-python in the search bar. You can also participate in the bi-weekly working meetings; see the meeting notes for details.
Helge Wehder (myteron) is a Security Principal Master with a background in Operations Support Systems (OSS) for large scale radio networks using Python. Helge enjoys creating embedded systems with his 4 children. Plays Bass guitar on a Sunday session in Flann’s Athlone and does a bit of Inline Hockey for sports. Thomas McDermott (tommcd) is a Senior Engineer at Ericsson, where he works as a software engineer with a particular interest in secure coding. He works extensively with Python and Java, with a particular interest in data analysis and Markdown- and notebook-based workflows, and he follows developments in AI-assisted engineering tooling. Before moving into software engineering 14 years ago, Thomas spent earlier parts of his career as a researcher and lecturer in Chemical Engineering and as a design engineer in the energy sector, though a long-standing love of coding (Fortran, C, Python, Mathematica, and Bash since the mid-1990s) eventually won out. He holds a PhD in Chemical Engineering from University College Dublin and an MSc in Applied Software Development, and his research background in molecular simulation and statistical mechanics continues to inform his analytical approach to software engineering and security.
Hubert Daniszewski (s19110) is a Java and Python software developer with over five years of experience writing, maintaining, and debugging code in both languages. A former Security Master at TietoEvry, he continues to expand his expertise in secure coding and applies it in practice. He was one of the first contributors to the Secure Coding for Python project, where he reviewed and authored rules, particularly in the area of concurrency.
Bartlomiej Karas (BartKaras1128) is a Software Developer and Security Master at Ericsson, bringing hands-on experience with Cloud Native solutions and a strong command of multiple programming languages, including Python. Throughout his career, he has contributed to numerous security enhancements and developed various automation solutions for hardware installation. Beyond his professional work, Bartlomiej has a passion for Game Development and has created multiple games as a hobbyist.
Andrew Costello (andrew-costello) is a Computer Science graduate with a focus on cybersecurity and software engineering. His work centres on practical system design, including machine learning-based malware analysis, and he also works on tools, cars, small engines, and farming, reflecting a strong hands-on engineering mindset. He is particularly interested in building secure, efficient systems that perform reliably in real-world conditions.
Dr. David A. Wheeler is an expert on developing secure software and on open source software. He created the Open Source Security Foundation (OpenSSF) courses “Developing Secure Software” (LFD121), “Understanding the EU Cyber Resilience Act (CRA)” (LFEL1001), and “Secure AI/ML-Driven Software Development” (LFEL1012). His other contributions include “Fully Countering Trusting Trust through Diverse Double-Compiling (DDC)”. He is the Director of Open Source Supply Chain Security at the Linux Foundation and teaches a graduate course in developing secure software at George Mason University (GMU).
Dean Wiley (dwiley258) is a Senior Software Engineer and Security Master at Ericsson with over five years of experience in Python development. He specialises in cloud-based solutions and automation tooling for cloud deployments, with a strong focus on security and building secure systems. Throughout his career, he has developed a keen interest in enforcing design rules and coding standards across codebases, as well as building tools to ensure ongoing compliance. Outside of work, he enjoys playing music, with a particular passion for bass guitar and cello.
Georg Kunz (gkunz) is a passionate advocate for open source software and a long term contributor to a wide range of open source projects and communities. He currently serves on the Technical Advisory Council (TAC) and the Governing Board of the Open Source Security Foundation (OpenSSF), co-chairs the OpenSSF Best Practices Working Group, and is a member of the TODO Group’s Steering Committee.
Noah Spahn (noah-de) is an open source software contributor and Associate Professor at Point Loma Nazarene University. He has a broad background in software development and DevSecOps, with experience in applications ranging from Earth science models to data center automation, network forensics and enterprise business solutions. David Mather (davidmather) currently working as Product Owner in Operations Support Systems (OSS) for large scale radio networks. David was one of the first contributors helping to architect the Secure Coding Guide for Python. Has been working as a software engineer and security master at Ericsson for several years. He encouraged team members, including Bartlomiej Karas and Andrew Costello, to contribute to the guide. Additionally, he collaborated with Bartlomiej Karas and Georg Kunz to demonstrate the project in [Vienna 2025] We envision a future where OSS is universally trusted, secure, and reliable. Join us in making open source more secure.
tl;dr: Encrypt to a phone number or an email address, rather than under the recipient’s public key. In an identity-based encryption (IBE) scheme, a message is encrypted under two things: (1) the master public key (MPK) and (2) an identity string (e.g., a phone number), resulting in a ciphertext . To decrypt, a decryption key can be revealed given (1) the master secret key (MSK) and (2) the identity string. Then, the decryption key can be applied to the ciphertext yielding back the original message.
The entity that generates the MPK and MSK and, crucially, protects the secrecy of the MSK is called a key-issuing authority (KIA) . Obviously, the KIA can decrypt anything , since given any identity $\id$, it is able to derive the decryption key for that identity. This makes IBE not always applicable since it centralizes trust in the KIA. However, the KIA can be decentralized: it can be implemented as $t$-out-of-$n$ distributed system, so that at least $t$ nodes must collude in order to maliciously reconstruct a decryption key.
Encrypts a message $m$ under identity $\id$ and master public key $\mpk$ using randomness $r$, yielding a ciphertext $C$. Derives a decryption key $\dk$ for the identity $\id$ using the master key $\msk$. This $\dk$ can be used to decrypt messages encrypted under $\mpk$ and $\id$. Roughly speaking, an IBE is said to be correct if for any $(\msk,\mpk)$ honestly-generated via $\ibe.\kgen(1^\lambda)$, for any message $m$, any identity $\id$ and any randomness $r$, we have: \begin{align} m = \ibe.\dec(\ibe.\derive(\msk, \id), \ibe.\enc(\mpk, \id, m; r)) \end{align} Threshold-issuance IBE or, more simply, threshold IBE distributes the master secret key $\msk$ in $t$-out-of-$n$ fashion amongst $n$ players .
$\mathsf{TIBE}.\mathsf{DistKGen}(1^\lambda, t, n) \rightarrow \left(\left(\mathsf{msk}_i,\mathsf{mpk}_i\right)_{i\in[n]}, \mathsf{mpk}\right)$ Encrypts a message $m$ under identity $\id$ and master public key $\mpk$ using randomness $r$, yielding a ciphertext $C$.
This is the same as the non-threshold $\ibe.\enc$. That’s why we kept the same name for it here. $\mathsf{TIBE}.\mathsf{Derive}(\mathsf{msk}_i, \mathsf{id}) \rightarrow \mathsf{dk}_i$ Derives a decryption key share $\dk$ for the identity $\id$ using the master key share $\msk_i$. This $\dk_i$ can be used to threshold decrypt messages encrypted under $\mpk$ and $\id$.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Private%20biometrics • https://en.wikipedia.org/wiki/Secure%20Remote%20Password%20protocol • https://en.wikipedia.org/wiki/JSON%20Web%20Token • https://github.com/blackmoney069/IdentityBasedEnc • https://github.com/h1balamdani/identity-attribute-encryption • https://mahe94.github.io/projects/hierarchical-identity-based-encryption/ • https://en.wikipedia.org/wiki/Identity-based_encryption • https://github.com/topics/identity-based-encryption • https://openssf.org/blog/2026/05/12/secure-coding-guide-for-python-pyscg-first-release/ • https://alinush.github.io/ibe
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Identity Based Encryption Implementation In Python.
[*] Metasploit Scan Running on Target Subnet for Identity Based Encryption Implementation In Python... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |