Complete Technical Paper Content — Identity Theft Detection Using Machine Learning
Overview & System Context
Identity Theft Detection Using Machine Learning: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9503 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background With the rapid development of digital services, a large volume of personally identifiable information (PII) is stored online and is subject to cyberattacks such as Identity fraud. Most recently, the use of Artificial Intelligence (AI) enabled deep fake technologies has significantly increased the complexity of identity fraud. Fraudsters may use these technologies to create highly sophisticated counterfeit personal identification documents, photos and videos. These advancements in the identity fraud landscape pose challenges for identity fraud detection and society at large. There is a pressing need to review and understand identity fraud detection methods, their limitations and potential solutions. This research aims to address this important need by using the well-known systematic literature review method. This paper reviewed a selected set of 43 papers across 4 major academic literature databases. In particular, the review results highlight the two types of identity fraud prevention and detection methods, in-depth and open challenges. The results were also consolidated into a taxonomy of AI-based identity fraud detection and prevention methods including key insights and trends. Overall, this paper provides a foundational knowledge base to researchers and practitioners for further research and development in this important area of digital identity fraud.
Identity is used to identify an individual or entity [66-68]. Identity fraud is a criminal act involving the use of another person’s identity or the creation of a fake identity for fraudulent purposes [69-70]. Fraudsters’ main goal or motive could be to obtain money and public resources, evade obligation or commit other crimes [44]. With the rapid development of digital and online services, a large amount of personally identifiable information (PII) is scattered and generally stored in public databases. The monetary benefits of selling personal information on the black market have driven cyber-criminals to covet this personal data.
Every year, billions of PII records are breached or stolen due to cyber-attacks and security vulnerabilities [56-64], providing the means for committing identity fraud. Between 2020 and 2024, multiple data breaches have occurred, compromising personal information such as names, dates of birth, social security numbers, addresses, emails, phone numbers, and even bank account passwords [56-64]. In recent years, the development of Generative Artificial Intelligence (GAI) technology has made identity fraud feasible with the possibility of generating fake identities at a scale. Several fraud cases involving deep fake technology have emerged recently. For instance, deepfake allowed criminals to bypass identity verification systems and conduct fraud through live video [45]. The consequences of identity theft and the use of fake identities are far-reaching, influencing both individuals and organisations across a wide range of sectors [70]. The fraud ring or individuals obtain true identity information from others or fabricate fake identities through black market channels, using them for targeted scams, extortion, insurance and loan fraud, and even participating in illegal activities like money laundering (Fig.1) [44].
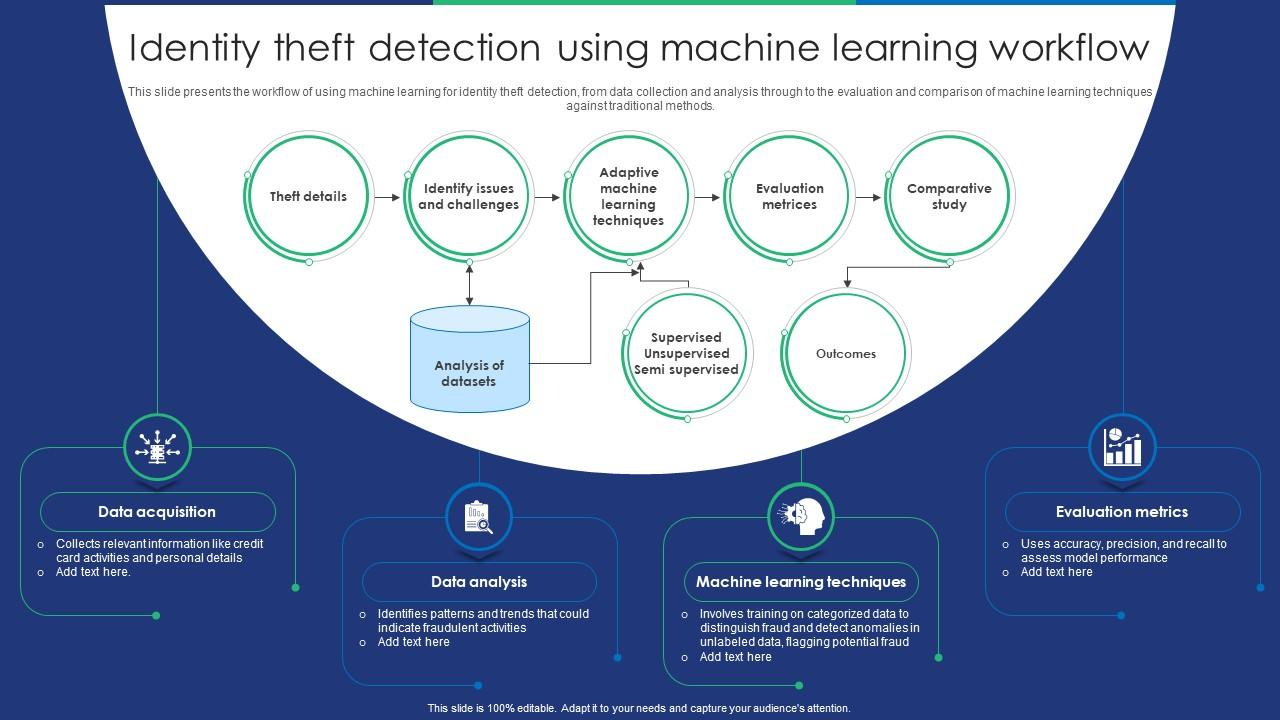
AI or GAI can be used for both enabling identity frauds via generating fake identities and fraud detection methods. There is a need to review and consolidate knowledge on this topic to facilitate the understanding of AI and identity fraud. Thus, this paper aims to address the following main research question: This review paper focused on the study of AI-based detection methods covering identity fraud prevention and detection stages. To the best of our knowledge, there is no similar Systematic Literature Review (SLR) study that examines the AI and integrated identity fraud prevention and detection processes. The main contribution and reflections of this paper are as follows: Figure 1: Identity Theft Detection Using Machine Learning Workflow Fraud ...
A novel taxonomy for identity fraud prevention and detection methods, categorised into two key phases: authentication and continuous authentication. This taxonomy provides a structured approach to understanding the strategies and challenges employed in each phase. Key insights about the increasing importance of biometric authentication, especially facial recognition.
Continuous authentication using user behaviour analysis, which is becoming more important for improving fraud detection after the initial authentication. This paper is organised as follows. Firstly, it discusses the research motivation and method. Secondly, it presents the analysis of the identified fraud detection methods based on the review of selected papers. Thirdly, it discusses the open challenges before concluding.
Figure 2: CSSE | Free Full-Text | Performance Analysis of Machine Learning-Based ... Identity, which serves to identify an individual and entity, is widely used daily to access various activities such as public services, education, medication, job applications, financial transactions, social media, etc. [66]. The threats to identity are known as identity theft and identity fraud, which are collectively referred to as identity-related crimes, including all forms of illicit conduct involving identity, such as acquiring, manipulating, producing, transferring, possessing, or using identity information for unlawful activities [44], [69]. Identity theft and identity fraud, though related, are not identical. Initially, the two concepts were not clearly distinguished until 2011 when The United Nations Commission on Crime Prevention and Criminal Justice provided a clear definition of them [69],[71].
Identity theft is often the first step of identity fraud, which primarily involves the unlawful acquisition of identity information, such as PII [78]. As shown in Fig 1 ., identity thieves initiate malicious attacks, including malware, phishing, and brute force, to intrude into various institutions such as financial institutions, hospitals, governments, and enterprises to steal identity information [56–64]. These stolen identities are either directly sold or transferred to accomplices, such as identity forgers, who produce synthetic or fabricated identities for resale to criminal individuals or groups [78-79]. With the assistance of AI technologies, particularly GAI, the manipulation and creation of both real and synthetic identities have become significantly easier [80]. Identity fraudsters then use this identity information to create new identities or take over other identities to gain either financial or non-financial benefits at the cost of other accounts [44]. For example, defraud financial institutions to receive payouts or services [81]. This identity information can also be used to facilitate a means to an end as part of other illegal acts such as human trafficking, money laundering, and illegal immigration [82]. Beyond financial losses, the consequences of identity fraud extend, encompassing psychological distress, reputation damage, and potential legal repercussions for victims [72-77].
The current defence against identity fraud primarily relies on two processes: authentication and continuous authentication. Authentication is the process of verifying whether someone or something is truly who or what it claims to be. Authentication methods are categorised into three categories based on the type of information being verified: knowledge, possession, and inherence [46]. Knowledge-based authentication involves confirming a user’s identity through information they know, such as a one-time password (OTP), answers to security questions, or a personal identification number (PIN) [84]. Possession-based authentication verifies identity through physical items the user owns, such as mobile devices, smart cards, or hardware tokens [83]. Inherence-based authentication confirms a user’s identity through their biometric or behavioural characteristics. This type of biometric authentication includes, but is not limited to, facial recognition, voice recognition, and fingerprint recognition [46],[47],[85].
However, initial authentication alone may not be enough, as data breaches and advanced attack techniques (e.g., biometric spoofing and deepfakes) still enable criminals to bypass verification systems relatively easily [65],[86-87]. Therefore, defending against identity fraud also requires continuous authentication. Continuous authentication is the process of continuously verifying the user’s identity and detecting anomalies by monitoring user behaviour and contextual data in real-time [48]. It reduces vulnerabilities to unauthorised access and enhances the overall security of online interactions and transactions [88].
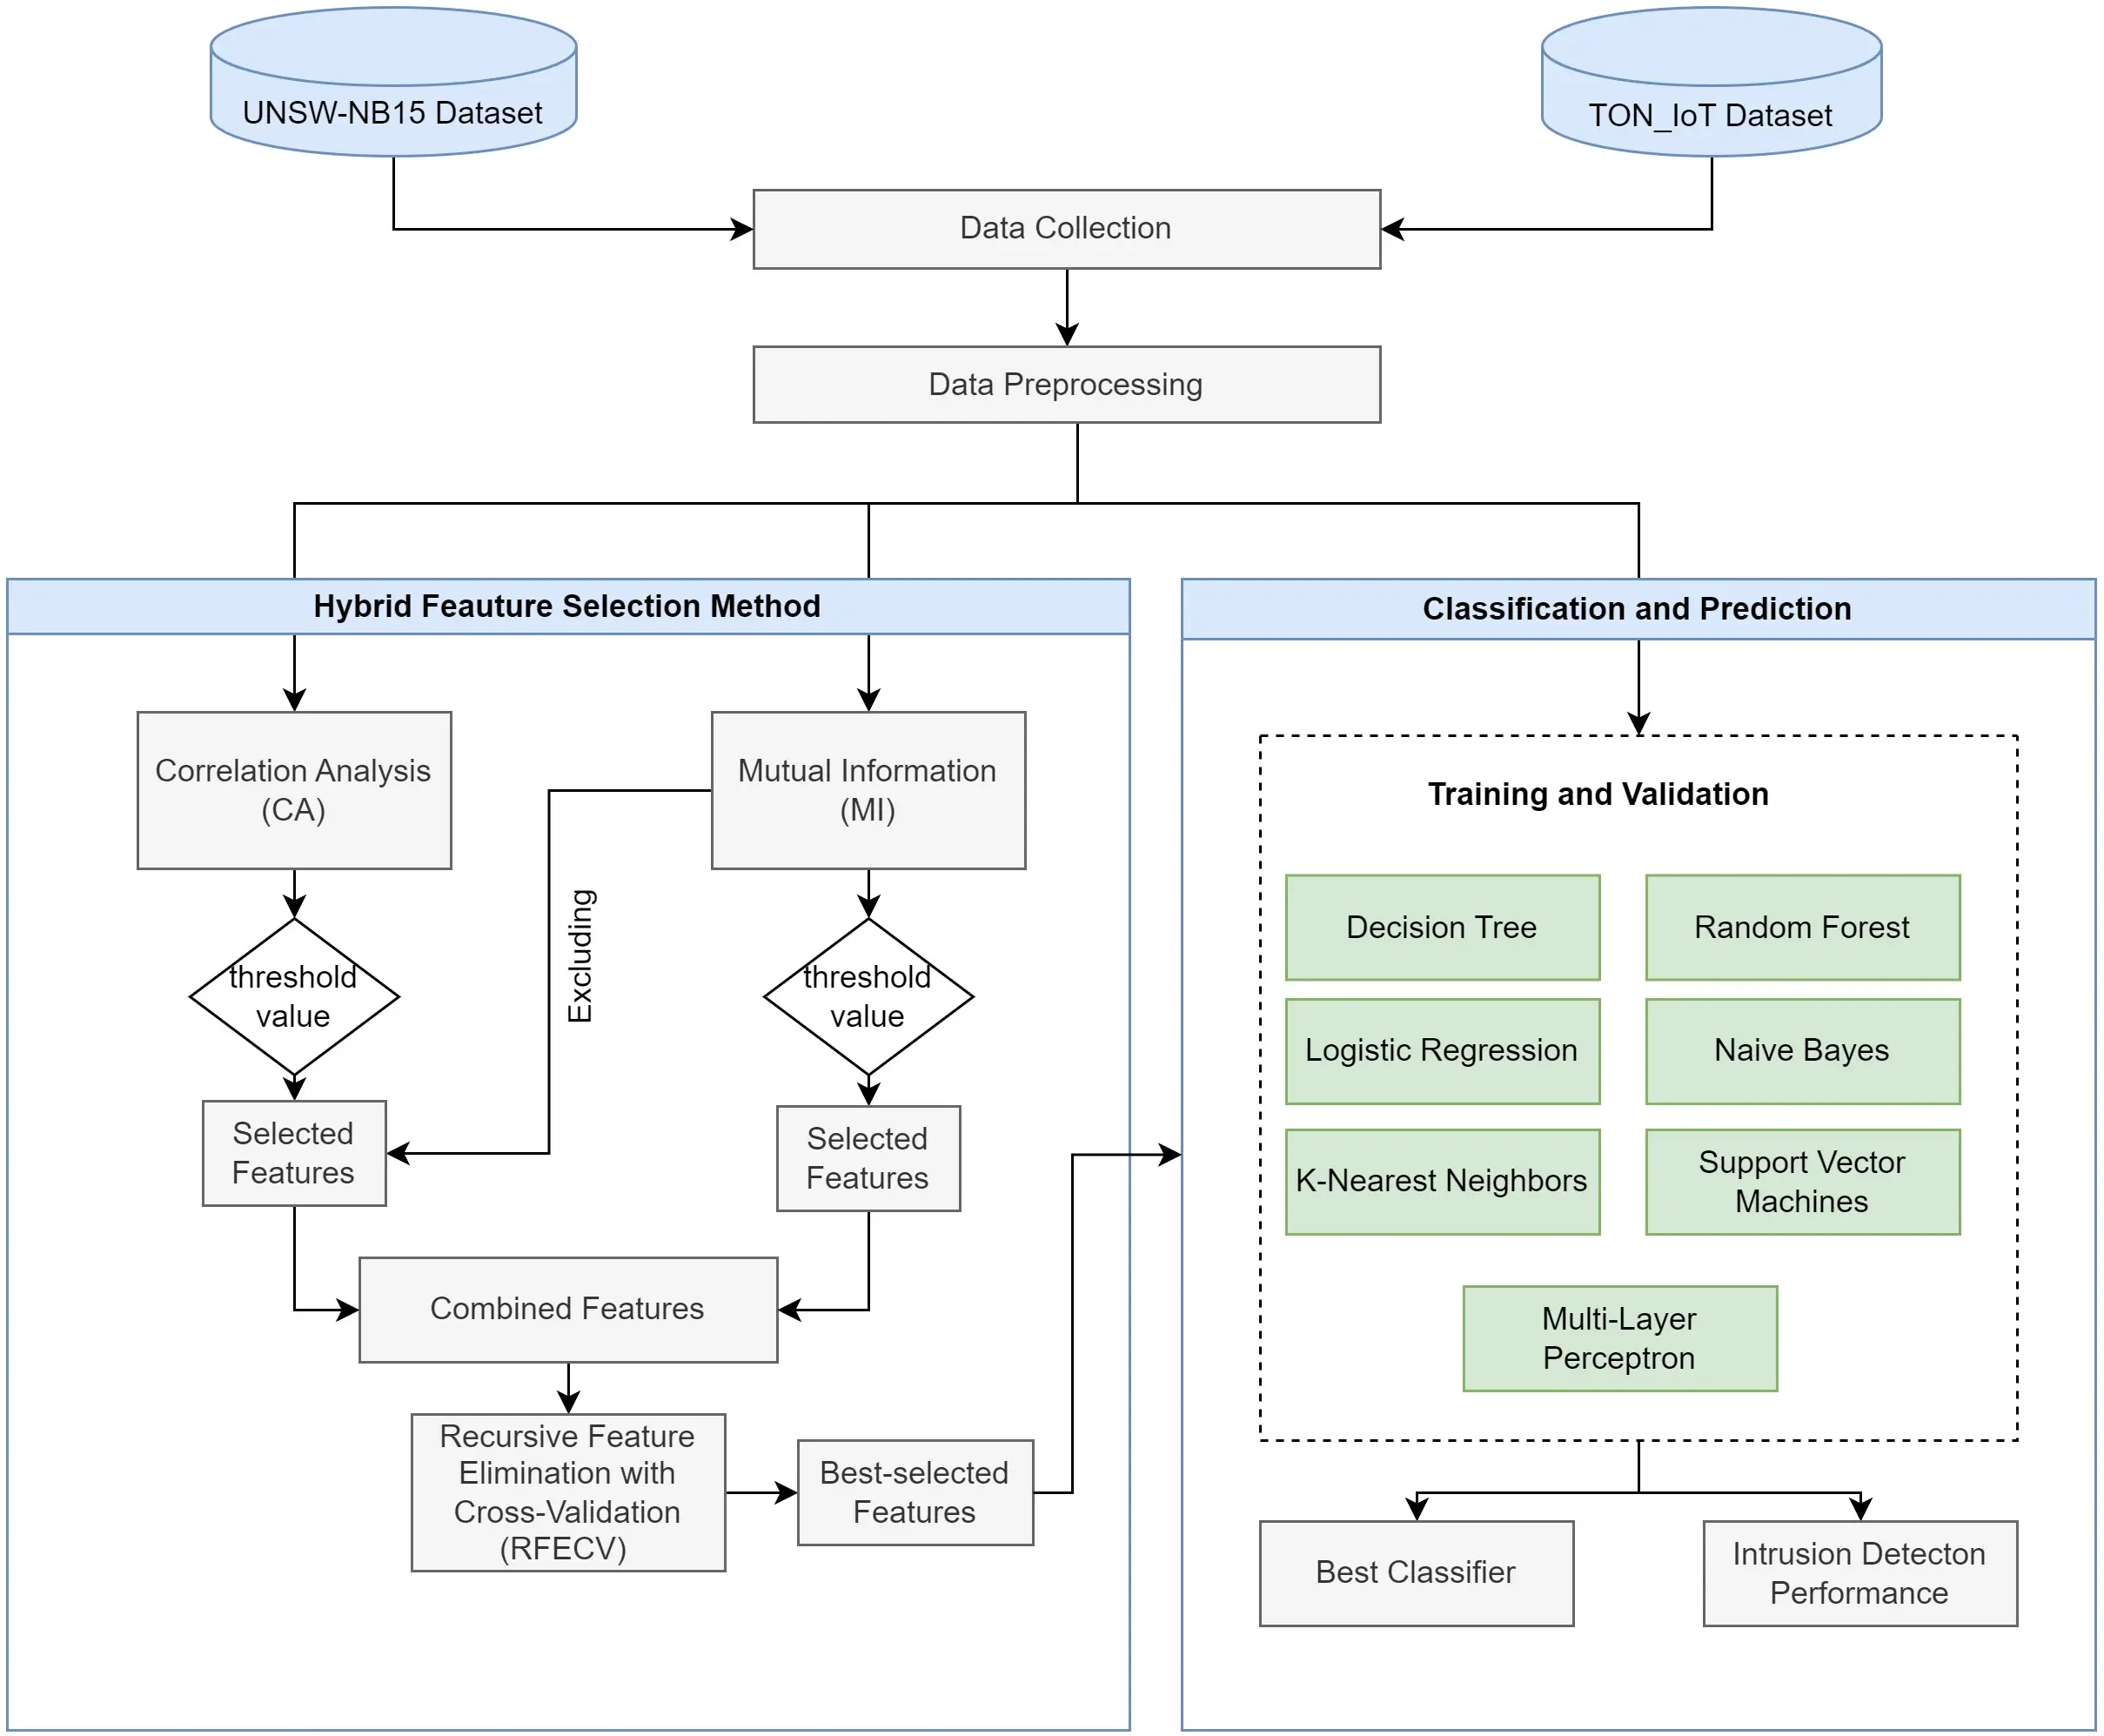
Figure 3: [II II] A Review of Various Datasets for Machine Learning Algorithm ... AI, which originated in 1956 to replicate human thinking and problem-solving [49], has evolved to effectively combat identity fraud in both authentication and continuous authentication. By integrating machine learning and deep learning models with technologies such as computer vision, natural language processing (NLP), and graph technology, AI empowers systems to perform tasks like identification, recognition, and anomaly detection [49]. For example, in biometric authentication, AI leverages deep learning and computer vision technologies to authenticate users by first recognising and then comparing their biometric features[47],[53]. In continuous authentication, AI incorporates graph technology for relationship modelling and NLP for analysing textual data to detect fraud patterns across structured data (e.g., transaction records) and unstructured data (e.g., social media content), which enables real-time and adaptive authentication [48].
Existing literature on identity fraud reveals the following gaps, which this review aims to address. These gaps include (1) many existing reviews primarily address financial fraud detection but not identity fraud detection [93-96]; (2) a lack of exploration into how AI can be applied across both stages of authentication to prevent identity fraud effectively, with existing studies focusing mainly on specific technical aspects of fraud detection[93],[95-96].
This review, motivated by an industrial project to develop an AI fraud engine for identity verification systems, investigates how AI detects identity fraud during authentication processes and identifies gaps in current methods to guide the development of more robust solutions. It introduces a novel framework by adopting authentication processes as a consolidated structure, systematically deconstructing and analysing each phrase of identity fraud detection methods and AI integration. This hierarchical "top-down" approach provides a rigorous and structured exploration of methodologies. Furthermore, this review addresses existing research gaps and provides insights and future directions for researchers and practitioners.
This review conducts a systematic literature review based on the detailed approach described in [51]. It begins with research planning, where we define research questions, keywords, databases, and selection criteria. Then, we conduct the data search and selection based on the inclusion and exclusion criteria and quality assessment criteria. Finally, we extract data from the selected documents according to the defined fields The primary aim of this SLR is to discover all AI-based methods to detect and prevent identity fraud during authentication processes. The methods are compared to evaluate their effectiveness, and identify open challenges and future development points in combating identity fraud.
Four popular databases were selected because they cover a wide range of high-quality, peer-reviewed technology and computer science articles. The databases are listed as: Based on the research questions defined in Section II-A, we divide the research questions into three search categories and collect a series of related concepts for each (TABLE 1 ). We then formulated the search query as follows: We searched the titles and abstracts for articles published from 2020 to 2024. Limiting the search data range is driven by the fact that the big jump in the use of AI started from the introduction of GPT-3 by OpenAI in 2020, though AI and its related technologies have been studied for years [52].
We defined the following inclusion and exclusion criteria to restrict the selection of articles from the returned results (TABLE 2 ). This review only includes technical papers on identity fraud detection and excludes articles that address cybercrimes and cyberattacks, as mentioned in Inclusion Criteria 5. The reason for designing Inclusion Criteria 5 this way is that the focus of detecting fraud that involves using false or stolen identities is on verifying the authenticity of the identity being used (i.e., whether it is true or false). However, as the search query includes "identity theft”, articles related to defending against cyberattacks, such as malware detection, are also included in the search results. This is not aligned with the research problem of detecting identity fraud. Therefore, to more accurately select articles relevant to this topic, Inclusion Criteria 5 filters the results using the process outlined in Fig. 2 . If an article does not focus on detecting cyberattacks and proposes a method related to "identity" used for verifying true or false identities, it will be included.
The five stages of filtering, as described in TABLE 3 , ensure a thorough selection of relevant articles. First, duplicates are removed, followed by the exclusion of reviews and case studies. Next, papers are filtered based on keywords in their titles and abstracts. The fourth stage applies inclusion and exclusion criteria to refine the selection further. Finally, the remaining full texts are evaluated using six Quality Assessment Criteria (TABLE 4 ) to confirm their relevance to the research topic.
This section gathers and extracts data from the primary studies addressing the review questions outlined in Section II-A. The extracted data were organised in a spreadsheet, and the critical information retrieved from these studies was summarised using the Data Extraction Form in TABLE 5 . A total of 1257 papers were extracted from all databases, of which 137 were duplicated. The review excluded paper types of survey, literature review, systematic literature review, and case report, in which 81 papers were filtered out by Filter.2. Filter.3 then picked out 269 papers in which keywords were not included in their titles and abstracts. At the same time, Filter 4 further examined the titles and abstracts based on exclusion criteria three and inclusion criteria five, i.e. any papers not related to identity fraud and related to prevention against cyberattacks were excluded. 588 papers were exempted from Filter.4. The quality assessment criteria for the remaining are in TABLE 4 . If the paper meets the requirements, it will score 1; otherwise, it will score 0. Papers in a score range from 3-6 were selected. Finally, 43 papers remained for this review. Fig. 3 presents the selection outcomes, while Appendix A provides the scoring details for the chosen papers.
This section presents the results of the SLR, addressing RQ1 and RQ2. The findings are organised into five main areas: (A) taxonomy of AI-based identity fraud (IDF) detection methods (Fig. 4 ), (B) framework and frequency analysis for open challenges, (C) observed trends, and (D-E)an in-depth analysis of individual methods including the identification of open challenges across technical and non-technical dimensions.
The review of the literature resulted in the identification of three main types of AI-based identity fraud (IDF) detection methods: biometric recognition, visual anomaly detection, and user behaviour anomaly detection. These methods are organised into a taxonomy (Fig 4 ) and broadly classified into two authentication processes: authentication and continuous authentication.The categorisation was based on the operational purposes, process and core principles of the methods.
The distinction between authentication and continuous authentication methods lies in their approach to identity verification. Authentication methods typically verify identity at the initial login, while continuous authentication methods involve ongoing monitoring of user behaviour, device characteristics and environmental factors throughout a session [68], [91-92]. Authentication methods were further classified based on their operational purposes. For example, methods designed to defend against attacks during authentication, such as fake biometrics or identity forgery, were categorised as authentication defence methods. Conversely, methods that solely address authentication system functionality were classified under authentication. Following this second-round classification, a detailed examination of each method’s operational principles, functional components, and implementation techniques was conducted to ensure clear and systematic categorisation.
This review revealed that biometric recognition is the sole method applied for authentication. Methods targeting authentication attacks, such as fake biometrics or identity forgeries, rely on visual anomaly detection, which is further divided into feature-based and deep learning-based approaches. For continuous authentication, all methods fall under user behaviour anomaly detection, where User and Entity Behaviour Analytics (UEBA) serves as the foundational framework. This framework was further examined through two key technical components: profiling models and analytical techniques [91]. The review articles were categorised accordingly to analyse the methods used for constructing behavioural profiles and the analytical techniques applied for anomaly detection, offering a comprehensive understanding of the underlying technologies.
Fig. 5 further illustrates how these methods are implemented within two key authentication processes: authentication and continuous authentication. It maps the IDF detection and prevention methods from the taxonomy to their respective roles in these processes, providing a detailed view of their functional implementation. 2. System Architecture & Core Working Principles Note: •The IDF detection and prevention process begins with identity authentication, where users’ biometric data or official ID documents are captured. Key features are extracted to create a user-specific template, which is stored and matched against records to verify identity. •Visual anomaly detection with advanced feature extraction algorithms analyses provided samples in detail to safeguard the process. •Continuous authentication monitors users’ behavioural patterns, relying on baseline profiles to identify anomalies. If anomalies are detected, the system suspends access and prompts for additional identity verification.
The open challenges identified in this study were examined using the Adaptive Enterprise Architecture (EA) framework [89], which addresses key aspects critical to industrial projects and enterprise decision-making. This structured approach facilitates the categorisation and analysis of challenges in identity fraud detection methods. This review selected three key dimensions from the framework: Technology, Human, and Environment.
The Technology dimension was evaluated based on quality characteristics such as accuracy, robustness, resiliency, and effectiveness [90], while the Human and Environment dimensions were derived and coded to capture non-technical challenges. To quantify and highlight prominent issues across methods, frequency analysis was applied, aligning the findings with key themes identified in the selected literature. This approach was used to examine both individual open challenges for each method and broader challenges across the entire review.
TABLE 6 and TABLE 7 present evaluation criteria and frequency analysis results for the open challenges in this study. The findings highlight four key challenges in AI-based IDF detection methods: data quality and diversity, data privacy and security, dynamic and evolving fraud patterns, and optimising training time and method efficiency. These challenges will be examined in detail in the discussion section, guiding the exploration of future research directions and advancements.
The distribution of AI-based IDF detection methods reveals important trends in the focus and application of these techniques. As shown in TABLE 8 , 55.81% of the methods are predominantly applied to authentication, whereas 44.91 % are designed for continuous authentication, reflecting a growing emphasis on adaptive and ongoing verification mechanisms. As shown in Fig 6 biometric authentication is the most commonly used method in authentication, accounting for 79% (19/24) of authentication-related articles. Among these, 36.8% (7/19) focus on performance improvements in biometric recognition systems, while 63.2% (12/19) address their vulnerabilities. Notably, facial recognition emerges as the most discussed biometric method, appearing in 12 articles within this category.
Visual anomaly detection is identified as the primary defence mechanism in authentication processes, representing 39.35% of the total articles reviewed. In contrast, continuous authentication methods exclusively rely on user behaviour anomaly detection, which accounts for 44.19% of the articles. Deep learning techniques dominate both visual anomaly detection and user behaviour anomaly detection, with 76% of visual anomaly detection and 53% of user behaviour anomaly detection articles employing this approach. These findings indicate a growing research emphasis on deep learning as a means to address the evolving challenges of identity fraud.
This distribution provides a foundation for analysing the operational principles, related techniques, and specific challenges of each method, as elaborated in the subsequent sections. Note: •The Reference column lists all the papers that include methods within the Sub-categories, including duplicates. •Sub-Frequency represents the number of papers for each Sub-category. •Sub-Percentage is calculated as the ratio of Sub-Frequency to Total Frequency, showing the relative contribution of each Sub-category. •Total Frequency represents the total number of papers across the two Sub-stages. •Percentage is calculated as Total Frequency divided by the overall frequency of the Main Process (e.g., for Authentication, 7/(7+17)). •Total Percentage indicates the proportion of the Main Process’s total frequency to the total number of selected articles (e.g., for Authentication, 24/43).
Note: Because some articles used multiple data types, the results reflect an aggregated analysis of the overall data. This section focuses on two AI-based authentication methods: biometric recognition and visual anomaly detection. Each method is analysed in detail based on its operational principles, including core components and related implementation techniques. Using the categorisation framework from Section B, the open challenges of current techniques are systematically evaluated and elaborated in the subsequent sections.
This section analyses the biometric recognition system in terms of its operational components and examines the open challenges identified through frequency analysis. Biometrics refers to the process of identifying individuals by capturing and analysing their unique physical or behavioural characteristics using electronic devices, such as face, fingerprints, signature, voice, Electrocardiogram (ECG) and chirp Sound [14], [25],[27], [32], [36], [42] as shown in Fig 7 . Biometrics, characterised by their inherent uniqueness and reliability, offer a more effective method for verifying the authenticity of an individual’s identity [27],[53]. As shown in Fig. 5 , a biometric recognition system is composed of the following modules: sensor, feature extraction, matching, and decision-making [53]. The process flow for authentication is depicted by the directional arrows, highlighting the sequence from input data acquisition to final decision-making.
The Sensor Module is responsible for capturing a user’s biometric information, like cameras on smartphones, fingerprint scanners, and microphones [27], [41]. The Feature Extraction Module is used to extract key biometric measures, making the system more effective at identity recognition [42]. For example, facial features such as the eyes, nose, and mouth are crucial for enabling machines to identify individuals. are applied to strengthen these features and improve the accuracy of facial recognition systems.
The Matching Module is used to compare the newly captured biometric template with the one stored in the database [32]. There are two approaches: one-to-one and one-to-many. In a one-to-one matching system, the biometric template of the verified user is already stored in the system. A common example is a smartphone’s identity verification system [22],[24],[25]. In a one-to-many matching, there is no pre-stored biometric template, which means the individual’s identity is unknown [32].
The system must search a large database to identify the person. An example of this is the watch list screening conducted by financial institutions before onboarding customers [32]. The Decision Module is the system that makes the final decision after the comparison. If the matching result shows a high similarity, the authentication is approved; if the similarity is low, the authentication is denied.
TABLE 9 summarises the key challenges identified in biometric recognition systems based on the findings of this review. These challenges highlight critical limitations in the current state of the technology, including data quality, system resilience, implementation effectiveness and security vulnerabilities, which are detailed below. Data quality is the most frequently cited challenge affecting model accuracy, due to variability in data sampling conditions and sample collection devices (See TABLE 9 ). Factors such as lighting and angle [22] are common sources of variability in biometric recognition. As noted in [41], different fingerprint sampling devices produce varying biometric templates, which also increases the difficulty of detection.
In facial recognition systems, dataset diversity is another critical factor influencing performance. For example, changes in a person’s age or facial expressions in facial recognition systems can impact verification accuracy [32]. If the dataset lacks diverse samples for each user, the verification results may be significantly affected. High-quality data relies on advanced sampling devices, particularly when employing more specialised biometric features like Chirp Sound and ECG [14], [27], [36]. These features have been validated for their role in biometric recognition [36]. However, implementing these methods requires specialised equipment for capturing high-quality signals. Similarly, noise during voice data collection remains a significant challenge, as highlighted by [27], [43].
A significant challenge to achieving the effectiveness of biometric recognition systems lies in their inherent complexity. Long training times [14], [22], [25], intricate biometric data structures such as ECG signal sequences, and extended data collection for specialised biometrics [27] all contribute to delays in achieving practical and timely implementation. Common biometric systems (e.g., facial recognition, fingerprints, voice recognition) are vulnerable to potential security breaches from evolving fraud technologies, such as morphing attacks and presentation attacks [18], [19], [22], [26], and Deepfake attacks [13], [15], [23], [37], [40]. Criminals can bypass these systems using simple forgeries, like 2D or 3D printed masks or by displaying images on a phone screen [18], [19]. In high-security areas such as border control, criminals may use morphing techniques by submitting a fused-feature passport photo during visa applications [22]. This changes the stored template in the database, complicating the detection of fraudulent activities.
This section analyses the visual anomaly detection system in terms of its key implementation techniques. Additionally, it summarises the detection techniques, targeted features, addressed attack types, and the algorithms or models in table and examines the open challenges identified through frequency analysis to provide insights into the limitations of current methods. Visual anomaly detection is a method designed to detect abnormal or unexpected patterns in images and videos that are different from the expected form as defined [54]. This technique is implemented within recognition systems to enhance the matching accuracy with more detailed features, as highlighted in the designated region of the authentication process (Fig 5 ).
Among the articles discussing vulnerabilities in authentication systems, their main focus is to counter biometric spoofing and deepfake and ID document forgery attacks. TABLE 10 summarised articles for visual anomaly detection along with the types of attacks they counter. Aside from [13], [18] and [19], which use adversarial learning to counter these attacks, other studies [26], [32], [37], [38], [40] rely on techniques in feature detection or deep learning models to achieve successful defence.
Based on the collected articles, visual anomaly detection can be implemented using feature detection and deep learning. Feature detection: Feature detection is a concept in computer vision and image processing. This process uses computers to extracts information from images and then determines if certain points within the image are part of an object [55]. For instance, feature detection extracts interest points from an image (e.g., points, lines, edges) along with their neighbour area to form regions of interest. By comparing these regions, feature matching can detect global or local anomalies between normal and abnormal images.
Feature detection occurs at the stage of feature extraction to identify abnormal features in images or videos. When countering forgery attacks, feature detection enables models to focus on critical areas of change which can effectively detect anomalies, such as eyes and mouths in paper-cut attacks [19], facial expression regions in deepfake videos or subtle statistical differences in morph attacks. Methods like the EBHOG descriptor in [18], [42] and the Multi LBP Model in [34] use feature weighting and multi-feature combination to achieve this.
Conventional feature extraction methods include HOG, Scale-Invariant Feature Transform (SIFT)[25], Local Binary Patterns (LBPs) [34], ORB (Oriented FAST and Rotated BRIEF) [25], and Gabor Filters [32]. In addition to these texture features, statistical features like Multidimensional Co-occurrence Matrices (MCMs) [26] are used to capture spatial relationships of pixel values in an image.
3. Software Implementation, Frameworks & Protocols Deep learning: Deep learning based approach is the more advanced version of feature detection. The effectiveness of deep learning techniques in image classification has motivated researchers to use deep neural networks like Convolutional Neural Network (CNN), Residual Network (ResNet), U-shaped Convolutional Neural Network (U-Net), and Visual Geometry Group Network (VGG) [23], [25], [26], [32], [33] for extracting more advanced features from images automatically. CNN [18], [25], [32] and its related architectures, such as Inception and its variant XceptionNet [15], [37], [40], are among the most widely used deep neural networks in visual anomaly detection. For example, methods [15] and [18] use encoder-decoder architectures to extract and segment facial features in detail and reconstruct anomalous samples, allowing the decoder to determine authenticity. Neural networks specifically designed to extract facial features, such as Viola-Jones Object Detection and Multi-task Cascaded Convolutional Networks [23], [37], are also applied during the training process, particularly targeting complex attacks like face-swap, face replacement, and face reenactment. Additionally, it incorporates feature detection methods, using descriptors that extract key features [18] or the statistical features of the images to enhance the neural network’s detection of anomalous features [40].
TABLE 11 provides an overview of the open challenges of the Visual anomaly detection method identified in this review. This method faces several critical challenges, including data quality issues, limited robustness and resilience, operational inefficiencies, data privacy constraints, and increasingly sophisticated fraud tactics driven by technological advancements, as shown below: Detection accuracy is influenced by the quality of the data such as image resolution [15], and the quality of data processing [11], [31], [34]. For instance, [11] applies generative adversarial networks (GAN), StyleGAN2, and CycleGAN to generate synthetic ID cards. Though the method performs well on trained datasets, the synthetic data lacks real-world fidelity, compromising the model’s performance in real-world scenarios. [34] then highlights the impact of document misalignment during video processing, which leads to detection errors.
Lack of data diversity adversely affects robustness and transferability, hindering the method’s performance in real-world scenarios [10], [19], [23], [33], [40], [41], [42]. As mentioned in [10], [40], [41], [42], the model can only distinguish seen patterns in the trained images and may fail to adapt to diverse scenarios, such as real-time sample capturing with complex lighting, angles, backgrounds and etc.
The use of deep learning methods results in a slower process during both training and testing phases, particularly when handling large datasets [13], [15], [18], [19], [23]. Data privacy regulations have restricted access to private data, affecting the implementation and effectiveness of methods. Both [10] and [11] highlight the prolonged data collection process for real ID document samples due to regulatory constraints.
Fast-evolving fraud tactics, such as the use of advanced technologies like deepfake, also challenge the ability of these methods to effectively handle new scenarios [13], [15], [31], [38]. For instance, while [11] demonstrates promising performance on previously unseen deepfake models, the high transferability of evolving adversarial examples across diverse model architectures and real-world conditions poses significant challenges.
This section focuses on continuous authentication, primarily implemented through user behaviour anomaly detection. The analysis of these methods is conducted within the framework of UEBA, which serves as the foundational operational principle to guide their implementation. Additionally, the open challenges were identified through frequency analysis. User behaviour anomaly detection utilises AI techniques, such as machine learning and deep learning, to identify deviations from normal behaviour in user profiles. In the reviewed articles, the analysis reveals the application of methods based on UEBA, a widely adopted approach in industrial practices [92]. These methods construct user profiles by analysing user behaviour patterns and their interactions with entities such as devices and applications [91]. This profile serves as a baseline for the users and is compared with real-time user data to identify potential anomalies [91-92]. Fig 8 shows the three pillars that underpin the functionality of the UEBA tool.
The user behaviour anomaly detection methods are analysed using the dimensions of the UEBA framework. The analysis is organised into five key aspects: (a) core data for user profile creation, (b) profile modelling techniques, (c) analytics techniques, (d) use cases, and (e) open challenges. User profiles provide an important baseline for analysing user behaviour patterns and detecting anomalies [91]. Fig 7 illustrates the data and feature elements identified in the reviewed articles. These components, essential for user profile construction, are categorised as follows: Personal information: basic details such as name, date of birth, address, email address, phone, etc. [1], [2], [3], [12].
Behavioural Patterns: the typical actions and interactions that users exhibit within a system. It includes these categories as in the followings: Device interaction: user’s interaction with such as touchscreen [30], zoom gestures [29], keystrokes [28], browser fingerprint [3] and sensor [39].
Social features: user data linked to an account and its posts on an online social platform, such as friend counts, like counts, comments, etc. [16], [17], [21], [35], [9]. Transaction history: details of performed transactions, including amounts and recipients, etc., [4], [5], [6], [7], [9]. Communication patterns: the distinctive ways individuals express themselves through language, such as word choice, sentence structure, tone, and writing styles [8], [17], [20], [35],[16].
Device Information: details about devices used, such as IP addresses, MAC addresses, and device types [1], [3],[12]. Geographical information: regular physical locations from which the user accesses the system [12]. Note: Because some articles used multiple data types, the results reflect an aggregated analysis of the overall data. (Abbreviation refers to TABLE 10 ) Fig 9 illustrates the distribution of attributes used to construct user profiles in this review based on an aggregated analysis.
Communication patterns, device interaction, social features, and transaction history are equally important attributes for building user profiles, with each being utilised in five articles Due to differences in modelling purposes, the modelling techniques of user profiles can be broadly categorised into two types: historical patterns modelling and relational patterns modelling. Their workflows for anomaly detection differ slightly.
Historical patterns modelling: this is the most common approach, utilised in 15 articles [4], [5], [6], [7], [8], [9], [16], [17], [20], [21], [28], [29], [30], [35], [39]. First, behaviour data of users and entities is collected from various data sources (e.g., logs, devices, application activities, etc.) and preprocessed. Next, feature extraction is performed. Due to the diversity of behavioural data, this step is particularly crucial. Feature engineering, a method used to extract more representative features from the data, has become prevalent in user behaviour anomaly detection [5], [12], [9], [16], [17], [20], [21], [29], [30], [35]. It helps models focus on more relevant features and effectively represent user profiles. Subsequently, historical behaviour patterns are modelled. The model learns the normal behaviour of users as a baseline. When new user data is received, the model automatically identifies whether the new behaviour is expected or anomalous.
Relational patterns modelling: This method first analyses labelled business data to identify fraudster behaviour patterns and then constructs these relational patterns using graph techniques [1], [2], [3], [12]. It highlights the interrelations among users, which support the mapping of networks that underpin organised crime. Therefore, the model detects anomalies by analysing whether new data points align with the characteristics of the identified anomaly group.
This review identified analytics techniques, including machine learning, deep learning and statistical modelling, to identify and analyse abnormal behaviour patterns [92]. Fig 10 presents the distribution of analytics techniques in this review. Deep learning: The reviewed articles identify deep learning as the most extensively applied technique, referenced in 10 studies. Of these, seven use supervised learning [1], [5], [8], [20], [21], [28], [30], two use unsupervised learning [3], [12], and one employs a semi-supervised approach [2]. Except for [5], [21], and [30], the reviewed deep learning methods demonstrate significant potential in addressing complex tasks. These tasks include processing unstructured data such as graphs, text, and audio [1], [8], [20], [28]. These techniques also decrease reliance on human intervention such as data labelling and model optimisation, and improve the accuracy of predictions for previously unknown suspicious points [2], [3]. For instance, [2] employs a semi-supervised learning, training a Graph Neural Network (GNN) with labelled anomalous nodes. The GNN then infers additional suspicious nodes based on similarities within anomalous communities. Similarly, [3] employs unsupervised learning, such as clustering, DeepWalk, and probability-based models, to identify anomalous node groups and predict additional suspicious points.
Machine learning: Machine learning is the second most widely used technique, featured in 9 articles [4], [6], [7], [9], [16], [17], [21], [29], [30]. All machine learning methods employ supervised learning, which involves human input to label users as either legitimate or malicious. Support Vector Machine (SVM) is the most commonly used algorithm, known for its high accuracy in detecting anomalies [4], [6], [16], [17], [29]. Random Forest is the second most widely applied algorithm, also demonstrating strong performance [4], [16], [17], [29]. The reviewed articles suggest that machine learning models are particularly effective at classification tasks, with notable success in establishing behavioural baselines and detecting anomalies (Appendix Appendix B ).
Statistical modelling: Two articles employ statistical modelling to detect anomalous users, through statistical methods and distribution-based analysis. [35] utilises the F-test to define a baseline, represented by a behaviour feature matrix derived from social features. The F-test is then applied to evaluate new user data and determine the presence of anomalous behaviour. In contrast, [39] adopts probabilistic modelling, constructing user profiles through the Gaussian Process Model. This method constructs a covariance matrix to predict the likelihood of new data points within the learned distribution. Statistical modelling effectively uncovers anomalies unnoticed by humans and performs well with limited samples and features [35], [39].
A use case represents a specific scenario or problem that a method is designed to address such as detecting fraud. User behaviour anomaly detection is applied to defend against various identity fraud cases. Among the reviewed articles, account takeovers are the most frequently addressed use case with 11 articles on this topic [4], [5], [6], [7], [9], [20], [28], [29], [30], [35], [39], followed by organised crime [1], [2], [3], [12] and bot accounts [16],[17],[21], while scam detection is the least discussed [8].
The open challenges in user behaviour anomaly detection reveal a complex interplay of technical and non-technical factors, with non-technical issues, such as changing user behaviour and data privacy regulations, being the most frequently highlighted. Key technical challenges include the limited diversity of datasets and the lack of transferability of techniques to real-world use cases. The following section elaborates on these challenges derived from TABLE 14 : 4. Practical Deployment, Analysis & Case Studies Dynamic user behaviour, shaped by factors such as changing life events, priorities, and preferences, introduces significant variability that impacts the detection accuracy of methods [28], [29], [30]. [35], [39]. Consequently, anomalies in data do not necessarily indicate actual abnormal behaviour. As noted in [3], detected anomalies may include cases involving normal users. To mitigate this issue, incorporating expert opinions and business-specific rules has been suggested in [3] and [7] to refine models and reduce false positives.
Threshold misconfiguration is a frequently cited challenge affecting accuracy. While the rules outlined in [3] and [7] effectively distinguish normal users from anomalies, improper threshold settings can still lead to false negatives or false positives. Achieving an optimal balance in rule configuration remains a critical challenge, as it directly impacts detection performance and system reliability.
Restricted access to privacy data and user consent emerge as two key highlights identified in the review. Studies such as [3], [7], and [28] have raised concerns about accessing private user data for training purposes. Additionally, [5] and [9] discuss the impact of user consent policies on model performance and validation, particularly when users withdraw their data after training, posing challenges to both compliance and model reliability.
Inconsistent performance across diverse datasets is a frequently observed issue, particularly in cases involving imbalanced datasets [29], [8]. This challenge is further compounded by the scarcity of labelled true fraud cases in user behaviour anomaly detection, which limits the model’s ability to learn and generalise suspicious features due to insufficient data representation [8]. Additionally, studies such as [1], [20], and [35] identify challenges associated with real-time datasets and datasets tailored to varying use cases. For instance, while some methods effectively detect shared device relationships, they often lack sensitivity to subtle anomalies in individual behavioural characteristics. These findings highlight the difficulties in achieving consistent and reliable performance across diverse and dynamic datasets.
Technique complexity is a significant factor impacting method effectiveness, particularly for those requiring intricate data processing and modelling [39], [20], [4], [6]. For instance, [39] describes a method that processes multiple sources of sensor data through unification, sequence conversion, and subsequent model training and classification. This multi-step pipeline is resource-intensive and poorly suited for large-scale datasets, creating significant barriers to real-time applications.
TABLE 12 summarises the articles on user behaviour anomaly detection. TABLE 13 summarises the three methods at each phase of the analysis, detailing the data type, application, applied context, and their advantages and disadvantages. Appendix Appendix B summarises AI’s application and presents the performance metrics of the best models identified across all methods.
This section addresses the research questions by analysing the findings and their broader implications. It explores how the results contribute to understanding the topic, suggests directions for future research and identifies the limitations of this review. This section addresses the research questions by summarising the key findings derived from the analysis. Each research question is discussed individually to ensure clarity and relevance.
Given the impact of authentication and continuous authentication on combating identity fraud, this SLR carefully selected and reviewed 43 articles that applied AI-based methods to detect and prevent identity fraud in the two authentication processes. There is a noticeable increase in the number of articles that use AI-based methods to address identity fraud for the two authentication processes, as in Fig 11 .
In biometric recognition, facial recognition has emerged as the most discussed and extensively utilised biometric method in this field. Its application in secure access systems and mobile device authentication is driven by its ability to offer high accuracy and ease of use [27], [41]. The increasing deployment of facial recognition systems presents critical challenges, particularly in the areas of privacy and security. Among these, biometric spoofing and deepfake attacks are the most significant threats (Fig 12 ). Simultaneously, the emergence of GAI technologies has further accelerated the evolution of fraud techniques [23], [37],[40]. This rapid advancement has likely driven intensified research efforts to address these risks.
Moreover, it underlines the urgency of developing resilient solutions to ensure the trustworthiness and long-term sustainability of these technologies. Fig 12 shows the yearly trend in articles on face recognition, categorised by the research problem they addressed. Continuous authentication has become increasingly important after initial authentication to combat identity fraud on a broader scale[28] (See Fig 11 ). Communication patterns have gained increasing recognition as a crucial component in user behaviour anomaly detection, now on par with conventional factors such as device interactions, social features, and transaction history for user profile creation (See Fig 9 ). This growing prominence aligns with advancements in GAI, which have significantly improved their ability to interpret and analyse semantic content. Consequently, contextual data analysis is becoming a valuable approach for assessing user identity. For instance, [28] illustrated that unique writing styles, influenced by personal background and education, offer distinguishing characteristics that reinforce the utility of communication patterns in continuous authentication.
Deep learning has emerged as a dominant technology across various methods in identity fraud detection, including biometric recognition, visual anomaly detection and user behaviour anomaly detection. This progress is particularly evident in the application of CNNs, which excel at detecting subtle visual irregularities [15],[18], [25], [32], 37], [40], and GNNs, which effectively model user relational profiles using graph-based representations[1-3], [12]. These developments highlight deep learning’s exceptional ability to process complex data modalities such as images, graphs, and text, and to automate complex detection tasks with minimal human intervention. Such capabilities position deep learning as a cornerstone for future innovations in identity fraud detection systems. However, this wide applicability is not without challenges. One significant limitation is the dependence on large-scale and diverse annotated datasets, particularly in areas like user behaviour analysis, where labelled data are scarce and expensive to obtain[10],[11]. Moreover, the high computational requirements of deep learning models often hinder their deployment in environments with limited resources such as mobile devices operating in real-time scenarios[13].
The results of this research indicate that certain challenges are repeatedly mentioned in the literature. The findings emphasise the need to address these recurring challenges to advance research and improve practical implementations. A significant challenge in this field lies in overcoming technical limitations that hinder the performance of current methods (See TABLE 6 ).
Robustness: The lack of diverse data samples is the primary technical challenge for IDF detection methods. These methods often struggle to detect inputs outside the learned patterns. Resilience: The limited transferability of techniques is the second major challenge. This suggests that while current AI methods perform well on familiar patterns, their performance significantly declines when applied to unfamiliar scenarios, such as dynamic or real-world environments. These challenges underscore the need for more robust and adaptable approaches to address the evolving nature of identity fraud.
Accuracy: Data quality is critical for the accuracy of IDF detection methods. Challenges arise from noisy samples and inadequate preprocessing techniques. Addressing these issues requires diverse data sampling strategies that capture real-world variations, such as environmental conditions and device characteristics. Metadata collected during sampling can support targeted corrections during preprocessing.
Effectiveness: Lengthy training times represent a major challenge in terms of method effectiveness, particularly in deep learning-based approaches. The computational demands of these models often result in extended training durations, which can hinder their scalability and applicability in real-time or resource-constrained environments. These limitations reinforce the need for more efficient model architectures and training algorithms to optimise performance.
Although significant research has been conducted on identity fraud, the understanding of its complex dynamics and mechanisms remains limited. One of the primary challenges is the continuous evolution of fraud tactics driven by advancing fraudulent technologies and emerging real-world threats, such as the rise of GAI. Business data from companies can assist in identifying suspicious patterns and labelling data for machine learning; however, this often occurs after fraud has already taken place. When new patterns emerge, models frequently struggle to make accurate predictions or adapt to novel situations.
Dynamic user behaviours further complicate the issue. As user behaviour constantly evolves, baseline patterns established by these methods may no longer hold true. Additionally, anomalies identified by detection systems do not always indicate actual fraud. Further analysis is often required to distinguish true fraud from benign outliers [3], [7]. Data privacy and security remain critical in identity fraud detection. Data privacy regulation has restricted the use of privacy data, which is essential for good model performance.
Although data encryption techniques have been applied for years, encrypted data will comprise the model performance to find meaningful information from the data, especially in today’s context, where contextual data are used by an increasing number of researchers [28]. The challenge extends to protecting private data stored in centralised databases, a common practice among many organisations [9]. Centralised storage increases the risk of identity theft, especially when AI models rely on such data for training. Though federated Learning is effective in some cases, it’s not always a viable solution [9]. This is particularly true for global issues like identity fraud, which spans across multiple industries and sectors rather than being confined to a single company. A single method may not address the broader, cross-industry scale of identity fraud.
The challenges outlined in the previous section serve as a foundation for identifying potential research directions. By addressing these challenges, IDF detection can achieve significant advancements in the following areas. The scarcity and homogeneity of data samples, driven by privacy regulations and limited access to real-world scenarios, significantly hinder effective model training. Although synthetic data generated using advanced techniques can increase sample sizes, it often falls short in representing diverse and unforeseen conditions.
This gap highlights the need for more innovative methods to improve both the quality and diversity of data. Research should particularly focus on designing and validating synthetic data approaches that better mimic realistic variations, thus enhancing model robustness and adaptability to the dynamic and evolving nature of identity fraud. Despite progress in understanding identity fraud, current methods rely heavily on post-incident data, limiting their ability to adapt to new and evolving fraud patterns. Future research should focus on developing innovative methods to detect and differentiate suspicious activities from normal behaviors, particularly in the absence of pre-existing fraud patterns or labeled data. Advancing anomaly detection techniques that do not rely on pre-labeled datasets is crucial for enabling models to adapt quickly and effectively to evolving fraud tactics. These efforts will facilitate the development of more robust and proactive fraud detection systems, capable of responding to the dynamic nature of identity fraud.
Ensuring data privacy and security remains a critical issue. Future discussions should address two key questions: How can privacy-preserving methods be implemented during data processing without compromising data utility for analytical purposes? How can data lifecycle management be optimised to address identity fraud at a cross-industry scale while balancing privacy, security, and data utility? 5. Performance Evaluation & Extended Technical Observations Research should emphasise the development of frameworks and tools that uphold data security and compliance while supporting effective fraud detection efforts. These areas highlight the need for interdisciplinary collaboration to create innovative solutions that address the evolving challenges of identity fraud.
As AI’s ability to understand semantics improves, multimodal data have been increasingly utilised in identity fraud detection. Methods employing image data, behavioural data, and time-series data are already well-established; however, context-based detection techniques remain less commonly implemented. Future research should focus on developing effective methods to integrate context-based data, exploring strategies to preserve critical information for model learning, such as temporal or spatial relationships, while ensuring robust privacy measures to protect sensitive user data.
The findings of this SLR highlight the importance of adopting advanced AI-driven methods, such as anomaly detection and behavior modeling, to enhance fraud detection and prevention systems. Adaptive, scalable, and efficient models capable of handling dynamic user behaviours and evolving fraud tactics are essential for both industrial applications and academic advancements. Additionally, there is a pressing need to explore unsupervised learning and robust anomaly detection techniques that do not rely on pre-labelled data. Addressing challenges in data quality, contextual variability, and real-world applicability requires interdisciplinary approaches and stronger collaboration between academia and industry.
Like any other SLR study, this research has limitations that should be considered when interpreting the findings. First, it only relies on four databases, which are limited in number, however they provide sufficient coverage of the existing literature. It is worth mentioning that the review was conducted within a specific time frame, and studies published after this period may not have been included, which potential overlook recent advancements. However, this SLR study provides a solid foundation for future studies by other researchers.
Second, due to the scope of this research, a specific set of search strings was employed, which may have influenced the breadth of the results. While efforts were made to balance specificity and comprehensiveness, it is possible that some relevant studies were omitted due to variations in terminology or indexing practices. Furthermore, the review focuses on the domain of identity fraud detection and may have overlooked insights from adjacent fields such as cybersecurity which could provide valuable complementary perspectives. However, it was important to keep the focus on the identity fraud detection rather a broad SLR across cybersecurity. Here, it is important to mention that research team met regulatory to review the results and discuss any individual research or researcher bias with a view to maintain the study focus and improve the quality of results.
Finally, the rapid pace of advancements in AI and related technologies poses a challenge in maintaining the relevance of the findings. While the review provides a comprehensive snapshot of the field, some trends or methods discussed may already be evolving, which requires future studies to continuously update the state of knowledge. Identity fraud can have significant impacts on individuals and organisations, making it essential to understand and investigate methods for its early detection. AI has demonstrated its potential in various tasks, including computer vision, natural language processing, and graph processing, and our systematic literature review highlights its effectiveness in identity fraud detection.
From our findings, anomaly detection, either on image or behaviour data, is the main method in identity fraud detection. Deep learning has higher capabilities in handling complex scenarios that require the input of various data forms, from images to structured data, while machine learning has higher computation efficiency. Privacy data concerns with the use of AI also require attention to be extracted while implementing identity fraud detection.
Overall, our systematic review highlights the transformative role of AI in combating identity fraud and identifies key areas for future research. We also provide a detailed list of current gaps and unresolved issues to guide future research in this area. Specifically, the next steps include: Mitigating privacy issues to guarantee secure and compliant handling of sensitive data.
Our new plans help you spot threats fast and protect against scams with our 24/7 Virtual Advisor. If you do get scammed, we’ll reimburseI up to $10,000, coverage banks or other providers may not offer. From detection to recovery, we’ve got your back every step of the way. We defend what you’ve worked so hard to build in your life. When you become a victim of identity theft or scams, without LifeLock experts, recovery can be a huge challenge. We fix identity theft or give you your money back, guaranteed. * Your personal information exists across countless databases, accounts, and online systems and any one of which can expose you to identity theft. LifeLock provides proactive monitoring and, if needed, your own US based Restoration Specialist will restore your identity quickly and completely.
Identity thieves use AI to mimic real people and transactions, making fraud harder to spot. LifeLock helps detect unusual activity across all of your connected accounts early and guides you to act fast, so you can catch suspicious transactions and help protect your money. 81 million+ LifeLock Identity Theft Protection alerts and notifications were sent in the past year.
81 million+ LifeLock Identity Theft Protection alerts and notifications were sent in the past year. Real specialists. From start to finish. Providing identity, credit, and financial protection. My husband and I have been members of LifeLock for over 5 years. We appreciate knowing that LifeLock securely monitors our personal information and accounts. It is a relief to know that we will be alerted to any activity in our accounts and properties. The peace of mind that comes with having LifeLock is well worth any cost.
I'm so thankful that I have LifeLock. This company has saved me several times, and continues to monitor my identity, accounts etc. Thank you! Excellent service! LifeLock keeps me informed and protected at all times. Their alerts are fast, accurate, and the support team is fantastic. I feel secure knowing my identity is in safe hands.
As a senior adult, finances and life can be overwhelming at times. It is great to feel safe and protected by LifeLock. There are so many scams and thieves preying on older adults; it is such a comfort to know that LifeLock is watching out for me. Thanks LifeLock! Your service to protect my personal information is awesome! I sleep well at night because of the trust I have in your company!! "The 600-pound gorilla in the ID Protection space, LifeLock has one of the most comprehensive services for preventing an identity theft and if that fails, surviving it." "The 600-pound gorilla in the ID Protection space, LifeLock has one of the most comprehensive services for preventing an identity theft and if that fails, surviving it." Identity fraud costs businesses and consumers billions of dollars every year, and fraud tactics keep shifting faster than most security teams can keep up with. Stolen credentials, synthetic identities, and account takeovers no longer look like the crude attempts of a decade ago. They look like normal customers, right up until the losses show up on a balance sheet.
This is why so many banks, fintechs, insurers, and marketplaces have moved away from static rules and toward identity fraud detection machine learning systems. Instead of checking a transaction against a fixed list of conditions, these models learn what normal behavior looks like for a given user, account, or channel, then flag the activity and patterns that break from it. Below is a plain-language look at how the underlying algorithms actually work, what data and features they rely on, where the approach tends to fall short, and what a realistic fraud prevention stack looks like in 2026.
Identity fraud covers any scheme where a bad actor uses stolen, fabricated, or manipulated personal information to gain access to money, credit, benefits, or services. A few categories show up again and again in fraud analysts' case queues: Each category leaves a slightly different data trail across accounts, devices, and transaction history, which is part of why a single rule engine struggles to catch all of them at scale.
Traditional fraud prevention leaned on rule-based logic. Block a transaction over a certain amount. Flag a login from a new location. Reject an application with a mismatched address. Rules are easy to explain and simple to implement, but fraudsters study the logic behind them and route around it within weeks. Rule-based systems also generate a flood of false positives. A legitimate customer traveling abroad or switching devices can trip the same alerts as an actual criminal, which forces analysts to spend hours clearing accounts that were never at risk. As transaction volume and applications grow, this manual review process becomes a bottleneck that no amount of hiring or added resources can fully solve.
Harvested Online Documentation & Reference Sources • https://arxiv.org/html/2501.09239v1 • https://www.bing.com/aclick?ld=e8BLiuO2eby4T5-64rzOYxUzVUCUwS1lM59biBc23g_7TeCM5s3yOJhX-RcYkaSl4ZRvzc2 oGPYhpOfa7HcEAbKNLTt9KB6x2j2Uc7-yn8QQ9u0uHGQUU9p2hn0i801MN9RLTgg-eyyiqy1OefzmCnI-G5r7LBhrl3IFXHzCu vqeCWP027zdyrxbvWOGoZTXTS7PeSGw&u=aHR0cHMlM2ElMmYlMmZhZC5kb3VibGVjbGljay5uZXQlMmZzZWFyY2hhZH MlMmZsaW5rJTJmY2xpY2slM2ZsaWQlM2Q0MzcwMDA4MTYyOTg5MjE5NyUyNmRzX3Nfa3dnaWQlM2Q1ODcwMDAwOD g2MDcyNjEzMiUyNmRzX2FfY2lkJTNkNDA1NTMwODU1JTI2ZHNfYV9jYWlkJTNkMjIzMjM5NDcyNDQlMjZkc19hX2FnaWQl M2QxNzk4Njk0NjAyODElMjZkc19hX2xpZCUzZGt3ZC0zODIwNTg1NDAxMDAlMjYlMjZkc19lX2FkaWQlM2Q4MTkxMzc2MT A3MTE4NiUyNmRzX2VfdGFyZ2V0X2lkJTNka3dkLTgxOTEzOTc3MTg3NDk3JTNhbG9jLTEyOSUyNiUyNmRzX2VfbmV0d29 yayUzZG8lMjZkc191cmxfdiUzZDIlMjZkc19kZXN0X3VybCUzZGh0dHBzJTNhJTJmJTJmbGlmZWxvY2subm9ydG9uLmNvbS UyZm9mZmVycyUzZmV4cGlkJTNkU0VNLU5CLUlELU5GJTI2b21fc2VtX2NpZCUzZGhob19zZW1fc3klM2ElN2Vlbi11c19sZ mxfbGxrX3NjaF9nZW5fbW10X25mcl9ibmdfbmFkX2xvdyUzYV9sZmtfa3diX2lkZW50aXR5JTdlY19rdzAwMDA3MzYwMjIlMjZ wcm9tb2NvZGUlM2RTRU1MTE5CTkZJREJORyUyNmNxX3NyYyUzZGJpbmdfYWRzJTI2Y3FfY21wJTNkNTU1MzQ0NDA2J TI2Y3FfbmV0JTNkbyUyNmJfY2FtcGFpZ24lM2Rlbi11c19sZmxfbGxrX3NjaF9nZW5fbW10X25mcl9ibmdfbmFkX2xvdyUyNTN BX2xma19rd2JfaWRlbnRpdHklMjZiX2NhbXBhaWduaWQlM2Q1NTUzNDQ0MDYlMjZiX2FkZ3JvdXAlM2RJZGVudGl0eSUyN TIwVGhlZnQlMjUyMC0lMjUyMENoZWNrJTI1MjAtJTI1MjBIb3clMjUyMHRvJTI2Yl9hZGdyb3VwaWQlM2QxMzEwNjE5MDY5 MTMzNzkwJTI2Yl9hZGlkJTNkODE5MTM3NjEwNzExODYlMjZiX3Rlcm0lM2RpZCUyNTIwaWRlbnRpdHklMjUyMHRoZWZ0J TI2Yl90ZXJtaWQlM2Rrd2QtODE5MTM5NzcxODc0OTclM2Fsb2MtMTI5JTI2Yl9pc3Byb2R1Y3QlM2QlMjZiX3Byb2R1Y3RpZ CUzZCUyNmdjbGlkJTNkMjMyMjNlYjE5ODc4MTk2NDk4MmE1NDY1NzA2NzYyMjAlMjZnY2xzcmMlM2QzcC5kcyUyNiUyNm 1zY2xraWQlM2QyMzIyM2ViMTk4NzgxOTY0OTgyYTU0NjU3MDY3NjIyMA&rlid=23223eb198781964982a546570676220 • https://www.docklands.ai/blog/identity-fraud-detection
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Identity Theft Detection Using Machine Learning.
[*] Metasploit Scan Running on Target Subnet for Identity Theft Detection Using Machine Learning... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |