Complete Technical Paper Content — Insecure Direct Object Reference Detection Tool Project
Overview & System Context
Insecure Direct Object Reference Detection Tool Project: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9552 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Memory safety is the state of being protected from various software bugs and security vulnerabilities when dealing with memory access, such as buffer overflows and dangling pointers. For example, Java is memory-safe because its runtime error detection checks array bounds and pointer dereferences. By contrast, programming languages like C, C++, and Fortran allow arbitrary pointer arithmetic with pointers implemented as direct memory addresses with no provision for bounds checking, making them memory-unsafe. Memory-unsafe code is typically found in low level programming, with higher level programming languages generally incorporating either garbage collection or static analysis (as in Rust) to prevent such errors.
Spatial Buffer overflow – out-of-bound writes can corrupt the content of adjacent objects, or internal data (like bookkeeping information for the heap) or return addresses. Buffer over-read – out-of-bound reads can reveal sensitive data or help attackers bypass address space layout randomization. Temporal Use after free – dereferencing a dangling pointer storing the address of an object that has been deleted. Double free – repeated calls to free may prematurely free a new object at the same address. If the exact address has not been reused, other corruption may occur, especially in allocators that use free lists. Uninitialized variables – a variable that has not been assigned a value is used. It may contain sensitive information or bits that are not valid for the type. Wild pointers arise when a pointer is used prior to initialization to some known state. They show the same erratic behaviour as dangling pointers, though they are less likely to stay undetected. Invalid free – passing an invalid address to free can corrupt the heap. Mismatched free – when multiple allocators are in use, attempting to free memory with a deallocation function of a different allocator. Spatiotemporal Struct tearing or non-atomic reads may be observed when data larger than the cpu word size is read from memory.
Stack exhaustion – occurs when a program runs out of stack space, typically because of too deep recursion. A guard page typically halts the program, preventing memory corruption, but functions with large stack frames may bypass the page, and kernel code may not have the benefit of guard pages. Heap exhaustion – the program tries to allocate more memory than the amount available. In some languages, this condition must be checked for manually after each allocation. Memory leak – Failing to return memory to the allocator may set the stage for heap exhaustion (above). Failing to run the destructor of an RAII object may lead to unexpected results. Null pointer dereference – A null pointer dereference will often cause an exception or program termination in most environments, but can cause corruption in operating system kernels or systems without memory protection or when use of the null pointer involves a large or negative offset. In C++, because dereferencing a null pointer is undefined behavior, compiler optimizations may cause other checks to be removed, leading to vulnerabilities elsewhere in the code. Some lists may also include race conditions (concurrent reads/writes to shared memory) as being part of memory safety (e.g., for access control). The Rust programming language prevents many kinds of memory-based race conditions by default, because it ensures there is at most one writer or one or more readers. Many other programming languages, such as Java, do not automatically prevent memory-based race conditions, yet are still generally considered "memory safe" languages. Therefore, countering race conditions is generally not considered necessary for a language to be considered memory safe.
BoundWarden, a new spatial memory enforcement approach that utilizes a combination of compile-time transformation and runtime concurrent monitoring techniques. Capability Hardware Enhanced RISC Instructions (CHERI), which replaces ordinary pointers with a longer value that not only encodes the address, but also the memory bounds and permissions. FORTIFY_SOURCE, a lightweight but weak form of runtime error detection on known-vulnerable C standard library functions usable by LLVM and GCC when using compatible header files (such as those from glibc). Other lightweight methods such as stack canary checking (specifically for stack overflows), ASLR (provides only probabilistic protection against memory errors, but can often be easily implemented in existing software by relinking the binary). Fuzz testing tries to explore all the code-paths found in a program. It is well-suited for finding memory safety bugs, especially when used in combination with dynamic checkers such as AddressSanitizer.
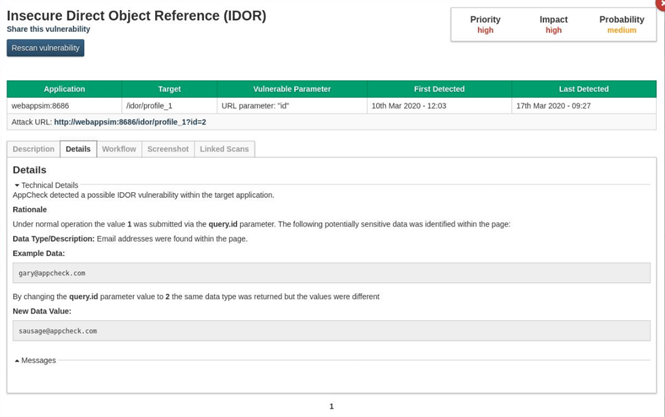
Figure 1: Insecure Direct Object Reference In computer science, a pointer is an object in many programming languages that stores a memory address. This can be that of another value located in computer memory, or in some cases, that of memory-mapped computer hardware. A pointer references a location in memory, and obtaining the value stored at that location is known as dereferencing the pointer. As an analogy, a page number in a book's index could be considered a pointer to the corresponding page; dereferencing such a pointer would be done by flipping to the page with the given page number and reading the text found on that page. The actual format and content of a pointer variable is dependent on the underlying computer architecture. Using pointers significantly improves performance for repetitive operations, like traversing iterable data structures (e.g. strings, lookup tables, control tables, linked lists, and tree structures). In particular, it is often much cheaper in time and space to copy and dereference pointers than it is to copy and access the data to which the pointers point. Pointers are also used to hold the addresses of entry points for called subroutines in procedural programming and for run-time linking to dynamic link libraries (DLLs). In object-oriented programming, pointers to functions are used for binding methods, often using virtual method tables. A pointer is a simple, more concrete implementation of the more abstract reference data type. Several languages, especially low-level languages, support some type of pointer, although some have more restrictions on their use than others. While "pointer" has been used to refer to references in general, it more properly applies to data structures whose interface explicitly allows the pointer to be manipulated (arithmetically via pointer arithmetic) as a memory address, as opposed to a magic cookie or capability which does not allow such. Because pointers allow both protected and unprotected access to memory addresses, there are risks associated with using them, particularly in the latter case. Primitive pointers are often stored in a format similar to an integer; however, attempting to dereference or "look up" such a pointer whose value is not a valid memory address could cause a program to crash (or contain invalid data). To alleviate this potential problem, as a matter of type safety, pointers are considered a separate type parameterized by the type of data they point to, even if the underlying representation is an integer.
Other measures may also be taken (such as validation and bounds checking), to verify that the pointer variable contains a value that is both a valid memory address and within the numerical range that the processor is capable of addressing. This declares a variable ptr that stores a pointer to an object of type int. Other types can be used in place of int; for example, bool *ptr would declare a pointer to an object of type bool. After a pointer has been declared, it can be assigned an address. In C, the address of a variable can be retrieved with the & unary operator: int *ptr;, which emphasises that the expression *ptr has type int. int* ptr;, which emphasises that ptr has type int*. This style is more prevalent in C++ than C. Both int *x, y; and int* x, y; declare x to be a pointer to int, but declare y to be an int. This is because the * applies only to the variable immediately following it. The asterisk can also be used on the left-hand side of an assignment to change the object a without having to be in the same scope.
If a is accessed later, its new value will be 8. Because the C language does not specify an implicit initialization for objects of automatic storage duration, pointer variables can sometimes point to unexpected locations, causing undefined behavior. To combat this, pointers are sometimes initialized with a null pointer value, represented in C by the NULL macro; in C23 and later, nullptr is also available as an alternative, which is of type nullptr_t.
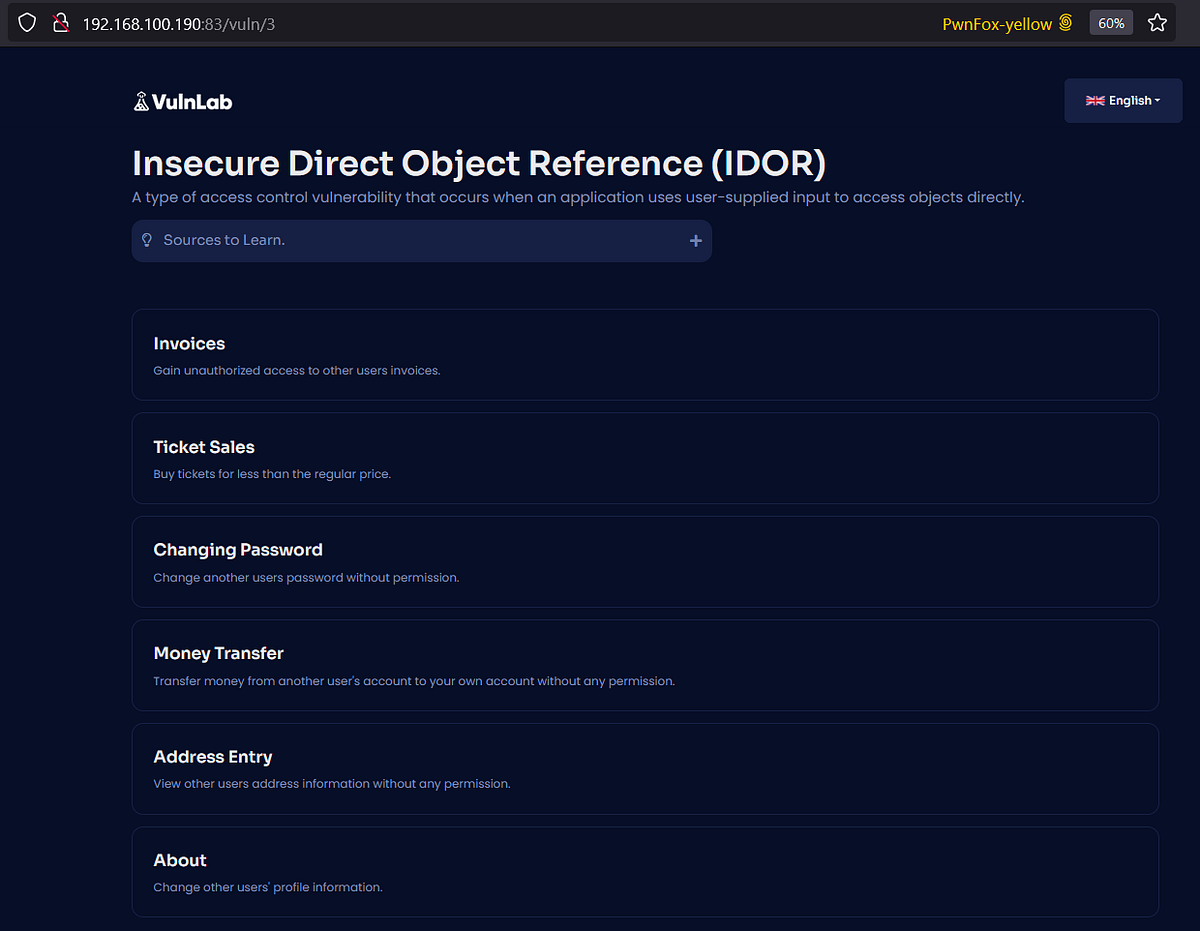
Figure 2: VulnLab: Insecure Direct Object Reference (IDOR) - Yogasatriautama - Medium Dereferencing a null pointer produces undefined behavior, which can result in unpredictable bugs and results. This example may be clearer if memory is examined directly. Assume that a is located at address 0x8130 in memory and ptr at 0x8134; also assume this is a 32-bit machine such that an int is 32-bits wide. The following is what would be in memory after the following code snippet is executed: the computer will take the contents of ptr (which is 0x8130), 'locate' that address, and assign 8 to that location yielding the following memory: Clearly, accessing a will yield the value of 8 because the previous instruction modified the contents of a by way of the pointer ptr.
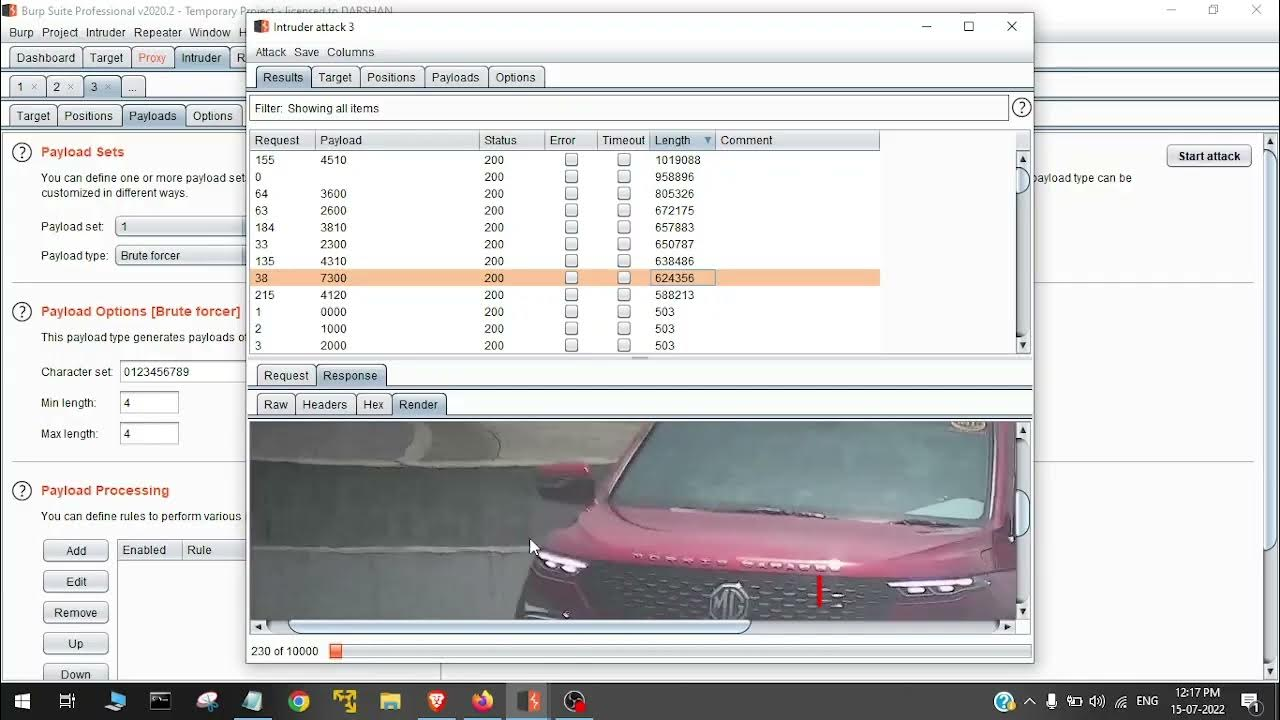
This allocates a block of five integers and names the block a; the expression a evaluates, in most contexts, as a pointer to the first element of the block. Another common use of pointers is to point to dynamically allocated memory from malloc which returns a consecutive block of memory of no less than the requested size that can be used as an array. While, when used as an operand for most operators, an array evaluates as a pointer to the first element of the array, this is not the case for the sizeof operator. In this example, sizeof(a) will evaluate to 5 * sizeof(int) (the size of the array), while sizeof(ptr) will evaluate to sizeof(int *), the size of the pointer itself. Default values of an array can be declared like: Figure 3: IDOR (Insecure Direct Object Reference) - YouTube If a is located in memory starting at address 0x1000 on a 32-bit little-endian machine then memory will contain the following (values are in hexadecimal, like the addresses): Represented here are five integers: 2, 4, 3, 1, and 5. These five integers occupy 32 bits (4 bytes) each with the least-significant byte stored first (this is a little-endian CPU architecture) and are stored consecutively starting at address 0x1000. The syntax for C with pointers is: a means 0x1000; a + 1 means 0x1004: the "+ 1" means to add the size of 1 int, which is 4 bytes; *a means to dereference the contents of a. Considering the contents as a memory address (0x1000), look up the value at that location (0x0002); a[i] means element number i, 0-based, of a which is translated into *(a + i). The last example is how to access the contents of a. Breaking it down: a + i is the memory location of the ith element of a, starting at i = 0; *(a + i) takes that memory address and dereferences it to access the value.
This pointer-recursive definition is essentially the same as the reference-recursive definition from the language Haskell: where Nil is the empty list, and Cons a (LinkedList a) is a cons cell of type a with another link also of type a. The definition with references, however, is type-checked and does not use potentially confusing signal values. For this reason, data structures in C are usually dealt with via wrapper functions, which are carefully checked for correctness.
The code below illustrates how memory objects are dynamically deallocated, i.e., returned to the heap or free store. The standard C library provides the function free() for deallocating a previously allocated memory block and returning it back to the heap. In the mid-1980s, using the BIOS to access the video capabilities of PCs was slow. Applications that were display-intensive typically used to access CGA video memory directly by casting the hexadecimal constant 0xB8000 to a pointer to an array of 80 unsigned 16-bit int values. Each value consisted of an ASCII code in the low byte, and a colour in the high byte. Thus, to put the letter 'A' at row 5, column 2 in bright white on blue, one would write code like the following: Control tables that are used to control program flow usually make extensive use of pointers. The pointers, usually embedded in a table entry, may, for instance, be used to hold the entry points to subroutines to be executed, based on certain conditions defined in the same table entry. The pointers can however be simply indexes to other separate, but associated, tables comprising an array of the actual addresses or the addresses themselves (depending upon the programming language constructs available). They can also be used to point to earlier table entries (as in loop processing) or forward to skip some table entries (as in a switch or "early" exit from a loop). For this latter purpose, the "pointer" may simply be the table entry number itself and can be transformed into an actual address by simple arithmetic.
money would be an integer pointer and bags would be a char pointer. The following would yield a compiler warning of "assignment from incompatible pointer type" under GCC: because money and bags were declared with different types. To suppress the compiler warning, it must be made explicit to make the assignment by typecasting it: which says to cast the integer pointer of money to a char pointer and assign to bags. A 2005 draft of the C standard requires that casting a pointer derived from one type to one of another type should maintain the alignment correctness for both types (6.3.2.3 Pointers, par. 7): In languages that allow pointer arithmetic, arithmetic on pointers takes into account the size of the type. For example, adding an integer number to a pointer produces another pointer that points to an address that is higher by that number times the size of the type. This allows us to easily compute the address of elements of an array of a given type, as was shown in the C arrays example above. When a pointer of one type is cast to another type of a different size, the programmer should expect that pointer arithmetic will be calculated differently. In C, for example, if the money array starts at 0x2000 and sizeof(int) is 4 bytes whereas sizeof(char) is 1 byte, then money + 1 will point to 0x2004, but bags + 1 would point to 0x2001. Other risks of casting include loss of data when "wide" data is written to "narrow" locations (e.g. bags[0] = 65537;), unexpected results when bit-shifting values, and comparison problems, especially with signed vs unsigned values. Although it is impossible in general to determine at compile-time which casts are safe, some languages store run-time type information which can be used to confirm that these dangerous casts are valid at runtime. Other languages merely accept a conservative approximation of safe casts, or none at all.
In C++ the iterator can overload operator++, similar to the traditional syntax of incrementing a pointer in C. A custom-defined iterator traditionally overloads three operators: Some languages, like C++, support smart pointers, which use a simple form of reference counting to help track allocation of dynamic memory in addition to acting as a reference. In the absence of reference cycles, where an object refers to itself indirectly through a sequence of smart pointers, these eliminate the possibility of dangling pointers and memory leaks. Delphi strings support reference counting natively. The Rust programming language introduces a borrow checker, pointer lifetimes, and an optimisation based around option types for null pointers to eliminate pointer bugs, without resorting to garbage collection.
A null pointer has a value reserved for indicating that the pointer does not refer to a valid object. Null pointers are routinely used to represent conditions such as the end of a list of unknown length or the failure to perform some action; this use of null pointers can be compared to nullable types and to the Nothing value in an option type. A dangling pointer is a pointer that does not point to a valid object and consequently may make a program crash or behave oddly. In the Pascal or C programming languages, pointers that are not specifically initialized may point to unpredictable addresses in memory. The following example code shows a dangling pointer: Here, p2 may point to anywhere in memory, so performing the assignment *p2 = 'b'; can corrupt an unknown area of memory or trigger a segmentation fault.
to mean an offset from the address of a structure rather than from the address of the pointer itself; to mean a pointer containing its own address, which can be useful for reconstructing in any arbitrary region of memory a collection of data structures that point to each other. This implementation uses a pointer to the first element in the list as a surrogate for the entire list. If a new value is added to the beginning of the list, head has to be changed to point to the new element. Since C arguments are always passed by value, using double indirection allows the insertion to be implemented correctly, and has the desirable side-effect of eliminating special case code to deal with insertions at the front of the list: In this case, if the value of item is less than that of head, the caller's head is properly updated to the address of the new item.
A basic example is in the argv argument to the main function in C (and C++), which is given in the prototype as char **argv (or char *argv[])—this is because the variable argv itself is a pointer to an array of strings (an array of arrays), so *argv is a pointer to the 0th string (by convention the name of the program), and **argv is the 0th character of the 0th string. std::unique_ptr (represents unique ownership of a resource, cannot be copied but can be moved) std::shared_ptr (represents shared ownership of a resource, resource is only deleted once the last shared pointer is destroyed or reset) std::weak_ptr (represents no ownership, can point to a shared pointer's resources without incrementing the reference count) std::hazard_pointer (single-writer multi-reader pointer that may be owned by at most one thread at any point of time) std::unique_ptr replaces the previous smart pointer std::auto_ptr, which was deprecated in C++11 and removed in C++17. In contrast to C, C++ does not allow the implicit conversion of void* to other pointer types, even in assignments. This was a design decision to avoid careless and even unintended casts, though most compilers only output warnings, not errors, when encountering other casts.
In C++, there is no void& (reference to void) to complement void* (pointer to void), because references behave like aliases to the variables they point to, and there can never be a variable whose type is void. 2. System Architecture & Core Working Principles The .NET framework includes many classes and methods in the System and System.Runtime.InteropServices namespaces (such as the Marshal class) which convert .NET types (for example, System.String) to and from many unmanaged types and pointers (for example, LPWSTR or void*) to allow communication with unmanaged code. Most such methods have the same security permission requirements as unmanaged code, since they can affect arbitrary places in memory. C# allows stack-allocated arrays in safe code using System.Span.
C#, like C and C++, also has a void* (void pointer) type, but it is highly unrecommended. Unlike C and C++, right-aligned asterisks are not accepted by the compiler. For example: In C and C++, this would declare a as int* and b as int, but in C# this declares both variables as int*. Fortran-2003 adds support for procedure pointers. Also, as part of the C Interoperability feature, Fortran-2003 supports intrinsic functions for converting C-style pointers into Fortran pointers and back.
Line 2 shows the creation of a new type months and creates named constants of the months of the year. Line 3 defines a pointer to a record type. Lines 4-10 define that record. Lines 12-15 define the pointer variables; line 13 defines a pointer to a scalar and lines 14-15 create a linked list. Line 18 allocates memory through the new function, and stores the address of that memory to the variable calendar. Lines 19-23 initialize a linked list. Line 26 shows assignment to the memory pointed to by the pointer that. Lines 28 to 31 show the creation of a new link in the linked list. Lines 33-35 release the memory allocated to those pointers.
std::boxed::Box: equivalent to C++'s std::unique_ptr std::rc::Rc: equivalent to a reference-counted single-threaded shared pointer std::sync::Arc: equivalent to an atomically reference-counted thread safe shared pointer std::rc::Weak: equivalent to C++'s std::weak_ptr A pointer to T is written as *const T or *mut T in Rust. The following demonstrates raw pointers in Rust: PL/I List Processing Paper from the June 1967 issue of CACM cdecl.org A tool to convert pointer declarations to plain English Over IQ.com A beginner level guide describing pointers in a plain English. Pointers and Memory Introduction to pointers – Stanford Computer Science Education Library Pointers in C programming Archived 2019-06-09 at the Wayback Machine A visual model for beginner C programmiers 0pointer.de A terse list of minimum length source codes that dereference a null pointer in several different programming languages "The C book" – containing pointer examples in ANSI C Joint Technical Committee ISO/IEC JTC 1, Subcommittee SC 22, Working Group WG 14 (2007-09-08). International Standard ISO/IEC 9899 (PDF).{{cite book}}: CS1 maint: multiple names: authors list (link) CS1 maint: numeric names: authors list (link) Committee draft.
Antivirus software (abbreviated to AV software), also known as anti-malware, is software intended to prevent, detect, and remove malware. Antivirus software was originally developed to detect and remove computer viruses, hence the name. However, with the proliferation of other malware, antivirus software started to protect against other computer threats. Some products also include protection from malicious URLs, spam, and phishing.
Powerful macros used in word processor applications, such as Microsoft Word, presented a risk. Virus writers could use the macros to write viruses embedded within documents. This meant that computers could now also be at risk from infection by opening documents with hidden attached macros. The possibility of embedding executable objects inside otherwise non-executable file formats can make opening those files a risk. Later email programs, in particular Microsoft's Outlook Express and Outlook, were vulnerable to viruses embedded in the email body itself. A user's computer could be infected by just opening or previewing a message. In 2005, F-Secure was the first security firm that developed an Anti-Rootkit technology, called BlackLight. Because most users are usually connected to the Internet on a continual basis, Jon Oberheide first proposed a Cloud-based antivirus design in 2008. In February 2008 McAfee Labs added the industry-first cloud-based anti-malware functionality to VirusScan under the name Artemis. It was tested by AV-Comparatives in February 2008 and officially unveiled in August 2008 in McAfee VirusScan. Cloud AV created problems for comparative testing of security software – part of the AV definitions was out of testers control (on constantly updated AV company servers) thus making results non-repeatable. As a result, Anti-Malware Testing Standards Organisation (AMTSO) started working on method of testing cloud products which was adopted on May 7, 2009. In 2011, AVG introduced a similar cloud service, called Protective Cloud Technology.
Sandbox detection: a particular behavioural-based detection technique that, instead of detecting the behavioural fingerprint at run time, it executes the programs in a virtual environment, logging what actions the program performs. Depending on the actions logged which can include memory usage and network accesses, the antivirus engine can determine if the program is malicious or not. If not, then, the program is executed in the real environment. Although this technique has shown to be quite effective, given its heaviness and slowness, it is rarely used in end-user antivirus solutions. Data mining techniques: one of the latest approaches applied in malware detection. Data mining and machine learning algorithms are used to try to classify the behaviour of a file (as either malicious or benign) given a series of file features, that are extracted from the file itself.
Anti-virus software can attempt to scan for rootkits. A rootkit is a type of malware designed to gain administrative-level control over a computer system without being detected. Rootkits can change how the operating system functions and in some cases can tamper with the anti-virus program and render it ineffective. Rootkits are also difficult to remove, in some cases requiring a complete re-installation of the operating system.
Some apparent antivirus programs are actually malware masquerading as legitimate software, such as WinFixer, MS Antivirus, and Mac Defender. May 2007: a faulty virus signature issued by Symantec mistakenly removed essential operating system files, leaving thousands of PCs unable to boot. May 2007: the executable file required by Pegasus Mail on Windows was falsely detected by Norton AntiVirus as being a Trojan and it was automatically removed, preventing Pegasus Mail from running. Norton AntiVirus had falsely identified three releases of Pegasus Mail as malware, and would delete the Pegasus Mail installer file when that happened. In response to this Pegasus Mail stated: On the basis that Norton/Symantec has done this for every one of the last three releases of Pegasus Mail, we can only condemn this product as too flawed to use, and recommend in the strongest terms that our users cease using it in favour of alternative, less buggy anti-virus packages. April 2010: McAfee VirusScan detected svchost.exe, a normal Windows binary, as a virus on machines running Windows XP with Service Pack 3, causing a reboot loop and loss of all network access. December 2010: a faulty update on the AVG anti-virus suite damaged 64-bit versions of Windows 7, rendering it unable to boot, due to an endless boot loop created. October 2011: Microsoft Security Essentials (MSE) removed the Google Chrome web browser, rival to Microsoft's own Internet Explorer. MSE flagged Chrome as a Zbot banking trojan. September 2012: Sophos' anti-virus suite identified various update-mechanisms, including its own, as malware. If it was configured to automatically delete detected files, Sophos Antivirus could render itself unable to update and required manual intervention to fix the problem. September 2017: the Google Play Protect anti-virus started identifying Motorola's Moto G4 Bluetooth application as malware, causing Bluetooth functionality to become disabled.
September 2022: Microsoft Defender flagged all Chromium based web browsers and Electron based apps like WhatsApp, Discord, Spotify as a severe threat. It's something that they miss a lot of the time because this type of [ransomware virus] comes from sites that use a polymorphism, which means they basically randomize the file they send you and it gets by well-known antivirus products very easily. I've seen people firsthand getting infected, having all the pop-ups and yet they have antivirus software running and it's not detecting anything. It actually can be pretty hard to get rid of, as well, and you're never really sure if it's really gone. When we see something like that usually we advise to reinstall the operating system or reinstall backups. A proof of concept virus has used the Graphics Processing Unit (GPU) to avoid detection from anti-virus software. The potential success of this involves bypassing the CPU in order to make it much harder for security researchers to analyse the inner workings of such malware.
Antivirus software running on individual computers is the most common method employed of guarding against malware, but it is not the only solution. Other solutions can also be employed by users, including Unified Threat Management (UTM), hardware and network firewalls, Cloud-based antivirus, online scanners, and Content Disarm & Reconstruction (CDR). Virus removal tools are available to help remove stubborn infections or a certain type of infection. Examples include Windows Malicious Software Removal Tool, Kaspersky Virus Removal Tool, and Sophos Scan & Clean. It is also worth noting that sometimes antivirus software can produce a false-positive result, indicating an infection where there is none. A rescue disk that is bootable, such as a CD or USB storage device, can be used to run antivirus software outside of the installed operating system in order to remove infections while they are dormant. A bootable rescue disk can be useful when, for example, the installed operating system is no longer bootable or has malware that is resisting all attempts to be removed by the installed antivirus software. Examples of software that can be used on a bootable rescue disk include the Kaspersky Rescue Disk, Trend Micro Rescue Disk, and Comodo Rescue Disk.
Insecure Direct Object Reference (IDOR) is a vulnerability that allows an attacker to exploit insufficient access control and insecure exposure of object identifiers, such as database keys or file paths. However, as well as checking that the request came from an authenticated user, the server must implement access control for the resources that the user requests: that is, they must check that this user is allowed to access the specific resource requested. For example, each authenticated user must only be allowed to see their own purchase history.
If a server does not implement access control for resources, then an attacker who is signed into the site may be able to access the resources belonging to a different user. This is called an Insecure Direct Object Reference (IDOR) attack. The classic IDOR attack happens when the server only checks that the user is authenticated, but not whether they are authorized to access an object reference. In a typical flow, the attacker: A common type of IDOR attack involves manipulation of direct object references in the URL. The "1234" in the following URLs is an identifier for the user's record in the server's database. If an attacker changes this number to any other number (say "1235") and gains access to another user's information, your application is vulnerable to Insecure Direct Object Reference.
For example, in the Express code below, the value given in the URL is available as req.params.id , and we use that value to retrieve the corresponding record in the database. We also check that the request is from an authenticated user, by (calling the isAuthenticated function). But critically, we don't check that the ID of the authenticated user matches the ID in the URL, and this enables one authenticated user (the attacker) to get a page for a different authenticated user (the victim).
Instead, you should implement rules to authorize access to user information. For example, only render the user page if the logged-in user id matches with the requested user id. Otherwise return an HTTP 401 Unauthorized response. Similar to URL tampering, the document body of a page can be manipulated by an attacker by modifying values of
A special case of IDOR attacks is access to files or directories that aren't protected by access control. For example, if you provide a folder for PDF file uploads and the uploads get named sequentially, an attacker can guess the filenames and download them all if no access control is provided. Potentially, other files in unprotected directories, such as server configuration files, can be obtained as well which could lead to additional vulnerabilities.
The most important mitigation for IDOR attacks is to implement server-side access control checks for each object that users try to access. Always verify that the authenticated user has the right to access or perform actions on the targeted object. Ensure that identifiers for resources can't be guessed by an attacker. Do not expose any personally identifiable information (PII), like user names or email addresses in the URL. Instead use a unique non-guessable token to represent the user. You can use more complex IDs as primary keys, like UUIDs , and make it harder to guess valid values. However, this only reduces the likelihood of guessing valid IDs and does not replace the need for proper access control.
Insecure Direct Object Reference (IDOR) is consistently one of the highest-impact vulnerabilities in web applications and APIs âII and it’s one of the easiest to miss during a standard pentest if you don’t know where to look. It doesn’t require complex payloads. No memory corruption. No custom shellcode. You find an ID, swap it for another ID, and suddenly you’re reading someone else’s data. Or deleting it. Or taking over their account.
This guide covers everything you need to find and exploit IDOR in 2026: detection methodology, exploitation techniques, automation tools, WAF bypass, and how to chain IDOR with other vulnerabilities for maximum impact. Insecure Direct Object Reference occurs when an application uses user-controllable input to access objects (database records, files, functions) directly âII without verifying that the requesting user is actually authorized to access that specific object.
You’re user ID 55. Invoice 1042 belongs to user ID 89. If the application returns it anyway âII that’s IDOR. The vulnerability isn’t in the ID being exposed. It’s in the missing authorization check . The server trusts that if you know the ID, you’re allowed to see it. That assumption is wrong. IDOR falls under Broken Access Control in the OWASP Top 10 âII the #1 category since 2021 âII and it’s the root cause of some of the most damaging data breaches of the past decade.
3. Software Implementation, Frameworks & Protocols Developers assume obscurity = security. UUIDs are “random enough,” they think. GUIDs are “unpredictable.” Except they test with their own account and never try another user’s ID. Authorization is hard to test systematically. Static analysis tools are terrible at finding IDOR. You need multiple accounts with different permission levels and you need to actively probe.
Modern APIs explode the attack surface. Every REST endpoint that accepts an ID is a potential IDOR. A typical SaaS app has hundreds of these. Most are never manually tested. Bug bounty programs pay well for IDOR because the business impact is real: PII exposure, data exfiltration, account takeover, privilege escalation. P1/critical findings on HackerOne and Bugcrowd are frequently IDOR.
BOLA (Broken Object Level Authorization) is OWASP API Security’s name for the same thing âII IDOR in the context of APIs. If you see BOLA referenced in API security docs, it’s IDOR. The classic. User IDs, order IDs, invoice numbers, document IDs âII sequential integers that increment predictably. Swap 10042 for any other number. If the server doesn’t verify ownership, you can enumerate every order in the system.
GUIDs generated with weak entropy or predictable seeds can be brute-forced. More importantly, GUIDs often leak âII in API responses, email notifications, URL redirects, referrer headers. Find another user’s GUID through a different endpoint and use it directly. Step 3 returns another user’s order if you guess their order ID. Multi-step IDOR is frequently missed because testers focus on the obvious endpoints.
The user_id field isn’t displayed in the UI but the server processes it. Adding it to the request changes whose profile gets updated. Classic mass assignment / parameter pollution leading to IDOR. abc123 is a thread ID that belongs to another user’s conversation. If the mapping isn’t authorization-checked server-side, you can read any thread.
Start every web app pentest with a systematic scan for object references. Here’s where to look: JWTs are common âII decode the payload and check if any fields map to objects you can manipulate. Browse the application as Account A. Use Burp Suite to intercept everything. Build a list of every ID/reference you see in: Log in as Account B and create the same types of objects (invoices, orders, documents, messages). Note the IDs assigned to B’s objects.
Log back in as Account A. Take every endpoint that accepts an object reference and replace A’s reference with B’s: Use B as a low-privilege account. Test whether A (also low-privilege) can access admin-only resources: Manual testing covers known endpoints. Automation covers the surface you’d otherwise miss. Authorize is the go-to Burp extension for IDOR testing. It intercepts every request from Account A and automatically replays it using Account B’s session token. Differences in response indicate potential IDOR.
Burp extension that discovers hidden parameters not visible in the UI. Often uncovers user_id , account_id , role parameters that the application processes but doesn’t expose to the frontend. Document the full scope of exposure. If you can read 1 record, you can enumerate all records. Calculate the blast radius. If the role field isn’t filtered server-side and you can modify your own user object, you’ve escalated to admin.
The endpoint exists and processes requests regardless of the caller’s role. This is IDOR combined with Broken Function Level Authorization. WAFs can’t prevent IDOR âII they block malicious input patterns, and IDOR requires only a valid ID. There’s nothing malicious in the payload itself. A WAF that blocks SQL injection won’t block GET /api/invoices/1043 when you should only have access to 1042 .
That said, some applications implement custom WAF rules or rate limiting that may interfere with IDOR enumeration: If direct ID enumeration triggers rate limiting, find the ID through a different endpoint first: Researcher Laxman Muthiyah found that authenticated users could delete any other user’s posts by modifying the post_id parameter. Affected every Facebook account. Bounty: $12,500.
IDOR in the driver activation flow allowed attackers to intercept activation tokens and take over driver accounts. The exploit chain combined IDOR with a token leak in the API response. HackerOne public disclosure: an IDOR on a DoD contractor portal exposed PII of thousands of government employees. Sequential integer IDs on profile endpoints, no authorization check.
A researcher discovered that Shopify’s partner API accepted partner IDs without ownership verification. An attacker with any partner account could read analytics, orders, and customer data for any other partner’s stores. No introspection disabled + missing authorization checks = full data model exposed to IDOR. GraphQL BOLA findings dominated bug bounty programs in 2025.
The best way to learn IDOR is hands-on. These labs give you safe environments to practice: DVWA’s IDOR module covers basic ID enumeration. Set difficulty to Medium/High to practice bypass techniques. PentesterLab’s Pro version has IDOR-specific exercises including API BOLA scenarios. Good for certification prep (PCAP, BSCP).
A $6/month VPS on Vultr or DigitalOcean is enough to run multiple vulnerable Docker containers simultaneously and practice the full enumeration workflow. 4. Practical Deployment, Analysis & Case Studies IDOR is simple in concept, brutal in impact, and still present in the majority of web applications and APIs tested in 2026. It requires no special tooling, no exotic payloads âII just systematic testing with two accounts and attention to every object reference the application exposes.
If you’re doing bug bounty or red team assessments, IDOR should be one of the first things you test systematically âII before you spend hours on XSS or complex injection chains. The payoff-to-effort ratio is hard to beat. Want pentest reports and red team deliverables that actually look professional? CipherWrite handles technical writing for security teams âII reports, whitepapers, and client-facing documentation.
Insecure Direct Object Reference (IDOR) is a vulnerability that arises when attackers can access or modify objects by manipulating identifiers used in a web application's URLs or parameters. It occurs due to missing access control checks, which fail to verify whether a user should be allowed to access specific data. For instance, when a user accesses their profile, the application might generate a URL like this: The 123 in the URL is a direct reference to the user's record in the database, often represented by the primary key. If an attacker changes this number to 124 and gains access to another user's information, the application is vulnerable to Insecure Direct Object Reference. This happens because the app didn't properly check if the user had permission to view data for user 124 before displaying it.
In some cases, the identifier may not be in the URL, but rather in the POST body, as shown in the following example: In this example, the application allows users to update their profiles by submitting a form with the user ID in a hidden field. If the app doesn't perform proper access control on the server-side, attackers can manipulate the "user_id" field to modify profiles of other users without authorization.
In this example, the filename acts as the object reference. If an attacker modifies the filename to another valid document, such as: and gains access to a document belonging to another user, the application is vulnerable to IDOR. Object references are not limited to numeric identifiers and may include filenames, account numbers, tokens, or other values.
In some cases, using more complex identifiers like GUIDs can make it practically impossible for attackers to guess valid values. However, even with complex identifiers, access control checks are essential. If attackers obtain URLs for unauthorized objects, the application should still block their access attempts. When testing for IDOR vulnerabilities, it is useful to create multiple user accounts with different authorization scopes. This allows developers and testers to verify that object-level authorization checks are consistently enforced.
This verification should be performed for all operations involving object references, including read, create, update, delete, export, and administrative actions. To mitigate IDOR, implement access control checks for each object that users try to access. Web frameworks often provide ways to facilitate this. Additionally, use complex identifiers as a defense-in-depth measure, but remember that access control is crucial even with these identifiers.
Avoid exposing identifiers in URLs and POST bodies if possible. Instead, determine the currently authenticated user from session information. When using multi-step flows, pass identifiers in the session to prevent tampering. When looking up objects based on primary keys, use datasets that users have access to. For example, in Ruby on Rails: Verify the user's permission every time an access attempt is made. Implement this structurally using the recommended approach for your web framework.
As an additional defense-in-depth measure, replace enumerable numeric identifiers with more complex, random identifiers. You can achieve this by adding a column with random strings in the database table and using those strings in the URLs instead of numeric primary keys. Another option is to use UUIDs or other long random values as primary keys. Avoid encrypting identifiers as it can be challenging to do so securely.
These illustrative examples assume authenticated requests and a policy that only owners can read documents. currentUser() represents an application helper that obtains the user from the trusted authentication context. Consider a Spring Boot endpoint that returns a document by its identifier: The {id} path variable is controlled by the requester and flows directly into findById() . Nothing verifies that the returned document belongs to the currently authenticated user, so any user who can guess or obtain a valid identifier can read another user's document.
Prefer a lookup limited to documents owned by the current user. This mirrors the scoped-query approach shown for Ruby on Rails above: The post-fetch check can distinguish a missing object from one the caller cannot access. If the resource's existence is sensitive, use the scoped lookup and map both cases to the same public response, such as a 404 (Not Found) response . For example, GET /user/ [email protected] should not reveal whether an account exists to a caller who is not allowed to know.
To use Spring Security's @PreAuthorize alternative, first enable method security with @EnableMethodSecurity on a Spring @Configuration class; Spring Boot's security starter does not enable it by default. The following example applies to a Spring-managed component and assumes an application-provided documentAuthorizationService that checks ownership: Insecure Direct Object Reference (IDOR) is an access control vulnerability that occurs when an application exposes internal object references — such as database keys, file names, or record IDs — and fails to verify that the requesting user is authorized to access the referenced object. An attacker can exploit this by modifying the reference value to access resources belonging to other users.
Web applications frequently use predictable values to reference objects. For example, a URL like /api/users/123/profile uses the ID 123 to look up a specific user record. When the application does not verify that the authenticated user is authorized to access that particular record, an attacker can simply change 123 to 124 to view or modify another user’s data. The core issue is that the application trusts the client to supply a valid reference without enforcing server-side authorization checks. Even if object identifiers are not sequential, an attacker who can obtain or guess another user’s identifier can exploit the flaw.
A REST API returns a user’s profile based on the ID in the URL path. The server retrieves the record but never checks whether the authenticated user is allowed to access it. Because the endpoint only checks that the caller is authenticated (via @login_required ), user 123 can retrieve user 124’s profile simply by changing the ID in the URL.
If the server does not verify that the requested file belongs to the authenticated user, the attacker downloads another user’s invoice. Insecure Direct Object Reference (IDOR) is an access control flaw where applications expose internal object identifiers, allowing attackers to access objects they should not. Analogy: giving users a visible filing-cabinet key that opens any drawer.
Formal: an authorization failure caused by relying on direct object references without adequate server-side access checks. Insecure Direct Object Reference is a class of authorization vulnerability where a system exposes internal identifiers—database keys, filenames, URLs—so that an attacker or unauthorized user can manipulate references to access or modify other users’ data. It is not encryption failure, not always an input validation bug, nor solely an injection issue. The root is missing or improper authorization checks on a resource access path.
An authorization flaw where direct use of internal object identifiers allows unauthorized access because the server fails to enforce ownership or permission checks. 1) User profile API: A query parameter id=123 returns profile; changing 123 returns another user’s profile. 2) File download endpoint: /download?file=invoice_2026_42.pdf downloads any invoice when filename is guessable. 3) Cloud object storage: Public URLs are protected via names; enumerating keys yields PII downloads. 4) Background job: A job processes tasks by job_id; a worker lacking tenant checks reads other tenants’ data. 5) Admin UI bug: A dashboard lists object IDs; developers assume UI hides sensitive IDs but API accepts them.
This section clarifies when exposing direct object references is acceptable and when it is not. 1) Direct-ID APIs: REST endpoints using database IDs in path. Use when objects are public or when server enforces strict ACLs. 2) Opaque mapping token: Server returns a token mapping to an internal ID. Use for sensitive resources. 3) Signed URL pattern: Short-lived URLs for downloads with embedded signatures. Use for object storage access via public endpoints.
4) Service-mesh enforced RBAC: Mutual TLS and service identity plus policy checks to ensure inter-service requests include tenant claims. Use in microservices for zero-trust. 5) Policy-gated reads: Centralized authorization service validates every object access; use when consistency of checks is critical. 6) Attribute-based access control (ABAC): Authorization based on resource attributes and requester attributes; use for complex rules.
5. Performance Evaluation & Extended Technical Observations Glossary of 40+ terms. Each entry: term — brief definition — why it matters — common pitfall. How to Measure Insecure Direct Object Reference (Metrics, SLIs, SLOs) (TABLE REQUIRED) This section recommends practical SLIs, measurement approaches, starting SLO guidance, and alerting strategy.
1) Prerequisites – Inventory of sensitive resources and ownership model. – Authn and authz framework selected. – Observability: logging, tracing, monitoring in place. – CI/CD pipelines and test environments. 2) Instrumentation plan – Instrument endpoints to log sanitized resource IDs and authorization decisions. – Add tracing spans for authorization checks. – Define metrics for SLIs.
3) Data collection – Configure centralized logging, tracing, and metrics. – Ensure logs redact PII while retaining identifier hashes for correlation. – Retain audit logs for required compliance windows. 4) SLO design – Define authorization success rate SLI for sensitive RBAC endpoints. – Create SLOs such as unauthorized access incidents = 0 critical per quarter, or time-to-remediate <24 hours.
5) Dashboards – Build exec, on-call, debug dashboards as described earlier. – Include anomaly detection panels. 6) Alerts & routing – Critical: immediate page for confirmed unauthorized reads of sensitive data. – High: ticket for suspicious enumeration with failed attempts. – Route to security team and owning service team. 7) Runbooks & automation – Runbook: identification, containment (revoke tokens, block IP), mitigation, and rollback. – Automation: revoke signed URLs, rotate keys, or apply temporary rate limits.
8) Validation (load/chaos/game days) – Run DAST in isolated pre-prod. – Conduct chaos experiments where auth layer is temporarily bypassed to validate detection and containment. – Run game days focusing on cross-tenant data exposure. 9) Continuous improvement – Postmortem lessons fed back into SAST/DAST rules and CI gates. – Update policies, reduce TTLs, and improve test coverage.
1) User profile access – Context: REST API exposes userId in path. – Problem: Users can query other profiles by altering IDs. – Why IDOR helps: Identifies missing ownership checks. – What to measure: Unauthorized access rate M1. – Typical tools: SAST, API gateway logs. 2) Invoice or billing downloads – Context: Download endpoint with filename param. – Problem: Guessable filenames expose invoices. – Why IDOR helps: Shows need for signed URLs or ACLs. – What to measure: Signed URL misuse M3. – Typical tools: CDN logs, object storage audits.
3) Multi-tenant SaaS customer data – Context: Shared service handles tenant objects by ID. – Problem: Cross-tenant reads due to missing tenant context. – Why IDOR helps: Focus on tenant isolation. – What to measure: Cross-tenant cache hits M5. – Typical tools: Service mesh, tracing. 4) Mobile app file access – Context: App stores document IDs in local state. – Problem: Manipulated ID leads to other users’ docs. – Why IDOR helps: Ensure server validates user identity against resource owner. – What to measure: Enumeration attempts M2. – Typical tools: DAST, mobile test harness.
5) Background job processing – Context: Worker pulls job by job_id from queue. – Problem: Jobs reference other tenant data. – Why IDOR helps: Enforce tenant context in workers. – What to measure: Authorization coverage M6. – Typical tools: Queue logs, job tracing. 6) Serverless file handlers – Context: Lambda function downloads file by key. – Problem: Function accepts third-party-supplied key. – Why IDOR helps: Use signed tokens or IAM roles. – What to measure: Signed URL misuse M3. – Typical tools: Cloud function logs, IAM policy checks.
7) Admin tooling and internal UIs – Context: Admin consoles have raw IDs. – Problem: Insufficient admin guards allow mass access. – Why IDOR helps: Insert audit and RBAC. – What to measure: Failed permission audits M7. – Typical tools: Admin audit logs. 8) CI/CD artifact access – Context: Build artifacts referenced directly. – Problem: Unauthenticated or wrong tenant can pull artifacts. – Why IDOR helps: Secure artifact registry. – What to measure: Unauthorized access rate M1. – Typical tools: Artifact registry and gateway logs.
9) Third-party integrations – Context: Webhooks include object IDs. – Problem: External services can fetch resources with IDs. – Why IDOR helps: Use signed callbacks and validate origin. – What to measure: External access patterns M2. – Typical tools: Webhook logs, integration dashboards. 10) Observability pipelines – Context: Traces include object IDs. – Problem: Logs and traces expose PII. – Why IDOR helps: Identify leakage vectors. – What to measure: Sensitive ID leakage M4. – Typical tools: Tracing and logging pipelines.
Context: Multi-tenant web app running in Kubernetes with shared DB and object storage. Goal: Prevent cross-tenant data access by ID tampering. Why Insecure Direct Object Reference matters here: Pods may fetch objects by DB ID without tenant checks; namespace isolation alone is insufficient. Architecture / workflow: Ingress -> AuthN -> API Service -> DB + Object Storage; service mesh enforces mTLS. Step-by-step implementation: Context: Serverless functions generate download links for user images stored in object storage. Goal: Prevent users from downloading images they do not own. Why Insecure Direct Object Reference matters here: Signed URLs and file keys can be predictable. Architecture / workflow: Client requests image -> Function verifies ownership -> Generates signed URL with short TTL. Step-by-step implementation: Context: Support engineer accidentally logs invoice IDs in Slack debug posts, attacker harvests and downloads invoices.
Goal: Contain leak, rotate identifiers, and patch code to prevent future logging. Why Insecure Direct Object Reference matters here: Leaked IDs allowed unauthorized access via API. Architecture / workflow: API accepted invoice_id param and returned invoice without ownership check. Step-by-step implementation: Context: High throughput API caches responses per object ID but originally omitted tenant key to improve cache hit rate. Goal: Avoid cross-tenant leakage while maintaining performance. Why Insecure Direct Object Reference matters here: Cache shape caused different tenants to see each other’s data. Architecture / workflow: API -> Cache -> DB; cache key previously object_id only. Step-by-step implementation: 1) Symptom: Users can access other users’ records. -> Root cause: No server-side ownership check. -> Fix: Implement ownership validation in service layer. 2) Symptom: Sequential IDs returned in APIs. -> Root cause: Exposed primary keys. -> Fix: Use opaque tokens or UUIDs. 3) Symptom: High volume of requests across ID ranges. -> Root cause: Enumeration attack. -> Fix: Rate limit and require stronger auth. 4) Symptom: Sensitive IDs in logs. -> Root cause: Logging raw parameters. -> Fix: Redact or hash IDs in logs. 5) Symptom: Cache returns wrong tenant’s data. -> Root cause: Missing tenant in cache key. -> Fix: Include tenant qualifier in cache keys. 6) Symptom: Signed URLs used after expected invalidation.
-> Root cause: Long TTL or clock skew. -> Fix: Shorten TTL and implement revocation hooks. 7) Symptom: False positives in SAST findings. -> Root cause: Generic rules without context. -> Fix: Tune rules and add annotations. 8) Symptom: Traces contain PII. -> Root cause: Unsanitized trace attributes. -> Fix: Sanitize and sample traces. 9) Symptom: Inter-service calls accept raw IDs without tenant claim. -> Root cause: No mutual authentication. -> Fix: Add mTLS and caller identity propagation. 10) Symptom: Admin console exposes raw IDs. -> Root cause: Developer convenience over safety. -> Fix: Implement admin RBAC and tokenized references. 11) Symptom: Third-party webhook can fetch resources. -> Root cause: Lack of signed callbacks. -> Fix: Add signature verification and limited scopes. 12) Symptom: CI pulls artifacts without auth. -> Root cause: Poor artifact registry permissions. -> Fix: Enforce registry auth and token scopes. 13) Symptom: High on-call churn after auth deploys. -> Root cause: Abrupt policy enforcement causing legitimate denies. -> Fix: Canary policies and gradual enforcement. 14) Symptom: Incidents without audit trail. -> Root cause: Inadequate logging of authorization decisions.
-> Fix: Log decisions with context and retention. 15) Symptom: Monitoring noise from legitimate scans. -> Root cause: Alert thresholds not tuned. -> Fix: Baseline tuning and group alerts. 16) Symptom: Over-reliance on client-side checks. -> Root cause: Trusting front-end to prevent tampering. -> Fix: Move checks to server. 17) Symptom: SLOs triggered by authorization fixes. -> Root cause: Emergency changes without plan. -> Fix: Reserve error budget and coordinate deployments. 18) Symptom: Tools expose IDs in dashboards. -> Root cause: Observability tooling not sanitized. -> Fix: Redaction rules and role-based access to dashboards. 19) Symptom: Policy changes break background jobs. -> Root cause: Missing service account permissions. -> Fix: Update job IAM roles and test. 20) Symptom: Pentest finds IDOR in API. -> Root cause: Limited QA and missing automated tests. -> Fix: Add contract tests and DAST in pipeline. 21) Symptom: Delayed remediation. -> Root cause: No prioritized process for security bugs. -> Fix: Define SLAs for security fixes and triage. 22) Symptom: Excessive privilege in cloud IAM. -> Root cause: Broad roles for convenience. -> Fix: Apply least privilege and periodic role reviews. 23) Symptom: Unexpected cross-region data access. -> Root cause: Global replicas not segregated by tenant. -> Fix: Enforce tenant-aware access in replication logic. 24) Symptom: Observability pipelines drop events. -> Root cause: High-volume sanitization pipeline issues. -> Fix: Tune sampling and ensure essential audit events are preserved. 25) Symptom: Developers bypass checks in quick fixes. -> Root cause: Pressure to ship. -> Fix: Enforce code review and pre-merge security checks.
Observability pitfalls included above: logs/traces exposing IDs, insufficient audit logs, noisy alerts, dropped events, dashboards leaking IDs. Apply server-side ownership checks validating the authenticated user against object owner, then rotate exposed tokens. UUIDs reduce guessability but are not a substitute for server-side authorization; they help but do not eliminate risk.
Short TTLs are best practice; typical ranges are minutes to hours depending on use case and UX needs. Service mesh provides mTLS and identity propagation enabling policy enforcement for inter-service calls. Add tests that attempt cross-tenant access, use seeded enumerations, and include DAST stages. Unauthorized access rate, ID enumeration attempts, signed URL misuse, and sensitive ID leakage.
Pen tests validate that IDOR findings are exploitably accessible in realistic scenarios. Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Memory%20safety • https://en.wikipedia.org/wiki/Pointer%20%28computer%20programming%29 • https://en.wikipedia.org/wiki/Antivirus%20software • https://developer.mozilla.org/en-US/docs/Web/Security/Attacks/IDOR • https://redteamguide.com/guides/idor-attack-guide-2026/ • https://cheatsheetseries.owasp.org/cheatsheets/Insecure_Direct_Object_Reference_Prevention_Cheat_Sheet.html • https://community.owasp.org/attacks/insecure_direct_object_reference • https://devsecopsschool.com/blog/insecure-direct-object-reference/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Insecure Direct Object Reference Detection Tool Project.
[*] Metasploit Scan Running on Target Subnet for Insecure Direct Object Reference Detection Tool Project... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |