Complete Technical Paper Content — Internal Network Lateral Movement Detection System
Overview & System Context
Internal Network Lateral Movement Detection System: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9663 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Network detection and response (NDR) refers to a category of network security products that detect abnormal system behaviors by continuously analyzing network traffic. NDR solutions apply behavioral analytics to inspect raw network packets and metadata for both internal (east-west) and external (north-south) network communications.
Improved threat detection: AI can analyze large volumes of data on vulnerabilities, threats, and attack tactics to identify anomalous network activities. This allows NDR to detect emerging attack patterns with greater accuracy and fewer false positives. Alert prioritization: AI models can evaluate the criticality of NDR alerts based on factors like affected assets, exploitability, and potential impact. This enables security teams to triage alerts effectively despite staff shortages. Analyst workflow optimization: AI assistants can guide analysts during incident response, suggesting relevant investigation steps based on details of the threat. This amplifies analyst efficiency, especially for junior staff lacking specialized expertise.
Automated response: Although not yet widely adopted, AI could enable NDR platforms to autonomously execute containment measures like quarantining endpoints. AI would identify and recommend response actions for analyst approval. Security team communications: NDR vendors are exploring integrations with natural language AI to generate incident reports and metrics digestible for business leaders, not just technical security staff.
In information security, threat hunting is the process of proactively searching for threats against computer systems in order to protect them. This is in contrast to traditional threat management measures, such as firewalls, intrusion detection systems (IDS), malware sandbox (computer security) and SIEM systems, which typically involve an investigation of evidence-based data after there has been a warning of a potential threat. Threat analyst Lesley Carhart stated that there is no consensus amongst practitioners what threat hunting actually entails.
Analytics-Driven: "Machine-learning and UEBA, used to develop aggregated risk scores that can also serve as hunting hypotheses" Situational-Awareness Driven: "Crown Jewel analysis, enterprise risk assessments, company- or employee-level trends" Intelligence-Driven: "Threat intelligence reports, threat intelligence feeds, malware analysis, vulnerability scans" The analysts research their hypothesis by going through vast amounts of data about the network. The results are then stored so that they can be used to improve the automated portion of the detection system and to serve as a foundation for future hypotheses. The Detection Maturity Level (DML) model expresses threat indicators can be detected at different semantic levels. High semantic indicators such as goal and strategy or tactics, techniques and procedures (TTPs) are more valuable to identify than low semantic indicators such as network artifacts and atomic indicators such as IP addresses. SIEM tools typically only provide indicators at relatively low semantic levels. There is therefore a need to develop SIEM tools that can provide threat indicators at higher semantic levels.
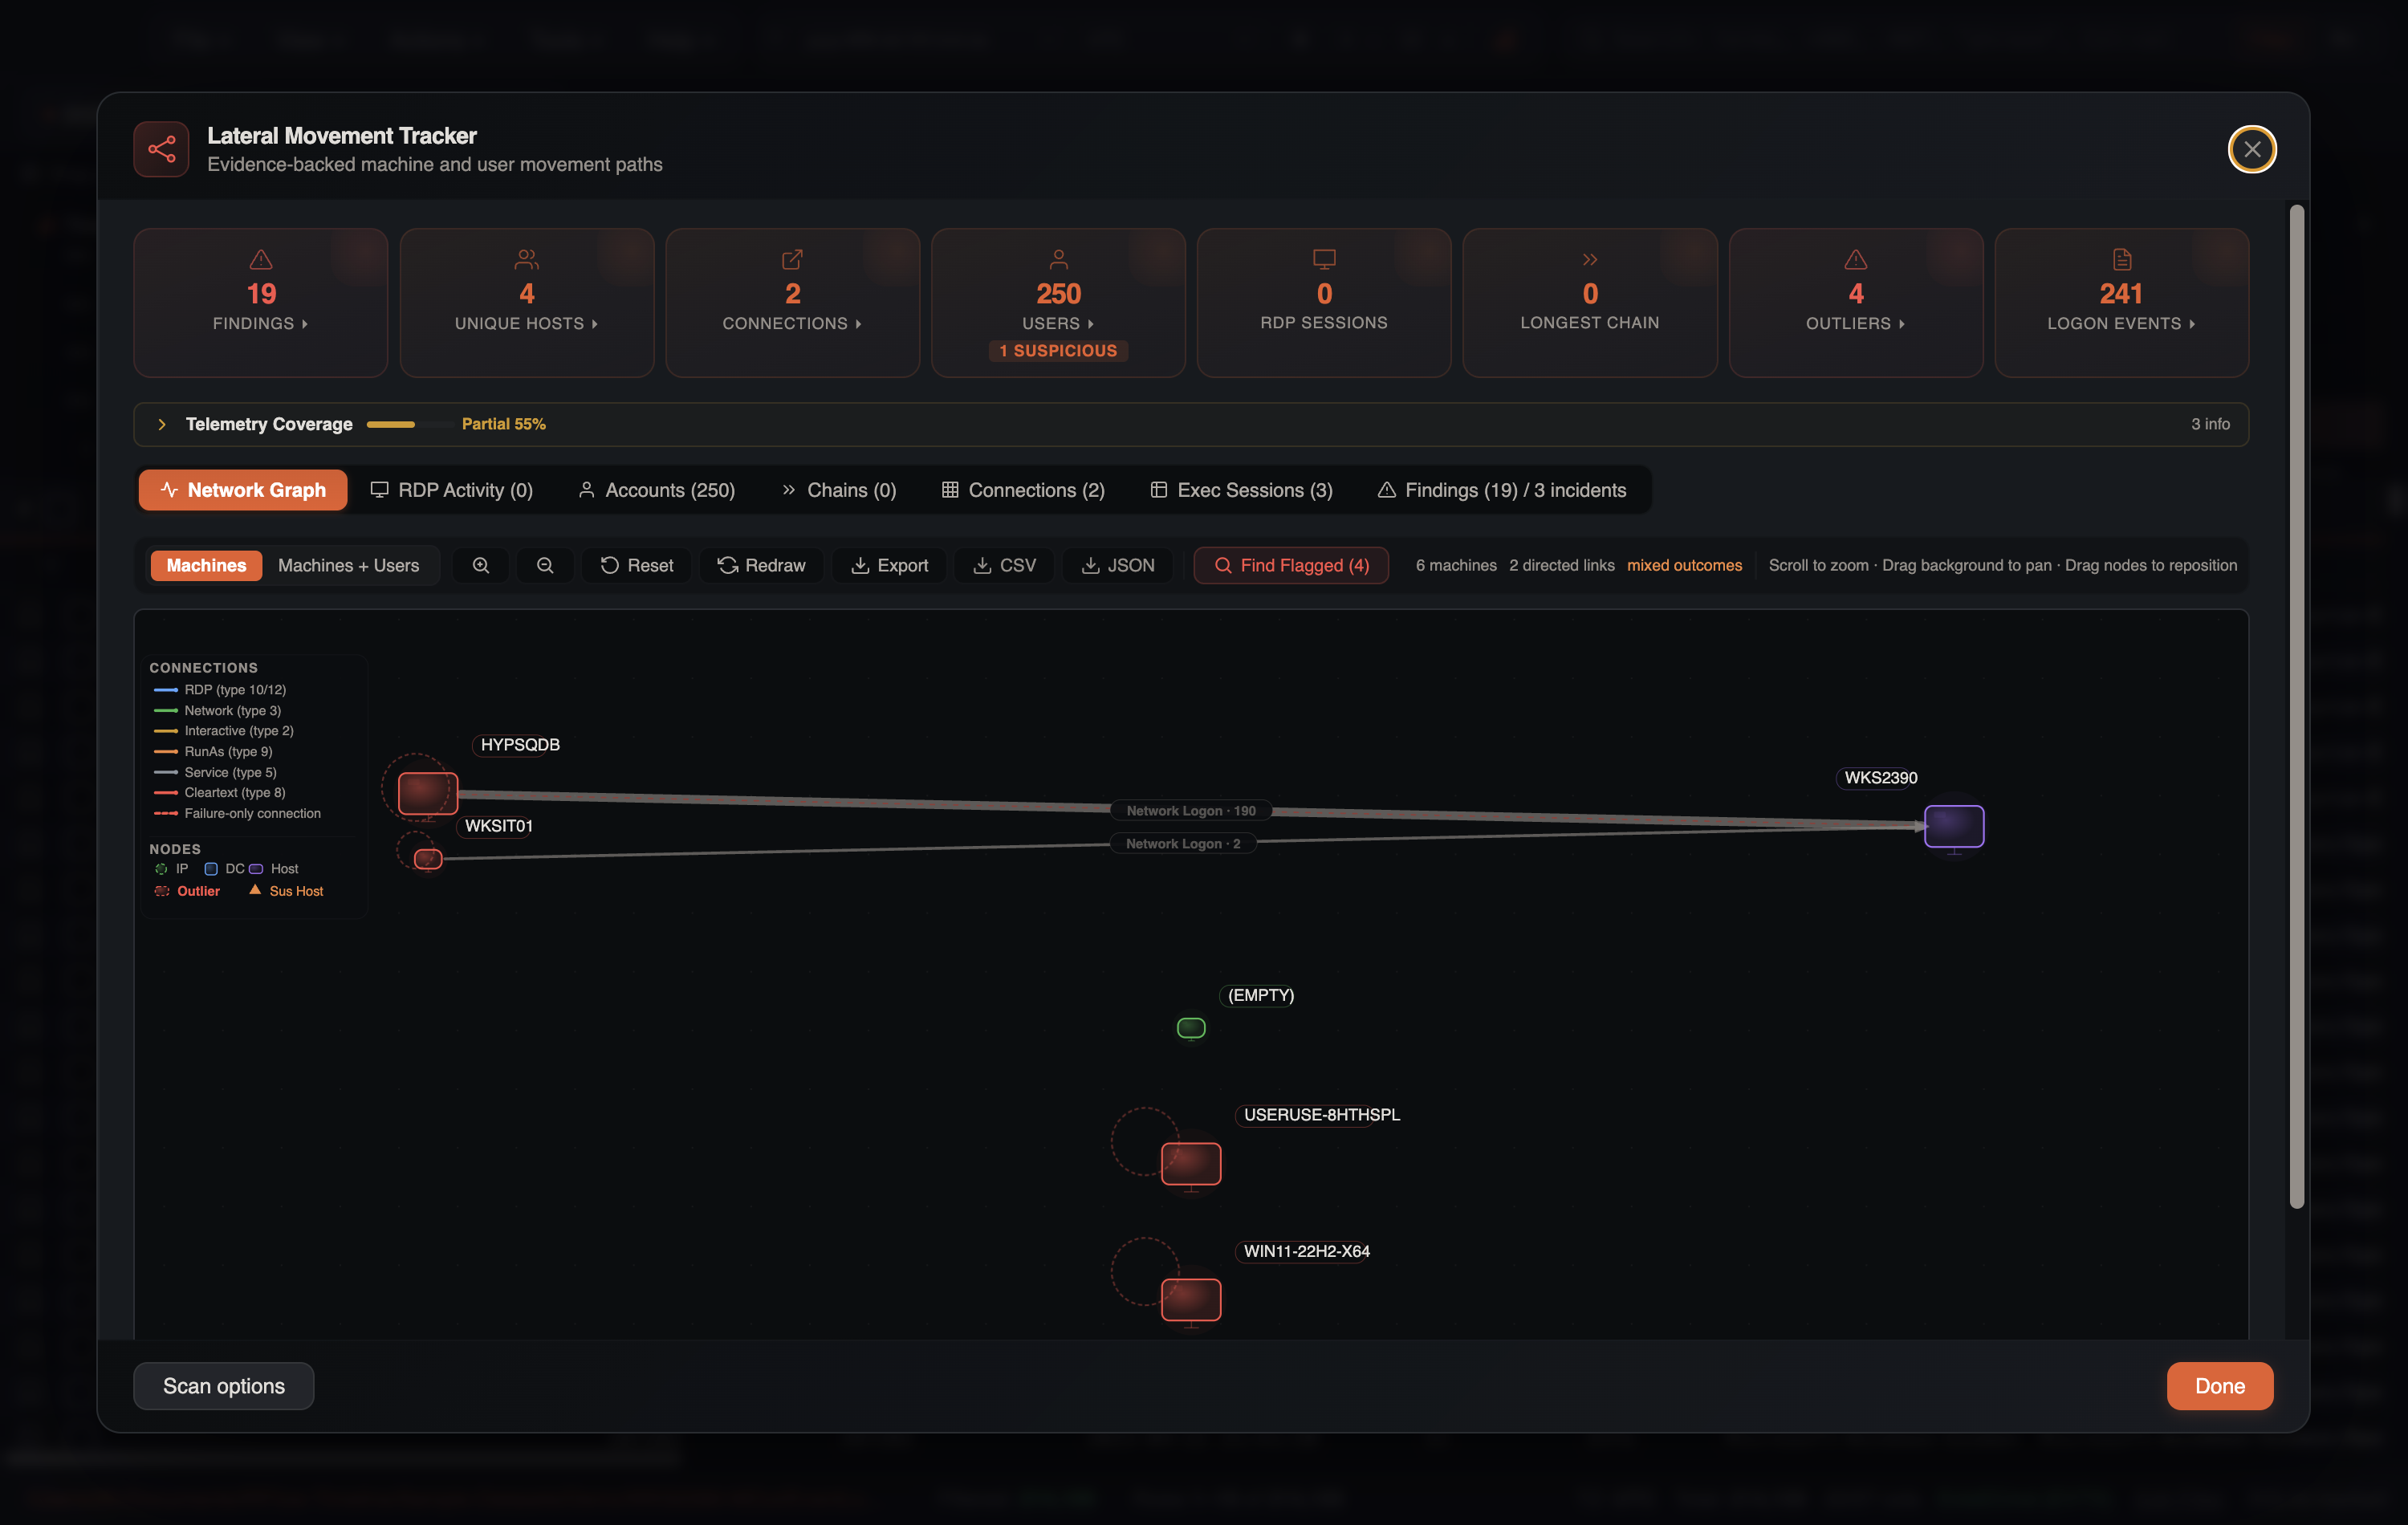
Figure 1: Lateral Movement Tracing | IRFlow Timeline Indicator of compromise - An indicator of compromise (IOC) tells you that an action has happened and you are in a reactive mode. This type of IOC is done by looking inward at your own data from transaction logs and or SIEM data. Examples of IOC include unusual network traffic, unusual privileged user account activity, login anomalies, increases in database read volumes, suspicious registry or system file changes, unusual DNS requests and Web traffic showing non-human behavior. These types of unusual activities allow security administration teams to spot malicious actors earlier in the cyberattack process. Indicator of Concern - Using Open-source intelligence (OSINT), data can be collected from publicly available sources to be used for cyberattack detection and threat hunting.
Initial – At Level 0 maturity, an organization relies primarily on automated reporting and does little or no routine data collection. Minimal – At Level 1 maturity, an organization incorporates threat intelligence indicator searches. It has a moderate or high level of routine data collection. Procedural – At Level 2 maturity, an organization follows analysis procedures created by others. It has a high or very high level of routine data collection. Innovative – At Level 3 maturity, an organization creates new data analysis procedures. It has a high or very high level of routine data collection. Leading – At Level 4 maturity, automates the majority of successful data analysis procedures. It has a high or very high level of routine data collection.
Reactive Threat Hunting - This method is triggered by a malicious event, typically after a data breach or theft is discovered. Efforts are typically focused on forensics and remediation. Proactive Threat Hunting - This method actively seeks out ongoing malicious events and activities inside the network, the goal is to detect an in progress cyber attack. Efforts are typically focused on detection and remediation. Outside the network perimeter External Threat Hunting - This method proactively seeks out malicious threat actor infrastructure to map and predict where cyber attacks are likely to emerge to prepare defensive strategies. Efforts are typically focused on Cyber Threat Reconnaissance, Threat Surface Mapping and monitoring of third-party risks. In a Team Cymru blog, they explain that unlike internal threat hunting, the threat actors themselves are proactively tracked, traced, and monitored as they shift infrastructure and claim victims. Indicators of compromise (IOCs), typically used to inform of a breach, become signals intelligence beyond the network perimeter.
Figure 2: A closer look at LATMA, the open-source lateral movement detection tool ... The cyber kill chain is a taxonomy for cyberattack phases developed by Lockheed Martin, inspired on the military kill chain. The cyber kill chain model has seen limited adoption in the information security sector, with critics pointing to what they believe are fundamental flaws in the model.
Reconnaissance: Intruder selects target, researches it, and attempts to identify vulnerabilities in the target network. Weaponization: Intruder creates remote access malware weapon, such as a virus or worm, tailored to one or more vulnerabilities. Delivery: Intruder transmits weapon to target (e.g., via e-mail attachments, websites or USB drives) Exploitation: Malware weapon's program code triggers, which takes action on target network to exploit vulnerability.
Installation: Malware weapon installs an access point (e.g., "backdoor") usable by the intruder. Command and Control: Malware enables intruder to have "hands on the keyboard" persistent access to the target network. Actions on Objective: Intruder takes action to achieve their goals, such as data exfiltration, data destruction, or encryption for ransom. Defensive courses of action can be taken against these phases: Detect: Determine whether an intruder is present. Deny: Prevent information disclosure and unauthorized access. Disrupt: Stop or change outbound traffic (to attacker). Degrade: Counter-attack command and control. Deceive: Interfere with command and control. Contain: Network segmentation changes A U.S. Senate investigation of the 2013 Target Corporation data breach included analysis based on the Lockheed Martin kill chain framework. It identified several stages where controls did not prevent or detect progression of the attack.
Reconnaissance: This is the initial phase where the attacker gathers information about the target system or network. This could involve scanning for vulnerabilities, researching potential entry points, and identifying potential targets within the organization. Initial Intrusion: Once the attacker has gathered enough information, they attempt to breach the target system or network. This could involve exploiting vulnerabilities in software or systems, utilizing social engineering techniques to trick users, or using other methods to gain initial access. Establish a Backdoor: After gaining initial access, the attacker often creates a backdoor or a persistent entry point into the compromised system. This ensures that even if the initial breach is discovered and mitigated, the attacker can still regain access. Obtain User Credentials: With a foothold in the system, the attacker may attempt to steal user credentials. This can involve techniques like keylogging, phishing, or exploiting weak authentication mechanisms. Install Various Utilities: Attackers may install various tools, utilities, or malware on the compromised system to facilitate further movement, data collection, or control. These tools could include remote access Trojans (RATs), keyloggers, and other types of malicious software. Privilege Escalation / Lateral Movement / Data Exfiltration: Once inside the system, the attacker seeks to elevate their privileges to gain more control over the network. They might move laterally within the network, trying to access more valuable systems or sensitive data. Data exfiltration involves stealing and transmitting valuable information out of the network. Maintain Persistence: This stage emphasizes the attacker's goal to maintain a long-term presence within the compromised environment. They do this by continuously evading detection, updating their tools, and adapting to any security measures put in place.
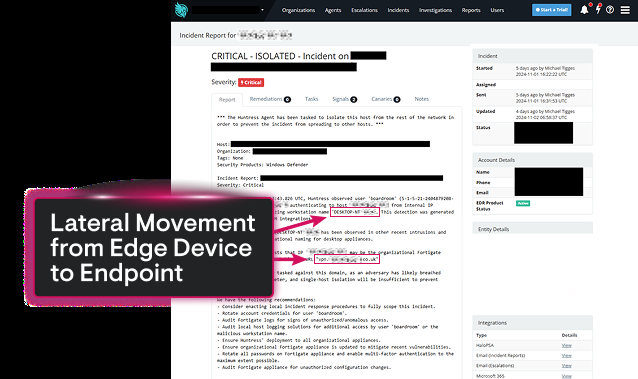
Figure 3: What is Lateral Movement? Tactics, Detection & Prevention | Huntress The Unified Kill Chain was developed in 2017 by Paul Pols in collaboration with Fox-IT and Leiden University to overcome common critiques against the traditional cyber kill chain, by uniting and extending Lockheed Martin's kill chain and MITRE's ATT&CK framework (both of which are based on the "Get In, Stay In, and Act" model constructed by James Tubberville and Joe Vest). The unified version of the kill chain is an ordered arrangement of 18 unique attack phases that may occur in an end-to-end cyberattack, which covers activities that occur outside and within the defended network. As such, the unified kill chain improves over the scope limitations of the traditional kill chain and the time-agnostic nature of tactics in MITRE's ATT&CK. The unified model can be used to analyze, compare, and defend against end-to-end cyberattacks by advanced persistent threats. A subsequent whitepaper on the unified kill chain was published in 2021.
Astral provides detection capabilities focused on identifying lateral movement and suspicious internal traffic within the environment. These detections aim to uncover attacker activity that occurs after initial access, when a threat actor attempts to move between systems, escalate privileges, or expand control across the network. Lateral movement detection in Astral analyzes internal communication patterns between hosts, services, and network segments. By evaluating connection frequency, traffic volume, access paths, and protocol usage, Astral identifies abnormal internal traffic that deviates from expected behavior. High volumes of lateral traffic, especially between systems that do not normally communicate, are treated as potential indicators of compromise.
Astral also detects internal scanning and enumeration activity. Repeated connection attempts across multiple internal hosts, ports, or services may indicate efforts to discover additional targets or identify exploitable systems. These behaviors are correlated over time to distinguish legitimate administrative activity from malicious propagation attempts. In addition, Astral evaluates internal service usage and access patterns to identify suspicious behavior. Sudden increases in access to specific services, unusual protocol usage within the internal network, or abnormal aggregation of connections may indicate credential abuse, automated tooling, or unauthorized movement within the environment.
All detections related to lateral movement and internal traffic are correlated with prior stages of the attack lifecycle, such as reconnaissance or exploitation activity. This correlation enables Astral to identify complete attack paths rather than isolated events. Once detected, these activities are integrated into Inopli’s Response and RPA workflows, enabling containment, investigation, and remediation of internal threats in a coordinated and auditable manner.
A documentation-only showcase of a senior cybersecurity project that explores how behavioral network analysis can identify lateral movement inside an isolated, simulated enterprise environment. Public showcase notice: The source code, operational configuration, datasets, packet captures, credentials, trained artifacts, and detailed attack procedures are intentionally excluded for security, privacy, and academic-integrity reasons.
2. System Architecture & Core Working Principles Traditional perimeter defenses are often less effective after an attacker gains an internal foothold, particularly when malicious activity uses legitimate credentials and ordinary network protocols. This project examines that problem through a controlled purple-team lab in which normal enterprise activity and authorized adversary simulations are observed by a behavioral detection pipeline.
The system is designed to establish normal communication patterns, identify meaningful deviations, generate explainable alerts, and map suspicious behavior to the MITRE ATT&CK framework. It provides a safe research environment for studying detection quality without using real malware or targeting production systems. This diagram is intentionally simplified and does not expose operational network design or attack procedures. See docs/architecture.md for the public architecture overview.
The project focuses on behavior rather than recognizing one specific offensive tool. Examples of evaluated signals include unusual connection fan-out, previously unseen destinations, atypical service usage, cross-boundary communication, and deviations from a learned baseline. Detections are designed to be interpretable and aligned with relevant MITRE ATT&CK concepts, including: The project is structured to evaluate both detection quality and operational usefulness. Relevant measures include: Numerical results are not published here unless they have been independently verified and approved for public release.
This project is limited to an authorized academic lab. It does not include real malware, production deployment, automated intrusion prevention, destructive actions, or instructions for attacking third-party systems. Read the ethical-use statement and security policy before referencing or sharing this project. This senior project was developed for CS 4176 under the supervision of Dr. Mohammad Nauman by: Team-member names are included for accurate academic attribution. Individual contributions should only be added with the agreement of the team.
The documentation and visuals in this showcase are provided for portfolio and evaluation purposes. All rights are reserved. See LICENSE . Documentation-only showcase of a purple-team behavioral lateral movement detection senior project. Providing access to infrastructure resources is inevitable. With the proper guardrails, as discussed in secure human access to infrastructure , you can reduce the risk of unauthorized access. However, if an attacker gains access to one resource, they may attempt to move laterally through your environment to compromise additional resources.
Lateral movement is the act of moving through the environment from a compromised resource into an uncompromised resource by exploiting the assumption that the compromised resource is secure. The MITRE ATT&CK framework provides an overview of lateral movement techniques that you can use to secure your infrastructure.
The following diagram shows the lateral movement techniques attackers commonly use to compromise systems through unauthorized means. With various techniques available to anyone, you need to protect your organization with a solution that stops lateral movement through bi-directional or mutual transport layer security (mTLS).
In the traditional datacenter approach to network security, network administrators segment the network into different virtual networks (VLANs). You apply rules to each VLAN to allow access between services in different VLANs. Following this model, however, might allow a compromised system in one VLAN to access services in other VLANs without proper authentication and authorization.
Modern infrastructure and applications that use a cloud native approach, dynamic services come up and down often. These services need to establish secure connections and not rely on long-lived secrets or manual authentication processes. 3. Software Implementation, Frameworks & Protocols HashiCorp Consul enables you to secure communication between systems by leveraging mTLS between systems in the service mesh.
A service mesh is an infrastructure layer that manages communication between services for distributed applications. Rather than embedding networking logic directly into application code, the service mesh abstracts these concerns into a separate layer. This allows services to communicate through the mesh infrastructure without needing to understand the underlying network.
The benefits of a service mesh include enhanced observability, security, and reliability. It provides load balancing, traffic routing, and failure handling without requiring code changes. Security is strengthened through automatic mutual TLS encryption and policy enforcement. This separation of concerns allows development teams to focus on business logic while the service mesh handles operational concerns like retries, timeouts, circuit breaking, and canary deployments, ultimately reducing complexity and improving the maintainability of large-scale distributed systems.
Running a service mesh introduces its own set of challenges. Organizations need to secure and manage the service mesh configuration and supporting resources. An example of some of these resources in a mesh are: If you're using a service mesh today, consider the level of effort to store the secrets associated with the service mesh. Centralization of secrets across your environments is essential to stop a lateral attack, among other vulnerabilities. Identity is the new perimeter, and identity is a secret. Managing multiple secrets may lead to secret sprawl.
HashiCorp Vault can help practitioners simplify these workloads and centralize these secrets. Vault's secrets engines give teams solutions for various use cases trying to manage secrets. In this section of how to Secure infrastructure, you learned why it is important to secure infrastructure against lateral movement attacks. Unmanaged traffic creates risks for your company's security programs, leading to leaked secrets, or unauthorized access to data. Prevent lateral movement is part of the Secure systems pillar .
Following these documents in order ensures a logical progression through the key concepts and best practices, helping you build a strong foundation for your organization's security program. Foundation models have recently emerged as a new paradigm in machine learning (ML). These models are pre-trained on large and diverse datasets and can subsequently be applied to various downstream tasks with little or no retraining. This allows people without advanced ML expertise to build ML applications, accelerating innovation across many fields. However, the adoption of foundation models in cybersecurity is hindered by their inability to efficiently process data such as network traffic captures or binary executables. The recent introduction of graph foundation models (GFMs) could make a significant difference, as graphs are well-suited to representing these types of data. We study the usability of GFMs in cybersecurity through the lens of one specific use case, namely lateral movement detection. Using a pre-trained GFM, we build a detector that reaches state-of-the-art performance without requiring any training on domain-specific data. This case study thus provides compelling evidence of the potential of GFMs for cybersecurity.
An immediate and lasting impact of large language models [ 9 , 42 ] (LLMs) and their multimodal counterparts, such as vision-language models [ 29 ] , has been the democratization of machine learning (ML) application development. Consider for instance natural language processing: whereas building a text classifier used to require gathering high-quality labeled data, then designing and training a model, it can now be achieved by simply sending the right prompt to a pre-existing LLM and extracting information from its answer. By allowing domain experts without advanced ML skills to build ML applications, this new paradigm accelerates the adoption of ML in various domains.
More generally, this trend results from the emergence of foundation models —that is, models pre-trained on large and diverse datasets, that can be used for various tasks with little or no retraining. Beyond LLMs, foundation models have been developed for tasks ranging from time series forecasting [ 2 ] to image segmentation and classification [ 24 , 34 ] . However, their contribution to cybersecurity-related applications has so far been limited because these applications often deal with peculiar data. Unlike textual documents, classifying binary executables or network traffic captures using LLMs is impractical as they differ too much from typical LLM training data. On the other hand, graphs are well-suited to representing such data, and graph neural networks (GNNs) are thus often used in cybersecurity-related ML applications [ 4 , 5 ] .
In the last few years, pre-trained GNNs specialized on various graph-related tasks have started to emerge. These graph foundation models [ 31 ] (GFMs) could make it significantly easier to build ML applications for many cybersecurity-related use cases, in the same way that LLMs democratized natural language processing. In previous work [ 25 ] , we performed an initial evaluation of GFMs for a specific cybersecurity problem, namely lateral movement detection. This task is well-suited to graph-based approaches as it can be framed as detecting anomalous edges in a graph [ 8 , 23 ] . Here, we extend this work into a detailed case study on the following question: can we reach state-of-the-art performance in lateral movement detection using a pre-trained GFM, only through careful input graph construction and output post-processing? By imposing this constraint, we aim to assess the ability of cybersecurity practitioners without ML expertise to build effective ML applications using GFMs. Through experiments on two benchmark datasets, we show that a GFM-based detector can indeed outperform the state-of-the-art GNN-based algorithm Argus [ 45 ] . This demonstrates the potential of GFMs in cybersecurity-related use cases, opening the way for further research on other cybersecurity problems involving graph-structured data.
We extend previous work on GFM-based lateral movement detection, improving the design of the detector with an input graph construction module that retrieves the most relevant contextual data and an output post-processing module that leverages domain knowledge on lateral movement to eliminate false positives. We thoroughly demonstrate the impact of these improvements on detection performance through experiments on two benchmark datasets.
Overall, we provide evidence that GFMs can already be used in valuable cybersecurity-related applications, motivating further research on this topic. The rest of this paper is structured as follows. We start with necessary background on lateral movement detection and graph foundation models in Section 2 . Then, we describe the design of our GFM-based detector in Section 3 , and report on our experiments in Section 4 . Finally, we discuss the limitations and possible extensions of our work in Section 5 .
We first provide some necessary background and definitions. Section 2.1 defines lateral movement detection, then Section 2.2 reviews past research on this problem. Finally, we provide an introduction to graph foundation models in Section 2.3 , focusing on Ultra [ 15 ] , which is the model we use in this work. Lateral movement is a widespread offensive tactic that consists in propagating from one compromised host to another within the target network. It is a critical phase of advanced, multi-step intrusions as it allows the attacker to explore the network and move closer to their end goal (e.g., stealing sensitive data from a given server or deploying ransomware on all hosts). Many techniques and procedures exist for lateral movement, often leveraging legitimate tools and credentials [ 1 ] . This diversity makes detecting lateral movement challenging.
Internal network traffic and authentication logs are useful data sources in the search for lateral movements 1 1 1 Note that our threat model assumes the integrity of these data sources. . Such data can be efficiently represented as a graph whose nodes are the hosts of an enterprise network, with edges standing for information flows between hosts. Additional nodes representing user accounts can also be included in this graph when authentication logs are available. The graph is typically directed, and it can also be made temporal (network flows and authentication events are timestamped) and heterogeneous (there are several edge types representing, for instance, network protocols or authentication packages). Lateral movement then results in unexpected edges in this graph. From a mathematical perspective, lateral movement detection can thus be phrased as a graph-based anomaly detection problem.
4. Practical Deployment, Analysis & Case Studies We consider a graph sequence ( I t ) t ≥ 0 \big(\mathcal{G}_{t}\big)_{t\geq{0}} , where each graph I t = ( I t , I t , I t ) \mathcal{G}_{t}=(\mathcal{V}_{t},\mathcal{E}_{t},\mathcal{R}_{t}) represents events recorded in a time window t t and is defined by its node set I t \mathcal{V}_{t} , edge set I t \mathcal{E}_{t} and relation (or edge type) set I t \mathcal{R}_{t} .
Edges, defined by a source node u u , an edge type r r , and a destination node v v , are denoted ( u , r , v ) ∈ I t × I t × I t (u,r,v)\in\mathcal{V}_{t}\times\mathcal{R}_{t}\times\mathcal{V}_{t} . Note that such heterogeneous graphs are typically called knowledge graphs in the literature. The goal of lateral movement detection is to build an anomaly scoring function s s such that s I ( u , r , v , t ) s(u,r,v;t) is large if the edge ( u , r , v ) (u,r,v) is anomalous in the graph I t \mathcal{G}_{t} . Finally, we define the union of two graphs as the graph whose node, edge, and relation sets are the union of theirs.
We now review the main approaches to lateral movement detection in the literature, distinguishing three main categories: heuristics, linear and multilinear link predictors, and graph neural networks. Early work on lateral movement detection uses rather simple models and heuristics. In particular, a straightforward way to define anomalous edges in a temporal graph is to count the occurrences of each edge over time. The edges that appear the least frequently are then deemed anomalous. Additional edge features, such as edge type or timestamp, can also be taken into account when looking for rare edges [ 7 ] . The main shortcoming of this basic heuristic is its tendency to generate many false positives, as rare edges are often observed due to benign errors or legitimate behaviors. A typical way to mitigate this problem is to look for clusters of rare edges sharing a common source node [ 32 , 33 , 43 , 7 ] , since attackers often use one compromised host as a stepping stone to explore the rest of the network. Rare connections between hosts can also be correlated with other possible signs of lateral movement, such as the creation of a new service on the target host [ 30 ] .
Alternatively, simple statistical models can be used to characterize normal rare edges, thus weeding out false positives [ 18 ] , or to detect anomalous paths in the host communication graph [ 6 ] . Finally, a closely related approach consists in mining frequent patterns among edges instead of frequent edges [ 39 ] . These patterns then also cover rarely observed edges that share some distinctive traits with frequent edges, ensuring that such rare but legitimate edges are not mistakenly flagged as malicious.
Detecting anomalous edges in a graph is in fact complementary to the well-studied problem of link prediction , i.e., predicting which new edges are the most likely to appear in a given graph. Since anomalous edges are those least likely to appear, a good link predictor can also be used as an anomaly detector. Several models that were initially designed for link prediction, typically for recommender systems, were thus subsequently used for lateral movement detection. These models include matrix factorization [ 37 ] , tensor factorization [ 12 , 13 ] , factorization machines [ 41 ] and latent space models [ 26 ] , which are all multilinear models. More specifically, these models compute a latent vector for each node during training, then define the probability of an edge as a function of the dot product between its endpoints’ latent vectors. A closely related approach relies on graph embedding algorithms such as node2vec [ 16 ] , which also compute a latent vector (also called embedding) for each node. Linear models can then take these vectors as input in order to predict normal edges and/or detect anomalous ones [ 44 , 50 , 8 , 35 ] .
Finally, more recent and sophisticated link prediction algorithms go beyond linear models and use multilayer graph neural networks [ 10 ] . As a consequence, research on lateral movement detection has also adopted GNNs. Early contributions treated internal network traffic or authentication logs as a static graph, training standard GNNs on all past data to predict future edges [ 28 , 40 ] . Subsequent work introduced a temporal perspective by representing connections between internal hosts as a sequence of graphs. This sequence can then be modeled by intertwining a GNN and a recurrent neural network (RNN), giving the model the ability to detect temporal anomalies in addition to structural ones [ 23 , 22 , 45 ] . The current state-of-the-art lateral movement detection algorithm, Argus [ 45 ] , relies on this RNN-GNN combination.
Following the emergence of powerful foundation models for modalities such as text and images, the graph machine learning community has started exploring the possibility of building such foundation models for graph-related tasks. As a result, such models have been proposed for various tasks, including node classification [ 19 , 49 ] , node anomaly detection [ 36 ] , and link prediction [ 11 , 38 ] . In particular, link prediction in knowledge graphs has been addressed by several GFMs [ 15 , 46 ] . This is especially interesting for lateral movement detection, which can be framed as detecting anomalous edges in a knowledge graph.
This work focuses on Ultra [ 15 ] , a GFM designed for link prediction in knowledge graphs. Ultra builds upon the Neural Bellman-Ford Network [ 51 ] (NBFNet) architecture to predict possible edges in any knowledge graph I = ( I , I , I ) \mathcal{G}=(\mathcal{V},\mathcal{E},\mathcal{R}) through the following steps. First, reciprocal edges are added to the graph I \mathcal{G} : for each relation r ∈ I r\in\mathcal{R} , a reciprocal relation r − 1 r^{-1} is defined and a new edge ( v , r − 1 , u ) (v,r^{-1},u) is created for each existing edge ( u , r , v ) ∈ I (u,r,v)\in\mathcal{E} . Then, a graph of relations I R = ( I , I R , I R ) \mathcal{G}_{\mathrm{R}}=(\mathcal{R},\mathcal{E}_{\mathrm{R}},\mathcal{R}_{\mathrm{R}}) is built. Its nodes are the relations of the original knowledge graph I \mathcal{G} , and an edge from relation r r to relation r ′ r^{\prime} indicates that there exist two edges in I \mathcal{G} , with respective types r r and r ′ r^{\prime} , that have at least one node in common.
This common node can be either the source or destination of each of the two edges, thus there are four possible types of interactions between relations r r and r ′ r^{\prime} (i.e., | I R | = 4 |\mathcal{R}_{\mathrm{R}}|=4 ). A first NBFNet is trained to compute embeddings of the relations in I \mathcal{R} given the graph of relations I R \mathcal{G}_{\mathrm{R}} . Then, given the original graph I \mathcal{G} and these relation embeddings, a second NBFNet predicts the probability of any edge ( u , r , v ) ∈ I × I × I (u,r,v)\in\mathcal{V}\times\mathcal{R}\times\mathcal{V} . The authors of Ultra pre-trained three such models on a set of knowledge graphs representing knowledge bases from several domains. They showed that these models achieved competitive link prediction performance on knowledge graphs not included in their training set, which makes them foundation models for link prediction in knowledge graphs.
From a high-level perspective, a pre-trained Ultra model is a function that takes as input a knowledge graph I = ( I , I , I ) \mathcal{G}=(\mathcal{V},\mathcal{E},\mathcal{R}) (which we call the context graph ) and a triple ( u , r , v ) ∈ I × I × I (u,r,v)\in\mathcal{V}\times\mathcal{R}\times\mathcal{V} , and returns a score g I ( u , r , v , I ) g(u,r,v;\mathcal{G}) that is large if the edge ( u , r , v ) (u,r,v) is likely to appear in the graph I \mathcal{G} . In previous work [ 25 ] , we showed that the pre-trained models introduced in the Ultra paper [ 15 ] could be used for lateral movement detection without retraining, achieving competitive detection performance with respect to standard multilinear models. Here, we extend this work by designing a better detector using the Ultra50g model. This GFM has 177K parameters and is openly available on GitHub 2 2 2 https://github.com/DeepGraphLearning/ULTRA and HuggingFace 3 3 3 https://huggingface.co/mgalkin/ultra_50g . Our hypothesis is that significant performance gains can be unlocked using the same pre-trained model, only through changes in context graph construction and output post-processing—an approach inspired by LLM-based applications.
We improve upon our initial algorithm, UltraLMD [ 25 ] , by drawing inspiration from the state-of-the-art GNN-based detector Argus [ 45 ] . Through this approach, we investigate the possibility of replicating the performance of a specially designed GNN by cleverly querying a pre-trained GFM. We provide an overview of our new detector, called UltraLMD ++ , in Section 3.1 , then describe its main components in further detail: context graph construction (Section 3.2 ), anomaly scoring (Section 3.3 ), and output post-processing (Section 3.4 ).
Given a sequence of authentication events and/or network flows, our lateral movement detector applies the following steps, illustrated in Figure 1 . First, the events are split into fixed-length windows . Then, for each time window t t , we build a graph I t \mathcal{G}_{t} representing the events within this window. In order to compute anomaly scores for the edges in I t \mathcal{G}_{t} , we first need to build a context graph I t \mathcal{H}_{t} using past events (Section 3.2 ). This context graph can then be passed as input to the GFM, which predicts how likely the edges in I t \mathcal{G}_{t} are given the context graph I t \mathcal{H}_{t} . Anomaly scores are derived from these predictions (Section 3.3 ). Finally, these anomaly scores are refined by leveraging the structure of the graph I t \mathcal{G}_{t} , building upon the idea that lateral movement edges tend to be clustered into connected regions of the network (Section 3.4 ).
At each time step t t , we observe a new graph I t = ( I t , I t , I t ) \mathcal{G}_{t}=(\mathcal{V}_{t},\mathcal{E}_{t},\mathcal{R}_{t}) . Our goal is to compute an anomaly score for each edge in I t \mathcal{E}_{t} by comparing the graph I t \mathcal{G}_{t} with past graphs { I t ′ ; t ′ < t } \left\{\mathcal{G}_{t^{\prime}};\,t^{\prime}
As explained in Section 2.3 , we consider a GFM that takes as input a context graph and a possible edge, and predicts the probability of that edge appearing in the context graph. Time-dependent information can thus be passed to the GFM through the construction of this context graph . Specifically, given the current graph I t \mathcal{G}_{t} and the sequence of past graphs { I t ′ ; t ′ < t } \left\{\mathcal{G}_{t^{\prime}};\,t^{\prime}
The long-term context graph is simply the union of all past graphs, I t L = I t ′ < t I t ′ . \mathcal{H}_{t}^{\mathrm{L}}=\bigcup_{t^{\prime}
The similarity function c c we use in our experiments is simple and computationally inexpensive. It is defined as the sum of two components, c = c V + c E c=c_{\mathrm{V}}+c_{\mathrm{E}} , where c V c_{\mathrm{V}} is the Jaccard index of the respective node sets of the two graphs, and c E c_{\mathrm{E}} measures the similarity of the two graphs in terms of edge types. Let θ r I ( I t ) = | { ( u , r ′ , v ) ∈ I t : r ′ = r } | \theta_{r}(\mathcal{G}_{t})=|\{(u,r^{\prime},v)\in\mathcal{E}_{t}:\,r^{\prime}=r\}| be the number of edges of type r r in the graph I t \mathcal{G}_{t} . Then the relation similarity function c E c_{\mathrm{E}} is defined as where θ ¯ r \bar{\theta}_{r} and σ r \sigma_{r} denote the mean and standard deviation of θ r \theta_{r} over the set of graphs { I t ′ ; t ′ ≤ t } \left\{\mathcal{G}_{t^{\prime}};\,t^{\prime}\leq{t}\right\} , respectively. In other words, c E c_{\mathrm{E}} is the cosine similarity between the standardized vectors of relation counts of the two graphs.
Given the current graph I t \mathcal{G}_{t} and the short and long-term context graphs I t S \mathcal{H}_{t}^{\mathrm{S}} and I t L \mathcal{H}_{t}^{\mathrm{L}} , we can now use the GFM to compute anomaly scores for the edges of I t \mathcal{G}_{t} . As stated in Section 2.3 , the GFM is a function that computes a score g I ( u , r , v , I ) g(u,r,v;\mathcal{H}) given a context graph I = ( I I , I I , I I ) \mathcal{H}=(\mathcal{V}_{\mathcal{H}},\mathcal{E}_{\mathcal{H}},\mathcal{R}_{\mathcal{H}}) and an edge ( u , r , v ) ∈ I I × I I × I I (u,r,v)\in\mathcal{V}_{\mathcal{H}}\times\mathcal{R}_{\mathcal{H}}\times\mathcal{V}_{\mathcal{H}} , with higher scores meaning more likely edges. We turn these scores into anomaly scores as follows. First, we define the predicted probability of the destination node v v given the source u u , the edge type r r , and the context graph I \mathcal{H} as The probability of the source node u u given the destination v v , the edge type r r , and the context graph I \mathcal{H} can be defined in a similar way using the reciprocal relation r − 1 r^{-1} , defined in Section 2.3 . The anomaly score of the edge ( u , r , v ) (u,r,v) given the context graph I \mathcal{H} is then defined as Two specific cases are handled differently. First, if ( u , r , v ) ∈ I I (u,r,v)\in\mathcal{E}_{\mathcal{H}} , then we set s I ( u , r , v , I ) = 0 s(u,r,v;\mathcal{H})=0 . In other words, known edges are considered normal . Note that while the long-term context graph contains all previously observed edges, the short-term context graph only contains edges from the past graphs most similar to the current graph. As a consequence, an edge that was previously observed in a different context can still be declared anomalous in the present context by our detector. The other specific case arises when scoring an edge whose type does not exist in the context graph, that is, r ∉ I I r\notin\mathcal{R}_{\mathcal{H}} . Since the GFM is unable to compute scores for such unknown edge types, we then define the anomaly score as the average over the set of known edge types I I \mathcal{R}_{\mathcal{H}} . With these definitions, the anomaly score for an edge ( u , r , v ) (u,r,v) given the short and long-term context graphs I t S \mathcal{H}_{t}^{\mathrm{S}} and I t L \mathcal{H}_{t}^{\mathrm{L}} is In addition to individually scoring each edge in the current graph, looking for connected clusters of anomalous edges is a widespread approach in the lateral movement detection literature [ 32 , 8 , 26 , 7 ] . The motivation for this strategy is that attackers typically perform several lateral movements originating from the same compromised host, whereas rare but legitimate activity is randomly scattered across the internal network. Argus leverages this domain knowledge through the design of its decoder (i.e., the last GNN layer that predicts likely edges). Once again, since we build upon a pre-trained model, we cannot change its architecture and must therefore look for a different method.
We draw inspiration from Bowman et al. [ 8 ] , who proposed discarding all anomalous edges that do not share a node with at least one other anomalous edge . This idea can be translated into the following edge score refinement method, formally described in Algorithm 1 of Appendix 0.A . For each edge e e in the current graph I t \mathcal{G}_{t} , we retrieve the anomaly scores (as defined in Equation 1 ) of all edges in I t \mathcal{G}_{t} that share at least one node with e e . Then, there are two possibilities: either there is at least one edge in this set with a higher anomaly score than e e , thus for any detection threshold low enough to declare e e anomalous, e e will be adjacent to another anomalous edge; or e e is the highest-scored edge within its neighborhood. In that second case, we set the score of e e to the maximum of the scores of adjacent edges, so that e e is only declared anomalous when there is at least one other anomalous edge within its neighborhood. In practice, this score refinement method can be implemented efficiently using a message passing algorithm.
5. Performance Evaluation & Extended Technical Observations We now empirically study the behavior and performance of UltraLMD ++ , specifically investigating the following questions. First, since our goal is to build a lateral movement detector that is at least as reliable as the state-of-the-art algorithm Argus [ 45 ] , we compare their respective detection performance on two public benchmark datasets. Secondly, since UltraLMD ++ differs from the original UltraLMD detector in two aspects (namely, context graph retrieval and score refinement), we are interested in evaluating the exact contribution of each of these two improvements . Third, an expected benefit of using a GFM-based lateral movement detector is that it can handle concept drift without retraining. Thus we investigate the temporal dynamics of the distribution of anomaly scores to assess the robustness of UltraLMD ++ to concept drift . Finally, the computational cost of UltraLMD ++ is an important aspect of its real-world usability. We thus study the run time of each of its components (i.e., context graph construction, score computation, and score refinement).
We implemented UltraLMD ++ in Python and make the code openly available 4 4 4 https://github.com/cl-anssi/UltraLMD . As for Argus , we used the implementation provided by the authors 5 5 5 https://github.com/C0ldstudy/Argus . We run our experiments on a 2.2GHz, 40-core CPU with 384GB of RAM, and an Nvidia GeForce RTX 2080 Ti GPU with 11GB of memory. The datasets and evaluation metrics used in our experiments are described in Section 4.1 . We then present our results on the two datasets in Sections 4.2 and 4.3 , respectively.
We compare UltraLMD ++ and Argus on two benchmark datasets: the "Operationally Transparent Cyber" ( OpTC ) dataset released by DARPA in 2020, and the "Comprehensive, Multi-Source Cyber-Security Events" ( LANL ) dataset released in 2015 by the Los Alamos National Laboratory [ 21 , 20 ] . OpTC consists of host and network logs generated over nine days in a simulated enterprise network. Three distinct attacks were carried out by pentesters against this simulated network, two of which comprise a lateral movement phase. The first six days are used for training Argus , and both Argus and UltraLMD ++ are evaluated on the last three days, during which the attacks take place. As for the LANL dataset, it contains anonymized host logs and network flows collected over 58 days within LANL’s enterprise network. A red team exercise took place during this time frame, and lateral movement events are labeled. Since the first of these events occurs during the 42 nd 42^{\mathrm{nd}} hour, we use the first 41 hours for training Argus and the remaining data for evaluation. Note that while the authors of Argus used the same datasets in their experiments, we perform different preprocessing steps here, which leads to discrepancies with respect to the results reported in the Argus paper [ 45 ] . See Appendix 0.B for more details.
Both Argus and UltraLMD ++ require representing the datasets as sequences of graphs. First of all, we chunk both datasets into fixed-length time windows. We use the same window lengths as the Argus paper, namely one hour for the LANL dataset and six minutes for the OpTC dataset. For Argus , we then use the same graph construction method as the original paper. As for UltraLMD ++ , the graphs are built as follows. For each remote authentication event, we create an edge from the source host to the destination host. The type of the edge is the pair (authentication package, logon type). We also create host-host edges for network flow events, whose type is the pair (transport protocol, destination port). To limit the number of edge types, only the 20 flow types most frequently seen during the training period are kept, and all other types are replaced with a single "Other" type. We add user-host edges for each authentication event, which indicate that the user has logged on from or to the host. Finally, we define five node types: user account, computer account, built-in account (e.g., SYSTEM or LOCAL SERVICE), computer, and domain. These types are represented as nodes and linked to other nodes with edges of a special type. See Figure 2 for a summary of these graph representations, and Table 1 for a summary of the datasets. Note that for consistency with Argus , only host-host edges representing network flows in the OpTC dataset and remote authentications in the LANL dataset are given anomaly scores.
We compare the detection performance of Argus and UltraLMD ++ using the following metrics. First, the area under the ROC curve ( AUC ) is a standard metric for binary classification, which captures the trade-off between the true positive rate (TPR, also called recall) and the false positive rate (FPR) at various detection thresholds. Since the AUC tends to be overly optimistic in highly imbalanced settings (base rate fallacy [ 3 ] ), we also compute the average precision ( AP ), which evaluates the ratio between the number of true and false positives at different true positive rates. This metric puts more emphasis on low-FPR settings, which corresponds to the operational constraints of intrusion detection. Finally, to get a more realistic picture of each detector’s reliability in a real-world deployment, we compute the recall for various detection budgets B B ( Rec@ B \boldsymbol{B} ). In other words, Rec@ B B is the proportion of lateral movement edges that are detected when the top B B most anomalous edges in each time window are investigated.
We run both Argus and UltraLMD ++ on the OpTC dataset, using the same hyperparameters as the authors for Argus and setting the number K K of past graphs to include in the short-term context of UltraLMD ++ to 100. The results of these experiments are shown in Table 2 . We now discuss them in further detail. First of all, UltraLMD ++ consistently outperforms Argus across all metrics , highlighting the ability of GFM-based lateral movement detectors to compete with GNNs that are specifically trained for this task. We emphasize that Ultra50g , which underpins UltraLMD ++ , was not trained on any cybersecurity-related data, whereas Argus was trained on the first 6 days of the OpTC dataset. This makes the performance of UltraLMD ++ especially compelling. Note that the recall at reasonable detection budgets remains rather low for both detectors. However, real-world intrusions often comprise several lateral movements, and detecting some of them can suffice to catch the whole attack. This principle stands for the OpTC dataset, where even detecting 5% of the hundreds of lateral movement edges is enough to make a detector useful.
As for the ablation study, while UltraLMD ++ clearly outperforms UltraLMD , most of the improvement comes from the retrieval component . Only adding score refinement leads to almost identical, and in fact slightly worse performance. This limited impact of score refinement might result from the short length of the time window used for the OpTC dataset: with each graph representing a six-minute window, lateral movement edges are more likely to be scattered across several graphs. As a consequence, graph-based score refinement can actually reduce their anomaly scores as much as those of benign edges.
While this does not refute the general usefulness of score refinement, it does point to unfavorable settings that can make it less effective. Still, the performance gain brought by context graph retrieval sustains our main hypothesis: careful input design can yield superior detection performance out of the same GFM. Regarding score dynamics, Figure 3 shows the evolution of the distribution of anomaly scores ( 90 th 90^{\mathrm{th}} , 99 th 99^{\mathrm{th}} , and 99.9 th 99.9^{\mathrm{th}} percentiles) over time, as well as the scores of lateral movement edges, for Argus and UltraLMD ++ . Due to the limited duration (three days) of the OpTC test set, no conclusion can be drawn regarding each detector’s propensity to concept drift from this dataset. However, we observe that Argus performs better on the first attack (around window 130) than on the second (windows 350-400), while UltraLMD ++ predicts relatively high anomaly scores for lateral movement edges in both attacks. This further demonstrates the superior reliability of UltraLMD ++ on the OpTC dataset.
Finally, Figure 4 shows the average run time of UltraLMD ++ for a single time window on OpTC. With only a few seconds of computation for a six-minute window, UltraLMD ++ is efficient enough to run in real time . Note that the anomaly scoring step makes up for most of the computational cost, which could thus be significantly reduced with more powerful GPUs. Similarly to our experiments on OpTC, we also run Argus with the same hyperparameters as the authors on the LANL dataset.
As for UltraLMD ++ , we set the number K K of past graphs to include in the short-term context to 10. Note that many lateral movement edges are repeated several times in the LANL dataset (i.e., the red team repeated the same lateral movement at different timestamps). Since detecting a single occurrence of each lateral movement edge can be considered sufficient, we also compute the performance metrics after removing duplicates. Specifically, for each evaluated detector, we only keep the highest-scoring instance of each unique lateral movement edge. The results of our experiments with and without this deduplication step are shown in Table 3 .
Starting with the results without deduplication , UltraLMD ++ performs best in terms of recall at fixed detection budgets , while Argus performs best in terms of AUC and AP. In contrast, UltraLMD ++ outperforms Argus across all metrics when removing duplicate lateral movement edges . The reason for this discrepancy is that we designed our detector to treat edges that appear in both the short and long-term context graphs as normal. As a consequence, even though lateral movement edges generally get a high anomaly score on their first occurrence, they are then included in the context graphs when they reoccur.
However, since detecting a lateral movement edge on its first occurrence is arguably good enough, this is not a major flaw. Besides, even without deduplication, UltraLMD ++ outperforms Argus with respect to the recall at fixed detection budgets, which more closely mirrors the constraints of real-world deployments. UltraLMD ++ can thus be considered more effective than Argus . Again, we emphasize that this level of performance is reached using a GFM that was not trained for lateral movement detection.
The respective contributions of context graph retrieval and anomaly score refinement to detection performance are more evenly distributed than in the OpTC experiment. Adding either one of these components increases almost all metrics, and adding both is even better, allowing UltraLMD ++ to consistently outperform Argus (whereas UltraLMD does worse than Argus by several metrics). Overall, this demonstrates the usefulness of the two improvements we bring to the original UltraLMD detector, further confirming that adequately querying a pre-trained GFM has a significantly positive impact.
The evolution of the distribution of anomaly scores over time and the scores of lateral movement edges for Argus and UltraLMD ++ are displayed in Figure 5 . The distribution remains rather stable for UltraLMD ++ , except for a downward trend in the first 400 windows. This trend is expected: as more and more past graphs become available, the context graphs used for anomaly scoring become denser and more similar to the current graph, thus the new edges appear less and less anomalous.
In contrast, evidence of drift can be observed for Argus . In particular, the 99 th 99^{\mathrm{th}} and 99.9 th 99.9^{\mathrm{th}} percentiles of the distribution exhibit a slight upward trend, suggesting that the model becomes less and less well-adjusted to the data distribution as the new graphs start becoming less similar to those in the training set. While this problem could typically be addressed by retraining the model on more recent data, the need for frequent retraining is impractical in real-world settings and can hinder the deployment of ML-based detectors. The ability of UltraLMD ++ to straightforwardly adapt to distribution shifts is therefore a significant upside.
Finally, Figure 6 shows the average run time of UltraLMD ++ for a single time window on LANL. Similarly to OpTC, the run time is low enough for UltraLMD ++ to be run in real time (less than two minutes per one-hour window). This time is also mostly spent on anomaly scoring. Overall, the ability of UltraLMD ++ to run in real time on a 16K-host enterprise network using rather affordable hardware demonstrates the efficiency of GFMs, which are typically orders of magnitude smaller than LLMs in terms of parameter count. This efficiency is another upside of GFMs for cybersecurity-related applications, which often deal with sensitive data and must therefore be run on premise.
We now discuss the limitations of our work as well as its possible extensions and implications for future research. First of all, UltraLMD ++ could still be improved in several directions. In particular, whether fine-tuning a pre-trained GFM could improve detection performance remains an open question. In that regard, a noteworthy aspect of Argus is that it was trained with a specific loss function, which was shown to yield better results [ 45 ] . Fine-tuning GFMs with carefully designed loss functions might thus be a lead worth investigating. Future work could also focus on the retrieval component of our detector: first, the similarity function could be improved so that more relevant context graphs are retrieved. Secondly, a current limitation of UltraLMD ++ is that it needs to observe an entire graph in order to compute its similarity to past graphs and score its edges.
Malicious edges can thus only be detected once the time window they fall into is over, which can be problematic in time-critical situations. A possible solution could be to train a model to predict which graphs are the most relevant at a given time, so that these graphs can be retrieved in advance. This approach is similar to the one used by Gutflaish et al. [ 17 ] to dynamically rescale anomaly scores in the context of user behavior analysis. Finally, experimenting with other GFMs , such as the more recently introduced TRIX [ 46 ] , could also increase detection performance.
Beyond lateral movement detection, there is significant potential for useful cybersecurity-related applications of GFMs. A straightforward way to identify such applications is to consider past research on using GNNs in this field. This includes host and network intrusion detection [ 4 ] , malware detection [ 5 ] , and report analysis for cyber threat intelligence [ 14 ] . The benefits brought by GFMs in such cases could be the following. First, by making it possible to develop new applications without training any model, they could accelerate innovation . In particular, lowering the required ML expertise would allow more domain experts to build graph ML-based applications tailored to their own needs. Secondly, in the specific case of intrusion detection, GNN-based methods typically require training one model for each monitored network. This model must also be regularly retrained to avoid concept drift. In contrast, our experiments show that a single GFM can deliver high detection performance in several different enterprise networks without any retraining. GFMs could thus make GNN-based intrusion detection more practical in real-world settings. Finally, applications built upon GFMs would also directly benefit from future research on these models: since no retraining is needed, substituting a new GFM into an existing application to study its performance is straightforward.
Besides the aforementioned opportunities, the adoption of GFMs in cybersecurity would also come with potential risks. Specifically, threats related to adversarial machine learning can be exacerbated in foundation models. For instance, creating adversarial examples [ 52 ] against an openly accessible GFM is easier than against a private, specifically tailored GNN. Note, however, that crafting an adversarial example against GFM-based detectors such as UltraLMD ++ would require additional knowledge besides the model itself—namely, since the anomaly scores depend on the context graph, the adversary would also need access to the data used to build this context graph. Risks related to adversarial examples thus depend on the application. Data poisoning [ 47 ] is another potential threat that becomes more serious when relying on pre-trained models: ensuring that GFMs used in cybersecurity-related applications are trustworthy and were not trained on poisoned data would be critical. Finally, if a GFM was trained specifically for cybersecurity applications and made openly accessible, the confidentiality of its training data against model inversion attacks [ 48 ] would be a legitimate concern. While none of these potential threats definitely precludes the use of GFMs in the cybersecurity domain, studying them remains instrumental to the adoption of GFM-based applications.
The emergence of graph foundation models could be a remarkable opportunity for researchers and practitioners in cybersecurity. By removing the need to train task-specific models, GFMs shift the focus onto other aspects of ML application development, such as input construction and output post-processing. This focus shift could both make it easier for domain experts to build applications relying on graph machine learning, and make these applications more practical in real-world settings. Through a detailed case study centered around lateral movement detection, we provide evidence of this potential by demonstrating that a GFM-based detector can outperform a more traditional approach that requires training a GNN from scratch. These initial results call for further research on the use of GFMs for cybersecurity. In particular, the numerous applications of GNNs in this domain are straightforward starting points for follow-up research. Investigating the effectiveness of GFM-based systems for these various use cases will in turn enable a more thorough assessment of the impact of GFMs on the field at large.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Network%20detection%20and%20response • https://en.wikipedia.org/wiki/Threat%20hunting • https://en.wikipedia.org/wiki/Cyber%20kill%20chain • https://docs.inopli.com/astral/rules/detection-capabilities/lateral-movement-and-internal-traffic-detection • https://github.com/leendalloul/lateral-movement-detection-showcase • https://developer.hashicorp.com/well-architected-framework/secure-systems/infrastructure/prevent-lateral-movement • https://arxiv.org/html/2504.13527v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Internal Network Lateral Movement Detection System.
! Define Extended Access List to Block Malicious Traffic ip access-list extended SECURE_PERIMETER_ACL remark Block Inbound Telnet and Unencrypted Services deny tcp any any eq 23 log remark Permit Verified Web SSL Traffic permit tcp any any eq 443 permit tcp any any eq 80 remark Mitigate ICMP Flood and Ping Sweeps permit icmp any any echo-reply deny icmp any any echo log deny ip any any log
! Apply ACL to Ingress Interface GigabitEthernet0/0 interface GigabitEthernet0/0 ip access-group SECURE_PERIMETER_ACL in no shutdown end write memory
Extended IP access list SECURE_PERIMETER_ACL (Cisco Packet Tracer) ──────────────────────────────────────────────────────────────────────── 10 deny tcp any any eq telnet log (142 matches) [Probes Dropped] 20 permit tcp any any eq 443 (18402 matches) [TLS 1.3 Traffic Permitted] 30 permit tcp any any eq 80 (4812 matches) 40 deny icmp any any echo log (524 matches) [Flood Mitigated] 50 deny ip any any log (38 matches) [Default Implicit Deny Rule] ──────────────────────────────────────────────────────────────────────── [✓] Packet Tracer Verification: 0 Unsanitized Ingress Leaks on Gi0/0
| Interface Port | Network Zone | Filter Applied | Traffic Processed | Firewall Decision |
|---|---|---|---|---|
| Gig0/0 (WAN) | Untrusted External | Extended ACL 101 | 24,810 Packets | INSPECTED & FILTERED |
| Gig0/1 (DMZ) | Public Web Services | Port 443 Only | 18,402 Packets | PERMITTED |
| Gig0/2 (LAN) | Corporate Users | 802.1X Port Security | 142 Probes | DENIED & QUARANTINED |