Complete Technical Paper Content — Keystroke Dynamics Based Continuous Authentication System
Overview & System Context
Keystroke Dynamics Based Continuous Authentication System: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9690 Words · Real Software Screenshots: 1 1. Executive Overview & Technical Background Keystroke logging, often referred to as keylogging or keyboard capturing, is the action of recording (logging) the keys pressed on a keyboard, typically covertly, so that a person using the keyboard is unaware that their actions are being monitored. Data can then be retrieved by the person operating the logging program. A keystroke recorder or keylogger can be either software or hardware. While the programs themselves are legal, with many designed to allow employers to oversee the use of their computers, keyloggers are most often used for stealing passwords and other confidential information. Keystroke logging can also be utilized to monitor activities of children in schools or at home and by law enforcement officials to investigate malicious usage. Keylogging can also be used to study keystroke dynamics or human-computer interaction. Numerous keylogging methods exist, ranging from hardware and software-based approaches to acoustic cryptanalysis.
A software-based keylogger is a computer program designed to record any input from the keyboard. Keyloggers are used in IT organizations to troubleshoot technical problems with computers and business networks. Families and businesspeople use keyloggers legally to monitor network usage without their users' direct knowledge. Microsoft publicly stated that Windows 10 has a built-in keylogger in its final version "to improve typing and writing services". However, malicious individuals can use keyloggers on public computers to steal passwords or credit card information. Most keyloggers are not stopped by HTTPS encryption because that only protects data in transit between computers; software-based keyloggers run on the affected user's computer, reading keyboard inputs directly as the user types. From a technical perspective, there are several categories: Hypervisor-based: The keylogger can theoretically reside in a malware hypervisor running underneath the operating system, which thus remains untouched. It effectively becomes a virtual machine. Blue Pill is a conceptual example. Kernel-based: A program on the machine obtains root access to hide in the OS and intercepts keystrokes that pass through the kernel. This method is difficult both to write and to combat. Such keyloggers reside at the kernel level, which makes them difficult to detect, especially for user-mode applications that do not have root access. They are frequently implemented as rootkits that subvert the operating system kernel to gain unauthorized access to the hardware. This makes them very powerful. A keylogger using this method can act as a keyboard device driver, for example, and thus gain access to any information typed on the keyboard as it goes to the operating system. API-based: These keyloggers hook keyboard APIs inside a running application. The keylogger registers keystroke events as if it was a normal piece of the application instead of malware. The keylogger receives an event each time the user presses or releases a key. The keylogger simply records it. This is usually done by inject a DLL to other processes. Windows APIs such as GetAsyncKeyState(), GetForegroundWindow(), etc. are used to poll the state of the keyboard or to subscribe to keyboard events. A more recent example simply polls the BIOS for pre-boot authentication PINs that have not been cleared from memory. Form grabbing based: Form grabbing-based keyloggers log Web form submissions by recording the form data on submit events. This happens when the user completes a form and submits it, usually by clicking a button or pressing enter. This type of keylogger records form data before it is passed over the Internet. IME-based: A malicious IME can do keylogging. JavaScript-based: A malicious script tag is injected into a targeted web page, and listens for key events such as onKeyUp(). Scripts can be injected via a variety of methods, including cross-site scripting, man-in-the-browser, man-in-the-middle, or a compromise of the remote website. Memory-injection-based: Memory Injection (MitB)-based keyloggers perform their logging function by altering the memory tables associated with the browser and other system functions. By patching the memory tables or injecting directly into memory, this technique can be used by malware authors to bypass Windows UAC (User Account Control). The Zeus and SpyEye trojans use this method exclusively.
Non-Windows systems have protection mechanisms that allow access to locally recorded data from a remote location. Remote communication may be achieved when one of these methods is used: Data is uploaded to a website, database or an FTP server. Data is periodically emailed to a pre-defined email address. Data is Wirelessly transmitted employing an attached hardware system. The software enables a remote login to the local machine from the Internet or the local network, for data logs stored on the target machine.
descriptions of writing strategies; the writing development of children (with and without writing difficulties), spelling, first and second language writing, and specialist skill areas such as translation and subtitling. Keystroke logging can be used to research writing, specifically. It can also be integrated into educational domains for second language learning, programming skills, and typing skills.
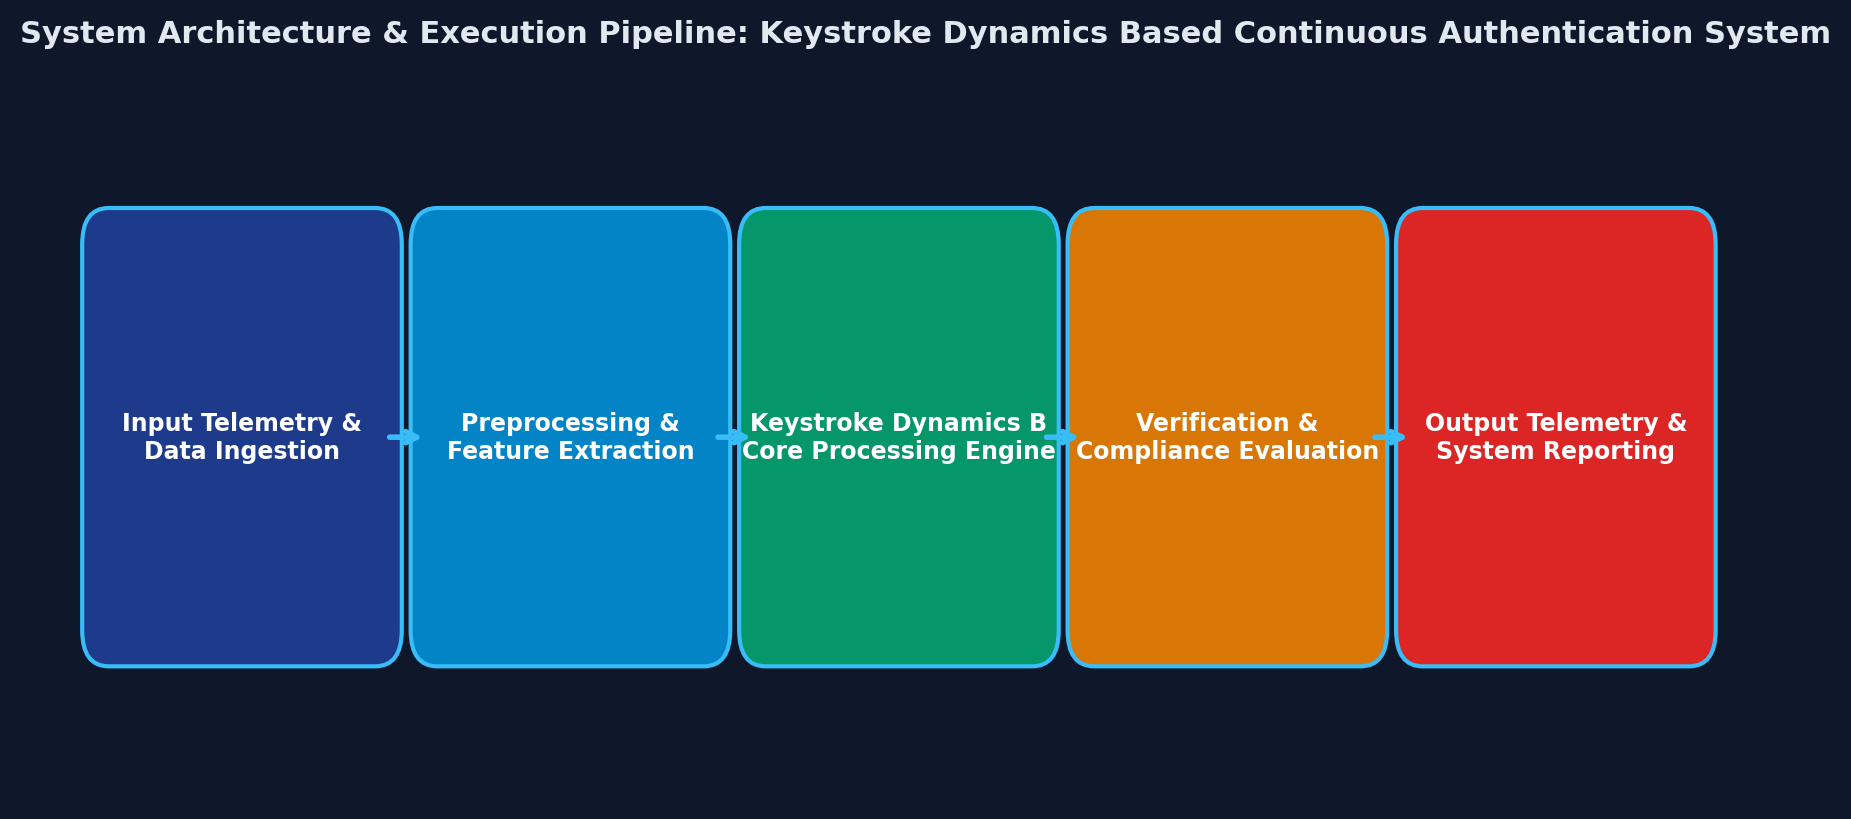
Figure 1: Figure 1: Verified System Architecture & Pipeline Workflow This study also reported that machine learning models trained on genuine typing behavior achieved low false acceptance and false rejection rates in most instances, showing that the use of continuous authentication systems can operate with low error rates. They also found that the typing patterns of most people have enough discriminatory signals that you could create a personal profile based on the typing habits alone. This shows that the same core exploits used by malicious attackers can also form the basis of security systems designed to protect users from intrusions and impersonations. The authors concluded that while keystroke-dynamics authentication is promising, its deployment must carefully balance security, usability, and privacy considerations for the optimal user experience.
Clipboard logging. Anything that has been copied to the clipboard can be captured by the program. Screen logging. Screenshots are taken to capture graphics-based information. Applications with screen logging abilities may take screenshots of the whole screen, of just one application, or even just around the mouse cursor. They may take these screenshots periodically or in response to user behaviors (for example, when a user clicks the mouse). Screen logging can be used to capture data inputted with an on-screen keyboard. Programmatically capturing the text in a control. The Microsoft Windows API allows programs to request the text 'value' in some controls. This means that some passwords may be captured, even if they are hidden behind password masks (usually asterisks). The recording of every program/folder/window opened including a screenshot of every website visited. The recording of search engines queries, instant messenger conversations, FTP downloads and other Internet-based activities (including the bandwidth used).
Hardware-based keyloggers do not depend upon any software being installed as they exist at a hardware level in a computer system. Firmware-based: BIOS-level firmware that handles keyboard events can be modified to record these events as they are processed. Physical and/or root-level access is required to the machine, and the software loaded into the BIOS needs to be created for the specific hardware that it will be running on. Keyboard hardware: Hardware keyloggers are used for keystroke logging utilizing a hardware circuit that is attached somewhere in between the computer keyboard and the computer, typically inline with the keyboard's cable connector. There are also USB connector-based hardware keyloggers, as well as ones for laptop computers (the Mini-PCI card plugs into the expansion slot of a laptop). More stealthy implementations can be installed or built into standard keyboards so that no device is visible on the external cable. Both types log all keyboard activity to their internal memory, which can be subsequently accessed, for example, by typing in a secret key sequence. Hardware keyloggers do not require any software to be installed on a target user's computer, therefore not interfering with the computer's operation and less likely to be detected by software running on it. However, its physical presence may be detected if, for example, it is installed outside the case as an inline device between the computer and the keyboard. Some of these implementations can be controlled and monitored remotely using a wireless communication standard. Wireless keyboard and mouse sniffers: These passive sniffers collect packets of data being transferred from a wireless keyboard and its receiver. As encryption may be used to secure the wireless communications between the two devices, this may need to be cracked beforehand if the transmissions are to be read. In some cases, this enables an attacker to type arbitrary commands into a victim's computer. Keyboard overlays: Criminals have been known to use keyboard overlays on ATMs to capture people's PINs. Each keypress is registered by the keyboard of the ATM as well as the criminal's keypad that is placed over it. The device is designed to look like an integrated part of the machine so that bank customers are unaware of its presence. Acoustic keyloggers: Acoustic cryptanalysis can be used to monitor the sound created by someone typing on a computer. Each key on the keyboard makes a subtly different acoustic signature when struck. It is then possible to identify which keystroke signature relates to which keyboard character via statistical methods such as frequency analysis. The repetition frequency of similar acoustic keystroke signatures, the timings between different keyboard strokes and other context information such as the probable language in which the user is writing are used in this analysis to map sounds to letters. A fairly long recording (1000 or more keystrokes) is required so that a large enough sample is collected. Electromagnetic emissions: It is possible to capture the electromagnetic emissions of a wired keyboard from up to 20 metres (66 ft) away, without being physically wired to it. In 2009, Swiss researchers tested 11 different USB, PS/2 and laptop keyboards in a semi-anechoic chamber and found them all vulnerable, primarily because of the prohibitive cost of adding shielding during manufacture. The researchers used a wide-band receiver to tune into the specific frequency of the emissions radiated from the keyboards. Optical surveillance: Optical surveillance, while not a keylogger in the classical sense, is nonetheless an approach that can be used to capture passwords or PINs. A strategically placed camera, such as a hidden surveillance camera at an ATM, can allow a criminal to watch a PIN or password being entered. Physical evidence: For a keypad that is used only to enter a security code, the keys which are in actual use will have evidence of use from many fingerprints. A passcode of four digits, if the four digits in question are known, is reduced from 10,000 possibilities to just 24 possibilities (104 versus 4! [factorial of 4]). These could then be used on separate occasions for a manual "brute force attack". Smartphone sensors: Researchers have demonstrated that it is possible to capture the keystrokes of nearby computer keyboards using only the commodity accelerometer found in smartphones. The attack is made possible by placing a smartphone near a keyboard on the same desk. The smartphone's accelerometer can then detect the vibrations created by typing on the keyboard and then translate this raw accelerometer signal into readable sentences with as much as 80 percent accuracy. The technique involves working through probability by detecting pairs of keystrokes, rather than individual keys. It models "keyboard events" in pairs and then works out whether the pair of keys pressed is on the left or the right side of the keyboard and whether they are close together or far apart on the QWERTY keyboard. Once it has worked this out, it compares the results to a preloaded dictionary where each word has been broken down in the same way. Similar techniques have also been shown to be effective at capturing keystrokes on touchscreen keyboards while in some cases, in combination with gyroscope or with the ambient-light sensor. Body keyloggers: Body keyloggers track and analyze body movements to determine which keys were pressed. The attacker needs to be familiar with the keys layout of the tracked keyboard to correlate between body movements and keys position, although with a suitably large sample this can be deduced. Tracking audible signals of the user' interface (e.g. a sound the device produce to informs the user that a keystroke was logged) may reduce the complexity of the body keylogging algorithms, as it marks the moment at which a key was pressed.
An anti-keylogger is a piece of software specifically designed to detect keyloggers on a computer, typically comparing all files in the computer against a database of keyloggers, looking for similarities which might indicate the presence of a hidden keylogger. As anti-keyloggers have been designed specifically to detect keyloggers, they have the potential to be more effective than conventional antivirus software; some antivirus software do not consider keyloggers to be malware, as under some circumstances a keylogger can be considered a legitimate piece of software.
Automatic form-filling programs may prevent keylogging by removing the requirement for a user to type personal details and passwords using the keyboard. Form fillers are primarily designed for Web browsers to fill in checkout pages and log users into their accounts. Once the user's account and credit card information has been entered into the program, it will be automatically entered into forms without ever using the keyboard or clipboard, thereby reducing the possibility that private data is being recorded. However, someone with physical access to the machine may still be able to install software that can intercept this information elsewhere in the operating system or while in transit on the network. (Transport Layer Security (TLS) reduces the risk that data in transit may be intercepted by network sniffers and proxy tools.) Keystroke dynamics, keystroke biometrics, typing dynamics, or typing biometrics refer to the collection of biometric information generated by key-press-related events that occur when a user types on a keyboard. Use of patterns in key operation to identify operators predates modern computing, and has been proposed as an authentication alternative to passwords and PIN numbers.
Authentication (from Greek: αIθεντικIς authentikos, "real, genuine", from αIθIντης authentes, "author") is the act of proving an assertion, such as the identity of a computer system user. In contrast with identification, the act of indicating a person or thing's identity, authentication is the process of verifying that identity. Authentication is relevant to multiple fields. In art, antiques, and anthropology, a common problem is verifying that a given artifact was produced by a certain person, or in a certain place (i.e. to assert that it is not counterfeit), or in a given period of history (e.g. by determining the age via carbon dating). In computer science, verifying a user's identity is often required to allow access to confidential data or systems. It might involve validating personal identity documents.
Authentication can be considered to be of three types: The first type of authentication is accepting proof of identity given by a credible person who has first-hand evidence that the identity is genuine. When authentication is required for art or physical objects, this proof could be a friend, family member, or colleague attesting to the item's provenance, perhaps by having witnessed the item in its creator's possession. With autographed sports memorabilia, this could involve someone attesting that they witnessed the object being signed. A vendor selling branded items implies authenticity, while they may not have evidence that every step in the supply chain was authenticated. The second type of authentication is comparing the attributes of the object itself to what is known about objects of that origin. For example, an art expert might look for similarities in the style of painting, check the location and form of a signature, or compare the object to an old photograph. An archaeologist, on the other hand, might use carbon dating to verify the age of an artifact, do a chemical and spectroscopic analysis of the materials used, or compare the style of construction or decoration to other artifacts of similar origin. The physics of sound and light, and comparison with a known physical environment, can be used to examine the authenticity of audio recordings, photographs, or videos. Documents can be verified as being created on ink or paper readily available at the time of the item's implied creation.
Attribute comparison may be vulnerable to forgery. In general, it relies on the facts that creating a forgery indistinguishable from a genuine artifact requires expert knowledge, that mistakes are easily made, and that the amount of effort required to do so is considerably greater than the amount of profit that can be gained from the forgery. In art and antiques, certificates are of great importance for authenticating an object of interest and value. Certificates can, however, also be forged, and the authentication of these poses a problem. For instance, the son of Han van Meegeren, the well-known art-forger, forged the work of his father and provided a certificate for its provenance as well. Criminal and civil penalties for fraud, forgery, and counterfeiting can reduce the incentive for falsification, depending on the risk of getting caught. Currency and other financial instruments commonly use this second type of authentication method. Bills, coins, and cheques incorporate hard-to-duplicate physical features, such as fine printing or engraving, distinctive feel, watermarks, and holographic imagery, which are easy for trained receivers to verify. The third type of authentication relies on documentation or other external affirmations. In criminal courts, the rules of evidence often require establishing the chain of custody of evidence presented. This can be accomplished through a written evidence log, or by testimony from the police detectives and forensics staff that handled it. Some antiques are accompanied by certificates attesting to their authenticity. Signed sports memorabilia is usually accompanied by a certificate of authenticity. These external records have their own problems of forgery and perjury and are also vulnerable to being separated from the artifact and lost.
2. System Architecture & Core Working Principles Taggant fingerprinting – uniquely coded microscopic materials that are verified from a database Encrypted micro-particles – unpredictably placed markings (numbers, layers and colors) not visible to the human eye Holograms – graphics printed on seals, patches, foils or labels and used at the point of sale for visual verification Micro-printing – second-line authentication often used on currencies Serialized barcodes UV printing – marks only visible under UV light Track and trace systems – use codes to link products to the database tracking system Water indicators – become visible when contacted with water DNA tracking – genes embedded onto labels that can be traced Color-shifting ink or film – visible marks that switch colors or texture when tilted Tamper evident seals and tapes – destructible or graphically verifiable at point of sale 2d barcodes – data codes that can be tracked RFID chips NFC chips A difficult-to-reproduce physical artifact, such as a seal, signature, watermark, special stationery, or fingerprint. A shared secret, such as a passphrase, in the content of the message. An electronic signature; public-key infrastructure is often used to cryptographically guarantee that a message has been signed by the holder of a particular private key. The opposite problem is the detection of plagiarism, where information from a different author is passed off as a person's own work. A common technique for proving plagiarism is the discovery of another copy of the same or very similar text, which has different attribution. In some cases, excessively high quality or a style mismatch may raise suspicion of plagiarism.
The ways in which someone may be authenticated fall into three categories, based on what is known as the factors of authentication: something the user knows, something the user has, and something the user is. Each authentication factor covers a range of elements used to authenticate or verify a person's identity before being granted access, approving a transaction request, signing a document or other work product, granting authority to others, and establishing a chain of authority. Security research has determined that for a positive authentication, elements from at least two, and preferably all three, factors should be verified. The three factors (classes) and some of the elements of each factor are: Knowledge: Something the user knows (e.g., a password, partial password, passphrase, personal identification number (PIN), challenge–response (the user must answer a question or pattern), security question). Ownership: Something the user has (e.g., wrist band, ID card, security token, implanted device, cell phone with a built-in hardware token, software token, or cell phone holding a software token). Inherence: Something the user is or does (e.g., fingerprint, retinal pattern, DNA sequence (there are assorted definitions of what is sufficient), signature, face, voice, unique bio-electric signals, or other biometric identifiers). Historically, fingerprints have been used as the most authoritative method of authentication, but court cases in the US and elsewhere have raised fundamental doubts about fingerprint reliability. Outside of the legal system as well, fingerprints are easily spoofable, with British Telecom's top computer security official noting that "few" fingerprint readers have not already been tricked by one spoof or another. Hybrid or two-tiered authentication methods offer a compelling solution, such as private keys encrypted by fingerprint inside of a USB device.
Multi-factor authentication involves two or more authentication factors (something you know, something you have, or something you are). Two-factor authentication is a special case of multi-factor authentication involving exactly two factors. For example, using a bank card (something the user has) along with a PIN (something the user knows) provides two-factor authentication. Business networks may require users to provide a password (knowledge factor) and a pseudorandom number from a security token (ownership factor). Access to a very-high-security system might require a mantrap screening of height, weight, facial, and fingerprint checks (several inherence factor elements) plus a PIN and a day code (knowledge factor elements), but this is still a two-factor authentication.
Enrollment – an individual applies to a credential service provider (CSP) to initiate the enrollment process. After successfully proving the applicant's identity, the CSP allows the applicant to become a subscriber. Authentication – After becoming a subscriber, the user receives an authenticator e.g., a token and credentials, such as a user name. He or she is then permitted to perform online transactions within an authenticated session with a relying party, where they must provide proof that he or she possesses one or more authenticators. Life-cycle maintenance – the CSP is charged with the task of maintaining the user's credential over the course of its lifetime, while the subscriber is responsible for maintaining his or her authenticator(s).
The authentication of information can pose special problems with electronic communication, such as vulnerability to man-in-the-middle attacks, whereby a third party taps into the communication stream, and poses as each of the two other communicating parties, in order to intercept information from each. Extra identity factors can be required to authenticate each party's identity.
Reliably identifying and verifying subjects remains integral to computer system security. Various novel authentication techniques such as biometric authentication systems have been devised in recent years. This paper surveys keystroke-based authentication systems and their applications. Keystroke dynamics is a behavioral biometric that is emerging as an important tool for cybersecurity as it promises to be non-intrusive and cost-effective. Also, no additional hardware is required, making it convenient to deploy. This survey covers novel keystroke datasets, state-of-the-art keystroke authentication algorithms, keystroke authentication on touch screen and mobile devices, and various prominent applications of such techniques beyond authentication. The paper covers all the significant aspects of keystroke dynamics and can be considered as a reference for future researchers in this domain.
The paper includes a discussion of the latest keystroke datasets, providing researchers with up-to-date resources for analysis and experimentation. Additionally, we review the state-of-the-art algorithms adopted within this domain, offering insights into the cutting-edge techniques utilized for keystroke analysis. Moreover, our paper explains the diverse applications of keystroke dynamics, particularly focusing on security, verification and identification uses. Beyond these crucial areas, we mention other additional applications where keystroke dynamics can be applied, broadening the scope of understanding regarding its potential impact across various domains. Unlike previous survey papers that typically concentrate on specific aspects of keystroke dynamics, our comprehensive analysis presents all relevant areas within this field. By introducing discussions on the latest advancements, we provide readers with a thorough understanding of the current landscape and emerging trends in keystroke dynamics research. Furthermore, our paper presents a summary of future research opportunities, highlighting potential areas for exploration and development within the realm of keystroke dynamics. This forward-looking perspective aims to inspire further inquiry and innovation, guiding the trajectory of future studies in this dynamic field.
Keywords— keystroke, authentication, behavioral, identification, imposter, detection, security. User authentication is a process which verifies that someone who is attempting to access services and applications is who they claim to be. There are three broad categories of approaches to authenticating a user. The first category is based on What you know , such as the username and password or answers to security questions. This is also known as Knowledge-based Authentication (KBA). The second category is based on What you have , i.e, a physical object that one can possess, e.g., a security badge or a security key such as Yubikey. The third category is based on What you are , which can be i) physiological , e.g., face, fingerprint, or iris ii) behavioral , e.g., keystroke dynamics, mouse dynamics, mobile motion, or swipes. While KBA currently is still the dominant approach for identity management, there are active efforts in creating alternatives such as face recognition and FIDO. In particular, an emerging field of user authentication is behavioral biometrics, which authenticates a user based on their behavior when interacting with a computing device( What you are ).
Keystroke biometric authentication systems are a convenient and user friendly authentication method where a person is authenticated based on their typing pattern. Though it shows great potential, its real world application so far has been limited. Keystroke biometric authentication systems have several advantages. They are cost effective as no additional hardware is required, only the regular keyboard is needed.
3. Software Implementation, Frameworks & Protocols Keystroke authentication operates by creating a template for each user based on their typing pattern during an enrollment period. Once enrolled, the test sample from the user is contrasted with the representation of that same user and a matching score will be calculated. Matching scores are calculated based on the timing features of keystrokes. Figure 1 provides an overview of the timing features of keystrokes.
Free-text, also known as dynamic text, permits the user to type freely without any restriction [ 85 ] . For example, if a user writes a paragraph on a topic, it will be free-text. Free-text based keystroke dynamics can enable continuous authentication as a user types. Fixed-text or static text [ 66 ] . Fixed-text is constant during the authentication process, during both template creation and testing. The keystroke data for a password can be used to create a second authentication factor.
Semi fixed-text, shares some characteristics with free and fixed-text. Example of semi fixed-text include Linux commands [ 126 ] and the webform keystroke data [ 125 ] . The oldest survey article we reviewed is Alsultan and Warwick’s article from 2013. Alsultan and Warwick [ 12 ] focused on free-text keystroke systems. Fixed-text or semi fixed-text keystroke systems were not included in their survey. In our survey, we focus on all kinds of keystroke systems. Zhong and Deng [ 131 ] presented a comprehensive survey of keystroke dynamics; Giot, Dorizzi, and Rosenberger [ 43 ] provided a review of previously created keystroke benchmarking datasets; Ali et al. [ 10 ] presented an elaborate survey of the keystroke data collection details and classification algorithms. However, as these surveys were published in 2015, they were not able to cover more recent trends in keystroke dynamics research or updated benchmark datasets e.g., [ 24 ] , [ 114 ] , [ 85 ] , [ 125 ] , [ 124 ] etc. available since 2015.
Saini, Kaur, and Bhatia [ 98 ] and Saifan et al. [ 97 ] presented a comprehensive review on keystroke dynamics research - especially for touch screen and mobile devices. But these papers are not up to date as these were published in 2016. Also these papers did not consider all kinds of devices for keystroke dynamics research - their only focus was mobile devices. Shinde, Shetty and Mehra [ 105 ] mainly focused on different aspects of static keystroke authentication. They did not discuss dynamic or continuous keystroke authentication in their survey. In our survey, we explain both static and dynamic keystroke authentication. Ali et al. [ 9 ] provided a comprehensive assessment of the newest datasets and algorithms used in keystroke dynamics based research. This survey was conducted in 2017 and new datasets and algorithms are now available.
Sanghi and Arya [ 100 ] presented a review of the methods and metrics used in keystroke dynamics. This paper described various applications of keystroke dynamics as well. Sadikan, Ramli, and Fudzee [ 95 ] performed a comprehensive analysis of the applications of keystroke dynamics. From this paper, we mention the latest applications of keystroke dynamics. Tewari [ 118 ] discussed only deep learning algorithms for keystroke dynamics. Conversly, in this paper we focus on many differing types of algorithms for keystroke dynamics.
In this survey, we present keystroke dynamics performance metrics, the latest benchmark datasets for keystroke dynamics, state of the art keystroke authentication algorithms, keystroke feature engineering techniques, keystroke dynamics for touch screen and mobile devices, and the most important applications of keystroke dynamics. Table 1 shows a comparison of existing surveys on keystroke dynamics. This paper surveys recent papers on keystroke dynamics. We highlight their unique contributions, advantages and disadvantages. We have categorized the studies based on their contribution to one of the following categories: keystroke datasets, keystroke authentication algorithms, keystroke feature engineering approaches, keystroke authentication on touch screen and mobile devices, applications of keystroke dynamics.
Through this paper, we cover all recent developments of keystroke dynamics research and their applications. We collected papers from 2013-present on keystroke dynamics from sources such as Google Scholar, IEEE and Academia.edu. The following search terms were used: We categorized them based on their contribution and uniqueness. The following contributions were considered: Any sort of novel method to improve the authentication performance of keystroke dynamics based systems such as novel/efficient keystroke authentication algorithm or software, effective keystroke feature engineering approach 4. Practical Deployment, Analysis & Case Studies If a paper contributed in any of the above areas, we included/discussed that paper in our survey. Predominantly papers published after 2013 were considered for this survey as we wanted to cover the developments of keystroke dynamics during the last decade. Previous surveys on keystroke dynamics focused on specific areas such as keystroke dynamics on touch screen and mobile devices, keystroke authentication algorithms and keystroke datasets. In this paper, we cover all the areas of keystroke dynamics. An overview of the structure of this paper is shown in Figure 2 .
Keystroke dynamics research has been ongoing for decades and the main intended application has been verification and identification of subjects. Modern computer systems contain vital user information making it important to ensure the cyber security of computer systems. Authentication via something a user knows (i.e. a password) is no longer sufficient to guarantee the security of sensitive data.
In the context of keystroke dynamics, authentication, verification, and identification have different goals. Authentication means ensuring that a user is who they claim to be by comparing their typing patterns with a previously stored profile. In order to confirm the access of the correct individual, authentication is used during login to the system. Verification process can be applied to different stages of interaction. In order to detect unauthorized/imposter access continuously during a session, verification is performed. Identification process seeks to determine the identity of an unknown user from a pool of candidates based on their typing patterns. In identification process, the input is effectively matched to the most similar profile within a database.
Sridhar, Vaidya and Yawalkar [ 108 ] proposed a keystroke authentication system for intruder detection in secure virtual environments. For this purpose, authentication data from login attempts were stored. Feature sets were extracted from 200 samples of username and password data. Fuzzy Logic algorithms were used in order to develop signatures for each participant. The typing pattern of each participant was compared to the respective signature in order to authenticate the participants. Membership functions of fuzzy logic were implemented for authenticating a participant. For 200 samples, they achieved a FAR of 0.0% and a FRR 0f 0.0% for both Bell MF and Gaussian MF.
Mondal and Bours [ 83 ] proposed three methods in order to identify a person from his/her typing behavior. They proposed pairwise user coupling technique along with different machine learning algorithms. They also tried to analyze person identification via an optimized feature set. For their experiment, they used a novel keystroke dataset. The dataset was gathered from three online exams. The subjects were PACE University undergraduates. 64 students participated in the data collection. The subjects typed minimum 500 keystrokes on each of the three exams. Mondal and Bours used a subset of data from the first exam as a training set. The remaining data was used for testing. They implemented Pairwise User Coupling (PUC) technique on their dataset using the machine learning classifiers. The best accuracy achieved was 89.7%.
Mohlala, Ikuesan, and Venter [ 81 ] proposed a method based on keystroke dynamics in order to collect evidence for digital forensic readiness. The main goal was to collect solid keystroke evidence for forensic investigations. Their proposed model consisted of two phases - 1) the pattern development phase and 2) the pattern testing/validation phase. In the development phase, input data was collected from the subject. They used the output of this phase as the input for the next phase which was the pattern identification phase. In the data storage and preservation phase, the extracted pattern was stored in the database.
A simple regression model decision process was used for subject attribution process. In the application development phase, WEKA machine learning libraries were used for feature classification. The extracted features were - key hold time, down-down time, up-down time, key press pressure, finger area, average hold time, average finger area and average pressure. They used an Android application with a software keyboard for recording raw data. The dataset consisted of 42 subjects. The subjects typed fixed password with 51 samples per subject. For the experiment process, Mohlala, Ikuesan, and Venter implemented their developed tool on the benchmark dataset [ 14 ] . In the pattern development process, 1574 rules were extracted. Each subject’s pattern was accurately attributed to the respective user on the test set, except for one user. However, all subjects were accurately attributed using the attribution mechanism. Based on the results, it was clear that this study could achieve reliable accuracy for subject attribution in digital forensics.
In [ 28 ] , Chen et al. designed a keystroke dynamics based user authentication system for online assesments and examinations. Their proposed framework was based on edge computing architecture. There were keystroke profiles of the users in the framework. In this study, Chen et al. used four features - hold time (HT), press flight time (FT), HT proportion (HTP) and FT proportion (FTP). There were two parts in the profile for static authentication and continuous authentication respectively. In order to perform static keystroke authentication, they used an anomaly detector based on Gaussian model. In the case of continuous keystroke authentication, keystroke events were collected continuously by the framework in order to form a continuous data stream of extracted keystroke timing features. For the evaluation purpose, three public datasets were used ( [ 66 ] , [ 47 ] , [ 114 ] ). In order to investigate the effectiveness of the framework, Chen et al. used a real-world case of an online examination. In order to verify their basic detector, they used this dataset [ 66 ] . Chen et al. achieved an EER of 6.62%. In order to evaluate the performance of keystroke static authentication, they used dataset [ 47 ] and achieved an EER of 5.71%. EER could be decreased to 4.03% using dynamic user profiles mechanism. In order to evaluate the performance of keystroke continuous authentication, they used dataset [ 114 ] . Chen et al. achieved an average EER of 2%. The edge computing architecture was implemented to develop a prototype of online examination system. There were three phases in the online examination system - registration phase, login phase and testing phase. In order to simulate possible security related situations, 27 users participated in the case study. The obtained results for this case study were promising.
There are a number of performance metrics used in keystroke dynamics and each is used to present some specific information about the biometric system. This section describes all the metrics and when they are preferably used. The most common performance metric used in biometric systems are the False Accept Rate (FAR) and the False Reject Rate (FRR). The FAR is the measure of the likelihood that the biometric system will incorrectly grant access to an unauthorized user [ 36 ] . This is calculated as the ratio of the number of false acceptances divided by the total number of impostor attempts, as shown in equation 1 .
The measure of the likelihood that an authorized user will be incorrectly rejected by the biometric system is called the FRR. This is measured by dividing the number of false rejections by the total number of genuine attempts, as shown in Equation 2 . The ideal value for both FAR and FRR is 0%, which translates to granting access to all genuine users while all impostors are caught. However, real world biometric systems are not ideal. Therefore, a lower value for both FAR and FRR is preferred instead. A system with 0% FAR is considered to have utmost security, while a system with 0% FRR is highly convenient.
There is usually a trade-off between security and convenience, as a highly secure system may reject too many genuine users, thus being inconvenient while a highly convenient system may be insecure and therefore ineffective. The FAR is also known as the False Positive Rate (FPR), while the FRR is 1 - True Positive Rate (TPR). The equal error rate (EER) is also a commonly used performance metric, especially when it is challenging to find an operating point between the FAR and FRR. The EER indicates the instance of FAR and FRR intersecting. Similar to the FAR and FRR, a lower EER value is preferred. As shown in Figure 3 (a), a threshold closer to 0 favors convenience (low FRR) but is less secure (high FAR), while a threshold closer to 1 favors security (low FAR) but is less convenient (high FRR). The EER balances these two points.
The Receiver Operating Characteristic (ROC) curve, is a graphical plot of FAR and TPR (i.e., 1 - FRR) that visualizes the performance of a binary classifier while the threshold for classification is changed. This metric provides a clear visualization of keystroke dynamics performance across varying classification thresholds. A perfect classifier will have a point at the top left corner with coordinate (0.0, 1.0) which illustrates no false accept or false reject (Figure 3 (b)). Since this is hardly practical in a large scale system, a classifier closer to the coordinate (0.0, 1.0) is therefore desired. The diagonal from the top right to bottom left corners indicates a random classifier, which is similar to a random guess and therefore not desired. A classifier with an ROC curve lower than the diagonal line is mostly assumed to have been wrongly labeled and therefore can be flipped.
The Area Under the Curve (AUC), often associated with the ROC curve, provides an combined performance measurement across all varying thresholds of classification. 5. Performance Evaluation & Extended Technical Observations In behavioral biometric studies, especially in continuous user authentication, performance metrics such as FAR, FRR, ROC and AUC may not be sufficient, as they fail to illustrate the average keystroke count required for a genuine user to be rejected or an impostor to be detected. Therefore, to further evaluate the performance of a CUA system, the Average Number of Impostor Actions (ANIA) and Average Number of Genuine Actions (ANGA) are used, where the actions in this case are keystrokes [ 84 ] . The ANGA is the number of legitimate actions users can perform before they are wrongfully denied access, while ANIA is the number of actions impostors can do before they are detected and locked-out. ANGA is perfered to be high (in fact, it is desired that a legitimate user should never be denied access), and ANIA as low as possible, so as to reduce the amount of actions an illegitimate user can perform before detection.
The ANIA and ANGA are mostly used in keystrokes dynamics continuous authentication and can be calculated as shown in Equation 3 and Equation 4 , where N N is the amount of consecutive actions a user (genuine or impostor) can finish before an authentication/identification decision is made. The authentication time is an additional metric used in keystroke dynamics to describe the usability in the system. The metric is the total average time necessary for collecting keystroke data and the average of time system takes to permit or deny user access [ 123 ] . While the desire to achieve a very low FAR and FRR stand, it is important to achieve this with a very short authentication time. For example, the authentication system of Zheng et al. [ 130 ] achieved FAR and FRR of 1.30% but with a very long authentication time (approximately 38 minutes). Such a long authentication time would leave impostors uncaught as most impostors require signifigantly less time to complete attacks. Additionally, the mouse dynamics-based authentication of Shen et al. [ 103 ] had 3.33% FAR and 2.12% FRR with about 119 seconds authentication time. Although this FAR and FRR is higher than that of Zhen et al., it could be considered a better system based on the lower authentication time.
Rank-n [ 1 ] is an evaluation method used to measure the performance of keystroke dynamics based authentication systems. A dataset of multiple samples from each subject is used to test the system. For each subject, one of the samples is used as reference sample and the rest of the samples are considered as test samples. A similarity metric such as Euclidean distance is used to measure the similarity of a test sample to the reference sample. The test samples are ranked based on their similarity to the reference sample. The percentage of the inclusion of the correct test sample within the top n ranked samples is measured by the rank-n metric. If the correct test sample is included within the top 5 ranked samples 90% of the time, then the rank-5 accuracy is 90%. Therefore, the rank-n value needs to be lower for better performance. Because for lower rank-n value, there is a better chance that the correct test sample will be ranked higher. A rank-1 accuracy of 90% indicates that the correct test sample is ranked 1st 90% of the time. A comprehensive analysis of the system’s performance is provided by rank-n evaluation.
There are other performance metrics such as precision, recall, ACC (accuracy), BA (balanced accuracy), and the F1-score which are occasionally used in keystroke dynamics. A keystroke dataset is required to perform satisfactory evaluation of keystroke dynamics-based authentication algorithms The quality, size and nature (fixed or free-text) of the dataset is a crucial factor in evaluating the performance of these algorithms.
To perform evaluation, an algorithm is applied that measures and compares the difference in timing between key presses and releases in the dataset, using this information to make an authentication decision. This section details various keystroke datasets and their effectiveness in terms of authentication performance. Killourhy and Maxion [ 66 ] collected fixed text (password) keystroke data and evaluated 14 algorithms with that dataset. 51 subjects were included in data collection. The fixed password was “ .tie5Roanl ”. Each subject typed this password 400 times during 8 sessions with 50 attempts in each session. There was at least one day gap between two sessions to reflect the temporal variation of typing of the subjects. A Microsoft Windows application was used for the data collection. For more accurate timestamps, an external reference clock was utilized. Killourhy and Maxion evaluated different algorithms with this dataset and achieved EER between 9.6% and 10.2%.
Giot, El-Abed, and Rosenberger [ 45 ] proposed a benchmark database and software for measuring the performance of authentication systems leveraging keystroke dynamics for user access control. Their focus was on static-keystroke authentication (such as passwords or pass phrases). GREYC-Keystroke was the proposed software. They developed a standard keystroke dynamics database using the GREYC-Keystroke software. The data consisted of 133 participants including researchers, students, and employees. Each participant typed the password between 5 and 107 times. The authors collected the data of 7555 attempts. Most of the participants attended minimum 5 sessions. On average there were 51 attempts per participant. In [ 46 ] , they used the GREYC keystroke dataset to evaluate their proposed technique based on SVM learning. The enrollment step was limited to 5 captures. The administrator set a passphrase that the users had to type. A two-class SVM was utilized for the enrollment. This SVM-based machine learning approach only needed five captured samples to develop the model. They used four types of algorithms for their experiment - 1) Statistical algorithm, 2) Distance-based algorithm, 3) Rhythm-based algorithm, 4) Machine learning based algorithm. They also investigated the variations in the authentication method due to different keyboards. The authors also considered the consequences of some other factors like differing amounts of samples needed to develop the model, individual or global threshold, the database size etc. The EER was calculated by using ten vectors from the head of the dataset for enrollment and the remaining samples used for the verification. In terms of EER, their proposed method performed better than all other algorithms.
Giot, El-Abed, and Rosenberger [ 47 ] created a new dataset for keystroke based biometric systems. To develop the dataset, two types of logins and passwords were used- chosen and imposed. Leveraging a web environment, the data was collected without any restriction. They performed statistical analysis of some key factors including the effect of password size on performance, significance of fusion techniques etc. The data collection process consisted of three steps. 1) Ten attempts using a prior researcher chosen login and password, 2) Ten attempts for the user chosen login and password, 3) Ten imposter samples from two other participants. 83 individuals participated in the data collection. They collected 5185 genuine samples, 5439 imposed samples and 5754 imposter samples. For each participant, 20 samples were used for training and the remaining samples were used for testing (with a minimum of 20). The conclusions of their experiment were - 1) Using an individual threshold was better than using a global threshold for computing the EER, as an individual threshold is a value specific to a user that determines the origin of the sample - legitimate user or an imposter, 2) Using logins provided better results than using passwords, 3) The performance improved by doing the fusion of all features (monographs and digraphs), 4) The performance was dependent on the password size and entropy.
Bakelman et al. [ 18 ] collected fixed-text numeric keypad data for keystroke authentication of 30 subjects over for four days. On each day a maximum of 60 samples were collected for each subject. There were 11 keystrokes per sample from numeric sequence, and the Enter key. The data was collected by a third party keylogger. The subjects had to type the samples with only right hand in order to simulate typing a phone number or ATM pin. There were 20 samples per subject. For this dataset, they got the EER 10.5% and 6.1%.
Vural et al. [ 122 ] developed a new dataset containing short pass-phrases, long text transcription(fixed-text) and free text. They also recorded videos showing subjects during data collection in order to capture the facial expressions and hand movements of the subjects. Vural et al. started the data collection at Clarkson University in 2011. The dataset includes 2 kinds of fixed text (password and transcriptions) and free text from 39 participants incliding university employess and students. For each participant, the data was collected in two one-hour sessions each occuring on a different day. The first task was typing 3 different passwords. The subjects typed each password 20 times. The passwords were: yesnomaybe , bahaNe312! , ballzonecart . For the second task, the subjects had to answer 9 survey questions in free text with a minimum of 500 characters to answer each survey question. The last task was copying the commencemen speech of Steve Jobs at Stanford University. A browser-based keylogger was used for the data collection. The data was collected for a period of 11 months between August 2011 and June 2012 in a lab at Clarkson University. On average each subject provided 11066 keystrokes in session 1 and 10467 keystrokes in session 2. Every dession recording was analyzed to determine digraphs and trigraphs.
N-graphs greater than 500 milliseconds or shorter than 30 milliseconds in length were discarded. In session 1, on average there were 8406 digraphs and 389 unique digraphs per subject, 7561 trigraphs and 1603 unique trigraphs per subject. In session 2, on average there were 8261 digraphs and 388 unique digraphs per subject, 7520 trigraphs and 1620 unique trigraphs per subject. To evaluate this dataset, two algorithms were used: Leggett et al. [ 72 ] and Gunetti & Picardi [ 52 ] .
Using the algorithm of Leggett et al. [ 72 ] , an FAR of 0.25% and FRR of 17.65% were obtained for a threshold of 0.9; an FAR of 3.45% and FRR of 8.82% were obtained for a threshold of 0.85. Ceker and Upandhyaya [ 24 ] utilized this dataset to examine the accuracy of a single-class support vector machine (SVM) on longer text data, as opposed to shorter password text. They found that using the four ranking digraphs by comonality ( ‘he’, ‘re’, ‘th’ and ‘an’ ) resulted in a 2.94% EER, while using the most common 12 or more digraphs led to an almost 0% EER.
Monaco et al. [ 82 ] described the results of the One-handed Keystroke Biometric Identification Competition (OhKBIC). In the dataset, Monaco et al. included the data of normal typing and handicapped typing (typing with one hand). Data was collected from three online exams of undergraduate students. There were 64 subjects. In each exam, there were five essay questions. The subjects typed normally in the first exam. The subjects were directed to type with their left hand only for the second exam and with their right hand only for the third exam. Each subject typed a minimum 500 keystrokes on each exam. The data was collected by a JavaScript based keylogger and transferred to a server. Each used different keyboard make and models throughout the three exams which was a drawback of this dataset. A portion of the data collected from the first exam of normal both-hands typing was used as labeled training data. The unlabeled data included all three types of data (both-hand) typing, left-hand typing and right-hand typing data. The top team used two regression models (Artificial Neural Network and Counter-Propagation Artificial Neural Network) and one prediction model (Support Vector Machine) for pairwise coupling [ 54 ] . The best recognition rate ranged from 55.7% to 82.8% for both-hand section, 19.9% to 30.5% for left-hand section and 24.8% to 34.3% for right-hand section.
Sun, Ceker, and Upadhyaya [ 114 ] proposed a shared dataset containing keystrokes collected from 157 participants. The data was both fixed and free-text. The data collection process continued for 4 months between September and December 2015. For each subject, the data was colled in 3 sessions. The tasks included fixed-text transcription and answering quesions in free text. On average there was a 28 days gap between 2 sessions to consider the temporal variations. There are 2 sections in the dataset- in one section the subjects used same keyboard across sessions. In the other section, the subjects used different keyboards across sessions. The first task was copying the 2005 commencement speech of Steve Jobs at Stanford University. The speech was divided into 3 parts with each part of equal length, the subjects had to type one part in each session. The second task consisted of multiple subtasks including answering survey questions and describing a picture, sending an email with attachment and free internet browsing. Each session lasted for about 50 minutes with 30 minutes for the first task and 20 minutes for the second task. A system logger was adopted for the data collection on the windows platform [ 41 ] [ 115 ] . Among the 157 subjects, the data of 148 subjects was included in the dataset. The data of the remaining users was discarded due to mistakes. On average each subject typed around 5700 keystrokes in each session, around 17000 keystrokes in 3 sessions. There was a 3 to 5 week time gap between 2 sessions to reflet the temporal effect. Gaussian mixture model, a probabilistic model for classifying data into different categories based on the probability distribution, was utilized to evaluate this dataset. The EER was 0.01% and 0.39% for Gaussian mixture model with one and two components, respectively.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Keystroke%20logging • https://en.wikipedia.org/wiki/Keystroke%20dynamics • https://en.wikipedia.org/wiki/Authentication • https://arxiv.org/html/2303.04605v2
Extracted Research Figures & Simulation Topologies
Total 1 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Keystroke Dynamics Based Continuous Authentication System.
[*] Metasploit Scan Running on Target Subnet for Keystroke Dynamics Based Continuous Authentication System... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |