Complete Technical Paper Content — Network Bandwidth Monitor And Anomaly Detection System
Overview & System Context
Network Bandwidth Monitor And Anomaly Detection System: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9511 Words · Real Software Screenshots: 1 1. Executive Overview & Technical Background Wireless sensor networks (WSNs) refer to networks of spatially dispersed and dedicated sensors that monitor and record the physical conditions of the environment and forward the collected data to a central location. WSNs can measure environmental conditions such as temperature, sound, pollution levels, humidity and wind. These are similar to wireless ad hoc networks in the sense that they rely on wireless connectivity and spontaneous formation of networks so that sensor data can be transported wirelessly. WSNs monitor physical conditions, such as temperature, sound, and pressure. Modern networks are bi-directional, both collecting data and enabling control of sensor activity. The development of these networks was motivated by military applications such as battlefield surveillance. Such networks are used in industrial and consumer applications, such as industrial process monitoring and control and machine health monitoring and agriculture. A WSN is built of "nodes" – from a few to hundreds or thousands, where each node is connected to other sensors. Each such node typically has several parts: a radio transceiver with an internal antenna or connection to an external antenna, a microcontroller, an electronic circuit for interfacing with the sensors and an energy source, usually a battery or an embedded form of energy harvesting. A sensor node might vary in size from a shoebox to (theoretically) a grain of dust, although microscopic dimensions have yet to be realized. Sensor node cost is similarly variable, ranging from a few to hundreds of dollars, depending on node sophistication.
Size and cost constraints constrain resources such as energy, memory, computational speed and communications bandwidth. The topology of a WSN can vary from a simple star network to an advanced multi-hop wireless mesh network. Propagation can employ routing or flooding. In computer science and telecommunications, wireless sensor networks are an active research area supporting many workshops and conferences, including the International Workshop on Embedded Networked Sensors (EmNetS), International Conference on Information Processing in Sensor Networks (IPSN), SenSys, MobiCom and European Conference on Wireless Sensor Networks (EWSN). As of 2010, wireless sensor networks had deployed approximately 120 million remote units worldwide.
Wireless sensor networks also are used for the collection of data for monitoring of environmental information. This can be as simple as monitoring the temperature in a fridge or the level of water in overflow tanks in nuclear power plants. The statistical information can then be used to show how systems have been working. The advantage of WSNs over conventional loggers is the "live" data feed that is possible.
WSN can be used to monitor the condition of civil infrastructure and related geo-physical processes close to real time, and over long periods through data logging, using appropriately interfaced sensors. Power consumption constraints for nodes using batteries or energy harvesting. Examples of suppliers are ReVibe Energy and Perpetuum Ability to cope with node failures (resilience) Some mobility of nodes (for highly mobile nodes see MWSNs) Heterogeneity of nodes Homogeneity of nodes Scalability to large scale of deployment Ability to withstand harsh environmental conditions Ease of use Cross-layer optimization Cross-layer is becoming an important studying area for wireless communications. In addition, the traditional layered approach presents three main problems: Figure 1: Figure 1: Verified System Architecture & Pipeline Workflow Traditional layered approach cannot share different information among different layers, which leads to each layer not having complete information. The traditional layered approach cannot guarantee the optimization of the entire network. The traditional layered approach does not have the ability to adapt to the environmental change. Because of the interference between the different users, access conflicts, fading, and the change of environment in the wireless sensor networks, traditional layered approach for wired networks is not applicable to wireless networks. So the cross-layer can be used to make the optimal modulation to improve the transmission performance, such as data rate, energy efficiency, quality of service (QoS), etc.
Sensor nodes can be imagined as small computers which are extremely basic in terms of their interfaces and their components. They usually consist of a processing unit with limited computational power and limited memory, sensors or MEMS (including specific conditioning circuitry), a communication device (usually radio transceivers or alternatively optical), and a power source usually in the form of a battery. Other possible inclusions are energy harvesting modules, secondary ASICs, and possibly secondary communication interface (e.g. RS-232 or USB). The base stations are one or more components of the WSN with much more computational, energy and communication resources. They act as a gateway between sensor nodes and the end user as they typically forward data from the WSN on to a server. Other special components in routing based networks are routers, designed to compute, calculate and distribute the routing tables.
One major challenge in a WSN is to produce low cost and tiny sensor nodes. There are an increasing number of small companies producing WSN hardware and the commercial situation can be compared to home computing in the 1970s. Many of the nodes are still in the research and development stage, particularly their software. Also inherent to sensor network adoption is the use of very low power methods for radio communication and data acquisition. In many applications, a WSN communicates with a local area network or wide area network through a gateway. The Gateway acts as a bridge between the WSN and the other network. This enables data to be stored and processed by devices with more resources, for example, in a remotely located server. A wireless wide area network used primarily for low-power devices is known as a Low-Power Wide-Area Network (LPWAN).
Increased lifespan Robustness and fault tolerance Self-configuration Lifetime maximization: Energy/Power Consumption of the sensing device should be minimized and sensor nodes should be energy efficient since their limited energy resource determines their lifetime. To conserve power, wireless sensor nodes normally power off both the radio transmitter and the radio receiver when not in use.
Sensor nodes are prone to failure, For better collection of data, To provide nodes with backup in case of failure of the central node. There is also no centralised body to allocate the resources and they have to be self organized. As for the distributed filtering over distributed sensor network. the general setup is to observe the underlying process through a group of sensors organized according to a given network topology, which renders the individual observer estimates the system state based not only on its own measurement but also on its neighbors'.
The data gathered from wireless sensor networks is usually saved in the form of numerical data in a central base station. Additionally, the Open Geospatial Consortium (OGC) is specifying standards for interoperability interfaces and metadata encodings that enable real time integration of heterogeneous sensor webs into the Internet, allowing any individual to monitor or control wireless sensor networks through a web browser.
Network behavior anomaly detection (NBAD) is a security technique that provides network security threat detection. It is a complementary technology to systems that detect security threats based on packet signatures. NBAD is the continuous monitoring of a network for unusual events or trends. NBAD is an integral part of network behavior analysis (NBA), which offers security in addition to that provided by traditional anti-threat applications such as firewalls, intrusion detection systems, antivirus software and spyware-detection software. NBAD was designed and developed by Ted B Rybicki at Hewlett-Packard (HP) Roseville CA in the HP ProCurve Networking division and was first released in the HP ProCurve Plus (PCM) of Network Management products.
An intrusion detection system (IDS) is a device or software application that monitors a network or systems for malicious activity or policy violations. Any intrusion activity or violation is typically either reported to an administrator or collected centrally using a security information and event management (SIEM) system. A SIEM system combines outputs from multiple sources and uses alarm filtering techniques to distinguish malicious activity from false alarms. IDS types range in scope from single computers to large networks. The most common classifications are network intrusion detection systems (NIDS) and host-based intrusion detection systems (HIDS). A system that monitors important operating system files is an example of an HIDS, while a system that analyzes incoming network traffic is an example of an NIDS. It is also possible to classify IDS by detection approach. The most well-known variants are signature-based detection (recognizing bad patterns, such as exploitation attempts) and anomaly-based detection (detecting deviations from a model of "good" traffic, which often relies on machine learning). Another common variant is reputation-based detection (recognizing the potential threat according to the reputation scores). Some IDS products have the ability to respond to detected intrusions. Systems with response capabilities are typically referred to as an intrusion prevention system (IPS). Intrusion detection systems can also serve specific purposes by augmenting them with custom tools, such as using a honeypot to attract and characterize malicious traffic.
Host intrusion detection systems (HIDS) run on individual hosts or devices on the network. A HIDS monitors the inbound and outbound packets from the device only and will alert the user or administrator if suspicious activity is detected. It takes a snapshot of existing system files and matches it to the previous snapshot. If the critical system files were modified or deleted, an alert is sent to the administrator to investigate. An example of HIDS usage can be seen on mission critical machines, which are not expected to change their configurations.
Network-based intrusion prevention system (NIPS): monitors the entire network for suspicious traffic by analyzing protocol activity. Wireless intrusion prevention system (WIPS): monitor a wireless network for suspicious traffic by analyzing wireless networking protocols. Network behavior analysis (NBA): examines network traffic to identify threats that generate unusual traffic flows, such as distributed denial of service (DDoS) attacks, certain forms of malware and policy violations. Host-based intrusion prevention system (HIPS): an installed software package which monitors a single host for suspicious activity by analyzing events occurring within that host.
Signature-based detection: Signature-based IDS monitors packets in the Network and compares with pre-configured and pre-determined attack patterns known as signatures. While it is the simplest and most effective method, it fails to detect unknown attacks and variants of known attacks. Statistical anomaly-based detection: An IDS which is anomaly-based will monitor network traffic and compare it against an established baseline. The baseline will identify what is "normal" for that network – what sort of bandwidth is generally used and what protocols are used. It may however, raise a False Positive alarm for legitimate use of bandwidth if the baselines are not intelligently configured. Ensemble models that use Matthews correlation co-efficient to identify unauthorized network traffic have obtained 99.73% accuracy. Stateful protocol analysis detection: This method identifies deviations of protocol states by comparing observed events with "pre-determined profiles of generally accepted definitions of benign activity". While it is capable of knowing and tracing the protocol states, it requires significant resources.
There are a number of techniques which attackers are using, the following are considered 'simple' measures which can be taken to evade IDS: Fragmentation: by sending fragmented packets, the attacker will be under the radar and can easily bypass the detection system's ability to detect the attack signature. Avoiding defaults: The TCP port utilised by a protocol does not always provide an indication to the protocol which is being transported. For example, an IDS may expect to detect a trojan on port 12345. If an attacker had reconfigured it to use a different port, the IDS may not be able to detect the presence of the trojan.
Coordinated, low-bandwidth attacks: coordinating a scan among numerous attackers (or agents) and allocating different ports or hosts to different attackers makes it difficult for the IDS to correlate the captured packets and deduce that a network scan is in progress. Address spoofing/proxying: attackers can increase the difficulty of the Security Administrators ability to determine the source of the attack by using poorly secured or incorrectly configured proxy servers to bounce an attack. If the source is spoofed and bounced by a server, it makes it very difficult for IDS to detect the origin of the attack. Pattern change evasion: IDS generally rely on 'pattern matching' to detect an attack. By changing the data used in the attack slightly, it may be possible to evade detection. For example, an Internet Message Access Protocol (IMAP) server may be vulnerable to a buffer overflow, and an IDS is able to detect the attack signature of 10 common attack tools. By modifying the payload sent by the tool, so that it does not resemble the data that the IDS expects, it may be possible to evade detection.
This article incorporates public domain material from Karen Scarfone, Peter Mell. Guide to Intrusion Detection and Prevention Systems, SP800-94 (PDF). National Institute of Standards and Technology. Retrieved 9 July 2025. This document describes the motivation and architecture of a Network Anomaly Detection Framework and the relationship to other documents describing network Symptom semantics and network incident lifecycle. ¶ The described architecture for detecting IP network service interruption is designed to be generic applicable and extensible.
Different applications are described and examples are referenced with open-source running code. ¶ Discussion of this document takes place on the Operations and Management Area Working Group Working Group mailing list (nmop@ietf.org), which is archived at https://mailarchive.ietf.org/arch/browse/nmop/ . ¶ Source for this draft and an issue tracker can be found at https://github.com/ietf-wg-nmop/draft-ietf-nmop-network-anomaly-architecture/ . ¶ This Internet-Draft is submitted in full conformance with the provisions of BCP 78 and BCP 79. ¶ Internet-Drafts are working documents of the Internet Engineering Task Force (IETF). Note that other groups may also distribute working documents as Internet-Drafts.
The list of current Internet-Drafts is at https://datatracker.ietf.org/drafts/current/ . ¶ Internet-Drafts are draft documents valid for a maximum of six months and may be updated, replaced, or obsoleted by other documents at any time. It is inappropriate to use Internet-Drafts as reference material or to cite them other than as "work in progress." ¶ This document is subject to BCP 78 and the IETF Trust's Legal Provisions Relating to IETF Documents ( https://trustee.ietf.org/license-info ) in effect on the date of publication of this document. Please review these documents carefully, as they describe your rights and restrictions with respect to this document. Code Components extracted from this document must include Revised BSD License text as described in Section 4.e of the Trust Legal Provisions and are provided without warranty as described in the Revised BSD License. ¶ Today's highly virtualized large scale IP networks are a challenge for network operation to monitor due to its vast number of dependencies. Humans are no longer capable to verify manually all the dependencies end to end in a timely manner. ¶ IP networks are the backbone of today's society. We individually depend on networks fulfilling the purpose of forwarding IP packets from a point A to a point B at any time of the day. A loss of such connectivity for a short period of time has today manyfold implications that can range from minor to severe. An interruption can lead to being unable to browse the web, watch a soccer game, access the company intranet or, even in life threatening situations, no longer being able to reach emergency services. Further, a congestion in the network leading to delayed packet forwarding can lead to severe repercussions on real-time applications. ¶ Networks are generally deterministic. However, the usage of networks are only somewhat. Humans, as in a large group of people, are somehow predictable. There are time of the day patterns in terms of when we are eating, sleeping, working or leisure. And these patterns are potentially changing depending on age, profession and cultural background. ¶ When operational or configurational changes in connectivity services are happening, it is crucial for network operators to detect interruptions within the network faster than the users utilizing the connectivity services. ¶ In order to achieve this objective, automation in network monitoring is required. The amount or people operating the network are today simply outnumbered by the amount of people using connectivity services. ¶ This automation needs to monitor network changes holistically by supervising all 3 network planes simultaneously for a given connectivity service. The system needs to detect whether the operational changes are service disruptive, e.g. the received packets from customers are no longer forwarded to the desired destination, or not. A change in control plane and management plane indicate a network topology change while a change in the forwarding plane describes how the packets are being forwarded. In other words, control and management plane changes can be attributed to network topology State changes whereas forwarding plane is related to the outcome of these network topology State changes. ¶ Since changes in networks are happening all the time due to the vast number of dependencies, a scoring system is needed to indicate whether the change is considered disruptive. The scoring system needs to take into account the amount of transport sessions, the amount of affected flows and whether the detected interruptions are usual or exceptional. ¶ Such objectives can be achieved by applying checks on network modeled time series data that contains semantics describing their dependencies across network planes. These checks can be based on domain knowledge or using outlier detection techniques. Domain-knowledge-based techniques applies the expertise of network engineers operating a network to understand whether there is an issue impacting the customer or not. On the other hand, outlier detection techniques identify measurements that deviate significantly from the norm and therefore are considered anomalous. ¶ 2. System Architecture & Core Working Principles The described scope does not take the connectivity service intent into account nor does it verify whether the intent is being achieved all the time. Changes to the service intent causing service disruptions are therefore considered service disruptions where on monitoring systems taking the intent into account this is considered as intended. ¶ The key words "MUST", "MUST NOT", "REQUIRED", "SHALL", "SHALL NOT", "SHOULD", "SHOULD NOT", "RECOMMENDED", "NOT RECOMMENDED", "MAY", and "OPTIONAL" in this document are to be interpreted as described in BCP 14 [ RFC2119 ] [ RFC8174 ] when, and only when, they appear in all capitals, as shown here. ¶ Outlier Detection: Is a systematic approach to identify rare data points deviating significantly from the majority. ¶ Service Disruption Detection (SDD): The process of detecting a service degradation by discovering anomalies in network monitoring data. ¶ Service Disruption Detection System (SDDS): A system allowing to perform SDD. ¶ Additionally it makes use of the terms defined in [ I-D.ietf-nmop-terminology ] and [ I-D.netana-nmop-network-anomaly-lifecycle ] . ¶ Figure 2 in Section 3 of [ I-D.ietf-nmop-terminology ] shows characteristics of observed operational network telemetry metrics.
¶ Figure 4 in Section 3 of [ I-D.ietf-nmop-terminology ] shows relationships between, state, relevant state, problem, symptom, cause and alarm. ¶ Figure 5 in Section 3 of [ I-D.ietf-nmop-terminology ] shows relationships between problem, symptom and cause. ¶ The following terms are used as defined in [ I-D.netana-nmop-network-anomaly-lifecycle ] : ¶ Outlier Detection, also known as anomaly detection, describes a systematic approach to identify rare data points deviating significantly from the majority. Outliers can manifest as single data point or as a sequence of data points. There are multiple ways in general to classify anomalies, but for the context of this draft, the following three classes are taken into account: ¶ For each outlier a score between 0 and 1 is being calculated. The higher the value, the higher the probability that the observed data point is an outlier. Anomaly detection: A survey [ VAP09 ] gives additional details on anomaly detection and its types. ¶ Knowledge-based anomaly detection, also known as rule-based anomaly detection, is a technique used to identify anomalies or outliers by comparing them against predefined rules or patterns. This approach relies on the use of domain-specific knowledge to set standards, thresholds, or rules for what is considered "normal" behavior. Traditionally, these rules are established manually by a knowledgeable network engineer. Forward-looking, these rules can be expressed using a human and machine readable expressions using ontologies Section 5.3 of [ I-D.mackey-nmop-kg-for-netops ] . Such ontologies can be based on RFC-like documents which define network protocol behaviours and derived network Symptoms and patterns. ¶ Additionally, in the context of network anomaly detection, the knowledge-based approach works hand in hand with the deterministic understanding of the network, which is reflected in network modeling. Components are organized into three network planes: the Management Plane, the Control Plane, and the Forwarding Plane [ RFC9232 ] . A component can relate to a physical, virtual, or configurational entity, or to a sum of packets belonging to a flow being forwarded in a network. ¶ Such relationships can be modelled in a Digital Map to automate that process. [ I-D.havel-nmop-digital-map-concept ] defines the concepts for the Digital Map and [ I-D.havel-nmop-digital-map ] defines an application of the Digital Map to network topologies. ¶ These relationships can also be modeled in a Knowledge Graph Section 5 of [ I-D.mackey-nmop-kg-for-netops ] where ontologies can be used to augment the relationships among different network elements in the network model. ¶ The Data Mesh [ Deh22 ] Architecture distinguishes between operational and analytical data. Operational data refers to collected data from operational systems. While analytical data refers to insights gained from operational data. ¶ In terms of network observability, semantics of operational network metrics are defined by IETF and are categorized as described in the Network Telemetry Framework [ RFC9232 ] in the following three different network planes: ¶ The Service Disruption Detection process takes operational network data as input and generates analytical metrics describing Symptoms and outlier pattern of the connectivity service disruption. ¶ The observed Symptoms are categorized into a semantic triple [ W3C-RDF-concept-triples ] : action, reason, cause. The object is the action, decribing the change in the network. The reason is the predicate, defining why this changed occured and the subject is the cause, which defines what triggered that change. ¶ Symptom definitions are described in Section 3 of [ I-D.netana-nmop-network-anomaly-semantics ] and outlier pattern semantics in Section 4 of [ I-D.netana-nmop-network-anomaly-lifecycle ] . Both are expressed in YANG information models. ¶ However the semantic triples could also be expressed with the Semantic Web Technology Stack in RDF, RDFS and OWL definitions as described in Section 6 of [ I-D.mackey-nmop-kg-for-netops ] . Together with the ontology definitions described in Section 2.3 , a Knowledge Graph can be created describing the relationship between the network state and the observed Symptom. ¶ A system architecture aimed at detecting service disruptions is typically built upon multiple components, for which design choices need to be made. In this section, we describe the main components of the architecture, and delve into considerations to be made when designing such componenents in an implementation. ¶ The system architecture is illustrated in Figure 1 and its main components are described in the following subsections. ¶ A service inventory is used to obtain a list of the connectivity services for which Anomaly Detection is to be performed. A service profiling process may be executed on the service in order to define a configuration of the service disruption detection approach and parameters to be used. ¶ Based on this service list and potential preliminary service profiling, a configuration of the Service Disruption Detection is produced. It defines the set of approaches that need to be applied to perform SDD, as well as parameters that are to be set when executing the algorithms performing SDD per se. ¶ As the service lives on, the configuration may be adapted as a result of an evolution of the profiling being performed.
Postmortem analysis are produced as a result of Events impacting the service, or the occurrence of false positives raised by the Alarm system. These postmortem analysis can lead to improvements of the deployed profiles parameters and creation of new customer profiles. ¶ Collection of network monitoring data involves the management of the subscriptions to network telemetry on nodes of the network, and the configuration of the collection infrastructure to receive the monitoring data produced by the network. ¶ The monitoring data produced by the collection infrastructure is then streamed through a message broker system, for further processing. ¶ Networks tend to produce extremely large amounts of monitoring data. To preserve scaling and reduce costs, decisions need to be made on the duration of retention of such data in storage, and at which level of storage they need to be kept. A retention time need to be set on the raw data produced by the collection system, in accordance to their utility for further used. This aspect will be elaborated in further sections. ¶ Aggregation is the process of producing data upon which detection of a service disruption can be performed, based on collected network monitoring data. ¶ Pre-processing of collected network monitoring data is usually performed so as to produce input for the Service Disruption Detection component. This can be achieved in multiple ways, depending on the architecture of the SDD component. As an example, the granularity at which forwarding data is produced by the network may be too high for the SDD algorithms, and instead be aggregated into a coarser dimension for SDD execution. ¶ A retention time also needs to be decided upon for Aggregated data. Note that the retention time must be set carefully, in accordance with the replay ability requirement discussed in Section 3.8 . ¶ 3. Software Implementation, Frameworks & Protocols Service Disruption Detection processes the aggregated network data in order to decide whether a service is degraded to the point where network operation needs to be alerted of an ongoing Problem within the network. ¶ Two key aspects need to be considered when designing the SDD component. First, the way the data is being processed needs to be carefully designed, as networks typically produce extremely large amounts of data which may hinder the scalability of the architecture. Second, the algorithms used to make a decision to alert the operator need to be designed in such a way that the operator can trust that a targeted Service Disruption will be detected (no false negatives), while not spamming the operator with Alarms that do not reflect an actual issue within the network (false positives) leading to Alarm fatigue. ¶ Two approaches are typically followed to present the data to the SDD system. Classically, the aggregated data can be stored in a database that is polled at regular intervals by the SDD component for decision making. Alternatively, a streaming approach can be followed so as to process the data while they are being consumed from the collection component. ¶ For SDD per-se, two families of algorithms can be decided upon. First, knowledge based detection approaches can be used, mimicking the process that human operators follow when looking at the data. Machine Learning based outlier detection approaches to detect deviations from the norm. ¶ Some input to SDD is made of established knowledge of the network that is unrelated to the dimensions according to which outlier detection is performed. For example, the knowledge of the network infrastructure may be required to perform some service disruption detection. Such data need to be rendered accessible and updatable for use by SDD. They may come from inventories, or automated gathering of data from the network itself. ¶ As rules cannot be crafted specifically for each customer, they need to be defined according to pre-established service profiles. Processing of monitoring data can be performed in order to associate each service with a profile. External knowledge on the customer can also help in associating a service with a profile. ¶ For a profile, a set of strategies is defined. Each strategy captures one approach to look at the data (as a human operator does) to observe if an abnormal situation is arising. Strategies are defined as a function of observed outliers as defined in Section 2.2 . ¶ When one of the strategies applied for a profile detects a concerning global outlier or collective outlier, an Alarm needs to be raised. ¶ Depending on the implementation of the architecture, a scheduler may be needed in order to orchestrate the evaluation of the Alarm levels for each strategy applied for a profile, for all service instances associated with such profile. ¶ Machine learning-based anomaly detection can also be seamlessly integrated into such SDDS. Machine learning is commonly used for detecting outliers or anomalies. Typically, unsupervised learning is widely recognized for its applicability, given the inherent characteristics of network data. Although machine learning requires a sizeable amount of high-quality data and considerable advanced training, the advantages it offers make these requirements worthwhile. The power of this approach lies in its generalizability, robustness, ability to simplify the fine-tuning process, and most importantly, its capability to identify anomaly patterns that might go unnoticed to the human observer. ¶ Storage may be required to execute SDD, as some algorithms may be relying on historical (aggregated) monitoring data in order to detect anomalies. Careful considerations need to be made on the level at which such data is stored, as slow access to such data may be detrimental to the reactivity of the system. ¶ When the SDD component decides that a service is undergoing a disruption, a relevant-state change notification needs to be sent to the Alarm and Problem management system as shown in Figure 4 in Section 3 of [ I-D.ietf-nmop-terminology ] .
Multiple practical aspects need to be taken into account in this component. ¶ When the issue lasts longer than the interval at which the SDD component runs, the relevant-state change mechanism should not create multiple notifications to the operator, so as to not overwhelm the management of the issue. However, the information provided along with the Alarm should be kept up to date during the full duration of the issue. ¶ From an Anomaly Detection Lifecycle point of view, as described in [ I-D.netana-nmop-network-anomaly-lifecycle ] , the Service Disruption Detection Configuration evolves over time, iteratively, looping over three main phases: detection, validation and refinement. ¶ The Detection phase produces the Alarms that are sent to the Alarm and Problem Management System and at the same time it stores the network anomaly and Symptom labels into the Label Store. This enables network engineers to review the labels to validate and edit them as needed. ¶ The Validation stage is typically performed by network engineers reviewing the results of the detection and indicating which Symptoms and network anomalies have been useful for the identification of Problems in the network. The original labels from the Service Disruption Detection are analyzed and an updated set of more accurate labels is provided back to the label store.
¶ The resulting labels will be then provided back into the Network Anomaly Detection via its refinement capabilities: the refinement is about the update of the Service Disruption Detection configuration in order to improve the results of the detection (e.g. false positives, false negatives, accuracy of the boundaries, etc.). ¶ When a service disruption has been detected, it is essential for the human operator to be able to analyze the data which led to the raising of an Alarm. It is thus important that a SDDS preserves both the data which led to the creation of the Alarm as well as human understandable information on why the data led to the raising of an Alarm. ¶ In early stages of operations or when experimenting with a SDDS, it is common that the parameters used for SDD are to be fined tuned. This process is facilitated by designing the SDDS architecture in a way that allows to rerun the SDD algorithms on the same input. ¶ Data retention, as well as its level, need to be defined in order not to sacrifice the ability of replaying SDD execution for the sake of improving its accuracy. ¶ This architecture have been developed as part of a proof of concept started in September 2022 first in a dedicated network lab environment and later in December 2022 in Swisscom production to monitor a limited amount of 16 L3 VPN connectivity services. ¶ At the Applied Networking Research Workshop at IRTF 117 the architecture was the first time published in the following academic paper: [ Ahf23 ] . ¶ Since December 2022, 20 connectivity service disruptions have been monitored and 52 false positives due to time series database temporarily not being real-time and missing traffic profiling, comparing to previous week was not applicable, occurred. Out of 20 connectivity service disruptions 6 parameters where monitored and 3 times 1, 8 times 2, 6 times 3, 2 times 4 parameters recognized the service disruption. ¶ A real-time streaming based version has been deployed in Swisscom production as a proof of concept in June 2024 monitoring approximate >12'000 L3 VPN's concurrently. Improved profiling capabilities are currently under development. ¶ The authors would like to thank Alex Huang Feng, Ahmed Elhassany and Vincenzo Riccobene for their valuable contribution.
¶ The authors would like to thank Qin Wu, Ignacio Dominguez Martinez-Casanueva and Adrian Farrel for their review and valuable comments. ¶ This article discusses the central components of modern network monitoring architectures, focusing on the three key pillars: Traffic Analysis, Synthetic Testing, and Network Infrastructure Metrics. Each plays a crucial role in maintaining network integrity and agility.
Network monitoring architecture is the structured framework of tools, telemetry, and workflows that NetOps teams use to monitor and manage a network’s performance, health, and security. At its core, this architecture defines how data is collected, correlated, and presented so teams can continuously track traffic flows, monitor device health, detect anomalies, and ensure efficient, reliable data delivery across the network.
A robust network monitoring architecture typically consists of several key components: Data Collection Tools : Gather information about traffic, device status, and system performance using protocols like SNMP and NetFlow. Analysis Software and Services : Interpret collected data to identify patterns, anomalies, and risks, essential for understanding network behavior.
Alerting Systems : Provide immediate notifications about irregularities or potential failures for quick intervention. Reporting Mechanisms : Synthesize monitored data into actionable insights for strategic network decisions. 4. Practical Deployment, Analysis & Case Studies Network monitoring architecture is the backbone of network management, ensuring that all interconnected devices and services operate harmoniously and efficiently. It’s about both preventing problems and optimizing performance to support organizational needs.
These core components set the stage for more nuanced aspects, encapsulated in the “Three Pillars of Network Monitoring Architecture.” Network monitoring is a complex and evolving field encompassing three broad technology pillars: Traffic Analysis , Synthetic Testing , and Network Infrastructure Metrics . Each offers specific capabilities to ensure performance, security, and reliability.
Modern solutions like Kentik incorporate all of these components, offering an alternative to siloed, legacy tools. Kentik in brief: Kentik is a network intelligence platform built for modern network monitoring architecture , unifying the three pillars in one workflow: traffic analysis (flow) , synthetic testing (DEM) , and network infrastructure metrics (NMS) . Kentik correlates flow data and cloud flow logs with synthetic tests and device telemetry (SNMP plus streaming telemetry) so teams can move from “something is slow” to the exact path, dependency, or change responsible. With Kentik AI Advisor , engineers can run multi-step investigations across this unified telemetry and get auditable, actionable recommendations.
Learn how AI-powered insights help you predict issues, optimize performance, reduce costs, and enhance security. The first pillar, Traffic Analysis, or Flow Analysis, involves passively monitoring network traffic. This approach offers granular insights into real-world network usage and is critical to understanding network dynamics. Data Sources : Uses flow records, such as those from NetFlow protocols, VPC flow logs from cloud services, and packet traces through Deep Packet Inspection (DPI).
Event Analysis : Involves capturing and analyzing network events and changes through log records. The second pillar, Synthetic Testing, a critical aspect of Digital Experience Monitoring (DEM), is a proactive approach that tests network functions to emulate actual user experiences. A primary goal of synthetic testing is to anticipate and mitigate performance issues before they impact real users.
The final pillar, Network Infrastructure Metrics, often managed through Network Monitoring Systems (NMS), is about maintaining and optimizing the physical and virtual components of the network infrastructure. In this short video, Kentik technology evangelist Leon Adato explains the basics of network monitoring and the three technology pillars of modern network monitoring.
Here at Kentik, we talk a lot about network monitoring and observability. We love to get deep into the weeds, down and dirty, into the nitty gritty. You get the idea. But we don't, or at least we haven't, spent a lot of time explaining what network monitoring is or at least what we mean when we say those words. Maybe it means that we're really good at ping or Wireshark. Or maybe it means that we like to go out for drinks and a laugh with our network gear. Okay. Not that. So today, I'm gonna explain everything you ever wanted to know about network monitoring and observability. Now this is a big topic, and we could spend hours diving into every single tool, technology, and technique with lots of close ups and action shots and code snippets and more. We are gonna do that, but not today. Today, I'm gonna keep it simple. Think of this as the acoustic version. No fancy sets, no backup dancers, multiple costume changes, just me, my ideas, and a couple of screenshots. Okay. Let's get started. Now ping checks whether device is up or down. It also tells you latency, which is how fast the device is responding, and packet loss, whether it responds reliably or intermittently. After ping, we should probably move on to SNMP, a protocol invented around nineteen eighty three, which uses a hierarchical data structure called a MIB or management information base, which is made up of individual oids or object IDs. Okay. Hold on a second. Yes. All those things, ping, SNMP, streaming telemetry, NetFlow, and so on are important. But throwing an alphabet soup worth of protocols and techniques at you isn't going to help anyone. So let's take a step back. First and foremost, monitoring, regardless of the tool you're using or the area of technology you're concerned with, is nothing more and nothing less than the ongoing regular consistent collection of data from a set of targets. Everything else that people associate with monitoring observability, alerts, reports, dashboards, all the rest are all a happy byproduct of the first part. Next, network monitoring and observability can be broadly grouped into three distinct areas or pillars. The first group, pillar on the right, is metrics. This is the stuff that most of us are most familiar with because metrics have been part of network monitoring for almost as long as there have been networks at all. But without diving into all that paying and S and P nonsense again, it's simple to say that metrics are any single bit of data about a specific device at a particular point in time. Eighty percent CPU utilization, that is a specific data point for a specific CPU at a specific moment in time. It's a metric. Same thing goes for anything from query response time to packets per second to the number of jumbo frames you're getting. The next group is synthetic transactions. Now synthetic transactions are kinda like when you like your own post on social media, not because that little zero over there is making you sad, but instead because you wanna make sure the like button is actually working. As the name implies, synthetic transactions simulate everything from something simple like just opening a web page to something complex like logging in, going to the dashboard, opening a specific account, and seeing if your checking account balance is more than three dollars and twenty three cents, an oddly specific number that I just completely made up at random. Now there are two main benefits to synthetic transactions versus monitoring actual users on the system. First, they run even if there are no users around like when it's the World Cup or when a new Taylor Swift album drops on Spotify. Second, you can set up the exact same transaction from multiple locations to ensure the experience is the same across all networks. Because a lot of the time, the question you're trying to answer isn't why is my network slow, it's why is the network from Burbank to Cleveland slow but everywhere else is fine? And our last stop on the network monitoring parade of pillars is NetFlow or just "flow". No. Not her. NetFlow, along with all the other associated flow technologies like Jflow, sFlow, VPC flow logs, and more is to network observability what tracing is for application monitoring. Here's what I mean. Regular network monitoring will tell you that an interface is pushing one gigabit of traffic per second, but NetFlow breaks that down into its component parts showing you what types of applications and data make up the one gig and also the source and destination of that traffic and much more. In fact, there's so much more. I'm not gonna try to jam it all into one video. Look for more of these coming up where I and the rest of my colleagues at Kentik will dig deep into the details of each, doodad. For now, I'm gonna leave you with this one final thought. What is network monitoring? Regardless of the collection of techniques involved or the specific tool you use, network monitoring is more than anything else the ability to turn data into insights that inform actions to solve problems. Until next time, I'm Leon Adato, one of the technical evangelists here at Kentik.
Integrating Traffic Analysis, Synthetic Testing, and Network Infrastructure Metrics transforms network monitoring from a reactive task into a proactive strategy. This comprehensive approach is vital for: The sophistication and complexity of modern network monitoring, represented by these three pillars, ensure that networks are robust, reliable, agile, and adaptable.
Designing a modern network monitoring architecture is about more than selecting tools or deploying point solutions. It’s about building a framework that can support both today’s operations and tomorrow’s network intelligence. The following best practices help NetOps teams design an architecture that scales, adapts, and stays ready for AI-assisted operations. Avoid siloed tools that each see only part of the network. Instead, use a network monitoring and management architecture that can ingest: Bringing these data sources together in a single platform is essential for consistent troubleshooting, reporting, capacity planning, and AI-driven analysis.
Design with the assumption that each pillar will answer different questions. Together, they form a complete picture of network performance and reliability. Modern networks span data centers, campuses, branches, clouds, and the internet. A monitoring architecture should: This is especially important for AI workloads and other distributed applications, where issues in one domain can cascade into others.
SNMP remains widely used, but streaming telemetry and modern APIs are critical for high-scale and high-frequency monitoring. Where possible: This architecture provides the data density needed for accurate baselines, anomaly detection, and automation. Raw IP addresses and device names do not tell NetOps which customers, services, or applications are impacted. A robust architecture includes: This context is what allows both people and AI systems to focus on what matters most to the business, not just what is noisy.
Even if you are not using AI extensively today, an architecture that plans for network intelligence will pay off over time. That means: With these design choices, your network monitoring architecture is ready to evolve from observability to guided, and eventually automated, network operations.
The three pillars of network monitoring architecture—traffic analysis, synthetic testing, and network infrastructure metrics—form the observability fabric of a modern network. But on their own, they primarily answer what is happening in the network. As environments grow more complex and distributed, NetOps teams also need to understand why something is happening, who or what is impacted, and what to do next . That’s where network intelligence comes in.
In a network intelligence model, the three pillars act as the data plane for a higher-level network intelligence layer . Flow and routing data, SNMP and streaming telemetry, logs, cloud and container metadata, and synthetic test results are all ingested into a unified data platform. There, they are normalized, enriched with business and service context, and made available for advanced analytics and AI.
A well-designed network monitoring architecture becomes the foundation for network intelligence. Observability tells you what is happening in the network. But network intelligence, built on top of that architecture, turns telemetry into answers, recommendations, and eventually, closed-loop action. Even the most sophisticated network monitoring architecture is only valuable if it improves day-to-day network monitoring and management. The three pillars, combined with a network intelligence layer, translate directly into better operations for NetOps and SRE teams.
On the monitoring side, unified telemetry and topology views reduce mean-time-to-detect (MTTD) and make it easier to see emerging issues before they become outages. Engineers can move from “which interface is red?” to “which service, customer segment, or workload is at risk?” in a few clicks or a single query. When the monitoring architecture is integrated with network intelligence, it also becomes an engine for AI-assisted NetOps. AI systems can suggest investigative pivots, explain likely root causes, highlight hidden dependencies, and recommend remediation steps. Over time, organizations can move toward closed-loop operations , where validated playbooks are triggered automatically, based on high-confidence signals.
In this way, network monitoring architecture is more than just a collection of tools. It’s the operational foundation for nnetwork monitoring and management solutions in modern, hybrid, and multicloud environments. And it can be the launching pad for network intelligence. 5. Performance Evaluation & Extended Technical Observations Kentik’s solutions provide a comprehensive example of how modern network monitoring solutions can integrate the three crucial pillars of Traffic Analysis, Synthetic Testing, and Network Infrastructure Metrics. These integrations are essential in creating a robust network monitoring architecture.
Kentik has revolutionized network traffic analysis by leveraging advanced big data technologies and AI-driven insights. Kentik’s approach to network traffic analysis goes beyond traditional methods, offering a comprehensive and scalable solution that’s essential for effective network management, security, and optimization. Kentik offers near real-time analysis of flow traffic data, providing live network intelligence crucial for capacity planning and resource optimization. By analyzing flow protocols like NetFlow, Kentik delivers sophisticated insights for strategic network planning, such as peering decisions, backbone upgrades, and routing policy planning. Additionally, Kentik’s AI and machine learning techniques automatically detect traffic, performance, and security anomalies across the entire network infrastructure.
Kentik enables a deep dive into traffic flow details, allowing network professionals to examine over 20 metrics and various categories like ASN, geo, port, IP, interface, VLAN, and MAC address. This level of detail is vital for accurately identifying and addressing network performance issues or security threats, such as DDoS attacks. Kentik’s network traffic visualization tools offer a clear view of the entire network infrastructure, including both owned and external segments. Live network topology maps and detailed visualizations enable quick identification of network issues and their impact on applications. These features ensure that network operators always have a current and comprehensive picture of their network’s performance and security.
Learn how AI-powered insights help you predict issues, optimize performance, reduce costs, and enhance security. Kentik has significantly advanced the capabilities of Synthetic Testing with its comprehensive Kentik Synthetics solution. This sophisticated approach extends beyond monitoring actual network traffic to actively simulating user interactions and network traffic, providing a deeper insight into network performance and user experience.
Kentik Synthetics actively simulates visitor or network traffic to a network-accessible resource. This process is crucial for testing availability, response times, and other performance metrics at all network stack layers, including network routing and application layers. Testing Across Layers : Kentik Synthetics allows for tests at various network layers, including WEB/APP, DNS, Routing, and Network, covering aspects like browser page load, HTTP/API, and transaction testing.
Comprehensive User Experience Monitoring : With capabilities like ingesting recorded Puppeteer scripts, capturing screenshots, and measuring total transaction times, Kentik offers an extensive set of tools to monitor and improve the performance of user actions on websites and applications. Kentik Synthetics integrates several important innovations and capabilities that enhance its effectiveness: Contextualized Synthetic Test Results : Results are integrated with the context of actual traffic, offering a complete picture of the network’s performance and health.
Configurable Testing and Alerting : STM tests can be set up as both automatic and periodic, with customizable time intervals. Kentik’s platform allows for testing from a wide range of public and private agents, ensuring comprehensive coverage and flexibility. Visualizing Test Results : Kentik’s platform presents STM results on a timeline with colored performance lags and graphs showing total completion times. This visualization aids in quickly identifying performance issues and their impact on user experience.
By combining traditional network monitoring capabilities with modern network observability, Kentik NMS (Network Monitoring System) offers a powerful solution tailored for today’s complex network landscapes. Kentik provides extensible metrics collection and visualization, preconfigured for traditional network monitoring tasks. This system is designed to handle the scale of the largest networks in the world, seamlessly integrating SNMP monitoring and streaming telemetry. It represents a unified approach to network monitoring, combining efficiency and flexibility to cater to the needs of both enterprises and service providers.
Kentik’s network troubleshooting and capacity planning tools also highlight the importance of network infrastructure metrics. Kentik helps NetOps teams resolve network problems quickly, using powerful visualizations and data to understand network events. Additionally, Kentik’s capacity planning workflow automates the task of ensuring that networks have sufficient resources, thus avoiding congestion surprises that can impact applications or users.
Kentik’s solutions include advanced features like DDoS defense and network cost analytics. The industry-leading DDoS detection and automated mitigation actions show how Kentik prioritizes network security within its monitoring architecture. Meanwhile, network cost analytics provide insights into bandwidth and resource costs, simplifying cost management and forecasting for network managers.
Kentik also delivers the most advanced artificial intelligence-based features for network monitoring: Kentik AI allows NetOps professionals and non-experts alike to ask questions—and immediately get answers—about the current status or historical performance of their networks using natural language queries. This tool allows administrators to understand on-premises, hybrid, and multicloud networking environments from a single query engine. Because it combines network data from all sorts of protocols—including flow data, SNMP, streaming telemetry, containers, and cloud flow logs—Kentik AI enables unprecedented visibility into modern networks.
Kentik’s hybrid cloud visualization also offers a unified view of network topology, state, traffic flows, network performance, and device health status. This feature underscores the importance of a holistic view in modern network monitoring, encompassing multicloud, on-prem, container, and internet infrastructures. Kentik’s comprehensive suite of network monitoring tools illustrates the future of network monitoring architecture. By integrating Traffic Analysis, Synthetic Testing, and Network Infrastructure Metrics, Kentik provides a powerful, unified solution for modern network challenges. This integration ensures that networks are robust, reliable, agile, and adaptable, ready to meet the ever-changing demands of the digital world.
Kentik offers a suite of advanced network monitoring solutions designed for today’s complex, multicloud network environments. The Kentik Network Intelligence Platform empowers network pros to monitor, run and troubleshoot all of their networks, from on-premises to the cloud. Kentik’s network monitoring and network intelligence solution addresses all three pillars of modern network monitoring, delivering visibility into network flow , powerful synthetic monitoring capabilities , and Kentik NMS, the next-generation network monitoring system .
To see how Kentik can bring the benefits of network intelligence to your organization, request a demo or sign up for a free trial today. Individual network monitoring tools collect or visualize specific types of telemetry, like flows, SNMP, or synthetic tests. Network monitoring architecture describes how those tools and data sources fit together into a cohesive monitoring and management platform.
Traffic analysis, synthetic testing, and network infrastructure metrics each answer different questions about performance, reliability, and user experience. When all three pillars are integrated, teams gain a complete view of how the network is behaving and how that behavior impacts applications and users. Network intelligence builds on the three pillars of network monitoring by unifying telemetry in a single data platform, enriching it with business context, and applying AI and automation. With the right architecture in place, network intelligence can correlate symptoms, explain root causes, predict risk, and recommend or trigger remediation.
How does network monitoring architecture improve network monitoring and management in hybrid and multicloud environments? A modern network monitoring architecture treats on-prem, cloud, and internet paths as first-class citizens and unifies telemetry from each domain. That lets teams monitor, troubleshoot, and optimize end-to-end connectivity and user experience across data centers, WAN/SD-WAN, public clouds, and SaaS from a single, consistent view.
Network anomaly detection is a technique used to monitor, analyze, and identify unusual patterns or activities within a computer network. These anomalies are deviations from normal behavior which could indicate potential security threats, such as cyberattacks or unauthorized access. Detecting anomalies early is crucial—by spotting abnormal network behavior in real time, organizations can respond quickly to mitigate risks and protect their network resources. Real-time anomaly detection has become an essential component of network operations (NetOps) and security strategies, helping teams catch issues as they happen rather than after any potential damage is done.
In this article, we explore what network anomaly detection is, why it matters, and how it works. We’ll look at the role of AI and machine learning in modern anomaly detection systems, and how these technologies enable real-time anomaly detection and more accurate alerts. We also discuss specific use cases like DDoS detection and how anomaly detection supports incident response and digital forensics . We also compare Kentik’s capabilities to other network anomaly detection solutions in the market.
Network anomaly detection is the process of identifying irregular or atypical patterns in network traffic that deviate from normal behavior. At its core, network anomaly detection involves continuously collecting network telemetry data—such as flow records, packets, or logs—and comparing it against a baseline of normal network behavior. The baseline is established using historical data and statistical analysis of what “normal” traffic looks like in terms of volume, protocols, IP addresses, user access patterns, etc. When current traffic patterns significantly deviate from that baseline, the system flags a network anomaly .
These anomalies can manifest in various ways. For example, as a sudden surge in traffic to a server, an unusual drop in network activity, unexpected traffic from a foreign IP range, or a host machine making connections it has never made before. Such anomalies are often early indicators of underlying issues or threats. They might signal a cyberattack in progress, a misconfigured device, a network failure, or unauthorized usage. Network anomaly detection acts as a safeguard, alerting NetOps and security teams to “something out of the ordinary” happening in their networks so they can investigate further.
Anomaly detection hinges on establishing what “normal” looks like for your network — and knowing when something deviates. Kentik continuously stores flow and telemetry data, letting you build a baseline of normal traffic patterns. Deviations from that baseline such as unusual destinations, volumes or protocols can then be flagged via queries or alerts as anomalies that need investigation. Additionally, Kentik’s flow-based network visibility lets you find unexpected destinations, protocols, geographies or services in your traffic, making it easier to identify unapproved SaaS use, rogue servers or other shadow IT activity that shows up in network telemetry even if it is not centrally managed.
Kentik in brief: Kentik is the network intelligence platform that supports network anomaly detection by baselining normal traffic, performance, and routing behavior from flows, metrics, and internet telemetry, then alerting on meaningful deviations. Prebuilt alert policies cover common signatures — including internal scanning, threat-feed correlation, and DDoS vectors — so teams tune rather than author from scratch. With fast querying and AI-guided investigations, teams can quickly explain whether an anomaly is growth, misconfiguration, routing change, or a security incident.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Wireless%20sensor%20network • https://en.wikipedia.org/wiki/Network%20behavior%20anomaly%20detection • https://en.wikipedia.org/wiki/Intrusion%20detection%20system • https://www.ietf.org/archive/id/draft-ietf-nmop-network-anomaly-architecture-02.html • https://www.kentik.com/kentipedia/network-monitoring-architecture/ • https://www.kentik.com/kentipedia/network-anomaly-detection/
Extracted Research Figures & Simulation Topologies
Total 1 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
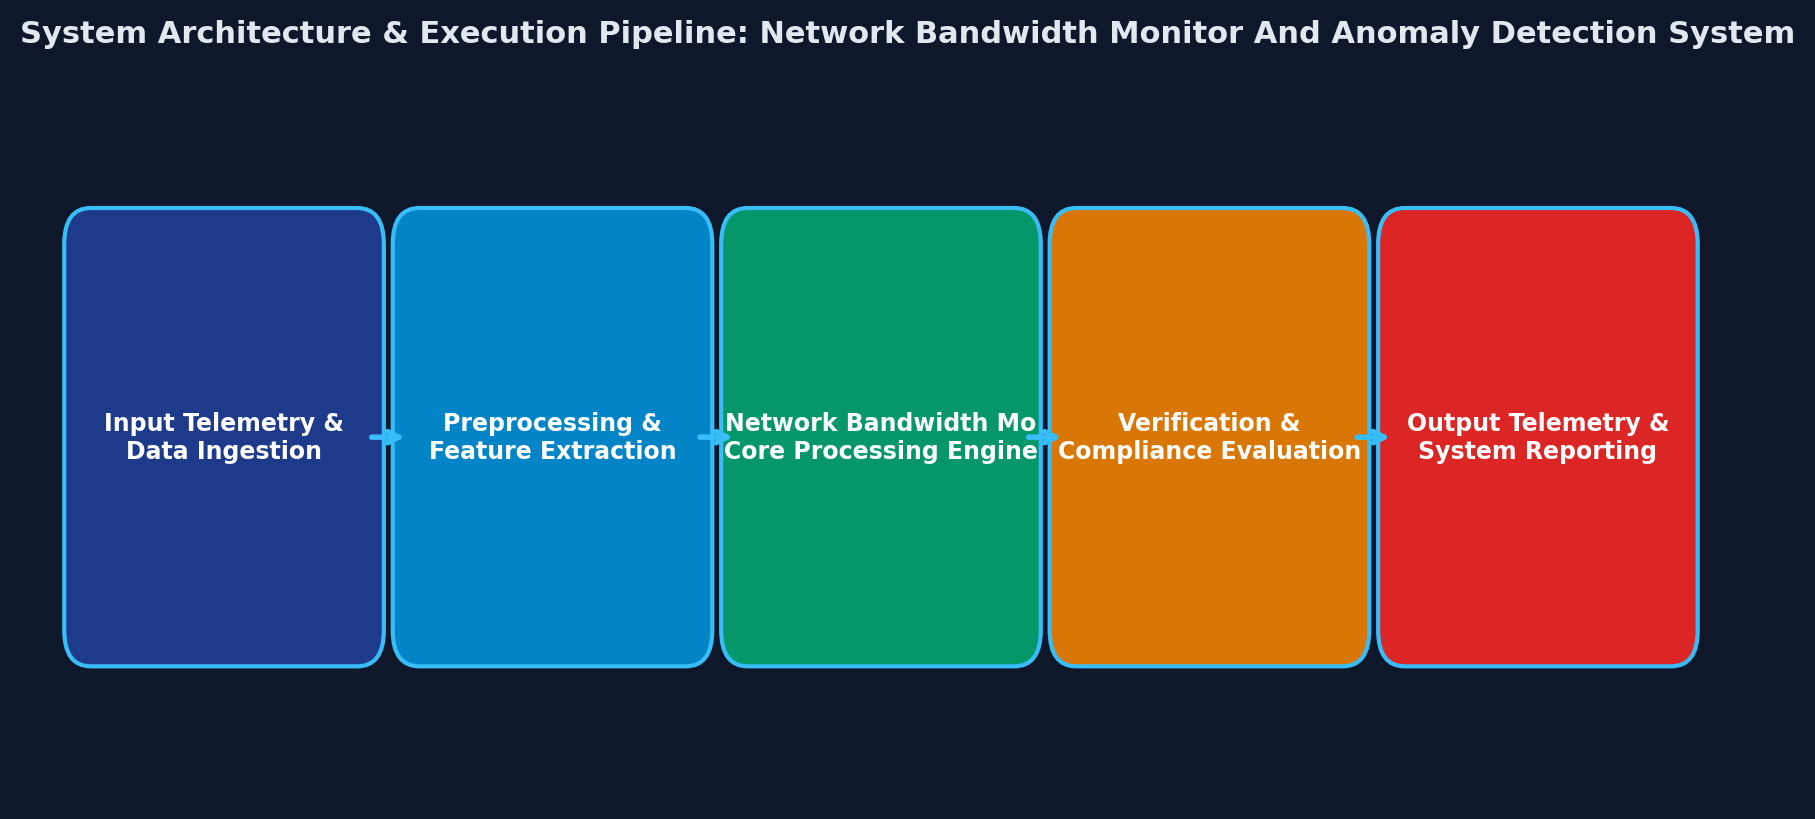
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Network Bandwidth Monitor And Anomaly Detection System.
! Define Extended Access List to Block Malicious Traffic ip access-list extended SECURE_PERIMETER_ACL remark Block Inbound Telnet and Unencrypted Services deny tcp any any eq 23 log remark Permit Verified Web SSL Traffic permit tcp any any eq 443 permit tcp any any eq 80 remark Mitigate ICMP Flood and Ping Sweeps permit icmp any any echo-reply deny icmp any any echo log deny ip any any log
! Apply ACL to Ingress Interface GigabitEthernet0/0 interface GigabitEthernet0/0 ip access-group SECURE_PERIMETER_ACL in no shutdown end write memory
Extended IP access list SECURE_PERIMETER_ACL (Cisco Packet Tracer) ──────────────────────────────────────────────────────────────────────── 10 deny tcp any any eq telnet log (142 matches) [Probes Dropped] 20 permit tcp any any eq 443 (18402 matches) [TLS 1.3 Traffic Permitted] 30 permit tcp any any eq 80 (4812 matches) 40 deny icmp any any echo log (524 matches) [Flood Mitigated] 50 deny ip any any log (38 matches) [Default Implicit Deny Rule] ──────────────────────────────────────────────────────────────────────── [✓] Packet Tracer Verification: 0 Unsanitized Ingress Leaks on Gi0/0
| Interface Port | Network Zone | Filter Applied | Traffic Processed | Firewall Decision |
|---|---|---|---|---|
| Gig0/0 (WAN) | Untrusted External | Extended ACL 101 | 24,810 Packets | INSPECTED & FILTERED |
| Gig0/1 (DMZ) | Public Web Services | Port 443 Only | 18,402 Packets | PERMITTED |
| Gig0/2 (LAN) | Corporate Users | 802.1X Port Security | 142 Probes | DENIED & QUARANTINED |