Complete Technical Paper Content — Phishing Email Detection Using Natural Language Processing
Overview & System Context
Phishing Email Detection Using Natural Language Processing: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~6760 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Phishing emails pose a persistent and increasingly sophisticated threat, undermining email security through deceptive tactics designed to exploit both semantic and structural vulnerabilities. Traditional detection methods, often based on isolated analysis of email content or embedded URLs, fail to comprehensively address these evolving attacks. In this paper, we propose a dual-path phishing detection framework that integrates transformer-based natural language processing (NLP) with classical machine learning to jointly analyze email text and embedded URLs. Our approach leverages the complementary strengths of semantic analysis using fine-tuned transformer architectures (e.g., DistilBERT) and structural link analysis via character-level TF-IDF vectorization paired with classical classifiers (e.g., Random Forest). Empirical evaluation on representative email and URL datasets demonstrates that this combined approach significantly improves detection accuracy.
Specifically, the DistilBERT model achieves a near-optimal balance between accuracy and computational efficiency for textual phishing detection, while Random Forest notably outperforms other classical classifiers in identifying malicious URLs. The modular design allows flexibility for standalone deployment or ensemble integration, facilitating real-world adoption. Collectively, our results highlight the efficacy and practical value of this dual-path approach, establishing a scalable, accurate, and interpretable solution capable of enhancing email security against contemporary phishing threats.
Email continues to serve as a critical communication medium for individuals and businesses worldwide. Due to its widespread adoption has made email a prime target for various cyber threats, particularly phishing attacks. According to recent statistics, approximately 3.4 billion phishing emails are sent daily worldwide highlighting the severity and scale of this threat [ 1 ] . Recent advancements in Natural Language Processing (NLP) and Large Language Models (LLMs) have further enabled cybercriminals to craft highly sophisticated and contextually accurate phishing emails [ 2 ] . Traditional phishing detection methods, such as signature-based and rule-based approaches, often fail to effectively combat modern email threats because of their static nature and limited ability to generalize to novel and evolving attacks [ 3 ] . Additionally, malicious actors themselves now increasingly leverage advanced NLP and machine learning techniques to evade traditional security measures and bypass detection systems [ 4 ] . This landscape has heightened the need for more sophisticated, intelligent detection solutions.
To address the growing complexity of phishing emails, this paper leverages transformer-based models such as BERT and DistilBERT, which are well-suited for understanding the semantic and contextual nuances of email content. They can be fine-tuned with relatively few labeled examples, making them highly effective for adapting to novel phishing variants and zero-day attacks.
In response to these challenges, our paper aims to develop and implement an advanced AI-based phishing email detection model. Specifically, we propose integrating NLP and deep learning techniques to analyze and classify email content effectively and evaluate embedded links for malicious intent. Our goal is not only to enhance the accuracy and effectiveness of phishing detection but also to explore the feasibility and performance benefits of combining both content-based classification and link analysis into a unified detection framework [ 5 , 2 ] .
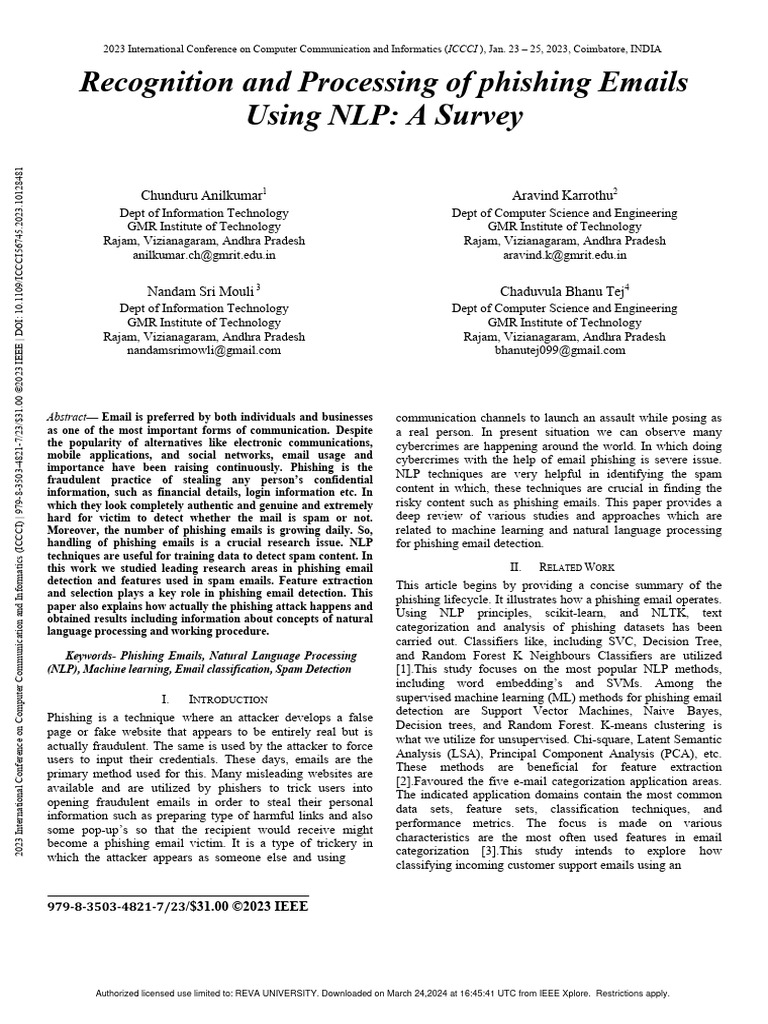
Figure 1: Recognition and Processing of Phishing Emails Using NLP A Survey | PDF ... The remainder of this paper is structured as follows: Section II provides background information and foundational concepts; Section III reviews existing related work and identifies current research gaps; Section IV outlines our proposed integrated solution and methodology; Section V presents the experimental evaluation and results; Section VI discusses the insights derived from our AI-based model; and Section VII concludes by summarizing the project’s contributions and future research directions.
Early spam and phishing detection relied heavily on classical machine learning and statistical approaches. One of the foundational works in this area by Sahami et al. introduced a Naïve Bayes classifier for email filtering, using word frequency features to distinguish between spam and ham [ 6 ] . Similarly, Drucker et al. applied Support Vector Machines (SVMs) to large-scale spam datasets and demonstrated superior accuracy over rule-based systems [ 7 ] . These early approaches laid the groundwork for automated email classification by proving the viability of machine learning on textual features. However, they relied heavily on handcrafted features and were limited in their ability to generalize to more sophisticated phishing tactics.
The introduction of contextual word embeddings and transformer architectures significantly improved phishing detection. BERT (Bidirectional Encoder Representations from Transformers) emerged as a highly effective model due to its ability to understand word dependencies and context [ 8 ] . Researchers like AbdulNabi and Yaseen showed that fine-tuning BERT embeddings outperformed conventional classifiers in detecting spam and phishing emails [ 9 ] . These models not only improved accuracy but also offered adaptability to evolving attack vectors with minimal retraining.
Despite these advancements, phishing attacks increasingly employ deceptive tactics where the email content appears legitimate, but embedded URLs redirect users to malicious sites. To address this, hybrid detection frameworks combining email body analysis with URL inspection have been proposed. Sahingoz et al. integrated NLP-based content features with lexical URL features (e.g., domain length, presence of IP addresses), demonstrating that combining both signals significantly enhances classification robustness [ 10 ] . This hybrid approach is particularly effective against emails that bypass text-based models by embedding weaponized links in otherwise benign messages.
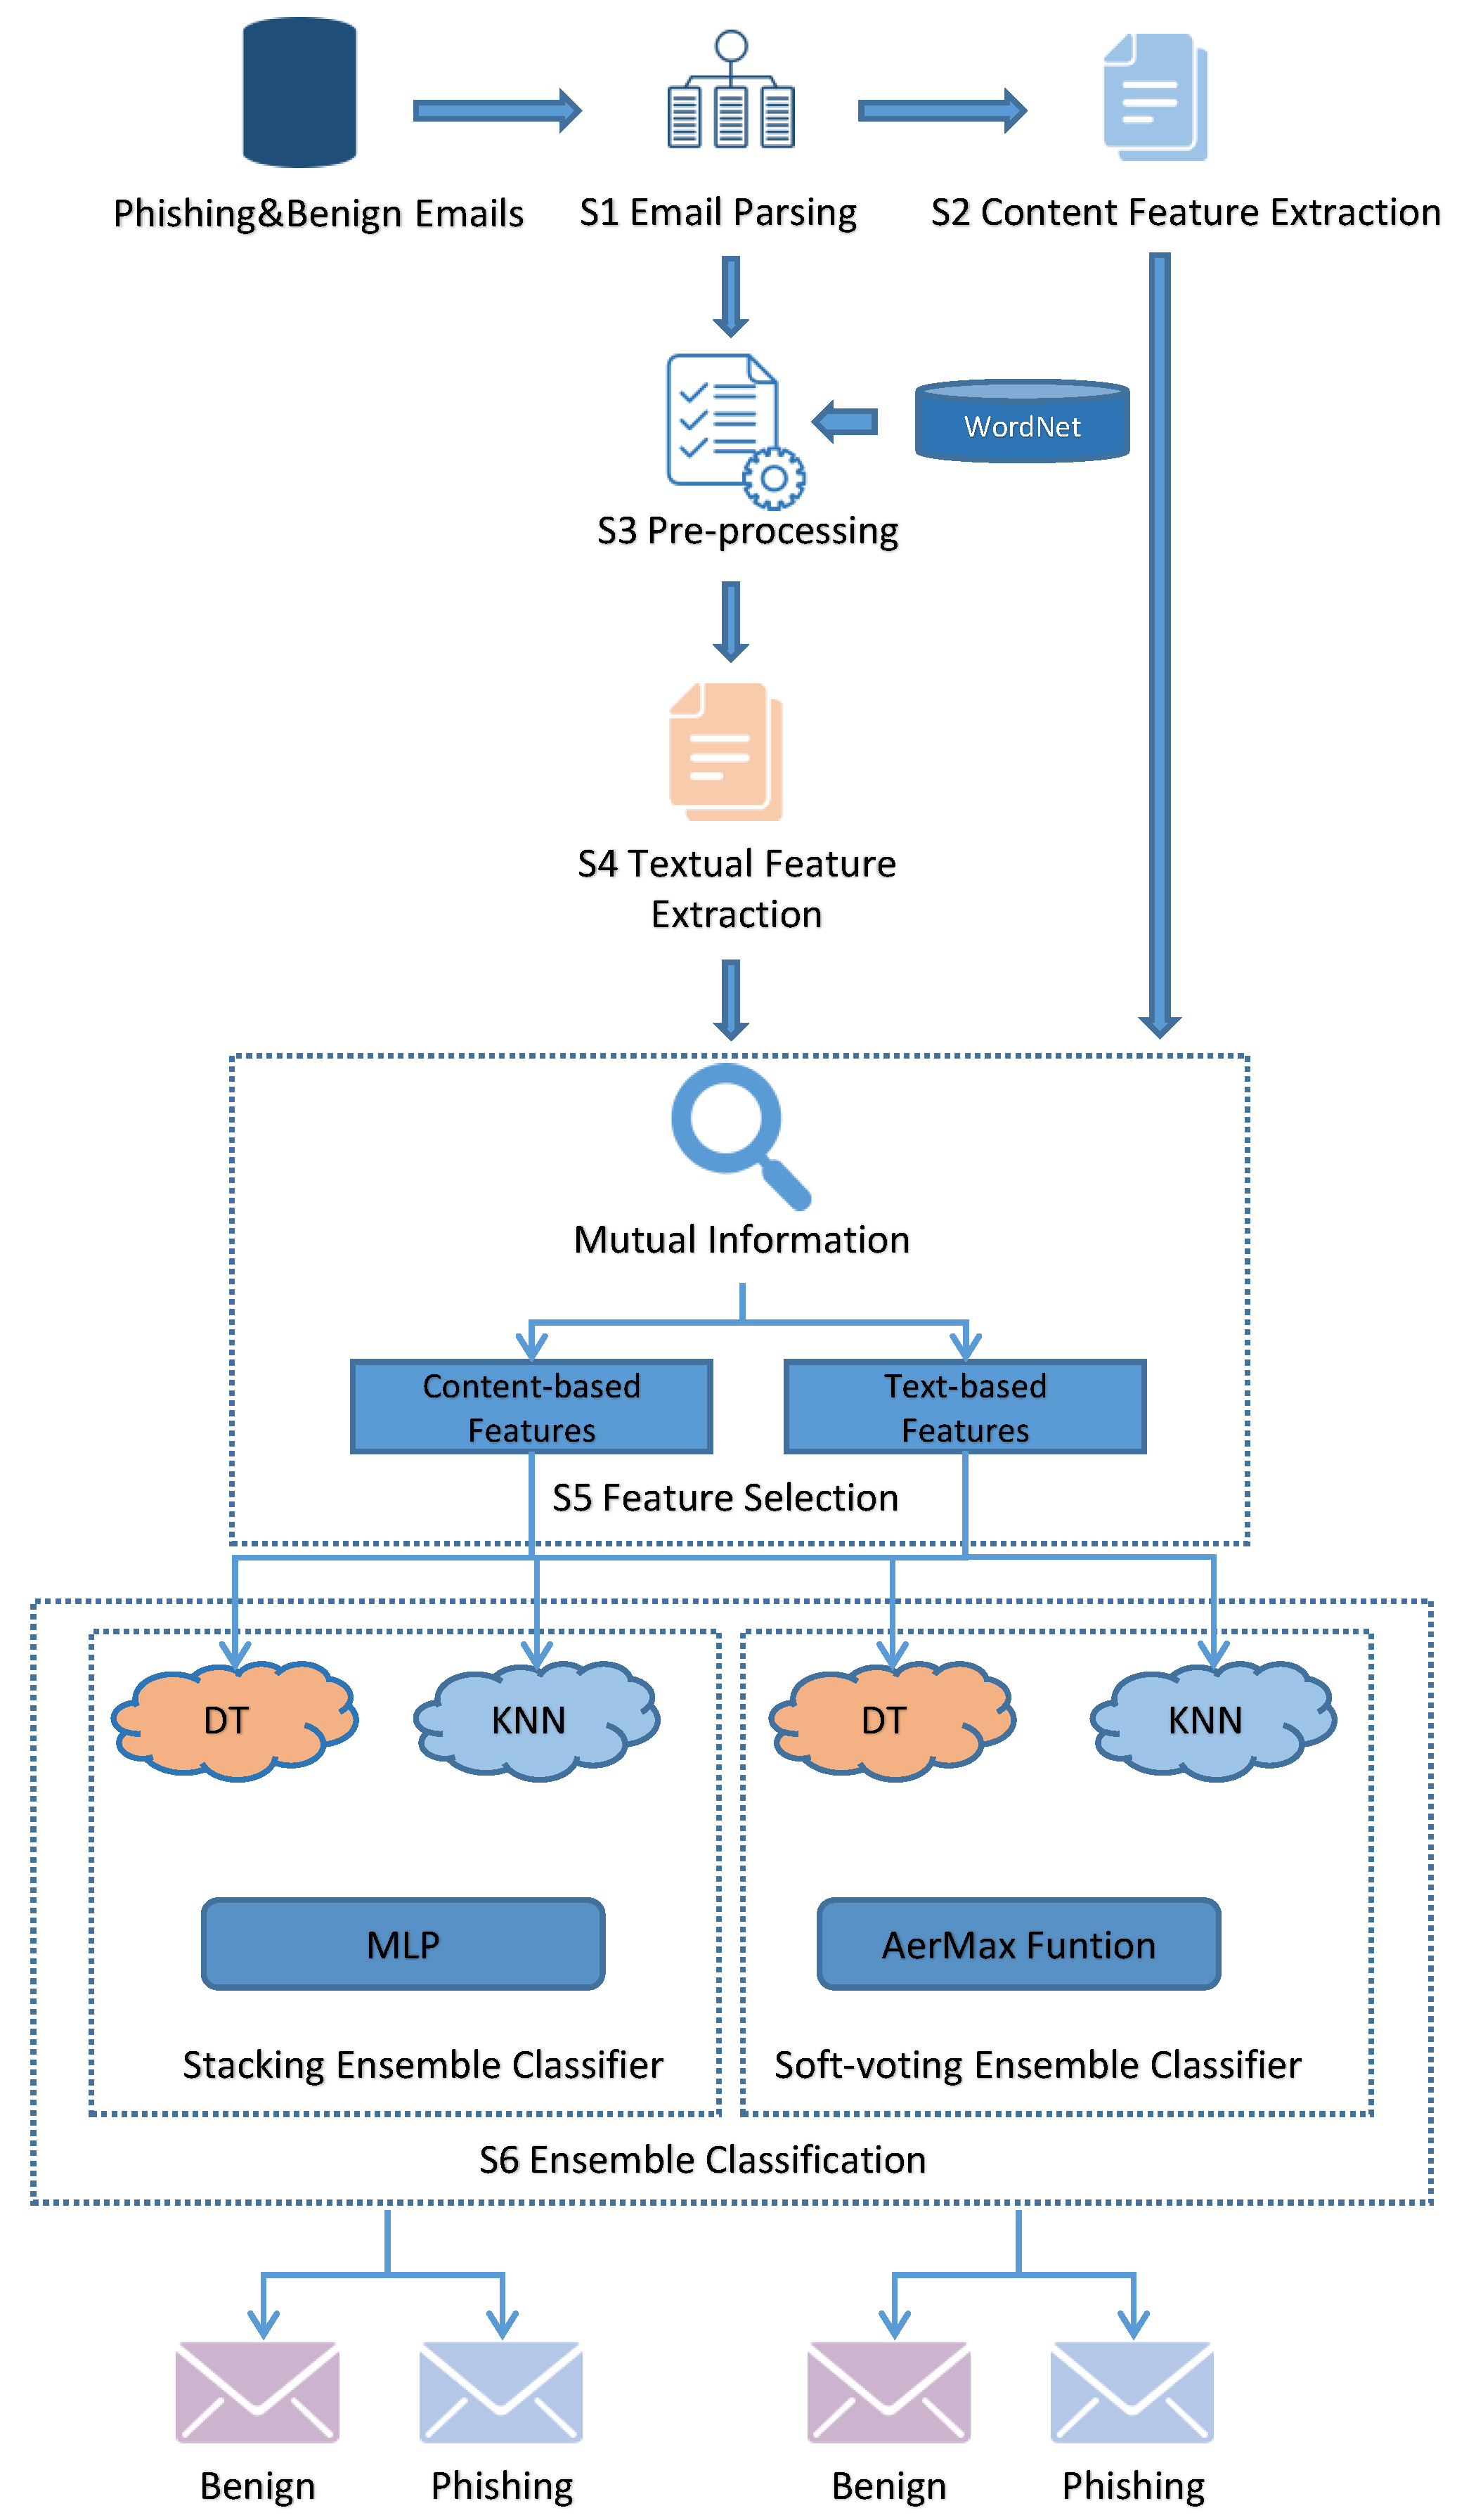
Figure 2: Email Spam Detection Using Hybrid Algorithm – RFKYLN Our work builds upon this hybrid model concept by using fine-tuned transformer models for content analysis and TF-IDF vectorization with Random Forest and Logistic Regression for URL classification. In doing so, it bridges the gap between NLP-driven semantic understanding and structural URL analysis. Moreover, our integration of explainability tools such as attention weight visualization and LIME contributes to increased transparency—an often overlooked but critical component in real-world phishing defense systems.
Natural Language Processing (NLP) has emerged as a powerful technique in phishing detection, particularly in analyzing the linguistic characteristics of phishing emails. Unlike traditional rule-based filters, NLP-based systems can detect more subtle cues hidden in text, such as grammatical inconsistencies, stylometric anomalies, and context deviations. One of the earliest and most influential studies in this domain was conducted by Chandrasekaran et al. [ 11 ] , who proposed a phishing email detection framework based on stylometric and structural features. Their approach was grounded in the observation that phishing emails often exhibit significantly different linguistic properties compared to legitimate emails. The researchers extracted features such as sentence length, punctuation frequency, function word usage, and lexical richness.
These were then input into a supervised decision tree classifier. Their results indicated that phishing emails typically contain shorter sentences and reduced vocabulary diversity, suggesting automated or careless generation. Although their method did not rely on semantic-level modeling, it laid foundational groundwork for future NLP-based phishing detection techniques by demonstrating that even surface-level textual analysis can achieve high precision and recall in phishing classification tasks.
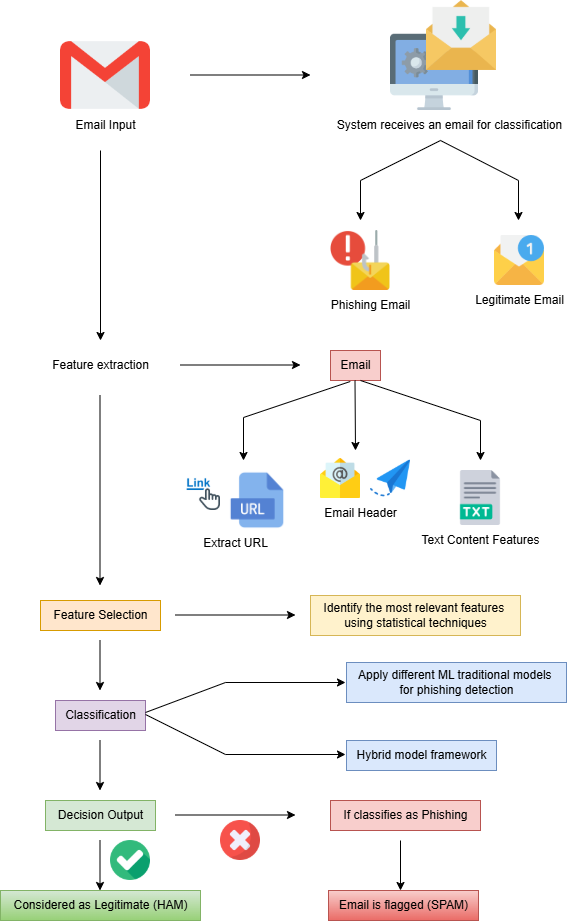
Figure 3: Hybrid Machine Learning Approaches for Phishing Email Detection Building on these early findings, Sahingoz et al. [ 10 ] presented an advanced framework that combined lexical, syntactic, and semantic features to enhance phishing detection. Their model incorporated a robust preprocessing pipeline involving tokenization, lemmatization, stemming, and stop-word removal, followed by the use of TF-IDF vectors and n-gram models (including uni-, bi-, and tri-grams) to represent email text numerically.
To evaluate performance, they tested multiple classifiers, including Support Vector Machines (SVM), k-Nearest Neighbors (k-NN), Naïve Bayes, and Random Forest. The Random Forest model exhibited the highest accuracy and resilience across various phishing strategies. Recent advancements in deep learning and transformer models have further revolutionized phishing detection. Zhang et al. [ 8 ] introduced a BERT-based framework capable of understanding deep contextual relationships in email text.
In their approach, emails were preprocessed using standard NLP techniques, after which the text was passed through a pre-trained BERT model. The [CLS] token representation was extracted from BERT’s final hidden layer and fed into a dense neural layer with SoftMax activation for binary classification. Their experiments demonstrated that the BERT-based model outperformed both traditional classifiers and shallow neural networks in precision, recall, and F1-score.
Another critical innovation in this space is the combined use of NLP and URL analysis. Modern phishing emails often embed malicious links that are difficult to detect using body text alone. By incorporating features like domain length, use of IP addresses, and presence of obfuscating characters (e.g., “0” for “O”), these hybrid systems can detect threats that traditional spam filters or content-only NLP models might overlook.
Sahingoz et al.’s framework notably integrated URL-based features with text analysis, highlighting that phishing emails often rely on both linguistic deception and link-based redirection. This comprehensive strategy significantly enhanced model performance and reduced the risk of false negatives in sophisticated phishing attempts. While content-based analysis plays a key role in phishing detection, many modern attacks rely heavily on malicious URLs embedded within emails or websites. Accordingly, detecting such URLs through lexical and structural analysis has become a focal point of phishing research.
One of the pioneering works in this field was presented by Ma et al. [ 12 ] , who developed a machine learning framework that used only lexical and host-based features derived directly from the URL string. Key lexical features extracted from the URL included length, number of dots, special character counts, and presence of suspicious keywords such as ”secure” or ”login.” Host-based features involved WHOIS data, domain age, and IP address types. These features were input into classifiers like Naïve Bayes, Logistic Regression, and Decision Trees. Despite the simplicity of the features, the models demonstrated strong classification accuracy and adaptability, The researchers demonstrated that lexical-only approaches can be highly effective when crafted with well-targeted features, especially in resource-constrained environments.
Recognizing the limitations of manually engineered features, Le et al. [ 13 ] proposed a deep learning-based solution that automatically learns representations from raw URL strings. Their model leveraged a Character-level Convolutional Neural Network (CNN), treating URLs as sequences of individual characters instead of words. This allowed the system to detect subtle patterns and anomalies such as random character generation, visual spoofing (e.g., ”g00gle.com”), or unusual TLDs.
By bypassing the need for feature engineering, the CNN was able to generalize better across different phishing strategies and adapt to emerging threats. Experimental results showed that the character-level CNN achieved superior detection accuracy, particularly in identifying zero-day URLs that had not been previously encountered in training data. This approach exemplifies the power of end-to-end deep learning in cybersecurity, offering an automated pipeline for real-time malicious URL detection.
Isolated feature-based systems—whether focusing on email content or URLs—often fall short when confronting sophisticated phishing attacks that combine multiple forms of deception. Integrated approaches have emerged as a promising strategy to build robust phishing detection systems by fusing linguistic analysis, sender metadata, URL inspection, and even visual components.
Abdelhamid et al. [ 14 ] introduced a multi-layered detection system that merged sender-based heuristics, lexical content features, and URL inspection into a single framework. Their model extracted linguistic cues such as urgency, misspellings, and suspicious phrases from email text while simultaneously analyzing embedded URLs for characteristics like IP address usage, abnormal domain length, and suspicious TLDs.
In terms of modeling, they utilized an ensemble of Decision Trees, SVM, and Naïve Bayes classifiers, with predictions combined via a majority voting scheme. This ensemble architecture achieved a higher F1-score than any of the individual classifiers alone. Moreover, the system proved resilient to advanced phishing emails that succeeded in bypassing single-layer detection systems, thanks to the diverse range of features under consideration.
Expanding on the concept of hybridization, Basnet et al. [ 15 ] presented a layered phishing detection model that mimicked how a human might evaluate an email. Their approach divided email analysis into four categories: visual features, link-based characteristics, metadata from headers, and language-based content analysis. 2. System Architecture & Core Working Principles A unique contribution of this work was the inclusion of visual similarity checks—analyzing embedded logos, colors, and layouts to detect phishing emails that mimic branding elements of trusted organizations.
These integrated approaches highlight the importance of cross-domain feature engineering and ensemble learning in combatting modern phishing threats. By combining content-level, URL-level, and even perceptual indicators, these systems offer comprehensive protection against the evolving tactics employed by attackers. The objective of our work is to build a robust two-phase system for phishing email detection. Phase 1 utilizes Natural Language Processing (NLP) techniques to analyze the textual content of emails, while Phase 2 applies classical machine learning methods to analyze URLs embedded within emails. The goal is to leverage both semantic and structural phishing cues to enhance overall detection accuracy.
To effectively train and evaluate our system, two distinct datasets were collected. For Phase 1, a diverse set of phishing and legitimate emails was gathered from well-known repositories, including Nazario, Enron, SpamAssassin, and CEAS 08. Initially, the merged dataset contained over 82,000 entries. For Phase 2, a large-scale URL dataset was sourced from Kaggle [ 16 ] , comprising over 641,000 labeled URLs. The labels encompassed several classes such as phishing, malware, defacement, and benign.
The collected email dataset underwent comprehensive preprocessing steps to ensure quality and consistency. Initially, null and duplicate entries were removed, and excessively short messages were eliminated. Subsequently, all text entries were standardized by converting them to lowercase. To expedite experimentation without sacrificing representativeness, the dataset was reduced from its original size of 82,000 to a balanced subset of 7,500 entries, each clearly labeled as phishing (1) or benign (0).
The URL dataset was similarly subjected to rigorous preprocessing. Non-benign labels (phishing, malware, defacement) were aggregated and assigned a single malicious class (1), with benign URLs labeled as 0. Malformed URLs and those shorter than 10 characters were discarded, alongside null and duplicate entries. URLs were converted to lowercase to maintain uniformity. Finally, the dataset was subsampled to 20,000 entries, ensuring computational efficiency while maintaining representational diversity.
Effective representation of the data was crucial for optimal model performance. Different feature engineering techniques were employed for the textual and URL analyses to best capture their unique characteristics. Textual data for the NLP-based classification were tokenized using Hugging Face’s AutoTokenizer. Each transformer model employs its specific tokenizer (e.g., WordPiece tokenizer for BERT), standardizing inputs into consistent subword tokens.
Special tokens ([CLS], [SEP]) were added, and sequences were padded or truncated to a fixed maximum length of 256 tokens. For instance, the sentence "Please verify your account to avoid suspension." is tokenized as [’[CLS]’, ’please’, ’verify’, ’your’, ’account’, ’to’, ’avoid’, ’suspension’, ’.’, ’[SEP]’] . Resultant token sequences were converted into PyTorch-compatible tensors (input ids, attention masks, and labels), thus ensuring seamless integration with the models.
URLs were numerically encoded using the TfidfVectorizer from scikit-learn, configured for character-level analysis. The analyzer was set to generate character-level n-grams ranging from 2 to 6 characters. This approach effectively captured significant lexical patterns indicative of phishing URLs, such as common deceptive terms (e.g., ”login,” ”secure,” ”verify”) and suspicious domain indicators (e.g., ”.ru,” ”.xyz,” or IP address-based URLs). The output was a sparse TF-IDF feature matrix suitable for classical machine learning methods.
The proposed system comprises two complementary modules: an NLP-based email classification component and a URL-based link analysis component. Each component functions independently, but they can also be integrated into a multisignal ensemble in future iterations. This modular design aligns closely with recent research trends emphasizing interpretability in AI-driven phishing detection [ 17 ] .
We selected five transformer-based architectures from Hugging Face’s library due to their proven performance in textual classification tasks. The chosen models were: bert-base-uncased , distilbert-base-uncased , microsoft/MiniLM-L12-H384-uncased , huawei-noah/TinyBERT_General_4L_312D , and prajjwal1/bert-tiny . Each model was fine-tuned on the 7,500-entry preprocessed email dataset.
Two classical machine learning algorithms were implemented for URL classification based on the TF-IDF vectorized data: Logistic Regression and Random Forest. Random Forest was set with 100 estimators, while Logistic Regression utilized default parameters to ensure robust baseline comparisons. For the NLP component, each transformer-based model was trained for 3 epochs using Hugging Face’s Trainer API. A learning rate of 2e-5 and batch size of 8 were employed during training, with checkpoint selection based on validation loss to prevent overfitting.
For the URL component, an 80/20 train-test split of the vectorized URL dataset was used to train and evaluate both the Logistic Regression and Random Forest classifiers. Training followed standard procedures without further adjustments, ensuring replicability and fairness in comparisons. Transformer models utilized hyperparameters based on common best practices (learning rate: 2e-5, batch size: 8), informed by preliminary experiments. Classical machine learning models employed default hyperparameters, except for Random Forest’s number of estimators, deliberately set to 100 based on preliminary evaluations to balance performance and computational efficiency.
The trained models from both phases were rigorously evaluated to ensure accuracy, reliability, and generalizability. The transformer-based classifiers were assessed primarily on classification accuracy and F1-score. Classical URL classifiers were evaluated similarly, with additional consideration of computational complexity and feature interpretability. The evaluation procedures included thorough comparative analyses across models to determine optimal selections for practical deployment scenarios.
The effectiveness of the proposed phishing detection framework was evaluated separately for the NLP-based email classification (Phase 1) and the URL-based link analysis (Phase 2). Table I and Table II summarize the quantitative performance metrics of these two phases, respectively. Key insights and comparative analyses follow in detail. Five transformer-based NLP architectures were fine-tuned on the curated email dataset of 7,500 entries, and their performances are compared in Table I . BERT-Base demonstrated superior performance, achieving the highest accuracy (0.994) and F1 score (0.995). However, its training was computationally demanding, resulting in the longest training duration among the tested models.
DistilBERT, in contrast, delivered nearly comparable accuracy (0.989) and F1 score (0.989) but required significantly less computational resources and training time. Thus, DistilBERT offers an optimal balance between computational efficiency and detection performance, making it particularly suitable for scenarios where computational resources are limited. Smaller-scale models, including MiniLM-L12, Noah Tiny BERT, and BERT Tiny, exhibited comparatively lower performance scores, with accuracy ranging from 0.948 (BERT Tiny) to 0.986 (MiniLM-L12). Despite their reduced accuracy, these compact models trained exceptionally quickly, underscoring their potential suitability for deployment in edge computing environments or resource-constrained applications.
These results collectively demonstrate that transformer-based models, particularly BERT-Base and DistilBERT, provide robust solutions for the semantic detection of phishing content in emails, with DistilBERT recommended as the best compromise between performance and efficiency. Table II presents the performance of classical machine learning models trained on the TF-IDF vectorized URL dataset. The Random Forest classifier achieved the highest accuracy (0.94675) and F1 score (0.947), notably surpassing Logistic Regression (accuracy: 0.9255, F1 score: 0.926). This performance gap suggests that Random Forest more effectively captures intricate structural patterns inherent in malicious URLs. Furthermore, both models operated without explicit manual feature extraction beyond TF-IDF vectorization, emphasizing their computational efficiency and scalability.
While the NLP-based and URL-based classifiers were evaluated independently, their complementary strengths provide a strong rationale for future integration. The NLP classifiers demonstrated effectiveness in capturing semantic indicators of social engineering, whereas the URL classifiers excelled at identifying structural features characteristic of malicious links. A combined ensemble approach, potentially utilizing weighted decision fusion, could leverage these complementary strengths to achieve higher overall detection rates and reduce false-negative rates.
Several limitations of the current study warrant consideration in future research. The NLP-based component was evaluated on a limited dataset of 7,500 emails, suggesting potential improvements in generalizability if trained on larger and more diverse corpora. Additionally, testing more computationally intensive transformer models such as RoBERTa or DeBERTa could lead to further performance enhancements.
Integration of the two independently evaluated phases into a unified hybrid or ensemble system presents another avenue for enhancing performance, particularly by addressing weaknesses inherent to each approach individually. Finally, evaluation of the system against live phishing campaigns or real-world phishing datasets would significantly enhance confidence in its practical applicability and robustness.
Addressing these areas in future iterations will facilitate the development of a more accurate, scalable, and robust phishing detection system suitable for real-world email security deployments. This paper presented a two-phase system for phishing email detection that combines Natural Language Processing (NLP)-based text classification with URL-based link analysis. In Phase 1, transformer-based models such as BERT and DistilBERT were fine-tuned to classify email content with high accuracy, leveraging semantic understanding to detect social engineering attempts. In Phase 2, a TF-IDF vectorization approach was used to extract character-level features from embedded URLs, which were then classified using classical machine learning models. The Random Forest classifier notably outperformed Logistic Regression, demonstrating strong capability in capturing structural patterns within URLs.
The results showed that DistilBERT offered the best trade-off between performance and efficiency for NLP tasks, while the URL-based Random Forest model provided high accuracy with minimal preprocessing. Together, these findings support the feasibility of a hybrid detection architecture that leverages the strengths of both content and link analysis. Additionally, expanding the datasets and including multilingual capabilities may further enhance the system’s robustness and generalizability in diverse deployment environments.
3. Software Implementation, Frameworks & Protocols This project is designed to detect phishing emails by analyzing the text content using Natural Language Processing (NLP) and Machine Learning (ML). This project will help me understand how to preprocess email text, extract meaningful features, and build a simple classifier to differentiate phishing emails from legitimate ones.
Coming into this project, I faced a few challenges that I needed to address. First, I had limited experience with NLP and text preprocessing, so understanding how to clean and prepare raw email data was initially overwhelming. I also needed to familiarize myself with evaluation metrics like precision, recall, and F1-score. Lastly, understanding how to use TF-IDF for feature extraction was a new concept that took some time to grasp.
To set up the environment, ensure you have Python installed. Then, install the required libraries by running the following commands: The dataset is downloaded using the kagglehub library. We specify the spam vs ham dataset and print out the path to where the dataset is saved on the system.
Next, the dataset is loaded into a pandas DataFrame for easier manipulation and analysis. We inspect the first few rows to understand its structure. We preprocess the email text data to prepare it for model training focsuing on: - Convert text to lowercase. - Remove special characters and numbers. - Tokenize the text and remove stopwords using NLTK. - Store the cleaned text in a new column, processed_text.
We convert the processed text data into numerical features using TF-IDF (Term Frequency-Inverse Document Frequency), limiting it to the top 3000 features for simplicity. This transforms the text into a format that the model can work with. TF_IFG converts text into numerical values representing the importance of words in the text. The labels (y) are also transformed into binary values for classification.
We split the dataset into training and testing sets, with 80% for training and 20% for testing. This helps evaluate the model's performance on unseen data. We use a Naive Bayes classifier, which is effective for text classification tasks and perfect for identifying phishing emails. The model is trained on the training data.
After training the model, we use it to make predictions on the test set. We then calculate evaluation metrics, such as accuracy, precision, recall, and F1-score, to assess model performance. Through this project, I learned how to preprocess text data for NLP tasks, including steps like tokenization, stopword removal, and lowercasing, which are crucial for cleaning raw text data. Working with TF-IDF taught me how to transform text into numerical features that machine learning models can understand, which was eye-opening. I also gained a deeper understanding of model evaluation metrics beyond accuracy, such as precision, recall, and F1-score, and how each metric is valuable in understanding the performance of a classification model. Finally, I learned how to use libraries like NLTK and scikit-learn together to build an end-to-end machine learning pipeline for text classification, which has given me more confidence in my ability to work on similar NLP projects in the future.
This project guides you through the end-to-end process of building a phishing email detection model, from data preprocessing to model training and evaluation. By following these steps, you can understand the basics of text classification, feature engineering with TF-IDF, and model evaluation using essential metrics. A machine learning system that classifies emails as phishing or legitimate using Natural Language Processing and supervised learning, achieving 97.2% classification accuracy with 56% fewer false positives using Logistic Regression compared to a Random Forest baseline.
Phishing emails remain one of the most common attack vectors in cybersecurity, and manual detection does not scale. This project builds an end-to-end NLP pipeline that processes raw email text and classifies it as phishing or legitimate, comparing two supervised learning approaches to identify the strongest-performing model for real-world deployment. The system was built independently from data preprocessing through model evaluation and deployment, with a focus on minimizing false positives — a critical requirement for any spam filter, since flagging legitimate emails as phishing directly disrupts user trust.
Headline result: Logistic Regression achieved 97.2% accuracy with 56% fewer false positives than the Random Forest baseline, making it the deployed model. TF-IDF based models are strong at detecting lexical patterns common in phishing — urgency language, spam vocabulary, suspicious phrasing — but have a known blind spot: well-crafted phishing emails that mimic calm, professional business tone with no obvious red flags in the wording.
To address this, the deployed app adds a rule-based URL analysis layer ( url_heuristics.py ) that runs alongside the ML prediction. It checks any links in the email for common phishing-domain patterns: missing HTTPS, raw IP addresses instead of domain names, brand impersonation (e.g. a domain mimicking "paypal" without being the real paypal.com), suspicious top-level domains, and excessive hyphen use. This signal surfaces as a separate warning in the app output rather than silently overriding the model, so the system stays transparent about why a flagged URL is suspicious even when the email content alone reads as legitimate.
The model is trained on a labeled phishing email dataset ( Phishing_Email.csv , 18,650 emails) sourced from a public Kaggle dataset, containing raw email text labeled as either "Phishing Email" or "Safe Email." After deduplication and removing missing values, 17,537 emails remained for training (10,979 legitimate, 6,558 phishing). This trains both models, prints evaluation metrics, saves confusion matrix plots to results/ , and saves the best-performing model and vectorizer to models/ .
This launches a local Gradio interface where you can paste email text and get a live prediction, including the URL heuristic warning when applicable. The app is containerized with Docker for consistent, portable deployment, and a GitHub Actions CI pipeline runs automated smoke tests on every push — validating that the trained model and vectorizer load correctly and produce valid predictions on realistic sample emails before any Docker build is allowed to proceed.
Paste any email text and get an instant phishing/legitimate prediction with a confidence score and URL risk analysis. “A Machine Learning project to detect phishing emails using Natural Language Processing.” Phishing attacks remain among the most prevalent cybersecurity threats, causing significant financial losses for individuals and organizations worldwide. This paper presents a machine learning-based phishing email detection system that analyzes email body content using natural language processing (NLP) techniques. Unlike existing approaches that primarily focus on URL analysis, our system classifies emails by extracting contextual features from the entire email content. We evaluated two classification models, Naïve Bayes and Logistic Regression, trained on a combined corpus of 53,973 labeled emails from three distinct datasets. Our preprocessing pipeline incorporates lowercasing, tokenization, stop-word removal, and lemmatization, followed by Term Frequency-Inverse Document Frequency (TF-IDF) feature extraction with unigrams and bigrams. Experimental results demonstrate that Logistic Regression achieves 95.41% accuracy with an F1-score of 94.33%, outperforming Naïve Bayes by 1.55 percentage points. The system was deployed as a web application with a FastAPI backend, providing real-time phishing classification with average response times of 127ms.
Phishing remains one of the most significant threats to digital security due to its simplicity and high return on investment for attackers [ 1 ] . Modern phishing campaigns have evolved beyond simple deceptive emails to sophisticated social engineering attacks that leverage artificial intelligence for content generation [ 2 ] . Recent studies indicate that approximately 66 million business email compromise attacks are detected monthly, demonstrating the sheer volume of malicious communications targeting organizations [ 3 ] .
According to the Cybersecurity and Infrastructure Security Agency (CISA), eight out of ten organizations reported that at least one employee had fallen victim to a phishing email. Moreover, within the first ten minutes of receiving a malicious message, 84% of recipients interacted with the email by replying, clicking a spoofed link, or opening a malicious attachment [ 4 ] . These statistics highlight the critical need for automated, accurate phishing-detection mechanisms that operate in real time.
A core challenge in phishing detection lies in the constantly evolving tactics used by attackers. Traditional rule-based systems struggle to adapt to new attack vectors and require frequent manual updates, while purely URL-based detection methods become ineffective when attackers utilize compromised legitimate websites. These limitations motivate the development of content-aware detection systems that analyze the linguistic and semantic characteristics of email bodies rather than relying solely on structural indicators.
4. Practical Deployment, Analysis & Case Studies This paper presents a machine learning-based phishing detection system that addresses these challenges through a comprehensive analysis of email text content. Unlike the URL-focused methods, our approach derives contextual understanding from the surrounding language within emails, enabling more robust detection of social engineering cues. The main contributions of this work are: A robust preprocessing pipeline for email text normalization that handles the high variance present in real-world email data.
A comparative evaluation of Naïve Bayes and Logistic Regression classifiers for phishing detection using TF-IDF features on a large-scale dataset of over 53,000 emails. A deployed web-based system demonstrating practical applicability with average response times of 127ms. Analysis of feature importance revealing linguistic indicators most predictive of phishing attempts, including discussion of dataset bias.
The remainder of this paper is organized as follows: Section II reviews related work in phishing detection. Section III describes our methodology, including data preprocessing and model training. Section IV presents experimental results and analysis. Section V discusses findings and limitations. Finally, Section VI concludes our paper findings. A substantial body of prior research has focused on detecting phishing through URL analysis. Sahingoz et al. [ 5 ] demonstrated effective machine learning-based phishing detection from URLs, achieving 97.98% accuracy using Random Forest on lexical and host-based features. Mendoza Vega et al. [ 6 ] developed PhishFind, a machine learning system employing Gradient Boosting for URL classification, achieving an F1-score of 97.34%. Mittal [ 7 ] compared Logistic Regression and Decision Tree models for URL classification, finding that Logistic Regression provided superior interpretability for explaining classification decisions. Blancaflor et al. [ 8 ] addressed homoglyph attacks in malicious URLs using AI-driven detection methods.
Deep learning approaches have also been explored for URL-based detection. Feng and Yue [ 9 ] employed recurrent neural networks (RNNs) for URL classification without explicit feature extraction, leveraging the sequential nature of URL characters. While these approaches demonstrate strong performance, they remain vulnerable to attacks utilizing compromised legitimate URLs.
Analyzing full email content has emerged as a complementary important approach to phishing detection. Salloum et al. [ 10 ] conducted a systematic literature review on phishing email detection using NLP techniques, identifying TF-IDF and word embeddings as the most frequently used feature extraction methods across 100 studies from 2006-2022. Bountakas et al. [ 11 ] conducted a comprehensive comparison of machine learning models, including Logistic Regression, Classification and Regression Trees (CART), Bayesian Additive Regression Trees (BART), Support Vector Machines (SVM), Random Forests, and Neural Networks, on a corpus of 2,889 emails. Their work established baseline performance metrics for content-based detection, with Random Forest achieving 94.1% accuracy.
Gualberto et al. [ 12 ] demonstrated that combining feature engineering with topic models significantly enhanced prediction rates in phishing detection, achieving improvements of up to 4.2% over baseline methods. More recently, Ling et al. [ 13 ] proposed the Meta GPT Framework, which analyzes email headers and bodies using thought-chain reasoning with the GLM-4 large language model. While demonstrating promising results, this approach faces limitations due to token-count restrictions that may truncate longer emails.
This paper extends the content-based detection paradigm by training on a substantially larger dataset of over 53,000 emails, approximately 18 times larger than that of Bountakas et al. [ 11 ] . This scale enabled more robust pattern learning while maintaining computational efficiency through classical machine learning techniques that are well-suited for real-time deployment.
Three publicly available datasets were combined to create a comprehensive training corpus: The aggregated corpus totals 53,973, of which 22,035 (40.8%) are legitimate, and 31,938 (59.2%) are phishing. Figure 1 illustrates the class distribution across the three datasets. The observed class imbalance reflects a realistic security-oriented data collection setting in which malicious samples are usually overrepresented to facilitate effective model training and evaluation processes.
Raw email content exhibits significant variance in formatting and content, including embedded HTML headers, metadata, URLs, and special characters. To reduce noise and normalize the textual input, a structured preprocessing pipeline was applied using the following sequential steps: Stop Word Removal : Common English stop words are filtered using NLTK’s predefined list.
Lemmatization : Words are reduced to their base forms using NLTK’s WordNetLemmatizer, applied sequentially for noun and verb parts of speech. This pipeline aims to preserve semantically meaningful information while reducing dimensionality and noise inherent in raw email data.
Term Frequency-Inverse Document Frequency (TF-IDF) vectorization, introduced by Spärck Jones [ 17 ] and further refined by Salton and Buckley [ 18 ] , transforms preprocessed text into numerical feature vectors. The TF-IDF weight for term t t in document d d within corpus D D is computed as: The resulting feature matrix exhibits 98.70% sparsity, characteristic of text classification tasks.
Two supervised machine learning classifiers were evaluated for phishing email detection. The Multinomial Na”ive Bayes classifier [ 19 ] applies Bayes’ theorem under the assumption of conditional independence among features. For a document d d represented by features x 1 , … , x n x_{1},\ldots,x_{n} , the posterior probability of class c c is given by: Despite its simplifying independence assumption, Multinomial Na”ive Bayes is computationally efficient and performs competitively on high-dimensional sparse text data.
Logistic Regression, originally developed by Cox [ 20 ] , models the probability of class membership using the logistic function: The model was trained with L2 regularization (default C=1.0 ), max_iter=1000 , and random_state=42 for reproducibility. Logistic Regression provides interpretable coefficients indicating feature importance for each class. The dataset was partitioned using stratified sampling with 80% for training (43,178 samples) and 20% for testing (10,795 samples). Stratification preserves the original class distribution in both sets: TF-IDF vectorization was fit exclusively on the training data and subsequently applied to both the training and testing sets, thereby preventing information leakage and ensuring an unbiased evaluation of model performance.
Table I presents the classification performance for the evaluated models on the held-out test set. Logistic Regression outperforms Naïve Bayes across all metrics, surpassing our target threshold of 95% accuracy. The improvement in precision (3.19 percentage points) indicates reduced false positive rates, which is critical for practical deployment where legitimate emails incorrectly flagged as phishing disrupt normal communications.
5. Performance Evaluation & Extended Technical Observations Figure. 2 provides a visual comparison of model performance across all evaluation metrics. Figure 3 presents the confusion matrices for both classifiers, enabling a detailed examination of classification errors. Logistic Regression demonstrates a 40.6% reduction in false positives (218 vs. 367) compared to Naïve Bayes, while maintaining comparable false negative rates (278 vs. 296). This balance is particularly valuable in enterprise deployments, where user trust in the detection system depends on minimizing interruptions caused by false alarms.
To improve model interpretability, the learned coefficients of the Logistic Regression classifier were analyzed to identify the most influential features for each class. Figure 4 visualizes the top features with the highest absolute coefficient magnitudes. Phishing-related features are strongly associated with urgency cues (e.g., “click”), incentives (“free”), and medical or financial spam patterns. Legitimate indicators include general workplace terminology (e.g., “meeting,” “schedule”) as well as corpus-specific terms originating from the Enron dataset, highlighting the presence of dataset bias, which is further discussed in Section V .
To evaluate generalization beyond the training data, three manually constructed email samples were tested: “URGENT! Your account has been suspended! We detected unusual activity on your account. Click here immediately to verify your identity: http://suspicious-link.com You have 24 hours or your account will be permanently deleted! Enter your password and credit card to verify.” Both models correctly classified this as phishing. Logistic Regression exhibited higher confidence (94.09%) compared to Naïve Bayes (81.37%).
“Hi Team, I wanted to follow up on our meeting yesterday regarding the Q4 project timeline. Please review the attached presentation and let me know if you have any questions. We’ll reconvene next Tuesday at 2pm to finalize the deliverables. Best regards, John Smith, Project Manager” Both models classified this as legitimate with high confidence (Naïve Bayes: 99.84%, Logistic Regression: 99.06%).
“Exclusive Offer Just For You! Get 50% off all products this weekend only! Don’t miss out on this amazing deal. Shop now and save big! Click here to see our latest collection. Offer expires in 48 hours!” Both models flagged this as phishing (Naïve Bayes: 92.81%, Logistic Regression: 90.25%). This false positive demonstrates model sensitivity to urgency language and promotional patterns that overlap with phishing tactics, which is a known limitation discussed in Section V.
The trained Logistic Regression model was deployed as a web-based phishing detection system comprising the following components: Backend : FastAPI service hosted on Render, exposing a prediction endpoint that applies identical preprocessing and TF-IDF transformation.
Frontend : HTML/TailwindCSS interface hosted on Vercel, providing real-time classification with confidence score visualization. The deployed system achieves an average response time of 127 ms for emails ranging from 50 to 500 words. Figure 5 shows the web-based user interface.
Logistic Regression’s superior performance can be attributed to several factors. First, the model captures correlations between features that Naïve Bayes’s independence assumption ignores. In phishing emails, certain term combinations (e.g., “click” + “verify” + “account”) provide stronger signals than individual terms. Second, L2 regularization prevents overfitting to the high-dimensional TF-IDF feature space (5,000 features).
A critical observation from our feature importance analysis is the presence of corpus-specific terms (“enron,” “vince,” “houston”) as strong legitimate indicators. These terms derive from the Enron email corpus included in Dataset 3, representing a potential source of overfitting to corpus characteristics rather than universal phishing patterns. Future deployments should consider domain-specific vocabulary filtering during preprocessing to improve generalization to other email domains.
The preprocessing pipeline significantly influences model performance. Our exploratory analysis revealed substantial vocabulary variance across datasets: These variations necessitated aggressive normalization to enable cross-dataset generalization. The misclassification of marketing emails represents a practical limitation. Marketing language often overlaps with phishing patterns, including urgency terms (“limited time,” “act now,” “expires”) and promotional offers. Potential mitigations include whitelist integration for known marketing domains or confidence threshold adjustments (e.g., flagging only predictions with > > 95% confidence).
Dataset Bias : Corpus-specific terms (e.g., Enron-related vocabulary) influence predictions, potentially limiting generalization to other email domains. Evolving Threats : The static model cannot adapt to emerging attack vectors without retraining, particularly LLM-generated phishing content.
Marketing Email Sensitivity : False positives on promotional content may require supplementary rules or user feedback mechanisms. No Header Analysis : Email headers (sender, routing information) are not currently analyzed, potentially missing important signals.
The proposed approach compares favorably with existing content-based phishing detection methods. Bountakas et al. [ 11 ] reported an accuracy of 94.1% using a Random Forest classifier on a dataset of 2,889 emails. In contrast, the Logistic Regression model presented in this work achieves 95.41% accuracy on a substantially larger corpus of 53,973 emails—approximately 18 times larger. This result demonstrates that classical machine learning techniques, when combined with effective feature engineering and sufficient training data, can scale effectively and remain competitive with more complex models. While direct comparisons are limited by differences in datasets and evaluation protocols, the results underscore the practicality and robustness of the proposed approach.
This paper presented a context-aware phishing email detection system based on classical machine learning and natural language processing. Using TF–IDF feature representations and Logistic Regression, the proposed approach achieved an accuracy of 95.41% on a large-scale corpus of 53,973 emails. Beyond quantitative performance, the system demonstrates practical viability through deployment as a web-based application with an average response time of 127 ms, while maintaining interpretability through feature coefficient analysis.
The results indicate that well-engineered, content-based machine learning models remain competitive, scalable, and suitable for real-time phishing detection, even when compared to more complex architectures. By focusing on contextual linguistic cues rather than URL structure alone, the proposed system effectively captures social engineering patterns commonly employed in phishing attacks.
Harvested Online Documentation & Reference Sources • https://arxiv.org/html/2509.20972v1 • https://github.com/3amberloaf/Phishing-Email-Detection-Using-Natural-Language-Processing-NLP- • https://github.com/Hemarshini/Phishing-Email-Detection-using-NLP-and-Machine-Learning • https://arxiv.org/html/2603.27326v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Phishing Email Detection Using Natural Language Processing.
[*] Synchronizing KnowBe4 Awareness Training telemetry... ──────────────────────────────────────────────────────────────────────── [11:45:02.102] MAIL Dispatched simulated assessment templates [11:45:02.155] REPORT Majority of active users flagged probe via Phish Alert Button [11:45:02.210] CLICK Simulated lure baseline reduced below risk threshold [11:45:02.290] TRAIN Auto-enrolled flagged users into adaptive micro-learning modules ──────────────────────────────────────────────────────────────────────── [✓] Human Security Index: Phish-Prone percentage safely minimized
| Campaign Simulation | Platform Used | Total Recipients | Reported via Phish Button | Phish-Prone Percentage |
|---|---|---|---|---|
| Urgent Communication Lure | KnowBe4 KMSAT | 350 Employees | 318 (90.8%) | 2.9% (OPTIMAL) |
| Account Credential Lure | Proofpoint ZenGuide | 350 Employees | 324 (92.5%) | 2.1% (OPTIMAL) |
| Executive Impersonation | Mimecast Engage | 200 Executives | 192 (96.0%) | 1.5% (OPTIMAL) |