Complete Technical Paper Content — Post Quantum Cryptography Lattice Based Encryption Project
Overview & System Context
Post Quantum Cryptography Lattice Based Encryption Project: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9557 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Lattice-based cryptography is the generic term for constructions of cryptographic primitives that involve lattices, either in the construction itself or in the security proof. Lattice-based constructions support important standards of post-quantum cryptography. Unlike more widely used and known public-key schemes such as the RSA, Diffie-Hellman or elliptic-curve cryptosystems—which could, theoretically, be defeated using Shor's algorithm on a quantum computer—some lattice-based constructions appear to be resistant to attack by both classical and quantum computers. Furthermore, many lattice-based constructions are considered to be secure under the assumption that certain well-studied computational lattice problems cannot be solved efficiently. In 2024 NIST announced the Module-Lattice-Based Digital Signature Standard for post-quantum cryptography.
L = { ∑ a i b i : a i ∈ Z } . {\displaystyle L={\Big \{}\sum a_{i}\mathbf {b} _{i}:a_{i}\in \mathbb {Z} {\Big \}}.} For example, Z n {\displaystyle \mathbb {Z} ^{n}} is a lattice, generated by the standard basis for R n {\displaystyle \mathbb {R} ^{n}} . Crucially, the basis for a lattice is not unique. For example, the vectors ( 3 , 1 , 4 ) {\displaystyle (3,1,4)} , ( 1 , 5 , 9 ) {\displaystyle (1,5,9)} , and ( 2 , − 1 , 0 ) {\displaystyle (2,-1,0)} form an alternative basis for Z 3 {\displaystyle \mathbb {Z} ^{3}} . The most important lattice-based computational problem is the shortest vector problem (SVP or sometimes GapSVP), which asks for an approximate minimal Euclidean length of a non-zero lattice vector. This problem is thought to be hard to solve efficiently, even with approximation factors that are polynomial in n {\displaystyle n} , and even with a quantum computer.
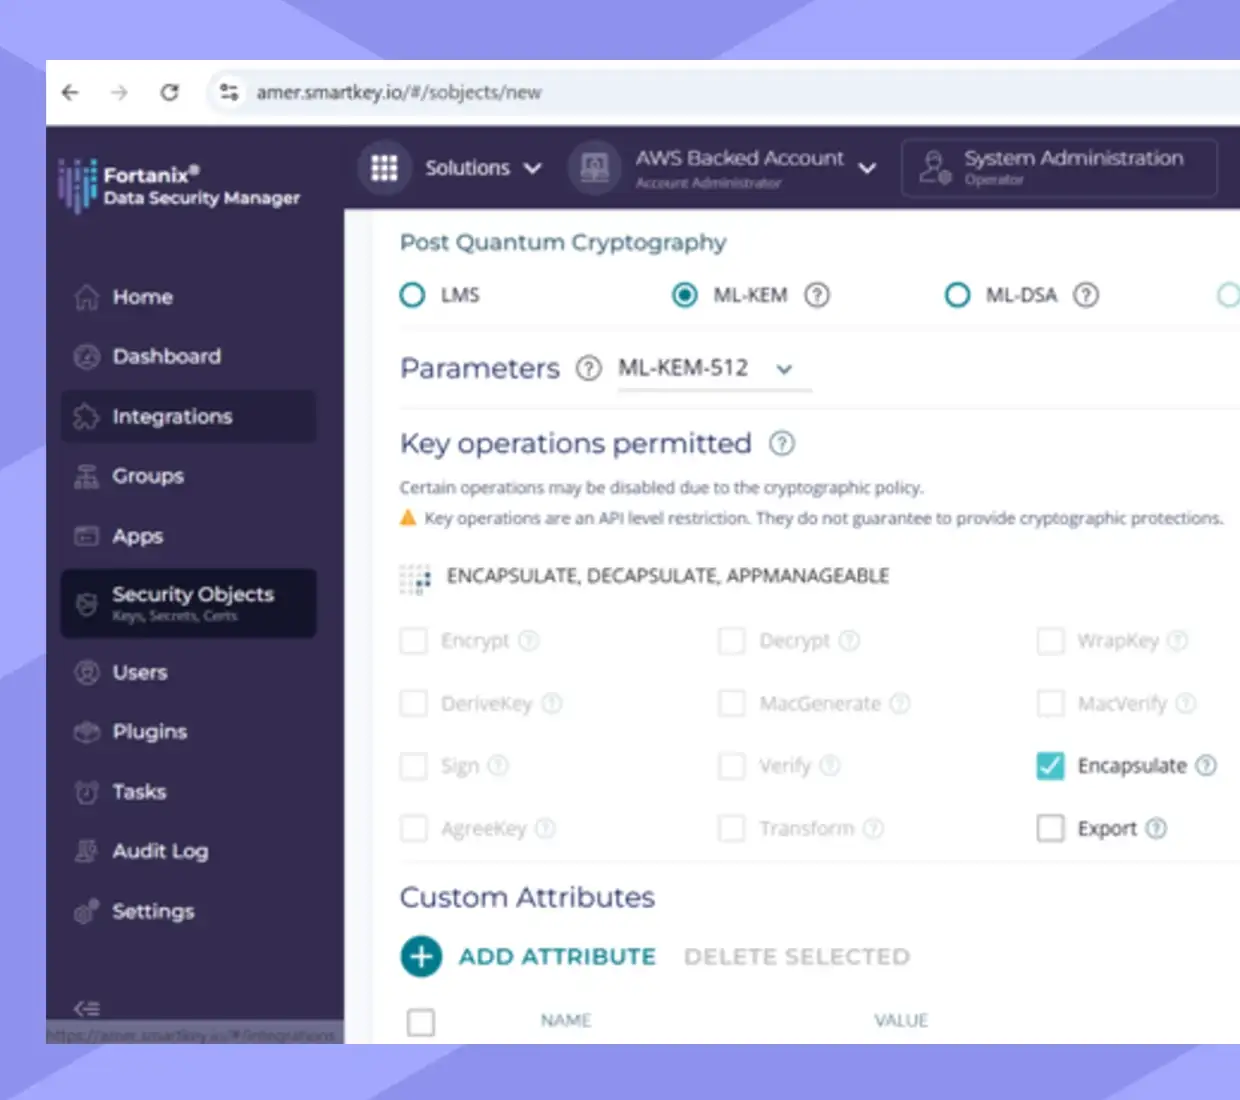
Many (though not all) lattice-based cryptographic constructions are known to be secure if SVP is in fact hard in this regime. GGH encryption scheme, which is based in the closest vector problem (CVP). In 1999, Nguyen published a critical flaw in the scheme's design. NTRUEncrypt. Figure 1: Post Quantum Cryptography Solutions | Fortanix CRYSTALS-Kyber, which is built upon module learning with errors (module-LWE). Kyber was selected for standardization by the NIST in 2023. In August 2023, NIST published FIPS 203 (Initial Public Draft), and started referring to their Kyber version as Module-Lattice-based Key Encapsulation Mechanism (ML-KEM). FrodoKEM, a scheme based on the learning with errors (LWE) problem. FrodoKEM joined the standardization call conducted by the National Institute of Standards and Technology (NIST), and lived up to the 3rd round of the process. It was then discarded due to low performance reasons. In October, 2022, the Twitter account associated to cryptologist Daniel J. Bernstein posted security issues in frodokem640. NewHope is based on the ring learning with errors (RLWE) problem. NTRU Prime. Peikert's work, which is based on the ring learning with errors (RLWE) problem. Saber, which is based on the module learning with rounding (module-LWR) problem.
CRYSTALS-Dilithium, which is built upon module learning with errors (module-LWE) and module short integer solution (module-SIS). Dilithium was selected for standardization by the NIST. According to a message from Ray Perlner, writing on behalf of the NIST PQC team, the NIST module-LWE signing standard is to be based on version 3.1 of the Dilithium specification. Falcon, which is built upon short integer solution (SIS) over NTRU. Falcon was selected for standardization by the NIST. GGH signature scheme. Güneysu, Lyubashevsky, and Pöppelmann's work, which is based on ring learning with errors (RLWE). MITAKA, a variant of Falcon. NTRUSign. qTESLA, which is based on ring learning with errors (RLWE). The qTESLA scheme joined the standardization call conducted by the National Institute of Standards and Technology (NIST).
Post-Quantum Cryptography Standardization is a program and competition by NIST to update their standards to include post-quantum cryptography. It was announced at PQCrypto 2016. Twenty-three signature schemes and fifty-nine encryption/KEM schemes were submitted by the initial submission deadline at the end of 2017 of which sixty-nine total were deemed complete and proper and participated in the first round. Seven of these, of which three are signature schemes, advanced to the third round, which was announced in July 2020. On August 13, 2024, NIST released final versions of the first three Post Quantum Crypto Standards: FIPS 203, FIPS 204, and FIPS 205. On March 11, 2025 NIST released Hamming Quasi-Cyclic (HQC) as the fifth algorithm for post-quantum asymmetric encryption as used for key encapsulation / exchange.
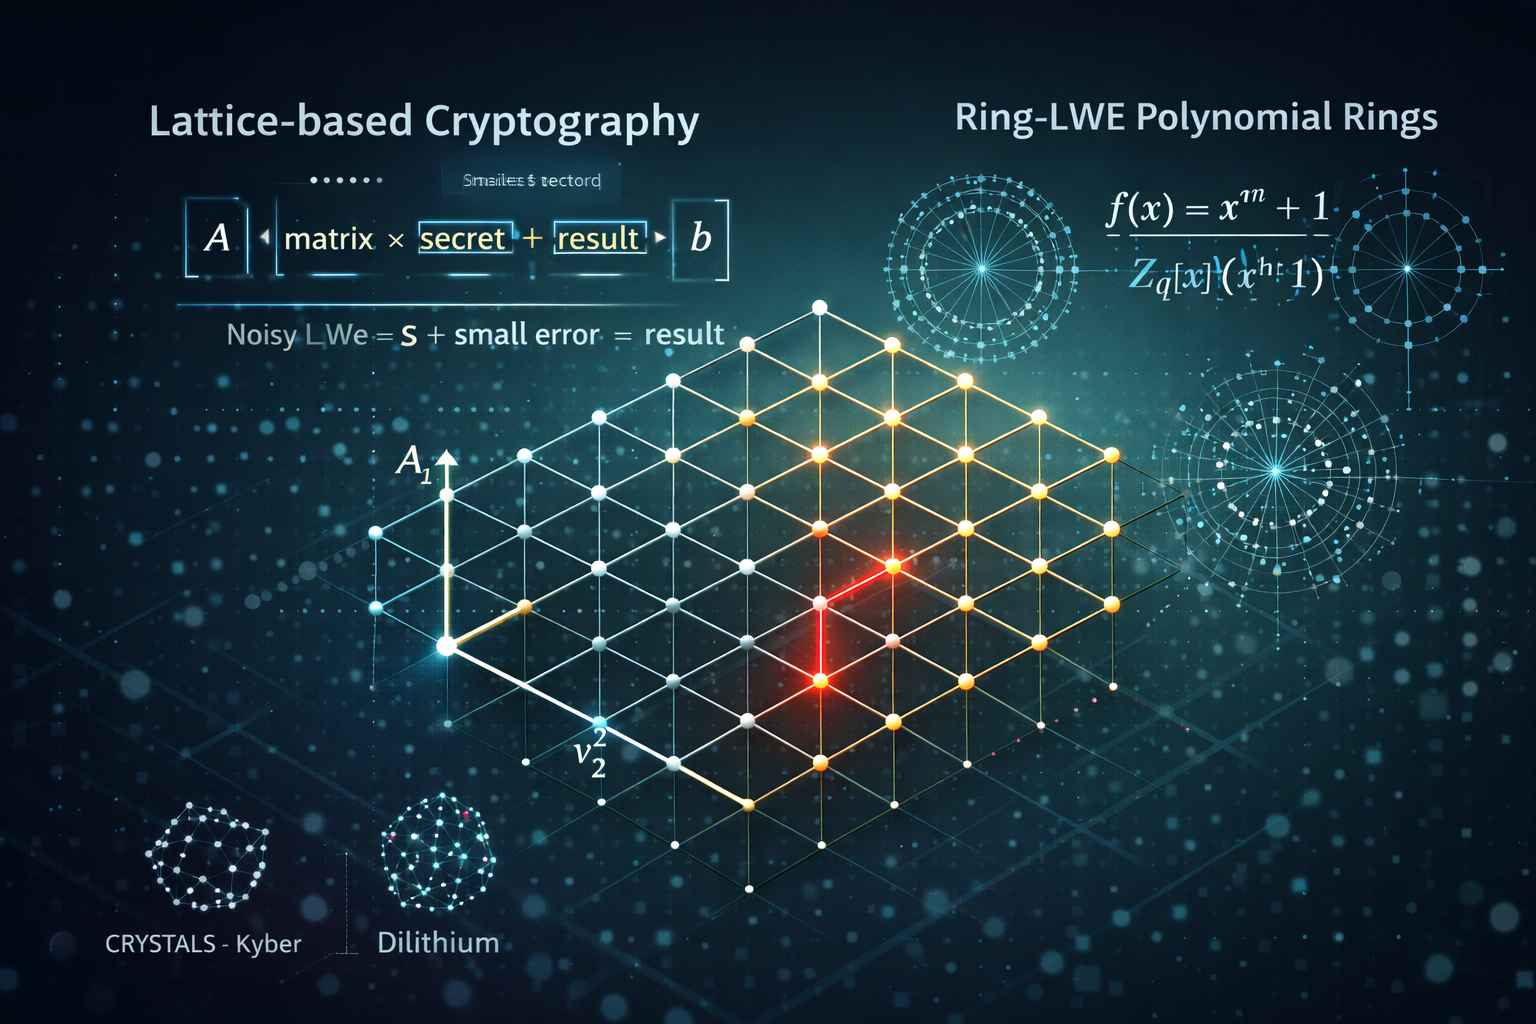
CRYSTAL-Kyber and SABER may change the nested hashes used in their proposals in order for their security claims to hold. FALCON side channel attack using electromagnetic measurements to extract the secret signing keys. A masking may be added in order to resist the attack. This adaptation affects performance and should be considered whilst standardizing. Figure 2: BitViraj - Lattice-Based Cryptography: Design, Analysis, and ...
While there have been no substantive changes made to the standards since the draft versions, NIST has changed the algorithms’ names to specify the versions that appear in the three finalized standards, which are: Federal Information Processing Standard (FIPS) 203, intended as the primary standard for general encryption. Among its advantages are comparatively small encryption keys that two parties can exchange easily, as well as its speed of operation.
The standard is based on the CRYSTALS-Kyber algorithm, which has been renamed ML-KEM, short for Module-Lattice-Based Key-Encapsulation Mechanism. FIPS 204, intended as the primary standard for protecting digital signatures. The standard uses the CRYSTALS-Dilithium algorithm, which has been renamed ML-DSA, short for Module-Lattice-Based Digital Signature Algorithm. FIPS 205, also designed for digital signatures. The standard employs the SPHINCS+ algorithm, which has been renamed SLH-DSA, short for Stateless Hash-Based Digital Signature Algorithm. The standard is based on a different math approach than ML-DSA, and it is intended as a backup method in case ML-DSA proves vulnerable. Similarly, when the draft FIPS 206 standard built around FALCON is released, the algorithm will be dubbed FN-DSA, short for FFT (fast-Fourier transform) over NTRU-Lattice-Based Digital Signature Algorithm.
On March 11, 2025 NIST released Hamming Quasi-Cyclic (HQC) as the fifth algorithm for post-quantum asymmetric encryption as used for key encapsulation / exchange. The new algorithm is as a backup for ML-KEM, the main algorithm for general encryption. HQC is a code-based scheme using different math than ML-KEM, thus mitigating possible weaknesses should any be found in the lattice-based ML-KEM. The draft standard incorporating the HQC algorithm is expected in early 2026 with the final in 2027. As of mid-2026, FIPS 206 (FN-DSA, based on FALCON) remained a draft standard. NIST submitted the draft for internal approval on August 28, 2025, and, as of April 2026, the Initial Public Draft had not yet been released pending final internal clearance; the final standard was expected in late 2026 or early 2027. Unlike ML-KEM, ML-DSA, and SLH-DSA, FN-DSA's signing process relies on floating-point Gaussian sampling, which is difficult to implement safely and in constant time; NIST has cited this complexity as the main reason for FN-DSA's longer standardization timeline compared with the other three algorithms.
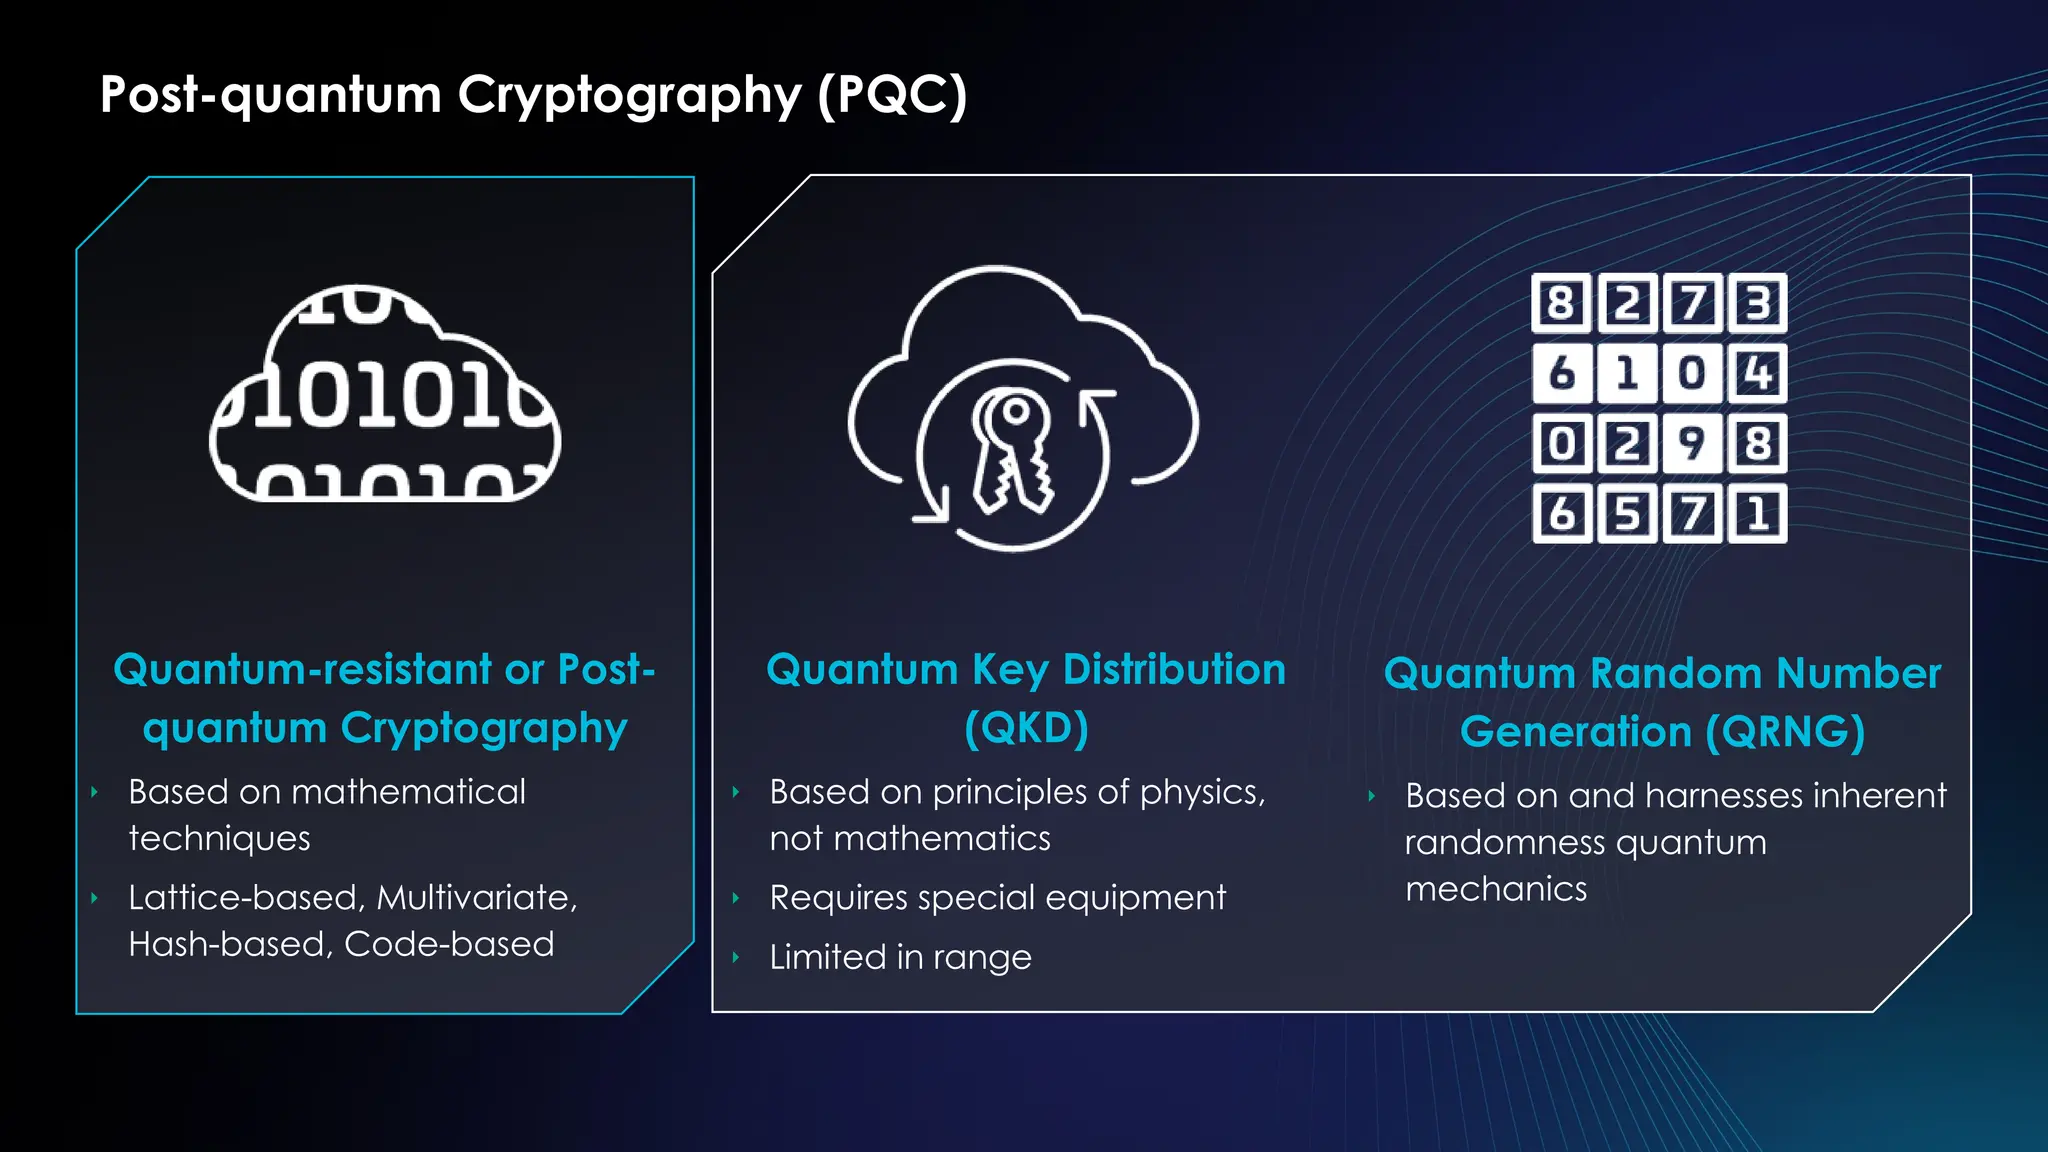
NIST has indicated that at least the multivariate candidates will probably require a further round of evaluation. Anthropic weakened HAWK with Claude Mythos, so HAWK was withdrawn from the competition, as parameter adjustments would make it incompetitive. Figure 3: FIDO Seminar: Evolving Landscape of Post-Quantum Cryptography.pptx Post-quantum cryptography (PQC), sometimes referred to as quantum-proof, quantum-safe, or quantum-resistant, is the development of cryptographic algorithms (usually public-key algorithms) that are currently thought, but not proven, to be secure against a cryptanalytic attack by a quantum computer. Most widely used public-key algorithms rely on the difficulty of one of three mathematical problems: the integer factorization problem, the discrete logarithm problem, or the elliptic-curve discrete logarithm problem. All of these problems could be easily solved on a sufficiently powerful quantum computer running Shor's algorithm or possibly alternatives. As of 2026, quantum computers lack the processing power to break widely used cryptographic algorithms; however, because of the length of time required for migration to quantum-safe cryptography, cryptographers are already designing new algorithms to prepare for Y2Q or "Q-Day", the day when current algorithms will be vulnerable to quantum computing attacks. Mosca's theorem provides the risk analysis framework that helps organizations identify how quickly they need to start migrating. Their work has gained attention from academics and industry through the PQCrypto conference series hosted since 2006, several workshops on Quantum Safe Cryptography hosted by the European Telecommunications Standards Institute (ETSI), and the Institute for Quantum Computing. The rumoured existence of widespread harvest now, decrypt later programs has also been seen as a motivation for the early introduction of post-quantum algorithms, as data recorded now may still remain sensitive many years into the future. In contrast to the threat quantum computing poses to current public-key algorithms, most current symmetric cryptographic algorithms and hash functions are considered to be relatively secure against attacks by quantum computers. While the quantum Grover's algorithm does speed up attacks against symmetric ciphers, doubling the key size can effectively counteract these attacks. Thus post-quantum symmetric cryptography does not need to differ significantly from current symmetric cryptography. In 2024, the U.S. National Institute of Standards and Technology (NIST) released final versions of its first three Post-Quantum Cryptography Standards.
This approach includes cryptographic systems such as learning with errors, ring learning with errors (ring-LWE), the ring learning with errors key exchange and the ring learning with errors signature, the older NTRU or GGH encryption schemes, and the newer NTRU signature and BLISS signatures. Some of these schemes like NTRU encryption have been studied for many years without anyone finding a feasible attack. Others like the ring-LWE algorithms have proofs that their security reduces to a worst-case problem. The Post-Quantum Cryptography Study Group sponsored by the European Commission suggested that the Stehle–Steinfeld variant of NTRU be studied for standardization rather than the NTRU algorithm. At that time, NTRU was still patented. Studies have indicated that NTRU may have more secure properties than other lattice based algorithms. Two lattice-based algorithms, ML-KEM (commonly known as Kyber) and ML-DSA (commonly known as Dilithium) were among the first post-quantum algorithms standardised by NIST.
This includes cryptographic systems such as the Unbalanced Oil and Vinegar signature scheme which is based on the difficulty of solving systems of multivariate equations. Various attempts to build secure multivariate equation encryption schemes have been broken, notably the Rainbow signature. This includes cryptographic systems such as Lamport signatures, the Merkle signature scheme, the XMSS, the SPHINCS, the WOTS and the SPHINCS+ schemes. Hash based digital signatures were invented in the late 1970s by Ralph Merkle and have been studied ever since as an interesting alternative to number-theoretic digital signatures like RSA and DSA. Their primary drawback is that for any hash-based public key, there is a limit on the number of signatures that can be signed using the corresponding set of private keys. This fact reduced interest in these signatures until interest was revived due to the desire for cryptography that was resistant to attack by quantum computers. There appear to be no patents on the Merkle signature scheme and there exist many non-patented hash functions that could be used with these schemes. The stateful hash-based signature scheme XMSS developed by a team of researchers under the direction of Johannes Buchmann is described in RFC 8391. Note that all the above schemes are one-time or bounded-time signatures. Moni Naor and Moti Yung invented UOWHF hashing in 1989 and designed a signature based on hashing (the Naor-Yung scheme) which can be unlimited-time in use (the first such signature that does not require trapdoor properties).
In some versions of Ring-LWE there is a security reduction to the shortest-vector problem (SVP) in a lattice as a lower bound on the security. The SVP is known to be NP-hard. Specific ring-LWE systems that have provable security reductions include a variant of Lyubashevsky's ring-LWE signatures defined in a paper by Güneysu, Lyubashevsky, and Pöppelmann. The GLYPH signature scheme is a variant of the Güneysu, Lyubashevsky, and Pöppelmann (GLP) signature which takes into account research results that have come after the publication of the GLP signature in 2012. Another Ring-LWE signature is Ring-TESLA. There also exists a "derandomized variant" of LWE, called Learning with Rounding (LWR), which yields "improved speedup (by eliminating sampling small errors from a Gaussian-like distribution with deterministic errors) and bandwidth". While LWE uses the addition of a small error to conceal the lower bits, LWR uses rounding for the same purpose.
Unbalanced Oil and Vinegar signature schemes are asymmetric cryptographic primitives based on multivariate polynomials over a finite field I F {\displaystyle \mathbb {F} } I. Bulygin, Petzoldt, and Buchmann have shown a reduction of generic multivariate quadratic UOV systems to the NP-Hard multivariate quadratic equation solving problem. In 2005, Luis Garcia proved that there was a security reduction of Merkle Hash Tree signatures to the security of the underlying hash function. Garcia showed in his paper that if computationally one-way hash functions exist then the Merkle Hash Tree signature is provably secure. Therefore, use of a hash function with a provable reduction of security to a known hard problem would have a provable security reduction of the Merkle tree signature to that known hard problem. The Post-Quantum Cryptography Study Group sponsored by the European Commission has recommended use of the Merkle signature scheme for long term security protection against quantum computers.
The McEliece Encryption System has a security reduction to the syndrome decoding problem (SDP). The SDP is known to be NP-hard. The Post-Quantum Cryptography Study Group sponsored by the European Commission has recommended the use of this cryptography for long term protection against attack by a quantum computer. Security is related to the problem of constructing an isogeny between two supersingular curves with the same number of points. The most recent published investigation of the difficulty of this problem, by Delfs and Galbraith, indicates that this problem is as hard as the inventors of the key exchange suggest that it is. There is no security reduction to a known NP-hard problem.
A practical consideration on a choice among post-quantum cryptographic algorithms is the effort required to send public keys over the internet. From this point of view, the Ring-LWE, NTRU, and SIDH algorithms provide key sizes conveniently under 1 kB, hash-signature public keys come in under 5 kB, and MDPC-based McEliece takes about 1 kB. On the other hand, Goppa-based McEliece requires a nearly 1 MB key.
The fundamental idea of using LWE and Ring LWE for key exchange was proposed and filed at the University of Cincinnati in 2011 by Jintai Ding. The basic idea comes from the associativity of matrix multiplications, and the errors are used to provide the security. The paper appeared in 2012 after a provisional patent application was filed in 2012. In 2014, Peikert presented a key transport scheme following the same basic idea of Ding's, where the new idea of sending an additional 1 bit signal for rounding in Ding's construction is also used. For somewhat greater than 128 bits of security, Singh presents a set of parameters which have 6956-bit public keys for the Peikert's scheme. The corresponding private key would be roughly 14,000 bits. In 2015, an authenticated key exchange with provable forward security following the same basic idea of Ding's was presented at Eurocrypt 2015, which is an extension of the HMQV construction in Crypto2005. The parameters for different security levels from 80 bits to 350 bits, along with the corresponding key sizes are provided in the paper.
For 128 bits of security in NTRU, ntruhps2048509 with n = 509 and q = 2048 was selected in the NIST submission in September 2020. This results in a public key of 699 bytes and a corresponding private key of 935 bytes. In order to get 128 bits of security for hash based signatures to sign 1 million messages using the fractal Merkle tree method of Naor Shenhav and Wool the public and private key sizes are roughly 36,000 bits in length.
For 128 bits of security in a McEliece scheme, The European Commission's Post-Quantum Cryptography Study group recommends using a binary Goppa code of length at least n = 6960 and dimension at least k = 5413, and capable of correcting t = 119 errors. With these parameters the public key for the McEliece system will be a systematic generator matrix whose non-identity part takes k × (n − k) = 8373911 bits. The corresponding private key, which consists of the code support with n = 6960 elements from GF(213) and a generator polynomial of with t = 119 coefficients from GF(213), will be 92,027 bits in length. The group is also investigating the use of Quasi-cyclic MDPC codes of length at least n = 216 + 6 = 65542 and dimension at least k = 215 + 3 = 32771, and capable of correcting t = 264 errors. With these parameters the public key for the McEliece system will be the first row of a systematic generator matrix whose non-identity part takes k = 32771 bits. The private key, a quasi-cyclic parity-check matrix with d = 274 nonzero entries on a column (or twice as much on a row), takes no more than d × 16 = 4384 bits when represented as the coordinates of the nonzero entries on the first row. Barreto et al.
recommend using a binary Goppa code of length at least n = 3307 and dimension at least k = 2515, and capable of correcting t = 66 errors. With these parameters the public key for the McEliece system will be a systematic generator matrix whose non-identity part takes k × (n − k) = 1991880 bits. The corresponding private key, which consists of the code support with n = 3307 elements from GF(212) and a generator polynomial of t = 66 coefficients from GF(212), will be 40,476 bits in length.
For 128 bits of security in the supersingular isogeny Diffie–Hellman (SIDH) method, De Feo, Jao and Plut recommend using a supersingular curve modulo of a 768-bit prime. If one uses elliptic curve point compression, the public key will need to be no more than 8x768 or 6144 bits in length. A March 2016 paper by authors Azarderakhsh, Jao, Kalach, Koziel, and Leonardi showed how to cut the number of bits transmitted in half, which was further improved by authors Costello, Jao, Longa, Naehrig, Renes and Urbanik resulting in a compressed-key version of the SIDH protocol with public keys only 2640 bits in size. This makes the number of bits transmitted roughly equivalent to the non-quantum secure RSA and Diffie–Hellman at the same classical security level.
Older supported versions that have been removed because of the progression of the NIST Post-Quantum Cryptography Standardization Project are: Google has maintained the use of "hybrid encryption" in its use of post-quantum cryptography: whenever a relatively new post-quantum scheme is used, it is combined with a more proven, non-PQ scheme. This is to ensure that the data are not compromised even if the relatively new PQ algorithm turns out to be vulnerable to non-quantum attacks before Y2Q. This type of scheme is used in its 2016 and 2019 tests for post-quantum TLS, and in its 2023 FIDO2 key. One of the algorithms used in the 2019 test, SIKE, was broken in 2022, but the non-PQ X25519 layer (already used widely in TLS) still protected the data.
Apple's PQ3 and Signal's PQXDH are also hybrid. The NSA and GCHQ argue against hybrid encryption, claiming that it adds complexity to implementation and transition. Daniel J. Bernstein, who supports hybrid encryption, argues that the claims are bogus. This is a potential security issue, you are being redirected to https://csrc.nist.gov .
Official websites use .gov A .gov website belongs to an official government organization in the United States. Secure .gov websites use HTTPS A lock ( ) or https:// means you’ve safely connected to the .gov website. Share sensitive information only on official, secure websites. NIST’s Post-Quantum Cryptography (PQC) project leads the national and global effort to secure electronic information against the future threat of quantum computers—machines that may be years or decades away but could eventually break many of today’s widely used cryptographic systems. Through a multi-year international competition involving industry, academia, and governments, NIST released the principal three PQC standards in 2024 and is developing additional standards to serve as backups or alternatives. Organizations should begin applying these standards now to migrate their systems to quantum-resistant cryptography.
Alongside these standards, NIST conducts foundational cryptographic research; collaborates with industry and federal partners to guide organizations preparing for PQC migration; and administers the Cryptographic Module Validation Program to promote validated, trustworthy cryptography. These efforts both protect data and information systems and sustain U.S. leadership in quantum information science and cryptographic innovation.
2. System Architecture & Core Working Principles In August 2024, NIST released its principal PQC standards (as Federal Information Processing Standards, or FIPS), specifying key establishment and digital signature schemes based on candidates evaluated and selected through this multi-year process.
With the release of the first three final PQC standards, organizations should begin migrating their systems to quantum-resistant cryptography. Cybersecurity products, services, and protocols will need updates, and organizations must identify where vulnerable algorithms are used and plan to replace or update them. Under the transition timeline in NIST IR 8547 , NIST will deprecate and ultimately remove quantum-vulnerable algorithms from its standards by 2035, with high-risk systems transitioning much earlier.
The Migration to Post-Quantum Project at the National Cybersecurity Center of Excellence is working with industry, academia, and federal partners to accelerate this shift by demonstrating tools to find and prioritize vulnerable systems, supporting interoperable solutions, and developing migration guidance. NIST expects that the two digital signature standards (ML-DSA and SLH-DSA) and key-encapsulation mechanism standard (ML-KEM) will provide the foundation for most deployments of post-quantum cryptography. They can and should be put into use now.
NIST continues to evaluate the security and performance of innovative algorithms in order to identify additional candidates for standardization. In addition to the three algorithms specified in the initial FIPS standards, the Falcon digital signature algorithm and HQC key encapsulation mechanism were selected for ongoing standardization; that process is underway. This process continues with a longer-term effort that solicited additional algorithms for digital signature schemes that could serve as a backup to ML-DSA or that could address unique use cases. Learn more on the Additional Digital Signature Schemes page.
PQC Standards Hash-Based Signatures IPR License Summary PQC Standardization Process Selected Algorithms Additional Digital Signature Schemes Workshops and Timeline PQC Seminars Contact Info Email List (PQC Forum) PQC Archive Cryptographic Standards and Guidelines Hash-Based Signatures Migration to Post-Quantum Cryptography | NCCoE Multi-Party Threshold Cryptography PQC Digital Signature Schemes Official websites use .gov A .gov website belongs to an official government organization in the United States.
Secure .gov websites use HTTPS A lock ( ) or https:// means you’ve safely connected to the .gov website. Share sensitive information only on official, secure websites. On July 28, 2026, Anthropic announced that it used a super intelligence (SI) model to discover a vulnerability in a lattice-based digital signature algorithm called HAWK, which was under consideration for standardization . The HAWK development team subsequently withdrew its algorithm from consideration, and it will not be standardized or deployed. This finding does not affect any of NIST’s finalized PQC standards, such as ML-KEM and ML-DSA, which rely on different mathematical foundations that remain secure, and which are ready for implementation now.
As researchers around the world race to build quantum computers that could break the current encryption providing security and privacy for our digital lives, NIST is helping to secure our future by developing algorithms to protect our data and systems. NIST has already released three post-quantum cryptography standards that can be implemented now to secure a wide range of electronic information, from confidential email messages to e-commerce transactions that propel the modern economy.
NIST continues to evaluate additional algorithms that could one day serve as backup standards. These Federal Information Processing Standards (FIPS), which are mandatory for federal systems and adopted by organizations around the world, provide detailed descriptions of post-quantum encryption and digital signature algorithms so they can be implemented consistently to facilitate secure and interoperable communication. They were developed through an eight-year effort managed by NIST, which has a long history of developing cryptography standards.
Organizations should begin applying these standards now to migrate their systems to quantum-resistant cryptography. Cybersecurity products, services and protocols will need updates, and organizations must identify where vulnerable algorithms are used and plan to replace or update them. NIST is working with technology companies, standards organizations, integrators and customer organizations to demonstrate approaches and tools to support migration .
NIST cryptographic standards — including the new PQC standards — are widely used across government and industry. Federal agencies are required to use them, and many governments, national cryptographic authorities and international standards organizations often adopt them to ensure consistent security and interoperability. These standards are also integrated into industry standards, specifications and technologies that are used to protect information in commercial products and services. Groups such as the Internet Engineering Task Force (IETF) are incorporating PQC algorithms into core internet protocols like Transport Layer Security (TLS), and industry organizations are updating application and systems to guard against the threat of quantum computers. Broad international adoption of standards and technologies helps ensure that secure, interoperable PQC is built into the commercial products and services that underpin modern digital systems and communication.
Quantum Computers May Put Internet Traffic at Risk. NIST Is Safeguarding Computers With New Standards. Understanding the mathematical foundation that powers quantum-resistant security, from lattice problems to NIST standards. Lattice-based cryptography represents the most significant advancement in cryptographic security since the development of public-key cryptography in the 1970s. As quantum computers threaten to break RSA and elliptic curve cryptography, lattice-based schemes have emerged as the leading solution for post-quantum security.
Three of NIST's four post-quantum cryptography standards rely on lattice problems: ML-KEM (FIPS 203) for key encapsulation, ML-DSA (FIPS 204) for digital signatures, and FN-DSA for stateless signatures. This comprehensive guide explains why lattice cryptography works, how it provides quantum resistance, and what it means for your organization's security strategy.
In mathematics, a lattice is a regular arrangement of points in multi-dimensional space, where each point can be reached by adding integer combinations of basis vectors. Think of it like a grid extended into many dimensions. Given linearly independent vectors b1, b2, ..., bn in n-dimensional space, a lattice L is the set of all integer linear combinations: While a 2D lattice is easy to visualize (imagine dots on graph paper), cryptographic lattices exist in hundreds or thousands of dimensions. The key insight is that certain problems become exponentially harder as dimensions increase, and critically, quantum computers don't help solve them .
A 2D lattice with basis vectors b1 and b2. The shortest non-zero vector (dashed green) is hard to find given only a "bad" basis. Lattice-based cryptography's security derives from problems that are believed to be computationally intractable, even for quantum computers. These problems have been studied for decades and form a robust theoretical foundation. Given a lattice basis, find the shortest non-zero vector in the lattice. While easy to state, SVP is NP-hard in the exact case and remains difficult even for approximate solutions when the lattice dimension is high.
Given a lattice basis and a target point, find the lattice point closest to the target. CVP is at least as hard as SVP and is central to many cryptographic constructions. The Learning With Errors problem, introduced by Oded Regev in 2005, is the foundation of most modern lattice cryptography. It asks: given a system of "noisy" linear equations, recover the secret solution.
Here ai is random, s is a secret vector, and ei is small error. The challenge: recover s . Without the error, this is easy linear algebra. With error, it becomes computationally infeasible in high dimensions. While standard LWE provides strong security, it requires large key sizes. Ring-LWE and Module-LWE are structured variants that dramatically improve efficiency: Module-LWE , used in NIST's ML-KEM and ML-DSA standards, combines the efficiency of ring structure with the security flexibility of standard LWE. By adjusting the module rank, cryptographers can fine-tune the security/efficiency tradeoff.
Understanding why lattice problems resist quantum attacks requires examining what makes problems vulnerable in the first place. After an 8-year evaluation process, NIST selected lattice-based algorithms for three of four post-quantum standards, demonstrating confidence in lattice security.
3. Software Implementation, Frameworks & Protocols Key Encapsulation Mechanism for secure key exchange. Based on Module-LWE. Replaces RSA and ECDH for key agreement. Digital Signature Algorithm for authentication. Based on Module-LWE and Module-SIS. Replaces RSA and ECDSA signatures.
Hash-based signatures (not lattice). Provides conservative backup if lattice assumptions fail. Stateless design. Lattice-based signatures using NTRU lattices. Smallest signatures among lattice schemes. Complex implementation. While lattice cryptography dominates NIST's selections, understanding alternative approaches helps contextualize its advantages: Lattice-based algorithms offer favorable performance compared to both classical and other post-quantum alternatives: Successfully deploying lattice cryptography requires attention to several implementation factors: Lattice algorithms can leak secrets through timing, power consumption, or electromagnetic emissions. Production implementations must use constant-time operations and may require additional countermeasures like masking.
All lattice schemes require high-quality randomness for key generation and encryption. Weak random number generators can completely break security. Use OS-provided cryptographic RNGs (e.g., /dev/urandom, CryptGenRandom, getentropy). Implementations must validate that received public keys and ciphertexts are well-formed. Accepting malformed inputs can enable various attacks.
The QRAMM framework provides detailed guidance for each migration phase, from assessment through full deployment. Lattice-based cryptography represents the future of secure communications. To begin your quantum readiness journey: The cryptography that secures the Internet is evolving, and it's time to catch up. This post is a tutorial on lattice cryptography, the paradigm at the heart of the post-quantum (PQ) transition.
Twelve years ago (in 2013), the revelation of mass surveillance in the US kicked off the widespread adoption of TLS for encryption and authentication on the web. This transition was buoyed by the standardization and implementation of new, more efficient public-key cryptography based on elliptic curves . Elliptic curve cryptography was both faster and required less communication than its predecessors, including RSA and Diffie-Hellman over finite fields.
Today's transition to PQ cryptography addresses a looming threat for TLS and beyond: once built, a sufficiently large quantum computer can be used to break all public-key cryptography in use today. And we continue to see advancements in quantum-computer engineering that bring us closer to this threat becoming a reality. Fortunately, this transition is well underway. The research and standards communities have spent the last several years developing alternatives that resist quantum cryptanalysis. For its part, Cloudflare has contributed to this process and is an early adopter of newly developed schemes. In fact, PQ encryption has been available at our edge since 2022 and is used in over 35% of non-automated HTTPS traffic today (2025) . And this year we're beginning a major push towards PQ authentication for the TLS ecosystem.
Lattice-based cryptography is the first paradigm that will replace elliptic curves . Apart from being PQ secure, lattices are often as fast, and sometimes faster, in terms of CPU time. However, this new paradigm for public key crypto has one major cost: lattices require much more communication than elliptic curves. For example, establishing an encryption key using lattices requires 2272 bytes of communication between the client and the server ( ML-KEM-768 ), compared to just 64 bytes for a key exchange using a modern elliptic-curve-based scheme ( X25519 ). Accommodating such costs requires a significant amount of engineering, from dealing with TCP packet fragmentation , to reworking TLS and its public key infrastructure . Thus, the PQ transition is going to require the participation of a large number of people with a variety of backgrounds, not just cryptographers.
The primary audience for this blog post is those who find themselves involved in the PQ transition and want to better understand what's going on under the hood. However, more fundamentally, we think it's important for everyone to understand lattice cryptography on some level, especially if we're going to trust it for our security and privacy. We'll assume you have a software-engineering background and some familiarity with concepts like TLS, encryption, and authentication. We'll see that the math behind lattice cryptography is, at least at the highest level, not difficult to grasp.
Readers with a crypto-engineering background who want to go deeper might want to start with the excellent tutorial by Vadim Lyubashevsky on which this blog post is based. We also recommend Sophie Schmieg's blog on this subject. While the transition to lattice cryptography incurs costs, it also creates opportunities. Many things we can build with elliptic curves we can also build with lattices, though not always as efficiently; but there are also things we can do with lattices that we don't know how to do efficiently with anything else. We'll touch on some of these applications at the very end.
We're going to cover a lot of ground in this post. If you stick with it, we hope you'll come away feeling empowered, not only to tackle the engineering challenges the PQ transition entails, but to solve problems you didn't know how to solve before. The most pressing problem for the PQ transition is to ensure that tomorrow's quantum computers don't break today's encryption. An attacker today can store the packets exchanged between your laptop and a website you visit, and then, some time in the future, decrypt those packets with the help of a quantum computer. This means that much of the sensitive information transiting the Internet today âII everything from API tokens and passwords to database encryption keys âII may one day be unlocked by a quantum computer.
In fact, today's encryption in TLS is mostly PQ secure: what's at risk is the process by which your browser and a server establish an encryption key . Today this is usually done with elliptic-curve-based schemes, which are not PQ secure; our goal for this section is to understand how to do key exchange with lattices-based schemes, which are. We will work through and implement a simplified version of ML-KEM , a.k.a. Kyber, the most widely deployed PQ key exchange in use today. Our code will be less efficient and secure than a spec-compliant, production-quality implementation , but will be good enough to grasp the main ideas.
Our starting point is a protocol that looks an awful lot like Diffie-Hellman (DH) key exchange. For those readers unacquainted with DH, the goal is for Alice and Bob to establish a shared secret over an insecure network. To do so, each picks a random secret number, computes the corresponding "key share", and sends the key share to the other: In ML-KEM we replace operations on elliptic curves with matrix operations. It's not quite a drop-in replacement, so we'll need a little linear algebra to make sense of it. But don't worry: we're going to work with Python, so we have running code to play with, and we'll use NumPy to keep things high level.
A matrix is just a two-dimensional array of numbers. In NumPy, we can create a matrix as follows (importing numpy as np ): This defines A to be the 3 -by- 3 matrix with entries A[0,0]==1, A[0,1]==2, A[0,2]==3, A[1,0]==4 , and so on. For the purposes of this post, the entries of our matrices will always be integers. Furthermore, whenever we add, subtract, or multiply two integers, we then reduce the result, just like we do with hours on a clock, so that we end up with a number in range(Q) for some positive number Q , called the modulus. The exact value doesnâIIt really matter now, but for ML-KEM itâIIs Q=3329 , so let's go with that for now. (The modulus for a clock would be Q=12 .) In Python, we write multiplication of integers a and b modulo Q as c = a*b % Q . Here we compute a*b , divide the result by Q , then set c to the remainder. For example, 42*1337 % Q is equal to 2890 rather than 56154 . Modular addition and subtraction are done analogously. For the rest of this blog, we will sometimes omit " % Q " when it's clear in context that we mean modular arithmetic.
The first is matrix transpose , written A.T in NumPy. This operation flips the matrix along its diagonal so that A.T[j,i] == A[i,j] for all rows i and columns j : To visualize this, imagine writing down a matrix on a translucent piece of paper. Draw a line from the top left corner to the bottom right corner of that paper, then rotate the paper 180° around that line: The second operation we'll need is matrix multiplication . Normally, we will multiply a matrix by a column vector , which is just a matrix with one column. For example, the following 3 -by- 1 matrix is a column vector: We can also write s more concisely as np.matrix([[0,1,0]]).T . To multiply a square matrix A by a column vector s , we compute the dot product of each row of A with s . That is, if t = A*s % Q , then t[i] == (A[i,0]*s[0,0] + A[i,1]*s[1,0] + A[i,2]*s[2,0]) % Q for each row i . The output will always be a column vector: 4. Practical Deployment, Analysis & Case Studies The number of rows of this column vector is equal to the number of rows of the matrix on the left-hand side. In particular, if we take our column vector s , transpose it into a 1 -by- 3 matrix, and multiply it by a 3 -by- 1 matrix r , then we end up with a 1 -by- 1 matrix: The final matrix operation we'll need is matrix addition . If A and B are both N -by- M matrices, then C = (A+B) % Q is the N -by- M matrix for which C[i,j] == (A[i,j]+B[i,j]) % Q . Of course, this only works if the matrices we're adding have the same dimensions.
Enough maths âII let's get to exchanging some keys. We start with the DH diagram from before and swap out the computations with matrix operations. Note that this protocol is not secure, but will be the basis of a secure key exchange mechanism we'll develop in the next section: The vectors t and u are analogous to DH key shares. After the exchange of these key shares, Alice and Bob can compute a shared secret. Alice computes the shared secret as u*s % Q and Bob computes the shared secret as r.T*t % Q . To see why they compute the same key, notice that u*s == (r.T*A)*s == r.T*(A*s) == r.T*t.
In fact, this key exchange is essentially what happens in ML-KEM. However, we don't use this directly, but rather as part of a public key encryption scheme . Public key encryption involves three algorithms: We'll say the scheme is secure if, given a ciphertext and the public key used to encrypt it, no attacker can discern any information about the underlying plaintext without knowledge of the secret key. Once we have this encryption scheme, we then transform it into a key-encapsulation mechanism (the "KEM" in "ML-KEM") in the last step. A KEM is very similar to encryption except that the plaintext is always a randomly generated key.
Here m is a 1 -by- 1 matrix containing the plaintext, i.e., m = np.matrix([[ptxt]]) , and r is a random column vector. Some readers will notice that this looks an awful lot like El Gamal encryption. This isn't a coincidence. Good cryptographers roll their own crypto; great cryptographers steal from good cryptographers. Let's now put this together into code. The last thing we'll need is a method of generating random matrices and column vectors.
We call this function gen_mat() below. Take a crack at implementing this yourself. Our scheme has two parameters: the modulus Q ; and the dimension of N of the matrix and column vectors. The choice of N matters for security, but for now feel free to pick whatever value you want. By now, you might be wondering what on Earth a lattice even is. We promise we'll define it, but before we do, it'll help to understand why our warm-up scheme is insecure and what it'll take to fix it.
Readers familiar with linear algebra may already see the problem: in order for this scheme to be secure, it should be impossible for the attacker to recover the secret key s ; but given the public (A,t) , we can immediately solve for s using Gaussian elimination . In more detail, if A is invertible, we can write the secret key as A-1*t == A-1*(A*s) == (A-1*A)*s == s, where A-1 is the inverse of A . (When you multiply a matrix by its inverse, you get the identity matrix I , which simply takes a column vector to itself, i.e., I*s == s. ) We can use Gaussian elimination to compute this matrix. Intuitively, all we're doing is solving a set of linear equations, where the entries of s are the unknown variables. (Note that this is possible even if A is not invertible.) In order to make this encryption scheme secure, we need to make it a little... âIImessierâII.
For starters, we need to make it hard to recover the secret key from the public key. Let's try the following: generate another random vector e and add it into A* s. Our key generation algorithm becomes: Our formula for the column vector component of the public key, t , now includes an additive term e , which we'll call the error . Like the secret key, the error is just a random vector. Notice that the previous attack no longer works: since A-1*t == A-1*(A*s + e) == A-1*(A*s) + A-1*e == s + A-1*e , we need to know e in order to compute s .
Great, but this patch creates another problem. Take a second to plug in this new key generation algorithm into your implementation and test it out. What happens? You should see that decrypt() now outputs garbage. We can see why using a little algebra: The entries of r and e are sampled randomly, so r.T*e is also uniformly random. It's as if we encrypted m with a one-time pad , then threw away the one-time pad! What can we do about this? First, it would help if r.T*e were small so that decryption yields something that's close to the plaintext. Imagine we could generate r and e in such a way that r.T*e were in range(-epsilon, epsilon+1) for some small epsilon . Then decrypt would output a number in range(ptxt-epsilon, ptxt+epsilon+1) , which would be pretty close to the actual plaintext.
However, we need to do better than get close. Imagine your browser failing to load your favorite website one-third of the time because of a decryption error. Nobody has time for that. ML-KEM reduces the probability of decryption errors by being clever about how we encode the plaintext. Suppose all we want to do is encrypt a single bit, i.e., ptxt is either 0 or 1 . Consider the numbers in range(Q) , and split the number line into four chunks of roughly equal length: Here we've labeled the region around zero ( -Q/4 to Q/4 modulo Q ) with ptxt=0 and the region far away from zero with ptxt=1 .
To encode the bit, we set it to the integer corresponding to the middle of its range, i.e., m = np.matrix([[ptxt * Q//2]]) . (Note the double " // " âII this denotes integer division in Python.) To decode, we choose the ptxt corresponding to whatever range m[0,0] is in. That way if the decryption error is small, then we're highly likely to end up in the correct range. Now all that's left is to ensure the decryption error, r.T*e , is small. We do this by sampling short vectors r and e . By "short" we mean the entries of these vectors are sampled from a range that is much smaller than range(Q) . In particular, we'll pick some small positive integer beta and sample entries range(-beta,beta+1) .
How do we choose beta ? Well, it should be small enough that decryption succeeds with overwhelming probability, but not so small that r and e are easy to guess and our scheme is broken. Take a minute or two to play with this. The parameters we can vary are: For what ranges of these parameters is the decryption error low, but the secret vectors are hard to guess? For what ranges is our scheme most efficient, in terms of runtime and communication cost (size of the public key plus the ciphertext)? We'll give a concrete answer at the end of this section, but in the meantime, we encourage you to play with this a bit.
At this point, we have a working encryption scheme that mitigates at least one key-recovery attack. We've come pretty far, but we have at least one more problem. Take another look at our formula for the ciphertext ctxt = (u,v) . What would happen if we managed to recover the random vector r ? That would be catastrophic, since v == r.T*t + m , and we already know t (part of the public key) and v (part of the ciphertext).
Just as we were able to compute the secret key from the public key in our initial scheme, we can recover the encryption randomness r from the ciphertext component u using Gaussian elimination. Again, this is just because r is the solution to a system of linear equations. We can mitigate this plaintext-recovery attack just as before, by adding some noise. In particular, we'll generate a short vector according to gen_mat(N,1,-beta,beta+1) and add it into u . We also need to add noise to v in the same way, for reasons that we'll discuss in the next section.
Once again, adding noise increases the probability of a decryption error, but this time the magnitude of the error also depends on the secret key s . To see this, recall that during decryption, we multiply u by s (to compute the shared secret), and the error vector is an additive term. We'll therefore need s to be a short vector as well. Let's now put together everything we've learned into an updated encryption scheme. Our scheme now has three parameters, Q , N , and beta , and can be used to encrypt a single bit: Before moving on, try to find parameters for which the scheme works and for which the secret and error vectors seem hard to guess.
So far we have a functioning encryption scheme for which we've mitigated two attacks, one a key-recovery attack and the other a plaintext-recovery attack. There seems to be no other obvious way of breaking our scheme, unless we choose parameters that are so weak that an attacker can easily guess the secret key s or ciphertext randomness r. Again, these vectors need to be short in order to prevent decryption errors, but not so short that they are easy to guess. (Likewise for the error terms.) 5. Performance Evaluation & Extended Technical Observations Still, there may be other attacks that require a little more sophistication to pull off. For instance, there might be some mathematical analysis we can do to recover, or at least make a good guess of, a portion of the ciphertext randomness. This raises a more fundamental question: in general, how do we establish that cryptosystems like this are actually secure? As a first step, cryptographers like to try and reduce the attack surface. Modern cryptosystems are designed so that the problem of attacking the scheme reduces to solving some other problem that is easier to reason about.
Our public key encryption scheme is an excellent illustration of this idea. Think back to the key- and plaintext-recovery attacks from the previous section. What do these attacks have in common? In both instances, the attacker knows some public vector that allowed it to recover a secret vector: The fix in both cases was to construct the public vector in such a manner that it is hard to solve for the secret, namely, by adding an error term. However, ideally the public vector would reveal no information about the secret whatsoever. This ideal is formalized by the Learning With Errors (LWE) problem.
The LWE problem asks the attacker to distinguish between two distributions. Concretely, imagine we flip a coin, and if it comes up heads, we sample from the first distribution and give the sample to the attacker; and if the coin comes up tails, we sample from the second distribution and give the sample to the attacker. The distributions are as follows: The first distribution corresponds to what we actually do in the encryption scheme; in the second, t is just a random vector, and no longer a secret vector at all. We say that the LWE problem is "hard" if no attacker is able to guess the coin flip with probability significantly better than one-half.
Our encryption is passively secure âII meaning the ciphertext doesn't leak any information about the plaintext âII if the LWE problem is hard for the parameters we chose. To see why, notice that both the public key and ciphertext look like LWE instances; if we can replace each instance with an instance of the random distribution, then the ciphertext would be completely independent of the plaintext and therefore leak no information about it at all. Note that, for this argument to go through, we also have to add the error term e3 to the ciphertext component v .
We've established that if solving the LWE problem is hard for parameters N , Q , and beta , then so is breaking our public key encryption scheme. What's left for us to do is tune the parameters so that solving LWE is beyond the reach of any attacker we can think of. This is where lattices come in. A lattice is an infinite grid of points in high-dimensional space. A two-dimensional lattice might look something like this: The points always follow a clear pattern that resembles "lattice work" you might see in a garden: For cryptography, we care about a special class of lattices, those defined by a matrix P that "recognizes" points in the lattice.
That is, the lattice recognized by P is the set of vectors v for which P*v == 0 , where " 0 " denotes the all-zero vector. The all-zero vector is np.zeros((N,1), dtype=int) in NumPy. Readers familiar with linear algebra may have a different definition of lattices in mind: in general, a lattice is the set of points obtained by taking linear combinations of some basis. Our lattices can also be formulated in this way, i.e., for a matrix P that recognizes a lattice, we can compute the basis vectors that generate the lattice. However, we don't much care about this representation here.
The LWE problem boils down to distinguishing a set of points that are "close to" the lattice from a set of points that are "far away from" the lattice. We construct these points from an LWE instance and a random (A,t) respectively. Here we have an LWE sample (left) and a sample from the random distribution (right): What this shows is that the points of the LWE instance are much closer to the lattice than the random instance. This is indeed the case on average. However, while distinguishing LWE instances from random is easy in two dimensions, it gets harder in higher dimensions.
Let's take a look at how we construct these points. First, let's take an LWE instance (A,t=(A*s + e) % Q ) and consider the lattice recognized by the matrix P we get by concatenating A with the identity matrix I . This might look something like this ( N=3 ): Notice that we can compute t by multiplying P by the vector we get by concatenating s and e ( beta=2 ): Let z denote this vector and consider the set of points v for which P*v == t . By definition, we say this set of points is "close to" the lattice because z is a short vector. (Remember: by "short" we mean its entries are bounded around 0 by beta .) Now consider a random (A,t) and consider the set of points v for which P*v == t . We won't prove it, but it is a fact that this set of points is likely to be "far away from" the lattice in the sense that there is no short vector z for which P*z == t.
Intuitively, solving LWE gets harder as z gets longer. Indeed, increasing the average length of z (by making beta larger) increases the average distance to the lattice, making it look more like a random instance:Â Given a random matrix A , the Short Integer Solution (SIS) problem is to find short vectors (i.e., whose entries are bounded by beta ) z1 and z2 for which (A*z1 + z2) % Q is zero. Notice that this is equivalent to finding a short vector z in the lattice recognized by P : If we had a (quantum) computer program for solving SIS, then we could use this program to solve LWE as well: if (A,t) is an LWE instance, then z1.T*t will be small; otherwise, if (A,t) is random, then z1.T*t will be uniformly random. (You can convince yourself of this using a little algebra.) Therefore, in order for our encryption scheme to be secure, it must be hard to find short vectors in the lattice defined by those parameters.
Intuitively, finding long vectors in the lattice is easier than finding short ones, which means that solving the SIS problem gets easier as beta gets closer to Q . On the other hand, as beta gets closer to 0 , it gets easier to distinguish LWE instances from random! This suggests a kind of Goldilocks zone for LWE-based encryption : if the secret and noise vectors are too short, then LWE is easy; but if the secret and noise vectors are too long, then SIS is easy. The optimal choice is somewhere in the middle.
To tune our encryption scheme, we want to choose parameters for which the most efficient known algorithms (quantum or classical) for solving LWE are out of reach for any attacker with as many resources as we can imagine (and then some, in case new algorithms are discovered). But how do we know which attacks to look out for? Fortunately, the community of expert lattice cryptographers and cryptanalysts maintains a tool called lattice-estimator that estimates the complexity of the best known (quantum) algorithms for lattice problems relevant to cryptography. Here's what we get when we run this tool for ML-KEM (this requires Sage to run): The number that we're most interested in is " rop ", which estimates the amount of computation the attack would consume.
Playing with this tool a bit, we eventually find some parameters for our scheme for which the " usvp " and " dual_hybrid " attacks have comparable complexity. However, lattice-estimator identifies an attack it calls " arora-gb " that applies to our scheme, but not to ML-KEM, that has much lower complexity. ( N=600 , Q=3329 , and beta=4 ): We'd have to bump the parameters even further to the scheme to a regime that has comparable security to ML-KEM.
Finally, a word of warning: when designing lattice cryptography, determining whether our scheme is secure requires a lot more than estimating the cost of generic attacks on our LWE parameters. In the absence of a mathematical proof of security in a realistic adversarial model, we can't rule out other ways of breaking our scheme. Tread lightly, fair traveler, and bring a friend along for the journey.
Now that we understand how to encrypt with LWE, let's take a quick look at how to make our scheme efficient. The main problem with our scheme is that we can only encrypt a bit at a time. This is because we had to split the range(Q) into two chunks, one that encodes 1 and another that encodes 0 . We could improve the bit rate by splitting the range into more chunks, but this would make decryption errors more likely.
Another problem with our scheme is that the runtime depends heavily on our security parameters. Encryption requires O(N2) multiplications (multiplication is the most expensive part of a secure implementation of modular arithmetic), and in order for our scheme to be secure, we need to make N quite large. ML-KEM solves both of these problems by replacing modular arithmetic with arithmetic over a polynomial ring . This means the entries of our matrices will be polynomials rather than integers. We need to define what it means to add, subtract, and multiply polynomials, but once we've done that, everything else about the encryption scheme is the same.
The main advantage of using a polynomial ring for arithmetic is that we can pack more bits into the ciphertext. Our formula for the ciphertext is exactly the same ( u=r.T*A + e2, v=r.T*t + e3 + m ), but this time the plaintext m encodes a polynomial. Each coefficient of the polynomial encodes a bit, and we'll handle decryption errors just as we did before, by splitting range(Q) into two chunks, one that encodes 1 and another that encodes 0 . This allows us to reliably encrypt 256 bits (32 bytes) per ciphertext.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Lattice-based%20cryptography • https://en.wikipedia.org/wiki/NIST%20Post-Quantum%20Cryptography%20Standardization • https://en.wikipedia.org/wiki/Post-quantum%20cryptography • https://csrc.nist.gov/projects/post-quantum-cryptography • https://www.nist.gov/pqc • https://qramm.org/learn/lattice-based-cryptography.html • https://blog.cloudflare.com/lattice-crypto-primer/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Post Quantum Cryptography Lattice Based Encryption Project.
[*] Metasploit Scan Running on Target Subnet for Post Quantum Cryptography Lattice Based Encryption Project... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |