Complete Technical Paper Content — Privacy Policy Summarizer And Risk Analyzer Using Nlp
Overview & System Context
Privacy Policy Summarizer And Risk Analyzer Using Nlp: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9517 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Most internet users accept Terms of Service and Privacy Policies without reading them due to their length and complexity .
These documents often contain important clauses related to data collection, tracking technologies, advertising practices, and third-party data sharing . The system performs text preprocessing, TF-IDF feature extraction, machine learning classification, and information retrieval techniques to identify and analyze privacy-related content.
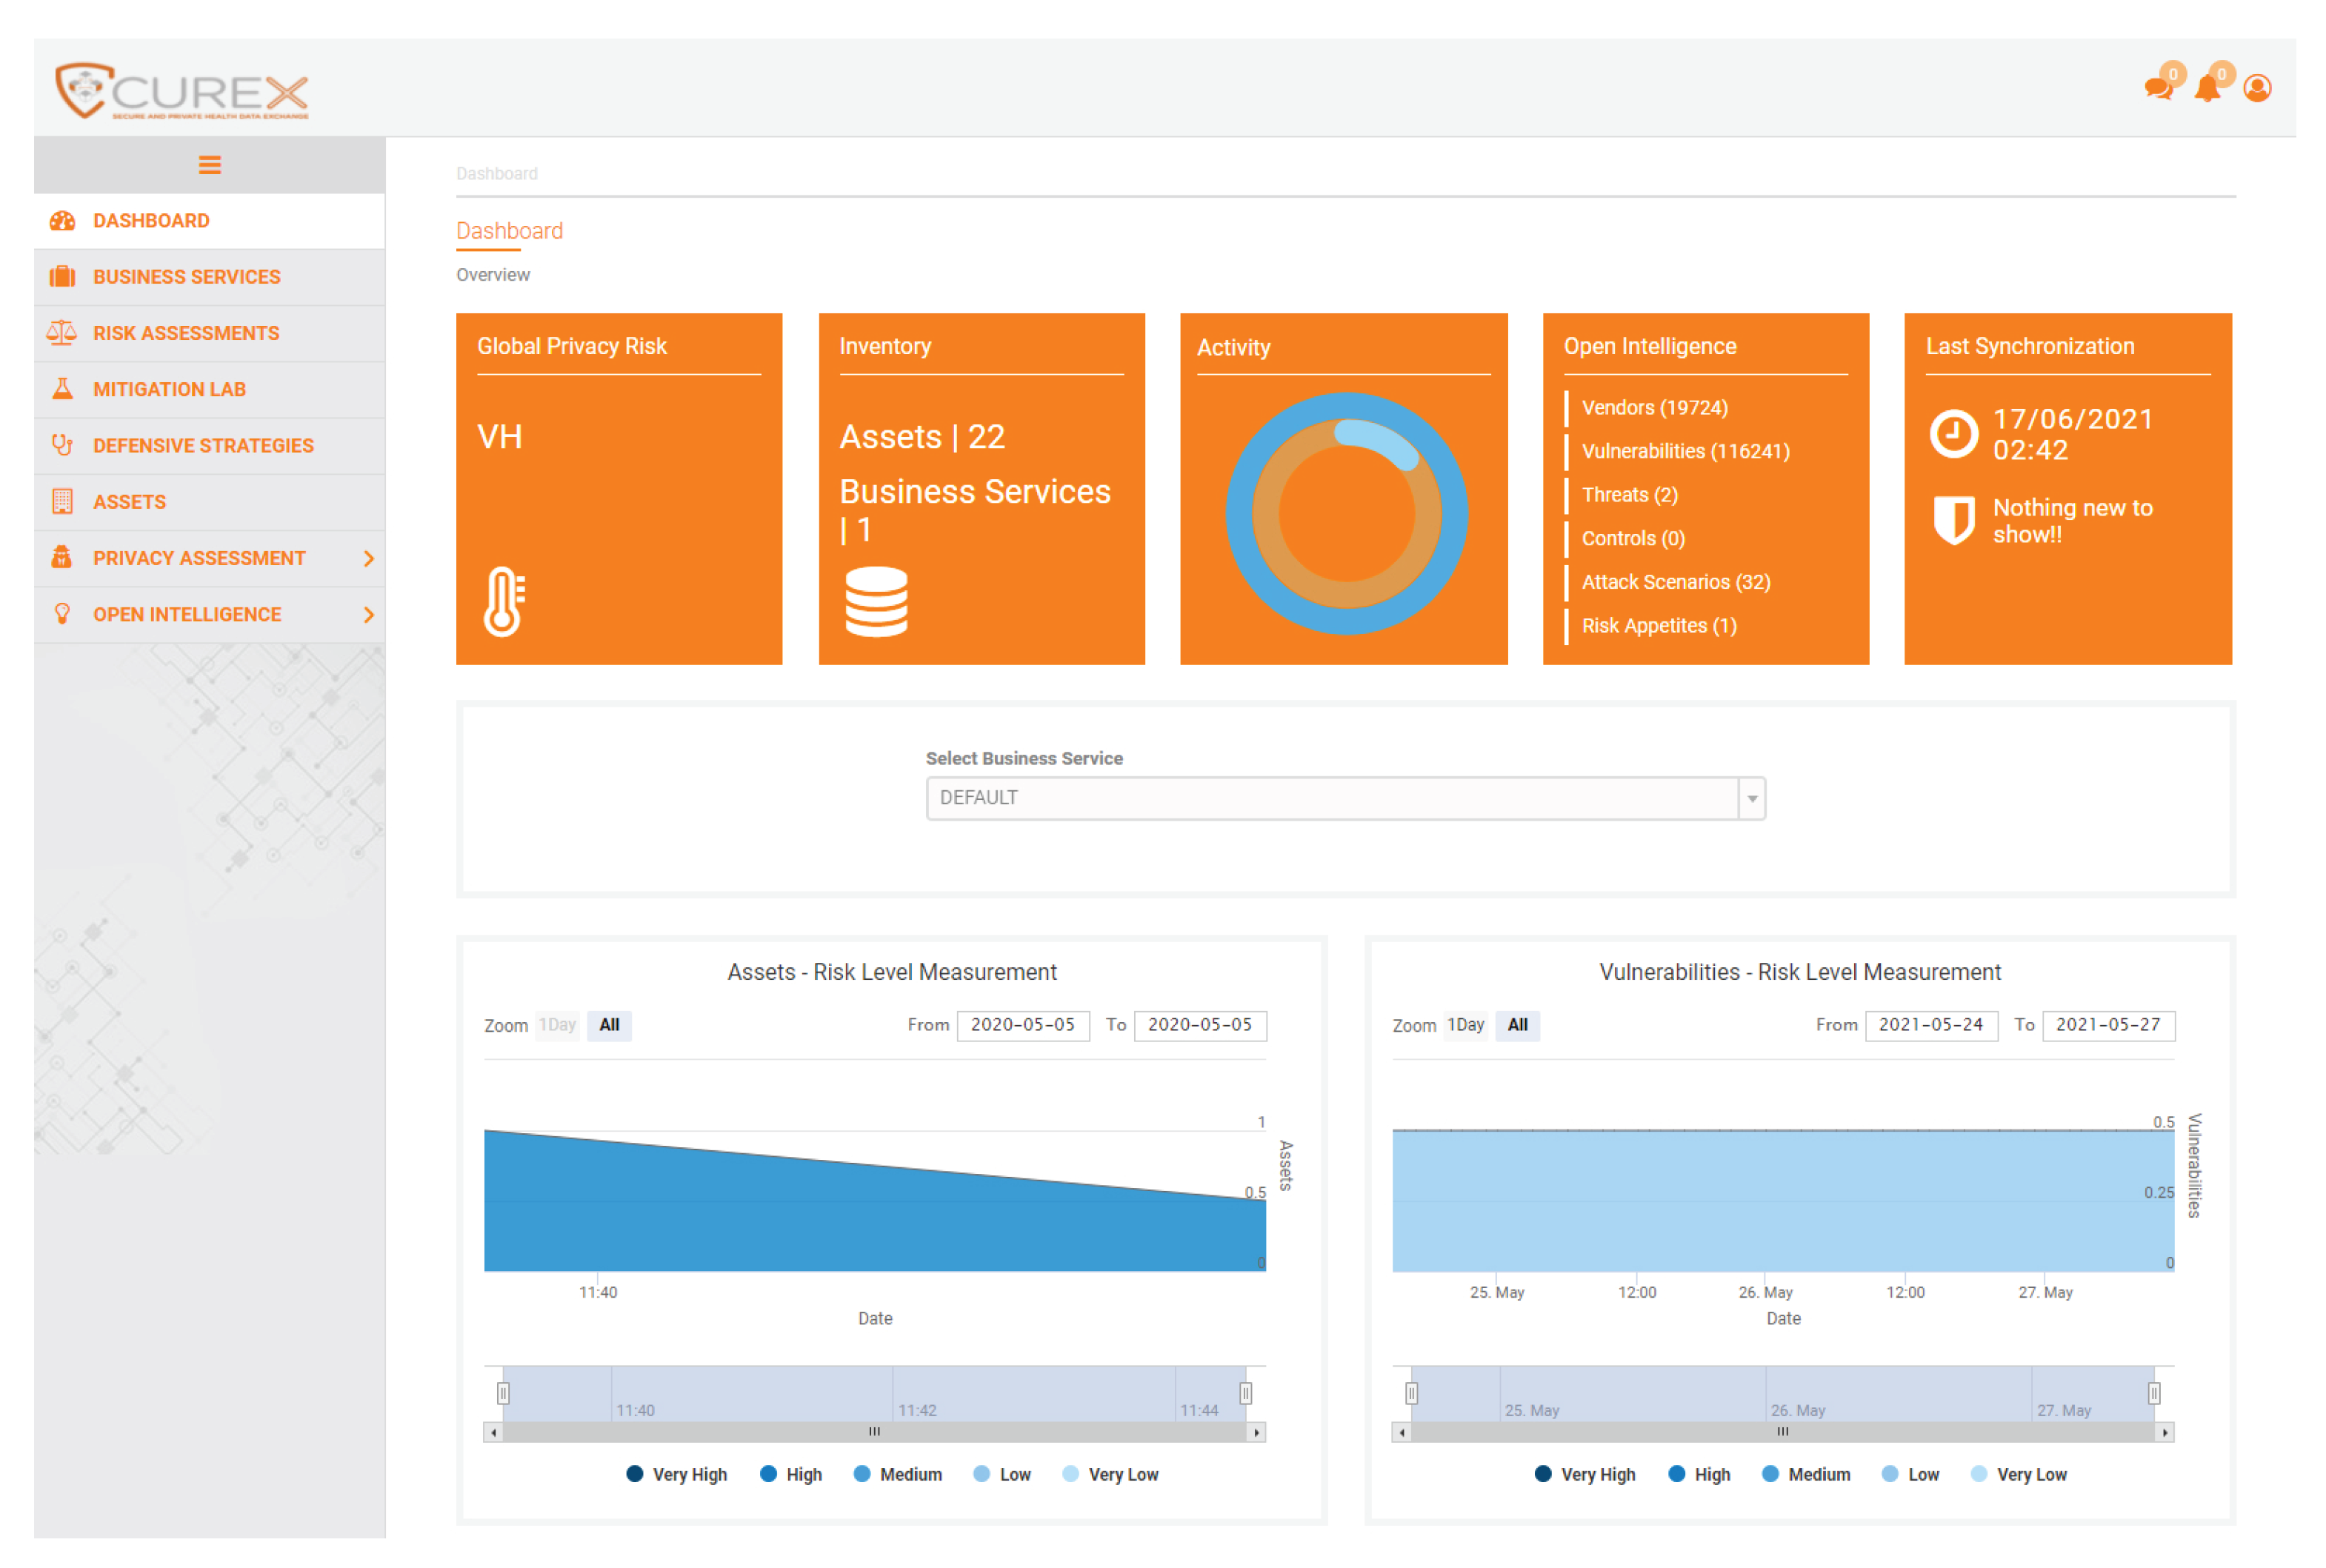
Privacy policies are long legal documents that most users do not read. Important clauses regarding data collection, tracking, and third-party sharing are often hidden within these documents. The documents are stored as text files , making them suitable for text mining and NLP analysis . Figure 1: Automated Cyber and Privacy Risk Management Toolkit Porter stemming was chosen because it is fast and effective for text classification tasks .
These settings improve the ability of the model to detect important privacy-related terms . This project demonstrates how text mining and NLP techniques can be applied to analyze privacy policies and identify privacy risks . By combining machine learning classification, TF-IDF feature extraction, information retrieval methods, and visualization techniques , the system helps users better understand complex privacy documents and improve transparency in data privacy practices.
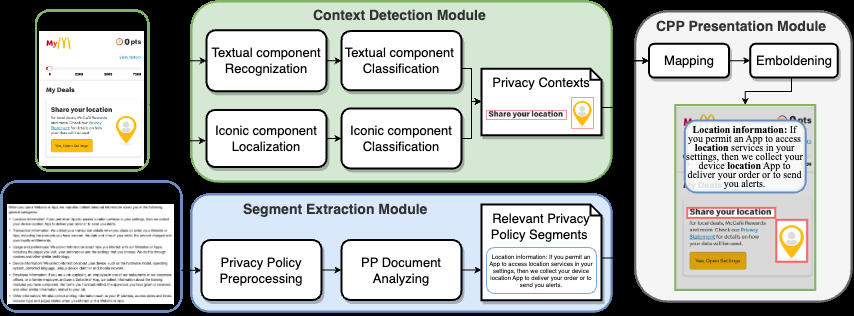
Figure 2: SeePrivacy: Automated Contextual Privacy Policies Generation for Mobile ... AI-powered system that analyzes privacy policies and Terms & Conditions to generate concise summaries, detect high-risk clauses, and assign a structured Privacy Risk Rating — fully offline and privacy-preserving. TermsBuster tackles the growing problem of uninformed digital consent caused by lengthy and legally complex privacy policies.
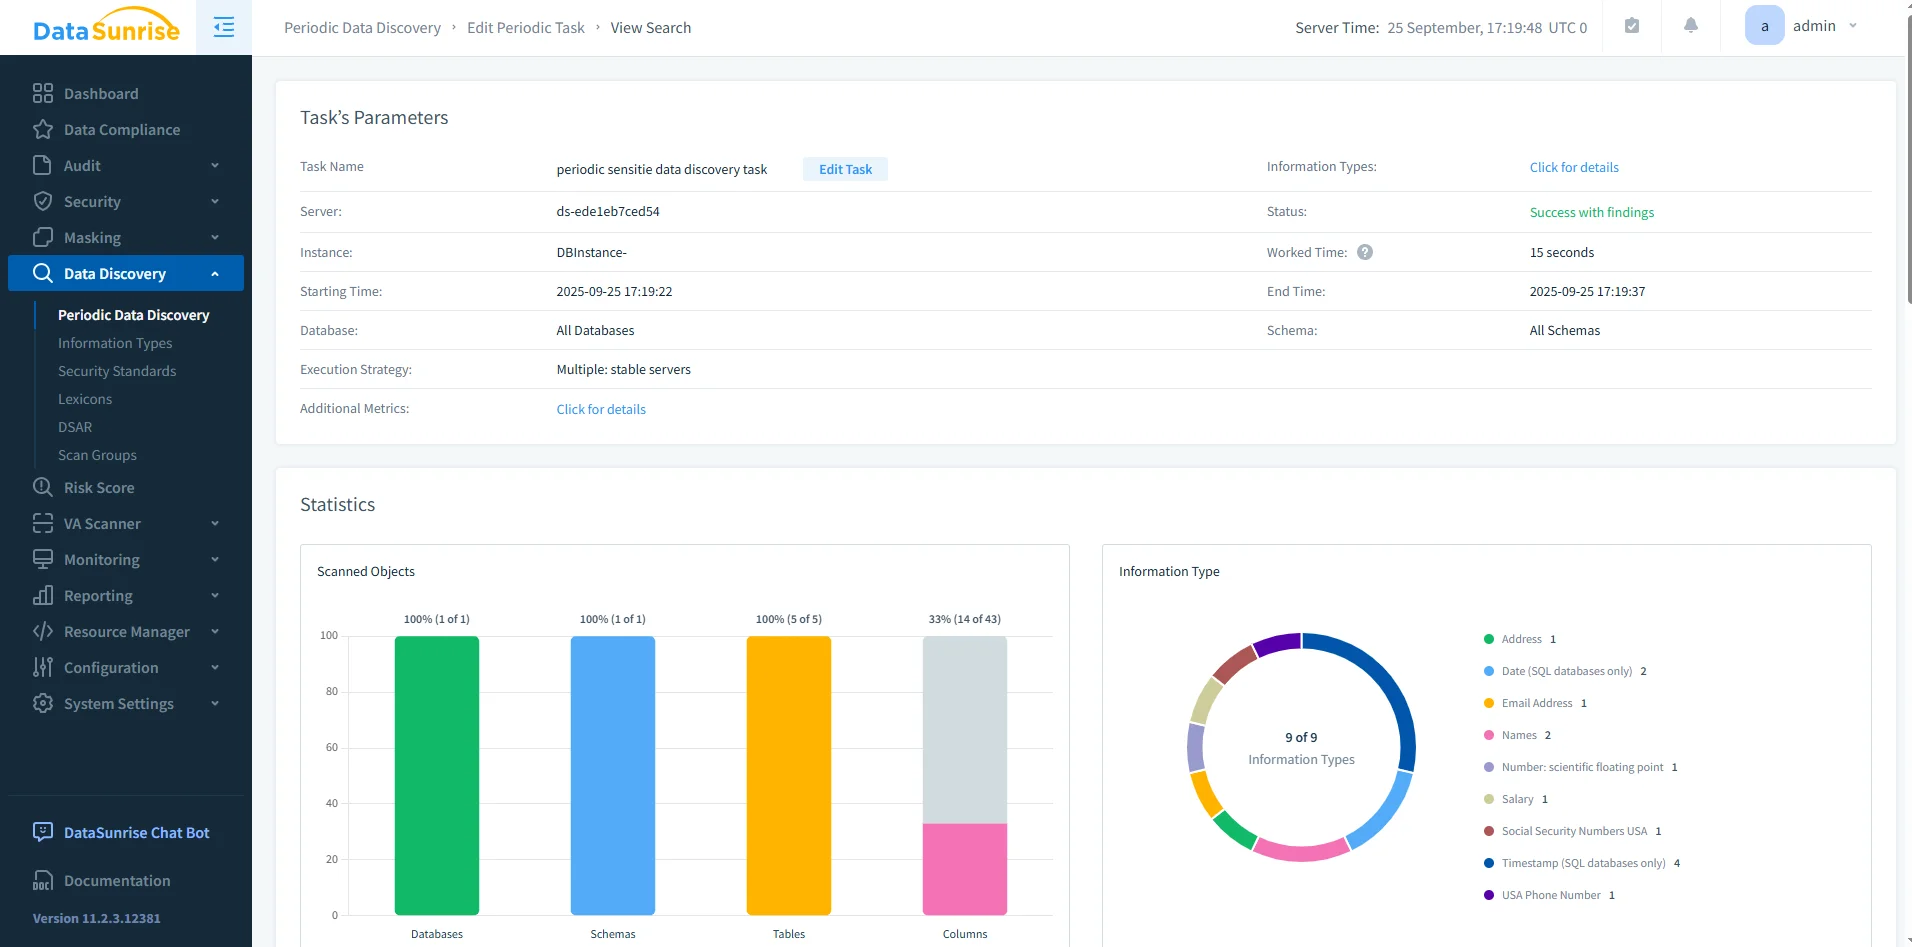
By combining transformer-based NLP with interpretable risk detection logic, the system improves transparency, compliance awareness, and digital risk assessment. In today’s digital ecosystem, every online platform requires users to accept privacy policies and terms of service. These documents are often: Figure 3: NLP, LLM & ML Data Compliance Tools for IBM Db2 | DataSunrise As a result, users frequently skip reading them and unknowingly consent to clauses involving data tracking, third-party sharing, and extended data retention.
TermsBuster transforms dense legal documents into clear summaries and actionable privacy insights. User Input (PDF / Image / Text) ↓ OCR & Text Preprocessing ↓ BART Summarization Engine ↓ Hybrid Risk Analyzer ↓ Privacy Rating Generator ↓ Streamlit Dashboard + Report Export The modular architecture ensures scalability, maintainability, and future enhancements.
The project incorporates multiple features, including privacy risk scoring, policy summarization, risk classification, infographic generation, audio-based explanations, and multilingual translation support. A Privacy Risk Dashboard visually presents detected risks, AI-generated scores, and policy insights, while a Chrome Extension allows users to access privacy analysis directly during web browsing. These features improve accessibility and help users quickly understand important privacy concerns without reading lengthy policy documents.
Through this project, I gained hands-on experience in Artificial Intelligence, Natural Language Processing, Flask web development, risk assessment systems, dashboard design, and browser extension development. The project strengthened my ability to build user-centric AI solutions that combine automation, data processing, visualization, and real-world problem solving to enhance digital privacy awareness.
AI-powered Privacy Risk & Policy Analyzer using NLP, Flask, Chrome Extension, risk scoring, summarization, translation, and infographic generation. Privacy policies are also periodically revised to reflect updates in practice, making users’ previous efforts on reading and understanding futile ( Schwartz and Solove, 2009 ) . Additionally, the timing of a policy notification is often inopportune and leads to immediate dismissal of any notice regarding policy updates or warnings to users on data sharing ( Inglesant and Sasse, 2010 ) . Despite these issues, privacy policies are critical for transparency between users and service providers. These policies are also regulatory, thus mandatory for organizations to add, especially after the onset of regulations such as GDPR (General Data Protection Regulation) ( Voigt and Von dem Bussche, 2017 ) , CCPA (California Consumer Privacy Act) ( Pardau, 2018 ) , COPPA (Children’s Online Privacy Protection Rule) ( Gadbaw, 2016 ) , and others.
Recent advances in natural language processing (NLP) have motivated the development of applications to make privacy policies more usable. The field of NLP encompasses a variety of techniques involving computational processing to understand human languages, and can analyze documents directly, requiring minimal manual scrutiny of policy content ( Sadeh et al., 2013 ) . Several prior works have been published that tackle different usability aspects of policies with diverse NLP techniques.
We have curated a collection of 109 109 area relevant papers to drive research solutions toward progress on significant challenges. We provide a viewpoint of the established area through systematization and evaluation of existing knowledge and the current research landscape. Our review captures areas that have enjoyed much research attention, points out areas with unsolved challenges and presents a prioritization that can guide researchers to progress in solving fundamental challenges. In our analysis, we first discuss the current state of privacy policies, identify their inherent problems, and then present a brief discussion on established non-NLP research. We also highlight the gaps in non-NLP solutions that necessitates NLP application. After that, we categorize current NLP research on privacy policies into different areas: information retrieval, summarization, automatic question-answering, classification, and alignment. Finally, we study the scope of each area, identify challenges and shortcomings, and provide future research directions that can benefit from the community’s attention. To our knowledge, no other survey articulates NLP research on privacy policies.
This section describes the inclusion/exclusion criteria for works explored during this review and the methodology for organization and study. 2. System Architecture & Core Working Principles The application of NLP on privacy policies has recently become popular. To better understand this popularity, we collected papers that study the challenges and issues of privacy policies and NLP solutions to improve the usability of privacy policies.
We also curated papers that tackle the usability of privacy policies without employing NLP to stress the importance of NLP in the domain. In addition, we included papers describing developments in word embedding and NLP models, which is crucial for NLP performance on privacy policies to be at par with the current state-of-the-art in other domains. Finally, papers from domains other than privacy policies (e.g., NLP for legal documents) are also included to inspire research for usable privacy policies.
Studies examining the usability problems with privacy policies are called ‘Comprehension challenges.’ We further sub-categorize papers into three facets of challenges: ‘Readability,’ ‘Ambiguity,’ and ‘Accessibility.’ These subjects highlight the distinctive features vital for efficient communication of privacy practices. Table 2 provides a list of papers classified with categories of challenges.
While some solutions concentrate on effective designs and recommendations to tailor natural language privacy policies into a more usable version, a significant portion of research has focused on developing usable notice and choice modality to present users with adequate privacy-specific information. Therefore, we categorize such solutions as ‘Non-NLP solutions.’ These papers present ideas to tackle challenges at the core of a policy disclosure methodology. We further categorize ‘Non-NLP solution’ papers into ‘Requirements and regulations, ‘Policy design,’ and ‘Machine-readable format,’ each representing a distinct method of realizing a solution. Table 3 lists the papers that present non-NLP solutions to enhance user privacy management.
The third category of papers is ‘Dataset creation and analysis,’ which focuses on corpus creation and analysis to facilitate the development of natural language processing tools for privacy policies. Papers that propose NLP research in the privacy domain are categorized as ‘NLP solutions,’ We further sub-categorize these into specific areas of NLP, namely ‘Information retrieval,’ ‘Summarization,’ ‘Question-answering,’ ‘Classification,’ and ‘Alignment.’ Table 4 lists the papers dedicated to each area of NLP solutions for privacy policies. It is evident from the table that the majority of the research focuses on the classification of privacy-inclined texts. Information retrieval follows classification and is crucial to present relevant information to users. Lastly, word embedding models must effectively capture the semantics of the policy jargon since privacy policies use specialized terminology to articulate information.
Websites, mobile apps, and other web products and services rely on natural language privacy policies to notify users about their privacy practices. These policies are unrestricted in terms of a well-defined structure and content. Despite that, policies are expected to cover content from the following categories ( Wilson et al., 2016 ) . Third party sharing/collection : how user information may be shared with or collected by third parties User access, edit, & deletion : if and how users can access, edit, or delete their information Do not track : if and how do not track signals for online tracking and advertising are honored International & specific audiences : practices that pertain only to a specific group of users (e.g., children, residents of the European Union, or Californians) Consent and Choice: User consent should be taken to collect and process their data. Users should be lucidly informed of their rights and choices. A policy should explain the implications of granting or withholding consent and provide mechanisms for the users to exercise their choice.
Collection limitation : The collection of user data should be within the bounds of the applicable law and the necessity of the stated purpose. Data minimization : Contact with user information should be minimized and a “need-to-know” principle should be followed. User information should be deleted periodically.
Use, retention, and disclosure limitation: User information should be used only for the intended purpose and retained only as long as necessary. When the specific purpose expires, the information should be locked if needed to be retained. Accuracy and quality: User information should be collected and processed accurately. Information should be verified, and the reliability of the information should be ensured.
Openness, transparency, and notice : Organizations should clearly and sufficiently communicate the policies, practices, and procedures governing user information. The communication should include the purpose of information collection, information disclosure and sharing principles, and retention and disposal practices. User choices and mechanisms to exercise them should be communicated. Users should be notified of any changes.
Individual participation and access : Users should be able to access, review, edit and delete their information in a simple, fast and efficient manner. Accountability : All the privacy-related policies, procedures, and practices should be documented. Third-party accountability should be ensured. A privacy officer should be assigned to enforce accountability.
Information security : Organizations should protect user information’s confidentiality, integrity, and availability. Information security should be guaranteed, and compliance with legal requirements and security standards should be ensured. Periodic security risk assessment and a cost/benefit analysis should be conducted. Actions and fail-safes should be implemented for any potential event.
Privacy compliance : Organizations should ensure their compliance with privacy principles. Periodic privacy audits and internal compliance checks should be conducted. In addition, a privacy risk assessment process should be developed and maintained. Privacy policies pose several challenges that hinder the general public from effectively utilizing policies to make informed privacy-related decisions. We identified three categories of these challenges: readability and comprehensibility, ambiguity, and accessibility ( Adhikari et al., 2023 ; Wagner, 2023 ) .
Privacy policies are arduously long, averaging over 2500 words ( McDonald and Cranor, 2008 ) , complicated, and have low readability and comprehension. This discourages users from attempting to read and understand them. In terms of time investment, a user will have to spend at least 181 hours per year to read applicable policies ( McDonald and Cranor, 2008 ; Libert, 2018 ) .
The number of different ways a policy can be interpreted makes privacy policies ambiguous. In order to give organizations more flexibility, policymakers frequently use ambiguity or vagueness, thereby concealing potentially harmful practices. Even law and policy experts find it challenging to agree on decisive policy composition ( Reidenberg et al., 2015 ; Reidenberg et al., 2016 ) . The incompleteness of information also contributes to ambiguity. For example, a typical policy discloses only 15 % 15\% of third-party data flow practices, and 7 % 7\% of policies do not mention the ‘Do Not Track’ signal ( Libert, 2018 ) .
3. Software Implementation, Frameworks & Protocols Accessing specific portions of a policy is also challenging for many users. An average user needs help finding information regarding a specific data practice due to the tremendous effort required to read the policy in the first place ( Habib et al., 2020 ) . Finding policies on a website can be challenging for an average adult as well ( Jensen and Potts, 2004 ) . In addition, the timing of privacy notices and security warnings is often inopportune, leading to immediate dismissal, as policies are shown at times that conflict with the user’s primary task ( Inglesant and Sasse, 2010 ) .
There are approaches other than NLP that can be used to address the challenges discussed in Section 3.2 and achieve usable privacy policies. However, these methods fell short and could not address the underlying issues with policies. This section discusses such approaches and their drawbacks, which prompted the research community to investigate NLP. Then, in Section 4 , we go over the various subjects of NLP research in depth.
To increase policy usability, several organizations have issued recommendations and mandated requirements. For instance, the European Article 29 Working Party provides suggestions for IoT devices ( Article 29 Working Party, 2014 ) , and the National Telecommunications and Information Administration offers policy drafting instructions for mobile apps ( National Telecommunications and Information Administration, 2013 ) . In addition, the Federal Trade Commission (FTC) in the United States suggests having privacy rules that are concise and easy to understand ( Commission et al., 2012 ) . On the other hand, the General Data Protection Regulation (GDPR) mandates greater transparency in privacy policies for data processing in Europe ( Voigt and Von dem Bussche, 2017 ) .
The effectiveness of a policy is determined by when it is provided, how it is delivered, the type of interaction used, and how to control the choices given. Schaub et al. ( Schaub et al., 2015 ) have identified requirements and best practices for practical and usable privacy notice design. They provide an overview of a design space to consider while authoring comprehensive policies that meet the audience-specific requirements and incorporate the constraints of policy practices. This design space contains dimensions such as the timing of notices, dissemination channels, the modality of communication, and actionable controls.
To improve the accessibility of conventional privacy policies, numerous extra or modified formats of expressing policy practices are suggested, given that natural language policies are required and cannot be replaced. Short notices : To effectively communicate vital information to consumers without overwhelming them, policies can be condensed ( Gluck et al., 2016 ; Strahilevitz and Kugler, 2016 ) .
Multi-layered policies : The Art.29 Data Protection Working Party suggested multi-layered privacy policies that place the most important information first (directly visible to all)—the controller’s identity, the aims of processing, and circumstantial procedures. The second and third layers would provide interested parties with more thorough information ( Article 29 Working Party, 2004 ) . The Center for Information Policy Leadership at the law firm of Hunton & Williams made one of the initial attempts to build multilayer privacy notification standards ( Center for Information Policy Leadership, 2007 ) .
Graphical privacy policies : Graphical representations of policies for increasing user understanding are also proposed. Privacy icons can represent data types and practices, such as IIIIIIIIIII \mathsf{KnowPrivacy} icons ( Gomez et al., 2009 ) . To better convey the level of privacy protection and invasion, icons can be supplemented with colored rings ( Pinnick, 2011 ) . Similar colored symbol indicators are used by browser plugins like IIIIIIIIIII \mathsf{PrivacyBird} to show whether a website’s P3P policy (a machine-readable format) complies with the preferences of the user ( CyLab Usable Privacy and Security Laboratory, 2019 ) . The tabular privacy format known as ‘privacy nutrition labels’ is another graphical representation that can help users better understand privacy policies by making the information more readily available, and by tabulating information on data collection, usage, and sharing ( Kelley et al., 2009 ) .
In order to be automatically processed by computers, machine-readable policies require XML or another computer-readable language. The World Wide Web Consortium’s specification of P3P (Platform for Privacy Preferences) was the most reviewed attempt ( Cranor, 2003 ) . Statements from the P3P XML specification describe the procedures for handling data sets. Each statement includes the data categories, the intended use, the recipients, and the retention policy. However, due to their intricate definitions, the privacy taxonomy and language in the XML specification proved controversial ( Cranor et al., 2002 ) .
There are also a variety of P3P extensions available, but they received little traction ( Cranor, 2002 ; Ashley et al., 2002 ; Agrawal et al., 2003 ) . Following the introduction of P3P, new languages with comparable syntax were developed, including the “Enterprise Policy Authorization Language” (EPAL) ( Ashley et al., 2003 ) , “Accountability Policy Language” (A-PPL) ( Azraoui et al., 2014 ) , “Customer Profile Exchange” (CPExchange) ( Bohrer and Holland, 2000 ) , “Purpose-to-Use” (P2U) ( Iyilade and Vassileva, 2014 ) and “Layered Privacy Language” (LPL) ( Gerl et al., 2018 ) . These languages make some improvements in terms of usability and enforcement while being similar to P3P.
Requirements and recommendation in reality make privacy policies more complicated. For example, the GLBA and HIPAA Privacy Rules governing finance and healthcare, respectively, the COPPA rule governing children’s information, the Video Privacy Protection Act (VPPA), and several other U.S. national security laws, all impose constraints on how privacy policies are written. Additionally, data imported into U.S. organizations must comply with a “Safe Harbor” agreement or foreign regulation. As a result of trying to simultaneously meet all the standards and serve the interests of the organization, regulators, and customers, these regulations result in extremely complicated privacy policies.
Policy redesign solutions suffer from vagueness and incompleteness. Alternatively, the general public will only be informed partially if privacy warnings are condensed only to include the most crucial procedures. Furthermore, multi-layered policies allow businesses to choose each segment’s language and content, which may conflict with user expectations of critical information. For lay people, graphical visualizations like nutrition labels and privacy icons are devised, yet they show ambiguity in interpretation. The same is valid for privacy icons, where ambiguity might be introduced by cultural, educational, or contextual variations.
Machine-readable policies lack a workable and scalable implementation, making it challenging to employ them in actual applications. The lack of acceptance and human comprehensibility is another problem for machine-readable formats. Furthermore, many Internet users need help utilizing the P3P software that comes pre-installed in many systems. Another issue is that neither users of the Internet nor websites are required to utilize machine-readable formats. As a result, machine-readable privacy policies are no longer considered as helpful or practical as once.
In summary, natural language privacy policies are a popular way to “notice and choice.” However, many early works focus on alternative formats to communicate privacy practices and hence suffer from poor adoption or lack of expressiveness. Methods such as privacy nutrition labels have received attention from a select few large organizations (e.g., Google and Apple). However, natural language documents remain their primary, detailed, privacy-related communication tool. This has directed recent research to embrace natural language processing as the method of choice to extract relevant privacy information from a policy document, design query systems, and summarizations, and identify presentation issues that hamper a user’s ability to comprehend such documents. NLP solutions do not require organizations to reformat their mode of privacy communication and work directly on documents that already exist in most organizations.
Wilson et al. generated a dataset called the OPP-115 corpus that contains policy information from 115 websites ( Wilson et al., 2016 ) . With annotation for 23,000 data practice statements, 128,000 practice attributes, and 103,000 annotated text spans, OPP-115 is the most extensively used corpus. The OPP-115 corpus policies are annotated with the ten high-level categories listed in Section 3.1 . High-level categories are further broken down with a set of attributes that are distinct from each other. For example, a ‘User choice/control’ data practice is associated with attributes such as ‘choice type,’ ‘choice scope,’ ‘personal information type,’ ‘purpose,’ and ‘user type.’ ‘First party collection/use’ and ‘Third party sharing/collection’ are the two most frequently occurring categories in this corpus, hinting at the focus of most policies. The ‘Other’ category also gets heavily used, potentially indicating disagreements between annotators resulting from the ambiguity in privacy documents.
Categories such as ‘User choice/control,’ ‘User access, edit, and deletion,’ and ‘Do not track’ appear with a relatively lower frequency, indicating a paucity of information for user-specific actionable items. Over the past twenty years, there have been more than twice as many privacy policies. Because past studies had only been able to examine privacy policies from a single moment in time, Amos et al. created a longitudinal collection of policy corpora using a crawler on Archive’s Wayback Machine ( Amos et al., 2021 ) . This collection now contains 1,071,488 English language privacy policies. Policies from 130,000 websites, some of which have been around for more than 20 years, are included in this corpus. Broken links and careful processing to obtain the relevant texts are challenges when building a corpus with automated crawlers ( Wilson et al., 2016 ; Amos et al., 2021 ; Sarne et al., 2019 ; Bannihatti Kumar et al., 2020 ) .
The PrivaSeer corpus is a large, single snapshot, English language corpus of 1,005,380 privacy policies from 995,475 different web domains, gathered around early August of 2019 ( Srinath et al., 2021 ) . The corpus is created using a crawler seeded with 3.9 million potential URLs to privacy policies; the downloaded content was further filtered using language detection, document classification, URL cross-verification, and duplicate removal. The PrivaSeer corpus is also indexed and can be searched through a web interface.
The APP-350 corpus contains policies of Google Play Store apps that have more than 50 million installs and randomly chosen apps with more than 5 million installs, totaling 350 policies. The corpus was created to study enhancements that can be made to mobile application policies ( Zimmeck et al., 2019 ) . PRIVACYQA is another corpus of mobile application policies created for evaluating automated question-answering systems ( Ravichander et al., 2019 ) . This corpus has 3,500 annotations of appropriate responses to 1,750 questions identified by experts.
Numerous other corpora are created expressly for study or advancement in specific NLP fields. For instance, a corpus of 400 policies annotated with risk levels for an email address, credit card number, social security number, advertisement and marketing, location, personally identifiable information of children, sharing with law enforcement, policy change, control of data, and data aggregation have been used in research for automated risk assessment ( Zaeem et al., 2018 ) . Another example of one of these corpora is the 130,326 Android application policies collection, which was utilized to create a privacy domain-specific word-embedding ( Harkous et al., 2018 ) .
By engineering computational models and methods, natural language processing can be applied to human language problems, such as in privacy policies. Topics, including pertinent information extraction, content summarization, automated question-answering, document categorization, and document clustering, are all covered in the NLP application field for privacy policies. In reality, the themes mentioned above overlap, but we discuss the works within the context of a single field at a time.
Towards the end of this section, we also briefly review the word embedding models in general and expand upon the models that have been tried and tested for privacy policies. Information retrieval systems are designed to assist users in finding crucial data in the most practical format at the precise moment they need it ( Kenter et al., 2017 ) . Information retrieval from privacy policies entails identifying the texts’ sections that meet the needs of the current task. If done correctly, information extraction from policies can reduce the work required of users to comprehend the subtleties controlling their privacy.
Several challenges appear when designing a system to capture the syntactic and semantic information encoded in a text document. Syntax in privacy policies encompasses words and their arrangement in a sentence, conforming to formal grammar rules. Semantics is about the universally coded meaning, and pragmatics encoded in words and how an audience interprets them.
4. Practical Deployment, Analysis & Case Studies Any written sentence uses a specific word arrangement, known as semantics, to convey some meaning. Formal semantics, lexical semantics, and conceptual semantics are just a few branches and sub-branches of semantics study. The logical components of meaning, such as reference, implication, and sense, are described by formal semantics. Word relations are described by lexical semantics, and cognitive structure is described by conceptual semantics.
A defined, finite set of terminology that incorporates interconnected semantic concepts, and is utilized in knowledge management, is called an ontology. An information type ontology construction technique was demonstrated by Hosseini et al. using a manual grounded analysis of five privacy rules ( Hosseini et al., 2016 ) . This approach was tested against 50 mobile privacy policies, resulting in an ontology comprising 355 distinct pieces of information. The method is directed by seven heuristics that are used to extract associations between hypernyms, meronyms, and synonyms from information-type phrases, and finally culminated into 14 semantic rules. The semantic rules can be expanded to improve extraction efficiency; however, such an approach needs to adapt to the dynamics of policy composition and needs a clear strategy for information extraction that occurs automatically.
Ontology generation can assist in contradiction detection in privacy statements by capturing both positive and negative data collection statements within privacy policies. IIIIIIIIII \mathsf{PolicyLint} is one such tool, which uses an expanded set of Hearst patterns ( Hearst, 1992 ) on named-entity recognition, parts-of-speech analysis, and type dependence, to extract ontologies for both data objects and entities ( Andow et al., 2019 ) . To extract a succinct representation of the grammatical links between the data objects, entities, and verbs, IIIIIIIIII \mathsf{PolicyLint} builds data and entity dependency (DED) trees using dependency parse trees. When building a DED tree, paths between labeled nodes are calculated on a dependency-based parse tree by copying nodes associated with a manually curated lists of verbs applied in sharing and collection statements, data objects, and entities, while retaining information about negated verbs and exception clauses.
Contradictions and limited definitions are detected using predicate logic rules on the resulting four tuples actor, action, data object, and entity components. When IIIIIIIIII \mathsf{PolicyLint} was used to analyze 11,430 privacy policies from well-known apps on Google Play, it was found that 14.2 % 14.2\% of the statements contained logical conflicts and 17.7 % 17.7\% contained narrowing definitions. A closer look found false presentations and redefining of popular terminology, which are alarming outcomes.
Semantic connections can also highlight the shortcomings of privacy policies. For instance, by representing data practice descriptions as semantic frames, one can analyze the degree of integration of semantic roles with data action within a frame ( Fillmore et al., 1976 ) . Bhatia and Breaux used this approach on 202 annotated statements from five privacy policies, yielding 17 semantic roles and 281 instances of data actions ( Bhatia and Breaux, 2018 ) . They determined whether the data practice description was incomplete by looking at missing role associations. It was noted that almost 32 % 32\% of statements about retention, 45 % 45\% of statements about sharing, and 19 % 19\% of statements about usage lack topic roles and purpose roles.
While specialized approaches exist that use syntax-driven semantic analysis methods to construct partial ontologies, and context-free grammar for inferring semantic relations ( Hosseini et al., 2021 ) , deep learning and NLP can facilitate automated methods for improved and scalable extraction of semantic frame representations of policies, and enable large-scale analysis. Shvartzshnaider et al. proposed information extraction through semantic role labeling (SRL) using domain-specific rule-based heuristics to include information for a predefined list of verb predicates ( Shvartzshnaider et al., 2023 ) . Adhikari et al.
demonstrated the value of such fine grain information extraction in its ability to serve as building blocks for a variety of other tasks, including the creation of alternative visualizations and question-answering systems ( Adhikari et al., 2025 ) . Among other applications of SRL in the privacy domain, PurPliance ( Bui et al., 2021 ) has utilized it to handle lengthy and complex phrases within purpose clauses. However, these predicates are mostly limited to first-party collection and use of data, and rarely include information beyond the highly coupled application-specific requirements.
Using stop words to separate the text into candidate keywords, a general unsupervised keyword extractor such as Rapid Automated Keyword Extraction (RAKE) also enables entity extraction from individual documents. The degree and frequency of the word vertices in the word co-occurrence graph are then used to grade potential entities ( Rose et al., 2010 ) . Entities resembling catchphrases can also be extracted using conditional rules based on statistical information ( Galgani et al., 2012 ) .
Named Entity Recognition (NER) is another method to identify collected data, entities collecting information, served purposes, and subsumption relations, thus aggregating the information dispersed across a policy ( Cui et al., 2023 ) . These extracted entities provide concise information, but needs detailed and accompanying textual descriptions. Entity extraction can help categorize privacy policies or extract features, but relationship links must be established between the extracted keywords to guide privacy-specific actionable recommendations. The non-availability of annotations, and coupled scalability issues, also place restrictions on entity extraction research.
Combining crowdsourcing with natural language processing can be a successful strategy for extracting entities from privacy regulations. When paired with crowd worker annotations, dependency tree parsing can be utilized to identify actions on various information kinds reliably ( Bhatia et al., 2016 ) . State of the art in NLP still needs to improve in human interpretation, even though it offers a practical way to scale the extraction from more documents. Crowdsourcing and NLP complement each other and fill in each other’s gaps. While NLP struggles to find semantic traits for meaningful information extraction on its own, crowd workers are prone to missing information.
Summarization can condense privacy policies to critical points by finding elements of interest in the document and encapsulating the most important content. Summarization can either be extractive or abstractive. Extractive summarization extracts, simplifies and organizes sentences in a document to convey critical information. Abstractive summarization conveys information in a document through abstract generation ( Jurafsky, 2000 ) .
The only summary tool for privacy policies is IIIIIIIIIIII \mathsf{PrivacyCheck} , providing an extractive summary in the format of 10 10 user-essential questions with extracted answers ( Zaeem et al., 2018 ) . The questions were compiled using surveys and expert consultations, and answers were extracted using a classification model trained using the Google Prediction API on a corpus of 400 policies. IIIIIIIIIIII \mathsf{PrivacyCheck} also provides a risk score based on the extracted answers.
Question-answering (QA) extracts pertinent words, phrases, or sentences from a document in response to a request. For instance, if users want to inquire about data storage, they can ask, “How long will my information be stored within the organization?” The system should then be able to extract the policy segments that correspond to the user’s query. Finding specific material areas is imperative for these systems that work with natural language documents.
There are two versions of QA, open and closed. In closed QA, questions are marked with predefined labels. Annotations in a corpus such as OPP-115 can define value level, attribute level, and category level granularity for question labels and can then be used to realize a closed QA ( Sathyendra et al., 2017a ) . However, testing showed that it is challenging to map every user inquiry to one of the predetermined categories.
Supervised text classification is a technique used to process documents written in a natural language. This is heavily demonstrated in the legal regime, where classifiers were employed for the automatic recognition of arguments in legal writings and extraction of features involving the lexical, syntactic, semantic, and discourse qualities of texts ( Moens et al., 2007 ; Francesconi and Passerini, 2007 ) . Furthermore, introducing neural networks in the domain has significantly improved text classification performance ( Chen, 2015 ) .
Ammar et al. demonstrated the viability of extracting salient characteristics from privacy policies and evaluating whether a concept is present in a policy by training a logistic regression classifier on a limited sample of privacy policies ( Ammar et al., 2012 ) . The categorization of privacy regulations was eventually tested using several alternative classifier models, including k-NN, SVM, LSVM, and decision trees ( Costante et al., 2012 ) .
It is critical to note that the language used in policy writings is often specialized, making it impossible for a general word embedding model to represent it adequately. Using word embedding produced from training on policy texts is a crucial way to get around this limitation. For example, with domain-specific embedding, a policy analysis tool called IIIIIII \mathsf{Polisis} was developed that classifies both high-level privacy practices and fine-grained data in privacy policies, using a hierarchy of convolutional neural networks ( Harkous et al., 2018 ) .
While the availability of well-performing text classification models has made privacy policies more amenable for high-level concept extraction, note that a policy segment may contain statements from multiple categories. When training classification models, these sentences may inject noise into the semantic interpretation of a category. However, most research has been restricted to segment categorization due to a lack of sentence annotation corpora, and only segment annotations are available in gold standard corpora such as OPP-115.
Although some studies have looked into categorizing sentences, they are primarily interested in identifying the existence of a specific notion. One example is determining if a sentence implies a choice regarding described privacy practices. By converting sentences into unigram and bigram bag-of-words features and then modifying those features to indicate the presence of modal verbs and opt-out specific phrases, a logistic regression model that outperforms linear SVM, random forest, naive Bayes, and nearest-neighbor models for opt-in/out choice detection can be trained ( Sathyendra et al., 2016 ) .
Active learning for data set cleaning and upgrading into a two-classifier architecture improves choice detection performance, where the first classifier determines whether a sentence is a choice instance, and the second classifier automatically identifies and labels different types of opt-out choices offered in privacy policies ( Sathyendra et al., 2017b ) . To improve the performance of a baseline bag-of-words model, a combination of feature types such as stemmed unigrams and bigrams, relative location in the document, and opt-out specific phrases were used. The tools created from these works were also incorporated into a browser extension ( Nisal et al., 2017 ) . For creating tools for opt-out detection and making the results available to users, logistic regression is preferable to BERT ( Devlin et al., 2018 ) and FastText ( Joulin et al., 2016 ) when factors such as words and bigrams, modal verbs/key phrases, subject modeling, hyperlink URL, and hyperlink anchor text are taken into account during feature creation ( Bannihatti Kumar et al., 2020 ) .
Low-frequency categories, such as ‘Do not track,’ have been found to perform poorly in multi-class classifications ( Wilson et al., 2016 ; Liu et al., 2018 ) . In addition, due to a lack of context, sentence-level classification fared poorly when compared to segment-level classification in such categories. According to experimental findings, ambiguity affects how privacy policies are automatically classified since the imbalance between categories often hampers classifier performance.
Another application of supervised classification has been demonstrated in AI-enabled completeness testing of privacy rules in compliance with the General Data Protection Regulation ( Torre et al., 2020 ) . At three distinct hierarchical levels, texts were classified using ML-based classifiers (SVM), similarity-based classifiers (cosine similarity), and keyword-based classifiers. Sentences were vectorized using GloVe ( Pennington et al., 2014 ) , and text generalization swapped out specialized textual elements for more general ones. Through the development of a conceptual model, many tiers of metadata types were created to describe the information content that GDPR intended for privacy rules. Automatic metadata is employed to determine if a given policy complies with the GDPR’s information requirements.
Supervised classification of privacy policies requires text annotations, preferably from law experts who are conversant with the language used in such documents. However, this can be highly expensive and needs to scale better. As an unsupervised alternative, the intersection of language learned from topic modeling, and category-specific essential vocabulary can also be used to connect privacy practices stated in a document to categories and themes ( Liu et al., 2016 ) . For example, Sarne et al. proposed an unsupervised method for classifying policy texts by using Latent Dirichlet Allocation (LDA) on 4,982 privacy policies ( Sarne et al., 2019 ) . LDA produced word clusters for a pre-set limit of 100 100 topics, and word probabilities concerning each topic were calculated. The topic with the highest probability is given to a paragraph after the topic probabilities for each word in the paragraph are added up. Although the 100 100 identified topics were found to cover only 36 36 specific subjects (through manual processing), the topic model analysis suggested the existence of more detailed categories beneath each high-level category compared to the annotations in the OPP-115 corpus.
Recent work in unsupervised classification attempts to leverage the power of LLMs in text analysis, and make inferences about a text segment’s privacy-specific category label. PolicyGPT is one such attempt where multiple LLM models were evaluated on their labeling accuracy against two human annotated corpus ( Tang et al., 2023 ) . The primary challenge here is to clearly establish the context of the task, which includes communicating the descriptions of the categories and engineering the prompts to guide the process. Models such as GPT4, even in a zero-shot configuration, demonstrated the potential to carry out the classification with reasonable accuracy; however, the performance can vary significantly across the data sets used for evaluation. Further, the efficacy of this approach in performing finer grain sentence classification is unknown.
We note that unsupervised classification of policy text segments is often stated as a method to obtain automated annotation on a large corpus of privacy policies ( Goknil et al., 2024 ) . However, in the absence of a subsequent process to evaluate the correctness of the assigned labels, the procedure is still subject to the usual concerns of precision and recall, and not to be used as ground truth in downstream tasks.
The task of splitting a given text data set into topically coherent pieces is known as an alignment or text segmentation. In order to improve user accessibility and comprehension, alignment seeks to generate parts where each segment only covers one topic. For the alignment of policy segments, an unsupervised model based on a hidden Markov model (HMM) may be used. The model’s parameters are virtually identical to those of a traditional HMM, except that each hidden state in the model corresponds to a topic and that emissions are represented by multinomial distributions rather than categorical ones ( Ramanath et al., 2014 ; Liu et al., 2014 ) .
5. Performance Evaluation & Extended Technical Observations IIIIIIII \mathsf{GRAPHSEG} is another technique that can be used to align sentences that are semantically connected to one another ( Glavaš et al., 2016 ) . A semantic relatedness graph is constructed in this method, where nodes represent sentences and edges are placed between nodes based on the cosine similarity of two sentences. Coherent segments are then identified using a maximal clique finding algorithm. This method does not assign predefined topical labels to text segments but instead attempts to identify sentences that elaborate on the same topic.
Word embedding (or representation) maps text into a continuous vector space with a fixed dimension. The assignment of a similar vector representation to related words is crucial in any natural language domain. Following the distributional notion that similar words tend to appear in similar situations, most embedding models are constructed for this purpose using co-occurrence statistics from sizable monolingual corpora. However, many NLP vectorizations regard words as atomic units represented as indices in a lexicon (for instance, one hot encoding) with no concept of word similarity. Representing the semantics of a text mathematically is still a challenge; word embedding techniques that can capture semantic, syntactic, and thematic information are still the subject of ongoing research. Nevertheless, the use of NLP in the privacy sector relies heavily on word embedding.
The most typical fixed-length vector form for texts is the bag-of-words or bag-of-n-grams ( Harris, 1954 ) . Since bag-of-words do not encode the word order, representations of distinct sentences can be identical. Furthermore, it has a high degree of dimensionality, and due to sparsity in the data, bag-of-words, and bag-of-n-grams essentially do not encode semantic information. A fundamental framework for learning vector representation using a recurrent neural network (RNN) was outlined by Bengio et al. ( Bengio et al., 2003 ) . The RNN was trained to predict the next word using the previous words as input. This strategy dramatically outperforms n-gram models ( Brown et al., 1992 ) and enables the use of lengthier contexts.
Furthermore, training a neural network on such vectorized word representations makes it possible to realize a more straightforward model to learn continuous word vectors. There are two architectures in this regard: the continuous bag-of-words model, which predicts the current word based on context, and the skip-gram model, which predicts surrounding words based on the current word. Using these architectures, embeddings are generated on large corpora using Word2Vec ( Mikolov et al., 2013 ) . Word2Vec has also been used to train privacy-specific word embeddings for extrinsic tasks such as question-answering, albeit the effectiveness of these word embeddings was not compared to generic word embeddings ( Sathyendra et al., 2017a ) .
Analysis of Word2Vec’s model features reveals fine-grained semantic and syntactic regularities, subsequently used to propose GloVe. This new global log-bilinear regression model combines global matrix factorization with local context window techniques ( Pennington et al., 2014 ) . In addition, GloVe uses globally aggregated word-word co-occurrence counts, while Word2Vec is guided by statistics of words that frequently occur besides a given term.
Using an extension of the continuous skip-gram model, another method is to learn representations for character n-grams and express words as the sum of the n-gram vectors. Consequently, this results in the inclusion of subword information in the process. By merging the vectors of each word’s constituent subwords, this model, known as FastText 1 1 1 https://github.com/facebookresearch/fastText , can be applied to words that are absent from the corpus ( Bojanowski et al., 2017 ) . FastText word embeddings trained with privacy policies outperform generic embeddings like GloVe ( Harkous et al., 2018 ; Kumar et al., 2019 ) . Furthermore, it was discovered that higher dimensional embeddings frequently yield better results than their lower dimensional counterparts. Despite requiring additional training time due to its higher order and a more significant number of dimensions, the higher order dimension may expressly capture interactions between words.
Recent advances in deep learning models using transformers-based mechanisms have produced effective models like BERT that accurately capture the contextual relationships between words and subwords ( Devlin et al., 2018 ; Vaswani et al., 2017 ) . An encoder reads the transformers’ text input, followed by a decoder that forecasts the task output. As the complete string of words is read at once, capturing both the left and right context of any word, BERT is inherently bidirectional in encapsulation contexts. However, autoregressive learning models, including BERT, are restricted to taking context into account either in a forward or a backward direction and not both at once. Permutation language modeling was the solution XLNet suggested for learning the bidirectional context ( Yang et al., 2019 ) . All token permutations are taken into account for any sequence of tokens. As a result, the model will learn to gather data from both forward and backward directions through permutation.
Another contextualized word representation, called Embeddings from Language Models (ELMo) ( Peters et al., 2018 ) , simulates words’ syntactic and semantic aspects that depend on their context. These word vectors are learned functions of a deep bidirectional language model’s internal states (biLM). Word-level embeddings are produced using a bi-directional LSTM (long short-term memory) using chara-cter-level tokens as inputs.
In policy classification for classes with a more significant number of examples, BERT performed admirably ( Kumar et al., 2019 ) . However, BERT performs worse for classes with fewer examples. This is in line with the findings of numerous NLP tasks, including question-answering and natural language inference. However, this reported behavior is from an off-the-shelf model trained on the OPP-115 corpus for three epochs, and no fine-tuning of any hyper-parameters for BERT was performed.
Nevertheless, a thorough exploratory investigation of the BERT model’s use in the field of privacy regulations may produce workable solutions for privacy-related applications. Prior research in information retrieval for privacy regulations has mainly relied on rule-based heuristics, which have limitations when addressing texts that do not follow a clear pattern. The majority of the effort involves extracting features from the text, such as dependency tree parsing, word occurrence statistics, and POS tags, and then applying a rule to the features to retrieve the necessary information. Because privacy-specific terminology is present, using a generic parser to analyze privacy messages results in incomplete information being captured. These methods also suffer from information retrieval saturation, which results in outcomes that are not full, as is the case with lexicons ( Bhatia and Breaux, 2015 ) .
Information retrieval tasks have been handled utilizing neural networks for natural language processing in different fields. Researchers have used CNNs to pinpoint occurrences, the arguments supporting those events, and the roles those arguments played in those events ( Chen et al., 2015 ) . There is also an RNN-based model to determine the cause of such incidents ( Nguyen et al., 2016 ) . An event schema can also be induced for open domain events using a latent variable neural model ( Liu et al., 2019 ) . Adopting neural network-based approaches for privacy policies may also overcome the limitations of a rule-based approach and be a possible direction for future research.
A similarity metric between the word vectors of a query and the segments is presently used in question-answering work to retrieve pertinent policy segments. As a result, the kind of embedding model used for the job significantly impacts the application’s performance. FastText-created domain-specific embedding outperformed generic embedding in terms of performance ( Harkous et al., 2018 ) . However, FastText is a static word embedding method, meaning that once it has been learned, the context is not altered by the embedding, and the embedding does not change across sentences. Since user inquiries are not restricted to a fixed format and given that a word’s representation might alter depending on the context in which it occurs, contextualized word embedding may lead to improved outcomes. Thus, exploring contextualized word embedding can positively contribute to building more efficient QA systems.
Even though HMM-based techniques outperformed topic models and clustering, text alignment is a computationally expensive job ( Ramanath et al., 2014 ; Misra et al., 2009 ; Glavaš et al., 2016 ) . However, categorizing phrases before alignment can still considerably boost performance. When employing classification to carry out an initial clustering, which might reduce the number of comparisons, Adhikari and Dewri demonstrated improvements in sentence matching ( Adhikari and Dewri, 2021 ) .
Similar intra-category alignment may also enhance the performance of current alignment techniques. Using categories also allows for parallelizing prediction tasks, dividing them, and aligning intra-categorically. Language modeling with neural networks has several benefits. However, contrary to commonly used n-gram language models, these networks use implicit smoothing. Because the full lexicon is projected onto a thin hidden layer, semantically related words cluster together. Although several studies have attempted to solve this issue, the time required to train such big models (with millions of parameters) is a recognized drawback of modern word representation models ( Levy et al., 2015 ) .
Without external resources, a linear post-processing transformation method can enhance the semantic and syntactic information encoded in the embedding, as demonstrated by intrinsic and extrinsic evaluation of similarity and relatedness for the changed embedding ( Artetxe et al., 2018 ) . Our investigation revealed that most NLP-based efforts were placed on categorizing policy contents into categories about privacy practices. Classification occasionally deals with different issues, such as ensuring compliance. Information extraction, summarization, question-answering, and alignment are all strategies that try to convey privacy-focused information to consumers in the most understandable way possible. The main issue with the current research trend is the separation of aims.
The ideal course would be to have a unified privacy framework that can enable categorization, summarization, alignment, question-answering, and information extraction on a shared basis. Automating a natural language policy into a machine-readable format is one way to achieve a common foundation supporting various NLP applications. Current research also focuses on developing technologies to make privacy policies usable across all business areas. Nevertheless, in practice, depending on the nature of the business, policies might vary considerably. For instance, privacy policies communicating practices of a social media organization are articulated differently than privacy policies referring to banking or financial domains. The performance of currently available tools is limited due to these differences in characteristics that still need to be addressed.
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website. Both individuals and organizations that work with arXivLabs have embraced and accepted our values of openness, community, excellence, and user data privacy. arXiv is committed to these values and only works with partners that adhere to them.
Have an idea for a project that will add value for arXiv's community? Learn more about arXivLabs . The number and dynamic nature of web and mobile applications presents significant challenges for assessing their compliance with data protection laws. In this context, symbolic and statistical Natural Language Processing (NLP) techniques have been employed for the automated analysis of these systems’ privacy policies. However, these techniques typically require labor-intensive and potentially error-prone manually annotated datasets for training and validation. This research proposes the application of Large Language Models (LLMs) as an alternative for effectively and efficiently extracting privacy practices from privacy policies at scale. Particularly, we leverage well-known LLMs such as ChatGPT and Llama 2, and offer guidance on the optimal design of prompts, parameters, and models, incorporating advanced strategies such as few-shot learning. We further illustrate its capability to detect detailed and varied privacy practices accurately. Using several renowned datasets in the domain as a benchmark, our evaluation validates its exceptional performance, achieving an F1 score exceeding 93%. Besides, it does so with reduced costs, faster processing times, and fewer technical knowledge requirements. Consequently, we advocate for LLM-based solutions as a sound alternative to traditional NLP techniques for the automated analysis of privacy policies at scale.
K eywords Large Language Models ⋅ \cdot Natural Language Processing ⋅ \cdot Privacy policies ⋅ \cdot Data protection ⋅ \cdot Privacy ⋅ \cdot Feature extraction The digital era has led to an unprecedented expansion of web and mobile applications and a myriad of online services. This growth is a testament to technological advancement and the increasing reliance of businesses and organizations on digital platforms for various operations. A central aspect of this digital proliferation is the extensive use of technologies for personal data collection, primarily driven by the objective of enhancing targeted marketing strategies. The ability to collect, analyze, and utilize user data has become a cornerstone of modern commerce, offering businesses invaluable insights into consumer behavior and preferences.
However, the increasing collection and utilization of personal data have raised significant privacy concerns. Users’ privacy is at risk as their data becomes valuable in the digital marketplace. This concern has led to the emergence of regulatory bodies and the formulation of data protection legislation aimed at safeguarding user privacy. These legislations, such as the General Data Protection Regulation (GDPR) in the European Union and the California Consumer Privacy Act (CCPA) in the United States, impose stringent requirements on how organizations should handle personal data.
Ensuring compliance with these legislations, however, poses a formidable challenge. The overgrowth of online services, compounded by globalization, makes it impractical, if not impossible, for regulators to manually assess each service’s adherence to privacy laws. This situation is further exacerbated by the dynamic nature of online services, where data processing practices and the privacy policies disclosing them are subject to frequent changes [ 1 ] . In response to these challenges, automated-driven methods have been proposed for analyzing privacy policies at scale [ 2 ] . This approach holds the potential for research endeavors aimed at understanding and highlighting privacy concerns, and it also offers a practical tool for regulators to conduct mass evaluations of applications and services, thereby promoting a higher level of compliance with privacy regulations.
The automated analysis of privacy policies has leveraged Natural Language Processing (NLP) techniques [ 2 ] . Symbolic and statistical state-of-the-art NLP techniques are proposed to address this task, although each has drawbacks. Symbolic approaches rely on pre-defined rules, leading to lower performance when compared to statistical approaches due to the lack of adaptability to differences present in legal texts. Thus, state-of-the-art research has predominantly relied on statistical approaches such as machine learning (ML) techniques, and particularly supervised learning models, to train and evaluate models identifying privacy practice disclosures such as personal data collection or sharing [ 3 ] . These models require the use of manually annotated datasets [ 4 , 5 , 6 ] , which are often expensive, time-consuming to create, and prone to errors [ 7 ] .
Furthermore, building and training those models require advanced technical expertise, contributing to a higher barrier to entry. As a result, their practical application is mainly suitable for large-scale projects where the benefits can outweigh these significant costs. On the other hand, modern Generative Artificial Intelligence (GenAI), particularly Large Language Models (LLMs), represents a significant advancement in the NLP domain, being able to understand and generate human-like text, making it particularly well-suited for parsing and analyzing the complex language present in privacy policies without needing annotated datasets. In this context, this paper proposes the application of LLMs for the effective and efficient extraction of privacy practices from privacy policies. In particular, we focus on ChatGPT, which relies on Generative Pre-trained Transformer (GPT) models.
Harvested Online Documentation & Reference Sources • https://github.com/BalashanmugamK/Privacy-Policy-Risk-Analyzer • https://github.com/VETRI11K/TermsBuster---Smart-Privacy-Policy-Assistant • https://github.com/Amirtha277/AI-Based-Privacy-Risk-Policy-Analyzer • https://arxiv.org/html/2501.10319v1 • https://arxiv.org/abs/2309.10238 • https://arxiv.org/html/2405.20900v1
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Privacy Policy Summarizer And Risk Analyzer Using Nlp.
[*] Metasploit Scan Running on Target Subnet for Privacy Policy Summarizer And Risk Analyzer Using Nlp... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |