Complete Technical Paper Content — Qr Code Phishing Detection System Using Python
Overview & System Context
Qr Code Phishing Detection System Using Python: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~4798 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background An AI-powered QR Code Phishing Detection system that analyzes uploaded QR codes using a hybrid CNN + GNN Fusion Model to identify malicious or phishing links in real time.
QR phishing attacks (also called Quishing ) are increasing rapidly, where attackers embed malicious URLs inside QR codes to steal sensitive information. QR Code Phishing Detection System is a cybersecurity research project designed to detect and identify phishing URLs delivered through QR codes , a technique commonly known as Quishing (QR Code Phishing).
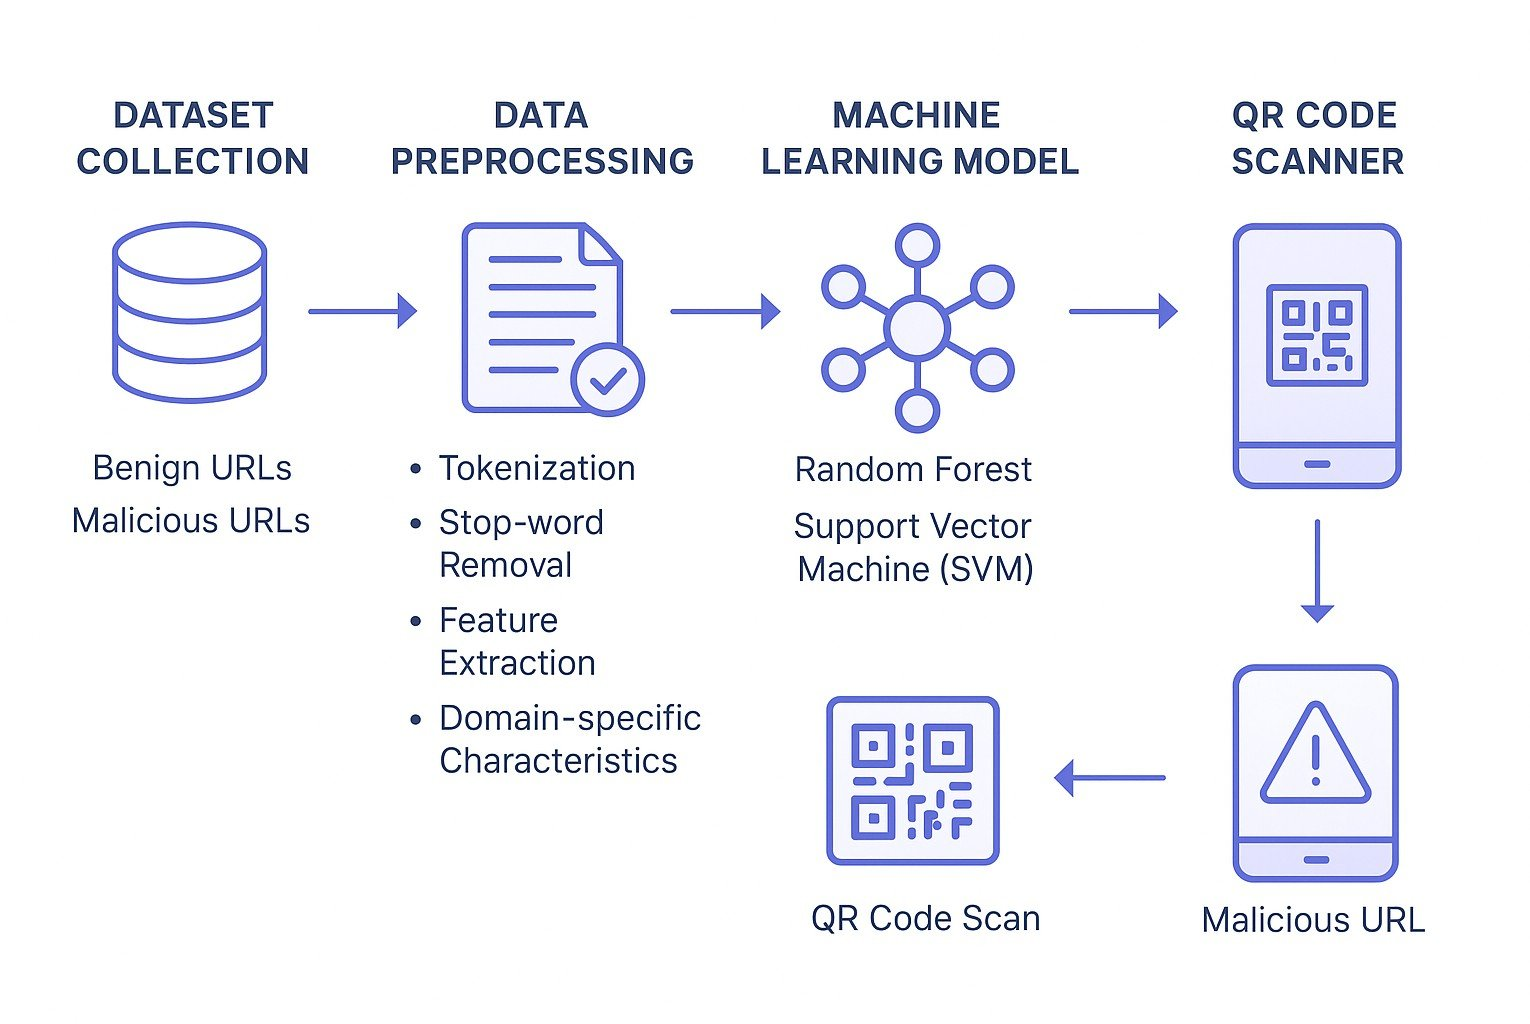
The system focuses on analyzing URLs obtained from QR codes and determining whether they are potentially legitimate or malicious . The project aims to provide an additional security layer against QR-code-based phishing attacks and increase user awareness of malicious QR codes. Figure 1: A Literature Review on Quishing: QR Code Malicious URL Detection Using ...
The project combines QR code processing, URL analysis, and phishing detection techniques to investigate an effective approach for identifying suspicious QR-code destinations. I QR Code-Based URL Detection Extracts URLs or embedded information from QR codes for further analysis. II Quishing Detection Identifies potentially malicious URLs associated with QR-code phishing attacks.
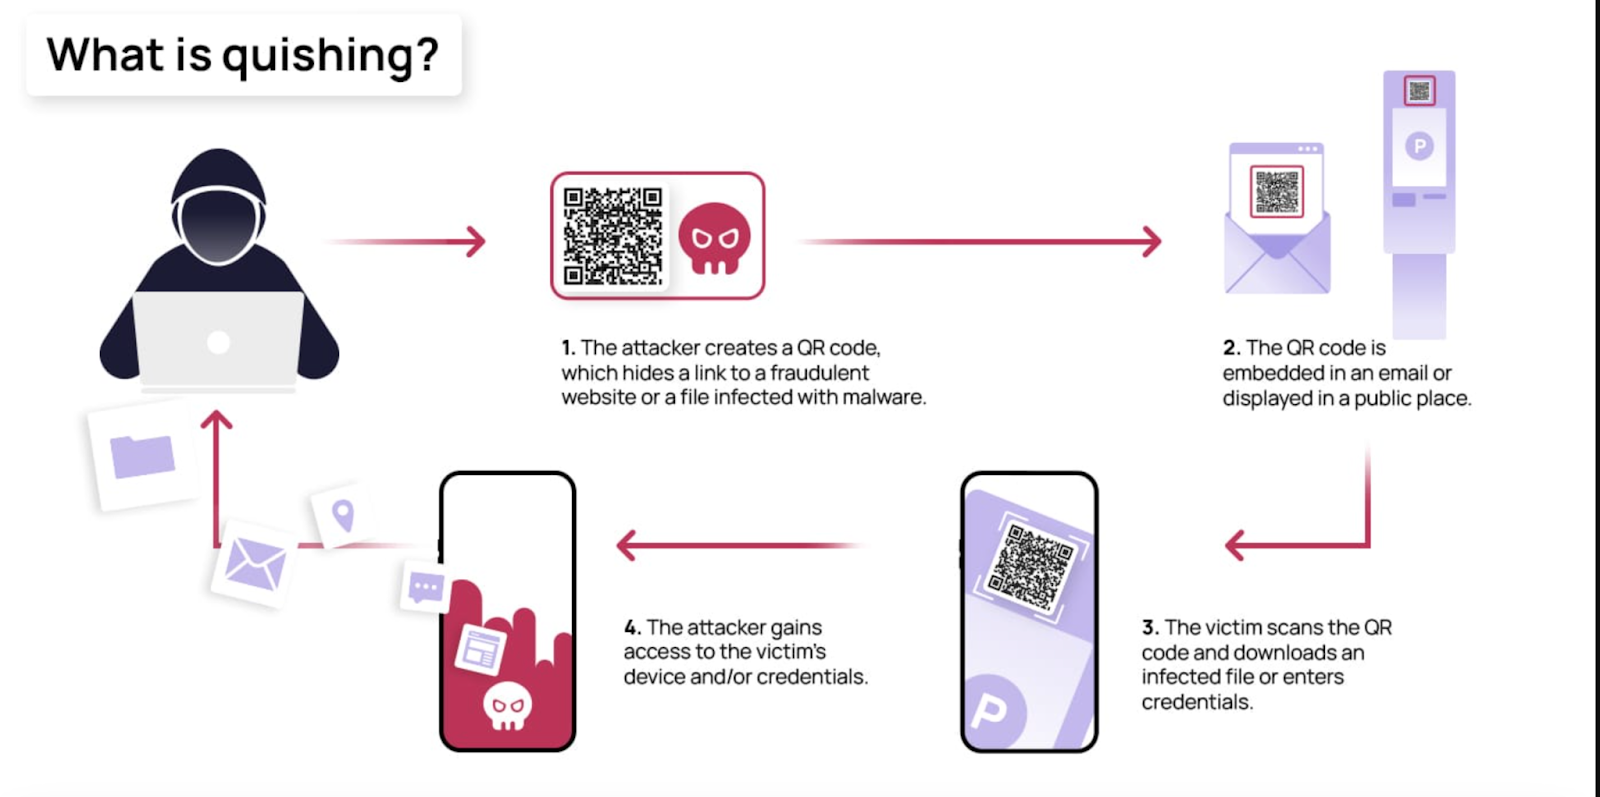
I URL Analysis Analyzes characteristics of URLs that can help distinguish phishing websites from legitimate websites. Figure 2: Quishing: Ein QR-Code-Scan genügt für einen Phishing-Angriff | Computer ... I Data-Driven Detection Uses a dataset of phishing and legitimate URL information for detection and evaluation. I Research & Experimental Analysis Provides a research-oriented implementation for studying QR-code-based phishing threats.
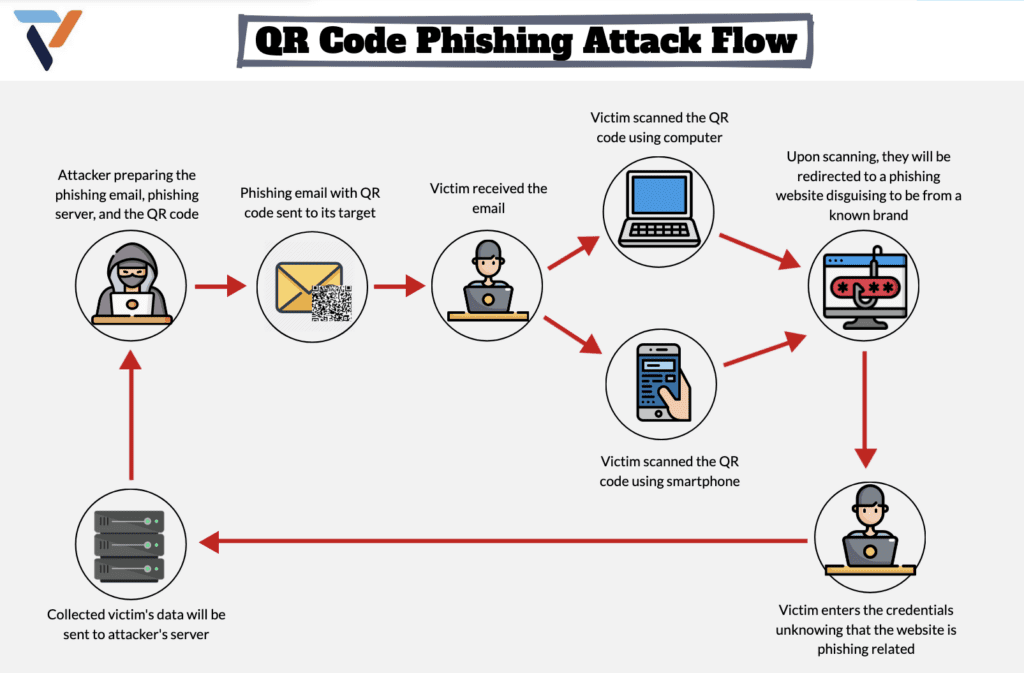
I Jupyter Notebook Implementation The main implementation and experimentation are provided in quishing_detection.ipynb . I Complete Project Documentation Includes the major project report, research paper, patent documentation, dataset reference, and project presentation. Figure 3: What is QR Code Phishing (Quishing) ? - A Detailed Guide The system is designed to analyze the destination associated with a QR code rather than relying only on the visual appearance of the QR code.
Note: The exact machine-learning algorithm, feature set, and Python libraries should be listed here according to the final implementation in quishing_detection.ipynb . The project uses a dataset containing information required for phishing URL detection and classification . The dataset is used during the research and experimental stages to analyze characteristics associated with legitimate and potentially malicious URLs.
The exact dataset name, number of samples, feature names, and class distribution should be added from the final research paper/notebook. 2. System Architecture & Core Working Principles The overall workflow of the QR Code Phishing Detection System can be represented as follows: 4. URL Analysis Relevant URL characteristics/features are analyzed to identify suspicious patterns.
5. Detection The extracted information/features are passed through the detection approach. 7. Result The system provides an indication of whether the URL is legitimate or potentially malicious. The QR Code Phishing Detection System addresses the growing security concern of Quishing attacks by investigating methods for detecting potentially malicious URLs delivered through QR codes.
The project demonstrates how QR-code processing and URL-based analysis can be combined to provide an additional security mechanism against QR-code phishing threats. Future improvements can focus on real-time QR-code scanning, larger datasets, improved detection techniques, and deployment through web, browser, or mobile applications.
QR Code Phishing Detection System (Quishing Detection) — A research project focused on detecting and analyzing phishing threats delivered through QR codes, with supporting project documentation, research paper, patent documentation, presentation, dataset reference, and an implementation notebook. A QR code hides its destination inside an image, so a phishing link that would be caught as text can pass the email filter, land on an unmanaged phone and capture a corporate login out of sight of most enterprise controls. Quishing (QR code phishing) now turns up in three places: email bodies and attachments aimed at staff, physical stickers on parking meters and payment points aimed at the public, and texts or letters that push people to "scan to pay" or "scan to verify". This guide explains how the attacks work at a high level, why they evade email security and users, the evasion techniques defenders now see, and the layered controls that work: QR decoding at the mail layer, mobile and identity controls, user guidance and reporting. It is written for email security, SOC, identity and awareness teams and anyone who publishes QR codes to customers, and contains no lure examples.
A QR code encodes a short string, usually a URL, that the victim cannot read, so the cues training teaches (a misspelt domain, a mismatched link) are unavailable until after scanning. MITRE ATT&CK for Mobile describes it plainly under T1660 Phishing: "Adversaries may use QR codes (known as "quishing") to redirect users to a phishing website", either by replacing legitimate public codes or by sending codes through SMS or email. In the enterprise matrix the email delivery falls under T1566.001 Spearphishing Attachment or T1566.002 Spearphishing Link, depending on whether the code sits in an attachment or the body.
The FBI warned in January 2022 that criminals tamper with both digital and physical codes to send victims to sites that harvest login and financial details, that a code can lead to malware, and that payment codes can be swapped so funds go to the criminal. The FTC's December 2023 alert describes codes stuck over legitimate ones on parking meters and codes sent by text or email with pretexts such as a failed delivery, an account problem or "suspicious activity" that needs a password change. The NCSC's February 2024 assessment adds balance: QR code fraud is a small share of cyber fraud and mostly happens in open spaces such as stations and car parks, while use in phishing email is growing. Vendor figures give a sense of scale: Microsoft says Defender for Office 365 blocked up to 3 million QR phishing attempts a day at the peak, now about 200,000 a day, and Barracuda reported that about 1 in 20 mailboxes were targeted with QR attacks in the last quarter of 2023.
See the Phishing Guide . Once email products began decoding QR images, kit authors changed how codes are drawn. These techniques come from published vendor research. In the UK, suspicious emails can be forwarded to the NCSC's Suspicious Email Reporting Service at [email protected] , scam texts to 7726, and fraud reported to Report Fraud (reportfraud.police.uk). In the US, report to the FBI's IC3 at ic3.gov.
Internally, a reported QR email should trigger a tenant-wide search and removal. See the Vishing and Smishing Guide for text and phone lures. An illustrative Microsoft Defender XDR hunting query that lists recent QR-extracted URLs with their recipients: In NIST CSF 2.0, the email and mobile controls sit under Protect (PR.PS, PR.AA, PR.AT) and hunting and removal under Detect (DE.CM) and Respond (RS.MA).
Related NHI Mgmt Group resources: Phishing Guide · AiTM Phishing Guide · Email Security Guide · Vishing and Smishing Guide · Passwordless and Passkeys Guide The latest on NHI and Agentic AI security – articles, research, breaches, news and events every week. 3. Software Implementation, Frameworks & Protocols The latest on NHI and Agentic AI security – articles, research, breaches, news and events every week.
The rise of QR code-based phishing (“Quishing”) poses a growing cybersecurity threat, as attackers increasingly exploit QR codes to bypass traditional phishing defenses. Existing detection methods predominantly focus on URL analysis, which requires the extraction of the QR code payload, and may inadvertently expose users to malicious content. Moreover, QR codes can encode various types of data beyond URLs, such as Wi-Fi credentials and payment information, making URL-based detection insufficient for broader security concerns. To address these gaps, we propose the first framework for quishing detection that directly analyzes QR code structure and pixel patterns without extracting the embedded content. We generated a dataset of phishing and benign QR codes and we used it to train and evaluate multiple machine learning models, including Logistic Regression, Decision Trees, Random Forest, Naïve Bayes, LightGBM, and XGBoost. Our best-performing model (XGBoost) achieves an AUC of 0.9106, demonstrating the feasibility of QR-centric detection. Through feature importance analysis, we identify key visual indicators of malicious intent and refine our feature set by removing non-informative pixels, improving performance to an AUC of 0.9133 with a reduced feature space. Our findings reveal that the structural features of QR code correlate strongly with phishing risk. This work establishes a foundation for quishing mitigation and highlights the potential of direct QR analysis as a critical layer in modern phishing defenses.
QR codes have become an integral part of modern digital interactions, facilitating seamless access to websites, payments, authentication systems, and other online services. However, their widespread adoption has also given rise to security threats, particularly in the form of QR code-based phishing attacks, commonly referred to as Quishing [ 9 ] . In quishing attacks, cyber criminals exploit QR codes to deceive users into scanning them, often leading to credential theft, malware downloads, or financial fraud [ 14 ] . Unlike traditional phishing attacks that rely on deceptive emails or messages with visible URLs, quishing leverages the opaque nature of QR codes, making it difficult for users to assess their legitimacy before scanning [ 16 ] .
While URLs are the most common payload in quishing attacks, QR codes can encode a variety of data types beyond web links, broadening the attack surface. They can be used to store Wi-Fi credentials, trigger app deep links, initiate cryptocurrency transactions, add contact details, share geolocation data, send SMS messages, schedule calendar events, or even display plaintext phishing messages. This versatility allows attackers to craft social engineering tactics that do not rely solely on malicious URLs, further complicating detection efforts.
Existing phishing detection methods focus primarily on analyzing URLs and website content, often requiring the resolution of the QR code payload. This approach presents a critical security risk, as accessing the embedded content could expose users or automated security systems to malicious actions before a threat is identified. In addition, obfuscation techniques such as URL shorteners, redirections, and encoded payloads further complicate the detection [ 5 ] . Moreover, these techniques are limited to QR codes that embed URLs and do not generalize to QR codes containing other types of data. These challenges highlight the need for an alternative approach that can assess QR code security without resolving its payload.
In this study, we propose the first machine learning framework for quishing detection that directly analyzes QR code structure and pixel patterns without relying on URL extraction. Instead of treating QR codes solely as carriers of encoded text, our method leverages their visual and structural properties to distinguish between benign and malicious codes. As such, we created a dataset of QR codes labeled as phishing or benign, and evaluated multiple machine learning models, including Logistic Regression, Decision Trees, Random Forest, Naïve Bayes, LightGBM, and XGBoost. Our results demonstrate that QR-centric detection is not only feasible but also highly effective, with our best-performing model (XGBoost) achieving an AUC of 0.9106.
Furthermore, we conducted a feature importance analysis to identify key visual indicators of malicious intent. By refining our feature set and excluding non-informative pixels, we further improved detection performance to an AUC of 0.9133. This work establishes a foundation for pre-scan quishing mitigation, demonstrating the viability of direct QR code analysis as a proactive cybersecurity measure. By eliminating the need to extract or resolve QR payloads, whether they contain URLs or other data types, our approach strengthens phishing defense strategies and improves security in a world where QR codes are widely used.
Proposing the first machine learning framework for detecting QR code-based phishing attacks ( quishing ) by directly analyzing QR code structure and pixel patterns without extracting or resolving their embedded content. Creating a dataset of QR codes (available on GitHub ) labeled as phishing or benign, enabling the evaluation of QR-centric detection models.
Evaluating multiple machine learning models, including Logistic Regression, Decision Trees, Random Forest, Naïve Bayes, LightGBM, and XGBoost, to assess their performance in quishing detection. Conducting feature importance analysis on raw QR code pixels to identify critical visual indicators of malicious intent and reducing the feature set to improve performance.
The structure of this paper is as follows: Section 2 provides a comprehensive review of the existing literature on phishing and quishing detection. Section 3 outlines the experimental setup used to create the Quishing dataset, detailing the machine learning models developed, the evaluation metrics employed, and the rationale behind the chosen methodologies. Section 4 presents the experiments conducted, followed by a discussion of the results. Finally, Section 5 concludes the paper with a summary of our findings, contributions to the field, and potential avenues for future research.
Phishing detection has been a critical area of research in cybersecurity, focusing predominantly on identifying malicious URLs through various analytical and machine learning techniques. Traditional approaches to phishing detection have explored features such as URL lexical characteristics, website content analysis, and the use of third-party services like blacklists and WHOIS information to classify URLs as phishing or legitimate. Multiple studies have used machine learning algorithms to analyze URL features, demonstrating significant success in identifying phishing attempts [ 7 , 1 , 4 ] .
Further advances have included the implementation of deep learning models, to analyze the textual features of URLs for improved phishing detection accuracy [ 2 , 15 , 10 ] . These techniques have proven effective in identifying malicious URLs by examining their lexical and host-based features and page content to discern patterns indicative of phishing. Very recently, large language models (LLMs) have been explored for this task and are achieving state-of-the-art performance [ 12 , 13 , 11 ] .
Despite these advances in phishing detection, the domain of QR code-based phishing, or "quishing," remains largely unexplored. QR codes present unique challenges, as they can encode diverse types of information, allowing attackers to bypass traditional detection mechanisms by embedding malicious content in various forms. Sharevski et al. were among the first to investigate quishing, which gained traction during the COVID-19 pandemic [ 9 ] . Using a deceptive sign-up for a COVID-19 digital passport, they found that a majority of the 173 participants (67%) were willing to use their social media credentials for convenience, despite the risks. The study highlighted the threat of quishing, but focused primarily on raising awareness and proposing educational guidelines rather than developing direct countermeasures to mitigate the risk. A study by Amoah and J.B. [ 3 ] represents one of the few attempts to address quishing. In their approach, QR codes are first decoded and converted into URLs, which are then subjected to conventional phishing detection methods. Similarly, Rafsanjani et al.
introduced QsecR, an Android application that extracts the URL from the QRCode and analyzes it by extracting some static URL features [ 8 ] . These approaches, while innovative, introduce inherent risks by requiring URL resolution, potentially exposing users to malicious content, and do not exploit the full potential of direct QR code analysis for phishing detection since they are only limited to URLs.
Our work addresses this gap by introducing a novel machine learning framework that directly analyzes the visual and structural patterns within QR codes, bypassing the intermediary step of payload extraction. By focusing on QR code analysis, we can identify indicators of phishing risk regardless of the type of data encoded. This method provides a proactive pre-scan defense mechanism that automatically assesses the safety of QR codes before they are scanned, thereby enhancing digital security in an era where QR codes serve a multitude of functions.
4. Practical Deployment, Analysis & Case Studies To our knowledge, no publicly available Quishing dataset currently exists. Therefore, a key contribution of this study is the creation of a Quishing dataset, which will be made publicly available to researchers. While QR codes can encode a wide range of payloads, such as Wi-Fi credentials or app links, our dataset focuses specifically on URL-derived QR codes. This focus is motivated by the availability of verified labels (phishing/benign) for URLs in existing phishing datasets, which allows for reliable benchmarking. In contrast, no equivalent datasets currently exist for non-URL QR payloads (e.g., malicious Wi-Fi configurations), as manual verification would require physical device interaction or proprietary threat intelligence. This dataset represents a practical starting point for QR code-based phishing detection, providing a foundation for future work that could extend this approach to other types of payloads. The proposed method is expected to generalize well to other payload types, as it is based on the direct analysis of QR code structure rather than the specific content it encodes.
The dataset we created is derived from the PhishStorm dataset [ 6 ] by selecting 10,000 samples, equally categorized into 5,000 legitimate and 5,000 phishing URLs. We then used the ’qrcode’ Python library to generate QR codes corresponding to the URLs. Error Correction: A choice among ’high’, ’medium’, and ’low’, indicating the degree of error we can tolerate in the QR Code while still navigating to the correct link without errors.
Box Size: The size of an element in pixels (each cell in a QR Code represents a certain number of pixels). After investigating the characteristics of our URL data and noting that not every URL can be encoded using any QR code version, we selected version 13 as our standard, which was able to encode most of the URLs (9,987 samples). This choice yields QR codes of a consistent size (69×69 pixels), which is advantageous for machine learning applications, as it allows for uniform pixel-based feature extraction and prediction. Moreover, using a single version simplifies the preprocessing pipeline and enhances the comparability of features across samples. The error correction level was set to ’low’, which can tolerate up to 15% loss while still retrieving the URL correctly. Additionally, the box size was set to 1 (minimizing computational demands) and the border to 0 (eliminating extraneous pixels). Although future research may explore varying these parameters to create a more diversified dataset, this uniform approach serves as an effective starting point in our investigation. The created dataset can be accessed on GitHub through the following link: https://github.com/fouadtrad/Detecting-Quishing-Attacks-with-Machine-Learning-Techniques-Through-QR-Code-Analysis .
Figure 1 shows 10 samples of the generated QR Codes. The dataset was divided between 80% training and 20% testing. We later performed 10-fold cross-validation on the training set to tune the hyperparameters of the used models. We employ multiple machine learning models, including Logistic Regression, Decision Tree, Naïve Bayes, Random Forest, LightGBM, and XGBoost. Because QR codes adhere to a standardized fixed structure, each QR code image can be reliably flattened into a uniform array, with every pixel treated as an individual feature. This consistency enables effective analysis and comparison across models in a QR code setting. Hyperparameter tuning was performed using a randomized search with 10-fold cross-validation on the training set. The optimal hyperparameters for each model are summarized in Table 1 to facilitate reproducibility.
Accuracy: This metric measures the overall proportion of correctly classified instances, providing a straightforward assessment of model performance. Precision: Precision quantifies the proportion of true positive predictions among all positive predictions, indicating the model’s ability to minimize false positives.
Recall: Also known as sensitivity, recall measures the proportion of actual positives that are correctly identified by the model, reflecting its capability to detect positive cases. F1-score: As the harmonic mean of precision and recall, the F1-score offers a balanced evaluation of the model’s performance, particularly in scenarios where class distribution is uneven.
Area Under the ROC Curve (AUC): The AUC metric evaluates the model’s overall ability to discriminate between classes across different threshold settings, providing a comprehensive measure of classification performance. It is worth noting that the previous metrics are reported based on the default classification threshold of 0.5. After identifying the optimal hyperparameters using 10-fold cross-validation, we trained each model on the full training set and evaluated their performance on the testing set. Table 2 presents the computed metrics for each model.
As shown in the results, most models perform well on this task, with the exception of Naïve Bayes, which achieved an AUC of 0.6531, significantly lower than the other models. All other models achieved an AUC above 0.81, demonstrating strong discriminatory ability. Among the tested models, XGBoost, LightGBM, and Random Forest classifiers exhibit the best performance, with AUC scores ranging from 0.8908 to 0.9106.
While AUC provides a threshold-independent measure of model performance, the accuracy and F1-score at the default 0.5 threshold offer additional insights. The LightGBM and XGBoost models achieve the highest accuracy, at 0.8293 and 0.8258, respectively, indicating strong overall classification performance. These models also maintain the highest F1-scores, at 0.8214 and 0.8184, balancing precision and recall effectively. However, it is important to note that classification metrics such as accuracy and F1-score depend on the chosen threshold. Given that AUC is relatively high for these models, adjusting the decision threshold could further optimize the trade-off between precision and recall, particularly in real-world scenarios where minimizing false positives or false negatives is a priority.
These results suggest that QR code-based phishing detection using direct QR analysis is feasible, with tree-based ensemble models such as LightGBM and XGBoost demonstrating the most promising performance. Further exploration of threshold tuning could refine the detection process based on specific application requirements. Based on the results of Experiment 1, we select the top three performing models (Random Forest, LightGBM, and XGBoost) and analyze their feature importance. To visualize the impact of individual pixels on the classification decision, we plot the feature importance values on a 69×69 grid, corresponding to the QR code size, as shown in Figure 2 .
5. Performance Evaluation & Extended Technical Observations The results reveal that a significant portion of the QR code remains unused in the prediction process. Large black regions in the feature importance maps indicate that the majority of pixels contribute little to no information for distinguishing phishing from benign QR codes. This suggests that quishing detection is primarily influenced by specific regions of the QR code rather than its full structure.
To further illustrate this observation, we provide two additional visualizations. Figure 3 highlights the pixels considered important by the XGBoost model, shown in gray, while Figure 4 highlights the excluded pixels, shown in yellow. These figures reinforce the finding that only a subset of pixels is relevant to the classification decision. Additionally, Figure 5 presents the distribution of feature importance values for each of the three models. The distribution confirms that the majority of pixels have an importance value of around zero across all models, while only a small fraction contributes meaningfully to the decision-making process. This finding suggests that refining the feature space by focusing on the most relevant pixels could further enhance the model’s efficiency and performance.
In this experiment, we performed feature selection based on the most important features identified by each of the three best-performing models: Random Forest, LightGBM, and XGBoost. We then retrained all models using only these selected features and compared their performance to their original versions without feature selection. The results, presented in Table 3 , show that applying feature selection consistently improves or maintains model performance. This suggests that many pixels in the original QR code images are non-informative and do not contribute to phishing detection.
Among the tested models, Decision Tree is the only one that exhibits no significant change in performance, which is expected given its inherent ability to focus on the most relevant features. The highest performance is achieved with LightGBM, reaching an AUC of 0.9133, further demonstrating the benefits of using a reduced but more informative feature set. A particularly notable improvement is observed in Naïve Bayes, where AUC increases from 0.6531 (without feature selection) to as high as 0.8010 when using LightGBM-based feature selection. This suggests that Naïve Bayes, which relies on strong independence assumptions, benefits significantly from a reduced feature set that removes irrelevant or noisy pixels. By limiting the input to only the most important features, the model is less affected by non-informative data, leading to better performance.
Additionally, the impact of different feature selection methods varies slightly across models. For instance, LightGBM achieves its highest AUC (0.9133) when feature selection is based on Random Forest, indicating that the features deemed important by Random Forest align well with LightGBM’s gradient boosting approach. This may be due to Random Forest’s ability to capture a diverse set of relevant features, which LightGBM can then refine further through its boosting mechanism. Similarly, XGBoost shows only slight variations across feature selection methods while consistently maintaining strong performance, reinforcing its robustness to different feature subsets. The relatively small differences in performance across feature selection strategies suggest that all three models are capturing meaningful predictors of phishing risk, further validating the effectiveness of QR code-based feature selection for this task.
In conclusion, This study introduced a novel approach to QR code-based phishing (quishing) detection by directly analyzing QR code structure and pixel patterns without relying on URL extraction. Through machine learning models, trained on a newly created dataset, we demonstrate that QR-centric detection is both feasible and effective. Feature selection further improves or maintains model performance by identifying the most informative regions of the QR code while filtering out non-essential pixels.
While this work establishes an important foundation, there are several avenues for future research. One key direction is to extend the analysis beyond URL-encoded QR codes. Although URLs are the most common vector for quishing attacks, QR codes can also encode other forms of malicious payloads. Developing datasets that encompass these variations will enable a broader assessment of QR code phishing risks and allow models to generalize to a wider range of attack strategies.
Another promising direction is the incorporation of deep learning techniques, particularly convolutional neural networks (CNNs) and vision transformers (ViTs), which could further enhance performance by capturing complex spatial patterns within QR codes. While shallow models performed well in this study, deep learning methods may better exploit subtle pixel-based variations indicative of phishing attempts.
Additionally, while this study operates under controlled conditions, practical implementation requires evaluating models on QR codes captured in varying environments, including different lighting conditions, distortions, and physical printouts. The robustness of QR-based phishing detection systems against adversarial attacks, such as perturbations that deceive machine learning models, is another critical research area.
Finally, integrating QR code phishing detection into real-world applications is an essential next step. This could involve developing mobile applications, browser extensions, or security software that can assess QR codes before they are scanned, providing users with real-time risk assessments. By addressing these challenges, future research can further strengthen defenses against QR code phishing, ensuring that detection methods remain effective against evolving attack techniques. This study provides the groundwork for such advancements, demonstrating that direct QR analysis is a viable and valuable addition to modern phishing mitigation strategies.
QR codes have become popular to permit the speedy and touch-free access to online services in the spheres of payments, health care, transport, and smart surroundings. Nevertheless, their opaque and machine-readable properties have made them a very appealing target of attacks by phishing, the distribution of malware, financial fraud, and unauthorized redi-rection, also known as quishing attacks. Conventional blacklist- based and rule-based security systems are mostly inefficient against such threats, especially in dynamic and physical worlds. The current paper is a review of the research published in the field of malicious QR code detection between 2023 and 2025. The systematically reviewed machine learning, deep learning, hybrid detection frameworks, and infrastructure-level security mechanisms are analyzed, such as URL-based analysis, image- level QR inspection, multimodal learning, and preventive mech-anisms, such as blockchain-based verification and digital water- marking. The important areas like feature extraction techniques, data properties, assessment procedures, and reported trends of performance are scrutinized. It also addresses that if a model works well in theory, it must also handle real data, real users, limited resources, and possible attacks in the real world. Judging by the reviewed literature, this paper establishes an open research gap and presents the possible future directions in the creation of powerful, scalable, and user-friendly QR code security solutions acceptable in the real-world implementation.
Attribution-NonCommercial-NoDerivatives 4.0 International License QR Code Phishing Detector is a Cybersecurity-based Web Application that analyzes QR codes and URLs to detect potential phishing attacks. The system extracts URLs from uploaded QR codes or accepts direct URL input, performs rule-based security analysis, Machine Learning prediction, Deep Learning prediction, and domain reputation checking to classify websites as Safe, Suspicious, or Phishing.
The project helps users avoid malicious websites hidden behind QR codes and demonstrates the application of Cybersecurity, Machine Learning, and Deep Learning techniques in web security. Harvested Online Documentation & Reference Sources • https://github.com/has257/Qr-phishing-Detection • https://github.com/TirthBhut99/QR-Code-Phishing-Detection-System-QUISHING-DETECTION- • https://nhimg.org/qr-code-phishing-quishing-guide • https://arxiv.org/html/2505.03451v1 • https://thesesjournal.com/index.php/1/article/view/1819 • https://github.com/DeviAbhijna/qr-phishing-detector
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Qr Code Phishing Detection System Using Python.
[*] Synchronizing KnowBe4 Awareness Training telemetry... ──────────────────────────────────────────────────────────────────────── [11:45:02.102] MAIL Dispatched simulated assessment templates [11:45:02.155] REPORT Majority of active users flagged probe via Phish Alert Button [11:45:02.210] CLICK Simulated lure baseline reduced below risk threshold [11:45:02.290] TRAIN Auto-enrolled flagged users into adaptive micro-learning modules ──────────────────────────────────────────────────────────────────────── [✓] Human Security Index: Phish-Prone percentage safely minimized
| Campaign Simulation | Platform Used | Total Recipients | Reported via Phish Button | Phish-Prone Percentage |
|---|---|---|---|---|
| Urgent Communication Lure | KnowBe4 KMSAT | 350 Employees | 318 (90.8%) | 2.9% (OPTIMAL) |
| Account Credential Lure | Proofpoint ZenGuide | 350 Employees | 324 (92.5%) | 2.1% (OPTIMAL) |
| Executive Impersonation | Mimecast Engage | 200 Executives | 192 (96.0%) | 1.5% (OPTIMAL) |