Complete Technical Paper Content — Searchable Encryption System For Secure Database Search
Overview & System Context
Searchable Encryption System For Secure Database Search: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9523 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Database encryption can generally be defined as a process that uses an algorithm to transform data stored in a database into "cipher text" that is incomprehensible without first being decrypted. It can therefore be said that the purpose of database encryption is to protect the data stored in a database from being accessed by individuals with potentially "malicious" intentions. The act of encrypting a database also reduces the incentive for individuals to hack the aforementioned database as "meaningless" encrypted data adds extra steps for hackers to retrieve the data. There are multiple techniques and technologies available for database encryption, the most important of which will be detailed in this article.
Traditional database encryption techniques normally encrypt and decrypt the contents of a database. Databases are managed by "Database Management Systems" (DBMS) that run on top of an existing operating system (OS). This raises a potential security concern, as an encrypted database may be running on an accessible and potentially vulnerable operating system. EFS can encrypt data that is not part of a database system, which implies that the scope of encryption for EFS is much wider when compared to a system such as TDE that is only capable of encrypting database files. Whilst EFS does widen the scope of encryption, it also decreases database performance and can cause administration issues as system administrators require operating system access to use EFS. Due to the issues concerning performance, EFS is not typically used in database applications that require frequent database input and output. In order to offset the performance issues it is often recommended that EFS systems be used in environments with few users.
Searchable encryption enables you to search encrypted records without decrypting the entire database. This is accomplished using beacons , which create a map between the plaintext value written to a field and the encrypted value that is actually stored in your database. The AWS Database Encryption SDK stores the beacon in a new field that it adds to the record. Depending on the type of beacon you use, you can perform exact match searches or more customized complex queries on your encrypted data.
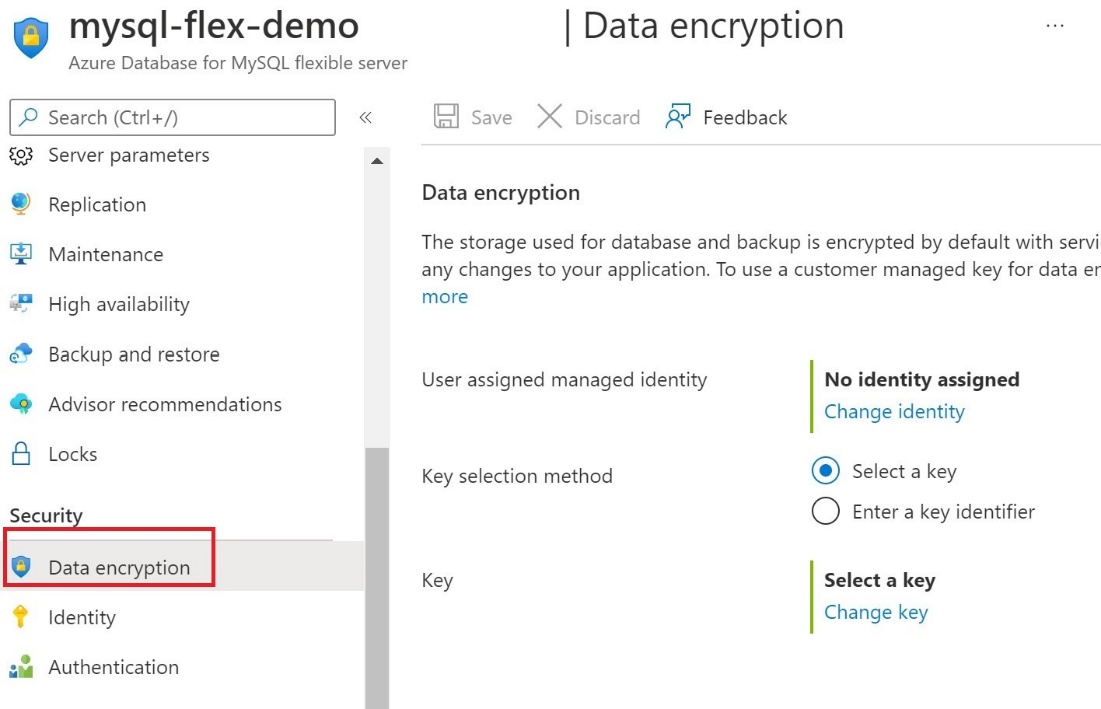
Searchable encryption in the AWS Database Encryption SDK differs from the searchable symmetric encryption defined in academic research, such as searchable symmetric encryption . Figure 1: Set up Data Encryption by Using the Azure Portal - Azure Database for ... A beacon is a truncated Hash-Based Message Authentication Code (HMAC) tag that maps a plaintext field value to an encrypted, searchable identifier. When you write a value to an encrypted field configured for searchable encryption, the AWS Database Encryption SDK computes an HMAC over the plaintext value. This HMAC output is a oneâIItoâIIone (1:1) match for the plaintext value of that field. The SDK intentionally truncates the HMAC output so that multiple distinct plaintext values collide on the same beacon. These collisions (false positives) limit an unauthorized userâIIs ability to infer sensitive information from frequency patterns. When you query a beacon, the AWS Database Encryption SDK automatically filters out these false positives and returns the plaintext result of your query. To further address this problem of frequency leakage, beacons are partitioned, allowing identical plaintext values to produce different beacon values across partitions. When the table uses only a single partition, this behavior naturally matches traditional, non-partitioned beacons.
The average number of false positives for each beacon depends on the remaining beacon length after truncation and the number of partitions. For help determining the appropriate beacon length for your implementation, see Determining beacon length . Searchable encryption is designed to be implemented in new, unpopulated databases. Any beacon configured in an existing database will only map new records uploaded to the database, there is no way for a beacon to map existing data.
Using beacons to perform queries on encrypted data reduces the performance costs associated with client-side encrypted databases. When you use beacons, there is an inherent tradeoff between how efficient your queries are and how much information is revealed about the distribution of your data. The beacon does not alter the encrypted state of the field. When you encrypt and sign a field with the AWS Database Encryption SDK, the plaintext value of the field is never exposed to the database. The database stores the randomized, encrypted value of the field.
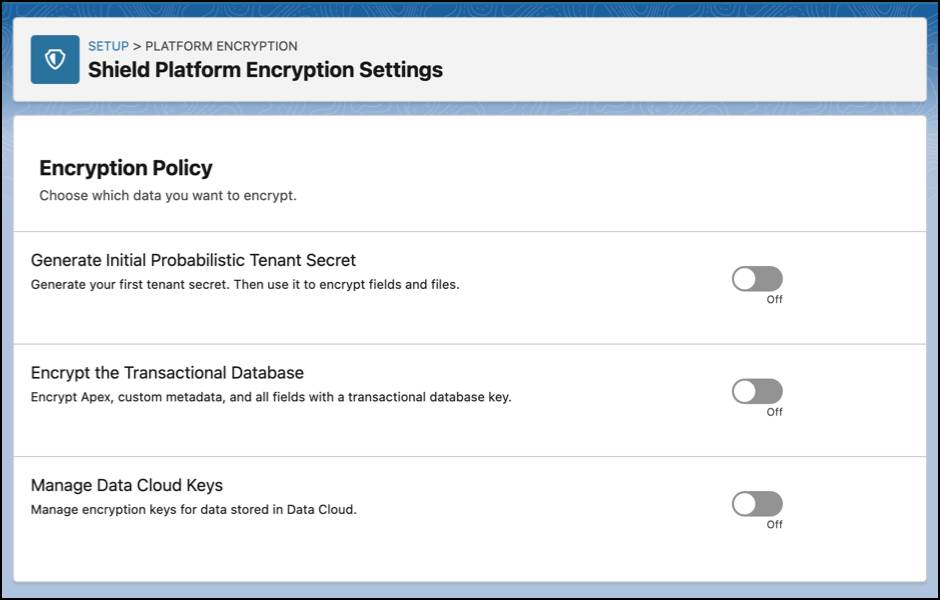
Figure 2: Implement Database and File Encryption for Enhanced Security Beacons are stored alongside the encrypted fields they are calculated from . This means that even if an unauthorized user cannot view the plaintext values of an encrypted field, they might be able to perform statistical analysis on the beacons to learn more about the distribution of your dataset, and, in extreme cases, identify the plaintext values that a beacon maps to.
Proper beacon configuration is essential for mitigating these risks. Selecting an appropriate beacon length and partitioning scheme preserves confidentiality by ensuring sufficient collisions and mitigating frequency-based attacks through limiting the concentration of values in any single beacon. Shorter beacon lengths and higher partition counts improve security by increasing collisions and reducing frequency leakage, Longer beacon lengths and fewer partitions improve performance by reducing false positives and query fan-out.
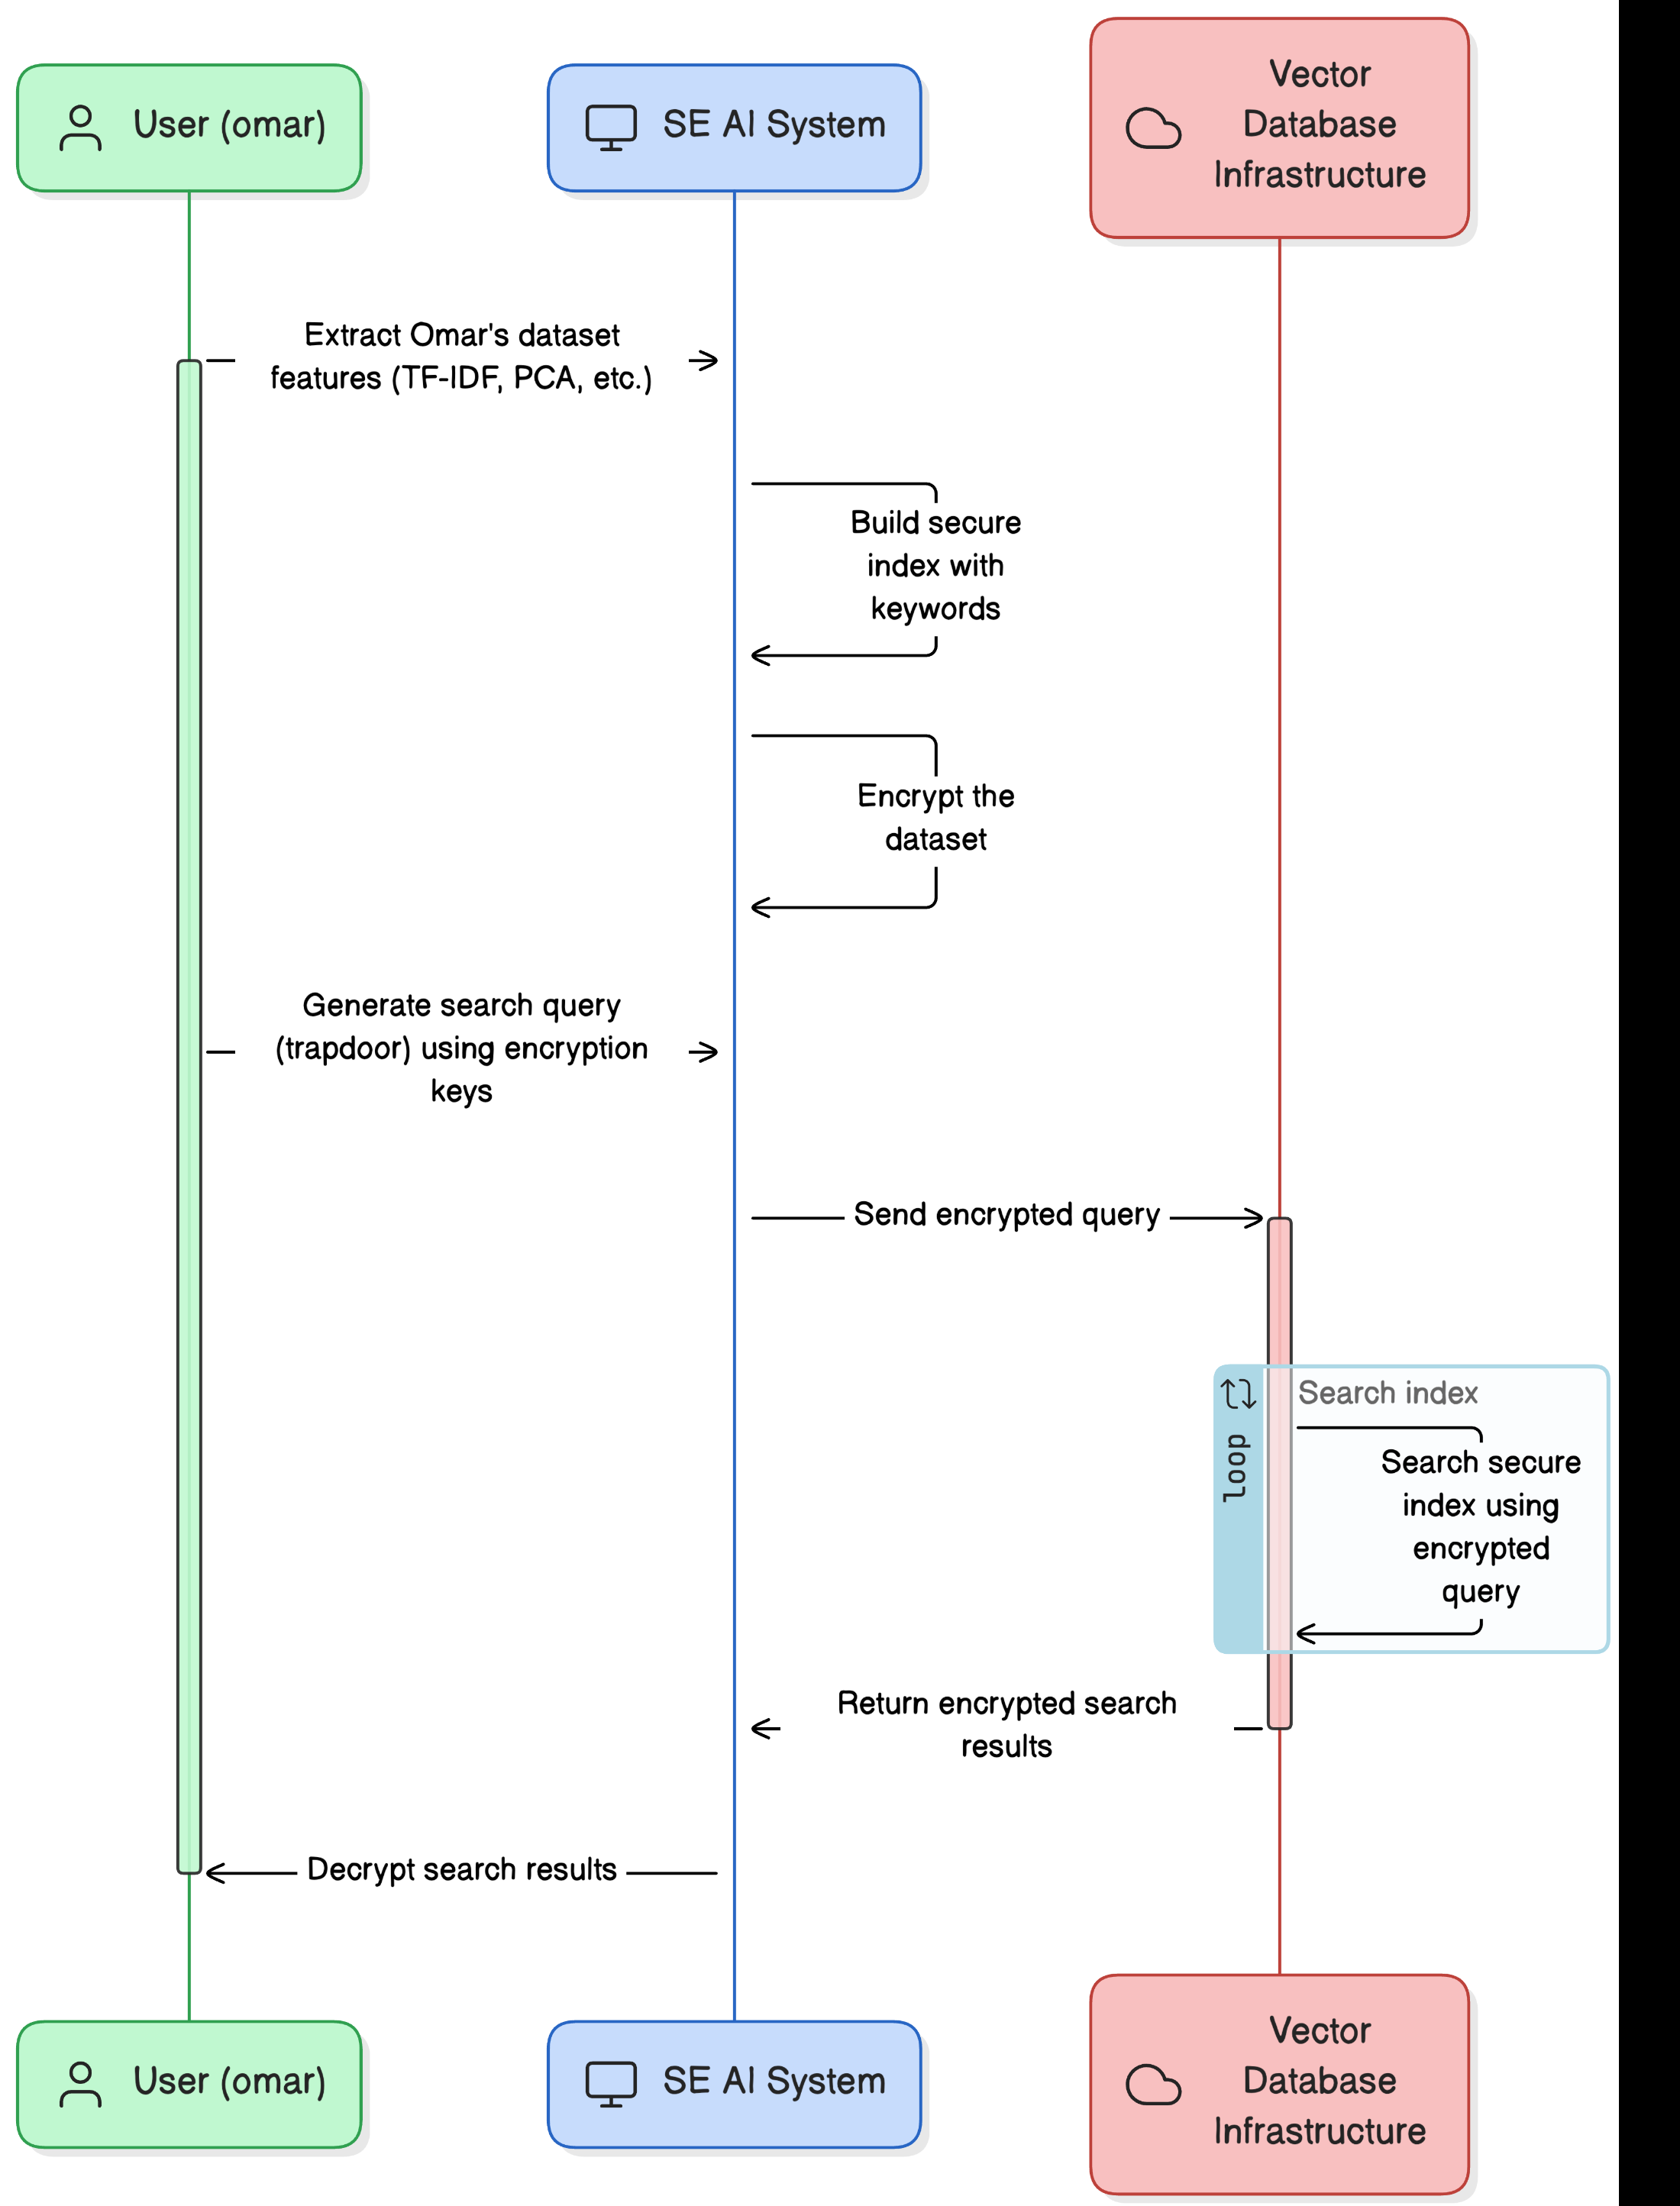
In many practical scenarios, a well-chosen configuration can balance these competing goals. However, searchable encryption may not be able to deliver the desired levels of both security and performance for every dataset. Figure 3: Securing Vector Databases Before configuring any beacons, carefully review your threat model, security requirements, and performance needs, and consider the uniqueness characteristics of your dataset to determine whether searchable encryption is an appropriate choice.
The security properties of a beacon depend on both the distribution of the underlying data and how the beacon is configured, including how many partitions are used. When you configure an encrypted field for searchable encryption, the AWS Database Encryption SDK computes an HMAC over each plaintext value written to that field and derives the beacon using a cryptographic key. Beacons are computed in the context of a partition, which allows identical plaintext values to produce different beacon values across partitions. When the table uses only a single partition, identical plaintext values always map to the same truncated HMAC tag, which can preserve frequency patterns from the original dataset.
Fields with highly skewed distributions require special care. For example, consider a database that stores the city of residence for all residents of Illinois. If you construct a beacon from the encrypted City field, the value âIIChicagoâII will occur far more frequently than other cities. Even if an unauthorized user can only access encrypted items and beacon values, this imbalance may allow them to infer which records correspond to residents of Chicago by observing overrepresented beacons.
Truncating the beacon can reduce this leakage by forcing more collisions, but the beacon length required to sufficiently hide severe skew can introduce significant performance overhead due to increased false positives. To configure beacons safely, you should analyze the frequency distribution of your data and understand how truncation and partitioning interact. The number of bits retained in a beacon determines how much statistical information is exposed, while the number of partitions bounds how concentrated any single beacon value can become. Shorter beacon lengths and more partitions reduce frequency leakage but increase false positives and query fan-out. Longer beacon lengths and fewer partitions improve query efficiency but expose more information about the underlying distribution.
In some extreme cases, workloads are not viable when the table uses only a single partition. Attributes with very small populations or highly imbalanced binary outcomesâIIsuch as medical test results where NEGATIVE values dominateâIIcannot be protected using truncation alone. With one partition, a beacon short enough to hide the distribution collapses all values into a single tag, while a longer beacon makes rare values easy to identify. In these cases, partitioned beacons are required to make searchable encryption feasible. By distributing overrepresented values across multiple partitions, this approach reduces the size of equivalence classes and limits frequency leakage in ways that are not possible when using a single partition.
We strongly recommend that you avoid constructing distinct beacons from fields with correlated values. Beacons constructed from correlated fields require shorter beacon lengths to sufficiently minimize the amount of information revealed about the distribution of each dataset to an unauthorized user. You must carefully analyze your dataset, including its entropy and the joint distribution of correlated values, to determine how much your beacons need to be truncated. If the resulting beacon length does not meet your performance needs, then beacons might not be a good fit for your dataset.
For example, you should not construct two separate beacons from City and ZIPCode fields because the ZIP code will likely be associated with just one city. Typically, the false positives generated by a beacon limit an unauthorized user's ability to identify distinguishing information about your dataset. But the correlation between the City and ZIPCode fields means that an unauthorized user can easily identify which results are false positives and distinguish the different ZIP codes.
You should also avoid constructing beacons from fields that contain the same plaintext values. For example, you should not construct a beacon from mobilePhone and preferredPhone fields because they likely hold the same values. If you construct distinct beacons from both fields, the AWS Database Encryption SDK creates the beacons for each field under different keys. This results in two different HMAC tags for the same plaintext value. The two distinct beacons are unlikely to have the same false positives and an unauthorized user might be able to distinguish different phone numbers.
Even if your dataset contains correlated fields or has an uneven distribution, you might be able to construct beacons that preserve the confidentiality of your dataset by using shorter beacon lengths. However, beacon length does not guarantee that every unique value in your dataset will produce a number of false positives that effectively minimizes the amount of distinguishing information revealed about your dataset. Beacon length only estimates the average number of false positives produced. The more unevenly distributed your dataset, the less effective beacon length is at determining the average number of false positives produced.
Carefully evaluate the distribution of the fields you choose to beaconize and determine how much truncation is required to meet your security requirements. The following topics in this chapter assume that, within each partition, beacon values are uniformly distributed and that the underlying data does not introduce correlations that would weaken these assumptions. The following example demonstrates a searchable encryption solution and illustrates the core concepts discussed in this chapter. In this scenario, certain field values occur very frequently, which would lead to large equivalence classes and increased frequency leakage if a single partition were used. To address this, the configuration uses multiple partitions so that highly frequent values are distributed more evenly, reducing leakage while preserving the ability to perform efficient equality searches.
Consider a database named Employees that tracks employee data for a company. Each record in the database contains fields called EmployeeID , LastName , FirstName , and Address . Each field in the Employees database is identified by the primary key EmployeeID . If you marked the LastName and FirstName fields as ENCRYPT_AND_SIGN in your cryptographic actions , the values in these fields are encrypted locally before they're uploaded to the database. The encrypted data that is uploaded is fully randomized, the database doesn't recognize this data as being protected. It just detects typical data entries. This means that the record that is actually stored in the database might look like the following.
If you need to query the database for exact matches in the LastName field, configure a standard beacon named LastName to map the plaintext values written to the LastName field to the encrypted values stored in the database. This beacon calculates HMACs from the plaintext values in the LastName field. Each HMAC output is truncated so that it is no longer an exact match for the plaintext value. For example, the complete hash and the truncated hash for Jones might look like the following.
2aa4e9b404c68182562b6ec761fcca5306de527826a69468885e59dc36d0c3f824bdd44cab45526f70a2a18322000264f5451a cf75f9f817e2b35099d408c833 In a dataset with many employees, certain last names such as Jones , Smith , or Johnson may occur far more frequently than others. To reduce frequency leakage and limit the size of beacon equivalence classes, you should configure the LastName beacon to use more than one partition.
When partitions are enabled, each item is assigned to a partition at write time, and the partition number is incorporated into beacon derivation. As a result, employees with the same last name may map to different beacon values across partitions. This spreads highly frequent names across multiple partitions, reducing overrepresentation of any single beacon value. 2. System Architecture & Core Working Principles After the standard beacon is configured, you can perform equality searches on the LastName field. For example, if you want to search for Jones , use the LastName beacon to perform the following query.
When querying for a specific high-frequency last name, such as Jones , the application should issue one query per partition using the LastName beacon. The AWS Database Encryption SDK then decrypts the results and automatically filters out any false positives, returning the correct plaintext records. Encrypt sensitive data and you can no longer search it. That's the friction that pushes most teams toward one of two unhappy choices: skip encryption "for now" and hope nothing leaks, or wedge in homomorphic encryption and live with five-figure-slower queries.
There is a third option, and it has been quietly working in production for years. It is built specifically for Postgres, the encrypted indexes plug into normal Postgres indexing, and it is roughly 410,000× faster than fully homomorphic encryption on the queries you actually run — and close to no-encryption performance for most workloads. This post is a working guide. By the end you will have a Postgres table with an encrypted email column, the associated database indexes, and three real queries — equality, free-text search, and ordering — running over ciphertext with no plaintext touching the database.
What you almost always want is the fourth thing — encryption in use : data encrypted at rest, queries evaluated by Postgres without decrypting, and an attacker reading the database files sees only ciphertext. pgcrypto / pgsodium for everything. Fine for fields you store but never search. The moment you need a WHERE you're scanning the whole table and decrypting every row. There are no indexes on encrypted columns, by construction — and the per-query key exposure described above.
Homomorphic encryption. Cryptographically beautiful and operationally unusable for OLTP. Saved for analytics in research environments. The right shape of the answer is purpose-built encrypted index structures that Postgres can use the way it uses any other index, with plaintext only ever existing in your application's memory.
Encrypt Query Language (EQL) is an open-source library that installs into any Postgres database as a set of types and functions. No extension is required, which means it works on managed Postgres: AWS RDS, Google Cloud SQL, Azure Database, Supabase. The plaintext never leaves your application. Postgres only ever evaluates the encrypted index.
That installs EQL into your database, sets up auth, and generates a starter encryption client. The walkthrough below is what stash init produces, decomposed — useful both as a mental model and as a reference if you'd rather wire it up by hand. The TypeScript schema is the source of truth — the Stack client reads it at runtime to know how to encrypt each column and to assemble valid queries.
The exact CREATE INDEX syntax differs slightly between self-hosted Postgres and managed providers; the docs cover each variant. That creates a local profile at ~/.cipherstash/ — the SDK reads it automatically in development, so there's nothing else to configure on your laptop. ( npx stash init from the top of this walkthrough wraps the same login into a full guided project setup if you'd rather use it.) For production, generate API credentials in the CipherStash dashboard and set the env vars referenced in the next step.
The ~~ operator runs over a Bloom-filtered set of 3-character n-grams of the indexed text. It is closer in spirit to a substring tsearch than to SQL LIKE : matching is case-insensitive, multi-word inputs are supported, and there is no concept of leading-wildcard or positional patterns ( %foo is not a thing; "foo" matches anywhere it appears). (Range queries follow the same encryptQuery pattern with queryType: 'orderAndRange' .) Plaintext never crossed the wire to Postgres. The query planner used the encrypted indexes the way it would use any other index.
A pg_dump of the table looks like ciphertext JSONB and opaque index structures. There are no plaintext column values, no document hashes you could rainbow-table, no shared deterministic ciphertext between users. A snapshot, a backup, a stolen credential, an over-permissioned admin — they all see the same thing: ciphertext with no key. The key itself never leaves your application's process boundary. Per-value keys are derived on demand from a root key held in your own AWS KMS account, brokered by ZeroKMS . CipherStash never sees your data or your keys.
Cloud Service Providers, such as Google Cloud Platform, Microsoft Azure, or Amazon Web Services, offer continuously evolving cloud services. It is a growing industry. Businesses, such as Netflix and PayPal, rely on the Cloud for data storage, computing power, and other services. For businesses, the cloud reduces costs, provides flexibility, and allows for growth. However, there are security and privacy concerns regarding the Cloud. Because Cloud services are accessed through the internet, hackers and attackers could possibly access the servers from anywhere. To protect data in the Cloud, it should be encrypted before it is uploaded, it should be protected in storage and also in transit. On the other hand, data owners may need to access their encrypted data. It may also need to be altered, updated, deleted, read, searched, or shared with others. If data is decrypted in the Cloud, sensitive data is exposed and could be exposed and misused. One solution is to leave the data in its encrypted form and use Searchable Encryption (SE) which operates on encrypted data. The functionality of SE has improved since its inception and research continues to explore ways to improve SE. This paper reviews the functionality of Searchable Encryption, mostly related to Cloud services, in the years 2019 to 2023, and evaluates one of its scheme, Fully Homomorphic Encryption. Overall, it seems that research is at the point where SE efficiency is increased as multiple functionalities are aggregated and tested.
Keywords Security Information ⋅ \cdot Privacy ⋅ \cdot Searchable Encryption ⋅ \cdot Homomorphic Encryption ⋅ \cdot Cloud Computing Examples of some of the resources or services provided in cloud computing are dedicated virtual machines, core computing, security and identity, virtual networks, machine learning platforms, cloud storage, and streaming analytics [ 7 ] . The cloud provides services to Location Based Services (LBS), Internet of Things (IoTs), electronic Health (eHealth) research and organizations, blockchains, smart devices, and other fields. Data sent to the cloud may contain sensitive information. This includes personal or customer information, user location and geographical habits, medical records, and trade secrets.
Businesses, such as Netflix, Zoom, and PayPal, rely on the Cloud as part of their business structure. The Cloud is accessed by the Internet which makes it a target for hackers. It can also be a target from a business insider looking to make money off of a company’s trade secret. Data such as personal or financial data is a precious resource that needs protection. One method of protecting data is to encrypt the data in storage and transit. At times, however, the encrypted data needs to be operated on. For example, the data would need to be decrypted in order to search for a file or to change a record. If this data is decrypted, plain-text is exposed to potential adversaries. So, the data should remain encrypted in the cloud while in transit to other locations, at rest in memory, or when used.
A proposed solution is to keep data encrypted while in the cloud. When needed, and decryption needs to occur, transport the encrypted data out of the cloud and back to the data owner. The owner decrypts the data in his or her protected private server. Changes are made on plain-text data. After changes are made, the owner encrypts the data and then sends it back to the cloud.
The problem with this solution involves the download of the entire database, decrypting the data, operating on the plain-text, re-encryption, and then sending it back to the cloud. This is not worthwhile. This would not only involve time but would require memory to hold the data, high computational costs, and heavy network usage. A recently proposed solution is to utilize Searchable Encryption (SE). With this method, data in the cloud or other server is never decrypted. It remains encrypted, even when operated on [ 13 ] . SE allows searches, updates, or calculations on encrypted data such that its plaintext is never exposed.
There are different SE schemes that allow operations on encrypted data. Data is never decrypted. One type of scheme is Homomorphic Encryption (HE). Its definition meets the definition of SE such that it operates on encrypted data while stored in an untrusted server. Formally, "homomorphic encryption systems allow data to be analyzed and processed on a ciphertext rather than the underlying data itself" [ 31 ] . HE distinguishes itself from SE such that HE can add or multiply numbers while in encrypted form. An issue with HE is that it involves heavy memory and computation costs. Some research indicates it may not always be practical.
In fact, there are concerns from online articles. For instance, one article claims that the HE process, when compared to data that is not encrypted, is one million times slower when conducting operations on data [ 11 ] . This article, Intel to Build Silicon for Homomorphic Encryption , talks about a complex dataset such as a Magnetic Resolution Image (MRI) that undergoes screening and processing. Dr Cutress claims that homomorphic encryption is not a viable option with MRIs. He claims that one second of plaintext processing is equivalent to a week of HE processing. So, it appears that HE is limited in its use when dealing with complex datasets. In terms of research contribution, however, there are hundreds of research projects on the subject. Google Scholar produced over 51,000 articles related to homomorphic encryption.
Our paper reviews the functionality of Searchable Encryption, which includes Homomorphic Encryption, from 2019 to 2023. 3. Software Implementation, Frameworks & Protocols The Cloud is widespread and a massive infrastructure. It stores and retrieves data. Privacy of sensitive data is an issue [ 3 ] . Encryption schemes have been developed to ensure privacy. Organizations as well as individuals use the cloud to store data.
An example of Cloud usage is when airports use Cloud Services as part of their infrastructure. This technology increases profits. Manual labor is shifted to automated operations in the Cloud. In addition, airport networks integrate with IoT, sensors, GPS, surveillance cameras, facial recognition, etc. Data stored in the Cloud contain trade secrets, as well as customer information, that the airlines rely on. The airline industry, with its data and operations in the Cloud, is vulnerable to cyber attacks [ 42 ] .
Netwrix claim that 80% of cloud users store sensitive data [ 8 ] . Sensitive data includes employee and customer data, financial records, and trade secrets. Attacks on sensitive data include phishing, ransomware, data leakage, and data loss or theft. Businesses surveyed report that data breaches can be costly and leads to unplanned expenses. In regards to healthcare, according to Netwrix, 55% of healthcare organizations have experienced a data breach. If a data breach occurs, the healthcare company will need to protect the consumer. One method used is to offer the consumer a credit monitoring service, such as IDX.
IDX is a data breach response company. In their research, they found that data breaches include "stolen or compromised credentials (19%), phishing (16%), cloud mis-configuration (15%), vulnerabilities in third-party software (13%), and malicious insiders (11%)" [ 9 ] . They further claim, via an IBM survey, that 83% of surveyed businesses reported at least one data breach. Companies identified as "organizations in critical infrastructures", e.g., banks and technology companies, have an average expense of $4.82 million. This cost can go up or down depending on the security defenses used [ 30 ] .
Overall, there are advantages of using the cloud. They include data availability, reduced business costs, and unlimited storage space for data. However, they are not immune from unauthorized access, data breaches or insider threats [ 3 ] . Encryption is needed to protect sensitive data. There are many encryption schemes such as secure search, private information retrieval (PIR), and searchable encryption (SE) [ 3 ] . When protecting data, there are three different areas. The first is data "in transit," such as data traveling across the Internet. Second, there is data "at rest," or simply data in storage or sitting in memory. Finally, there is data "in use." This is when data is created, read, updated, deleted, searched for, added, or any other operation. Data needs protection in all of these three states.
Searchable encryption has many uses as it allows operations on encrypted data. For instance, a search operation is conducted on encrypted data without the decryption to plaintext. Because the data remains encrypted, it can be used to secure data in the Cloud while at rest, in transit, and in use. Searchable encryption appeared in 2000. It performs search operations while maintaining privacy and confidentiality. Song et al. proposed that untrusted servers should only have encrypted data, i.e., data should not be decrypted while in the server.
Although some functionality is lost, data remains encrypted even when searching for words [ 13 ] . This makes sense since storing data on servers, such as email, in its encrypted form makes data unreadable. In turn, it reduces security and privacy risks. If an attacker gained access to the server, he or she would only see ciphertext. Moreover, the server remains unaware of what is stored, even when conducting searches. In SE schemes, the server is never given plaintext; the server is not given keys to decrypt the data - for any operation. To ensure that a server never sees plaintext data, the data owner encrypts the data before uploading to the server.
Users have different options to protect their data. They may use several keys at different locations to encrypt documents. Stronger schemes include the changing of encryption keys, re-encrypting all documents, and re-ordering ciphertext [ 13 ] . These methods are used to ensure an outsourced or untrusted server cannot deduce the meaning of words. Extract the dataset features such as keywords from the documents. Most schemes use TF-IDF to extract the features, as explained below.
As explained later, there are various methods to conduct searches such as using single or multiple keywords. Current research involves multi-keyword searches such as the Multi-Keyword Rank Searchable Encryption (MRSE) scheme based on Homomorphic Encryption. This uses the Paillier cryptosystem with Threshold Decryption (PCTD) algorithm [ 68 ] , an indexed based search scheme.
Searchable Symmetric Encryption (SSE) is an example of a SE scheme that is a symmetrical type. It uses a symmetric key to encrypt data and allows other authorized users to search the encrypted data using certain keywords or search terms. After the search is conducted, results are returned in encrypted form [ 56 ] . The authorized user would use his or her key to decrypt the message.
Public Key Searchable Encryption (PKSE) is another popular type of searchable encryption scheme. This is an asymmetric type of encryption scheme. The public key is used to encrypt both the data and keywords. The encrypted keywords are sent to the server. The server uses its private key to search the encrypted data and return the results. The results are returned back to the user in encrypted form [ 56 ] .
Another scheme is the Attribute Based Encryption (ABE) scheme that uses fuzzy identification to implement fine-grained data access control. This is needed since data owners cannot invoke access controls on outsourced data . ABE can be used where cloud servers perform complex computing tasks [ 56 ] . Additionally, it allows encrypted data to be searched with searchable encryption algorithms, allows file updating, and attribute revocations [ 39 ] .
Simply, ABE makes fine-grained access control manageable by allowing specified persons to access certain encrypted files. Order-Preserving Encryption (OPE) is an SE scheme that allows comparisons to occur over encrypted data. OPE allows the ciphertexts to maintain the same order as its plaintext version. So, if plaintext 1 is greater than plaintext 2, then Encrypted(plaintext 1) is greater than Encrypted(plaintext 2). With this scheme, servers can perform comparisons, ordering, ranking, and range queries over encrypted data [ 51 ] .
An encryption scheme is Homomorphic Encryption (HE). It allows operations on the encrypted data without the need to decrypt them [ 44 ] . Homomorphic Encryption is a type of searchable encryption. Of the SE schemes, Fully HE is a relatively new scheme when compared to the others. HE is the encryption of data and then analyzing and processing the ciphertext while never exposing it in decrypted form [ 31 ] . Fully HE allows unlimited mathematical operations, primarily addition and multiplication, on the encrypted data. Because the data remains private and plaintext is not shown, outside parties are unable to understand the data [ 23 ] .
Research has expanded Homomorphic Encryption, and developed variation. However, there are three common types. This includes Partial HE, Somewhat HE, and Fully HE. Of the three common HE schemes, PHE is the most widely used [ 3 ] . It is also the least secure. This has been around since 1978 [ 31 ] . Rivest, Adelman, and Dertouzos proposed it as "privacy homomorphisms." They proposed that data remains encrypted and is never decrypted. They found that some functions exist to allow operations to be performed while the data is encrypted. The only time that it is decrypted is when it is downloaded to the user’s computer [ 47 ] .
PHE is efficient over both SHE and FHE, but PHE is limited to one type of math operation, either addition or multiplication. It is still in use and researched. For example, a recent study proposed that PHE be used at airports to secure data, or keep it private, while in the Cloud [ 42 ] . The scheme uses a Single Keyword Searchable Encryption (SKSE) scheme based on the Paillier Cryptosystem.
This also has been around since 1978 [ 31 ] . SHE can perform both addition and multiplication. With SHE, the number of homomorphic operations are limited [ 44 ] . As more operations are performed, more noise or error, is introduced in the calculations. At some point, too much error causes loss in accuracy and decryption is not possible. SHE is not as efficient as PHE, but it is more efficient than Fully Homomorphic Encryption (FHE). Because SHE is faster and more compact than FHE, it is useful to more applications [ 69 ] .
Fully Homomorphic Encryption (FHE) is the third common type of HE schemes. FHE is relatively new in comparison to other techniques. Regarding FHE, a popular paper is Dr. Craig Gentry’s FHE scheme, proposed in 2009. His scheme leads to addition and multiplication on encrypted ciphertext an unlimited number of times [ 22 ] . Dr. Gentry’s scheme basically controls the size of math operations on ciphertext so they do not grow uncontrollably large. Although, research has noted the high computational costs and large ciphertexts involved in FHE.
In Dr. Gentry’s scheme, bootstrapping is utilized, i.e., he uses a decryption algorithm on a produced ciphertext, along with the private key, after each operation. This reduces the "noise" and allows infinite homomorphic operations [ 44 ] . The decrypted ciphertext then gets re-encrypted. Without the reduction, the noise grows and accumulates after each operation. If it becomes too large, the ciphertext cannot be decrypted.
Noise is a "bounded element of randomness in the encryption scheme added to the message so that it is easy to remove and unveil the original message for trusted parties and conceal the message from adversaries" [ 26 ] . Nowadays, FHE is combined or modified and used in encryption schemes. One example is where Rajan et al. uses dynamic multi-keyword search that uses a modified fully homomorphic encryption scheme along with Prim’s algorithm to increase efficiency [ 45 ] .
There are many Fully Homomorphic Schemes. According to Wikipedia, there are 12 open source libraries for FHE [ 64 ] : Microsoft SEAL: Its developer is Microsoft and includes the BGV, CKKS, and BFV schemes OpenFHE: These has several developers that include, Intel, MIT, Samsung Institute of Technology, UC San Diego, and others. This is the successor to Palisade and includes all schemes, i.e., BGV, CKKS, BFV, FHEW, CKKS Bootstrapping, and TFHE.
4. Practical Deployment, Analysis & Case Studies PALISADE: The developers include New Jersey Institute of Technology, MIT, UC San Diege, and others. Like OpenFHE, it includes all schemes except CKKS Bootstraping. HEAAN: Developed out of Seoul National University. Its schemes include CKKS and CKKS Bootstrapping.
FHEW: It has two developers, Leo Ducas and Daniele Micciancio and focus is on the FHEW scheme. Lattigo: The developers are EPFL-LDS and Tune Insight. Both EPFL-LDS and Tune Insight conduct research on data security. TFHE-rs: The developer is a company called Zama. They built applications using HE, with a focus on FHE.
Above all, there are three "effective and peer-reviewed FHE schemes" which are Brakerski-Gentry-Vaikuntanatha (BGV), Brakerski, Fan-Vercauteren (BFV), and Cheon-Kim-Kim-Song (CKKS). With the various schemes and developments, they should not be implemented unless the user understand them. Some HE platforms are emerging and not fully developed [ 14 ] . Some schemes have emerged but not yet been fully tested, and some schemes are effective but are proprietary [ 31 ] .
Cloud services can benefit from HE as it preserves privacy and companies can share data without compromising sensitive information. At this time, it is impenetrable by quantum computers [ 31 ] . Businesses use cloud services and storage services and may have security concerns. HE is a promising solution. The cloud when used with HE allows businesses to share sensitive information with trusted parties. HE also helps with regulations where privacy, such as in areas of finance and medical records, is required by law.
The database is an asset for most organizations and needs to be protected. Protection includes multiple layers of security. This includes firewalls, authentication, access control, and database encryption. Database Encryption has two disadvantages The first is Key management . Authorized users must have access to the decryption key if they need to access the encrypted data. Because a database is typically accessible to a wide range of users and a number of applications, providing secure keys to selected parts of the database to authorized users and applications is a complex task [ 54 ] .
The second disadvantage of an encrypted database is inflexibility . This refers to parts or all of an encrypted database. Encryption can be applied to the entire database, at the record level (encrypt selected records), at the attribute level (encrypt selected columns), or at the level of the individual field. Performing record searches on encrypted data is a highly complex task where not much flexibility is given.
Another disadvantage, is that encryptions such as FHE is too slow to be useful. FHE is claimed to be too slow to have practical applications. It is about 1 million times slower than if operations were in plaintext [ 11 ] . This, however, appears to focus on complex datasets. When Song et al. proposed their paper in 2000, they used a sequential scan search. Each document contains a set of n-bit keywords. Each keyword gets encrypted. This provides a document full of encrypted keywords. When a search is conducted, it looks for the encrypted keyword. So, a search is done on all documents. Documents that contain the encrypted keyword are returned. The keywords are never decrypted to plaintext unless downloaded to the data owner with the decryption key. Thus, the server does not know what is being searched for. There are limitations with the sequential scan [ 49 ] : The search complexity is linear which depends on the number of documents and the size of the documents.
The encryption of the general files cannot be applied like the encryption of the documents. The files cannot be compressed to save space. If compressed, the documents cannot be searched. Despite the initial limitations, research has continued to improve efficiency or the functionality of SE. This includes single keyword searches, multi-keyword searches, range searches, fuzzy keyword searches, verifiable searches, image searches, multiple users searches, bloom filter searches, etc.
Symmetrical Searchable Encryption was proposed by Song et al [ 13 ] . In this scheme, a document in a cloud server is searched by progressing through the whole document. A single, specific word is used to determine if it is in the document. Lately, single keyword is not researched unless search efficiency is demonstrated. Using single keywords has limited functionality. It may be researched with a particular scheme such as Partial Homomoprhic Encryption that uses Paillier Cryptosystem [ 42 ] . Overall, many schemes may use single keywords for searching; after all, it is more efficient when compared to multi-keyword searches.
Using multiple keywords to search an encrypted database is needed since it provides better functionality with today’s applications. When moving from a one keyword search to a multi-keyword search, there is a noticeable drop in efficiency [ 60 ] . So, attempts are made to reduce the computation overhead and increase efficiency [ 10 ] , or make searching faster [ 40 ] . In addition, research increases functionality by using multi-keyword searches alongside other functionalities. For example, it can be combined with fuzzy and semantic searches [ 12 ] . Multi-keyword searches can use ranked, searchable ABE schemes (FEMRSABE) [ 39 ] . Moreover, multi-keyword searches increases its functionality by including research to improve its security. For instance, the Multi-Keyword Ranked Search Scheme with Fine-grained access control (MRSF) provides multiple keyword searches along with access control in a cloud environment that maintains encrypted data [ 32 ] .
Research is also extended to "ranking" as in the multi-keyword ranked searchable encryption (MRSE). In this scheme, multi keywords are used in a query and the top search results are returned. This is a nice feature as we only want the most relevant documents returned to us [ 41 ] [ 50 ] . There is another multi-functionality that this scheme provides. If a user does not use the correct keyword for searching, the server may infer another keyword [ 41 ] . Other combined functionalities include the searching of multi-keywords and by allowing files to be updated [ 27 ] , [ 4 ] . Finally, it can be combined and improved with index-based platforms [ 53 ] , [ 4 ] .
Ranges are different from using multiple keywords. Ranges could involve a specifying a keyword and a number. A user specifies the number of times a keyword appears in a document in order for it to be returned [ 3 ] . Ranges could also include spatial attributes or geographical keyword range queries over encrypted data [ 24 ] . Geometric range queries are useful in research as it can find data points within an area such as a rectangle or circle [ 34 ] . This is useful, as related to location based services, to not to reveal a person’s location when looking for a service or Point of Interest. It also extends to Internet of Things (IoT), vehicle networks, valet parking, and other services [ 52 ] .
Most schemes only support exact keyword searches. If a word is misspelled, the user will not be able to retrieve any records or files from the server [ 35 ] . Fuzzy word resolves this issue but the searches increase computational costs. Research has improved to allow more misspellings and to increase the search efficiency [ 33 ] . Like the other functionalities, fuzzy keyword searches extends, or combines, with other functionalities such as multi-keywords, phrases, ranking, blockchains, semantics, etc.
"TF-IDF is a statistical method used to evaluate the importance of a word in a file collection…There is a hypothesis that the most meaningful words for distinguishing documents should be those that appear frequently in a single document and less frequently in other documents in the entire file collection" [ 35 ] . Ranked searches allow the most relevant documents to be returned based on the keywords used [ 50 ] . Although I did not specifically track "TF-IDF," it appears often in the articles that I searched. It is worthwhile to understand and explain as it relates to ranked searches. It is a common method used in finding the most relevant keywords [ 2 ] [ 39 ] , and widely used and integrated in index development and query generation [ 4 ] .
TF stands for Term Frequency and IDF stands for Inverse Document Frequency. In mathematical terms [ 20 ] : Research continues with ranking and retrieval by itself as the efficiency may be improved [ 1 ] . Ranked searches are used in combination of other functionalities such as multi-keyword searching. It is not uncommon to see "multi-keyword" and "ranked" to be paired. "Multi-keyword ranked search" is used quite often since it quickly returns the most relevant documents to the requester [ 50 ] . Multi-keyword ranked searches can be paired with security for access control and analysis [ 32 ] .
Indexes are search structures that are researched to improve the search performance. A problem can arise, especially in big datasets, where the index becomes the "processing bottleneck" [ 72 ] . Index searches are in a different category from the sequential scan searches. Some index structures conduct sequential searches with different types. According to Amorin et al., index structures include simple indices, inverted indices, and tree indices. Index searches reduce the number of comparisons made and are efficient, but queries are limited to keywords contained in the index [ 3 ] .
A simple index structure involves two actors, the data owner and the cloud service provider. The data owner sends his encrypted data to the cloud service provider, along with an index of keywords. When the owner wants a document, he sends a search token - with a keyword - to the cloud service provider. The cloud service provider uses the search token to locate the keyword and retrieve the document [ 67 ] .
Normally, an index is when a data owner extracts keywords from plaintext files. The extracted keywords are used to build a "Secure Index." The plaintext is then encrypted with symmetric encryption. The keywords are then transformed into trapdoors. The cloud servers that store the encrypted data match an authorized user’s trapdoor to to the Secure Index. This produces search results of the user’s target keywords, which are returned to the user. This method is used to improve efficiency and security [ 39 ] .
"Several recent schemes employ a server-side encrypted index in the form of a search tree where each node stores a bit vector denoting for each keyword whether any file in its sub-tree contains that keyword…the way data is distributed in such a search tree has a big impact on the cost of searches" [ 16 ] . 5. Performance Evaluation & Extended Technical Observations Tree-based searching methods provide range searches. These are good for numerical datasets, and may be used in other search schemes such as FHE schemes [ 39 ] .
There are different types of trees that range from simple to complex and can be used in search schemes. Trees split data or data structures and provide choices or decisions to access data. For instance, the binary decision (BD) tree has a dataset in the parent node and splits its attributes into the child nodes. The splitting continues until the leaves are reached. The leaf nodes are subsets of the attribute set [ 71 ] .
For complexity, trees can be reshaped and used in different ways. For example, a segment tree is a "binary tree-based data structure for conducting efficient range aggregation queries on a sequential data set" [ 25 ] . In this tree structure, the inner nodes stores the results of range aggregation function and the leaf nodes store a data record from the data set. Search trees provide only part of the functionality of an encryption schemes and are combined with other functionalities. For instance, by using a search tree data structure, Lin et al. created two different flexible and efficient multi-keyword, ranked searchable attribute-based schemes (FEMRSABE) [ 39 ] . These tree schemes use fuzzy keyword searching as well as semantic searches.
Efficiency may be improved with certain methods of how trees are searched. There are different methods such as Depth First Search, Breadth First Search, Boundary Traversal, Post Order Traversal etc. For example, Bhavya et al. used the Greedy Depth-first Search in their proposed Efficient File Upload and Multi-Keyword Search over Encrypted Cloud Data (EFUMS) scheme [ 5 ] . In Ashwini’s research, he also proposed the Greedy Depth-first Search in his tree for his multi-keyword, ranked scheme to improve efficiency [ 4 ] .
Efficiency is also increased depending on the type of query. Li et al. proposed a R-Tree index for their geometric range query scheme on encrypted data [ 34 ] . R-Trees are efficient for indexing spatial data although B+ trees are the most common structures in databases. B+ trees can index data in single, sequential order; R trees store multi dimensional data which makes them better for range scans [ 59 ] .
When searching for keywords, indexed in a tree, the tree can be an elaborate structure such as the Four Branch Tree [ 66 ] . The structure uses a keyword binary trees. Each node in the tree contains a set of keywords. Although, the nodes are allowed to be empty. The structure also implements a w-tree, which is a sub-type of a keyword tree. Each node, at most, contains "w" elements inside. Meaning, if a keyword contains {a,b}, {a}, or {b} in its parent node, then a w-tree can be split into two trees such that one tree contains all a’s in its nodes and the other split tree contains all b’s in its nodes.
Graphs have vertices and the vertices are connected by edges. Graphs, between two connected vertices, can flow in one direction, i.e., directed graphs, or flow in both directions, i.e. undirected graphs. There are similarities and differences between graphs and trees. Graphs may or may not have leaf nodes. Trees, in comparison to graphs, have leaf nodes, where every leaf can be access from a root node. Although, some graphs can have a root node. A tree is considered to be a special type of graph, but acyclic and always directed. Meaning, graphs can loop but trees never do. Trees flow in one direction while graphs can flow in one or both directions.
Researchers are not bound when formulating graphs or trees when improving the functionality. Improvements can be made in a "rooted hierarchical graph structure" [ 46 ] . Searching graphs while the structure is encrypted is resource intensive. Nevertheless, research continues to improve its efficiency. For instance, Ge et al. proposes a matching query scheme that supports subgraph extraction to improve efficiency [ 19 ] . Their scheme uses two cloud servers for the matching operation yet ensures privacy. In additional to efficiency, graph searching can be combined with other functionalities, like the other functionalities previously addressed. For example, while using road networks, where graphs are often used, misspelling can be rectified [ 57 ] . Encrypted graph searching is not limited to road networks and seen in different schemes. For instance, a graph is applied in Industrial Internet of Things (IIoT). IIoT refers to end devices that uses sensors, networking, information gathering and processing, security, and efficiency in an business or industrial environment [ 18 ] .
"Untrusted cloud servers may return incorrect or incomplete results…Since cloud servers are mostly untrusted, verifiable search has become a hot topic among scholars" [ 61 ] . Data in the cloud is susceptible to attacks. Encryption ensures confidentiality but what if an attacker alters our encrypted data. It is important to ensure our data is trustworthy by checking its integrity. Verifiable SE schemes can verify if the returned results have be modified or deleted. This uses high overhead [ 35 ] . Verifiable schemes, verifies the results, but also allows all involved parties to monitor the legitimacy of others [ 67 ] . Depending on the scheme, verification could be improved. Some schemes may not be as effective since some verifiable results are not "comprehensive"; they need to demonstrate correctness and integrity [ 15 ] .
Like the other functionalities, research has combined verification with other searchable functions. "For security and privacy concerns, images (e.g., medical diagnosis, personal photos) should be encrypted before being outsourced. However, traditional encrypted image retrieval techniques still suffer from costly access control and low search accuracy" [ 37 ] .
Images include personal photographs and medical images that need protection. They also include high value images that need to be protected from copyright infringement. Some people make money from images and want to control their use [ 63 ] . Images can be encrypted and later searched for. Retrieval of images of some encryption schemes have low accuracy return [ 36 ] [ 37 ] [ 43 ] . With image searching, efficiency or speed along with accuracy seems to be the focus of most of the research in this area.
Not all platforms use single users. Some platforms will need multiple users to access the encrypted data. Especially in the medical field where collaboration, data sharing, and collective intelligence is needed for medical research [ 2 ] . This is an important functionality since many servers are semi-trusted yet multiple users rely on cloud storage solutions to protect personal data [ 70 ] .
Bloom Filters provide an important tool in SE. There are different ways of searching data, such as linear searches or binary searches. In contrast, a Bloom Filter is a different type of search method. "A bloom filter is a space-efficient probabilistic data structure that is used to test whether an element is a member of a set" [ 21 ] . It uses hashing where hashing takes an input, and outputs a unique identifier of fixed length. This unique identifier identifies a member of a set.
According to Liang et al., SE schemes that use bloom filters for searching are called Bloom Filter-based Searchable Encryption . Their study further claims that these searches are highly efficient over other schemes without bloom filters [ 38 ] . In their study, the Bloom-filter based SE scheme is improved upon. There are several other functionalities that have been improved but not detailed and listed that involve encrypted data use.
This includes semantics, words with similar meanings, [ 39 ] , multiple data owners with multiple users [ 62 ] , deduplication of data or the removal of duplicated data [ 58 ] , comparing multiple dimensional data between two different users without revealing the users’ data [ 51 ] , having the ability to query encrypted data sets with heterogeneous data sources [ 17 ] , clustering encrypted unstructured big data [ 72 ] , etc.
Searchable encryption is not limited to improving one type of function. They mostly include multiple functionalities. For instance the Verifiable Ranked Fuzzy Multi-keyword Search scheme (VRFMS) uses a hashing and bloom filter. As you can see, it utilizes fuzzy keyword searches that also employs multiple keywords, ranking, a bloom filter, and a verifiable search scheme [ 35 ] .
As mentioned in Search Trees, above, the FEMRSABE also include various functions that have a wide range of functionalities. Overall, this paper looks at studies within the last five years. It seems that the functionality of SE continues to improve in different areas. We also see the different searchable encryptions schemes. This is important to understand as research continues to expand functionality of schemes.
The various homomorphic schemes are complex and part of the Searchable Encryption family. Paillier Homomorphic Encryption is a partial homomorphic encryption (PHE) scheme while Pyfhel is a Fully Homomorphic Encryption (FHE). FHE schemes being the latest of the Searchable Encryption family. We look at Paillier’s HE as demonstrated on Wikipedia. It is public and accessible with ample resources explaining the process. We also look at open source Pyfhel since it is offered in Python and its GitHub files have been recently updated and maintained.
Partial Homomorphic Encryption (PHE) schemes are the most widely used. In 1999, Pascal Paillier invented the Paillier Cryptosystem [ 65 ] . It is an asymmetric homomorphic encryption system that can add two ciphertexts or allows scalar multiplication [ 42 ] . Simply, two encrypted numbers can be added together and the numbers are never revealed in plaintext. After adding the two encrypted numbers, the sum can be decrypted to derive the results.
Wikipedia is a resource that demonstrates the Paillier encryption schemes [ 65 ] . Tracing through the calculations is obtainable without the use of HE libraries. Although, math libraries will be needed. FHE schemes are written in C++ but there is a scheme that is written in Python. Ibarrondo et al. introduced Pyfhel, an open source encryption library. It is a useful tool for learning FHE [ 29 ] . The library is based on a python wrapper for the C++ Microsoft SEAL Backend and implements the BFV algorithm for integers and CKKS for operations using real numbers [ 6 ] .
Microsoft SEAL is an open source homomorphic encryption library that allows math computations on encrypted data [ 48 ] . With either Pyfhel or Microsoft SEAL, users may conduct unlimited addition and multiplication operations on encrypted data. The noise, which previously prevented unlimited operations on HE schemes, is controlled and may be observed. Afterward, decryption should reveal accurate results in plaintext. Examples of Pyfhel operations may be found at [ 28 ] .
The use of Cloud services is on the rise along with the need to protect data. Searchable Encryption (SE) is a method used to protect data with its encryption as it allows operations on such data. Plain-text is never exposed in an untrusted server. Research into SE continues. SE is extends into many branches and is a complex process. As research continues in many areas, we view its functionality.
Nowadays, researchers have addressed various functionalities and combined them to make SE applicable to a wide variety of situations. Multiple words, fuzzy words, range and spatial searches, verifiable searches, and other functions and tools such as indexes, bloom filters, trees, etc are now used in conjunction with each other. Fully homomorphic encryption (FHE) is the latest type of SE. In his dissertation, Dr. Gentry made the first functional model in 2009. Since then, it has further developed and expanded. Intensive computing may be involved but research has increased its viability. Although, we may see articles claim that Fully Homomorphic Encryption is not a viable scheme. See figure 1 Public articles may not be peer-reviewed but we should objectively evaluate them. As stated at the beginning of this paper, Intel to Build Silicon for Homomorphic Encryption is an Internet article. It states that FHE is a million times slower, compared to plaintext operations, and not useful [ 11 ] . Depending on the dataset and type of operations, this could slow computer processing. Datasets, such as MRI, are highly complex especially when encrypted. Artificial Intelligence has the ability to separate patient data from MRI images. The MRI images do not need to be encrypted before they are analyzed. Only patient information needs to be removed or hidden for protection. Furthermore, research should consider the social justification of working without encrypted data.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Database%20encryption • https://docs.aws.amazon.com/database-encryption-sdk/latest/devguide/searchable-encryption.html • https://cipherstash.com/blog/searchable-encryption-in-postgres • https://arxiv.org/html/2312.14434v1 • https://www.mongodb.com/docs/manual/core/queryable-encryption/features/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Searchable Encryption System For Secure Database Search.
[*] Metasploit Scan Running on Target Subnet for Searchable Encryption System For Secure Database Search... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |