Complete Technical Paper Content — Secrets Management Tool Using Hashicorp Vault Integration
Overview & System Context
Secrets Management Tool Using Hashicorp Vault Integration: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9503 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Netdata is a real-time observability platform for monitoring infrastructure and applications. The project started in 2016 as an open-source system monitoring tool that collected and visualized metrics such as CPU, memory, disk, and network usage through an automatic web-based dashboard. Today, Netdata provides over 800 integrations for metrics collection, log management, machine learning-based anomaly detection, and AI-assisted troubleshooting. The company behind Netdata also offers Netdata Cloud, a commercial hosted service for centralized monitoring across multiple nodes.
Netdata Agent: A daemon that collects metrics, stores time-series data, runs anomaly detection, and serves a web dashboard. Netdata Parent: An optional aggregation node that receives metrics from multiple agents. Netdata Cloud: A commercial hosted service for centralized monitoring of multiple nodes. The agent includes an embedded web server that serves its dashboard and provides a REST API for accessing metrics. Metrics are stored using Netdata's custom time-series database engine (dbengine), which supports up to five storage tiers at different resolutions (per-second, per-minute, per-hour by default). Netdata claims the database achieves approximately 0.5 bytes per sample on disk for high-resolution data. The agent supports credential resolution through external secret management backends, including cloud provider vaults and HashiCorp Vault. Netdata can monitor system resources (CPU, memory, storage, network), containers, Kubernetes clusters, running processes, and common services such as databases. It runs on Linux, Windows, FreeBSD, and macOS.
A public key infrastructure (PKI) is a set of roles, policies, hardware, software and procedures used to create, manage, distribute, use, store and revoke digital certificates and manage public-key cryptography set-ups. The purpose of a PKI is to facilitate the secure storage and/or transfer of information for activities such as e-commerce, internet banking and confidential email, where passwords are an inadequate method of authentication, and more rigorous proofs are required to confirm the identities of the parties involved, and to validate the information. In cryptography, a PKI is an arrangement that binds public keys with respective identities of entities (like people and organizations). The binding is established through a process of registration and issuance of certificates at and by a certificate authority (CA). Depending on the assurance level of the binding, this may be carried out by an automated process or under human supervision. When done over a network, this requires using a secure certificate enrollment or certificate management protocol such as CMP. The PKI role that may be delegated by a CA to assure valid and correct registration is called a registration authority (RA). An RA is responsible for accepting requests for digital certificates and authenticating the entity making the request. The Internet Engineering Task Force's RFC 3647 defines an RA as "An entity that is responsible for one or more of the following functions: the identification and authentication of certificate applicants, the approval or rejection of certificate applications, initiating certificate revocations or suspensions under certain circumstances, processing subscriber requests to revoke or suspend their certificates, and approving or rejecting requests by subscribers to renew or re-key their certificates. RAs, however, do not sign or issue certificates (i.e., an RA is delegated certain tasks on behalf of a CA)." While Microsoft may have referred to a subordinate CA as an RA, this is incorrect according to the X.509 PKI standards. RAs do not have the signing authority of a CA and only manage the vetting and provisioning of certificates. So in the Microsoft PKI case, the RA functionality is provided either by the Microsoft Certificate Services web site or through Active Directory Certificate Services that enforces Microsoft Enterprise CA, and certificate policy through certificate templates and manages certificate enrollment (manual or auto-enrollment). In the case of Microsoft Standalone CAs, the function of RA does not exist since all of the procedures controlling the CA are based on the administration and access procedure associated with the system hosting the CA and the CA itself rather than Active Directory.
Most non-Microsoft commercial PKI solutions offer a stand-alone RA component. An entity must be uniquely identifiable within each CA domain on the basis of information about that entity. A third-party validation authority (VA) can provide this entity information on behalf of the CA. The X.509 standard defines the most commonly used format for public key certificates. PKI provides "trust services" - in plain terms trusting the actions or outputs of entities, be they people or computers. Trust service objectives respect one or more of the following capabilities: Confidentiality, Integrity and Authenticity (CIA).
Confidentiality: Assurance that no entity can maliciously or unwittingly view a payload in clear text. Data is encrypted to make it secret, such that even if it was read, it appears as gibberish. Perhaps the most common use of PKI for confidentiality purposes is in the context of Transport Layer Security (TLS). TLS is a capability underpinning the security of data in transit, i.e. during transmission. A classic example of TLS for confidentiality is when using a web browser to log on to a service hosted on an internet based web site by entering a password. Integrity: Assurance that if an entity changed (tampered) with transmitted data in the slightest way, it would be obvious it happened as its integrity would have been compromised. Often it is not of utmost importance to prevent the integrity being compromised (tamper proof), however, it is of utmost importance that if integrity is compromised there is clear evidence of it having done so (tamper evident). Authenticity: Assurance that an entity has: i) certainty of what it's connecting to; and / or ii) can evidence its own legitimacy when connecting to a protected service.
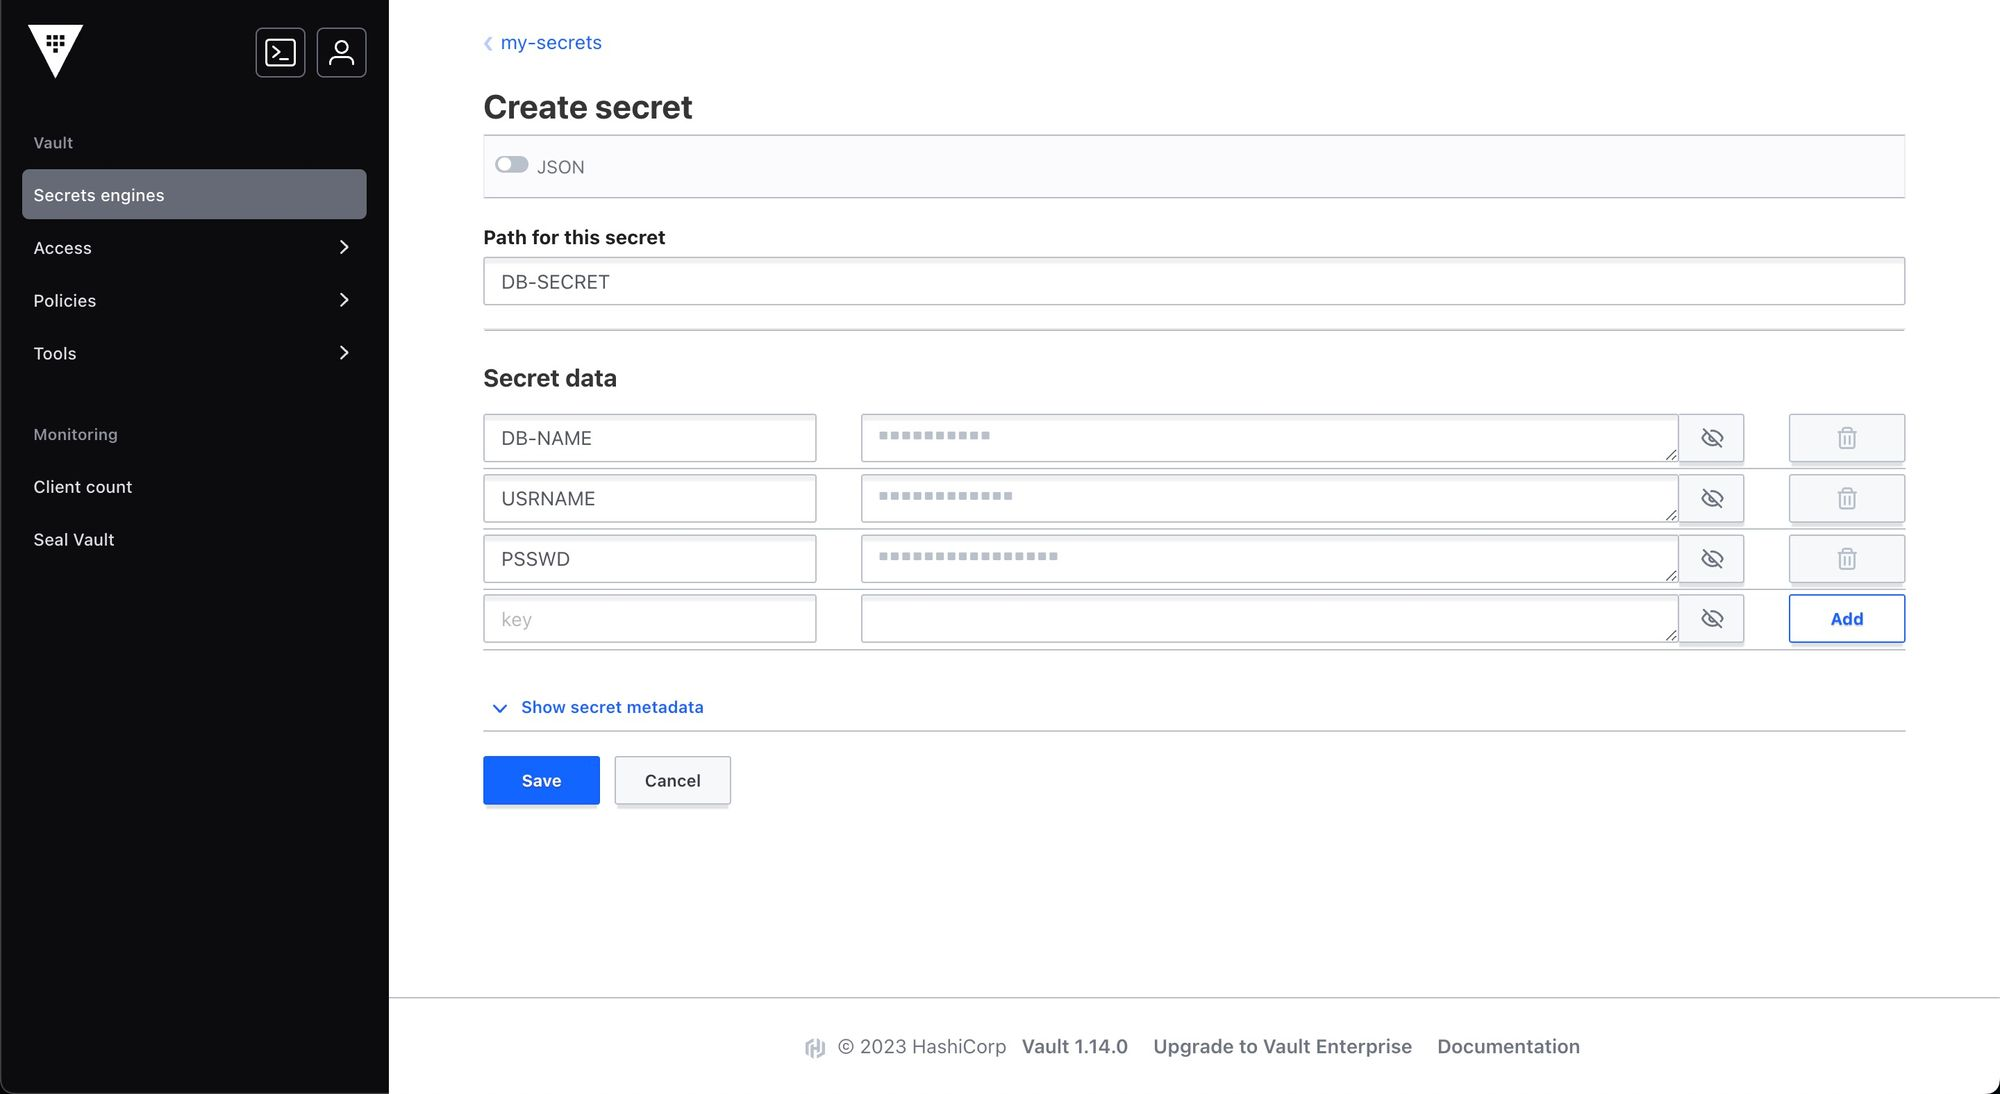
The former is labelled as server certificate authentication, typically employed when logging on at a web server. The latter is designated as client certificate authentication, for instance used when logging on with a smart card hosting a digital certificate and private key. Figure 1: Deploy HashiCorp Vault on Kubernetes | Secure Secrets with Devtron A certificate authority (CA), which stores, issues and signs the digital certificates; A registration authority (RA), which verifies the identity of entities requesting their digital certificates to be stored at the CA; A central directory, a secure location in which keys are stored and indexed; A certificate management system, which manages things like the access to stored certificates or the delivery of the certificates to be issued; A certificate policy, which states the PKI's requirements concerning its procedures.
Its purpose is to allow outsiders to analyze the PKI's trustworthiness. The primary role of the CA is to digitally sign and publish the public key bound to a given user. This is done using the CA's own private key, so that trust in the user key relies on one's trust in the validity of the CA's key. When the CA is a third party separate from the user and the system, then it is called the Registration Authority (RA), which may or may not be separate from the CA. The key-to-user binding is established, depending on the level of assurance the binding has, by software or under human supervision. The term trusted third party (TTP) may also be used for certificate authority (CA). Moreover, PKI is itself often used as a synonym for a CA implementation.
A certificate may be revoked before it expires, which signals that it is no longer valid. Without revocation, an attacker would be able to exploit such a compromised or mis-issued certificate until expiry. Hence, revocation is an important part of a public key infrastructure. Revocation is performed by the issuing certificate authority, which produces a cryptographically authenticated statement of revocation. For distributing revocation information to clients, timeliness of the discovery of revocation (and hence the window for an attacker to exploit a compromised certificate) trades off against resource usage in querying revocation statuses and privacy concerns. If revocation information is unavailable (either due to accident or an attack), clients must decide whether to fail-hard and treat a certificate as if it is revoked (and so degrade availability) or to fail-soft and treat it as unrevoked (and allow attackers to sidestep revocation). Due to the cost of revocation checks and the availability impact from potentially-unreliable remote services, Web browsers limit the revocation checks they will perform, and will fail-soft where they do. Certificate revocation lists are too bandwidth-costly for routine use, and the Online Certificate Status Protocol presents connection latency and privacy issues. Other schemes have been proposed but have not yet been successfully deployed to enable fail-hard checking.
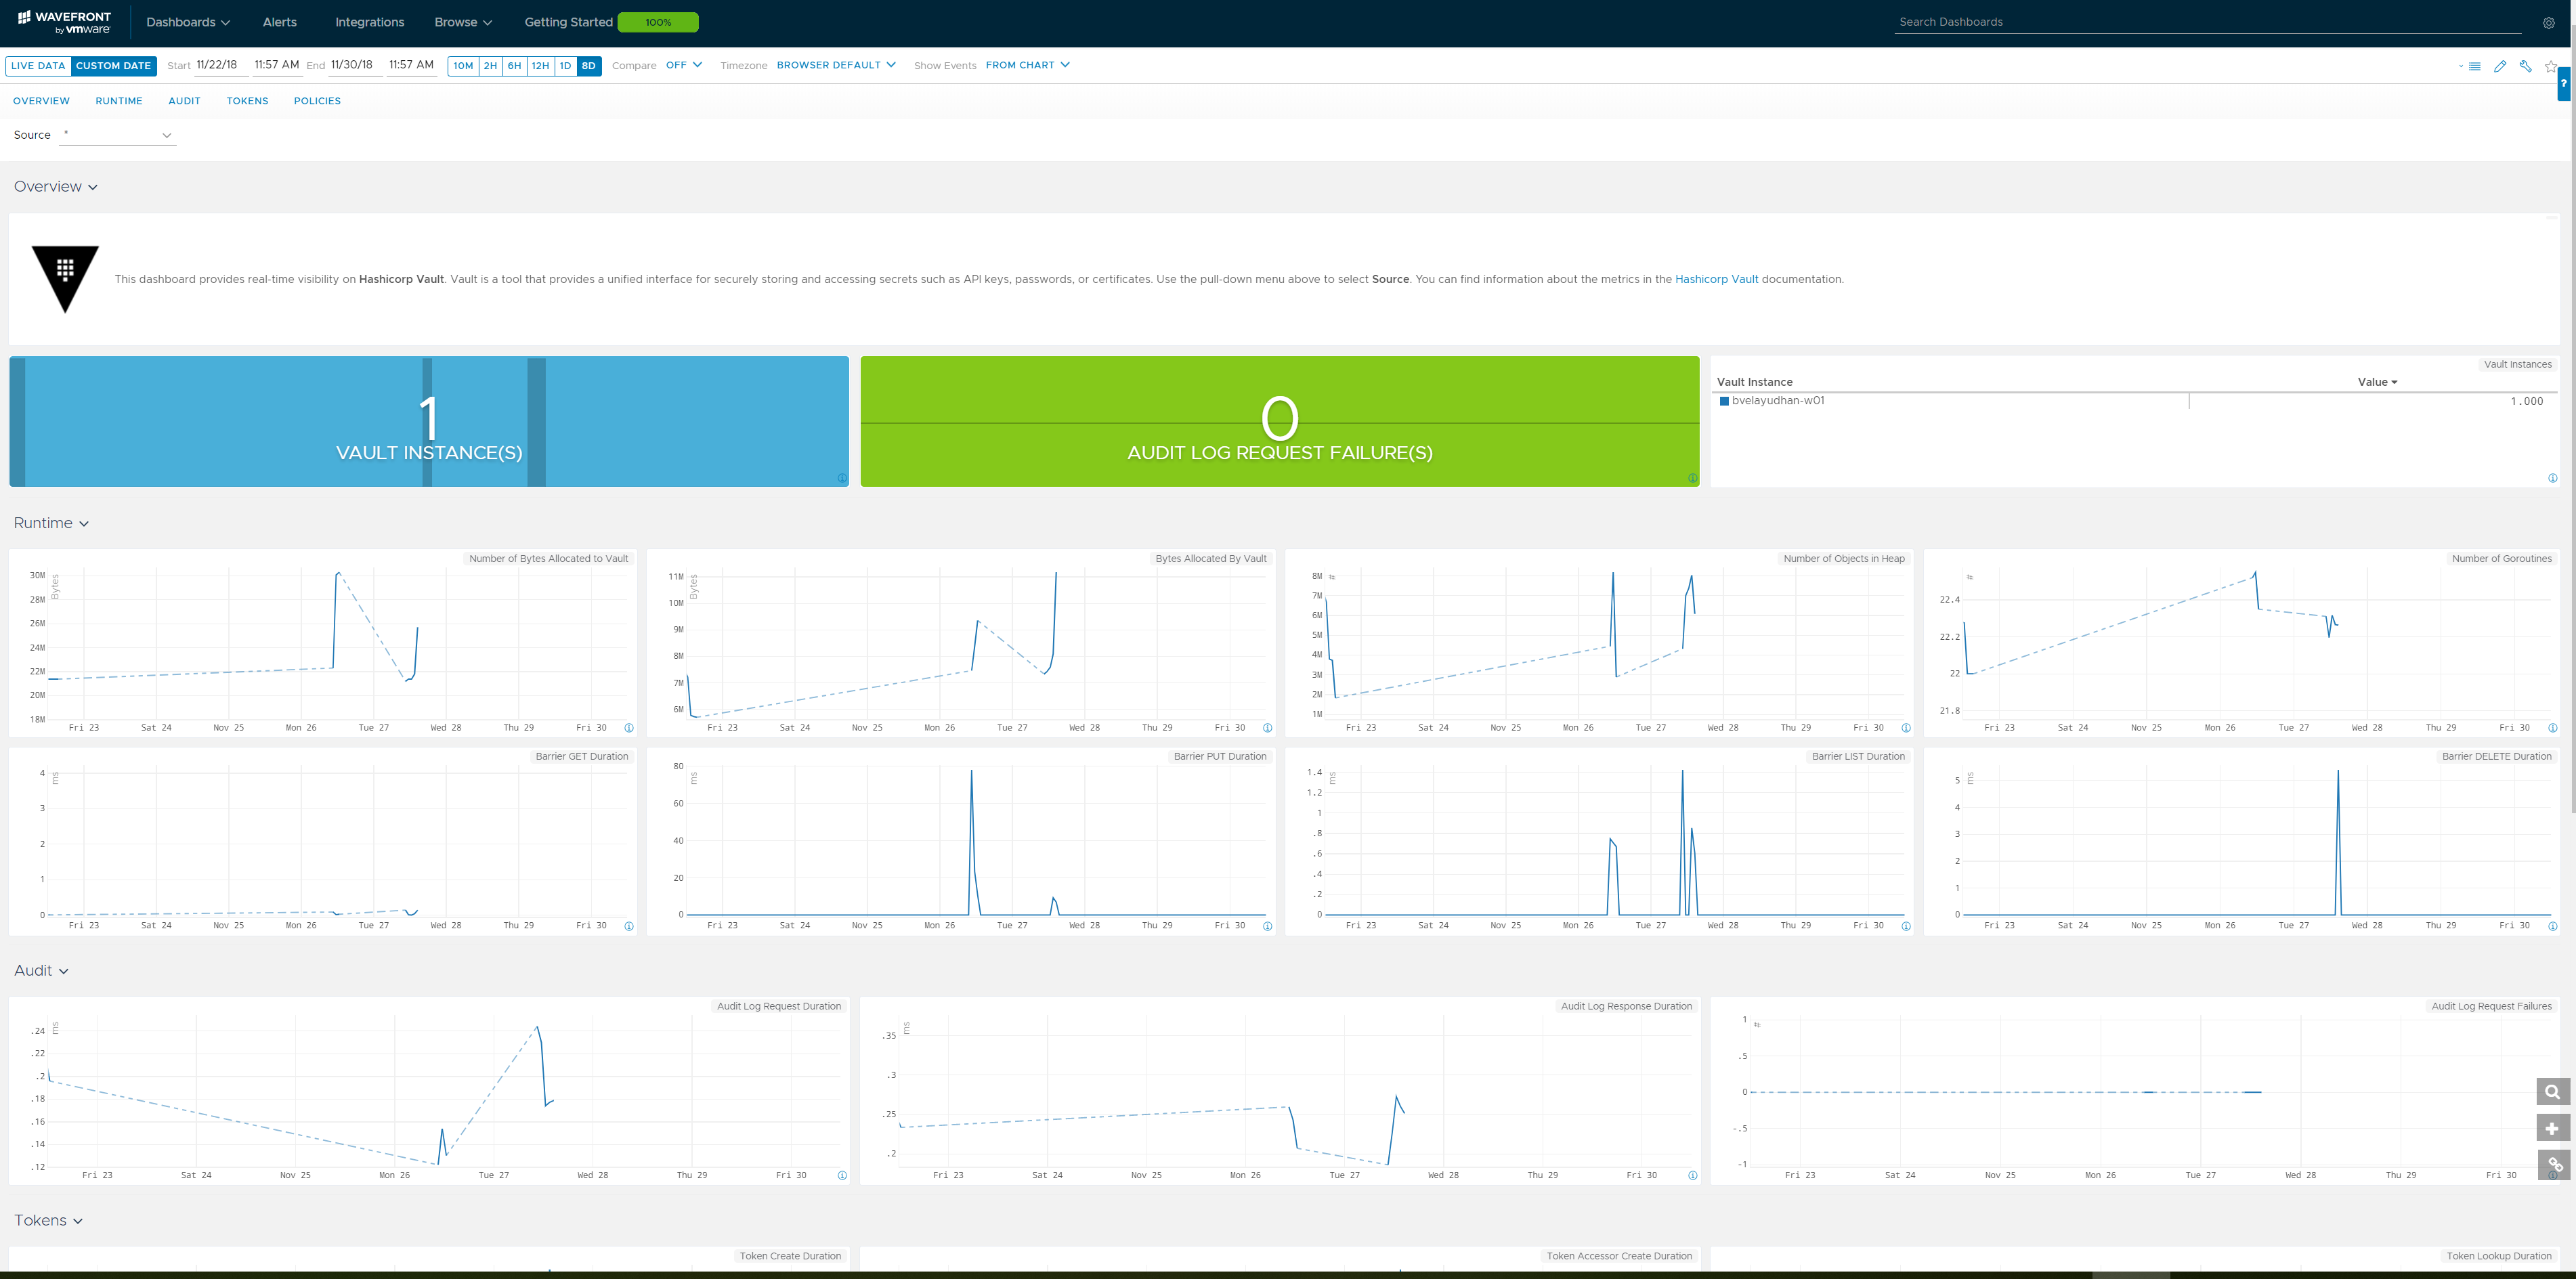
An alternative approach to the problem of public authentication of public key information is the web-of-trust scheme, which uses self-signed certificates and third-party attestations of those certificates. The singular term "web of trust" does not imply the existence of a single web of trust, or common point of trust, but rather one of any number of potentially disjoint "webs of trust". Examples of implementations of this approach are PGP (Pretty Good Privacy) and GnuPG (an implementation of OpenPGP, the standardized specification of PGP). Because PGP and implementations allow the use of e-mail digital signatures for self-publication of public key information, it is relatively easy to implement one's own web of trust. One of the benefits of the web of trust, such as in PGP, is that it can interoperate with a PKI CA fully trusted by all parties in a domain (such as an internal CA in a company) that is willing to guarantee certificates, as a trusted introducer. If the "web of trust" is completely trusted then, because of the nature of a web of trust, trusting one certificate is granting trust to all the certificates in that web. A PKI is only as valuable as the standards and practices that control the issuance of certificates and including PGP or a personally instituted web of trust could significantly degrade the trustworthiness of that enterprise's or domain's implementation of PKI. The web of trust concept was first put forth by PGP creator Phil Zimmermann in 1992 in the manual for PGP version 2.0: Figure 2: Hashicorp Vault Integration | VMware Aria Operations for Applications ...
As time goes on, you will accumulate keys from other people that you may want to designate as trusted introducers. Everyone else will each choose their own trusted introducers. And everyone will gradually accumulate and distribute with their key a collection of certifying signatures from other people, with the expectation that anyone receiving it will trust at least one or two of the signatures. This will cause the emergence of a decentralized fault-tolerant web of confidence for all public keys.
Another alternative, which does not deal with public authentication of public key information, is the simple public key infrastructure (SPKI), which grew out of three independent efforts to overcome the complexities of X.509 and PGP's web of trust. SPKI does not associate users with persons, since the key is what is trusted, rather than the person. SPKI does not use any notion of trust, as the verifier is also the issuer. This is called an "authorization loop" in SPKI terminology, where authorization is integral to its design. This type of PKI is specially useful for making integrations of PKI that do not rely on third parties for certificate authorization, certificate information, etc.; a good example of this is an air-gapped network in an office.
Developments in PKI occurred in the early 1970s at the British intelligence agency GCHQ, where James Ellis, Clifford Cocks and others made important discoveries related to encryption algorithms and key distribution. Because developments at GCHQ are highly classified, the results of this work were kept secret and not publicly acknowledged until the mid-1990s. The public disclosure of both secure key exchange and asymmetric key algorithms in 1976 by Diffie, Hellman, Rivest, Shamir, and Adleman changed secure communications entirely. With the further development of high-speed digital electronic communications (the Internet and its predecessors), a need became evident for ways in which users could securely communicate with each other, and as a further consequence of that, for ways in which users could be sure with whom they were actually interacting. Assorted cryptographic protocols were invented and analyzed within which the new cryptographic primitives could be effectively used. With the invention of the World Wide Web and its rapid spread, the need for authentication and secure communication became still more acute. Commercial reasons alone (e.g., e-commerce, online access to proprietary databases from web browsers) were sufficient. Taher Elgamal and others at Netscape developed the SSL protocol ('https' in Web URLs); it included key establishment, server authentication (prior to v3, one-way only), and so on.
A PKI structure was thus created for Web users/sites wishing secure communications. Vendors and entrepreneurs saw the possibility of a large market, started companies (or new projects at existing companies), and began to agitate for legal recognition and protection from liability. An American Bar Association technology project published an extensive analysis of some of the foreseeable legal aspects of PKI operations (see ABA digital signature guidelines), and shortly thereafter, several U.S. states (Utah being the first in 1995) and other jurisdictions throughout the world began to enact laws and adopt regulations. Consumer groups raised questions about privacy, access, and liability considerations, which were more taken into consideration in some jurisdictions than in others. The enacted laws and regulations differed, and there were technical and operational problems in converting PKI schemes into successful commercial operation. Progress has been much slower than pioneers had imagined it would be. By the first few years of the 21st century, the underlying cryptographic engineering was clearly not easy to deploy correctly. Operating procedures (manual or automatic) were not easy to correctly design (nor even if so designed, to execute perfectly, which the engineering required). The standards that existed were insufficient. PKI vendors have found a market, but it is not quite the market envisioned in the mid-1990s, and it has grown both more slowly and in somewhat different ways than were anticipated. PKIs have not solved some of the problems they were expected to, and several major vendors have gone out of business or been acquired by others. PKI has had the most success in government implementations; the largest PKI implementation to date is the Defense Information Systems Agency (DISA) PKI infrastructure for the Common Access Cards program.
Encryption and/or sender authentication of e-mail messages (e.g., using OpenPGP or S/MIME); Encryption and/or authentication of documents (e.g., the XML Signature or XML Encryption standards if documents are encoded as XML); Authentication of users to applications (e.g., smart card logon, client authentication with SSL/TLS); Bootstrapping secure communication protocols, such as Internet key exchange (IKE) and SSL/TLS. In both of these, initial set-up of a secure channel (a "security association") uses asymmetric key—i.e., public key—methods, whereas actual communication uses faster symmetric key—i.e., secret key—methods; Mobile signatures are electronic signatures that are created using a mobile device and rely on signature or certification services in a location independent telecommunication environment; Internet of things requires secure communication between mutually trusted devices. A public key infrastructure enables devices to obtain and renew X.509 certificates, which are used to establish trust between devices and encrypt communications using TLS.
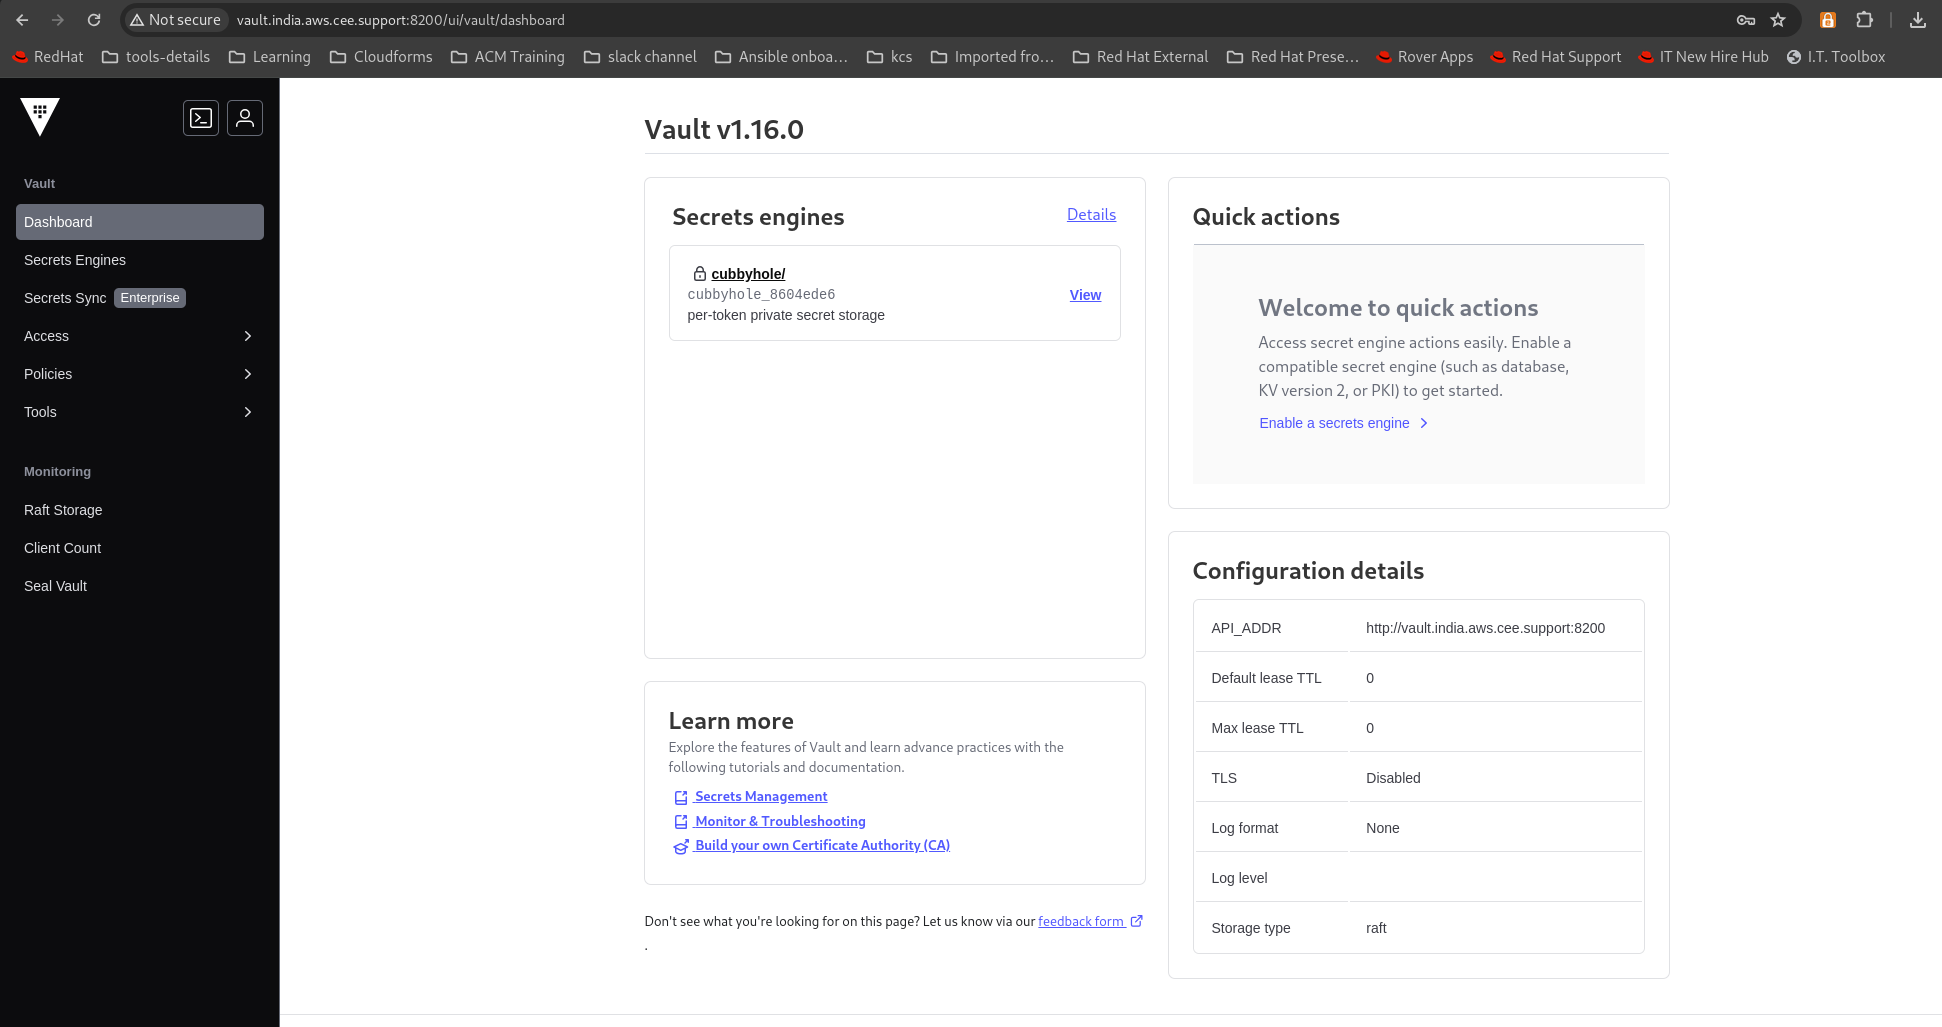
Figure 3: Automating secrets management with HashiCorp Vault and Red Hat Ansible ... Some argue that purchasing certificates for securing websites by SSL/TLS and securing software by code signing is a costly venture for small businesses. However, the emergence of free alternatives, such as Let's Encrypt, has changed this. HTTP/2, the latest version of HTTP protocol, allows unsecured connections in theory; in practice, major browser companies have made it clear that they would support this protocol only over a PKI secured TLS connection. Web browser implementation of HTTP/2 including Chrome, Firefox, Opera, and Edge supports HTTP/2 only over TLS by using the ALPN extension of the TLS protocol. This would mean that, to get the speed benefits of HTTP/2, website owners would be forced to purchase SSL/TLS certificates controlled by corporations. Currently the majority of web browsers are shipped with pre-installed intermediate certificates issued and signed by a certificate authority, by public keys certified by so-called root certificates. This means browsers need to carry a large number of different certificate providers, increasing the risk of a key compromise. When a key is known to be compromised, it could be fixed by revoking the certificate, but such a compromise is not easily detectable and can be a huge security breach. Browsers have to issue a security patch to revoke intermediary certificates issued by a compromised root certificate authority.
Hardcoded credentials in source control remain the leading cause of preventable breaches, yet many teams still rely on environment variables or encrypted files that lack audit trails and rotation capabilities. Proper secrets management with HashiCorp Vault solves this by centralizing encryption, enforcing access policies, and generating short-lived credentials dynamically. If you are building cloud-native applications or preparing for SOC 2 compliance, moving beyond static secrets is no longer optional.
Setting up Vault requires treating it as critical infrastructure, not an afterthought. In my experience helping Nepali fintech startups achieve ISO 27001 certification, the difference between a toy setup and a production-grade deployment lies in storage backend selection, high availability configuration, and unseal key management. Never run Vault with in-memory storage outside of local development.
For production, use Integrated Storage (Raft) or Consul. Raft is now the recommended default for most deployments because it eliminates external dependencies while providing strong consistency. Configure at least three nodes to tolerate a single failure without losing quorum. Always enable auto-unseal using a cloud KMS (AWS KMS, Azure Key Vault, or GCP Cloud KMS). Manual unseal with Shamir shares is operationally fragile; if your team cannot respond to a restart at 3 AM during a monsoon-induced power outage in Kathmandu, your service will remain down until someone physically intervenes. Auto-unseal removes this human bottleneck securely.
After initialization, enable only the auth methods your workloads actually need. For Kubernetes-native applications, use the Kubernetes auth method. For CI/CD pipelines integrating with tools discussed in our GitLab CI pipeline guide , use AppRole or JWT/OIDC authentication. Static secrets are liabilities. Every database password stored in an environment variable is a potential breach vector that never expires unless manually rotated. Dynamic secrets invert this model: Vault generates unique, short-lived credentials on demand and automatically revokes them when the lease expires. This is the single most valuable feature in secrets management with HashiCorp Vault .
The database secrets engine supports PostgreSQL, MySQL, MongoDB, Oracle, and dozens of other datastores. Below is a working PostgreSQL configuration I have deployed across multiple AWS RDS environments: Your application now requests credentials via the Vault API or agent. Each pod or instance receives unique credentials valid for one hour. If a credential leaks, its blast radius is limited to that specific instance and timeframe. When the lease expires, Vault connects to PostgreSQL and drops the user automatically. No cron jobs, no manual rotation scripts, no shared passwords.
A common question from teams already invested in AWS is whether they need Vault at all. The answer depends on your multi-cloud strategy, compliance requirements, and secret complexity. As someone who manages infrastructure across AWS, Azure, and on-premises government data centers, I use both — but for different purposes. Choose AWS Secrets Manager if you are single-cloud, have simple static secrets, and want zero operational burden. Choose Vault if you need dynamic secrets, operate across multiple clouds or hybrid environments, require encryption-as-a-service, or must meet strict audit requirements where vendor lock-in is a concern. For teams deploying Laravel on AWS as described in our AWS hosting guide , starting with SSM Parameter Store and migrating to Vault when dynamic database credentials become necessary is a pragmatic path.
Vault’s policy language is powerful but unforgiving. A misconfigured policy either blocks legitimate application traffic or grants excessive access. Treat policies as code: version them, review them in pull requests, and test them against staging environments before applying to production. Audit every policy change. Enable the file or syslog audit device in production so every access attempt — successful or denied — is logged immutably. During SOC 2 audits, these logs are the primary evidence reviewers examine to verify that access controls function as documented. I have seen audits fail because teams had correct policies but no proof they were enforced consistently.
Implementing secrets management with HashiCorp Vault is a foundational step toward production-grade security and audit readiness. Start with a clear threat model, deploy with auto-unseal and Raft storage, adopt dynamic secrets for databases first, and enforce least-privilege policies as code. The operational investment pays dividends in reduced breach surface area and smoother compliance reviews. If your team needs hands-on guidance designing a Vault architecture that fits your existing infrastructure and compliance requirements, reach out to discuss your specific environment .
Master HashiCorp Vault from installation to production. Complete guide covering secrets management, authentication, policies, CI/CD integration, and security operations with links to 9 detailed tutorials. HashiCorp Vault has become the industry standard for secrets management, providing a centralized solution for storing, accessing, and distributing sensitive data. Whether you're managing database credentials, API keys, certificates, or encryption keys, Vault provides the security controls and audit capabilities that modern infrastructure demands.
This comprehensive guide introduces Vault's core concepts and links to our detailed tutorials covering every aspect of Vault administration and usage. Vault is a tool for securely accessing secrets. A secret is anything you want to tightly control access to, such as: Vault provides a unified interface to any secret while providing tight access control and recording a detailed audit log.
Understanding Vault's architecture helps you make better decisions about deployment and usage. Vault uses a unique security model where the master encryption key is split using Shamir's Secret Sharing: This means even if someone steals your storage backend, they cannot decrypt secrets without the unseal keys. For detailed installation instructions including GUI setup, see our Vault CLI Install Guide .
The KV (Key-Value) secrets engine is the most commonly used for storing static secrets. Most deployments should use KV v2 for its versioning capabilities. Learn more in our KV v2 Secrets Engine Guide . Vault's security model separates authentication (who you are) from authorization (what you can do). Best practice: Generate root tokens only when needed, complete the task, then revoke immediately.
Centralize secrets - Stop storing credentials in config files, environment variables, or code repositories Use appropriate auth methods - Match authentication to client type (humans vs machines) Protect unseal keys - Distribute using Shamir shares, consider auto-unseal for operations For questions about implementing Vault in your organization, contact our team for expert guidance on secrets management strategy and deployment.
Vault is a secrets management tool that securely stores and controls access to sensitive data like passwords, API keys, certificates, and encryption keys. It solves problems of secrets sprawl, lack of audit trails, manual credential rotation, and insecure secret storage in config files or environment variables. Yes, Vault has an open-source version under the Business Source License (BSL) that's free for most use cases. HashiCorp also offers Enterprise and HCP Vault (cloud) versions with additional features like namespaces, HSM support, disaster recovery, and performance replication.
Install via package managers (brew install vault on macOS, apt/yum on Linux), download pre-compiled binaries from hashicorp.com/downloads, use Docker (hashicorp/vault image), or deploy via Helm on Kubernetes. See our CLI Install Guide for detailed instructions. Dev mode (vault server -dev) runs in-memory with automatic unseal and a root token printed to console - it's for testing only.
Production mode requires persistent storage, TLS certificates, proper initialization with Shamir key shares, and manual or auto-unseal configuration. After authenticating, use 'vault kv put secret/myapp password=value' for KV v2 secrets engine. This stores a key-value pair at the specified path. You can store multiple fields in one command and retrieve them with 'vault kv get secret/myapp'.
Use LDAP or OIDC for human users with SSO, AppRole for CI/CD pipelines and automated systems, Kubernetes auth for pods running in K8s, and cloud IAM auth (AWS, GCP, Azure) for cloud workloads. Each method issues Vault tokens with attached policies. 2. System Architecture & Core Working Principles Use AppRole authentication with role_id (embedded in config) and secret_id (delivered securely). Jenkins has the HashiCorp Vault plugin, GitHub Actions has vault-action, and GitLab CI can use CLI scripts. Retrieve secrets at runtime rather than storing them in CI/CD variables.
When sealed, Vault's master encryption key isn't in memory, making all secrets inaccessible. This is a security feature that protects data even if storage is compromised. Unseal by providing the required threshold of unseal keys (e.g., 3 of 5) or configure auto-unseal with a cloud KMS. Create policies in HCL that define path-based permissions with capabilities (create, read, update, delete, list, sudo, deny).
Attach policies to authentication methods, roles, or tokens. Follow least privilege principles - grant only the minimum access needed. Deploy in HA mode with 3+ nodes using Raft or Consul storage, enable audit logging to track all operations, implement auto-unseal with cloud KMS or HSM, use short-lived tokens, enforce least privilege policies, enable TLS everywhere, and maintain regular encrypted backups.
Install HashiCorp Vault CLI and GUI in minutes. Verified 2026 setup for Windows, Mac, and Linux with copy-paste commands and client verification steps. Master Vault token management: create, renew, revoke tokens using CLI. Learn token types, policies, TTLs, and security best practices for HashiCorp Vault authentication.
Configure Vault authentication methods: LDAP, Userpass, AppRole, Certificate, and Token auth. Step-by-step setup for enterprise security and CI/CD integration. Notes, sketches and ideas laid out spatially instead of in a list. For people who think in diagrams and keep outgrowing linear note apps.
Learn how to use HashiCorp Vault to securely store, access, and manage secrets in your applications and infrastructure. Managing secrets like API keys, database passwords, and certificates is one of the most critical aspects of running secure infrastructure. Hardcoding secrets in configuration files or environment variables leaves you vulnerable to leaks, makes rotation difficult, and creates audit nightmares. HashiCorp Vault solves these problems by providing a centralized, secure, and auditable way to manage secrets.
In this guide, I will walk you through setting up Vault, storing secrets, and integrating it into your applications. You can run Vault in development mode for testing or production mode for real deployments. Let's start with a development setup. This command starts Vault in development mode with a known root token for easy testing.
Download and install the Vault binary for production setups where you need more control. In production mode, Vault starts in a sealed state. You need to initialize it once and unseal it every time it starts. The initialization process generates the master key and root token. This only happens once. Vault comes with KV version 2 enabled at secret/ in dev mode. For production, you may want to enable it at a custom path.
Store your application secrets with meaningful paths that reflect your organization structure. AppRole is designed for machine-to-machine authentication, making it perfect for applications. Policies define what secrets a token can access. Always follow the principle of least privilege. This policy allows reading secrets under the myapp path but prevents writing or deleting.
One of Vault's most powerful features is generating short-lived credentials on demand. This eliminates the need to manage static database passwords. Vault Agent runs as a sidecar and handles authentication and token renewal automatically. This is the recommended approach for production.
Here is how to deploy an application with Vault integration in Kubernetes using the Vault Agent sidecar injector. Configure short TTLs for tokens and secrets to limit exposure if credentials are compromised. Vault transforms secret management from a manual, error-prone process into a secure, auditable, and automated workflow. By centralizing your secrets, implementing proper access controls, and using dynamic credentials, you significantly reduce the risk of credential leaks and simplify compliance.
Start with the basics - store your static secrets in Vault and gradually adopt more advanced features like dynamic secrets and the Vault Agent. The initial setup effort pays off quickly in improved security posture and operational efficiency. Looking for a complete observability platform to monitor your infrastructure alongside your secret management? OneUptime provides integrated monitoring, incident management, and status pages to keep your systems running smoothly. Start your free trial today.
Every OneUptime blog post is open source. Found a typo, an inaccuracy, or have a clearer way to explain something? Anyone can contribute — your edits make this post better for everyone who reads it next. Your complete reliability stack unified: infrastructure monitoring, incident management, status pages, and APM. Open-source and self-hostable.
Every homelab accumulates secrets. Database passwords live in plaintext Docker Compose files. API keys get copy-pasted into environment variables. TLS certificates sit in directories with permissions that seemed right at the time. SSH keys multiply across machines. And when you need to rotate a credential, you're grepping through dozens of config files hoping you found every reference.
HashiCorp Vault is a secrets management tool that centralizes all of this. Instead of scattering credentials across your infrastructure, every service asks Vault for the secrets it needs at runtime. Vault handles encryption, access control, audit logging, and even dynamic credential generation. It can issue short-lived database passwords, generate TLS certificates on demand, and revoke everything with a single command if a machine gets compromised.
For a homelab, Vault might sound like overkill. But once you have more than a handful of services, the alternative -- secrets sprawled across files, environment variables, and your memory -- becomes a real operational liability. Vault provides a single source of truth, and the skills you build using it translate directly to production environments. Vault operates on a client-server model. The Vault server stores encrypted secrets and enforces access policies. Clients authenticate using one of several methods (tokens, AppRole, certificates, LDAP) and receive a time-limited token that grants access to specific secret paths.
For a homelab, running Vault in dev mode is tempting but wrong. Dev mode stores everything in memory and auto-unseals with a root token -- fine for testing, terrible for actual use. We'll set up a proper deployment with file-based storage, which is appropriate for a single-node homelab. The IPC_LOCK capability prevents Vault's memory from being swapped to disk, which would expose decrypted secrets.
For production homelabs, you should terminate TLS at your reverse proxy (Traefik, Caddy, Nginx) rather than disabling it entirely. The connection between your proxy and Vault should still be on a trusted network. Store each unseal key in a different location. A password manager, a printed copy in a safe, an encrypted USB drive -- the point is that no single compromise reveals enough keys to unseal Vault.
After the third key, Vault transitions from sealed to unsealed and begins serving requests. Manually unsealing after every restart gets old fast. For a homelab, you have a few options: The script approach works for most homelabs. Create a systemd service that runs after Docker starts, reads unseal keys from an age-encrypted file, and posts them to the Vault API. It's not perfect, but it's pragmatic.
The Key-Value secrets engine is where most of your homelab secrets will live. Vault supports two versions: KV v1 (simple key-value) and KV v2 (versioned, with metadata and soft-delete). Want more security guides? Get guides like this in your inbox — HomeLab Starter delivers one free deep-dive every week. This is where Vault really shines for homelabs. Instead of using Let's Encrypt for internal services (which requires DNS challenges and public domain ownership) or manually generating self-signed certificates, Vault can act as your own Certificate Authority.
The output includes the certificate, private key, and CA chain. You can feed these directly into your reverse proxy or application configuration. The root token is for administrative work only. Services should authenticate using AppRole, which provides machine-oriented authentication through a role ID (like a username) and a secret ID (like a password).
The cleanest integration pattern for Docker-based homelabs uses an init container or entrypoint script that fetches secrets from Vault before starting the application. Vault HMAC-hashes all secret values in audit logs by default, so the log itself doesn't become a security risk. But it does record which paths were accessed, by whom, and when -- invaluable for debugging access issues and investigating incidents.
The file storage backend stores everything on disk. Back it up like any other directory, but with care: 3. Software Implementation, Frameworks & Protocols For homelabs using the file backend, consider scheduling this as a cron job during low-activity hours. With Vault running, you've centralized your secrets and gained the ability to issue internal TLS certificates on demand. From here, consider: The initial setup is the hardest part. Once Vault is running and your services are configured to pull credentials from it, rotating a compromised secret becomes a single API call instead of an hour of grepping through config files.
Get a free weekly guide from HomeLab Starter — one focused topic, delivered every week. No spam. Operating Vault in an efficient manner to support your use cases requires that you are able to accurately measure its performance. Ideally, you can benchmark and measure performance in environments which resemble production use cases to produce realistic results.
You need to measure Vault performance in a meaningful way, and in an environment that also resembles that of your intended use case with respect to compute resources. The Vault server under test should have the same auth methods and secrets engines enabled, along with example secrets, leases, and token data present to accurately simulate your use cases.
HashiCorp provides the open source utility vault-benchmark to help you measure Vault performance at a granular level using several of the available auth methods and secrets engines. You can use vault-benchmark as a command line interface, as a Docker image, or as a Kubernetes workload to match the infrastructure you are using for Vault.
The end-to-end scenario and lab sandbox described in this tutorial involves one persona. The persona is a Vault operator with privileged permissions to enable and disable auth methods and secrets engines. You perform all the tasks in the hands-on scenario as this persona. You need the following resources to complete the hands-on scenario based on whether you will use the Vault community edition with CLI, Docker, Kubernetes, or HCP Vault Dedicated.
To complete the lab sandbox using CLI versions of Vault and vault-benchmark, you need the following: To complete the lab sandbox using Docker versions of Vault and vault-benchmark, you need the following: To complete the lab sandbox using Vault and vault-benchmark in Kubernetes, you need the following: To complete the lab sandbox using HCP Vault Dedicated and vault-benchmark, you need the following: This tutorial includes a free interactive command-line lab that lets you follow along on actual cloud infrastructure.
This tutorial was last tested 05 Mar 2026 on macOS using the following software versions. The setup for this tutorial's lab sandbox is different depending on whether you want to experiment with vault-benchmark in the CLI with a dev mode server, in the CLI with a Vault Dedicated server, in Docker, or in Kubernetes. You can create a temporary directory to hold all the content needed for this lab sandbox and then assign its path to an environment variable for later reference.
Export the lab sandbox directory path as the value to the HC_LEARN_LAB environment variable. Now choose the lab set up workflow that matches the environment you want to use for this lab sandbox. Run a Vault dev mode server as a background process from your terminal session to follow the self-hosted Vault workflow in this lab sandbox.
Open a terminal and start a Vault dev server with root as the initial root token value. The Vault dev server defaults to running at 127.0.0.1:8200 . The server logs to the file vault-server.log in the lab sandbox working directory, and gets automatically initialized and unsealed. Do not run a Vault dev server in production. This approach starts a Vault server with an in-memory database, and you lose access to all data in a dev mode Vault server when you stop the process.
Tail the server log to learn about important environment variables you need to export before you can use Vault. Export the environment variable for the client to use the Vault server CA certificate. Export an environment variable for the vault CLI to authenticate with the Vault server. Run a Vault dev mode Docker container from your terminal session to follow the Docker workflow in this lab sandbox.
Create a Docker network named learn-vault that all containers in this lab sandbox use. If you have never used the Vault image before, Docker pulls it for you and then starts a container using the image. Do not run a Vault dev server in production. This approach starts a Vault server with an in-memory database, and you lose access to all data in a dev mode Vault server when you stop the process.
Check the Vault server container logs to learn the CA certificate path so that you can copy the certificate to your host computer temporary directory. Copy the certificate file from the container to the temporary directory ( /tmp ) on your host computer. Export the environment variable that informs the Vault client of the Vault server's URL and port information.
Export an environment variable that the Vault client uses to set the Vault server CA certificate value. The Vault dev mode server Docker container is ready for you to proceed with the lab sandbox. Deploy Vault into minikube using a Helm chart from your terminal session to follow the Kubernetes workflow in this lab sandbox.
If you are unfamiliar with this process or would like to dive deeper, review the Vault installation to minikube via Helm with Integrated Storage tutorial. Do not run a Vault dev server in production. This approach starts a Vault server with an in-memory database, and you lose access to all data in a dev mode Vault server when you stop the process.
The Vault dev mode server is running in the pod named vault-0 . Check the status as needed, and ensure that both pods have a Running status before continuing. Deploy a Vault Dedicated developer instance to follow the HCP Vault Dedicated workflow in this lab sandbox. If you are unfamiliar with this process or would like to dive deeper, review the Create a Vault cluster on HCP tutorial.
The admin namespace is the top-level namespace automatically created by HCP Vault. All CLI operations default to use the namespace defined in this environment variable. Now that you have established a working lab, you are ready to explore vault-benchmark and its configuration. Your goal for this section is to explore vault-benchmark using a terminal session. Resources for diving deeper are provided at the section's conclusion.
This lab sandbox focuses on your use of the run command. Get help for the run command. This lab sandbox focuses on your use of the run command. Get help for the run command. 4. Practical Deployment, Analysis & Case Studies The available tests documentation describes all of the available tests and their configuration. You can use this information to configure a vault-benchmark Kubernetes job.
You will use an example benchmark configuration that includes the Kubernetes auth method; the Kubernetes auth benchmark documentation covers all of the available parameters, caveats, and a usage example for this benchmark. This lab sandbox focuses on your use of the run command. Get help for the run command. Vault Benchmark is configured with a HashiCorp Configuration Language (HCL) file. You can use the example configuration shown in the Usage documentation in this lab sandbox.
Here is the entire example configuration file with detailed explanation of each configuration entry. vault_token : the literal token value for a token with capabilities to enable and manage secrets engines and auth methods. In this lab sandbox, the initial root token value is used, but you should not use a root token in production this way. You should benchmark Vault servers dedicated to the purpose, but not production servers. The benchmark can adversely affect performance of the server, and does not make guarantees about cleanup of artifacts created during the benchmark run.
Lines 7-15 and 17-23 represent the 2 tests making up this benchmark configuration. This test configuration runs two different tests, an approle_auth test and a kvv2_write test, with the percentage of requests split evenly between the two. The first test beginning at line 7, is for AppRole auth method logins. Note that the first parameter is weight . You can think of this as a percentage of the entire workload. This means that the benchmark performs AppRole logins 50% of the time throughout the entire run.
You can configure a test in its config stanza. In this test, role_name specifies the auth method role name benchmark-role . Each token Vault issues after an AppRole login with the benchmark-role is configured with a token_ttl value of 2 minutes to specify the token's time-to-live (TTL). You can learn more about available parameters in the AppRole auth method benchmark documentation .
The second test beginning at line 17, is for Key/Value version 2 secrets engine writes. This test takes the remaining 50% of benchmark operations with its weight setting. It also uses numkvs to specify that 100 key/value secrets be written, and kvsize to limit each value to 100 bytes. Available parameters are documented in the KV v1 and KV v2 secret benchmark documentation Now that you have reviewed the example configuration, you need to change it a bit to function with the Vault cluster you are using.
In the lab setup section, you set the VAULT_ADDR and VAULT_TOKEN (and VAULT_NAMESPACE for Vault Dedicated) environment variables for communicating to your Vault cluster. Values from environment variables override anything specified in the vault-benchmark configuration file. With this in mind, you can set the vault_addr , vault_token , and vault_namespace values to an empty string. Their values come from the environment variables you set.
If you are using a Vault cluster that is not in HCP, you might recall that you did not export a VAULT_NAMESPACE environment variable during your lab setup. vault-benchmark uses the root namespace by default when there is no value set in the configuration file. Specifying it is unnecessary unless you are using HCP Vault Dedicated or a Vault Enterprise cluster with a namespace that is not root .
Return to your terminal session and write the configuration file to /tmp/learn-vault-benchmark/vault-benchmark-config.hcl . You have configured vault-benchmark for 2 tests, and they are now ready for you to run them. You can configure vault-benchmark for Kubernetes as a job file. Here is the complete example from the vault-benchmark repository .
This benchmark has one test named kube_auth_test1 , that performs Kubernetes auth method logins. Create the job file /tmp/learn-vault-benchmark/vault-benchmark-job.yaml , paste the following updated configuration into it, and save it. Your goal for this section is to run vault-benchmark with the configuration that you just created.
The benchmark output is tabular by default. This example is from the self-hosted dev mode server, but the output will be similar for Vault in any environment. The first 4 lines are log outputs from vault-benchmark which describe its current actions. The 5th line shows the benchmark target URL, and the 6th line represents headings for the metric data.
The data metrics are as follows for the last 2 lines, which represent each of the 2 benchmark tests you configured. successRatio: the percentage of successful tests of this type. When tests are not successful, you should consult the Vault operational and audit logs for details on the unsuccessful tests. If you do not need your Vault Dedicated or HashiCorp Virtual Network resources any longer, access the HCP portal and delete the Vault cluster and HVN.
You learned the basics around the Vault Benchmark tool, including how to configure and run a benchmark. You also learned about the default benchmark output, and available documentation resources for Vault Benchmark. To dive deeper into Vault performance, consider reviewing the HashiCorp Well Architected Framework on identifying metrics , performance tuning and production hardening documentation.
This document explains the architecture, internals, and production considerations behind HashiCorp Vault. It covers the concepts that the demo touches on, and goes well beyond them into secrets engines, auth methods, dynamic secrets, and high-availability deployment patterns. Vault is a secrets management platform. At a high level, it does three things: stores secrets, controls access to those secrets, and logs every interaction. Under the hood, it is more complex than that sentence suggests.
The Barrier is the most important concept. Vault encrypts everything before writing it to the storage backend. The barrier sits between Vault’s internal logic and the storage layer. Data passes through the barrier on the way in (encrypted) and on the way out (decrypted). Nothing in the storage backend is readable without the master key. The Storage Backend is where encrypted data lives. Vault itself is stateless in the sense that it does not store data internally. It delegates persistence to a backend. Common choices include Consul, integrated Raft storage, S3, and PostgreSQL. In this demo, dev mode uses an in-memory backend: The server.dev.enabled=true flag starts Vault unsealed with data stored only in memory. Restart the pod and everything is gone.
The HTTP API is how all clients interact with Vault. The CLI, the web UI, and application code all talk to the same REST API on port 8200. Every operation is an API call. When the demo pod authenticates: That is a POST to /v1/auth/kubernetes/login . Every subsequent read is a GET with the token in the X-Vault-Token header. When Vault starts in production mode, it is sealed . A sealed Vault can respond to API requests, but it cannot decrypt anything. It knows data exists in the storage backend, but it cannot read it.
The unsealing process works through Shamir’s Secret Sharing. During initialization, Vault generates a master key and splits it into N shares. A configurable threshold (M of N) of those shares must be provided to reconstruct the master key and unseal Vault. For example, you might have 5 shares with a threshold of 3. Any 3 keyholders can unseal Vault. The master key itself does not encrypt data directly. It encrypts an encryption key , which encrypts the data. This indirection allows Vault to rekey (change the master key shares) without re-encrypting all stored data.
Auto-unseal replaces Shamir with a cloud KMS service. Instead of splitting the master key into shares, Vault wraps it with a KMS key (AWS KMS, GCP Cloud KMS, Azure Key Vault, or an HSM). On startup, Vault calls the KMS to unwrap the master key. No human intervention required. Dev mode exists for development and testing. It is not hardened. The root token is root . TLS is off. The storage is ephemeral.
Production deployments need every item in the right column. A secrets engine is a component that stores, generates, or encrypts data. Vault ships with many built-in engines. You enable them at a path, and all operations under that path go to that engine. KV v1 is a simple, non-versioned store. Writing to a key overwrites the previous value with no history. Reads return the current value. Simple and fast, but you lose previous values.
KV v2 adds versioning. Every write creates a new version. You can read previous versions, configure the maximum number of versions to retain, and soft-delete (destroy specific versions). This demo uses KV v2, which is the default in dev mode: The secret/ prefix maps to a KV v2 engine. Under the hood, KV v2 stores data at secret/data/demo/database and metadata at secret/metadata/demo/database . This distinction matters for policies, as we will see later.
The transit engine performs cryptographic operations without exposing keys. You send plaintext in, get ciphertext back. The encryption key never leaves Vault. This is “encryption as a service.” The transit engine supports key rotation. When you rotate a key, new encryptions use the latest version, but old ciphertext remains decryptable. You can also rewrap old ciphertext to use the new key version without exposing plaintext.
5. Performance Evaluation & Extended Technical Observations The PKI engine generates X.509 certificates. You configure a Certificate Authority (root or intermediate), and Vault issues certificates on demand. This solves the certificate lifecycle problem. Instead of requesting certificates through a ticketing system and waiting days, applications request short-lived certificates from Vault. If a certificate has a 24-hour TTL, compromise exposure is limited.
Rotation happens automatically. The database engine generates dynamic credentials. Instead of storing a static username and password, Vault connects to a database and creates a new user account for each request. Each credential set has a TTL. When the TTL expires, Vault revokes the credentials and drops the database user.
This is a powerful pattern. Every pod gets unique credentials. If a credential leaks, it expires quickly. You can trace any database query back to the specific pod that made it, because each pod has its own username. Supported databases include PostgreSQL, MySQL, MongoDB, MSSQL, Oracle, Elasticsearch, Redis, and many others through plugin support.
Policies define what a client can do. They are written in HCL (HashiCorp Configuration Language) and specify paths with allowed capabilities. A policy is a set of path blocks. Each path block names an API path and lists capabilities. The demo stores policies in a ConfigMap for reference: KV v2 adds data/ and metadata/ segments to paths. When you run vault kv put secret/demo/database , the actual API path is secret/data/demo/database . Policies must use the full path including data/ or metadata/ . This is a common source of confusion.
The app-readonly policy in this demo targets secret/data/demo/* (not secret/demo/* ) for exactly this reason. The app-admin policy also includes secret/metadata/demo/* to allow listing and deleting version metadata. Vault follows a default-deny model. If no policy explicitly grants access to a path, the request is denied. This is the opposite of many systems that grant access by default and require explicit deny rules.
Auth methods are mechanisms that verify a client’s identity and map it to policies. Vault supports many auth methods. Each one handles a different identity source. Every Vault interaction uses a token. All other auth methods ultimately produce a token. The token auth method is always enabled and cannot be disabled.
Tokens have properties: policies, TTL, renewal limits, and an accessor (a reference that can be used to look up or revoke the token without knowing the token itself). Tokens can be service tokens (persisted, renewable) or batch tokens (lightweight, not persisted, not renewable). The root token has unlimited access. In production, generate it during initialization, use it for initial setup, then revoke it.
Create new root tokens only when needed using the vault operator generate-root process. This is the auth method used in the demo. It allows pods to authenticate to Vault using their Kubernetes ServiceAccount token. A role binds a ServiceAccount identity to Vault policies. The role named demo-app says: if a pod presents a JWT from ServiceAccount demo-app in namespace vault-demo , issue a Vault token with the app-readonly policy and a one-hour TTL.
The authentication flow has several steps. Understanding them helps with troubleshooting. Pod obtains its ServiceAccount token.
Kubernetes automatically mounts a signed JWT at /var/run/secrets/kubernetes.io/serviceaccount/token . This token is a projected volume, rotated periodically by the kubelet.
Pod sends the JWT to Vault. The pod POSTs to /v1/auth/kubernetes/login with the JWT and the role name. Vault validates the JWT. Vault sends a TokenReview request to the Kubernetes API server. The API server verifies the token’s signature, confirms it has not expired, and returns the ServiceAccount name and namespace. Vault checks the role. Vault compares the ServiceAccount name and namespace from the TokenReview response against the role’s bound_service_account_names and bound_service_account_namespaces fields. If they match, authentication succeeds.
Vault issues a token. Vault creates a new token with the policies listed in the role and returns it to the pod. The Vault pod needs network access to the Kubernetes API server for this to work. The demo configures the host using the $KUBERNETES_PORT_443_TCP_ADDR environment variable, which Kubernetes injects into every pod. AppRole is designed for machine-to-machine authentication. It uses two credentials: a role ID (like a username, relatively static) and a secret ID (like a password, ephemeral and tightly controlled).
AppRole is a good fit for CI/CD pipelines. The pipeline knows its role ID. A trusted process delivers a secret ID just before the pipeline needs to authenticate. The secret ID can be single-use. LDAP auth lets users authenticate with their corporate directory credentials. Vault queries the LDAP server to verify the username and password, then maps LDAP groups to Vault policies. This is common in enterprises where Active Directory or FreeIPA manages user identities.
OIDC auth integrates with identity providers like Keycloak, Okta, or Azure AD. Users authenticate through a browser-based flow. Vault validates the OIDC token, extracts claims (like group membership), and maps those claims to policies. Dynamic secrets are generated on demand and automatically revoked. They are one of Vault’s most powerful features. Consider a PostgreSQL database. Instead of creating a static appuser account, you configure Vault with: When the TTL expires (or the lease is revoked), Vault connects to PostgreSQL and runs the revocation SQL to drop the user.
The result: every application instance gets unique, short-lived credentials. There is no shared password to leak. There is no password to rotate manually. And every database query can be traced to a specific application instance. Applications can renew a lease before it expires. Renewal extends the TTL without generating a new secret. There is typically a maximum TTL beyond which renewal is not possible, forcing the application to re-authenticate and get fresh credentials.
If an application crashes without revoking its lease, the TTL still expires and Vault revokes the credentials. No orphaned accounts. A client with a renewable lease can call /v1/sys/leases/renew with the lease ID. Vault extends the TTL, typically by the original increment. Renewal is not guaranteed. If the maximum TTL has been reached, Vault denies the renewal and the client must request a new secret.
Clients can explicitly revoke a lease by calling /v1/sys/leases/revoke . Administrators can revoke all leases under a prefix with /v1/sys/leases/revoke-prefix . When a lease is revoked, Vault calls back to the secrets engine (for example, the database engine drops the user). Both tokens and secrets have TTLs, and they interact. If a token expires, all secrets issued under that token are revoked. This creates a cascading revocation model. Revoking a token cleans up everything associated with it.
If the pod holds dynamic secrets under that token, they are all revoked when the token expires (if they have not expired already on their own). Vault can log every authenticated interaction. These logs are called audit logs, and the components that produce them are called audit devices.
Every API request and response is logged. The logs include the request path, the client token accessor (not the token itself), the request data, and the response. Sensitive values in the request and response are HMAC’d using a salt, so the audit log does not contain plaintext secrets. But you can verify whether a specific value was read by HMAC’ing it with the same salt and comparing.
In production, Vault requires at least one audit device to be functional. If all audit devices fail (for example, the disk is full), Vault stops processing requests. This is a deliberate design choice: Vault would rather stop serving than serve without an audit trail. Vault supports high availability through leader election. Only one Vault node handles requests at a time (the active node).
Other nodes are standby nodes. If the active node fails, a standby node takes over. The recommended HA storage backend is Vault’s integrated Raft storage. It uses the Raft consensus protocol to replicate data across Vault nodes. Raft provides: A typical production deployment runs 3 or 5 Vault nodes. Three nodes tolerate one failure. Five nodes tolerate two failures.
Using an odd number avoids split-brain scenarios. With Raft, each Vault node stores a copy of the encrypted data locally. Writes go to the leader, which replicates them to followers. Reads can be served from the leader or (with performance standby nodes in Enterprise) from followers. Standby nodes receive client requests but forward them to the active node. From the client’s perspective, any Vault node can accept requests. The Kubernetes Service in front of Vault pods distributes traffic, and standby nodes handle the forwarding transparently.
Manual unsealing with Shamir shares requires human intervention on every restart. For Kubernetes deployments where pods can restart at any time, this is unacceptable. Auto-unseal delegates the master key protection to a cloud KMS: The Vault pod needs IAM permissions (or equivalent) to call the KMS. On OpenShift, this can be configured via pod identity or mounted credentials.
Production Vault must use TLS. All API communication should be encrypted in transit. Options: For internal service-to-service communication, Vault can use its own PKI engine to issue its own certificate. That is a satisfying bit of self-referential infrastructure. Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Netdata • https://en.wikipedia.org/wiki/Public%20key%20infrastructure • https://khimananda.com/blog/secrets-management-with-hashicorp-vault • https://inventivehq.com/blog/hashicorp-vault-complete-guide • https://oneuptime.com/blog/post/2026-02-02-vault-secret-management/view • https://homelabstarter.com/hashicorp-vault-homelab/ • https://developer.hashicorp.com/vault/tutorials/operations/benchmark-vault • https://savitojs.github.io/k8s-learn-by-doing/labs/security/vault-deep-dive/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Secrets Management Tool Using Hashicorp Vault Integration.
[*] Metasploit Scan Running on Target Subnet for Secrets Management Tool Using Hashicorp Vault Integration... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |