Complete Technical Paper Content — Server Side Request Forgery Vulnerability Scanner Tool
Overview & System Context
Server Side Request Forgery Vulnerability Scanner Tool: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9544 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background In computer security, a vulnerability is a flaw or weakness in a system's design, implementation, or management that can be exploited by a malicious actor to compromise its security. Despite a system administrator's best efforts to achieve complete correctness, virtually all hardware and software contain bugs where the system does not behave as expected. If the bug could enable an attacker to compromise the confidentiality, integrity, or availability of system resources, it can be considered a vulnerability. Insecure software development practices as well as design factors such as complexity can increase the burden of vulnerabilities. Vulnerability management includes identifying systems and prioritizing which are most important, scanning for vulnerabilities, and taking action to secure the system. Vulnerability management typically is a combination of remediation, mitigation, and acceptance. Vulnerabilities can be scored for severity according to the Common Vulnerability Scoring System (CVSS) and added to vulnerability databases such as the Common Vulnerabilities and Exposures (CVE) database. As of April 2026, more than 327,000 vulnerabilities had been recorded in the CVE database. A vulnerability is initiated when it is introduced into hardware or software. It becomes active and exploitable when the software or hardware containing the vulnerability is running. The vulnerability may be discovered by the administrator, vendor, or a third party. Publicly disclosing the vulnerability (through a patch or otherwise) is associated with an increased risk of compromise, as attackers can use this knowledge to target existing systems before patches are implemented. Vulnerabilities will eventually end when the system is either patched or removed from use.
Complexity: Large, complex systems increase the possibility of flaws and unintended access points. Familiarity: Using common, well-known code, software, operating systems, and/or hardware increases the probability an attacker has or can find the knowledge and tools to exploit the flaw. However, using well-known software, particularly free and open-source software, comes with the benefit of having more frequent and reliable software patches for any discovered vulnerabilities. Connectivity: any system connected to the internet can be accessed and compromised. Disconnecting systems from the internet can be extremely effective at preventing attacks, but it is not always feasible. Legacy software and hardware is at increased risk by nature. System administrators should consider upgrading from legacy systems, but this is often prohibitive in terms of cost and downtime.
The National Vulnerability Database classifies vulnerabilities into eight root causes that may be overlapping, including: Input validation vulnerabilities exist when input checking is not sufficient to prevent the attacker from injecting malicious code. Buffer overflow exploits, buffer underflow exploits, and boundary condition exploits typically take advantage of this category. Access control vulnerabilities enable an attacker to access a system that is supposed to be restricted to them, or engage in privilege escalation. When the system fails to handle and exceptional or unanticipated condition correctly, an attacker can exploit the situation to gain access. Configuration vulnerability come into existence when configuration settings cause risks to the system security, leading to such faults as unpatched software or file system permissions that do not sufficiently restrict access. A race condition—when timing or other external factors change the outcome and lead to inconsistent or unpredictable results—can cause a vulnerability.
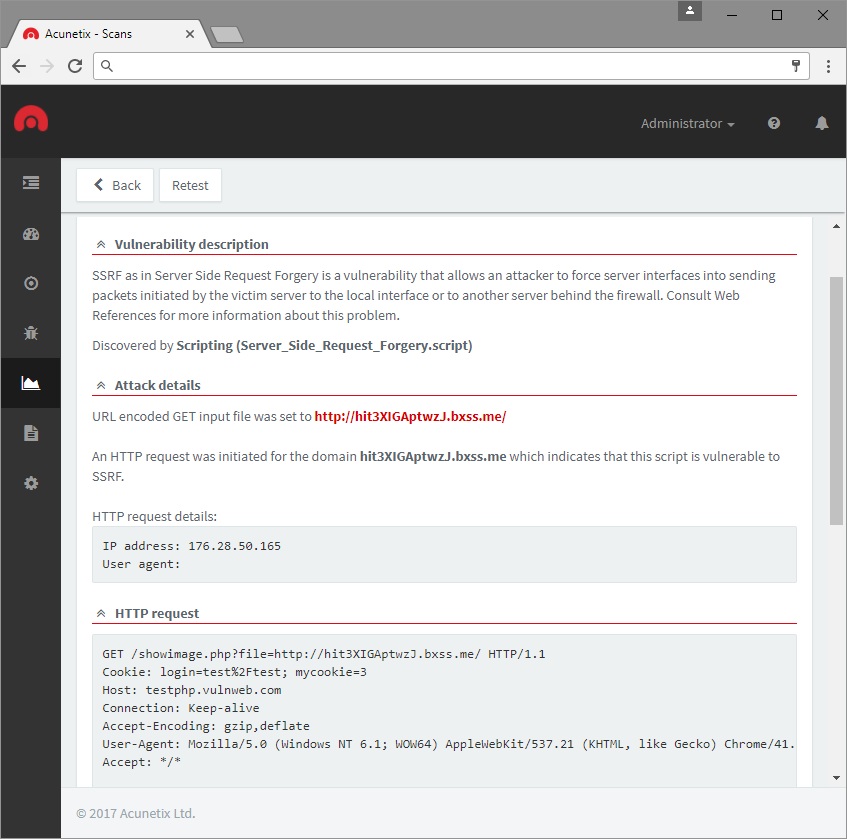
Figure 1: Port scanning with Server Side Request Forgery (SSRF) Although operating system vulnerabilities vary depending on the operating system in use, a common problem is privilege escalation bugs that enable the attacker to gain more access than they should be allowed. Open-source operating systems such as Linux and Android have a freely accessible source code and allow anyone to contribute, which could enable the introduction of vulnerabilities. However, the same vulnerabilities also occur in proprietary operating systems such as Microsoft Windows and Apple operating systems. All reputable vendors of operating systems provide patches regularly.
Unencrypted data that is in permanent storage or sent over a network is relatively easy for attackers to steal. Process hijacking occurs when an attacker takes over an existing computer process. Authentication and authorization failures enable attackers to access data that should be restricted to trusted users. Business logic vulnerability occurs when programmers do not consider unexpected cases arising in business logic. Attacks used against vulnerabilities in web applications include: Cross-site scripting (XSS) enables attackers to inject and run JavaScript-based malware when input checking is insufficient to reject the injected code. XSS can be persistent, when attackers save the malware in a data field and run it when the data is loaded; it can also be loaded using a malicious URL link (reflected XSS). Attackers can also insert malicious code into the domain object model. SQL injection and similar attacks manipulate database queries to gain unauthorized access to data.
Command injection is a form of code injection where the attacker places the malware in data fields or processes. The attacker might be able to take over the entire server. Cross-site request forgery (CSRF) is creating client requests that do malicious actions, such as an attacker changing a user's credentials. Server-side request forgery is similar to CSRF, but the request is forged from the server side and often exploits the enhanced privilege of the server. Business logic vulnerability occurs when programmers do not consider unexpected cases arising in business logic.
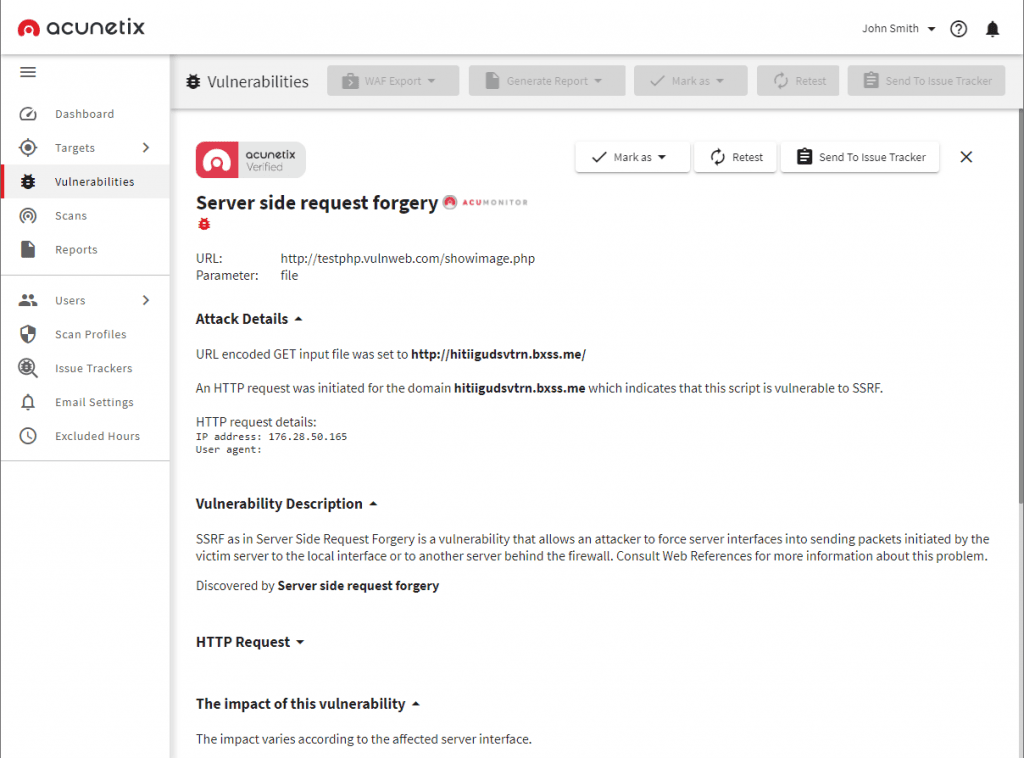
Figure 2: What is server-side request forgery (SSRF)? | Acunetix Memory safety (e.g. buffer overflow and dangling pointer bugs) Race condition Secure input and output handling Faulty use of an API Improper use case handling Improper exception handling Resource leaks, often but not always due to improper exception handling Preprocessing input strings before they are checked for being acceptable There is little evidence about the effectiveness and cost-effectiveness of different cyberattack prevention measures. Although estimating the risk of an attack is not straightforward, the mean time to breach and expected cost can be considered to determine the priority for remediating or mitigating an identified vulnerability and whether it is cost effective to do so. Although attention to security can reduce the risk of attack, achieving perfect security for a complex system is impossible, and many security measures have unacceptable cost or usability downsides. For example, reducing the complexity and functionality of the system is effective at reducing the attack surface. Successful vulnerability management usually involves a combination of remediation (closing a vulnerability), mitigation (increasing the difficulty, and reducing the consequences, of exploits), and accepting some residual risk. Often a defense in depth strategy is used for multiple barriers to attack. Some organizations scan for only the highest-risk vulnerabilities as this enables prioritization in the context of lacking the resources to fix every vulnerability. Increasing expenses is likely to have diminishing returns.
The vulnerability lifecycle begins when vulnerabilities are introduced into hardware or software. Detection of vulnerabilities can be by the software vendor, or by a third party. In the latter case, it is considered most ethical to immediately disclose the vulnerability to the vendor so it can be fixed. Government or intelligence agencies buy vulnerabilities that have not been publicly disclosed and may use them in an attack, stockpile them, or notify the vendor. As of 2013, the Five Eyes (United States, United Kingdom, Canada, Australia, and New Zealand) captured the plurality of the market and other significant purchasers included Russia, India, Brazil, Malaysia, Singapore, North Korea, and Iran. Organized criminal groups also buy vulnerabilities, although they typically prefer exploit kits. Even vulnerabilities that are publicly known or patched are often exploitable for an extended period. Security patches can take months to develop, or may never be developed. A patch can have negative effects on the functionality of software and users may need to test the patch to confirm functionality and compatibility. Larger organizations may fail to identify and patch all dependencies, while smaller enterprises and personal users may not install patches. Research suggests that risk of cyberattack increases if the vulnerability is made publicly known or a patch is released. Cybercriminals can reverse engineer the patch to find the underlying vulnerability and develop exploits, often faster than users install the patch. Vulnerabilities become deprecated when the software or vulnerable versions fall out of use. This can take an extended period of time; in particular, industrial software may not be feasible to replace even if the manufacturer stops supporting it.
An exploit is a method or piece of code that takes advantage of vulnerabilities in software, applications, networks, operating systems, or hardware, typically for malicious purposes. The term "exploit" derives from the English verb "to exploit," meaning "to use something to one’s own advantage." Exploits are designed to identify flaws, bypass security measures, gain unauthorized access to systems, take control of systems, install malware, or steal sensitive data. While an exploit by itself may not be a malware, it serves as a vehicle for delivering malicious software by breaching security controls. Estimates of the economic cost of cyberattacks that rely on exploits vary widely depending on methodology and scope; a 2020 McAfee/CSIS report estimated the global cost of cybercrime at more than US$1 trillion annually. In response to this threat, organizations are increasingly utilizing cyber threat intelligence to identify vulnerabilities and prevent hacks before they occur.
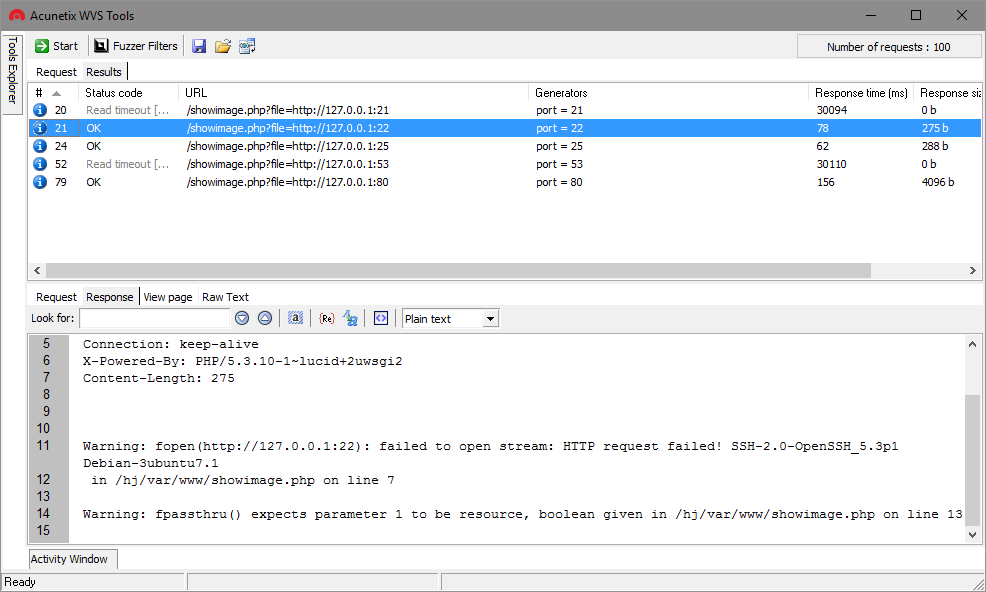
Figure 3: Port scanning with Server Side Request Forgery (SSRF) Remote exploits – Works over a network and exploits the security vulnerability without any prior access to the vulnerable system. Local exploits – Requires prior access or physical access to the vulnerable system, and usually increases the privileges of the person running the exploit past those granted by the system administrator.
Server-side exploits – Target vulnerabilities in server applications, such as web servers or database servers, often by sending maliciously crafted requests to exploit security flaws. Client-side exploits – Target vulnerabilities in client applications, such as web browsers (browser exploits) or media players. These exploits often require user interaction, like visiting a malicious website or opening a compromised file. Exploits against client applications may also require some interaction with the user and thus may be used in combination with the social engineering method.
Code execution exploits – Allow attackers to execute arbitrary code on the target system, potentially leading to full system compromise. Denial-of-service (DoS) exploits – Aim to disrupt the normal functioning of a system or service, making it unavailable to legitimate users. Privilege escalation exploits – Enable attackers to gain higher privileges on a system than initially granted, potentially leading to unauthorized actions. Information disclosure exploits – Lead to unauthorized access to sensitive information due to vulnerabilities in the system.
Buffer overflow – Attackers send more data to a buffer than it can handle, causing it to overflow and overwrite adjacent memory, potentially allowing arbitrary code execution. SQL injection – Malicious SQL code is inserted into input fields of web applications, enabling attackers to access or manipulate databases. Cross-site scripting (XSS) – Attackers inject malicious scripts into web pages viewed by other users, potentially leading to session hijacking or data theft. Cross-site request forgery (CSRF) – Attackers trick users into performing actions they did not intend, such as changing account settings, by exploiting the user's authenticated session.
Proxy pivoting is the practice of channeling traffic through a compromised target using a proxy payload on the machine and launching attacks from the computer. This type of pivoting is restricted to certain TCP and UDP ports that are supported by the proxy. VPN pivoting enables the attacker to create an encrypted layer to tunnel into the compromised machine to route any network traffic through that target machine, for example, to run a vulnerability scan on the internal network through the compromised machine, effectively giving the attacker full network access as if they were behind the firewall. Typically, the proxy or VPN applications enabling pivoting are executed on the target computer as the payload of an exploit. Pivoting is usually done by infiltrating a part of a network infrastructure (as an example, a vulnerable printer or thermostat) and using a scanner to find other devices connected to attack them. By attacking a vulnerable piece of networking, an attacker could infect most or all of a network and gain complete control.
Application security (AppSec) includes all tasks that introduce a secure software development life cycle to development teams. Its final goal is to improve security practices and, through that, to find, fix and preferably prevent security issues within applications. It encompasses the whole application life cycle from requirements analysis, design, implementation, verification as well as maintenance. Web application security is a branch of information security that deals specifically with the security of websites, web applications, and web services. At a high level, web application security draws on the principles of application security but applies them specifically to the internet and web systems. The application security also concentrates on mobile apps and their security which includes iOS and Android Applications. Web Application Security Tools are specialized tools for working with HTTP traffic, e.g., Web application firewalls.
Design review. Before code is written the application's architecture and design can be reviewed for security problems. A common technique in this phase is the creation of a threat model. White-box testing, or code review. Critical examination of internal structure, architecture, design, etc. Black-box testing. Tests functionality rather than internal structure. Automated Tooling. Many security tools can be automated through inclusion into the development or testing environment. Examples of those are automated DAST/SAST tools that are integrated into code editor or CI/CD platforms. Coordinated vulnerability platforms. These are hacker-powered application security solutions offered by many websites and software developers by which individuals can receive recognition and compensation for reporting bugs.
Broken access control Cryptographic failures Injection Insecure design Security misconfiguration Vulnerable and outdated components Identification and authentification failures Software and data integrity failures Security logging and monitoring failures* Server-side request forgery (SSRF)* Implement access control Use cryptography the proper way Validate all input & handle exceptions Address security from the start Secure by default configurations Keep your components secure Implement digital identity Use browser security features Implement security logging and monitoring Stop server-side request forgery Static application security testing (SAST) analyzes source code for security vulnerabilities during an application's development. Compared to DAST, SAST can be utilized even before the application is in an executable state. As SAST has access to the full source code it is a white-box approach. This can yield more detailed results but can result in many false positives that need to be manually verified. Dynamic application security testing (DAST, often called vulnerability scanners) automatically detects vulnerabilities by crawling and analyzing websites. This method is highly scalable, easily integrated and quick. DAST tools are well suited for dealing with low-level attacks such as injection flaws but are not well suited to detect high-level flaws, e.g., logic or business logic flaws. Fuzzing tools are commonly used for input testing. Industry application security research highlights increasing risks related to insecure APIs, client-side code tampering, and runtime exploitation, reinforcing the importance of comprehensive dynamic and runtime security testing. Interactive application security testing (IAST) assesses applications from within using software instrumentation. This combines the strengths of both SAST and DAST methods as well as providing access to code, HTTP traffic, library information, backend connections and configuration information. Some IAST products require the application to be attacked, while others can be used during normal quality assurance testing. Runtime application self-protection augments existing applications to provide intrusion detection and prevention from within an application runtime. Dependency scanners (also called software composition analysis) try to detect the usage of software components with known vulnerabilities. These tools can either work on-demand, e.g., during the source code build process, or periodically.
SSRF occurs when a web application fetches a remote resource without validating the user-supplied URL, allowing attackers to coerce the server into sending requests to internal resources, metadata endpoints, or loopback interfaces. In modern web infrastructure, server-side request forgery (ssrf) represents a critical failure mode in security controls. According to A10:2021 - Server-Side Request Forgery and documented under CWE-918: Server-Side Request Forgery (SSRF), applications failing to enforce proper controls at this layer expose their attack surface to automated crawlers, botnets, and skilled penetration testers.
When evaluating target perimeters, threat actors systematically probe for this condition using fingerprinting engines like Nmap, Nuclei, and custom fuzzing scripts. If left unresolved, this weakness can be chained with auxiliary application vulnerabilities to achieve elevated privileges, exfiltrate sensitive data, or bypass downstream security filters. Direct compromise of confidentiality, integrity, or service availability depending on attack chain context.
To eliminate this vulnerability, apply the following hardened configurations to your edge web server or application codebase: Run the following terminal command to audit and verify that your production fixes are actively enforced: Founder & Principal Security Researcher at WebScanify. Focused on automated attack surface management, OWASP Top 10 remediation, and cryptographic infrastructure defense. Reviewed in accordance with OWASP ASVS and NIST standards.
WebScanify tests your entire perimeter against 100+ critical security vulnerabilities, weak SSL ciphers, and misconfigured headers in under 3 minutes. Server-side request forgery (SSRF) is a vulnerability where an attacker makes a server send HTTP requests to a destination the attacker chooses. The classic impact is credential theft: one request from a vulnerable image-resizer to http://169.254.169.254/ and the attacker walks out with the instance's IAM role. It is catalogued as CWE-918 .
SSRF is ranked A10 in the OWASP Top 10 2021 , where it was added on the strength of community survey signal rather than scanner data, because most SSRF lives in the long tail of bespoke "fetch this URL" features that no generic scanner covers. Of all the modern bugs, SSRF is the one I spend the most time on in cloud engagements. The metadata-service surface is where these chains finally land impact, and most teams underestimate how thin their internal allowlists actually are once you start chasing redirects and DNS rebinding.
This is the deep-dive companion to the web application security vulnerabilities taxonomy . I cover the mechanism, the breach that made every security team care about it, every major variant with a working exploit against the ssrf-basic lab in the techearl-labs repo, and then turn around and cover the defences (IMDSv2, allowlists done right, egress firewalling) in equal depth. The tools that automate the discovery side live in the best SSRF tools for 2026 listicle.
Server-side request forgery is what happens when an application takes a URL (or any value that gets used as part of a URL) from the user and then has its own backend make that request. The attacker does not get to make the request directly; the server makes it on the attacker's behalf, from inside whatever network position the server occupies. That is the entire shape of the bug, and it is also the reason it matters: the server's network position is almost always more privileged than the attacker's.
A normal request is ?url=https://example.com/feed.xml .
An attacker request is ?url=http://169.254.169.254/latest/meta-data/iam/security-credentials/ , which on an EC2 instance running IMDSv1 returns the names of the IAM roles attached to the instance. A second request peels off the actual credentials. From there the attacker has whatever the role was permitted to do.
SSRF is distinct from two siblings it often gets confused with. Open redirect changes where the user's browser navigates after a redirect (a phishing aid, not a server-side primitive). Remote file inclusion is SSRF's older cousin where the fetched content is then executed as code ( include($_GET['url']) ); SSRF stops at the fetch, which is enough on its own once the target is a metadata service or an internal admin panel.
The reason every cloud security team takes SSRF seriously is one breach in 2019. A former AWS engineer, Paige Thompson, used an SSRF in a misconfigured ModSecurity web application firewall running on an EC2 instance in Capital One's infrastructure to reach the EC2 instance metadata service version 1 . The metadata endpoint returned the temporary IAM credentials attached to the instance. With those credentials, Thompson listed and exfiltrated S3 buckets containing data on roughly 106 million Capital One customers and applicants (about 100 million in the US, 6 million in Canada). Capital One disclosed the breach on July 29, 2019. Thompson was indicted under the Computer Fraud and Abuse Act, convicted in 2022, and sentenced in 2022 to time served plus five years of probation.
The mechanics are worth pinning down because they are the template every cloud-era SSRF follows: AWS released IMDSv2 on November 19, 2019 (about three months after the Capital One disclosure) specifically to break this attack chain. New EC2 launches default to IMDSv2-required on most modern AMIs, but instances launched before that date, or with explicit IMDSv1 configuration, are still out there . Greenfield is mostly safe; brownfield is not.
Variant axes for SSRF are: does the response come back to the attacker (basic vs blind), is the attacker hitting a metadata endpoint or an internal service, and does the bypass live in URL parsing or DNS resolution. Pick one from each axis and you have a real attack class. The simplest case. The server fetches the URL and includes the response body in its own response to the attacker. The PHP file_get_contents example above is this. The attacker reads everything the server reads. Useful for hitting internal admin panels, internal HTTP APIs, and anything else inside the perimeter that does not expect to receive attacker-shaped requests.
The server fetches the URL but discards the body. Maybe it only logs the HTTP status code, maybe it just notes whether the fetch succeeded. The attacker reads nothing directly and has to infer state via: Blind SSRF maps internal networks one port at a time. Slow, scriptable, and what most modern SSRF actually looks like, because frameworks have mostly stopped echoing fetch responses verbatim.
The most elegant SSRF variant and the one allowlist authors keep missing. The attacker registers a hostname under their control with a very short TTL DNS record. On the first lookup, the record points at an innocuous public IP (passes the allowlist). On the second lookup, milliseconds later, it points at 127.0.0.1 or 169.254.169.254 or an internal RFC1918 address. The application validates the URL, sees the safe IP, then re-resolves at connection time and connects to the dangerous IP.
The window between check and use is the bug. 2. System Architecture & Core Working Principles The fix is not "block private IPs in the input" (the input does not contain a private IP at validation time). The fix is to resolve the hostname once, validate the resolved IP, and then connect by IP not by hostname. Or to use an HTTP client that pins the resolved address. More on this in the defences section.
Every major cloud provider exposes an instance metadata service on the link-local address 169.254.169.254 . Each works slightly differently: The pattern across the post-Capital-One designs is identical: require something an SSRF cannot easily forge. AWS chose PUT + a header. GCP and Azure chose a custom request header. All three defeat the naive GET arbitrary URL SSRF primitive. They do not defeat an SSRF that lets the attacker control the HTTP method or arbitrary headers, which is a separate (and rarer) failure mode.
If the HTTP client is libcurl with all protocols enabled (the default in many language bindings), the attacker is not limited to http:// . The interesting wrappers: The fix is to restrict the scheme to http and https explicitly, then to disallow the rest. Curl's CURLOPT_PROTOCOLS_STR (or CURLOPT_PROTOCOLS on older versions) sets this per handle. Most language wrappers expose it.
The newest SSRF surface is the tool-calling pattern in autonomous coding and browsing systems. A user (or a third-party document the system was told to "read") supplies a URL, and the orchestrator's fetch_url tool retrieves it. From the orchestrator's network position. With whatever credentials the orchestrator carries. This is just SSRF with a new front door, but the front door is wide: a prompt-injection payload in a fetched page can rewrite the next URL the tool is asked to fetch, including a metadata IP. Defences are the same as the rest of this article: scheme allowlist, DNS-pinned client, default-deny egress, IMDSv2-required hop-limit-1 on every host the orchestrator runs on.
The ssrf-basic lab in the techearl-labs repo is a small PHP app with three vulnerable endpoints and two internal-only backend services (a mock admin panel and a mock AWS IMDSv1) on the Docker network. Bring it up with: The app listens on http://localhost:8082 . The two backend services have no published ports on purpose; the only way to reach them is to route through the SSRF.
The vulnerable endpoint is /fetch.php , which passes $_GET['url'] straight to file_get_contents : The response is the HTML of the internal admin panel. From the public-facing app's perspective the perimeter is intact; from the attacker's perspective the perimeter does not exist, because the perimeter does not apply to outbound requests originating inside the network.
The response is a JSON blob containing AKIAIOSFODNN7EXAMPLE (the documented AWS example access key, not a real one). In production this URL is http://169.254.169.254/latest/meta-data/iam/security-credentials/
The "better" endpoint is /fetch-allowlist.php , which checks parse_url($url)['host'] against ['example.com', 'api.example.com'] before fetching. Looks safe. Is not: The URL has the form http://user@host/ . PHP's parse_url reports the host as example.com (the segment before @ , which is the userinfo segment). file_get_contents then makes the request, and the HTTP authority is actually ssrf-basic-internal (the segment after @ ). The allowlist passes; the fetch lands on the internal target. Substring matching against parse_url output is a recurring own-goal in real codebases.
The third endpoint, /fetch-blind.php , fetches the URL with a 5-second timeout and returns only "OK" or "Timeout" with no body. No response leakage. Still mappable, via timing: Two distinguishable outcomes. The fast one means the destination accepted the connection; the slow one means it dropped or did not exist. Sweep an internal IP range and a port list against that oracle and you have a network map without ever seeing a response body.
The defences that work are layered. None of them on their own is enough; together they make the bug expensive to exploit even when the application code makes the original mistake. The single highest-impact change for any AWS workload. IMDSv2 requires the caller to first PUT to /latest/api/token with a X-aws-ec2-metadata-token-ttl-seconds header to retrieve a session token, and then to send that token in a X-aws-ec2-metadata-token header on every subsequent metadata request. An SSRF that only forwards a GET URL cannot satisfy either requirement.
The hop-limit setting matters too. Set HttpPutResponseHopLimit to 1 and the IMDS responses cannot be forwarded out of the instance (a container running on the host with NAT would otherwise see a hop count of 2). This blocks the container-escape variant of metadata theft. For organisation-wide enforcement, use a Service Control Policy that denies launching instances without http_tokens = required . Greenfield is then safe by construction; you only have to remediate brownfield.
The naive allowlist is parse_url($url)['host'] in approved_hosts . As exploit 3 above showed, that fails on the userinfo trick. The robust pattern is: In Python, the IP-pinning step looks like passing a custom socket.create_connection to urllib3 's pool, or using a library like requests-ip-rotator or httpx with a transport that takes a pre-resolved IP. In Node.js, set the lookup option on the HTTP request (or on the connection pool) to a function that returns the IP you already validated. In Go, set Resolver and the Dialer.Control callback. The point is that the IP you validated is the IP you connect to, not whatever DNS returns at connection time.
The cheapest defence and the one most teams skip. Public-facing application servers should not be able to make arbitrary outbound HTTP requests. Concretely: The combination of "IMDSv2 required" and "default-deny egress" reduces the cloud-metadata SSRF risk to essentially zero, even on application code that still has the original bug.
The HTTP client itself should be configured to refuse the dangerous protocols. For libcurl-based clients: Same idea in language wrappers: Python pycurl exposes it; Node.js node-fetch and undici only support http / https by default; PHP curl exposes CURLOPT_PROTOCOLS . Disable redirects entirely if the application does not need them, or follow at most one redirect and re-validate the destination after each hop.
Each of these is the same shape: a feature whose job is "fetch a URL", input control by the attacker, and a target reachable from the server that is not reachable from the internet. The fix in every case was a combination of input validation and tightening the network's outbound reach. Systems and network architect and Chief Technology Officer with more than two decades designing, building, and running production software, cloud and network architecture, Linux systems, and the bare metal underneath them, and lately working AI into the stack. A US Army veteran who served in Operation Iraqi Freedom. What I write here is drawn from the full arc of that work, across architecture, engineering, and operations, not any single job.
CSRF in 2026: how the classic GET/POST/JSON variants still work, what SameSite=Lax actually changed in 2020, and the defences that hold up: anti-CSRF tokens, Origin validation, Fetch Metadata, and custom headers. Remote code execution explained from the sink level up. Command injection, argument injection past escapeshellarg, server-side template injection, and direct eval, with a Dockerised lab that reproduces each one, plus the defences that actually contain blast radius.
Server-Side Request Forgery (SSRF) is a web security vulnerability that allows an attacker to cause the server-side application to make requests to unintended locations. In a typical SSRF attack, the attacker might cause the server to make a connection to internal-only services within the organization’s infrastructure or to arbitrary external systems, potentially leaking sensitive data.
SSRF occurs when an application accepts user-controllable input that specifies a URL or network resource, and then uses this input to make a request on behalf of the server without proper validation. In this type of SSRF, the attacker tricks the server into making a request to itself (via localhost or 127.0.0.1). The server fetches its own /admin page, which is normally protected. Since the request is local, the server allows full admin access.
Sometimes the server can access internal systems (with private IPs like 192.168.x.x) that normal users can’t reach. These internal systems are often less secure and may not require authentication. Blind SSRF happens when the server makes the request, but you don’t see the result in the response. Use a service like Burp Collaborator or your own HTTP server to see if the server makes a request to you.
Some applications try to prevent SSRF by using a whitelist—only allowing URLs that start with or contain trusted values. Sometimes, SSRF filters only allow URLs from trusted domains, but if that trusted domain has an open redirection vulnerability, attackers can use it to trick the server into going somewhere else. Some structured data formats (like XML, YAML, SVG) allow the inclusion of URLs inside them. When the server parses this data, it might make a request to the URL specified.
DNS rebinding is a technique that can bypass SSRF protections by changing the DNS resolution of a hostname between validation checks and the actual request. Note : This guide is for educational purposes and authorized security testing only. Always obtain proper authorization before testing systems for vulnerabilities.
Find Server-Side Request Forgery before someone else does. A fast, async SSRF scanner that hammers a target through 14 attack phases and confirms blind SSRF out-of-band instead of guessing. Modern Next.js apps have their own SSRF sinks that the generic phases can't reach, so they get a dedicated phase: Blind SSRF can't be proven from the HTTP response — the only real signal is the target calling you . Point wildcard DNS ( *.oob.example.com ) at a host the target can reach, then: 3. Software Implementation, Frameworks & Protocols Every callback-style payload gets a unique token ‹token›.oob.example.com . An inbound hit = confirmed SSRF , attributed to the exact payload/header/parameter that carried it (attack type OOB:… , method OOB Interaction ).
II --oob-mode selfhosted opens an unauthenticated inbound HTTP listener so the target can reach it. It only logs requests and always returns a benign response, but bind it deliberately and expose it only for the scan. Without OOB, use -b with a Burp Collaborator host and watch Collaborator yourself. Reports land in output/
Each finding records the URL, attack type, exact payload, response code/size, verification method, timestamp, and baseline diff. For authorized security testing and education only. You are responsible for having permission to test any target. The authors assume no liability for misuse or damage.
Server-Side Request Forgery (SSRF) is one of the most dangerous and consistently exploited web vulnerabilities of the last five years. It made the OWASP Top 10 in 2021 and has been weaponized in some of the biggest breaches in cloud history âII including the Capital One breach that exposed 100 million records. If you’re doing web application pentesting or bug bounty hunting in 2026 and you’re not hunting SSRF systematically, you’re leaving money and flags on the table.
This guide covers everything: what SSRF is, how to find it, how to exploit it, cloud metadata attacks, blind SSRF techniques, and every filter bypass worth knowing. SSRF happens when an attacker can make a server-side application send HTTP requests to an arbitrary destination âII one the attacker controls or one that would normally be off-limits.
The classic scenario: a web app has a feature that fetches a URL server-side (thumbnail generator, URL preview, webhook validator, PDF renderer, etc.). If the app doesn’t validate what URLs it will request, an attacker can point it at internal services, cloud metadata APIs, or other sensitive endpoints the attacker couldn’t reach directly. Most targets today run on cloud infrastructure. Every major cloud provider exposes a metadata API accessible at a well-known internal IP âII and those APIs contain credentials, tokens, and configuration data for the entire instance.
Successful SSRF against a cloud host = access to IAM credentials = potential full account takeover. That’s why this vulnerability class gets critical-severity ratings and five-figure bug bounties. XXE vulnerabilities can chain into SSRF when external entities trigger server-side requests. Worth chaining if you find XML input.
If you get a DNS lookup or HTTP request in Collaborator, SSRF is confirmed âII even if the response to you is empty. That’s blind SSRF, and it’s still exploitable. If any of these return different responses (content, timing, error messages), internal services are reachable. That’s temporary AWS credentials you can use with aws-cli to operate as the EC2 instance role.
AWS introduced IMDSv2 as a defense specifically against SSRF. It requires a PUT request with a session token first: IMDSv2 defeats simple SSRF because the PUT step typically can’t be replicated through a basic URL-fetch SSRF. But if the SSRF allows custom headers, or if the application follows redirects, it may still be exploitable. GCP’s metadata API requires the Metadata-Flavor: Google header. If the vulnerable application passes through custom headers, you can exploit it. If not, look for applications that make server-side requests and pass headers along.
Many SSRF vulnerabilities don’t return server responses to the attacker. The app makes the request but only uses the result internally (or discards it). This is “blind SSRF” âII harder to exploit but still valuable. Any DNS lookup or HTTP request to your callback server confirms SSRF even with zero response. This writes a cron job to Redis that executes a reverse shell âII if Redis is running as root or the cron user.
Unauthenticated Docker socket = container escape, new container with host volume mount, full host compromise. For sophisticated bypasses, DNS rebinding attacks make an external domain first resolve to a legitimate IP (passing blocklist check), then resolve to an internal IP on the subsequent request. Requires setup but bypasses most DNS-based filters. The gopher:// scheme lets you send raw bytes over a TCP connection âII useful for protocols that don’t speak HTTP: Same pattern âII if user input reaches axios.get(url) or fetch(url) without validation, it’s SSRF.
These often bypass simple filters because the renderer is a full browser âII it may also execute JavaScript, enabling DOM-based attacks on internal services. Need a VPS for your SSRF callback server? Vultr and DigitalOcean both have cheap $4-6/month instances you can spin up, run interactsh or a redirect server, and tear down when the engagement is over.
SSRF is one of those vulnerabilities that scales with your target. Against a startup with EC2 instances and no IMDSv2, it’s a credential dump and potential full account takeover. Against a hardened cloud deployment, it still opens doors to internal services that weren’t meant to be reachable. Either way, it’s worth hunting. Want professional pentest reports written for your findings? CipherWrite handles technical writing for security professionals âII from bug bounty writeups to full red team reports.
Learn SSRF the way it's actually exploited — hands-on, against a live target. Turn a harmless URL-preview feature into a doorway to internal services and cloud metadata in the FetchFlow lab. Server-Side Request Forgery is a vulnerability that lets an attacker make a server issue HTTP requests to destinations of the attacker's choosing. The crucial detail is where the request comes from : because it originates on the server, it inherits the server's network position — reaching internal services, loopback-bound admin panels, and cloud metadata endpoints that are completely unreachable from the public internet.
SSRF hides inside convenient features. Anything that fetches a URL on your behalf — a link-preview generator, a webhook validator, a PDF renderer, an image proxy, an import-by-URL tool — is a candidate. If the destination isn't strictly validated, that helpful feature becomes a pivot into the network. Admin panels and internal APIs that return 403 to the outside world are often wide open from the server itself. SSRF lets an attacker speak to them directly, bypassing the network boundary that was supposed to protect them.
On cloud platforms, a special link-local address at 169.254.169.254 serves instance metadata — and on some configurations, temporary credentials. SSRF that reaches it can escalate from a web bug to cloud account access. SSRF is significant enough to hold its own dedicated slot — A10:2021 – Server-Side Request Forgery — in the current OWASP Top 10. It was promoted into the list in the 2021 revision because of how common and how damaging it has become in cloud-hosted applications. The impact classes below are what earn it a high-severity rating.
The core lesson of Room 8 is that automation and human judgment are a pipeline, not a competition . An autonomous scan maps the attack surface in minutes — the exposed paths, the forbidden endpoints, the open ports. But SSRF is interaction-based: it only reveals itself when you craft a request and watch where the server actually goes. That's the gap a human closes.
In the lab, you run a real PhantomRed scan against FetchFlow, read the findings it surfaces, then take over manually to prove the SSRF the scanner can't see: Room 9 takes this a step further with a dedicated XXE lab , where an XML parser can be turned into an SSRF primitive — the two vulnerability classes chain together directly.
The FetchFlow lab is live and free to play. Run a real autonomous scan, then exploit the SSRF the scanner can't see — reach the internal admin panel and the cloud metadata endpoint, end to end. In 2019, a single SSRF vulnerability led to the breach of over 100 million customer records at a major US bank. The attacker exploited a misconfigured web application firewall to make requests to the cloud provider's internal metadata service, extracted temporary credentials, and used those credentials to access private S3 buckets. Total cost: hundreds of millions in fines, remediation, and reputational damage.
SSRF earned its own category in the OWASP Top 10 (2021) for a reason. It is consistently one of the highest-impact findings in bug bounty programs, and it remains one of the most under-tested vulnerability classes in production applications. This guide walks through how SSRF works, where to find it, how to exploit it step by step, and how to prevent it. Server-Side Request Forgery happens when an application takes a URL or network address from user input and makes a server-side request to that address without proper validation.
The critical distinction: the request originates from the server , not your browser. That server typically sits inside a private network, behind firewalls, with access to internal services, cloud metadata endpoints, and other infrastructure that is invisible from the outside. You are not attacking the server directly. You are convincing it to attack itself, or its neighbors, on your behalf.
4. Practical Deployment, Analysis & Case Studies SSRF does not live in one specific feature. It hides anywhere the application makes outbound requests based on user-supplied input. URL preview and fetchers. Social media cards, link previews, and URL validators all fetch remote content server-side. Supply an internal address instead of a public URL.
Webhook configurations. Applications that let you configure webhook URLs will make HTTP requests to whatever endpoint you specify. Point it at http://169.254.169.254 and see what comes back. PDF and document generators. HTML-to-PDF engines that render user-supplied HTML will resolve embedded images and stylesheets. Embed an tag pointing to an internal host.
File import by URL. "Import from URL" features in file upload flows. Instead of uploading a file, the server fetches it from a URL you provide. Image processing. Avatar uploads that accept URLs, image resizing services, and screenshot tools. Any feature that downloads an image from a user-supplied address.
API integrations. Applications that proxy API calls or allow users to configure third-party service endpoints. The server fetches the resource and returns the full response to you. This is the jackpot. You can read internal files, query metadata APIs, and enumerate internal services directly. Example: A URL preview feature that displays the fetched page content. Change the URL to http://localhost:8080/admin and the admin panel HTML comes back in the response.
The server makes the request, but you never see the response . The application might return a generic "success" or "error" message regardless of what happened on the backend. Exploitation approach: Use an out-of-band channel. Point the SSRF at a server you control (a Burp Collaborator instance or a simple HTTP listener). If you receive a callback, you have confirmed the SSRF. From there, you can infer internal network topology by timing differences: requests to open ports return faster than requests to closed ports or non-existent hosts.
You get partial feedback . Maybe the response length differs, the response time varies, or error messages change based on whether the internal resource exists. Enough signal to map internal services without seeing full responses. Here is the practical walkthrough. We will use a deliberately vulnerable URL preview feature as our target. If the response includes the server's own default page, internal service banner, or any content that is not publicly accessible, you have confirmed SSRF.
Different response times or error messages for each port reveal which services are running internally. This is where SSRF becomes critical. Every major cloud provider exposes an internal metadata service at a well-known IP: On AWS with IMDSv1, a successful request to the IAM credentials endpoint returns temporary AccessKeyId , SecretAccessKey , and Token values. Those credentials grant whatever permissions the instance role has: S3 buckets, databases, other AWS services.
This reads arbitrary files from the server's filesystem. Environment variables frequently contain database passwords, API keys, and session secrets. Most modern applications have some level of URL validation. Here is how testers evaluate whether those filters are sufficient. Maintain an allowlist of permitted domains and IP ranges. Deny everything else by default.
Validate and sanitize the resolved IP address , not just the hostname. Check after DNS resolution to prevent rebinding. Block requests to private IP ranges (10.x, 172.16-31.x, 192.168.x, 127.x, 169.254.x, ::1). Disable unnecessary URL schemes . Only allow http:// and https:// . Block file:// , gopher:// , dict:// , ftp:// . Do not follow redirects on server-side requests, or re-validate the destination after each redirect.
Upgrade to IMDSv2 on AWS instances. IMDSv2 requires a PUT request with a token header, which SSRF payloads through GET-based fetchers cannot satisfy. Apply network segmentation . The web application server should not have network access to sensitive internal services it does not need.
Strip or ignore the response body when only a status check is needed. Do not reflect fetched content to the user. Implement egress filtering at the firewall level. Restrict outbound connections from application servers to known, necessary destinations. Log and monitor outbound requests from application servers. Alert on connections to metadata endpoints or internal IP ranges.
SSRF is deceptively simple. An application fetches a URL you control. But the blast radius, especially in cloud environments, is enormous. One parameter, one metadata endpoint, one set of temporary credentials, and you are inside the infrastructure. The patterns here are not theoretical. They are the exact techniques used in real-world pentests and bug bounty programs. The Capital One breach, countless HackerOne reports, and OWASP's decision to give SSRF its own Top 10 category all point to the same conclusion: this vulnerability class demands attention.
If you are building applications, audit every feature that makes server-side HTTP requests. If you are testing them, SSRF should be near the top of your checklist. Want hands-on practice? Our platform includes isolated lab environments where you can practice SSRF exploitation techniques against deliberately vulnerable applications, from basic in-band SSRF to cloud metadata extraction, in a safe and legal setting.
A realistic 7-day roadmap to finding your first web vulnerability in a bug bounty program, covering tools, methodology, and the mindset that gets results. The 8 most common techniques attackers use to bypass authentication, with defensive patterns that actually work. Separating hype from reality. What AI can and cannot do in penetration testing, and why the human pentester is not going anywhere.
Server-side request forgery (SSRF) is a web security vulnerability that allows an attacker to induce the server-side application to make requests to an unintended location. SSRF vulnerabilities may enable you to communicate with back-end systems that are not normally publicly available via a compromised server. This is often done via non-routable private IP addresses. You can use Intruder to enumerate these IP addresses and potentially gain access to these back-end systems.
Before you test for SSRF, you need to identify a suitable attack vector. This could be a request with a parameter that contains a full or partial URL, for example. To learn more about identifying SSRF attack surface, see Finding hidden attack surface for SSRF vulnerabilities . You can follow along with the process below using the Basic SSRF against a backend system lab from our Web Security Academy.
Use Intruder to look for internal IP addresses or private host names that give a different response. In the lab, you can do this as follows: You can also use Intruder to look for directories, if you find an interesting internal IP address or private host name. For more information, see Burp Intruder .
Server-side request forgery has quietly become one of the most impactful vulnerability classes in cloud-native infrastructure. When an application fetches a URL on your behalf — importing a profile picture, rendering a PDF, calling a webhook — and that URL isn’t properly validated, you can redirect the server’s request to places it was never meant to go. Internal services. Cloud metadata endpoints. The AWS credentials sitting one HTTP request away at 169.254.169.254 .
The problem with testing for SSRF is that the interesting cases are almost always blind. The server fetches your URL, but you don’t see the response. You need to infer exploitation through side channels — timing differences, response size anomalies, or out-of-band callbacks that prove the server reached your controlled infrastructure. And even when you find a promising parameter, the application’s URL validation might block your payloads, requiring a cascade of bypass techniques specific to the server-side technology stack.
I built Enigma’s SSRF engine to automate this entire process. It implements a 4-phase methodology — discover SSRF-prone features, select internal targets, apply filter bypasses, and confirm exploitation via out-of-band callbacks — as a single autonomous scanner. It generates payloads from composable building blocks, orders them by success probability, and uses statistical analysis to detect blind SSRF through timing and response size side channels when direct observation isn’t possible.
5. Performance Evaluation & Extended Technical Observations The methodology and techniques implemented here draw from the published work of several researchers: Every SSRF scan follows four phases. Each phase builds on what the previous one learned: This isn’t a linear pipeline — it loops. When bypass techniques are exhausted for one target, the engine returns to discovery for new parameters. When a bypass is blocked, it tries the next technique in the stack-specific priority order. The phases are states in a state machine, not steps in a checklist.
SSRF doesn’t live in random parameters. It lives in features that fetch URLs by design — webhook callbacks, PDF generators, image processors, URL importers. The discovery phase identifies these features by analyzing HTTP traffic patterns. Each feature type maps to a database of likely-vulnerable parameter names. Webhooks map to url , callback , callback_url , webhook_url , notification_url , ping_url . PDF generators map to url , source , html , template . The engine doesn’t just look for ?url= — it understands that a POST to /api/webhooks with a callback_url field in the JSON body is a higher-priority SSRF candidate than a query parameter named redirect .
The discovery command integrates with Caido’s HTTP proxy, generating HTTPQL filter queries to surface candidates from captured traffic: Once you have a parameter that fetches URLs, the question becomes: where should you send it? The engine maintains payload generators for four target categories, ordered by impact: The highest-impact targets. Every major cloud provider exposes an instance metadata service at a link-local IP, and credentials fetched from it can compromise the entire cloud account.
The engine generates 49 cloud metadata payloads across all six providers, plus Kubernetes API server endpoints. For AWS specifically, it implements the two-step credential chain: first enumerate role names at the security-credentials path, then fetch the actual credentials for the discovered role. Port scanning and service fingerprinting through SSRF. The engine knows 30+ internal services by port, protocol, and response fingerprint: When a service is identified by its fingerprint regex, the engine generates service-specific exploitation payloads. Redis gets gopher-protocol command injection. Elasticsearch gets search and credential dump paths. Docker gets container creation for RCE.
Before fancy exploitation, the engine tests 22 common admin endpoints that are often only accessible from localhost: /admin , /phpmyadmin , /server-status , /actuator , /actuator/env , /debug/vars , /metrics , /health , /info . These are tested first because they have the highest success probability — many applications trust requests from 127.0.0.1 without additional authentication. When a subnet is known or guessed, the engine generates a cartesian product of hosts and critical ports, effectively using the SSRF as a port scanner for the internal network.
This is where the engine earns its keep. Most modern applications validate URLs before fetching them. The bypass phase implements three categories of evasion techniques, each with multiple variants. The simplest bypass category. When an application blocks 127.0.0.1 or 169.254.169.254 by string matching, alternative IP representations bypass the check while resolving to the same address: The engine also maintains 20+ localhost DNS names that resolve to 127.0.0.1 : localtest.me , 127.0.0.1.nip.io , spoofed.burpcollaborator.net , and others. These bypass IP-based checks entirely because the validation sees a hostname, not an IP.
For cloud metadata specifically, the engine generates all representations of 169.254.169.254 crossed with the four critical AWS IMDS paths, producing dozens of payloads from composable building blocks. The most technically interesting bypass category. This exploits the fact that the library validating the URL and the library making the HTTP request may parse the same URL differently.
Authority confusion — The @ symbol in URLs separates userinfo from host . Some parsers see the part before @ as the host; others see the part after: Fragment injection — The # character starts a URL fragment. Some parsers strip it, others don’t: Backslash normalization — Windows and cURL normalize \ to / , but many validators don’t: Unicode normalization — The deepest technique set, with 10+ variants exploiting how different parsers handle Unicode: Open redirect chaining — Using the target application’s own redirect endpoints as a proxy: Allowlist bypass — Subdomain spoofing ( 169.254.169.254.allowed.com ), partial match exploitation, and case variation.
Not all bypasses work equally against all technology stacks. The engine fingerprints the server-side technology from response headers and error messages, then prioritizes bypass techniques accordingly: When HTTP-based bypasses fail, the engine tries alternative URL schemes that the server’s HTTP client may support: The gopher protocol deserves special attention. It allows sending arbitrary bytes to any TCP port, which means SSRF-to-RCE through internal services becomes possible: This sends the Redis FLUSHALL command through the SSRF. The engine generates gopher payloads for Redis command injection (including webshell writes and SSH key injection), Memcached enumeration, SMTP email smuggling, and internal HTTP request forging.
The file protocol generator maintains a database of 50+ sensitive files across Linux, Windows, application configs, and cloud credential paths. The hardest part of SSRF testing. Most SSRF is blind — the server fetches your URL but you never see the response. The confirmation phase uses three methods: The primary confirmation method. The engine generates unique canary tokens and embeds them in payload URLs pointing to a controlled callback server ( poc-harness.com ). When the target server fetches the URL, the callback server records the connection: Each token is registered with full scan context — the target URL, parameter name, bypass technique used, and timestamp.
When a callback arrives minutes or hours later, the notification includes everything needed to understand what triggered it. Service-specific callbacks are also generated: Redis SLAVEOF replication pointing to the callback server, and Elasticsearch snapshot repository callbacks. The notification system fires across four channels simultaneously: Slack (rich Block Kit messages with context), desktop notifications ( notify-send ), terminal alerts (bell + colored output), and audio alerts.
When OOB callbacks aren’t possible, the engine falls back to statistical timing analysis. It measures response times across all payloads and looks for anomalies: The key insight: when a server tries to connect to an internal IP that exists but doesn’t respond on that port, the request hangs until timeout — producing a dramatically longer response time than a normal rejected request. A payload targeting 169.254.169.254:80 that takes 9 seconds when all other payloads take 200ms is strong evidence of SSRF, even without seeing the response.
The third confirmation method compares response sizes between internal and external target payloads. The engine separates payloads by target type, calculates average response sizes for each group, and flags significant differences: The autonomous scanner doesn’t just generate payloads and send them. It makes decisions about phase transitions, bypass selection, and impact assessment: The impact assessment is automatic. When cloud metadata credentials are leaked ( AccessKeyId + SecretAccessKey in the response), the engine classifies it as critical with a CVSS estimate of 9.8. When internal services are exposed but no credentials leak, it’s high severity. The classification drives how findings are reported and prioritized.
A key architectural decision: payloads are generated from composable building blocks, not maintained as static wordlists. This matters because the number of useful payloads is a cartesian product of independent dimensions: For a single cloud provider with a single bypass category. Across all providers, all bypass categories, and all target types, the engine can generate thousands of payloads — far more than a curated wordlist, and each one is structurally valid rather than a random guess.
Beyond parameter-based SSRF, the engine tests HTTP headers that applications commonly trust and forward: Each header is tested with canary URLs, localhost variants, and metadata endpoints. The engine uses baseline comparison — sending the request first without injection, then with — and flags responses that differ by more than 10% in size or 500ms in timing.
The --watch flag keeps the scanner running after all payloads are sent, listening for delayed callbacks. Some SSRF triggers are asynchronous — a webhook fires minutes after submission, a PDF renders in a queue, an import job processes overnight. The watch mode catches these. This is the full strategy map showing how all four phases connect, what bypass techniques are available, and how confirmation feeds back into the loop: Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Vulnerability%20%28computer%20security%29 • https://en.wikipedia.org/wiki/Exploit%20%28computer%20security%29 • https://en.wikipedia.org/wiki/Application%20security • https://www.webscanify.com/kb/ssrf-protection • https://techearl.com/server-side-request-forgery • https://0x3n1ty.github.io/writings/ssrf-comprehensive-guide/ • https://github.com/Dancas93/SSRF-Scanner • https://redteamguide.com/guides/ssrf-attack-guide-2026/ • https://www.phantomred.com/ssrf-tutorial.html • https://www.chakravue.io/blog/ssrf-exploitation-guide
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Server Side Request Forgery Vulnerability Scanner Tool.
[*] Initializing Burp Suite Spider & Vulnerability Engine for Server Side Request Forgery Vulnerability Scanner Tool... [✓] Burp Extender / Macro Automation Hook Synced ──────────────────────────────────────────────────────────────────────── [11:42:01.104] AUDIT Crawled dynamic endpoints | Injecting input vectors [11:42:01.218] FINDING Cymulate / Burp: Input sanitation check executed in parameter 'q' [11:42:01.312] VERIFY SafeBreach payload validation: Out-of-band interaction confirmed [11:42:01.405] REPORT Severity: Evaluated | Remediation: Enforce context-aware validation ──────────────────────────────────────────────────────────────────────── [✓] Burp Suite Audit Completed: Verified across OWASP Top 10 vectors
| Vulnerability Vector | Testing Tool | Injection Target | Severity | Remediation Status |
|---|---|---|---|---|
| SQL Injection (SQLi) | Burp Suite Professional | POST /api/auth/login | CRITICAL | PARAMETERIZED |
| Cross-Site Scripting (XSS) | SafeBreach / Cymulate | GET /search?q= | HIGH | CSP ENFORCED |
| Broken Object Level Access | Picus Security Audit | GET /user/account/840 | HIGH | RBAC APPLIED |
| Security Misconfiguration | AttackIQ Suite | HTTP Security Headers | MEDIUM | RESOLVED |