Complete Technical Paper Content — Ssh Brute Force Attack Detection And Blocking Script
Overview & System Context
Ssh Brute Force Attack Detection And Blocking Script: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~8558 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Fail2Ban is an intrusion prevention software framework. Written in the Python programming language, it is designed to prevent brute-force attacks. It is able to run on POSIX systems that have an interface to a packet-control system or firewall installed locally, such as iptables or TCP Wrapper.
Fail2ban operates by monitoring log files (e.g. /var/log/auth.log, /var/log/apache/access.log, etc.) for selected entries and running scripts based on them. Most commonly this is used to block selected IP addresses that may belong to hosts that are trying to breach the system's security. It can ban any host IP address that makes too many login attempts or performs any other unwanted action within a time frame defined by the administrator. It includes support for both IPv4 and IPv6. Optionally longer bans can be custom-configured for "recidivist" abusers that keep coming back. Fail2Ban is typically set up to unban a blocked host within a certain period, so as to not "lock out" any genuine connections that may have been temporarily misconfigured. However, an unban time of several minutes is usually enough to stop a network connection being flooded by malicious connections, as well as reducing the likelihood of a successful dictionary attack. Fail2Ban can perform multiple actions whenever an abusive IP address is detected: update Netfilter/iptables or PF firewall rules, TCP Wrapper's hosts.deny table, to reject an abuser's IP address; email notifications; or any user-defined action that can be carried out by a Python script. The standard configuration ships with popular filters, including Apache, lighttpd, sshd, vsftpd, qmail, Postfix and Courier Mail Server. Filters are defined by Python regexes, which may be conveniently customized by an administrator familiar with regular expressions. A combination of a filter and an action is known as a "jail" and is what causes a malicious host to be blocked from accessing specified network services. As well as the examples that are distributed with the software, a "jail" may be created for any network-facing process that creates a log file of access. Fail2ban is similar to DenyHosts, however, fail2ban can also be configured to monitor any service that logs login attempts to a log file, rather than just SSH, and rather solely relying on /etc/hosts.deny to block hosts, fail2ban supports other blocking mechanisms like Netfilter/iptables and TCP Wrappers.
DenyHosts, a log-based intrusion-prevention security tool Stockade, a rate-limiting approach to spam mitigation. OSSEC, an open-source host-based intrusion-detection system. A botnet is a group of Internet-connected devices, each of which runs one or more bots. Botnets can be used to perform distributed denial-of-service (DDoS) attacks, steal data, send spam, and allow the attacker to access the device and its connection. The owner can control the botnet using command and control (C&C) software. The word "botnet" is a portmanteau of the words "robot" and "network". The term is usually used with a negative or malicious connotation.
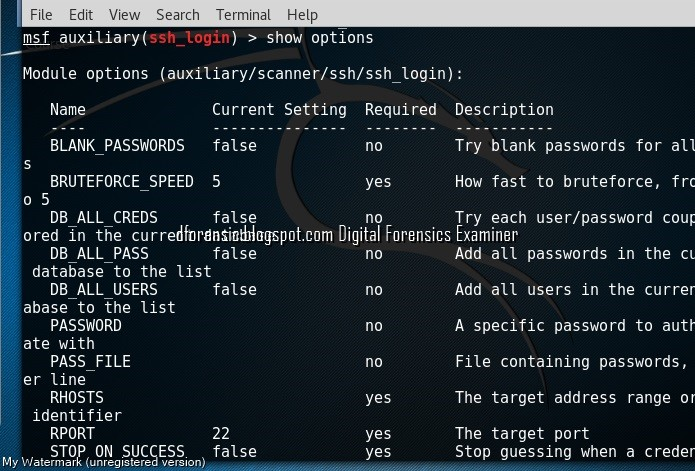
Figure 1: Digital Forensics Examiner: Digital Forensics: Brute Force Attack SSH The first botnets on the Internet used a client–server model to accomplish their tasks. Typically, these botnets operate through Internet Relay Chat networks, domains, or websites. Infected clients access a predetermined location and await incoming commands from the server. The bot herder sends commands to the server, which relays them to the clients. Clients execute the commands and report their results back to the bot herder. In the case of IRC botnets, infected clients connect to an infected IRC server and join a channel pre-designated for C&C by the bot herder. The bot herder sends commands to the channel via the IRC server. Each client retrieves the commands and executes them. Clients send messages back to the IRC channel with the results of their actions.
In response to efforts to detect and decapitate IRC botnets, bot herders have begun deploying malware on peer-to-peer networks. These bots may use digital signatures so that only someone with access to the private key can control the botnet, such as in Gameover ZeuS and the ZeroAccess botnet. Newer botnets fully operate over P2P networks. Rather than communicate with a centralized server, P2P bots perform as both a command distribution server and a client that receives commands. This avoids having any single point of failure, which is an issue for centralized botnets. In order to find other infected machines, P2P bots discreetly probe random IP addresses until they identify another infected machine. The contacted bot replies with information such as its software version and list of known bots. If one of the bots' version is lower than the other, they will initiate a file transfer to update. This way, each bot grows its list of infected machines and updates itself by periodically communicating to all known bots.
A hacker purchases or builds a Trojan and/or exploit kit and uses it to start infecting users' computers, whose payload is a malicious application—the bot. The bot instructs the infected PC to connect to a particular command-and-control (C&C) server. (This allows the botmaster to keep logs of how many bots are active and online.) The botmaster may then use the bots to gather keystrokes or use form grabbing to steal online credentials and may rent out the botnet as DDoS and/or spam as a service or sell the credentials online for a profit. Depending on the quality and capability of the bots, the value is increased or decreased. Newer bots can automatically scan their environment and propagate themselves using vulnerabilities and weak passwords. Generally, the more vulnerabilities a bot can scan and propagate through, the more valuable it becomes to a botnet controller community. Computers can be co-opted into a botnet when they execute malicious software. This can be accomplished by luring users into making a drive-by download, exploiting web browser vulnerabilities, or by tricking the user into running a Trojan horse program, which may come from an email attachment. This malware will typically install modules that allow the computer to be commanded and controlled by the botnet's operator. After the software is downloaded, it will call home (send a reconnection packet) to the host computer. When the reconnection is made, depending on how it is written, a Trojan may then delete itself or may remain present to update and maintain the modules.
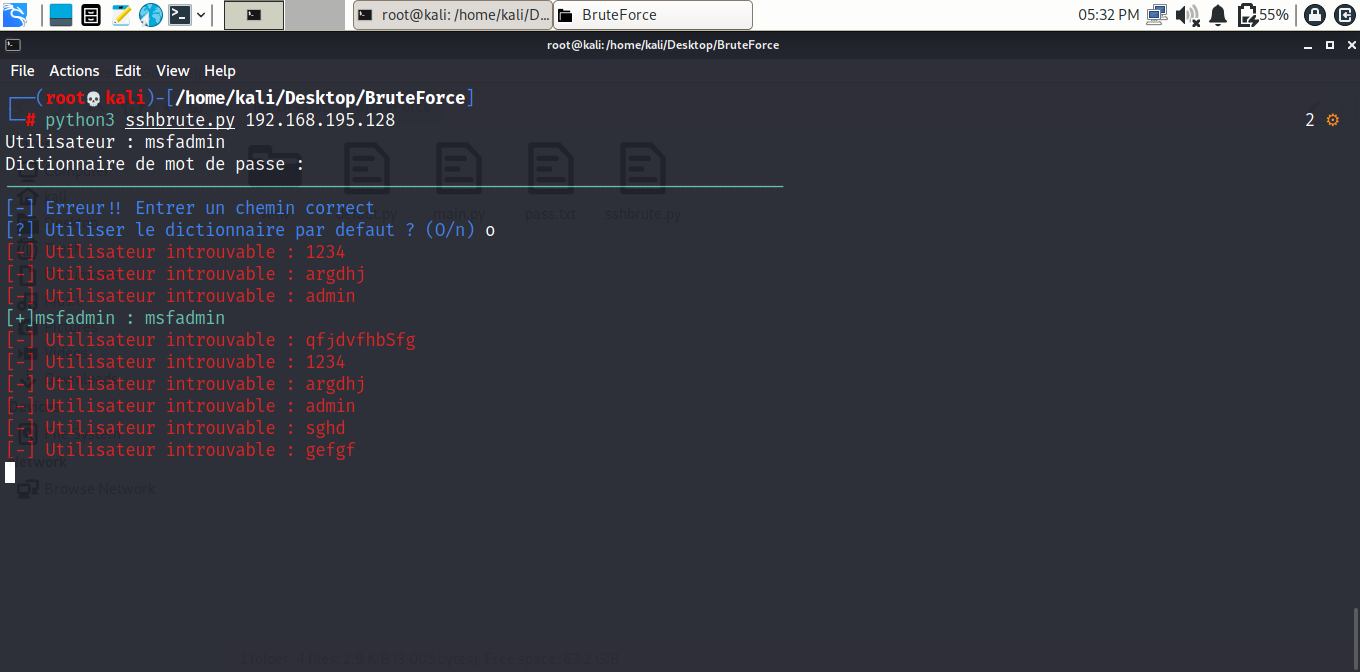
Researchers at the University of California, Santa Barbara took control of a botnet that was six times smaller than expected. In some countries, it is common for users to change their IP address a few times in one day. Estimating the size of the botnet by the number of IP addresses is often used by researchers, possibly leading to inaccurate assessments. Figure 2: GitHub - VlainLom/SSH-Brute-Force: Brute Force ssh port 22 A red team is a group that simulates an adversary, attempts a physical or digital intrusion against an organization at the direction of that organization, then reports back so that the organization can improve their defenses. Red teams work for the organization or are hired by the organization. Their work is legal, but it can surprise some employees who may not know that red teaming is occurring, or who may be deceived by the red team. Some definitions of red team are broader, and they include any group within an organization that is directed to think outside the box and look at alternative scenarios that are considered less plausible. This directive can be an important defense against false assumptions and groupthink. The term red teaming originated in the 1960s in the United States. Technical red teaming focuses on compromising networks and computers digitally. There may also be a blue team, a term for cybersecurity employees who are responsible for defending an organization's networks and computers against attack. In technical red teaming, attack vectors are used to gain access, and then reconnaissance is performed to discover more devices to potentially compromise. Credential hunting involves scouring a computer for credentials such as passwords and session cookies, and once these are found, can be used to compromise additional computers. During intrusions from third parties, a red team may team up with the blue team to assist in defending the organization. Rules of engagement and standard operating procedures are often utilized to ensure that the red team does not cause damage during their exercises. Physical red teaming focuses on sending a team to gain entry to restricted areas.
This is done to test and optimize physical security such as fences, cameras, alarms, locks, and employee behavior. As with technical red teaming, rules of engagement are used to ensure that red teams do not cause excessive damage during their exercises. Physical red teaming will often involve a reconnaissance phase where information is gathered and weaknesses in security are identified, and then that information will be used to conduct an operation (typically at night) to gain physical entry to the premises. Security devices will be identified and defeated using tools and techniques. Physical red teamers will be given specific objectives such as gaining access to a server room and taking a portable hard drive, or gaining access to an executive's office and taking confidential documents. Red teams are used in several fields, including cybersecurity, airport security, law enforcement, the military, and intelligence agencies. In the United States government, red teams are used by the Army, Marine Corps, Department of Defense, Federal Aviation Administration, and Transportation Security Administration.
In cybersecurity, a penetration test involves ethical hackers ("pen testers") attempting to break into a computer system, with no element of surprise. The organization is aware of the penetration test and is ready to mount a defense. A red team goes a step further, and adds physical penetration, social engineering, and an element of surprise. The blue team is given no advance warning of a red team, and will treat it as a real intrusion. One role of a permanent, in-house red team is to improve the security culture of the organization. A purple team is the temporary combination of both teams and can provide rapid information responses during a test. One advantage of purple teaming is that the red team can launch certain attacks repeatedly, and the blue team can use that to set up detection software, calibrate it, and steadily increase detection rate.
Purple teams may engage in "threat hunting" sessions, where both the red team and the blue team look for real intruders. Involving other employees in the purple team is also beneficial, for example software engineers who can help with logging and software alerts, and managers who can help identify the most financially damaging scenarios. One danger of purple teaming is complacence and the development of groupthink, which can be combatted by hiring people with different skillsets or hiring an external vendor. A white team is a group that oversees and manages operations between red teams and blue teams. For example, this may be a company's managers that determine the rules of engagement for the red team.
Once access to a network is achieved, reconnaissance can be conducted. The data gathered can be placed in a graph database, which is software that visually plots nodes, relationships, and properties. Typical nodes might be computers, users, or permission groups. Red teams will usually have very good graph databases of their own organization, because they can utilize home-field advantage, including working with the blue team to create a thorough map of the network, and a thorough list of users and administrators. A query language such as Cypher can be used to create and modify graph databases. Any type of administrator account is valuable to place in the graph database, including administrators of third-party tools such as Amazon Web Services (AWS). Data can sometimes be exported from tools and then inserted into the graph database. Once the red team has compromised a computer, website, or system, a powerful technique is credential hunting. These can be in the form of clear text passwords, ciphertext, hashes, or access tokens. The red team gets access to a computer, looks for credentials that can be used to access a different computer, then this is repeated, with the goal of accessing many computers.
Credentials can be stolen from many locations, including files, source code repositories such as Git, computer memory, and tracing and logging software. Techniques such as pass the cookie and pass the hash can be used to get access to websites and machines without entering a password. Techniques such as optical character recognition (OCR), exploiting default passwords, spoofing a credential prompt, and phishing can also be used. The red team can utilize computer programming and command-line interface (CLI) scripts to automate some of their tasks. For example, CLI scripts can utilize the Component Object Model (COM) on Microsoft Windows machines in order to automate tasks in Microsoft Office applications. Useful tasks might include sending emails, searching documents, encrypting, or retrieving data. Red teams can take control of a browser using Internet Explorer's COM, Google Chrome's remote debugging feature, or the testing framework Selenium.
An organization's red team may be an attractive target for real attackers. Red team member's machines may contain sensitive information about the organization. In response, red team member's machines are often secured. Techniques for securing machines include configuring the operating system's firewall, restricting Secure Shell (SSH) and Bluetooth access, improving logging and alerts, securely deleting files, and encrypting hard drives. One tactic is to engage in "active defense", which involves setting up decoys and honeypots to help track the location of intruders. These honeypots can help alert the blue team to a network intrusion that might otherwise have gone undetected. Various software can be used to set up a honeypot file depending on the operating system: macOS tools include OpenBMS, Linux tools include auditd plugins, and Windows tools include System Access Control Lists (SACL). Notifications can include popups, emails, and writing to a log file. Centralized monitoring, where important log files are quickly sent to logging software on a different machine, is a useful network defense technique.
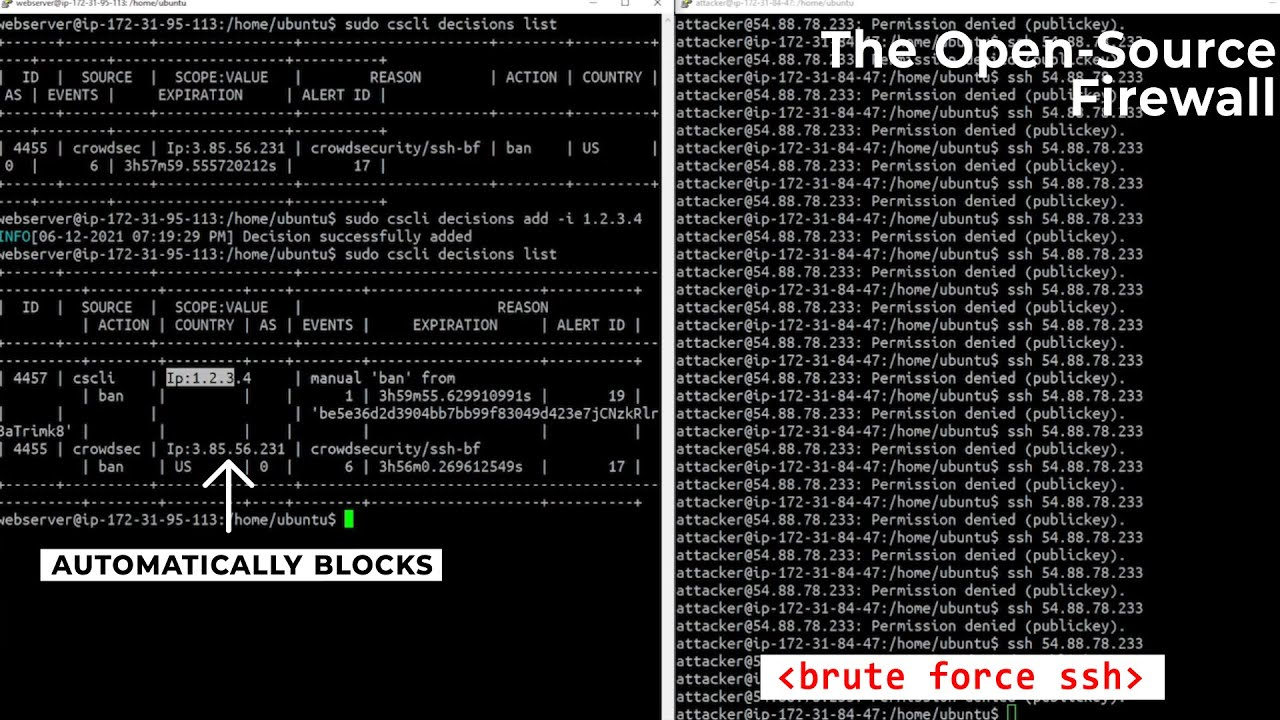
Figure 3: The Open-Source Firewall & IPS - A Quick Demo of CrowdSec (brute force ... Tracking certain metrics or key performance indicators (KPIs) can help to make sure a red team is achieving the desired output. Examples of red team KPIs include performing a certain number of penetration tests per year, or by growing the team by a certain number of pen testers within a certain time period. It can also be useful to track the number of compromised machines, compromisable machines, and other metrics related to infiltration. These statistics can be graphed by day and placed on a dashboard displayed in the security operations center (SOC) to provide motivation to the blue team to detect and close breaches. In order to identify worst offenders, compromises can be graphed and grouped by where in the software they were discovered, company office location, job title, or department. Monte Carlo simulations can be used to identify which intrusion scenarios are most likely, most damaging, or both. A Test Maturity Model, a type of Capability Maturity Model, can be used to assess how mature a red team is, and what the next step is to grow. The MITRE ATT&CK Navigator, a list of tactics, techniques, and procedures (TTPs) including advanced persistent threats (APTs), can be consulted to see how many TTPs a red team is exploiting, and give additional ideas for TTPs to utilize in the future.
Part of physical red teaming is performing reconnaissance. The type of reconnaissance gathered usually includes information about people, places, security devices, and weather. Reconnaissance has a military origin, and military reconnaissance techniques are applicable to physical red teaming. Red team reconnaissance equipment might include military clothing since it does not rip easily, red lights to preserve night vision and be less detectable, radios and earpieces, camera and tripod, binoculars, night vision equipment, and an all-weather notebook. Some methods of field communication include a Bluetooth earpiece dialed into a cell phone conference call during the day, and two-way radios with earpieces at night. In case of compromise, red team members often carry identification and an authorization letter with multiple after-hours contacts who can vouch for the legality and legitimacy of the red team's activities. Before physical reconnaissance occurs, open-source intelligence (OSINT) gathering can occur by researching locations and staff members via the Internet, including the company's website, social media accounts, search engines, mapping websites, and job postings (which give hints about the technology and software the company uses). It is a good practice to do multiple days of reconnaissance, to reconnoiter both during the day and at night, to bring at least three operators, to utilize a nearby staging area that is out of sight of the target, and to do reconnaissance and infiltration as two separate trips rather than combining them. Recon teams can use techniques to conceal themselves and equipment. For example, a passenger van can be rented and the windows can be blacked out to conceal photography and videography of the target. Examining and videoing the locks of a building during a walk-around can be concealed by the recon pretending to be on the phone. In the event of compromise, such as employees becoming suspicious, a story can be rehearsed ahead of time until it can be recited confidently. If the team has split up, the compromise of one operator can result in the team leader pulling the other operators out. Concealed video cameras can be used to capture footage for later review, and debriefs can be done quickly after leaving the area so that fresh information is quickly documented.
Common security devices include doors, locks, fences, alarms, motion sensors, and ground sensors. Doors and locks are often faster and quieter to bypass with tools and shims, rather than lock picking. RFID locks are common at businesses, and covert RFID readers combined with social engineering during reconnaissance can be used to duplicate an authorized employee's badge. Barbed wire on fences can be bypassed by placing a thick blanket over it. Anti-climb fences can be bypassed with ladders. Alarms can sometimes be neutralized with a radio jammer that targets the frequencies that alarms use for their internal and external communications. Motion sensors can be defeated with a special body-sized shield that blocks a person's heat signature. Ground sensors are prone to false positives, which can lead security personnel to not trust them or ignore them.
Red teams usually have goal locations selected and tasks pre-planned for each team or team member, such as entering a server room or an executive's office. However, it can be difficult to figure out a room's location in advance, so this is often figured out on the fly. Reading emergency exit route signs and the use of a watch with a compass can assist with navigating inside of buildings. Commercial buildings will often have some lights left on. It is good practice to not turn lights on or off, as this may alert someone. Instead, utilizing already unlit areas is preferred for red team operations, with rushing and freezing techniques to be used to quickly move through illuminated areas. Standing full-height in front of windows and entering buildings via lobbies is often avoided due to the risks of being seen. A borescope can be used to peer around corners and under doors, to help spot people, cameras, or motion detectors. Once the target room has been reached, if something needs to be found such as a specific document or specific equipment, the room can be divided into sections, with each red team member focusing on a section. Passwords are often located under keyboards. Techniques can be used to avoid disturbing the placement of objects in offices such as keyboards and chairs, as adjusting these will often be noticed. Lights and locks can be left in their original state of on or off, locked or unlocked. Steps can be taken to ensure that equipment is not left behind, such as having a list of all equipment brought in and checking that all items are accounted for. It is good practice to radio situation reports (SITREPs) to the team leader when unusual things happen. The team leader can then decide if the operation should continue, should be aborted, or if a team member should surrender by showing their authorization letter and ID. When confronted by civilians such as employees, red team operators can attempt social engineering. When confronted by law enforcement, it is good practice to immediately surrender due to the potential legal and safety consequences.
When applied to intelligence work, red teaming is sometimes called alternative analysis. Alternative analysis involves bringing in fresh analysts to double-check the conclusions of another team, to challenge assumptions and make sure nothing was overlooked. Three red teams were used to review the intelligence that led to the killing of Osama bin Laden in 2011, including red teams from outside the Central Intelligence Agency, because there were major diplomatic and public relations consequences for launching a military operation into Pakistan, so it was important to double-check the original team's intelligence and conclusions. After failures to anticipate the Yom Kippur War, the Israeli Defense Forces' Intelligence Directorate formed a red team called Ipcha Mistabra ("on the contrary") to re-examine discarded assumptions and avoid complacency. The North Atlantic Treaty Organization (NATO) utilizes alternative analysis.
The DoD uses cyber red teams to conduct adversarial assessments on their networks. These red teams are certified by the National Security Agency and accredited by the United States Strategic Command. The United States Federal Aviation Administration (FAA) has been implementing red teams since Pan Am Flight 103 over Lockerbie, Scotland, which suffered a terrorist attack in 1988. Red teams conduct tests at about 100 US airports annually.
Tests were on hiatus after the September 11 attacks in 2001, and resumed in 2003 under the Transportation Security Administration, who assumed the FAA's aviation security role after 9/11. Before the September 11 attacks, FAA use of red teaming revealed severe weaknesses in security at Logan International Airport in Boston, where two of the four hijacked 9/11 flights originated. Some former FAA investigators who participated on these teams feel that the FAA deliberately ignored the results of the tests, and that this resulted in part in the 9/11 terrorist attack on the US. The United States Transportation Security Administration has used red teaming in the past. In one red team operation, undercover agents were able to fool Transportation Security Officers and bring weapons and fake explosives through security 67 out of 70 times in 2015.
This project simulates an SSH brute-force attack on a Linux system and demonstrates how authentication logs can be analyzed to detect suspicious login activity. The goal was to simulate attacker behavior, generate failed login attempts, and investigate authentication logs like a SOC (Security Operations Center) analyst.
During this investigation, multiple failed SSH login attempts were observed targeting the attackeruser account. This technique involves automated attempts to guess passwords until valid credentials are found. Understanding MITRE ATT&CK mapping helps analysts identify attacker behavior patterns and implement appropriate defensive controls.
Repeated failed SSH login attempts indicate a brute-force attack attempt. If successful, attackers could gain unauthorized access to the system, leading to data compromise, privilege escalation, or system misuse. After identifying repeated failed SSH login attempts, the following response actions were taken: 2. System Architecture & Core Working Principles These actions helped contain the attack and prevent further unauthorized access attempts.
After detecting repeated failed SSH login attempts, Fail2Ban was installed to automatically block attackers after multiple failed login attempts. This configuration blocks an IP address after 3 failed login attempts within 5 minutes , banning the attacker for 10 minutes . Multiple failed SSH login attempts were generated again to trigger Fail2Ban protection.
SOC investigation lab simulating SSH brute-force attack detection, IP analysis, and firewall blocking using Linux logs. A hands-on cybersecurity project simulating a real-world SSH brute-force attack and detecting it using Splunk SIEM. This lab demonstrates the complete attack-and-detect lifecycle of an SSH brute-force attack in a controlled virtual environment. The project covers penetration testing, log analysis, and SIEM-based detection — skills used daily by SOC analysts.
SSH Brute-Force Detection Lab — Simulated real-world brute-force attacks using Hydra (rockyou.txt, 4 threads) against an Ubuntu SSH server, captured 276+ failed login events in auth.log, ingested logs into Splunk SIEM, and built SPL detection queries, automated alerts, and a monitoring dashboard identifying attacker IP across multiple target accounts. One of the most common and persistent threats to any server exposed to the internet is the brute force SSH attack. These are automated attempts to guess login credentials by repeatedly trying combinations of usernames and passwords. Left unchecked, they can waste system resources, fill up log files, and occasionally even succeed if weak credentials are in use.
Fortunately, detecting brute force attacks is well within reach using Python. By monitoring your system’s authentication logs and tracking failed login attempts, you can identify patterns, block offending IP addresses, and alert administrators before any real damage is done. In this article, we will walk through the process of building a lightweight Python-based SSH brute force monitor. It is a practical and educational project that will strengthen both your Python skills and your understanding of real-world threats.
Let’s begin with where brute force attempts leave their trace — the logs. On most Linux systems, SSH login activity is recorded in /var/log/auth.log or /var/log/secure depending on the distribution. Every failed attempt generates an entry including the username, IP address, and timestamp. By scanning this file, we can extract and analyze the data to detect abuse. The basic idea is simple: if the same IP address fails to log in too many times within a short time frame, it is probably not a legitimate user. Your script can then log this activity, notify an admin, or even ban the IP address automatically.
You do not need complex tools to make this happen. With Python, you can open the log file, read it line by line, and use regular expressions to pull out the relevant parts. The script can keep track of failed attempts by IP in a dictionary and compare the number of attempts against a defined threshold. This approach is simple, but very effective. You can run the script periodically using cron or keep it running continuously in the background, depending on your needs. You might also build in logging so you can review which IPs were blocked or flagged over time.
One thing to be careful of is avoiding re-parsing the same entries. If your script reads from the top of the log file every time it runs, you will get duplicate results. A good solution is to track the last read position using a small marker file, or even just process only new entries since the last run. Python’s flexibility means you can tailor this tool to fit any environment. In smaller settings, it might be your first line of defense. In larger networks, it can supplement existing intrusion detection systems.
The more context you can build around each event, the smarter your response will be. The goal is not just to stop attacks, but to understand them — their frequency, tactics, and origin. Once you have your SSH monitor running, you will likely be surprised by how often brute force attempts happen. Even low-profile servers receive regular attention from automated bots. Being able to see this in action reinforces the importance of basic hardening measures like using strong credentials, disabling root login, and enabling key-based authentication.
If you are looking to practice your Python skills on a real problem that defenders face every day, building an SSH brute force monitor is an ideal project. It teaches you to parse logs, track state, automate responses, and think like both an attacker and a defender. Best of all, it is something you can build quickly and improve over time. To go further, check out my 17-page PDF guide, Mastering Cybersecurity with Python: The Complete Pro Guide to Network Defense . It includes deeper dives into detection logic, script examples, and more hands-on projects for defensive Python development. You can download it now for just five dollars.
And if you have enjoyed this article or the series so far, I invite you to buy me a coffee . Your support helps me keep producing practical, focused cybersecurity content for learners and professionals alike. An end-to-end Tier 1 SOC simulation — detect an SSH brute-force attempt with Splunk SPL, map it to MITRE ATT&CK T1110, and run an AI-driven triage script that produces a structured analyst report with severity, false-positive scoring, and an escalation decision.
This lab recreates a Security Operations Center analyst's full workflow against an SSH brute-force attempt: from log ingestion and SPL detection, through MITRE ATT&CK behavior mapping, AI-assisted triage, response planning, and secure-development remediation after a real API-key exposure incident. The point isn't just to detect "failed password" events. It's to demonstrate the adversary-behavior reasoning that defines senior SOC work — every alert produced by this pipeline is tagged with its tactic, technique, sub-technique, and the kill-chain follow-on the analyst should watch for next.
Each stage is mapped to a concrete tool and a MITRE alignment so the chain of custody from raw event to escalation decision is fully explicit. 3. Software Implementation, Frameworks & Protocols Generate realistic SSH brute-force activity in a Kali Linux environment; collect raw authentication events into sample_logs/ .
SPL query extracts source IPs from Failed password events, counts attempts, and fires when the rate exceeds the brute-force threshold. claude_triage_demo.py classifies threat type, severity, false-positive probability, and produces a structured Tier 1 analyst report.
AbuseIPDB / VirusTotal / Shodan lookups on the source IP; cross-host correlation, targeted-account analysis, lateral-movement search. Block the source IP, document the alert, and escalate to Tier 2 if any of the five hard escalation criteria are met. Real incident handled mid-project: API key flagged by a pre-push hook, repo history reset, credentials rotated, clean state force-pushed.
Rather than just stating "SSH brute-force detected," this project maps every observation to a tactic, technique, and sub-technique from the MITRE ATT&CK framework. The output of the detection rule is framework-aware and audit-ready. Most analysts stop at detection. Elite SOC thinking asks: if this attack succeeds, what does the adversary do next? Each successor technique below has an explicit indicator to watch for.
Splunk runs inside the Kali Linux lab as the primary detection engine. The advanced query labels every alert with its MITRE technique, sub-technique, and tactic — and assigns dynamic severity based on attempt volume — so the analyst is briefed on adversary behavior the moment the alert fires. Baseline brute-force trigger — counts failed SSH passwords per source IP and fires above the threshold.
Upgraded SPL: extracts the source IP, scores severity dynamically, and tags every alert with its MITRE tactic, technique, and sub-technique. Every alert produced by this query is automatically tagged with its adversary-behavior context. When it fires in production, the analyst immediately knows the tactic, the technique, the sub-technique, and the recommended response — no manual lookup, no framework guesswork.
A custom Python script analyzes authentication activity and emits a structured Tier 1 investigation report. The format mirrors how analysts document alerts in a real SOC: threat classification, severity assessment, key evidence, false-positive probability, recommended response, and escalation criteria. SSH access provides direct shell — the highest-value credential an attacker can obtain.
During development, a Git pre-push hook detected an API-key pattern in commit history and blocked the push. The full remediation process below is exactly how credential exposure gets handled in production: contain, scrub, rotate, document. Exact commands used to scrub the repo, restart from a clean state, and force-push without nuking peer work. Version-control hygiene is treated as a security control, not just a developer convenience.
This activity is consistent with MITRE ATT&CK technique T1110 (Brute Force) , sub-technique T1110.001 (Password Guessing) , commonly observed during early-stage Credential Access attempts in intrusion scenarios. MITRE ATT&CK mapping was used to standardize detection logic and align findings with industry-recognized adversary behaviors. This project was conducted in a controlled lab environment for educational and defensive security purposes only. All indicators and IP addresses were sanitized.
Monitors SSH auth logs for brute force patterns and blocks offending IPs via firewall rules Before deploying the detector, ensure your target server has a stable SSH configuration. Verify that sshd is running and that logs are being written to /var/log/auth.log (Debian/Ubuntu) or /var/log/secure (RHEL/CentOS). Install necessary dependencies such as Python 3.9+ and psutil for resource monitoring. If you are using a cloud provider, ensure that security groups allow SSH traffic only from trusted IPs initially to establish a baseline. The AI model requires historical log data to train its behavioral baseline, so ensure your logging retention is at least 7 days. Disable password authentication if possible, or restrict it to specific users, as this reduces noise for the detector. Check your current fail2ban status if installed, as this tool complements rather than replaces it, focusing on pattern recognition rather than simple IP banning.
Ensure your system time is synchronized via NTP. Log timestamps are critical for the AI's temporal analysis of attack patterns. Clone the repository from the provided GitHub link. Navigate to the project directory and create a virtual environment to isolate dependencies. Use python -m venv venv and activate it. Install the requirements using pip install -r requirements.txt . The project structure typically includes a config.yaml file and a main.py entry point. Initialize the database or log storage if the tool uses a local SQLite or PostgreSQL backend for storing behavioral metrics. Run the initialization script, often python init.py , to set up the baseline environment. This step prepares the AI model to ingest log streams. Verify that the script can read the SSH log file by running a simple test command like python test_log_access.py . If permissions are denied, adjust the file ownership or run the script with appropriate privileges, but avoid running the main detector as root for security reasons.
Create a dedicated service user (e.g., 'ssh_detector') to run the application. This minimizes the impact if the tool is compromised. Open the config.yaml file. Define the log path, ensuring it matches your system's actual log location. Set the threshold for failed attempts; the AI uses this as a starting point but adjusts dynamically. Configure the window_size (e.g., 300 seconds) which determines how long the AI looks at recent history to detect anomalies. Enable the machine_learning flag to activate the behavioral analysis engine. Define the action_on_detect setting: options usually include 'log_only', 'ban_ip', or 'alert'. For initial deployment, set this to 'log_only' to observe the AI's decisions without disrupting legitimate traffic. Specify the 'ban_duration' if you plan to enable automatic banning. Also, configure the API endpoint if you intend to integrate alerts with Slack, PagerDuty, or a SIEM system. Save the file and validate the syntax using the tool's built-in config validator if available.
Start with a conservative threshold. You can always lower it later. A high threshold prevents the AI from learning from rare, legitimate typos. 4. Practical Deployment, Analysis & Case Studies Start the detector in foreground mode for debugging: python main.py --debug . Watch the console output for real-time log ingestion. The AI will begin building a profile of normal login behavior. To test the detection, simulate a brute force attack using hydra or ncrack against a non-critical test user from a different IP address. Observe how the detector flags the attempt. Look for JSON output in the logs showing the 'confidence_score' of the attack. The AI should distinguish between a single typo (low confidence) and a rapid sequence of failures (high confidence). Check the local database or log file to see if the IP was flagged. If the tool is integrated with an alerting system, verify that the notification was sent. Monitor CPU and memory usage to ensure the real-time analysis does not degrade server performance. Adjust the sampling_rate if resource usage is too high.
Use `tail -f /var/log/ssh_detector.log` to monitor the tool's own activity. Look for 'Model Updated' messages indicating the AI is adapting to new patterns. Once confident in the detection accuracy, switch action_on_detect to 'ban_ip' or 'alert'. Integrate with your existing security stack. For example, add a webhook to the config to send alerts to Slack. Test the alert flow by triggering a simulated attack. If using fail2ban, ensure there is no conflict; the AI detector can act as a pre-filter, banning IPs before fail2ban sees them, or vice versa. Consider adding the detector to your CI/CD pipeline for server hardening checks. Set up a cron job or systemd service to restart the detector if it crashes. Finally, document your baseline metrics. The AI's effectiveness depends on continuous learning, so review the false positive rate weekly. Tune the sensitivity parameter based on your traffic patterns.
This creates a robust, adaptive security layer that evolves with your network's behavior. Regularly export the AI's model weights or learned patterns to backup. This allows you to quickly restore detection capabilities on new servers. Get the hottest AI tools, exclusive tutorials, and insider tips delivered to your inbox every Friday. Free forever.
You SSH into sw-infrarunbook-01 for a routine check and something feels off. The login banner takes a beat longer than usual to appear. You run a quick tail -f /var/log/auth.log and the output is scrolling faster than you can read it. Or maybe you got paged at 2 AM because a disk-usage alert fired — and the culprit turns out to be a 4 GB auth log that didn't exist yesterday. This is a brute force attack. Automated scanners sweep the entire routable IPv4 space continuously, probing every host they find on port 22. If your server is reachable, it's being probed — the only question is whether your defenses are configured to absorb or stop it. Let's work through every reason this happens and exactly how to fix it.
The auth log is the ground truth for authentication events on a Linux system. Failed SSH attempts, PAM errors, sudo invocations — all of it ends up there. The problem isn't that the log exists; it's that most teams provision a server, open port 22, and never wire up any alerting against auth.log. The log fills silently, an attack runs for days or weeks, and nobody notices until disk fills or a compliance audit surfaces it.
Attackers know this. Sustained low-and-slow campaigns are specifically designed to stay under the radar — a few hundred attempts per hour from rotating IPs. Each individual source IP stays quiet enough to avoid triggering naive rate-limit rules, but collectively they grind through millions of password combinations around the clock. On a healthy server this should be in the single digits to low hundreds. If you see output like this, you have a problem: Then check which usernames are being targeted — this tells you whether it's a credential-stuffing campaign or just blind dictionary blasting: Beyond observing the log reactively, you need active monitoring. Forward auth.log to a SIEM, configure logwatch, or use a simple alerting rule that fires when "Failed password" exceeds a threshold in a rolling window. Tools like Loki + Grafana, Graylog, or even a cron job that mails you a daily summary work fine. The key is visibility before the problem becomes a crisis.
For immediate investigation when auth.log has already rotated, check compressed archives: This one comes up constantly. Someone spins up a VPS, installs OpenSSH, opens port 22, and ships it. fail2ban isn't part of the default installation on any major distribution — you have to install it deliberately. In my experience, this is the single biggest gap between servers that handle brute force gracefully and servers that get hammered into the ground. Without fail2ban, every failed authentication attempt is free. There's no penalty for being wrong a thousand times in a row.
fail2ban works by tailing log files for patterns and using iptables or nftables to temporarily ban offending IPs once a threshold is crossed. It's not a silver bullet — rotating botnets can exhaust its ban list — but it dramatically raises the cost of an attack and handles the long tail of automated scanners that dominate internet noise. Don't modify /etc/fail2ban/jail.conf directly — that file gets overwritten on package upgrades. Create a local override instead: This bans any IP that fails 5 times within 10 minutes for a full 24 hours. I push bantime to 86400 on any host with no legitimate reason to see auth failures from unknown sources. After applying the config, verify the jail is active: The default value of MaxAuthTries in OpenSSH is 6. That means an attacker gets 6 password attempts per TCP connection before the server closes it. This sounds restrictive, but nothing stops the attacker from immediately opening a new TCP connection and trying 6 more. With enough threads, they can run thousands of attempts per minute against a single host even with the default in place.
Worse, I've seen environments where an admin bumped MaxAuthTries to 20 or higher because they were seeing "Too many authentication failures" errors during debugging — a client-side issue caused by an SSH agent offering too many keys — and never walked it back after resolving the real problem. That setting then sits in production, handing attackers a wide-open window.
No output means the default of 6 is in effect. If you see something like this, it needs fixing immediately: Always check the effective running configuration rather than just the config file, because Include directives can pull in other files: Set MaxAuthTries to 3 in /etc/ssh/sshd_config. Combined with fail2ban, this means an attacker gets 3 guesses per connection, and fail2ban cuts the IP off once it's tripped that threshold enough times: While you're in sshd_config, also tighten LoginGraceTime. The default is 120 seconds — two full minutes that a half-open unauthenticated connection can hold a slot in the daemon. Dropping it to 30 seconds reduces resource consumption during flood attacks: Modern OpenSSH defaults PermitRootLogin to "prohibit-password", which only allows root login via public key authentication.
But I've seen countless production servers — especially older systems, systems migrated from aging cloud images, or boxes that started life as quick dev environments and quietly became important — where PermitRootLogin is set to "yes". That means root can log in with a password, and since every Linux system has a root account, attackers don't even need to guess a valid username. They already know one.
The volume this generates is staggering. Even "prohibit-password" carries risk if key management is loose, which is why the safest posture is to disable root login entirely and require admins to SSH as a named user and escalate with sudo. Before making this change, verify you have a non-root user with sudo access and a working SSH key. If you lock yourself out here, recovery requires console access — not fun at 3 AM. On sw-infrarunbook-01, confirm the admin account first: 5. Performance Evaluation & Extended Technical Observations From a separate terminal session , confirm you can still log in as infrarunbook-admin with your key before closing the root session. This step is not optional — I have seen engineers lock themselves out of cloud VMs by skipping it.
This is the architectural root of most SSH brute force problems. Password authentication over SSH means that as long as an attacker can reach your SSH port, they can attempt logins indefinitely — rate limits and fail2ban only slow them down. Key-based authentication eliminates the attack surface entirely. Without the private key, no amount of password guessing succeeds, period.
Password auth ships enabled by default in OpenSSH because it's easier for new users to get started. But "easier" cuts both ways — it's easier for attackers too. Every server with a public IP should have PasswordAuthentication set to no. There's no legitimate argument for leaving it enabled on a production host. That single line means a brute force attack against your server has a chance of succeeding. Also check ChallengeResponseAuthentication, which can act as an alternate path to password-based auth on some PAM configurations: Confirm your key-based login is working from a separate terminal before making this change. This is non-negotiable. Open /etc/ssh/sshd_config and set: UsePAM yes stays enabled because PAM handles account restrictions, session setup, and access controls — it doesn't re-enable password auth when PasswordAuthentication is explicitly set to no.
That's exactly right. Password auth is gone. The brute force attack is still generating log noise, but it can't succeed — and fail2ban will silence even the noise once IPs cross the retry threshold. Even with password auth disabled, an unconstrained sshd_config allows any account on the system to attempt key-based login. If a compromised CI/CD pipeline accidentally writes an authorized key to a service account's home directory, or if an attacker gains a foothold through another vulnerability and plants a key, there's nothing at the sshd layer blocking that account from gaining SSH access.
AllowUsers and AllowGroups enforce an explicit allowlist. Only accounts you name can SSH in — everything else is rejected before any other check runs. It's a cheap control with a high-value payoff. No output means there's no allowlist in effect. Any account on the system can attempt SSH authentication. Attackers probing common usernames like ubuntu, pi, or deploy will hit this wall immediately, even if somehow those accounts exist on the system.
fail2ban reacts after the fact. It reads the log, detects a pattern, then issues a ban. During the window between the first failed attempt and the ban being applied, the attack continues unimpeded. Against a large botnet with thousands of IPs, fail2ban may be banning addresses faster than it can process them while the log still grows. Firewall-level rate limiting is a proactive layer that throttles new TCP connections before they even reach sshd — before any log entry is written, before any auth attempt is processed.
No rate-limiting rules means new connection attempts hit sshd unbounded. Every bot on the internet gets full, unthrottled access to your auth stack. This drops any source IP that makes more than 10 new SSH connections in 60 seconds. Legitimate users won't notice — they don't open 10 fresh connections per minute. Brute force bots stall immediately.
Persist these rules through reboots using iptables-save, or manage them through your distro's preferred mechanism — ufw on Ubuntu, firewalld on RHEL-family systems. Don't set this and forget it; verify after any firewall management tool update that the rules survived. Port 22 is scanned continuously. Within minutes of a new public IP address appearing on the internet, automated scanners have already probed it for SSH. Moving SSH to a non-standard port won't stop a determined attacker — a full port scan will find it — but it eliminates the enormous volume of automated noise that targets port 22 specifically. In my experience, moving SSH off port 22 drops auth.log failure counts by 90% or more overnight. It's security through obscurity, it shouldn't be your only layer, but as one component of a defense-in-depth posture it's a free noise reduction you'd be foolish to skip.
Reload sshd, then update your SSH client config (~/.ssh/config), any automation that connects to this host, jump host definitions, and Ansible inventory. If sw-infrarunbook-01 functions as a bastion, update downstream jump configurations on every client that routes through it. A port change touches more config than it looks like — take a few minutes to audit everything before the change lands.
Defense in depth is the only real answer. No single control is sufficient. A well-hardened SSH configuration on sw-infrarunbook-01 looks like this in aggregate — this is the baseline I'd apply to any host facing the internet: Always validate sshd_config syntax before reloading — a syntax error here will prevent sshd from starting on next restart, which can lock you out permanently on a headless system: Beyond sshd_config, a complete prevention posture covers several additional areas. Key rotation : rotate SSH keys whenever a team member leaves. Audit all authorized_keys files across your fleet quarterly — keys accumulate faster than anyone tracks them, and forgotten keys are a persistent access risk.
Centralized log shipping : get auth.log into a SIEM or centralized logging system. Correlating failed logins across multiple hosts lets you spot distributed campaigns that stay below per-host thresholds. A botnet spreading 50 attempts per host across 500 hosts won't trip fail2ban anywhere, but it lights up immediately in a cross-host view. Two-factor authentication : for bastion hosts and any server with elevated access, consider adding TOTP via libpam-google-authenticator or a similar module. Even a compromised private key can't authenticate without the second factor. This is particularly valuable for the hosts an attacker would most want to reach.
SSH Certificate Authority : in environments managing more than a handful of hosts, replace static authorized_keys with an internal SSH CA. Issue short-lived certificates with defined principals and expiry windows. Revocation becomes a centralized operation rather than a file-editing exercise across every host in your fleet. OpenSSH has built-in CA support and it's more straightforward to deploy than people expect.
Source IP allowlisting : if your SSH hosts don't need to be reachable from arbitrary internet IPs, restrict port 22 (or your custom port) to known source ranges at the firewall or cloud security group level. A management network, VPN egress range, or office IP block combined with an explicit deny-all is far stronger than any application-layer defense. Application-layer tools like fail2ban exist to handle the cases where network-level allowlisting isn't feasible — but network-level allowlisting should always be your first option when it is.
The goal is to make your SSH surface so hostile to automated attacks that scanners move on to easier targets — and to make any meaningful breach attempt detectable before it becomes a crisis. With key-only auth enforced, fail2ban actively banning, root login disabled, MaxAuthTries at 3, and centralized log monitoring in place, you've addressed the vast majority of real-world brute force scenarios. Stack network-level controls on top of that and you're in genuinely good shape.
Run `grep 'Failed password' /var/log/auth.log | wc -l` to get the raw failure count. Anything in the tens of thousands indicates active brute forcing. Follow up with `grep 'Failed password' /var/log/auth.log | awk '{print $(NF-3)}' | sort | uniq -c | sort -rn | head -20` to identify the top attacking IPs and assess the scope. Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Fail2ban • https://en.wikipedia.org/wiki/Botnet • https://en.wikipedia.org/wiki/Red%20team • https://github.com/alexojocyber/SSH-BruteForce-Detection-Lab • https://github.com/gawaderahul21/ssh-bruteforce-detection-lab • https://dev.to/hexshift/detecting-ssh-brute-force-attacks-with-python-building-a-simple-monitor-3mon • https://mandozone.github.io/ai-soc-triage-lab/ • https://aiindigo.com/tutorials/getting-started-with-ssh-brute-force-detector-stop-attacks-in-real-time • https://infrarunbook.com/article/ssh-brute-force-attack-detection-mitigation
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Ssh Brute Force Attack Detection And Blocking Script.
[*] Metasploit Scan Running on Target Subnet for Ssh Brute Force Attack Detection And Blocking Script... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |