Complete Technical Paper Content — Threat Intelligence Correlation Tool Using Opencti API
Overview & System Context
Threat Intelligence Correlation Tool Using Opencti Api: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~8362 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Welcome to the OpenCTI Documentation space. Here you will be able to find all documents, meeting notes and presentations about the platform.
Please, be sure to also take a look at the OpenCTI releases notes , they may contain important information about releases and deployments. OpenCTI is an open source platform allowing organizations to manage their cyber threat intelligence knowledge and observables. It has been created in order to structure, store, organize and visualize technical and non-technical information about cyber threats.
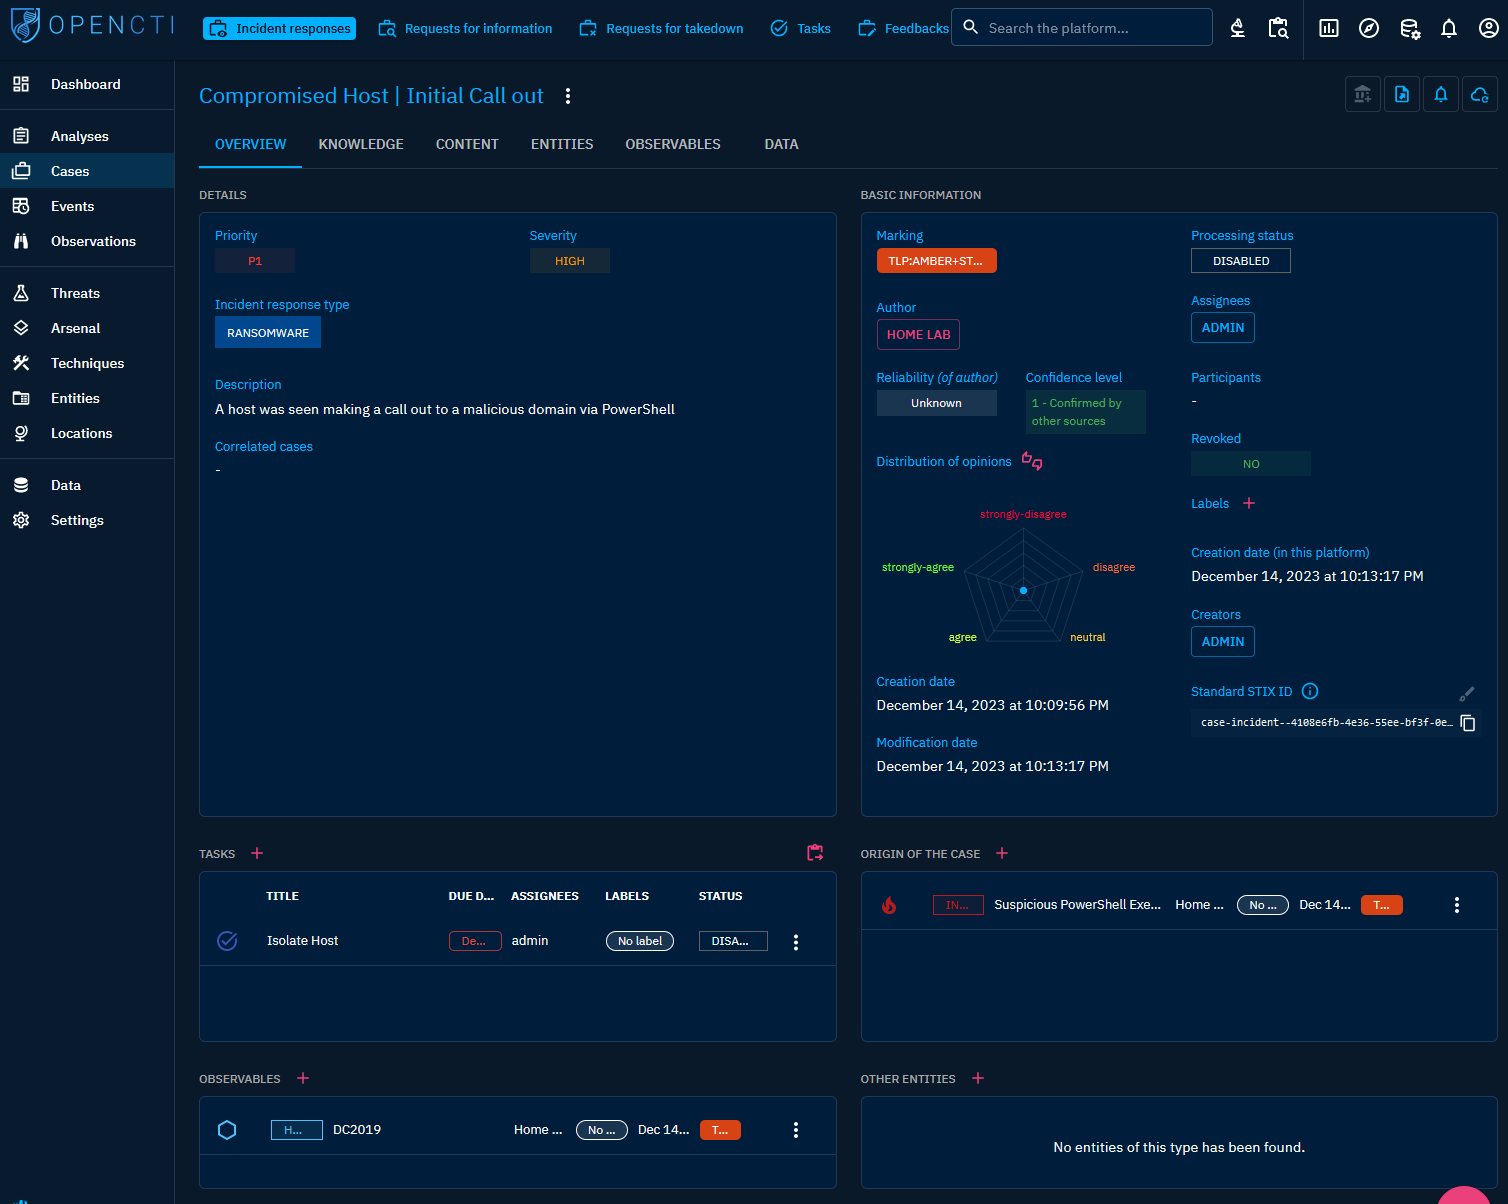
If you're looking for information about the deployment of the full eXtended Threat Management (XTM) suite using Docker, please refer to this repository and documentation . Figure 1: Centralize Threat Intellgience and Incident Management with OpenCTI ... Learn how to deploy and configure the platform as well as launch connectors to get the first data in OpenCTI.
Understand how to use the platform, explore the knowledge, import and export information, create dashboard, etc. Know how to administrate OpenCTI, create users and groups using RBAC / segregation, put retention policies and custom taxonomies. If you still have questions or you find something which is not sufficiently explained, join the Filigran Community on Slack .
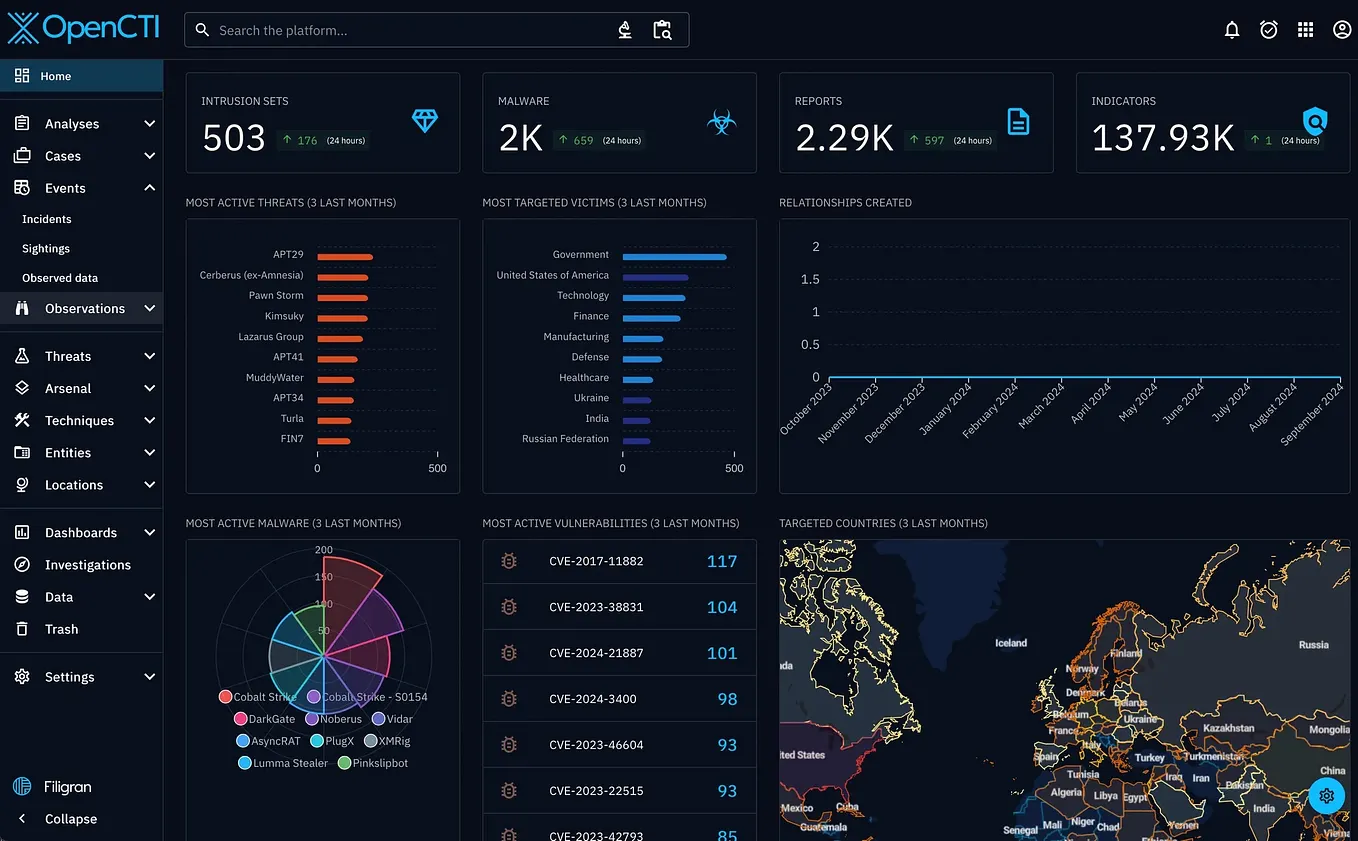
Figure 2: OpenCTI: Open-source cyber threat intelligence platform - Help Net Security Discover tutorials, best practices and deep dives on OpenCTI features on our Filigran blog. Below, you will find external resources which may be useful along your OpenCTI journey. XTM Hub Integrations Library List of available connectors and integrations to expand platform usage.
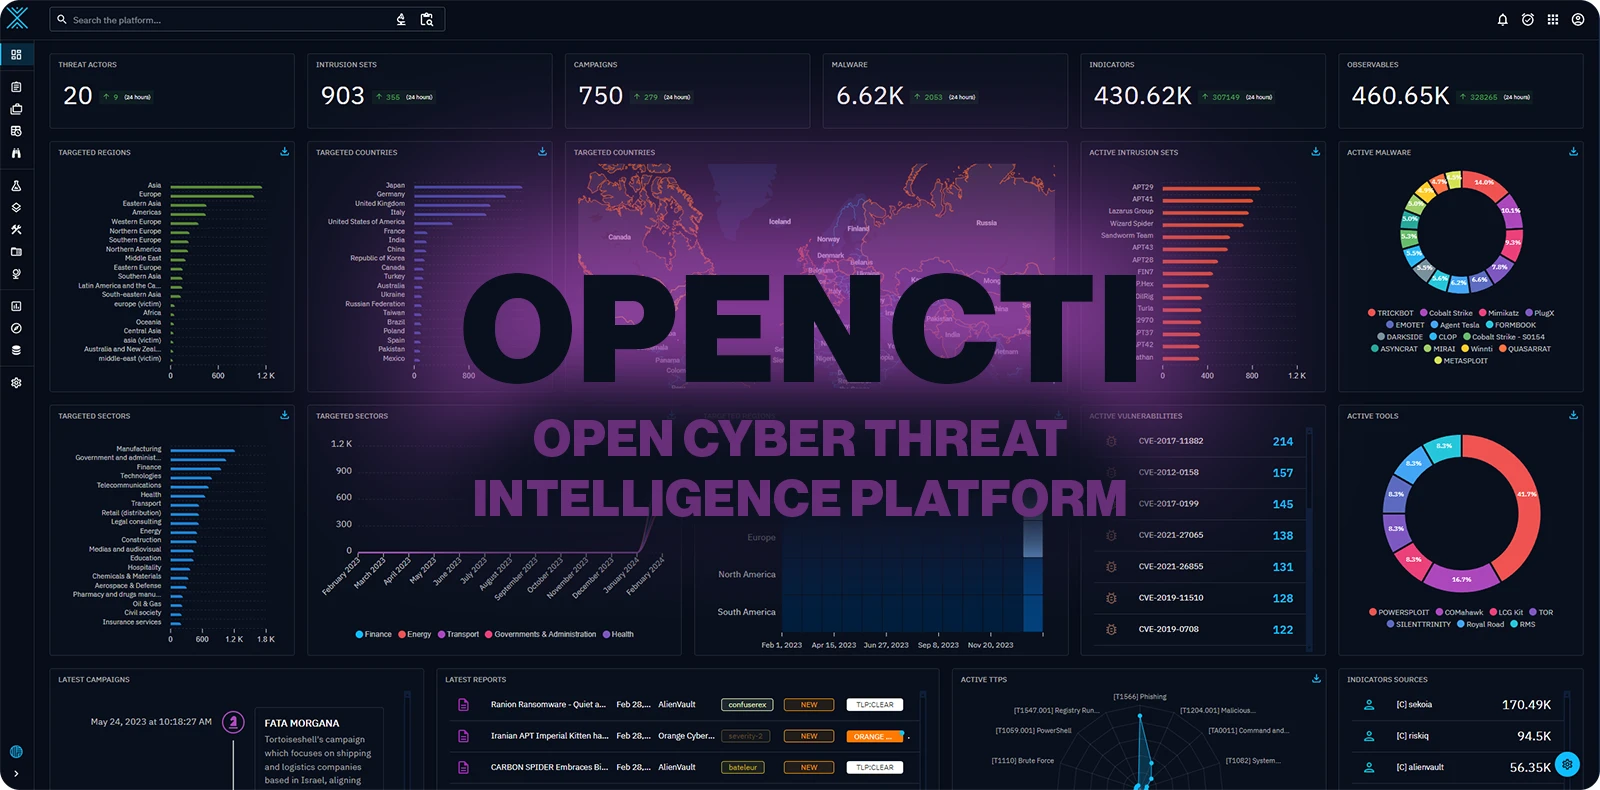
Training Courses Training courses for analysts and administrators in the Filigran Academy. Figure 3: OpenCTI Setup: Integrating MITRE, AbuseIPDB, AlienVault & RSS Feeds for ... Video materials Set of video illustrating the implementation of use cases and platform capabilities. Note: THREAD 2026 — 15 October, Paris. Our community conference for threat intelligence and cyber defense practitioners.
Talks, labs, workshops, and an evening social. Join us → OpenCTI is an open source platform allowing organizations to manage their cyber threat intelligence knowledge and observables. It has been created in order to structure, store, organize and visualize technical and non-technical information about cyber threats.
The structuration of the data is performed using a knowledge schema based on the STIX2 standards . It has been designed as a modern web application including a GraphQL API and a UX-oriented frontend. Also, OpenCTI can be integrated with other tools and applications such as MISP , TheHive , MITRE ATT&CK , etc. The goal is to create a comprehensive tool allowing users to capitalize technical (such as TTPs and observables) and non-technical information (such as suggested attribution, victimology etc.) while linking each piece of information to its primary source (a report, a MISP event, etc.), with features such as links between each information, first and last seen dates, levels of confidence, etc. The tool is able to use the MITRE ATT&CK framework (through a dedicated connector ) to help structure the data. The user can also choose to implement their own datasets.
Once data has been capitalized and processed by the analysts within OpenCTI, new relations may be inferred from existing ones to facilitate the understanding and the representation of this information. This allows the user to extract and leverage meaningful knowledge from the raw data. OpenCTI not only allows imports but also exports of data under different formats (CSV, STIX2 bundles, etc.). Connectors are currently developed to accelerate interactions between the tool and other platforms.
OpenCTI platform has 2 different editions: Community (CE) and Enterprise (EE). The purpose of the Enterprise Edition is to provide additional and powerful features which require specific investments in research and development. You can enable the Enterprise Edition directly in the settings of the platform. To understand what OpenCTI Enterprise Edition brings in terms of features, just check the Enterprise Editions page on the Filigran website. You can also try this edition by enabling it in the settings of the platform.
If you want to know more on OpenCTI, you can read the documentation on the tool . If you wish to discover how the OpenCTI platform is working, a demonstration instance is available and open to everyone. This instance is reset every night and is based on reference data maintained by the OpenCTI developers. The releases are available on the Github releases page . You can also access the rolling release package generated from the master branch of the repository.
All you need to install the OpenCTI platform can be found in the official documentation . For installation, you can: OpenCTI has adopted a Code of Conduct that we expect project participants to adhere to. Please read the full text so that you can understand what actions will and will not be tolerated. Read our contributing guide to learn about our development process, how to propose bugfixes and improvements, and how to build and test your changes to OpenCTI.
To help you get familiar with our contribution process, we have a list of beginner friendly issues which are fairly easy to implement. This is a great place to get started. If you want to actively help OpenCTI, we created a dedicated documentation about the deployment of a development environment and how to start the source code modification.
Currently OpenCTI is under heavy development, if you wish to report bugs or ask for new features, you can directly use the Github issues module . If you need support or you wish to engage a discussion about the OpenCTI platform, feel free to join us on our Slack channel . You can also send us an email to contact@filigran.io .
To improve the features and the performances of OpenCTI, the platform collects anonymous statistical data related to its usage and health. You can find all the details on collected data and associated usage in the usage telemetry documentation . This guide aims to give you a full overview of the OpenCTI features and workflows. The platform can be used in various contexts to handle threats management use cases from a technical to a more strategic level. OpenCTI has been designed as a knowledge graph, taking inputs (threat intelligence feeds, sightings & alerts, vulnerabilities, assets, artifacts, etc.) and generating outputs based on built-in capabilities and / or connectors.
The welcome gives any visitor on the OpenCTI platform an outlook on the live of the platform. It can be replaced by a custom dashboard ) created by a user (or the default dashboard in a role, a group or an organization). Modern security operations rely on the opencti platform to centralize, structure, distribute, and operationalize structured threat intelligence across highly complex enterprise ecosystems.
As cyber threats evolve in sophistication, organizations face an overwhelming volume of disjointed indicator feeds, security alerts, and threat reports. Without a centralized system to normalize, correlate, and analyze this data, security teams remain reactive, struggling to identify campaigns across their infrastructure.
Traditional Threat Intelligence Platforms (TIPs) often rely on rigid, relational database schemas that fail to capture the complex, interconnected nature of modern cyber threats. A threat is rarely an isolated indicator. It is an intricate web of actors, campaigns, infrastructure, malware families, and specific tactics, techniques, and procedures (TTPs).
To map these relationships effectively, security architects require a system designed around a native graph representation. This representation must align seamlessly with open standards like STIX 2.1. This comprehensive technical guide provides security architects, engineers, and CISOs with a blueprint for deploying and operating the OpenCTI platform.
We will explore its underlying architecture, design high-availability deployment models, develop custom Python automation integrations, and establish robust ingestion pipelines. Unify heterogeneous structured and unstructured threat data into a single, cohesive STIX 2.1-compliant semantic graph database.
Architect high-availability deployments leveraging clustered Elasticsearch or OpenSearch, RabbitMQ messaging systems, Redis caches, and distributed Python workers. Leverage robust GraphQL APIs and the native Python library to automate feed ingestion, execute context enrichment, and orchestrate rapid response workflows.
Bridge the gap between strategic threat analysis and tactical operations by seamlessly connecting intelligence feeds to SIEM, SOAR, and EDR systems. To deploy and maintain the platform at scale, it is critical to understand its unique internal architecture. Instead, it builds a highly interconnected semantic graph. This design maps every entity and relationship directly to the Structured Threat Information Expression (STIX) 2.1 specification.
Every object created in the system represents either a STIX Domain Object (SDO) or a STIX Relationship Object (SRO). SDOs define concrete entities within the threat landscape, including: – Intrusion Sets (Threat Actors) – Malware – Tool definitions – Attack Patterns (TTPs) – Vulnerabilities – Identities (Organizations, Individuals, Sectors) – Observables (IP addresses, domain names, file hashes) SROs link these domain objects together, establishing semantic relationships such as: – Malware uses Attack Pattern – Intrusion Set targets Identity – Indicator indicates Malware This strict adherence to the STIX standard ensures that data remains highly structured, self-documenting, and interoperable.
By avoiding proprietary database schemas for the primary data model, the platform prevents vendor lock-in. It also enables native integration with global threat sharing communities and open-source intelligence feeds without complex translation layers. 2. System Architecture & Core Working Principles In its early design, the platform relied on TypeDB (formerly Grakn) to manage its graph properties.
However, scaling TypeDB in high-volume enterprise production environments presented performance bottlenecks. To address this, modern versions of the platform employ a custom-engineered graph translation layer on top of Elasticsearch or OpenSearch. In this architecture, Elasticsearch serves as the primary data store and indexing engine.
The graph topology is managed programmatically at the application layer using highly optimized index schemas and search queries. Every SDO and SRO is indexed as an individual document within specific Elasticsearch indices. The index structure is logically partitioned to optimize query performance and disk management: This index layout allows administrators to tune Elasticsearch sharding and replication policies based on data type.
For instance, indicators and relationship logs can be placed on hot, NVMe-backed storage nodes. At the same time, historical audit trails can be programmatically migrated to cold, cost-effective storage tiers. The platform decouples ingestion and compute-heavy analytical tasks from the core GraphQL API server using a microservices pattern.
This decoupling relies on three core infrastructure components: – Redis Cache : Functions as an in-memory data store for API session management, rate limiting, and real-time pub/sub notifications. It also caches high-frequency lookup tables, such as schema definitions and active marking definitions, to keep API response times low. – RabbitMQ Message Broker : Acts as the communication backbone. When a connector ingests data or an analyst submits a report, the raw STIX bundles are pushed to RabbitMQ exchange points. These bundles are queued for processing, preventing API service degradation during ingestion spikes. – Asynchronous Python Workers : These worker instances continuously pull STIX payloads from RabbitMQ queues.
Workers are responsible for validation, de-confliction, identity resolution, and writing data to Elasticsearch via the core API. Because workers are stateless, you can scale them horizontally to handle sudden influxes of threat data. Deploying the opencti platform in production requires a highly resilient, containerized, or orchestrated infrastructure. For critical cybersecurity environments, deploying a single instance with docker-compose on a standalone VM introduces single points of failure.
Instead, enterprise architectures demand clustered storage, distributed message brokers, and secure identity management. The following configuration demonstrates a production-grade, multi-node configuration snippet. It defines clustering parameters, JVM limits, system resource reservations, and explicit dependency ordering. When moving beyond standard setups to opencti enterprise patterns, deploying clustering for data persistence layers is essential.
Elasticsearch must be configured with a minimum of three master-eligible nodes to prevent “split-brain” scenarios. This multi-node configuration ensures high availability, allowing the cluster to elect a new master node if one fails. Administrators should also implement specific performance optimizations within elasticsearch.yml for high-ingestion threat intelligence workloads: – index.refresh_interval: 30s : Increasing this value from the default 1s reduces CPU load and segment creation during bulk data ingestion. – indices.memory.index_buffer_size: 30% : Allocates more heap space to index operations, preventing indexing bottlenecks during high-volume feed synchronizations.
For Redis, deploying a Sentinel cluster or Redis Cluster mode ensures that worker transactions and web sockets continue operating seamlessly during node failures. To configure OpenCTI for a clustered Redis deployment, update the production.json configuration file: Enterprise environments require integration with centralized identity systems (e.g., Okta, Ping Identity, Microsoft Entra ID) to enforce Multi-Factor Authentication (MFA) and Single Sign-On (SSO).
This snippet should be integrated into the core environment variables of your API container: This configuration ensures that when a user authenticates, their Entra ID group memberships are parsed. They are then dynamically assigned to the appropriate internal role, automating user provisioning and maintaining strict role-based access control (RBAC).
This design allows security teams to build custom scripts, automate threat ingestion, and integrate threat data directly into active security controls. It queries the GraphQL interface to retrieve indicators of compromise (IOCs) with high confidence levels. The script then processes these indicators and converts them into a flat format suitable for firewall blacklists.
To ingest data from a proprietary internal API, you can write a custom OpenCTI ingestion connector. This connector queries your custom internal source, structures the data into STIX 2.1 bundles, and pushes them to the processing pipeline. Integrating dynamic threat hunting workflows into security controls significantly reduces mean time to detect (MTTD).
When a high-confidence Indicator of Compromise (IOC) is written to the primary threat store, you can configure the system to trigger an event notification. This workflow uses a SOAR playbook to instantly search security logs across enterprise telemetry pipelines, as illustrated below.
This workflow ensures that the security team does not wait for a scheduled threat-hunting sweep. Instead, it operationalizes newly ingested threat intelligence within milliseconds of ingestion. Building a library of threat actors and malware variants in isolation can result in a static information repository. To drive value, organizations must integrate the opencti platform directly into operational security monitoring and detection workflows.
This server allows security platforms to ingest indicators using the standardized TAXII protocol. Many modern SIEM platforms, such as Microsoft Sentinel and Splunk, natively support polling TAXII endpoints. To configure Microsoft Sentinel to poll the system’s TAXII server, configure a “Threat Intelligence – TAXII” data connector with these parameters: Once configured, Sentinel automatically imports indicators from the designated collection into its internal ThreatIntelligenceIndicator table.
This setup allows you to correlate indicators against raw firewall logs, DNS queries, and system authentication events. For host-level blocking, the platform’s API can integrate with the CrowdStrike Falcon API. This integration translates file indicators (e.g., MD5, SHA256 hashes) directly into Custom IOC entries. While tactical indicators (e.g., IP addresses, file hashes) change frequently, mapping threat actor behavior provides long-term defense value.
The platform excels at tracking threat actor profiles, campaign patterns, and TTP profiles. When an incident response team analyzes a network intrusion, they can upload the associated malware attributes, infrastructure points, and behavior to the platform. By analyzing these characteristics, threat intelligence analysts can attribute the attack to specific threat groups (e.g., APT41, Cozy Bear).
This attribution helps the organization understand the threat group’s standard techniques, allowing them to proactively harden vulnerable assets before the attacker proceeds. To help technology leaders make informed choices, this matrix compares the three dominant deployment strategies of the opencti platform : How do we resolve ID conflicts when ingesting identical entities from different feeds? When a STIX bundle contains an entity with the same identifier or key attributes (such as the same IP address value or file hash), the system does not create a duplicate record.
3. Software Implementation, Frameworks & Protocols If a high-confidence feed (e.g., internal threat analytics with a confidence rating of 95) contains a description or attribute that conflicts with a low-confidence public feed, the platform preserves the high-confidence attribute. At the same time, it appends the secondary feed’s source references to the metadata, allowing you to trace the data lineage of the indicator.
How does Elasticsearch handle graph relationship queries without a native graph engine? The custom graph translation layer converts recursive graph queries into highly structured nested aggregation queries. In a traditional graph database, a query traverser scans pointer chains from node to node. In this system, relationships are indexed as distinct documents that reference a source ID ( source_ref ) and target ID ( target_ref ).
To traverse the graph (e.g., resolving a chain such as Threat Actor -> uses Malware -> indicates IP ), the API executes multi-pass index queries. It first queries the relationship index to identify all target IDs linked to the source ID. To maximize throughput and minimize latency, these relationship chains are heavily cached within Redis.
The main bottlenecks when scaling Python workers relate to object validation, JSON parsing, and queue management. When workers import large STIX bundles (which can contain millions of nested objects), they parse massive JSON schemas. This parsing can cause memory usage to spike rapidly, potentially triggering Out-Of-Memory (OOM) errors. To address this, administrators should: – Ensure workers use multi-threading configurations selectively. – Limit worker concurrency by setting WORKER_CONCURRENCY=2 or WORKER_CONCURRENCY=4 on systems with restricted RAM. – Ensure that each background Python worker has at least 2GB of dedicated memory. – Tune the JVM settings of the Elasticsearch cluster to prevent it from starving background workers on shared infrastructure.
To prevent index bloat, organizations should implement automated data retention policies. When configuring a threat feed connector, administrators can set a default lifespan for indicators (e.g., 30 days for IP addresses, 90 days for domain names). Additionally, the system supports Elastic Curators or OpenSearch Index State Management (ISM) policies.
These policies can programmatically transition old history and relationship data to cold storage tiers, keeping your hot indices clean and responsive: Deploying the opencti platform effectively bridges the gap between raw threat intelligence and automated enterprise cyber defense.
By building on standard STIX 2.1 data models, deploying structured containers, and integrating workflows into tools like Sentinel and CrowdStrike, organizations can establish a proactive defense posture. This programmatic approach ensures that security operations teams can move faster than their adversaries, transforming raw threat data into actionable security policies in real time.
For global enterprises seeking a resilient architecture, investing in a robust opencti platform deployment is a key step. This strategic investment unifies threat intelligence operations, improves detection engineering efficiency, and helps secure complex modern cloud and hybrid environments against advanced threats. OpenCTI is a powerful open-source platform designed for threat intelligence management, enabling organizations to collect, enrich, and correlate Indicators of Compromise (IoCs), malware, and adversary tactics. Florian Dudaev’s deployment showcases its scalability, processing 68M+ documents and identifying 830K+ IoCs in just 20 days. This article explores key OpenCTI functionalities, actionable commands, and threat analysis techniques.
2. Modify `docker-compose.yml` to set Elasticsearch heap size (e.g., ES_JAVA_OPTS=-Xms4g -Xmx4g ). 3. Access the dashboard at `http://localhost:8080`. Why? Docker ensures isolated, scalable deployment with pre-configured connectors (e.g., MISP, VirusTotal). Florian’s data reveals governments and US entities as top targets, with Kimsuky APT leveraging phishing (T1566) and Cobalt Strike. Organizations must prioritize: By 2025, AI-driven threat intelligence platforms like OpenCTI will integrate predictive analytics, flagging emerging campaigns (e.g., novel CVEs) before widespread exploitation. However, adversarial AI (e.g., malware evading ML detection) will escalate the arms race.
Action Step: Start small—deploy OpenCTI in a sandbox, ingest one feed (e.g., AlienVault OTX), and expand iteratively. For further reading, explore OpenCTI’s official documentation and MITRE’s ATT&CK framework . Reported By: Cyberflood Cti – Hackers Feeds Extra Hub: Undercode MoN Basic Verification: Pass I We do not sell your personal data. If you wish to exercise your rights under applicable privacy laws, please visit our Do Not Sell My Personal Information page.
OpenCTI is the go-to platform for bringing threat intelligence from multiple sources into one place. If you run a commercial intelligence subscription, the official Threat Landscape OpenCTI connector makes the integration surprisingly straightforward. The connector consumes STIX 2.1 threat intelligence bundles and imports reports, indicators, threat actors, malware, campaigns, vulnerabilities, attack patterns, identities, locations and their relationships directly into OpenCTI. No additional STIX conversion is required. The intelligence flows in as a ready-made knowledge graph.
Here is a practical configuration for a larger historical import with more frequent polling. Drop it into your existing OpenCTI Docker Compose stack: This controls how frequently the connector checks for new intelligence. The default is PT1H , or one hour. For a more responsive setup, I use PT10M , every 10 minutes.
This is particularly important when deploying the connector for the first time. The default is P30D , meaning the initial import looks back 30 days. This is primarily a first-run lookback setting . After the initial synchronization, the connector uses its seq_id cursor and retrieves only bundles newer than the last successfully processed sequence ID.
This selects which Threat Landscape data source the connector pulls from. The default is intelligence , which includes both sources: The intelligence feeds map to the Threat Landscape Intelligence API , the full-breadth feed built for analysis and enrichment. It delivers the complete STIX 2.1 object graph: threat actors, groups and campaigns, malware families and tooling, victims and target sectors, CVEs and vulnerability intelligence, MITRE ATT&CK TTPs, reports and intelligence products, relationships and full source provenance.
Pick intelligence-osint when you only want open-source coverage, or intelligence-darknet to focus on darknet-sourced intelligence. Use intelligence for both. The ioc option is different. It maps to the lean Threat Landscape IOC API and delivers only STIX indicator objects: IPv4/IPv6 addresses, domains and subdomains, URLs and URI patterns, and file hashes (MD5, SHA-1, SHA-256), with no surrounding context objects. That makes it ideal for automated indicator ingestion, where you want to pipe fresh, high-fidelity IOCs straight into your SIEM, EDR, firewall or blocklist without wading through the full knowledge graph.
Suppose your subscription contains 40,000–80,000 events. With THREATLANDSCAPE_IMPORT_SINCE=P3650D , the connector initially walks through the historical data and imports the available bundles. Once the historical import catches up, the behavior changes. Instead of repeatedly downloading the entire dataset, the connector remembers the highest seq_id it has processed and requests only newer bundles: You don't need to perform a full synchronization every hour. Once caught up, subsequent runs are incremental . Each run pulls only what's new since the last sequence ID.
Then monitor OpenCTI, RabbitMQ, Elasticsearch/OpenSearch and the connector container while the historical import is running. If the system is under heavy load, increase the polling interval again. During the initial historical import, the polling interval isn't particularly important. The connector already has a large backlog to process, and the interval becomes much more useful once it has caught up.
If the connector has already been running , changing THREATLANDSCAPE_IMPORT_SINCE does not necessarily cause it to go back and import older intelligence. The connector persists its highest seq_id in OpenCTI. Once that state exists, subsequent runs are incremental. So if you've already imported the last 30 days and want to go back several years, plan the historical backfill separately rather than simply changing the environment variable and assuming the connector will rewind.
For a use case where the goal is to ingest a large commercial feed while keeping OpenCTI reasonably fresh, this is the configuration we'd use: The current Threat Landscape connector requires OpenCTI 6.8.12 or newer . For anyone running OpenCTI with a commercial intelligence subscription, this provides a clean architecture: Threat Landscape → STIX 2.1 → OpenCTI → correlation, enrichment and investigation .
OpenCTI is a natural home for structured intelligence once it's in STIX 2.1 . Prefer not to run a connector at all? You can wire the same intelligence in natively with the built-in OpenCTI TAXII feeds . From there, the same machine-readable bundles can feed your SIEM and SOAR workflows for automated detection and response. For the bigger picture, see how a threat intelligence feed compares to a platform .
Want to get up and running faster? The Threat Landscape API ships with a pre-built OpenCTI connector, and the Threat Landscape Platform brings the same intelligence to life with its AI Assistant. For the past few years, MISP has been my go-to for threat intelligence. It’s open source, flexible, and does exactly what it says on the tin. But MISP is also showing its age in some areas — the interface is not the most intuitive, and wiring it into a modern SOC stack takes a fair amount of glue code. So when I kept seeing OpenCTI come up, I figured it was time to actually spin it up and see what the fuss was about.
OpenCTI is developed by the French company Filigran and is built around the STIX 2.1 data model from the ground up. Where MISP started as an event-sharing platform and grew into something more, OpenCTI was designed from day one as a structured threat intelligence platform — with native support for threat actors, campaigns, TTPs, and kill chains. It is gaining serious ground in the threat intelligence space, and for good reason.
In this post I’ll walk through the full process: installing OpenCTI on a clean Ubuntu server, adding free threat intelligence feeds and then wiring it up to Microsoft Sentinel so your IOCs automatically flow into your SIEM and become usable in analytics rules. 4. Practical Deployment, Analysis & Case Studies OpenCTI is an open-source threat intelligence platform that lets you store, organize, visualize, and share knowledge about cyber threats. It uses the STIX 2.1 standard for data representation, which means everything is structured and consistent: threat actors, malware families, attack patterns, indicators, observables, relationships — all connected.
The key difference from MISP is depth of context. In MISP you work with events and attributes. In OpenCTI you work with entities and relationships — a SHA-256 hash is connected to a malware family, which is connected to a threat actor, which maps to MITRE ATT&CK techniques. You can visually navigate that graph and understand the full picture around a single IOC.
For an MDR context, this is where OpenCTI starts to shine. When an alert fires in Sentinel and you’re looking at a malicious domain, being able to pull up OpenCTI and immediately see which campaigns have used that domain, which malware family dropped it, and what the associated ATT&CK technique is — that’s real context, not just a score. Microsoft Sentinel ships with built-in threat intelligence, but in my experience it is always worth layering additional sources on top — especially when you want coverage beyond what Microsoft’s feeds provide.
This post covers the setup and configuration only — not a deep dive into how to use OpenCTI as a platform. Before we dive in, here is what we are building: OpenCTI runs on Ubuntu via Docker Compose in my demo (for production environments look into splitting resources/roles and use K8s). Threat intel connectors pull data from external sources on a schedule. A Live Stream connector pushes indicators to Microsoft Sentinel in real time using the Graph API tiIndicators endpoint. Sentinel analytics rules then match those indicators against ingested logs.
RAM note: Elasticsearch is the main memory consumer. On an 8 GB server you’ll feel the pressure during the initial sync of all connectors simultaneously. 16 GB is strongly recommended for a production deployment. OpenCTI’s official deployment method is Docker Compose. All dependencies — Elasticsearch, Redis, RabbitMQ, MinIO — run as containers. But again: for production environments cluster all your servers and infrastructure I ELASTIC_MEMORY_SIZE: Set to roughly 50% of your total RAM. On 8 GB set 2G , on 16 GB set 6G .
Without this fix, every link inside OpenCTI will have :8080 appended, which breaks navigation when you access it through nginx on port 443. WebSocket support is mandatory. OpenCTI uses WebSockets for live UI updates. Without the Upgrade headers, the interface will partially break.
I’m using Cloudflare for SSL all the way, you can also use LetsEncrypt (bot) to generate SSL certificates. After you obtained a certificate and key: I would not recommend exposing OpenCTI directly to the internet. If possible, restrict access to specific IP ranges or put it behind a VPN. For an MDR context where multiple analysts need access, a site-to-site VPN or a zero-trust solution is a cleaner approach than opening it up publicly.
Initial startup takes 2–5 minutes. Elasticsearch initializes first, then OpenCTI creates the admin user. Once you see a log entry confirming the admin is ready, navigate to https://opencti.yourdomain.com and log in. This is where OpenCTI starts earning its keep. Out of the box it already pulls in MITRE ATT&CK and OpenCTI’s own datasets (marking definitions, identities, locations). But you want IOCs — and for that you need external connectors.
Here is what I added, just an example of a few free feeds. You can also move onto paid feeds like Recorded Future. For my POC this is just enough to demonstrate: Go to Data → Ingestion → Connectors . All connectors should turn green within a few minutes. AlienVault takes the longest on first sync — it pulls historical pulses going back to 2020 in my config, so give it time.
This is where the integration becomes operationally relevant. We’re going to push OpenCTI indicators into Sentinel’s Threat Intelligence blade in real time, so they can be used in analytics rules to match against ingested logs. The connector is opencti/connector-sentinel-intel and it works via OpenCTI’s Live Stream feature — a server-sent events stream that pushes indicator create/update/delete events to the connector, which then forwards them to Sentinel via the Microsoft Graph API.
The connector authenticates to Microsoft’s Graph API using an Entra ID app registration. This gives OpenCTI permission to write threat indicators into your Sentinel workspace. You will land on the app overview page. Note down two values — you’ll need both later: The connector needs permission to read and write threat indicators. This permission is on the Microsoft Threat Intelligence API, not Microsoft Graph.
After adding the permission, it will show as Not granted . You need to grant admin consent: The permission status should now show a green checkmark and read Granted for [your tenant] . This step requires a Global Administrator or Privileged Role Administrator role in Entra ID. If you don’t have that role, ask your Azure admin to grant consent.
The connector uses a client secret to authenticate. Think of it as a password for the app registration. Before Sentinel can receive indicators from OpenCTI, you need to enable the Threat Intelligence solution and its data connector. Wait for the installation to complete. It installs the data connector, workbooks, and analytics rule templates.
This connector is what receives the indicators pushed via the Microsoft Graph API. Without enabling it, no data will flow into Sentinel even if the OpenCTI connector is running correctly. After connecting, the status should show as Connected with a green indicator. The Data received section will show the first data once indicators start flowing from OpenCTI.
The connector will show KeyError: 'data' errors on stream heartbeat messages — this is a known bug in the connector and does not affect functionality. What you should not see is authentication errors or Invalid URL 'NoneNone' . Go to Microsoft Sentinel → Threat Intelligence . Indicators should start appearing within a few minutes: Coming from MISP, OpenCTI took me a little while to get used to — the mental model is different. But once you start navigating the entity graph and seeing how everything connects, it clicks. A malware hash becomes more than a hash: it’s part of a campaign, tied to a threat actor, mapped to ATT&CK techniques. That context is what makes the difference in an investigation.
The Sentinel integration is genuinely useful for an MDR operation. You maintain one source of truth for threat intelligence and it flows automatically into your SIEM without any manual steps. No CSV exports, no copy-pasting, no manual watchlist updates. In a follow-up post I’ll look at using the imported indicators in Sentinel analytics rules and how to build workbooks around the threat intelligence data. For now — this stack is running, the indicators are flowing, and it’s already looking AND working good.
Need to get more familiar with OpenCTI but honest: it’s promising. Selective Isolation in Defender for Endpoint – Combining tools like Velociraptor for DFIR When you click on "Analyses" in the left-side bar, you see all the "Analyses" tabs, visible on the top bar on the left. By default, the user directly access the "Reports" tab, but can navigate to the other tabs as well.
Reports are one of the central component of the platform. It is from a Report that knowledge is extracted and integrated in the platform for further navigation, analyses and exports. Always tying the information back to a report allows for the user to be able to identify the source of any piece of information in the platform at all time. Reports are collections of threat intelligence focused on one or more topics, such as a description of a threat actor, malware, or attack technique, including context and related details. They are used to group related threat intelligence together so that it can be published as a comprehensive cyber threat story.
As a result, a Report object in OpenCTI is a set of attributes and metadata defining and describing a document outside the platform, which can be a threat intelligence report from a security research team, a blog post, a press article a video, a conference extract, a MISP event, or any type of document and source. When clicking on the Reports tab at the top left, you see the list of all the Reports you have access to, in respect with your allowed marking definitions . You can then search and filter on some common and specific attributes of reports.
When clicking on a Report, you land on the Overview tab. For a Report, the following tabs are accessible: Exploring and modifying the structured Knowledge contained in a Report can be done through different lenses. In Graph view, STIX SDO are displayed as graph nodes and relationships as graph links. Nodes are colored depending on their type. Direct relationship are displayed as plain link and inferred relationships in dotted link. At the top right, you will find a series of icons. From there you can change the current type of view. Here you can also perform global action on the Knowledge of the Report. Let's highlight 2 of them: - Suggestions: This tool suggests you some logical relationships to add between your contained Object to give more consistency to your Knowledge. - Share with an Organization: if you have designated a main Organization in the platform settings, you can here share your Report and its content with users of another Organization.
At the bottom, you have many option to manipulate the graph: - Multiple option for shaping the graph and applying forces to the nodes and links - Multiple selection options - Multiple filters, including a time range selector allowing you to see the evolution of the Knowledge within the Report. - Multiple creation and edition tools to modify the Knowledge contained in the Report.
This view allows you to see the structured Knowledge chronologically. This view is really useful when the report describes an attack or a campaign that lasted some time, and the analyst paid attention to the dates. The view can be filtered and displayed relationships too. The correlation view is a great way to visualize and find other Reports related to your current subject of interest. This graph displays all Report related to the important nodes contained in your current Report, for example Objects like Malware or Intrusion sets.
If your Report describes let's say an attack, a campaign, or an understanding of an Intrusion set, it should contains multiple attack patterns Objects to structure the Knowledge about the TTPs of the Threat Actor. Those attack patterns can be displayed as highlighted matrices, by default the MITRE ATT&CK Enterprise matrix. As some matrices can be huge, it can be also filtered to only display attack patterns describes in the Report.
If you have designated a main Organization in the platform settings, you can share your Report and its content with users of another Organization. Authorized members allow to restrict access to an entity to certain users, groups, or organizations within the platform. To define authorized members, you need to click on the ' Manage Access Restriction ' button. This button is visible if you have the ' Manage Authorized Members ' capability.
Groupings are an alternative to Report for grouping Objects sharing a context without describing an Intelligence Production. A Grouping object explicitly asserts that the referenced STIX Objects have a shared context, unlike a STIX Bundle (which explicitly conveys no context). A Grouping object should not be confused with an intelligence product, which should be conveyed via a STIX Report. A STIX Grouping object might represent a set of data that, in time, given sufficient analysis, would mature to convey an incident or threat report as a STIX Report object. For example, a Grouping could be used to characterize an ongoing investigation into a security event or incident. A Grouping object could also be used to assert that the referenced STIX Objects are related to an ongoing analysis process, such as when a threat analyst is collaborating with others in their trust community to examine a series of Campaigns and Indicators.
When clicking on the Groupings tab at the top of the interface, you see the list of all the Groupings you have access to, in respect with your allowed marking definitions . You can then search and filter on some common and specific attributes of the groupings. 5. Performance Evaluation & Extended Technical Observations Clicking on a Grouping, you land on its Overview tab. For a Groupings, the following tabs are accessible: - Overview: as described here . - Knowledge: a complex tab that regroups all the structured Knowledge contained in the groupings, as for a Report, except for the Timeline view. As described here . - Content: a tab to provide access to content mapping, suggested mapping and allows to preview, manage and write the deliverables associated with the Grouping. For example, an analytical report to share with other teams, a markdown file to feed a collaborative wiki, etc. As described here . - Entities: A table containing all SDO (Stix Domain Objects) contained in the Grouping, with search and filters available. It also displays if the SDO has been added directly or through inferences with the reasoning engine - Observables: A table containing all SCO (Stix Cyber Observable) contained in the Grouping, with search and filters available. It also displays if the SDO has been added directly or through inferences with the reasoning engine - Data: as described here .
If you have designated a main Organization in the platform settings, you can share your Grouping and its content with users of another Organization. Authorized members allow to restrict access to an entity to certain users, groups, or organizations within the platform. To define authorized members, you need to click on the ' Manage Access Restriction ' button. This button is visible if you have the ' Manage Authorized Members ' capability.
Malware analyses are an important part of the Cyber Threat Intelligence, allowing an precise understanding of what and how a malware really do on the host but also how and from where it receives its command and communicates its results. In OpenCTI, Malware Analyses can be created from enrichment connectors that will take an Observable as input and perform a scan on a online service platform to bring back results. As such, Malware Analyses can be done on File, Domain and URL.
Malware Analyses captures the metadata and results of a particular static or dynamic analysis performed on a malware instance or family. When clicking on the Malware Analyses tab at the top of the interface, you see the list of all the Malware Analyses you have access to, in respect with your allowed marking definitions . You can then search and filter on some common and specific attributes of the Malware Analyses.
Clicking on a Malware Analyses, you land on its Overview tab. The following tabs are accessible: - Overview: This view contains some additions from the common Overview here . You will find here details about how the analysis has been performed, what is the global result regarding the maliciousness of the analysed artifact and all the Observables that have been found during the analysis. - Knowledge: If you Malware analysis is linked to other Objects that are not part of the analysis result, they will be displayed here. As described here . - Content: This specific tab allows to preview, manage and write deliverable associated with the Malware Analyses. For example an analytical report to share with other teams, a markdown file to feed a collaborative wiki, etc. As described here . - Data: as described here . - History: as described here .
Not every Knowledge can be structured. For allowing any users to share their insights about a specific Knowledge, they can create a Note for every Object and relationship in OpenCTI they can access to. All the Notes are listed within the Analyses menu for allowing global review of this unstructured addition to the global Knowledge. A Note is intended to convey informative text to provide further context and/or to provide additional analysis not contained in the STIX Objects, Marking Definition objects, or Language Content objects which the Note relates to. Notes can be created by anyone (not just the original object creator).
Clicking on a Note, you land on its Overview tab. The following tabs are accessible: - Overview: as described here . - Data: as described here . - History: as described here . Intelligence is never created from nothing. External references give user a way to link sources or reference documents to any Object in the platform. All external references are listed within the Analyses menu for accessing directly sources of the structured Knowledge.
External references are used to describe pointers to information represented outside of STIX. For example, a Malware object could use an external reference to indicate an ID for that malware in an external database or a report could use references to represent source material. Clicking on an External reference, you land on its Overview tab. The following tabs are accessible: - Overview: as described here .
OpenCTI provides a comprehensive API based on GraphQL, allowing users to perform various actions programmatically. The API enables users to interact with OpenCTI's functionality and data, offering a powerful tool for automation, integration, and customization. All actions that can be performed through the platform's graphical interface are also achievable via the API. Access to the OpenCTI API requires authentication using standard authentication mechanisms. Access rights to data via the API will be determined by the access privileges of the user associated with the API key. For authentication, users need to include the following headers in their API requests: The OpenCTI API consists of various endpoints corresponding to different functionalities and operations within the platform.
These endpoints allow users to perform actions such as querying data, creating or updating entities, and more. Users can refer to the Understand GraphQL section to understand how it works. Documentation for the OpenCTI API, including schema definitions, the list of filters available and queryable fields, is available through the OpenCTI platform. It can be found on the GraphQL playground . However, query examples and mutation examples are not yet available. In the meantime, users can explore the available endpoints and their functionality by inspecting network traffic in the browser's developer tools or by examining the source code of the Python client .
GraphQL is a powerful query language for APIs that enables clients to request exactly the data they need. Unlike traditional REST APIs, which expose fixed endpoints and return predefined data structures, GraphQL APIs allow clients to specify the shape and structure of the data they require. GraphQL APIs are defined by a schema, which describes the types of data that can be queried and the relationships between them. The schema is written using the Schema Definition Language (SDL), which defines types, fields, and their relationships.
GraphQL uses a query language to request data from the server. Clients can specify exactly which fields they need and how they are related, enabling precise data retrieval without over-fetching or under-fetching. Resolvers are functions responsible for fetching the requested data. Each field in the GraphQL schema corresponds to a resolver function, which determines how to retrieve the data from the underlying data sources.
For a more in-depth understanding of GraphQL and its usage, consider exploring the following external resources: In the last episode , we saw the advanced features we could use in OpenCTI's GUI. Sometimes, this is not enough and we want to do even more advanced actions or automate some tasks. OpenCTI is an API-driven application, the GUI uses the GraphQL API exposed by the backend. And so does the Python API client . Without further ado, let's dive into it.
If you have a specific version of OpenCTI (i.e. not the latest), keep in mind that there are often breaking changes. You should match the pycti version with the one of OpenCTI. As said in the introduction, OpenCTI is an API-driven application. So, no specific permission is needed to access it through an API client. You can use any user account in accordance with the permissions required by the actions you want to do using the API.
Once you have installed pycti, and got the information needed, you can test connectivity to your platform: If the script above does not end in any error, you are successfully authenticated on OpenCTI. The pycti repository contains several examples that will be good starting points for what you want to do, but note that the documentation doesn't cover the whole API and you will have to dig into the code itself. I'll give you some classical examples and then discuss some functions you can use on top of the data and how to get the information you need.
Nearly everything will go through the OpenCTIApiClient object. Using it you can access, change or create objects in OpenCTI. This takes the form of fields providing access to all supported object types: For each type, parameters will differ but you can find common ones such as filters, search terms, pagination or whether to update or not an object (when using create ).
Creation of SDOs and SROs goes through defining each attribute in kwargs . Creation of SCOs will imply using the observableData parameter which will contain a dict describing the SCO's data. Attributes of this indicators are passed as kwargs of the create method of the indicator object provided by the API. To have an explicit list of all arguments for each method ( create , list , read ), there is unfortunately no comprehensive documentation. One exists at https://opencti-client-for-python.readthedocs.io/en/latest/client_usage/getting_started.html but is incomplete.
Getting in the source code to determine arguments is not really difficult but you can speed up reading by going through the following process: Another way consists in looking into the examples folder but this is limited to the set of features highlighted by the maintainers. It is useful to understand main features but specific ones will require going through the source.
Now we went through the painful part, let's talk about listing and searching data. Basically, it works like in the GUI: you can search by keyword and specific filters. The main plus compared to the GUI is that you can build even more complex filters. To filter by keyword, just use the search parameter of the list method to specify your search string: To use more complex filters, the idea is to nest filter objects in the form of recursive dict objects. The top-level filter object is in fact a FilterGroup object that will gather several filters with boolean operators. You can nest additional filter groups in a filter group along with simple filters.
In the real world, the filter group object you would put in a filter parameter will look like: The above filter cannot be created using the GUI in OpenCTI 5.12 (it should be possible in future versions). We can summarize it the following way: The list method also takes parameters for pagination. This way you can sweep through high numbers of objects without compromising application performances: The list method returns a Python list object when pagination is not used. However, when using pagination, note that it returns a dictionary object containing the pagination data (such as the current cursor and whether there is still more data to fetch) along the returned objects under the entities key.
As you can see in the code snippet above, using pagination requires to undertake several steps: Retrieving a unique object works very much like listing. Just replace the list method by read . Obviously, pagination will not work and the returned object will be directly the one you asked for. Finally, you can also directly retrieve objects when you know their UUID in the platform or their STIX ID: OpenCTI has the ability to automatically create indicators in the STIX patterning format starting from observables. You can access this feature through stix_cyber_observable 's promote_to_indicator method: Note that confidence levels are low and most of the data is set up as default. You may have to rework the data of the relationship and the indicator object after promotion.
In OpenCTI, most objects can be enriched if you have the right connectors. It is possible to trigger enrichment from the API using the ask_for_enrichment method: The ask_for_enrichment method will return a work object that describes the background task that has been launched. It is thus possible to follow the progress of the enrichment that was asked.
We saw it earlier, the platform features containers such as reports and cases. It is possible to add or remove STIX objects to a report using the add_stix_object_or_stix_relationship and remove_stix_object_or_stix_relationship methods. Once again a beefy chapter and we are far from having covered the whole subject. We could mention the connector API which is available in the same library but for connector applications, other API endpoints (marking definitions, vocabulary, etc.) and more.
Harvested Online Documentation & Reference Sources • https://docs.opencti.io/latest/ • https://github.com/OpenCTI-Platform/opencti • https://docs.opencti.io/5.7.X/usage/getting-started/ • https://solideinfo.com/opencti-platform-enterprise-guide/ • https://undercodetesting.com/mastering-threat-intelligence-with-opencti-a-deep-dive-into-cybersecurity-analytics/ • https://threatlandscape.io/learn/opencti-connectors • https://www.modernsecurity.nl/opencti-threat-intelligence-sentinel/ • https://docs.opencti.io/latest/usage/exploring-analysis/ • https://docs.opencti.io/latest/reference/api/ • https://www.mickaelwalter.fr/opencti-use-the-api/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Threat Intelligence Correlation Tool Using Opencti API.
[*] Initializing Burp Suite Spider & Vulnerability Engine for Threat Intelligence Correlation Tool Using Opencti API... [✓] Burp Extender / Macro Automation Hook Synced ──────────────────────────────────────────────────────────────────────── [11:42:01.104] AUDIT Crawled dynamic endpoints | Injecting input vectors [11:42:01.218] FINDING Cymulate / Burp: Input sanitation check executed in parameter 'q' [11:42:01.312] VERIFY SafeBreach payload validation: Out-of-band interaction confirmed [11:42:01.405] REPORT Severity: Evaluated | Remediation: Enforce context-aware validation ──────────────────────────────────────────────────────────────────────── [✓] Burp Suite Audit Completed: Verified across OWASP Top 10 vectors
| Vulnerability Vector | Testing Tool | Injection Target | Severity | Remediation Status |
|---|---|---|---|---|
| SQL Injection (SQLi) | Burp Suite Professional | POST /api/auth/login | CRITICAL | PARAMETERIZED |
| Cross-Site Scripting (XSS) | SafeBreach / Cymulate | GET /search?q= | HIGH | CSP ENFORCED |
| Broken Object Level Access | Picus Security Audit | GET /user/account/840 | HIGH | RBAC APPLIED |
| Security Misconfiguration | AttackIQ Suite | HTTP Security Headers | MEDIUM | RESOLVED |