Complete Technical Paper Content — Timeline Analysis Tool For Digital Forensics Investigations
Overview & System Context
Timeline Analysis Tool For Digital Forensics Investigations: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9507 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Digital forensics (sometimes known as digital forensic science) is a branch of forensic science encompassing the recovery, investigation, examination, and analysis of material found in digital devices, often in relation to mobile devices and computer crime. The term "digital forensics" was originally used as a synonym for computer forensics but has been expanded to cover investigation of all devices capable of storing digital data. With roots in the personal computing revolution of the late 1970s and early 1980s, the discipline evolved in a haphazard manner during the 1990s, and it was not until the early 21st century that national policies emerged. Digital forensics investigations have a variety of applications. The most common is to support or refute a hypothesis before criminal or civil courts. Criminal cases involve the alleged breaking of laws that are defined by legislation and enforced by the police and prosecuted by the state, such as murder, theft, and assault against the person. Civil cases, on the other hand, deal with protecting the rights and property of individuals (often associated with family disputes), but may also be concerned with contractual disputes between commercial entities where a form of digital forensics referred to as electronic discovery (ediscovery) may be involved. Forensics may also feature in the private sector, such as during internal corporate investigations or intrusion investigations (a special probe into the nature and extent of an unauthorized network intrusion). The technical aspect of an investigation is divided into several sub-branches related to the type of digital devices involved: computer forensics, network forensics, forensic data analysis, and mobile device forensics. The typical forensic process encompasses the seizure, forensic imaging (acquisition), and analysis of digital media, followed with the production of a report of the collected evidence. As well as identifying direct evidence of a crime, digital forensics can be used to attribute evidence to specific suspects, confirm alibis or statements, determine intent, identify sources (for example, in copyright cases), or authenticate documents. Investigations are much broader in scope than other areas of forensic analysis (where the usual aim is to provide answers to a series of simpler questions), often involving complex time-lines or hypotheses.
Seizing, preserving, and analyzing evidence stored on a computer is the greatest forensic challenge facing law enforcement in the 1990s. Although most forensic tests, such as fingerprinting and DNA testing, are performed by specially trained experts the task of collecting and analyzing computer evidence is often assigned to patrol officers and detectives. Through cyberspace, enemies will target industry, academia, government, as well as the military in the air, land, maritime, and space domains. In much the same way that airpower transformed the battlefield of World War II, cyberspace has fractured the physical barriers that shield a nation from attacks on its commerce and communication. The field of digital forensics still faces unresolved issues. A 2009 paper, "Digital Forensic Research: The Good, the Bad and the Unaddressed" by Peterson and Shenoi, identified a bias towards Windows operating systems in digital forensics research. In 2010, Simson Garfinkel identified issues facing digital investigations in the future, including the increasing size of digital media, the wide availability of encryption to consumers, a growing variety of operating systems and file formats, an increasing number of individuals owning multiple devices, and legal limitations on investigators. The paper also identified continued training issues, as well as the prohibitively high cost of entering the field. Additionally, since 2024 there has been an integration of Artificial Intelligence (AI) and Machine Learning (ML) which has poised to amplify the efficiency as well as the precision behind digital forensics investigations During the 1980s, very few specialized digital forensic tools existed. Consequently, investigators often performed live analysis on media, examining computers from within the operating system using existing sysadmin tools to extract evidence. This practice carried the risk of modifying data on the disk, either inadvertently or otherwise, which led to claims of evidence tampering. A number of tools were created during the early 1990s to address the problem. The need for such software was first recognized in 1989 at the Federal Law Enforcement Training Center, resulting in the creation of IMDUMP (by Michael White) and in 1990, SafeBack (developed by Sydex). Similar software was developed in other countries; DIBS (a hardware and software solution) was released commercially in the UK in 1991, and Rob McKemmish released Fixed Disk Image free to Australian law enforcement. These tools allowed examiners to create an exact copy of a piece of digital media to work on, leaving the original disk intact for verification. By the end of the 1990s, as demand for digital evidence grew, more advanced commercial tools such as EnCase and FTK were developed, allowing analysts to examine copies of media without using any live forensics. More recently, a trend towards "live memory forensics" has grown, resulting in the availability of tools such as WindowsSCOPE. More recently, the same progression of tool development has occurred for mobile devices; initially investigators accessed data directly on the device, but soon specialist tools such as XRY or Radio Tactics Aceso appeared.
Police forces have begun implementing risk-based triage systems to manage the overwhelming demand for digital forensic services. Figure 1: What is Timeline Analysis in Digital Forensics Investigation? acquisition or imaging of exhibits, analysis, and reporting. Acquisition does not normally involve capturing an image of the computer's volatile memory (RAM) unless this is done as part of an incident response investigation. Typically the task involves creating an exact sector level duplicate (or "forensic duplicate") of the media, often using a write blocking device to prevent modification of the original. However, the growth in size of storage media and developments such as cloud computing have led to more use of 'live' acquisitions whereby a 'logical' copy of the data is acquired rather than a complete image of the physical storage device. Both acquired image (or logical copy) and original media/data are hashed (using an algorithm such as SHA-1 or MD5) and the values compared to verify the copy is accurate. An alternative (and patented) approach (that has been dubbed 'hybrid forensics' or 'distributed forensics') combines digital forensics and ediscovery processes. This approach has been embodied in a commercial tool called ISEEK that was presented together with test results at a conference in 2017.
During the analysis phase an investigator recovers evidence material using a number of different methodologies and tools. In evidence related to the suspected crime." In 2006, forensics researcher Brian Carrier described an "intuitive procedure" in which obvious evidence is first identified and then "exhaustive searches are conducted to start filling in the holes." The actual process of analysis can vary between investigations, but common methodologies include conducting keyword searches across the digital media (within files as well as unallocated and slack space), recovering deleted files and extraction of registry information (for example to list user accounts, or attached USB devices). The evidence recovered is analyzed to reconstruct events or actions and to reach conclusions, work that can often be performed by less specialized staff. When an investigation is complete the data is presented, usually in the form of a written report, in lay persons' terms.
Digital forensics is commonly used in both criminal law and private investigation. Traditionally it has been associated with criminal law, where evidence is collected to support or oppose a hypothesis before the courts. As with other areas of forensics this is often a part of a wider investigation spanning a number of disciplines. In some cases, the collected evidence is used as a form of intelligence gathering, used for other purposes than court proceedings (for example to locate, identify or halt other crimes). As a result, intelligence gathering is sometimes held to a less strict forensic standard. In civil litigation or corporate matters, digital forensics forms part of the electronic discovery (or eDiscovery) process. Forensic procedures are similar to those used in criminal investigations, often with different legal requirements and limitations. Outside of the courts digital forensics can form a part of internal corporate investigations. A common example might be following unauthorized network intrusion. A specialist forensic examination, into the nature and extent of the attack, is performed as a damage limitation exercise, both to establish the extent of any intrusion and in an attempt to identify the attacker. Such attacks were commonly conducted over phone lines during the 1980s, but in the modern era are usually propagated over the Internet. The main focus of digital forensics investigations is to recover objective evidence of a criminal activity (termed actus reus in legal parlance).
However, the diverse range of data held in digital devices can help with other areas of inquiry. Attribution Meta data and other logs can be used to attribute actions to an individual. For example, personal documents on a computer drive might identify its owner. Alibis and statements Information provided by those involved can be cross checked with digital evidence. For example, during the investigation into the Soham murders the offender's alibi was disproved when mobile phone records of the person he claimed to be with showed she was out of town at the time. Intent As well as finding objective evidence of a crime being committed, investigations can also be used to prove the intent (known by the legal term mens rea). For example, the Internet history of convicted killer Neil Entwistle included references to a site discussing How to kill people. Evaluation of source File artifacts and meta-data can be used to identify the origin of a particular piece of data; for example, older versions of Microsoft Word embedded a Global Unique Identifier into files which identified the computer it had been created on. Proving whether a file was produced on the digital device being examined or obtained from elsewhere (e.g., the Internet) can be very important. Document authentication Related to "Evaluation of source," meta data associated with digital documents can be easily modified (for example, by changing the computer clock you can affect the creation date of a file). Document authentication relates to detecting and identifying falsification of such details.
When used in a court of law, digital evidence falls under the same legal guidelines as other forms of evidence, as courts do not usually require more stringent guidelines. In the United States, the Federal Rules of Evidence are used to evaluate the admissibility of digital evidence. The United Kingdom PACE and Civil Evidence acts have similar guidelines and many other countries have their own laws. US federal laws restrict seizures to items with only obvious evidential value. This is acknowledged as not always being possible to establish with digital media prior to an examination. Laws dealing with digital evidence are concerned with two issues: Figure 2: What is Timeline Analysis in Digital Forensics Investigation? Integrity - it's ensuring that the act of seizing and acquiring digital media does not modify the evidence (either the original or the copy). Authenticity - refers to the ability to confirm the integrity of information; for example that the imaged media matches the original evidence. The ease with which digital media can be modified means that documenting the chain of custody from the crime scene, through analysis and, ultimately, to the court, (a form of audit trail) is important to establish the authenticity of evidence. Attorneys have argued that because digital evidence can theoretically be altered it undermines the reliability of the evidence. US judges are beginning to reject this theory, in the case US v. Bonallo the court ruled that "the fact that it is possible to alter data contained in a computer is plainly insufficient to establish untrustworthiness." In the United Kingdom, guidelines such as those issued by ACPO are followed to help document the authenticity and integrity of evidence. Digital investigators, particularly in criminal investigations, have to ensure that conclusions are based upon factual evidence and their own expert knowledge. In the US, for example, Federal Rules of Evidence state that a qualified expert may testify "in the form of an opinion or otherwise" so long as: (1) the testimony is based upon sufficient facts or data, (2) the testimony is the product of reliable principles and methods, and (3) the witness has applied the principles and methods reliably to the facts of the case. The sub-branches of digital forensics may each have their own specific guidelines for the conduct of investigations and the handling of evidence. For example, mobile phones may be required to be placed in a Faraday shield during seizure or acquisition to prevent further radio traffic to the device. In the UK forensic examination of computers in criminal matters is subject to ACPO guidelines. There are also international approaches to providing guidance on how to handle electronic evidence. The "Electronic Evidence Guide" by the Council of Europe offers a framework for law enforcement and judicial authorities in countries who seek to set up or enhance their own guidelines for the identification and handling of electronic evidence.
The goal of computer forensics is to explain the current state of a digital artifact; such as a computer system, storage medium or electronic document. The discipline usually covers computers, embedded systems (digital devices with rudimentary computing power and onboard memory) and static memory (such as USB pen drives). Computer forensics can deal with a broad range of information; from logs (such as internet history) through to the actual files on the drive. In 2007, prosecutors used a spreadsheet recovered from the computer of Joseph Edward Duncan to show premeditation and secure the death penalty. Sharon Lopatka's killer was identified in 2006 after email messages from him detailing torture and death fantasies were found on her computer.
Mobile device forensics is a sub-branch of digital forensics relating to recovery of digital evidence or data from a mobile device. It differs from Computer forensics in that a mobile device will have an inbuilt communication system (e.g. GSM) and, usually, proprietary storage mechanisms. Investigations usually focus on simple data such as call data and communications (SMS/Email) rather than in-depth recovery of deleted data. SMS data from a mobile device investigation helped to exonerate Patrick Lumumba in the murder of Meredith Kercher. Mobile devices are also useful for providing location information; either from inbuilt GPS/location tracking or via cell site logs, which track the devices within their range. Such information was used to track down the kidnappers of Thomas Onofri in 2006.
Figure 3: Chronos — Forensic Timeline · PowerForensics Network forensics is concerned with the monitoring and analysis of computer network traffic, both local and WAN/internet, for the purposes of information gathering, evidence collection, or intrusion detection. Traffic is usually intercepted at the packet level, and either stored for later analysis or filtered in real-time. Unlike other areas of digital forensics network data is often volatile and rarely logged, making the discipline often reactionary. In 2000, the FBI lured computer hackers Aleksey Ivanov and Gorshkov to the United States for a fake job interview. By monitoring network traffic from the pair's computers, the FBI identified passwords allowing them to collect evidence directly from Russian-based computers.
Forensic Data Analysis is a branch of digital forensics. It examines structured data with the aim to discover and analyze patterns of fraudulent activities resulting from financial crime. Database forensics is a branch of digital forensics relating to the forensic study of databases and their metadata. Investigations use database contents, log files and in-RAM data to build a timeline or recover relevant information.
IoT forensics is a branch of Digital forensics that has the goal of identifying and extracting digital information from devices belonging to the Internet of things field, to be used for forensics investigations as potential source of evidence. Digital Forensics + Cyber Forensic + cloud forensic + Mobile Forensic + Computer Forensics Neerav Jindal today February 20, 2026 In digital investigations, understanding what happened is important. However, knowing when it happened is often even more critical. That is where timeline analysis plays a central role.
Timeline analysis in digital forensics helps investigators reconstruct events in chronological order. By organizing system activities, file modifications, log entries, and user actions into a structured timeline, forensic experts can uncover hidden patterns and establish a clear sequence of events. In cybercrime cases, insider threats, fraud investigations, and incident response, timeline reconstruction often becomes the backbone of the entire investigation.
Timeline analysis is the process of collecting and correlating time-based artifacts from digital devices to reconstruct user and system activities. When investigators extract and merge this data, they create a chronological map of events. As a result, they can see exactly how an incident unfolded.
Timeline reconstruction provides clarity in complex investigations. Instead of isolated data points, investigators see a connected story. Moreover, courts often rely on chronological evidence to establish intent and sequence. Therefore, accurate timeline construction strengthens the evidentiary value of digital findings.
Browser history, download records, and cached files often reveal user intent and online activity. Timestamps in emails, chat applications, and messaging platforms help correlate communication with suspicious events. 2. System Architecture & Core Working Principles First, investigators perform a proper forensic acquisition of the device to preserve evidence integrity. Hash verification ensures data authenticity.
Next, forensic tools extract timestamped artifacts from various sources such as disk images, memory dumps, and logs. Different systems use different time formats and time zones. Therefore, investigators normalize timestamps into a consistent format to avoid misinterpretation. After normalization, artifacts from multiple sources are merged into a unified timeline. Correlation helps identify relationships between events.
Because of these issues, investigators must validate timestamps carefully and corroborate findings across multiple artifact sources. Several forensic tools assist in automated timeline generation. These tools collect artifacts and present them in chronological order, making analysis more efficient.
However, tools alone are not enough. An investigator’s analytical skills determine how accurately the story behind the data is reconstructed. Consider a data theft investigation inside an organization. Timeline analysis may reveal: When correlated with CCTV footage or access control logs, this timeline can establish strong evidentiary linkage.
Timeline analysis in digital forensics transforms scattered digital traces into a structured narrative. It allows investigators to move beyond isolated artifacts and understand the complete sequence of events. In modern cyber investigations, reconstructing events step by step is not optional—it is essential. A well-built timeline often becomes the most compelling piece of digital evidence in court.
Forensic science is not just about finding data. It is about telling the story hidden within timestamps. Types of Digital Evidence Every Forensic Student Must Know In the modern digital age, crimes rarely occur without leaving electronic traces. Therefore, digital evidence has become a crucial part of ... Event reconstruction is a technique that examiners can use to attempt to infer past activities by analyzing digital artifacts.
Despite its significance, the field suffers from fragmented research, with studies often focusing narrowly on aspects like timeline creation or tampering detection. This paper addresses the lack of a unified perspective by proposing a comprehensive framework for timeline-based event reconstruction, adapted from traditional forensic science models. We begin by harmonizing existing terminology and presenting a cohesive diagram that clarifies the relationships between key elements of the reconstruction process. Through a comprehensive literature survey, we classify and organize the main challenges, extending the discussion beyond common issues like data volume. Lastly, we highlight recent advancements and propose directions for future research, including specific research gaps. By providing a structured approach, key findings, and a clearer understanding of the underlying challenges, this work aims to strengthen the foundation of digital forensics.
Event reconstruction involves recreating past events by analyzing digital artifacts, allowing examiners to determine system activities and make informed conclusions about what occurred. While traditional forensic science benefits from a well-defined framework summarizing the field ( Ribaux, 2023 ) , event reconstruction in digital forensics is often discussed in fragmented terms focusing on tasks such as super timeline creation ( Guðjónsson, 2010 ; Metz et al., 2024 ) , tampering detection ( Palmbach & Breitinger, 2020 ; Studiawan & Sohel, 2021 ) or environmental peculiarities ( Schatz et al., 2006 ) . As a result, research has centered on these narrow aspects, leaving broader challenges underexplored or overlooked. The absence of a unified perspective has led to a proliferation of terms, making it difficult to discuss event reconstruction comprehensively or find relevant research, e.g., some studies use the term artifact ( Harichandran et al., 2016 ) , others refer to observable facets ( Jaquet-Chiffelle & Casey, 2021 ) . Terms such as events ( Carrier & Spafford, 2004a ) , user actions, interactions, or clicks ( Neasbitt et al., 2014 ) are inconsistently used in literature.
The three contributions: First, the article discusses concepts and definitions in timeline-based event reconstruction and integrates them into a new visual model (the timeline-based event reconstruction model or TER-Model ), divided into four quadrants, integrating digital forensic timeline-based terminology and Ribaux (2014) model. Second, with this delineation, we provide a thorough discussion of the issues associated with timeline-based event reconstruction. These issues can be used to evaluate event reconstructions and identify areas of uncertainty in the results. They can also be used to systematically identify weaknesses in the timeline generation and analysis techniques and contribute to a knowledge base of such weaknesses such as SOLVE-IT ( Hargreaves et al., 2025 ) . Third, we provide future research directions needed within each quadrant of the event reconstruction process. This paper is predominantly theoretical, aiming to harmonize timeline-based event reconstruction terminology, however, a practical illustration of the use of the model is available online 1 1 1 https://github.com/chrishargreaves/TER-model-example .
Not in scope: The identification of relevant devices (computer profiling, Marrington et al. (2007) ), legal constraints or ethical issues ( Losavio et al., 2015 ) , technical challenges such as encryption, sophistication of crime ( Karie & Venter, 2015 ) , or very general challenges, e.g., that “results must be reproducible and verifiable” ( Soltani & Seno, 2019 ) . Outline: The next section summarizes core works in event reconstruction which served as a foundation for this work.
Subsequently, Sec. 3 presents terms and technology in existing literature and outlines the terminology used in this article. A contribution of this work is the TER-model which is developed and described in Sec. 4 . Using the model, we identified challenges according to the methodology in Sec. 5 and organized the challenges for event reconstruction in the two main sections: 6 Challenges stemming from environmental and process-related factors and 7 Challenges stemming from deliberate interference , which are summarized as key findings in Sec. 8 . Considering these, Sec. 9 provides a discussion and identifies specific research gaps. The final section concludes the paper.
Lee et al. (2001) and many others have discussed event reconstruction for physical crime scenes. Carrier & Spafford (2004a) ; Carrier & Spafford (2004b) were the first to define it as applied in digital forensics and presented an event-based investigation framework. Their work defines the basic terminology and introduces a formal process model that mirrors physical crime scene investigations but is tailored to the unique aspects of digital evidence. We borrow from this work as discussed in Sec. 3.1 .
Casey (2011) ’s work includes the practicalities of linking evidence to behaviors and motives. Casey emphasizes three core analysis types: (1) temporal which helps establish the timeline of events (the focus of this article), (2) relational which explores the connections between objects, people, and locations, clarifying how different elements of the crime are related, and (3) functional which assesses what was possible or impossible, such as determining how a system or tool was used in the crime.
Chabot et al. (2015a) defines terminology based on existing works, outlines challenges, and evaluates existing approaches. However, the authors limit their challenges to the volume of data and data heterogeneity where this article provides a broader discussion. Our work complements these existing works by providing a new visual model and a thorough discussion of challenges and future research.
According to Neale (2023) , there is a lack of harmonization in terms and definitions. This section briefly revisits (Sec. 3.1 ) and then highlights the terminology we use for this article (Sec. 3.2 ). Carrier & Spafford (2004a) define an event “as an occurrence that changes the state of one or more objects”. Over time, researchers suggested to differentiate between low-level and high-level events (human-understandable) ( Hargreaves & Patterson, 2012 ; Vanini et al., 2024b ) or introduced terms such as ‘activity’ ( Marrington et al., 2007 ) or ‘user-browser interaction’ and ‘click’ which are used interchangeably by Neasbitt et al. (2014) . Chabot et al. (2014) defines an event as “a single action occurring at a given time and lasting a certain duration”.
Jaquet-Chiffelle & Casey (2021) define an event as “a complete collection of related things that have happened (or are happening) in a World within a specific closed interval of time. […] The Event can be considered as a whole entity or as a collection of smaller sub-events”. Notably, their framework emphasizes the role of traces and introduces several key concepts, including trace, facet, and observable facet. While these terms are well-established in forensic science ( Ribaux, 2023 ) , they are less common in digital forensics. Therefore, we adopt a different terminology, while drawing conceptual links to their work.
Similarly, the term artifact is used with different meanings. For instance, Harichandran et al. (2016) compares various definitions and concludes properties an artifact should have such as “artificiality/external force, antecedent temporal relation, and exceptionality”. Horsman (2019) suggests “a digital object containing data which may describe the past, present or future use or function of a piece of software, application or device for which it is attributable to”. Casey et al. (2022) differentiates between atomic artifacts (“a singular unit of interpretable data that can be extracted from a given data source”) and dependable artifacts (“one or more atomic artifacts needed to expose the atomic artifact of interest”). Lyle et al. (2022) extends the atomic artifact definition by adding “…that is useful for addressing questions in forensic investigations”, but assessing usefulness is difficult, subjective and may change over time.
An environment/system is a computational setting or a software/hardware system that reacts to events such as user actions, API calls, or sensor inputs. Typically, it is one or more devices such as computers or smartphones but it could also be a virtual machine, network device, or cloud environment. For readability, the remainder of this paper uses the term environments instead of environments/systems. Note we use the plural, i.e., environments, considering that changes may be in one or more environments, locally, remotely, or both.
This article uses Casey et al. (2022) atomic artifact definition: a singular unit of interpretable data that can be extracted from a given data source. For simplicity, we will only say artifact throughout the paper. Examples include log files, registry keys, timestamps, or network traffic data. 3. Software Implementation, Frameworks & Protocols Based on Jaquet-Chiffelle & Casey (2021) , an event is “a complete collection of related things that have happened (or are happening) in a World within a specific closed interval of time.” These can be treated as a singular entity or decomposed into smaller sub-events and cause environmental changes. This broad definition provides the flexibility for an event to be at the resolution of: ‘file was accessed’, or ‘Google search was performed’, or ‘user account was used to run a program’ (consisting of at least two events: user logged in and user executed binary). Events can be triggered internally, e.g., a cron job, or externally, e.g., someone clicking the mouse. Note that the distinction between event and sub-event is blurred and it is up to the user to define the granularity. For instance, an event is sending an email with sub-events such as opening the email client, typing, establishing a connection to the SMTP server, and sending the message, or an event is establishing a connection to the SMTP server with sub-events such as performing a DNS lookup, initiating a handshake, and authenticating the user credentials.
This work draws inspiration from Vanini et al. (2023) , which, in turn, is influenced by the work of Ribaux (2023, p226, Fig. 4.4) 2 2 2 Note, this is an updated version from the previous work by Ribaux (2014) and thus has over a decade of history. . We adjusted these models to align with standard digital forensics terminology and emphasize timeline-based event reconstruction. Our model, named TER-Model (timeline-based event reconstruction), is depicted in Fig. 1 and can be separated into a reality space (Sec. 4.2 ) and a reconstruction space (Sec. 4.3 ). Each of these spaces can be further separated resulting in four quadrants (Q1-Q4). Before describing the model, this section first summarizes the goals of temporal event reconstruction which influenced the TER-Model. The summary of systematization of knowledge (SoK) in the TER-Model is shown in Table 1 .
Temporal event reconstruction aims to accurately recreate the sequence of events that occurred which includes finding gaps and inconsistencies, even if they cannot be accurately filled or corrected. Thus, it enables investigators to draw meaningful conclusions about what transpired. Event reconstruction involves several interrelated analytical processes that together provide a coherent and defensible narrative of what transpired. At its core is temporal sequencing and correlation, where a precise order of events is created. It may be necessary to analyze their relationships across different timelines to uncover causal links, sequence dependencies, or concurrent activities ( Adderley & Peterson, 2020 ) . Beyond simple chronology, contextual analysis places these events within a broader framework, considering factors such as user behavior, system settings, or external influences to give the data deeper interpretive meaning ( Chabot et al., 2015a ) . This groundwork supports hypothesis testing and scenario building, where investigators construct and refine possible explanations for what occurred, evaluating multiple narratives and ruling out those that conflict with the evidence ( Willassen, 2008a ; Willassen, 2008b ; Batten et al., 2012 ) . It is crucial that the reconstructed timelines are confirmed through correlation and verification of evidence to ensure consistency and reliability.
The goal is to produce a report to support legal proceedings that not only stands up to technical scrutiny, but also serves court proceedings by providing a clear, accurate and accessible story for stakeholders such as lawyers or jurors ( Chabot et al., 2014 ; Xu & Xu, 2022 ) . This quadrant is an interval that has a start time t S t_{S} and an end time t E t_{E} , i.e., T = [ t S , t E ] T=[t_{S},t_{E}] during which the event ( E E ) and sub-events ( e 1 , e 2 , … I e m e_{1},e_{2},...e_{m} ) occurred. Each E E or e e causes multiple environmental changes, e.g., new log entries, modified registry values, files marked as non-allocated, or updated timestamps.
The event (E) is what we wish to be able to say something about through the event reconstruction process. Carrier (2006) describes that an event can be any “an occurrence that changes the state of the system” and Hargreaves (2009) continues that “digital events occur on a system often as a result of interactions with another digital device, or as a result of interactions with the real world”. However, in Jaquet-Chiffelle & Casey (2021) event is formalized such that these external triggers are integrated into the event itself, defining an event that can capture the very broad, or the very detailed. In addition, there are concurrent events such as antivirus scanning files resulting in changes not tied to the primary event.
During this interval ∆ \Delta , the environment changes caused by E E may become intermingled with, altered, or overwritten by an ensemble of other data generated by unrelated subsequent events . Jaquet-Chiffelle & Casey (2021) categorized these changes as adjunction, suppression, and change. This second interval ends at time t P t_{P} when the data is preserved/extracted, i.e., ∆ = ( t E , t P ] \Delta=(t_{E},t_{P}] . As t E t_{E} belongs to T T , we exclude it here from this interval using a half-open interval. It is important to note that not all environment changes can be extracted, such as missing/deleted files or new artifacts without a parser. These gaps may stem from many causes, for example a lack of knowledge in digital forensics, a tool setup, or errors in the timeline generation process. Hence, what can be extracted is named extractable artifact , which is therefore context specific.
Combined with preservation and acquisition, timeline generation bridges the Reality and Reconstruction spaces. Hargreaves et al. (2024b) define it as a process within a forensic analysis tool for “extracting timestamps from the file system…[and] applying file specific processing and extracting timestamps from within files such as the Windows Registry, log files, SQLite databases etc., that contain timestamps”. This artifact and timestamp extraction is complemented by normalization, which is required since timestamps exist in a variety of formats (e.g., ASCII in a log vs. little-endian hexadecimal in a proprietary format), and resolutions (i.e., hours, minutes, seconds, nanoseconds, etc.) depending on their source ( Raghavan & Saran, 2013 ) . They may also be stored in UTC or local time. Ideally, after normalization, all timestamps should be presented in the same format for better readability and sortability.
The lower section of the diagram represents how examiners attempt to reconstruct past events using reasoning and available evidence. This process involves uncertainty, as the past cannot be revisited, making absolute certainty unattainable. Examiners construct a timeline to facilitate analysis, and the DFPulse 2024 Practitioner Survey ( Hargreaves et al., 2024a ) reports 80.3% are using timelines ‘often’ or ‘almost always’. Timelines are composed of a series of entries, each derived from individual artifacts that are arranged chronologically. Artifacts may originate from multiple independent data sources, e.g., a computer and a smartwatch. While specific implementations store multiple data points per event, fundamentally these timeline entries are defined as a 3-tuple ( t , S , C ) (t,S,C) : A source S S refers to the specific location from which the timestamp and context originate, such as the Master File Table (MFT), Windows registry, EPROCESS block in memory, or Chrome browser history file. For clarity, S S should be as detailed as possible; instead of stating the registry, the exact registry key path should be specified.
A context C C defines what the timestamp represents, such as the modification timestamp within the Standard Information Attribute (SIA) of MFT entry, or a value in a specific row or field within a database. Given the wide variety of contexts, a generic term is used to encompass the diverse nature of these representations. These timeline entries should not be conflated with events themselves or ‘low-level events’ ( Hargreaves & Patterson, 2012 ) .
The context provided by each entry, such as a value in a ‘modified’ or ‘last change’ field within a file system structure, does not inherently represent a specific event, such as a file modification. Instead, it reflects environmental behavior that must be understood before making any assumptions about what event occurred. This distinction is critical: while timeline entries provide the raw data needed for event reconstruction, they are not events in and of themselves. Rather, they are normalized, sorted compilations of data that result from parsing artifacts left by events. Therefore, we argue that the term event should be reserved for the inferred actions, while the term timeline entry more accurately describes the data points that examiners use to reach those inferences.
Timeline analysis bridges Q3 and Q4, and describes the process of moving from having a timeline to reconstructing events, which uses refinement techniques such as: filtering irrelevant entries, highlighting key entries, or aggregating entries into more meaningful events ( Hargreaves & Patterson, 2012 ) . Several other concepts have been discussed such as event abstraction ( Studiawan et al., 2020a ; Studiawan, 2023 ) , the application of machine learning ( Khan & Wakeman, 2006 ) , or visualization ( Berggren et al., 2024 ; Debinski et al., 2019 ) . Timeline analysis also draws in examiner knowledge to understand potential events that are capable of producing the timeline entries and integrating them into a reasoning process ( Gladyshev & Patel, 2004 ) .
To accurately approach event reconstruction, it is essential to distinguish between the event E E that occurred in reality and the inferred event E ′ E^{\prime} which is derived from the analysis of timeline entries. In the context of hypothesis generation, E ′ E^{\prime} represents the best approximation based on the available evidence. We define an inferred event E ′ E^{\prime} as a reconstructed scenario that may have occurred within a specific time frame, based on the interpretation and analysis of timeline entries and associated artifacts. This definition acknowledges the uncertainty in reconstructing past events.
Consideration of the timeline entries in the context of examiner knowledge may result in multiple plausible scenarios ( Jaquet-Chiffelle & Casey, 2021 ; Gladyshev & Patel, 2004 ) . Hargreaves (2009) states “if there are multiple events that could cause the same state of digital data, there is an actual, true event that caused it, and one or more other events that did not.” This means that rather than arriving at a single definitive inferred event E ′ E^{\prime} , we may generate k k alternative events, denoted as E j ′ E^{\prime}_{j} where 1 ≤ j ≤ k 1\leq j\leq k . Each E j ′ E^{\prime}_{j} represents a distinct interpretation of the evidence, each of which could potentially explain the observed data. These multiple instances of E ′ E^{\prime} highlight the complexity and ambiguity, where different sequences of events could produce similar artifacts. The process involves not only constructing these alternatives but also systematically and repeatedly testing and eliminating hypotheses to converge on the most likely scenario while acknowledging that multiple interpretations may still be viable based on the available evidence.
To test and eliminate hypotheses, Casey (2020) ’s ‘Strength of evidence scale’ (C-Scale) may be used, and it may involve research into artifact interpretation and experiments to determine if a set of actions could produce the observed system changes. To identify and categorize the challenges in event reconstruction, we followed a structured literature review process designed to balance breadth with relevance. The goal was not to exhaustively capture all existing work but to obtain a representative and insightful overview of the key challenges discussed in the field.
We defined a set of core search terms related to the topic: event reconstruction, timeline, timestamp analysis, digital forensics, correlation, challenges, and problems. These terms were combined using Boolean operators and phrasing variations (e.g., quotation marks for exact matches). Searches were conducted using Google Scholar, which indexes most major academic publishers (e.g., IEEE, ACM, Wiley, Springer) and relevant platforms such as DFRWS.org and arXiv.
For each query, we considered the first two pages of results (i.e., 20 entries). Articles were initially screened based on metadata displayed: title, author(s), publication venue, and two-line extract. If no direct reference to digital forensics was evident, the article was discarded. This filtering yielded a preliminary pool of approximately 200 articles. We extracted mentions of challenges primarily from the abstract and introduction sections, where such content is frequently summarized. Targeted keyword searches (e.g., challenge, problem, limitation) were also used within full texts to uncover implicit references.
The identified challenges were then mapped onto a diagram, categorizing them according to the stage or context in which they occur within the event reconstruction process. We also incorporated our domain expertise to address gaps in the literature, recognizing that some relevant challenges may not have been explicitly highlighted in existing works.
The article collection and analysis were conducted manually, which may have led to the omission or misclassification of relevant articles. By restricting searches to Google Scholar and considering only the first two pages of results, important sources further down the list or from other databases may have been excluded. The focus on abstracts and introductions might have caused us to overlook challenges discussed deeper within the papers. Moreover, the subjective nature of challenge classification introduces potential bias based on the researchers’ interpretations. Finally, the absence of automated or statistical tools for extraction and categorization limits the objectivity and comprehensiveness of the analysis. Despite these limitations, we believe the following sections offer a comprehensive and nuanced overview of the challenges.
This section focuses on unintentional challenges and the structure follows the diagram’s flow, discussing each quadrant. 4. Practical Deployment, Analysis & Case Studies Note, that while we have strived to define the challenge categories as distinctly as possible, some overlap is inevitable due to the interconnected nature of these activities. Certain actions may reasonably fall into multiple categories, depending on the context. The categorization is designed to provide guidance rather than enforce strict mutual exclusivity.
Clock-related challenges originate from the system time which is used to derive timestamps. If the clock is incorrect, all timestamps originating from this clock are incorrect ( Stevens, 2004 ; Raghavan & Saran, 2013 ; Vanini et al., 2024b ) . Skew refers to the difference in time readings between different systems. One reason for clock skew could be propagation delays which may occur due to network delays ( Schatz et al., 2006 ; Henderson, 2009 ) or due to synchronization problems, e.g., NTP servers providing incorrect times ( Buchholz & Tjaden, 2007 ; Hampton & Baig, 2016 ) .
Drift is the gradual deviation of a clock from the correct time, often caused by factors such as changes in temperature, voltage fluctuations, or inherent defects in the clock circuitry ( Sandvik & Årnes, 2018 ) . Clock drift may exacerbate over time. As drift accumulates, the discrepancies between different systems’ clocks can grow, making it increasingly difficult to correlate events across environments ( Becker et al., 2008 ) .
As systems traverse different time zones, whether due to travel or daylight-saving time changes, the system time may change ( Stevens, 2004 ) . This adjustment process can also be error-prone, e.g., due to an inaccurate time zone database ( Kaart & Laraghy, 2014 ) . Compared to skew and drift, the range is significantly larger, i.e., hours instead of seconds. Typically this is only relevant where local time is stored in a data structure rather than storing UTC.
Note that virtual environments come with their challenges which are beyond the scope of this article but have been discussed in VMware (2008) . Environments, systems, and application configurations define how/what data is generated, stored, and logged. These configurations comprise a wide range of settings, including logging levels, storage policies, network settings, and security controls.
Conservative default settings can result in insufficient logging, leading to missing artifacts, e.g., database logs prioritizing space efficiency over detail ( Adedayo & Olivier, 2015 ) . Systems may also be configured to suppress artifacts, such as private browsing ( Fernández-Fuentes et al., 2022 ) , or delete them, such as printer jobs removed after completion ( Gladyshev & Patel, 2004 ) or when an application is closed.
Different resolutions lead to inconsistencies, e.g., timestamps recorded in hh:mm vs. hh:mm:ss format ( Song et al., 2016 ) . File systems, drivers, and implementations may behave differently leading to unpredictable behavior ( Bang et al., 2009 ; Nordvik & Axelsson, 2022 ) . Environments may not behave as expected leading to the destructing of evidence or the not-creation of artifacts: A crash (system, application) can result in the loss or corruption of artifacts, potentially leaving logs incomplete and missing key events ( Studiawan et al., 2019 ; Oh et al., 2022 ) . Detecting crashes can be challenging, particularly if the logging mechanisms themselves are compromised during the crash. Crashes may also lead to restart anomalies such as services or applications that are supposed to start automatically failing to do so potentially altering the way subsequent events are logged.
Bugs in software may cause errors in data logging, such as incorrect timestamps or missing events ( Marrington et al., 2011 ) . Environments under heavy load may fail to log events properly due to resource constraints, leading to delayed or missed entries in the event data. Failures, including hardware malfunctions, can lead to inadequate data ( Marrington et al., 2011 ) . Volatile data, such as RAM content or network traffic, is lost if the ∆ \Delta is too large. In addition, IoT devices often have resource constraints resulting in short-lived data ( Sandvik et al., 2021 ) . In cloud environments, VMs can be easily deleted including their logs ( Marangos et al., 2016 ) .
The changes resulting from an event may be distributed across multiple locations, including cloud environments, resulting in fragmented evidence that is challenging to collect and analyze ( Group et al., 2014 ; Joseph & Singh, 2019 ; Manral et al., 2019 ) . Even with the cooperation of external service providers, data cannot be recovered, particularly when logging is explicitly disabled, as is often the case with many VPN services.
This period relates to the influence of time on the changes left behind after an event. Over time the changes generated by the primary event are altered by subsequent events (referred to as intrinsic events by Jaquet-Chiffelle & Casey (2021) , or evidence dynamics by Gruber et al. (2023) ). Initial changes may disappear due to subsequent events. Examples are rotating logs ( Sandvik et al., 2021 ) , temporary files, routine cleanup tasks, or reboots.
Subsequent events can modify or replace existing data. For instance, Khan et al. (2007) mention that much of the application footprint is rewritten each time the application runs. Routine file operations, such as automatic backups or updates, may also overwrite metadata, configurations, or timestamps ( Soltani et al., 2019 ) . Digital artifacts and physical devices are susceptible to degradation, affecting their reliability and accessibility. This degradation can manifest as file corruption, obsolescence of file types, or the deterioration of storage media. Furthermore, changes in software, file formats, or logging systems can introduce additional challenges. As schemas evolve, inconsistencies in log formats may emerge, complicating the process of reconciling older and newer data entries. Backward compatibility issues also arise when outdated systems or logs are incompatible with modern tools, requiring extra effort to ensure that historical data remains interpretable and consistent across different versions ( Schuster, 2007 ) .
This third quadrant summarizes all timeline-related challenges. We decided to include the trans-boundary boxes, i.e., timeline generation (Q2-Q3) and timeline analysis (Q3-Q4), in this section as we think they are closer related to the timeline. Data comes from various systems, including traditional computing environments and a growing number of IoT devices, each with distinct structures, conventions, and formats ( Patterson & Hargreaves, 2012 ; Mohammed et al., 2016 ) . This increasing heterogeneity of both data sources and devices causes several challenges.
Extracting data presents an ongoing challenge, as tools must be continuously updated to accommodate new and evolving software ( Horsman, 2019 ) . The acquisition process can introduce alterations, particularly when conducted on live systems, such as during memory dumps ( Soltani & Seno, 2017 ; Gruber et al., 2023 ) . This involves converting diverse data types, such as logs, databases, and sensor outputs, into a standardized structure that enables comprehensive analysis ( Han et al., 2020 ) . This can be challenging due to different timestamp formats, timestamp resolutions, and timezone settings. Timestamp formats can also change over time, meaning timestamp normalization needs to be updated over time and handle older and newer formats.
Evidence might be unintentionally modified during collection or handling, e.g., failing to use a write blocker ( Gruber et al., 2023 ) or corrupt software, leading to data contamination. Similarly, lapses in maintaining a proper chain of custody can result in evidence being mishandled, misplaced, or questioned in terms of authenticity and reliability. 5. Performance Evaluation & Extended Technical Observations Combining data from multiple sources to create a unified perception is challenging, especially when sources have different levels of reliability or granularity ( Gómez et al., 2005 ; Levett et al., 2010 ) .
Balancing automated tools with manual analysis is essential yet challenging. While automation expedites the process, it may overlook nuances that a human analyst would catch ( Kälber et al., 2013 ) and can introduce various types of error ( Hargreaves et al., 2024b ) . Incorrect settings or carelessness can lead to incorrect results. For example, errors in the configuration of the tools have been shown to result in inaccurate extractions of digital evidence, which can impact the credibility of the findings ( Bhat et al., 2021 ) . The transition to a new tool may lead to misinterpretation as tools may interpret/visualize data differently. Some features of tools also do not help in reducing chances of investigator misinterpretation (see Hargreaves et al. (2024b) ), e.g., if a tool provides an automated result of a Google search occurring, this is easy to interpret the event occurring as a fact rather than Google search data being present. This is an event reconstruction process, with all the uncertainty that could be present, as discussed in Sec. 6.4 . Tools can conflate facts with interpretation within their interfaces.
Many tools operate as black-boxes making it unclear how artifacts are handled. Transparency of functionality is critical, as proprietary processes can influence assumptions or conclusions, leading to misinterpretation. Tools may have limits on the amount of data they can process or the complexity of queries, leading to unnoticed gaps in analysis, e.g., a tool limited to analyzing 5,000 files at once. Consequently, validation is essential, but challenging, given the rapid change of artifacts ( Horsman, 2018 ; Arshad et al., 2018 ) .
AI-powered tools introduce complexities regarding explainability and transparency, not just of the models but of training data. Recent approaches such as LLMs are also problematic due to their non-deterministic nature and in many cases opaque training data and processes. These tools can produce inaccurate or misleading outputs, such as AI-generated errors or ‘hallucinations’ which can affect the analysis ( Scanlon et al., 2023 ) .
Developers aiming to create tools should consider the seven criteria outlined by Chabot et al. (2015b) , which provide a comprehensive framework for ensuring an efficient reconstruction tool. Q4 involves the generation and testing of hypotheses based on the timeline. This is critical and Hargreaves (2009) goes as far as defining a digital investigation as “a process that formulates and tests hypothesis using digital evidence” with the prior stages facilitating this goal. Some areas of this are explored, e.g., timeline analysis, but others, such as hypothesis forming and testing are less frequently discussed.
Although the processing is mostly done using tools, this section highlights challenges originating from the processing of timeline entries. The extensive amount of information (number of entries in the timeline) makes the analysis time-consuming ( Chabot et al., 2015a ) and overloads examiners. Additionally, significant resources are needed to extract, process, and store this data, including computational power, storage capacity, and advanced data management tools ( Quick & Choo, 2014 ) .
Techniques such as combining related events into cohesive units (sometimes called high-level events or super events) ( Buchholz & Falk, 2005 ; Kiernan & Terzi, 2009 ; Hargreaves & Patterson, 2012 ; Inglot & Liu, 2014 ; Raju et al., 2017 ) can streamline analysis but may result in the loss of granularity or context. Similarly, visualizations ( Osborne & Turnbull, 2009 ) require consideration to ensure that they accurately represent the data without oversimplifying or distorting the information.
The volume of the raw data can be a challenge to visualize and reduction of the data before visualization is meaningful may be necessary, e.g., Hargreaves & Patterson (2012) . The process of establishing meaningful relationships between disparate timelines entries is fraught with difficulties, especially when data originates from various sources or formats ( Schatz et al., 2006 ) or times across environments are not synchronized ( Marangos et al., 2016 ) . Detecting and validating these connections requires experience and meticulous attention ( Amato et al., 2017 ) . For example, incorrect handling of local time vs. UTC can disrupt the sequencing of events, particularly in global systems where data spans multiple time zones ( Buchholz & Tjaden, 2007 ) . Verifying data across different sources and formats is challenging but necessary to ensure the accuracy and completeness of the reconstructed timeline.
Ensuring that data is accurate and trustworthy is fundamental ( Neale et al., 2022 ) . Determining which sources to trust and how to weigh them can significantly affect the reliability of the reconstruction. This challenge becomes even more pronounced when different sources report the same event but provide inconsistent or conflicting details, leading to uncertainty. Investigators work with a static set of data which includes evidence and irrelevant information generated by subsequent activities or during investigative processes ( Roux et al., 2022 ) . Misinterpretation can arise from factors such as incorrect ordering, aggregation, or filtering of entries, leading to distortions in the reconstructed narrative but also from unawareness of an examiner, i.e., insufficient knowledge of an event or timestamp ( Boyd & Forster, 2004 ) .
The presence of anti-forensic tools ( Conlan et al., 2016 ) or tampering indicators, such as manipulated timestamps or hidden data, raises suspicion about the authenticity of the evidence 3 3 3 We decided to include this challenge here and not in Sec. 7 (deliberate interference) as the presence of these tools does not necessarily mean that they were executed. . According to Neale (2023) , detecting and addressing such tampering is crucial to maintaining trust in the evidence (more in Sec. 7 ).
Combining data from external sources, such as cloud services, introduces additional challenges. When the integrity of these sources cannot be independently verified, especially due to possible alterations in transit or at rest, the reliability of the event reconstruction may be compromised ( Battistoni et al., 2016 ) . Investigators may interpret evidence differently based on their prior knowledge, experience, or expectations, which can lead to skewed interpretations of the data. Perception and decision bias may cause certain patterns or details to be overlooked.
Previous knowledge may become outdated due to the release of a new operating system, or new version of an application ( Horsman, 2019 ) . Examiners may be unaware of certain behaviors (e.g., ( Thierry & Müller, 2022 ) identified multiple unexpected and non-compliant behaviors of timestamps). Limitations in knowledge reduce the investigator’s ability to generate viable alternative hypotheses that would produce the same artifacts.
Tools operate based on algorithms that might make certain assumptions or prioritize specific types of data, which can introduce biases into the reconstructed events ( Jinad et al., 2024 ) . For instance, an AI-powered tool may be biased due to unbalanced training data. Analysts may bring their own preconceptions into the analysis, influencing how they interpret and prioritize different events ( Kang et al., 2013 ) . This can lead to confirmation bias, where analysts might favor hypotheses that align with their pre-existing beliefs or expectations, unintentionally skewing the analysis ( Kassin et al., 2013 ) .
Testing hypotheses against a timeline is complex, especially when considering all the aforementioned challenges. Evidence may be open to multiple interpretations, making it difficult to draw definitive conclusions and infer events from the past. This ambiguity can lead to varied interpretations of the same data, which impacts the ability to test hypotheses with certainty. Effective hypothesis testing must address temporal inaccuracies or manage the inherent uncertainty that arises from imperfect data such as log files ( Latzo & Freiling, 2019 ) .
Hargreaves (2009) discusses that error in event reconstruction can be defined as “the difference between the inferred history and the true history of the examined digital evidence”. This error cannot necessarily be expressed as a definite value, e.g., x ± y x\pm y , but can be expressed as uncertainty (possible error) in the inferred events, i.e., alternative possible hypothesized events that explain the current state of the examined digital evidence. Communicating these uncertainties transparently is vital to ensure that conclusions drawn are appropriately qualified and reflect the limitations of the available evidence.
To complement the previous section, this one outlines challenges stemming from deliberate actions such as backdating, erasing, or wiping, to hide activities ( Casey, 2020 ) . While it may not always be the case, for this work we assume that the investigative body and tool vendors are free from insider threats. Therefore, challenges are limited to the reality . As already pointed out in Sec. 6 , some overlap of challenges is inevitable due to the interconnected nature of these activities.
Interference with the environment can be conducted before the event occurs, with the intent to complicate investigations. Such interference often seeks to generate misleading artifacts or prevent their creation altogether, e.g., examples under ‘defence evasion’ in the MITRE ATT&CK Matrix 4 4 4 https://attack.mitre.org/tactics/TA0005/ . Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Digital%20forensics • https://hawkeyeforensic.com/timeline-analysis-in-digital-forensics/ • https://arxiv.org/html/2504.18131
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
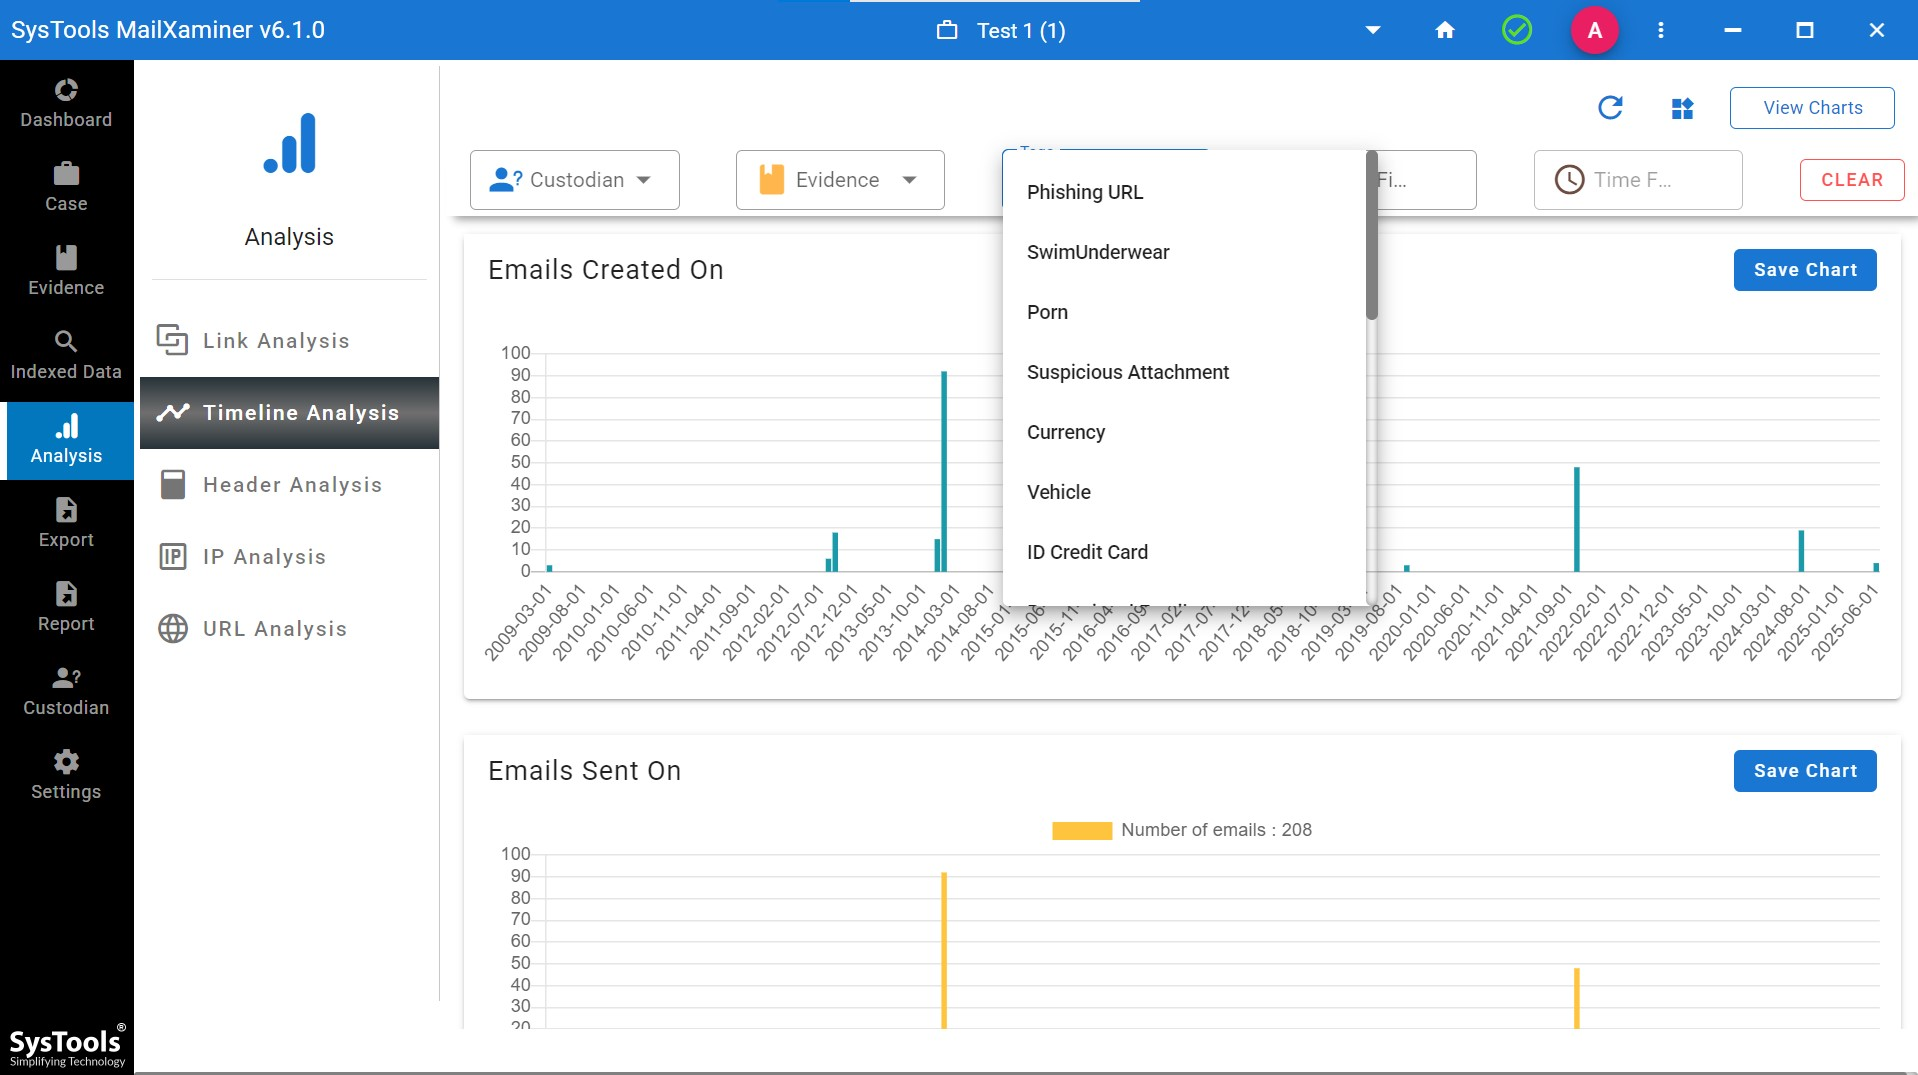
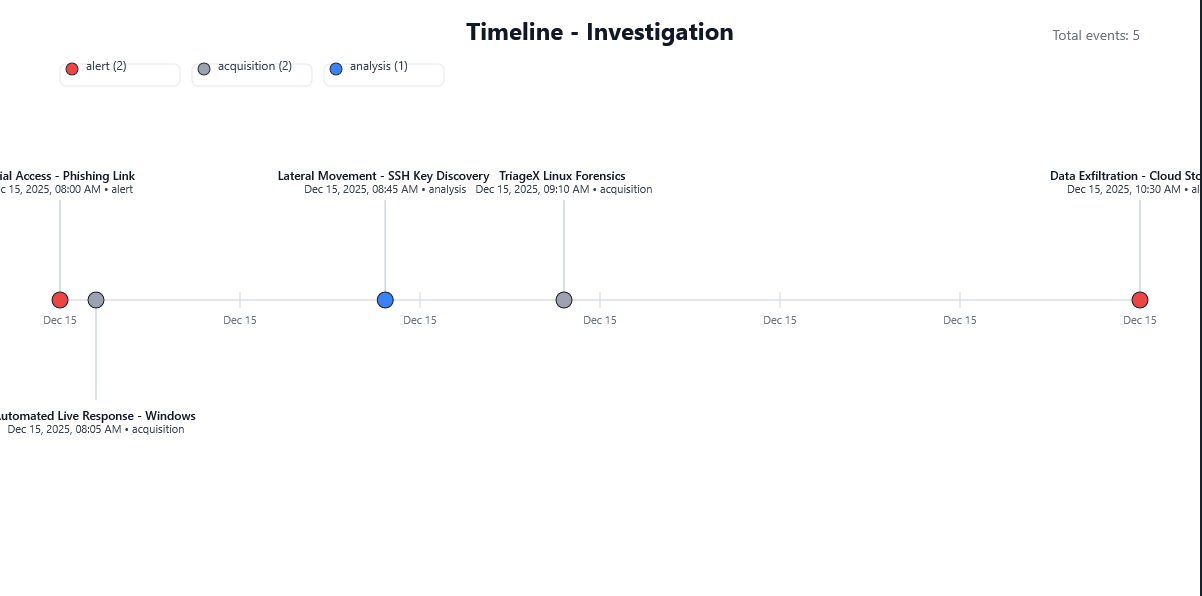
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Timeline Analysis Tool For Digital Forensics Investigations.
[*] Metasploit Scan Running on Target Subnet for Timeline Analysis Tool For Digital Forensics Investigations... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |