Complete Technical Paper Content — Trojan Horse Detection Using Machine Learning Algorithms
Overview & System Context
Trojan Horse Detection Using Machine Learning Algorithms: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~4065 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Incorporating deep learning models like CNNs and RNNs to improve the accuracy and robustness of trojan detection and evaluating the models against real-world data with diverse features can validate their effectiveness.
Step 2: Data Splitting Train-Test Split: Divide the preprocessed data into training and testing sets (typically 80% training, 20% testing) using train_test_split from scikit-learn. Incorporating deep learning models like CNNs and RNNs to improve the accuracy and robustness of trojan detection and evaluating the models against real-world data with diverse features can validate their effectiveness.
A personal machine learning project to detect Trojan horse malware in network traffic using a hybrid approach combining supervised classification and anomaly detection techniques. Figure 1: Scan Open Source AI Models for Security Risks Built and evaluated five different models on a dataset of 177,000+ real network traffic samples, achieving a best result of 73% accuracy and 0.815 ROC-AUC with Random Forest.
Trojan horse malware is one of the most dangerous cybersecurity threats today — it disguises itself as legitimate software while silently stealing data or enabling unauthorised access. Traditional signature-based detection methods struggle to catch evasive or previously unseen variants. This project explores whether supervised machine learning can improve real-time Trojan detection by learning patterns directly from network traffic behaviour — packet sizes, flow duration, communication intervals, flag counts, and more.
Note: The raw CSV file is not uploaded to this repo due to file size (93MB). Download it from Kaggle and place it in the /data folder before running notebooks. Figure 2: GitHub - SSudharsan10/Trojan-Horse-Detection-using-Deep-Learning ... Phase 1 — Baseline: Trained all models on the top 10 features selected via ANOVA F-score to establish baseline performance.
Phase 2 — Refined: Expanded to 12 optimised features after removing constant, non-informative, and high-noise columns. This significantly improved performance across all models. trojan-malware-detection-ml/ notebooks/ 01_EDA_and_Visualisation.ipynb 02_Preprocessing.ipynb 03_Model_Training_and_Evaluation.ipynb data/ README.md reports/ results_summary.md requirements.txt README.md 2. System Architecture & Core Working Principles git clone https://github.com/sudheer_krish/trojan-malware-detection-ml.git cd trojan-malware-detection-ml Sudheer Krishna Reddy Rendla MSc Advanced Computer Science AWS Certified | Kubernetes Certified | Cloud and Data Engineering LinkedIn: https://www.linkedin.com/in/rendla-sudheer-krishna-reddy-32a2b4186/ The risk of hardware Trojans being inserted at various stages of chip production has increased in a zero-trust fabless era. To counter this, various machine learning solutions have been developed for the detection of hardware Trojans. While most of the focus has been on either a statistical or deep learning approach, the limited number of Trojan-infected benchmarks affects the detection accuracy and restricts the possibility of detecting zero-day Trojans. To close the gap, we first employ generative adversarial networks to amplify our data in two alternative representation modalities, a graph and a tabular, ensuring that the dataset is distributed in a representative manner. Further, we propose a multimodal deep learning approach to detect hardware Trojans and evaluate the results from both early fusion and late fusion strategies. We also estimate the uncertainty quantification metrics of each prediction for risk-aware decision-making. The outcomes not only confirms the efficacy of our proposed hardware Trojan detection method but also opens a new door for future studies employing multimodality and uncertainty quantification to address other hardware security challenges.
Hardware Trojans (HT) have been a growing concern in today’s fabless semiconductor manufacturing, as malicious modifications can be made by attackers for a variety of reasons, such as information leakage, incorrect operation, or inflicting damage on the chip [ 1 , 2 , 3 , 4 ] . While comprehensive approaches are vital for countering HTs, they entail certain drawbacks. Formal methods and simulation-based testing can be resource-intensive and time-consuming. Intrusion detection systems may yield false alarms, disrupting operations. Establishing a secure supply chain can limit flexibility in supplier selection.
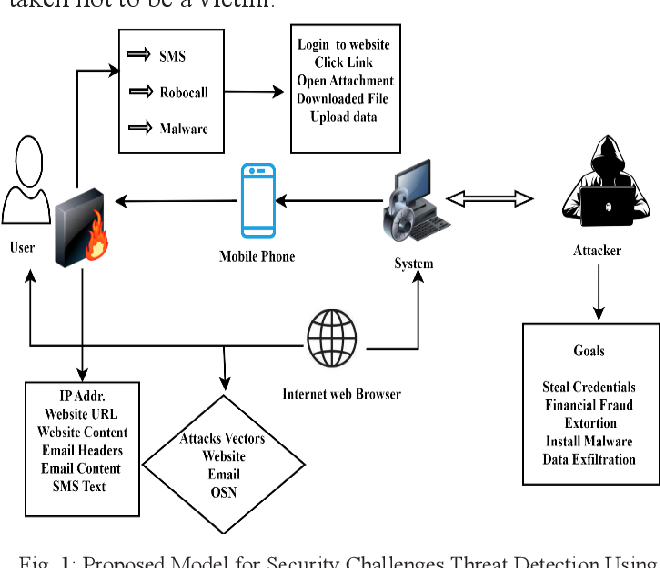
Figure 3: Figure 1 from Leveraging Machine Learning Algorithms for Threat ... Recently, Machine Learning (ML) has emerged as a powerful tool for detecting HTs [ 5 , 6 , 7 , 8 , 9 ] . It leverages algorithms to identify intricate patterns indicative of Trojans, even in increasingly sophisticated attacks. By training on diverse datasets, ML models can classify circuits as Trojan-free or Trojan-infected. Real-time processing enables continuous monitoring and immediate threat response. However, challenges exist, for example, acquiring large and diverse datasets, especially for rare Trojans, which can be difficult. Moreover, models are susceptible to adversarial attacks [ 10 ] , potentially undermining their decision-making. Interpretability [ 11 ] and explainability [ 12 ] are crucial for trust but can be complex in this context.
Additionally, resource-intensive training and deployment may limit accessibility for smaller manufacturers. Continuous retraining is necessary to adapt to evolving Trojan techniques, adding complexity to maintenance. Our goal in this paper is to address the gaps in the current ML-based approaches for identification of HTs by proposing NOODLE , an u N certainty-aware hardware Tr O jan detecti O n using multimo D al deep LE arning. The proposed method uses graph representation and tabular data and performs binary classification.
The emphasis in traditional ML approaches for HT detection has primarily been on modeling techniques. This entails the development and implementation of algorithms aimed at enhancing the overall accuracy of HT detection. Many research papers have concentrated on extracting features from Register Transfer Level (RTL) or gate-level netlists and employing ML models such as Support Vector Machine (SVM) [ 13 ] , Neural Network (NN) [ 14 ] , eXtreme Gradient Boosting (XGB) [ 15 ] , and the Random Forest (RF) classifier [ 16 ] . In [ 17 ] , image classification techniques are also employed.
Multimodal Deep Learning (DL) has been a well-explored topic in the Artificial Intelligence (AI) community. Early research, exemplified by Deep Boltzmann Machines (DBM) focused on the model’s capacity to understand probability distributions across inputs with multiple modes [ 18 ] . Additionally, applications of uncertainty-aware multimodal learning [ 19 ] have been successfully demonstrated in healthcare [ 20 ] and in scenarios involving multimodal task distributions [ 21 ] , particularly in safety-critical environments. In our study, we specifically target the fusion of graph [ 22 , 23 ] and Euclidean data as the modalities of interest along with uncertainty estimation.
Moreover, when working in the hardware security domain, it is expected to have fewer data points that are malicious or Trojan-infected. In this context, it becomes a necessity to work with small data [ 24 ] and the same has been achieved in various domains such as material science [ 25 ] , and also for anomaly detection [ 26 ] . In this paper, we investigate the feasibility of applying a multimodal ML approach for HT identification by deriving two data representations of circuits. The first is graphical representation [ 27 ] of circuits, and the second is euclidean data [ 28 ] derived by processing the Abstract Syntax Tree (AST) of the RTL files (Verilog). Although the use of multimodal approaches for improved model accuracy has been used in other domains, we do not see any application in Trojan identification. For uncertainty-aware multimodal learning, we believe the logic should be implemented at the information fusion level of the modalities, and for this, we leverage the p p -values aggregation with conformal prediction. Our main contributions are as follows: Proposing a multimodal learning approach using graph and euclidean data of the hardware circuits. To the best of our knowledge, this study is the first to investigate and implement a multimodal approach for HT detection.
3. Software Implementation, Frameworks & Protocols Suggesting a model fusion approach using p p -values with uncertainty quantifier. By employing p p -values as a statistical measure, we can systematically assess the significance of each modality’s contribution to the overall prediction. This not only enhances the interpretability of the fusion process but also enables more robust decision-making.
We address the challenges of missing modalities and solve the issue of handling imbalanced and small dataset by leveraging generative adversarial networks. Multimodal learning [ 29 ] addresses complex problems by integrating information from multiple modalities, such as text, images, and audio, to obtain a comprehensive understanding of a given phenomenon. In our case, we used graphical data and tabular representations of the source circuits. This approach enables models to capture nuanced relationships that may be overlooked when considering each modality in isolation. The fusion of information from different sources empowers the model to make more accurate and robust predictions.
From a mathematical perspective, multimodal learning involves the integration of data representations into a unified framework. Let X 1 , X 2 , … , X M X_{1},X_{2},...,X_{M} represent M M different modalities of data, each with their respective feature spaces I 1 , I 2 , … , I M \mathcal{F}_{1},\mathcal{F}_{2},...,\mathcal{F}_{M} . The task is to learn a mapping f f that captures the relationships between these modalities. Mathematically, this can be formulated as: The challenge lies in effectively combining information from diverse modalities, which can be approached through various techniques such as late fusion or early fusion.
In late fusion [ 30 ] , features are extracted independently from each modality and then combined at a later stage. This approach treats modalities as separate entities until a decision needs to be made and can be represented as: where h i h_{i} represents feature extraction for modality i i , and g g combines the extracted features. In early fusion [ 31 ] , information from different modalities is combined at the input level, resulting in a joint feature representation which can be expressed as: Calibration involves ensuring that a model’s confidence score accurately reflects the true probability of the prediction’s correctness [ 32 ] . Let X X be the input data, and Y Y be the output label. Given a training dataset D = ( x 1 , y 1 ) , ( x 2 , y 2 ) , … , ( x n , y n ) D={(x_{1},y_{1}),(x_{2},y_{2}),...,(x_{n},y_{n})} , the goal is to learn a function f f that can predict the correct output label y y for a given input x x . The output of the model for an input x x can be denoted as f I ( x ) f(x) , and the true probability of the prediction’s correctness can be denoted as P I ( y = 1 | x ) P(y=1|x) . A calibrated model produces a confidence score g I ( x ) g(x) that reflects the true probability of correctness of the prediction. The goal of calibration is to ensure that the confidence score g I ( x ) g(x) is well-calibrated, i.e., P I ( y = 1 | g I ( x ) = p ) = p P(y=1|g(x)=p)=p for all p p in the range [ 0 , 1 ] [0,1] .
Calibration is a crucial aspect in HT detection since it aids in determining the likelihood of the existence of a Trojan in a circuit, which can have a significant impact on decision-making. In situations where a model’s confidence score is high, but the likelihood of a Trojan’s presence is low, it is reasonable to assume that the circuit does not contain a Trojan. Conversely, if the confidence score is low but the likelihood of a Trojan’s presence is high, further investigation of the circuit is necessary.
Conformal Prediction (CP) is a ML framework that assesses prediction uncertainty by generating sets of possible predictions [ 33 ] . This approach strengthens the inference of conventional models, ensuring their reliability and enabling confidence estimation for individual predictions. It is worth noting that minority classes often bear a disproportionate burden of errors when label-conditional validity is lacking [ 34 ] . Nevertheless, this challenge can be mitigated by ensuring label-conditional validity, which guarantees that the error rate, even for the minority class, will eventually converge to the selected significance level in the long run.
4. Practical Deployment, Analysis & Case Studies In certain instances, CP may yield uncertain predictions, signifying that prediction sets contain more than one possible value. This happens when none of the labels can be rejected at the specified significance level. Moreover, when employing CP, the confusion matrix differs from the conventional one due to the distinctive nature of prediction sets, which encompass multiple values rather than a single one. In cases where providing a single-point prediction may be more appropriate than a prediction set or interval in a hedged forecast, opting for the label with the highest p p -value is a straightforward and reasonable choice.
There has been limited exploration of the application of CP in modal fusion [ 35 ] . This method entails treating individual data sources as separate hypothesis tests within the CP framework. Subsequently, it utilizes p p -value combination techniques as a test statistic for the combined hypothesis after the fusion process. Our approach relies on the Mondrian Inductive Conformal Prediction (ICP) methodology [ 36 ] outlined in Algorithm 1 for the uncertainty-aware fusion of various modalities during classification. This algorithm can be effectively extended for both early and late fusion of the modalities.
While state-of-the-art works on HT detection have focused mainly on choosing the right algorithm and choosing different representations of the dataset for improved accuracy, incorporating different modalities of the same data and feeding it to the ML system has not been investigated. By performing information fusion derived from different modalities, a more refined data representation can be achieved. Furthermore, in a real-time scenario, we encounter missing values while collecting data, and this may lead to missing modalities when dealing with a multimodal ML approach. So, we also need a method that handles missing modalities for any given dataset. Lastly, in the domain of hardware security, it is difficult to get enough data for training, especially the labels marked as Trojan-infected because of the rarity of the event. In such a situation, we need to work with limited data.
Our proposed NOODLE framework is shown in Fig. 1 emphasizing the design and implementation, and a pseudocode is also provided in Algorithm 2 . We choose to use two modalities, i.e., graph and tabular data representations. Methods like multimodal autoencoder [ 37 ] have been used for handing missing modalities; however, we use Generative Adversarial Networks (GANs) [ 38 ] to increase the dataset size to 500 data points as it aims to generate samples that are consistent with the joint distribution of the observed modalities and facilitate more effective multimodal fusion. The data points labeled as Trojan-Free (TF) will be segregated, and only these will be used to generate more data points using GAN so that they represent the same label, and we will do the same for data labeled as Trojan-Infected (TI). Before performing multimodal learning, we first explain the working of uncertainty-aware model fusion.
To perform an uncertainty-aware multimodal fusion, we leverage conformal prediction p p -values for the model fusion as described in Algorithm 1 . First, we use a Convolutional Neural Network (CNN)-based classifier for graph and tabular data sources with a designed non-conformity score that provides p p -values for each label and for each data modal. The below non-conformity score can be used in the CP framework to get calibrated conformal predictions: where B t I ( x , y ) B_{t}(x,y) is the non-conformity score of ( x , y ) (x,y) computed from a classifier, h t h_{t} . Thus, for every class label y I ( j ) y(j) , j ∈ { 1 , … , M } j\in\{1,...,M\} , we have an individual null hypothesis for each data source, H I 0 1 , H I 0 2 , … , H I 0 N H0_{1},H0_{2},...,H0_{N} , where M M is the number of class labels, which in our case is either TF or TI, and N N is the number of data sources. Thus, for every class label y I ( j ) y(j) , we obtain N N p p -values, p I ( i ) p(i) , i = 1 , … , N i=1,...,N (one for each modality). These p p -values are then combined into a new test statistic C I ( p I ( 1 ) , … , p I ( N ) ) C(p(1),...,p(N)) , which is used to test the combined null hypothesis H I 0 H0 for class label y I ( j ) y(j) . The conformal prediction region at a specified confidence level, r E r_{E} , is then presented as a set containing all the class labels with a p p -value greater than 1 − E 1-E . The mentioned steps helps in realization of uncertainty-aware multimodal fusion.
After obtaining a sufficient number of data points for the experiment, we implement multimodal ML using the graph and tabular data. Specifically, we have employed a CNN for binary classification. It’s worth mentioning that any ML model can be optimized through hyper-parameter tuning to enhance accuracy. However, our primary emphasis is on assessing the effectiveness of uncertainty-aware multimodality by accessing early and late fusions. Finally, the model will be used to make further informed decisions for the detection of HTs.
We used Python (3.9) and implemented NOODLE on macOS (13.3.1) with 8GB RAM. The experimental results with source code and the dataset are hosted on GitHub 1 1 1 https://github.com/cars-lab-repo/NOODLE . For our experiment, we have used the features extracted from the TrustHub RTL-level (Verilog) Trojan dataset based on code branching features [ 28 ] and the graph dataset in [ 27 ] which includes RTL source code files (Verilog) for each IP core design containing both malicious and non-malicious functions.
For any of the classification problem statements, the most common performance metric is model accuracy, followed by various other complementing metrics such as precision recall and F1-score. However, these metrics can be misleading in situations where the class distribution is imbalanced, as in our case. For this reason, we have used the Brier score as an evaluation metric for assessing the quality of probabilistic predictions in the classification of HTs. The Brier score, which offers insights into accuracy and calibration, is defined as follows: where N N is the number of instances, p i p_{i} is predicted probability for instance i i , and o i o_{i} is the observed outcome for instance i i . The Brier score ranges from 0 to 1. A score of 0 indicates perfect accuracy, meaning the predicted probabilities perfectly match the actual outcomes. A score of 1 signifies complete inaccuracy, where the predicted probabilities are entirely different from the actual outcomes.
5. Performance Evaluation & Extended Technical Observations We begin the evaluation process by independently assessing each modality. This involves conducting binary classification on both the graph dataset and the tabular data. The resulting comparative Brier scores for these classification tasks are presented in Table I . The experimental outcome demonstrates that, when employing the same CNN-based deep learning model with identical hyperparameters, the graph dataset yields a superior Brier score (0.1798) compared to the tabular data (0.1913). It is worth noting that while we established a baseline model using CNN, any other alternative classification algorithms can also be employed in this context.
Then, we tested NOODLE with two different information fusion approaches, i.e., early fusion (feature) and late fusion (decision). As shown in Table I , the early fusion approach, which combines the graph and tabular data before processing, yields a Brier score of 0.1685. On the other hand, the late fusion strategy, which integrates the graph and table data after individual processing, demonstrated the best performance with a Brier score of 0.1589.
It is worth noting that neither of these data fusion methods can be deterministically labeled as superior [ 39 ] as each one of them will demonstrate their potential to produce favorable outcomes when the data distribution changes. For this reason, we implemented both of the fusion approaches and chose the approach that provides a better Brier score (i.e., closer to 0), as mentioned in Step 8 of Algorithm 2 . The corresponding Brier score distribution with mean interval is also shown in Fig. 2 a and Fig. 2 b for early and late fusion, respectively. This provides a comprehensive view of predictive accuracy across multiple scenarios and is also useful for comparing models and understanding the variability in performance.
The confidence calibration curve plots observed probabilities of occurrence as a function of the predicted probabilities for the classification model, as shown in Fig. IV-B . For the model to be perfectly calibrated, it will have all data points along the diagonal; however, in our case, the model is not well calibrated because of the highly imbalanced dataset. These are the cases on which any decision-maker should focus while making a risk-aware decision and not completely relying on accuracy alone. It helps evaluate the alignment between a model’s predicted probabilities and the actual likelihood of events.
A histogram at the bottom of Fig. IV-B shows the predicted chance for 109 test data. It describes the distribution of the forecasts and helps with visualization of the sharpness, i.e., tendency of the predictions to lie at the extremes of the 0-1 distribution, and is equal to the variance of the predictions. The Receiver Operating Characteristic (ROC) curve illustrates the balance between sensitivity and specificity in a model. It provides a visual representation of how these two metrics change as the threshold for classifying a condition varies. The Area Under the Curve (AUC), on the other hand, quantifies the likelihood that a randomly chosen pair of circuits, one with the Trojan and one without, will be accurately classified by the model. The NOODLE ’s ROC-AUC curve is given in Fig. IV-B .
The white area represents the optimal zone for model performance, and the lightly shaded red areas represent the zones of acceptable efficacy. The values for ROC-AUC range from 0 to 1, where values near ‘1’ suggest that it can effectively discriminate between TF and TI cases with a high degree of confidence, and if the value is near ‘0’, the model’s performance is worse than random guessing. In our case, the value is 0.928, which suggests that the model is performing well.
The radar plot provides a visual means of presenting complex, multi-dimensional data, as shown in Fig. IV-B . When appraising the effectiveness of a predictor, there is a tendency to focus narrowly on a limited set of metrics. However, the radar plot provides a method for gaining a comprehensive understanding of performance across diverse dimensions. In a radar chart, each variable is represented along its corresponding axes (some variables have been normalized to conform to the 0-1 range of the radial axis). It is also important to organize the variables in a way that clusters connected ideas or principles. This aids in conducting a thorough evaluation of various facets of performance.
In the given radar plot, we have metrics related to discrimination, which include AUC, resolution, and refinement loss. Following these are combined metrics assessing both calibration and discrimination, namely the Brier score and Brier skill score. As shown in the figure, the model is less sensitive and has high accuracy. This implies that while the model is generally accurate in its predictions, it may not be as effective in identifying all the actual TI cases. This could be due to a higher number of false negatives, which means the model is missing some of the positive cases.
In this study, we have addressed the growing concern of maliciously inserted hardware Trojans into chips at various stages of production in an era where fabless manufacturing is hard to trust. To tackle this issue, we adopted an innovative approach by utilizing generative adversarial networks to expand our dataset with two distinct representation modalities: graph and tabular. Additionally, we introduced an uncertainty-aware multimodal deep learning framework called NOODLE for detecting hardware Trojans. We assessed our findings using both early and late fusion strategies, offering a comprehensive evaluation of our approach’s efficacy. Moreover, we integrated metrics for uncertainty quantification for each prediction, enabling us to make decisions that are mindful of potential risks. The utilization of multimodality and uncertainty quantification shows great potential for addressing other critical challenges in hardware security. These contributions collectively represent a significant step forward in enhancing the security and reliability of hardware systems in the face of emerging threats.
arXivLabs is a framework that allows collaborators to develop and share new arXiv features directly on our website. Harvested Online Documentation & Reference Sources • https://github.com/Shreekavinmr/Trojan-horse-detection • https://github.com/Sudheer-krish/trojan-malware-detection-ml • https://arxiv.org/html/2401.09479v1 • https://arxiv.org/abs/2401.09479
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Trojan Horse Detection Using Machine Learning Algorithms.
[*] Metasploit Scan Running on Target Subnet for Trojan Horse Detection Using Machine Learning Algorithms... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |