Complete Technical Paper Content — Web Scraping Protection And Bot Mitigation System
Overview & System Context
Web Scraping Protection And Bot Mitigation System: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9519 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background Cloudflare, Inc., is an American technology company headquartered in San Francisco, California, that provides a range of internet services, including content delivery network (CDN) services, cloud cybersecurity, DDoS mitigation, and ICANN-accredited domain registration. The company's services act primarily as a reverse proxy between website visitors and a customer's hosting provider, improving performance and protecting against malicious traffic. Cloudflare was founded in 2009 by Matthew Prince, Lee Holloway, and Michelle Zatlyn. The company went public on the New York Stock Exchange in 2019 under the ticker symbol NET. Cloudflare has since expanded its offerings to include edge computing through its Workers platform, a public DNS resolver (1.1.1.1), and a VPN-like service known as WARP. In recent years, the company has integrated artificial intelligence into its infrastructure, acquiring companies such as Replicate and launching tools to manage AI bots and scrapers. According to W3Techs, Cloudflare is used by approximately 21.3% of all websites on the Internet as of January 2026. The company has been the subject of controversy regarding its policy of content neutrality. While Cloudflare executives have historically advocated for remaining a neutral infrastructure provider, the company has terminated services for specific high-profile websites associated with hate speech and violence, including The Daily Stormer, 8chan, and Kiwi Farms, following significant public pressure. Cloudflare has also faced criticism and litigation regarding copyright infringement by websites using its services, notably losing a lawsuit against Japanese publishers in 2025. The company experienced significant global outages in late 2025 which disrupted services for major platforms internationally.
Since at least 2017, Cloudflare has used a wall of lava lamps at its San Francisco headquarters as a source of randomness for encryption keys, alongside double pendulums at its London offices and a Geiger counter at its Singapore offices. The lava lamp installation implements the Lavarand method, where a camera transforms the unpredictable shapes of the "lava" blobs into a digital image. In Q4 2022, Cloudflare provided paid services to 162,086 customers. In October 2024, Cloudflare won a lawsuit against patent troll Sable Networks. Sable paid Cloudflare $225,000, granted it a royalty-free license to its patent portfolio, and dedicated its patents to the public by abandoning its patent rights. In November 2025, it was announced Cloudflare had agreed to acquire Replicate, a San Francisco–based platform that enables software developers to run, fine-tune, and deploy open-source machine-learning models via an API without managing infrastructure. In January 2026, Cloudflare released an analysis regarding BGP routing leaks observed from the Venezuelan state-owned ISP CANTV (AS8048), which occurred on January 2 coincides with the arrest of Nicolás Maduro. While some security researchers had speculated that the outages were linked to U.S. cyber operations, Cloudflare's data indicated that the anomalies were consistent with a pattern of "insufficient routing export and import policies" by the ISP rather than malicious external interference. In January 2026, Cloudflare acquired Human Native, an AI data marketplace that brokers transactions between developers and content creators, for an undisclosed amount. On January 16, 2026, Cloudflare acquired The Astro Technology Company, the developers behind the open-source web framework Astro. In May 2026, Cloudflare announced the elimination of approximately 1,100 positions, around 20 percent of its workforce, in a restructuring the company attributed to the rapid adoption of artificial intelligence tools. The announcement coincided with the company's first-quarter 2026 earnings, which reported a record $639.8 million in quarterly revenue, a 34 percent year-over-year increase. CEO Matthew Prince stated the cuts were not driven by performance concerns but reflected roles made obsolete by AI, and that Cloudflare expected to employ more people by the end of 2027 than at any point during 2026. In June 2026, Cloudflare acquired VoidZero, the open-source company behind the JavaScript tool Vite and related developer tools including Vitest, Rolldown, and Oxc.
Cloudflare said the acquisition would integrate VoidZero's tooling into its Workers developer platform to support AI-assisted application development, while committing $1 million to an independent Vite ecosystem fund and continuing to maintain the projects as open source. From September 2016 until February 2017, a Cloudflare bug nicknamed Cloudbleed leaked sensitive data, including passwords and authentication tokens, from customer websites by sending extra data in response to web requests.
Cloudflare provided DDoS mitigation and acted as a reverse proxy for Kiwi Farms. The site often engages in harassment and doxxing of targets and has been implicated in the suicides of at least three people. Kiwi Farms also has a reputation for transphobic content, and its users have been accused of swatting vulnerable individuals. Although Cloudflare was not the primary website host, it did perform critical services to keep Kiwi Farms on-line, both protecting the site from denial-of-service attacks and optimizing content delivery. In 2022, a campaign was launched by transgender activist Clara Sorrenti, who has previously been targeted by the forum, to pressure Cloudflare into terminating service for Kiwi Farms. Cloudflare responded by issuing a statement on its abuse policies and saying it didn't want to set precedent for speech on the internet with its "extraordinary" decision. The company also released a blog post and likened its services to that of a public utility, emphasizing that it does not believe in shutting down security services based on content it finds objectionable. They acknowledged that while it might be more popular to remove sites that the Cloudflare team finds offensive, it stood by its decision not to do so.
The company also defended its decision by saying that it donated all earnings from anti-LGBTIQ+ sites to an organization that advocated for LGBTIQ+ rights. The blog post mentioned Cloudflare's terms of use agreement, which allows them to terminate service due to "content that discloses sensitive personal information, [and] incites or exploits violence against people" but, according to The Guardian, the statement did not address how Kiwi Farms users' doxxing behavior did not violate these terms. On September 3, 2022, Cloudflare blocked Kiwi Farms, citing urgent escalating rhetoric against targets of Kiwi Farms, stating that there is an "unprecedented emergency and immediate threat to human life". According to The Washington Post, there was a "surge in credible violent threats stemming from the site" and CEO Matthew Prince said that Cloudflare believes "there is an imminent danger, and the pace at which law enforcement is able to respond to those threats we don't think is fast enough to keep up".
Figure 1: Top Bot Detection and Mitigation Software Solutions In computer networking, a proxy server is an intermediary server application between a client requesting a resource and the server then providing that resource. Instead of connecting directly to a server that can fulfil a request for a resource, such as a file or web page, the client directs the request to the proxy server, which evaluates the request and performs the required network transactions. This serves as a method to control the complexity of the request or provide additional benefits such as load balancing, privacy or security. Proxies were devised to add structure and encapsulation to distributed systems.
An open proxy is a forwarding proxy server that is accessible by any Internet user. In 2008, network security expert Gordon Lyon estimated that "hundreds of thousands" of open proxies are operated on the Internet. Anonymous proxy: This server reveals its identity as a proxy server but does not disclose the originating IP address of the client. Although discovered easily as a proxy server, it can be beneficial for some users as it hides the originating IP address.
Forwarding headers: Some proxies append HTTP headers to disclose client or proxy information that would otherwise be lost when a request is forwarded. Historically this has often been done with non-standard fields such as X-Forwarded-For, while the standardised Forwarded field provides a defined syntax for similar information. Such headers are deployment-dependent and should not be treated as inherently trustworthy, since they may be absent, modified, or contain values added by multiple proxies.
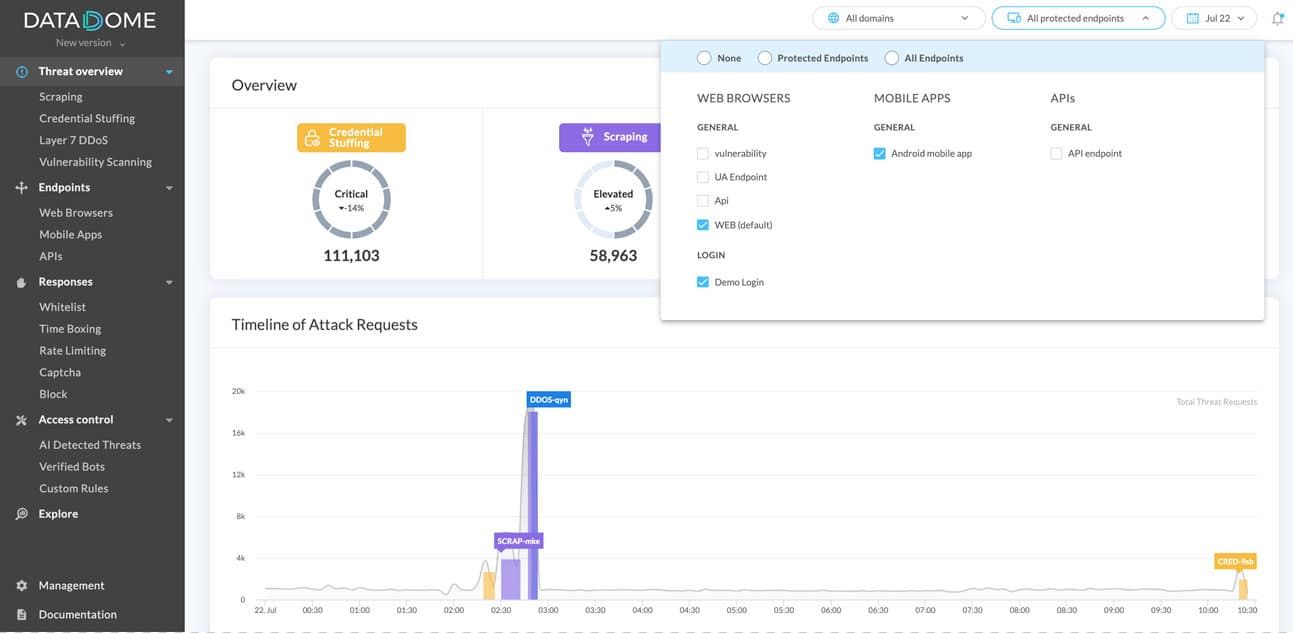
A reverse proxy (or surrogate) is a proxy server that appears to clients to be an ordinary server. Reverse proxies send requests to one or more ordinary servers that handle the request. The response from the original server is returned as if it came directly from the proxy server, leaving the client with no knowledge of the original server. Reverse proxies are installed in the vicinity of one or more web servers. All traffic coming from the Internet and with a destination of one of the neighborhood's web servers goes through the proxy server. The use of "reverse" originates in its counterpart, the "forward" proxy. The reverse proxy sits closer to the web server and serves only a restricted set of websites. There are several reasons for installing reverse proxy servers: Figure 2: 6 Best Bot Protection Software of 2024 TLS termination: Reverse proxies often terminate TLS connections from clients and forward requests to backend servers. This can centralise certificate management, access control, logging, and request routing, and can reduce the TLS-related work performed by backend servers. Backend connections may use HTTP or HTTPS depending on the deployment and security requirements. Modern deployments usually perform TLS termination in software, optionally with hardware assistance, rather than requiring dedicated SSL acceleration hardware. Certificates for multiple names can be handled using mechanisms such as Subject Alternative Name certificates, wildcard certificates, and Server Name Indication (SNI). Load balancing: the reverse proxy can distribute the load to several web servers, each serving its own application area. In such a case, the reverse proxy may need to rewrite the URLs in each web page (translation from externally known URLs to the internal locations).
Serve/cache static content: A reverse proxy can offload the web servers by caching static content like pictures and other static graphical content. Compression: The proxy server can optimize and compress the content to speed up the load time. Spoon feeding: reduces resource usage caused by slow clients on the web servers by caching the content the web server sent and slowly "spoon feeding" it to the client. This especially benefits dynamically generated pages. Security: The proxy server is an additional layer of defense and can protect against some OS and web-server-specific attacks. However, it does not provide any protection from attacks against the web application or service itself, which is generally considered the larger threat.
Extranet publishing: a reverse proxy server facing the Internet can be used to communicate with a firewall server internal to an organization, providing extranet access to some functions while keeping the servers behind the firewalls. If used in this way, security measures should be considered to protect the rest of your infrastructure in case this server is compromised, as its web application is exposed to attack from the Internet.
A content-filtering web proxy server provides administrative control over the content that may be relayed in one or both directions through the proxy. It is commonly used in both commercial and non-commercial organizations (especially schools) to ensure that Internet usage conforms to acceptable use policy. Content filtering proxy servers will often support user authentication to control web access. It also usually produces logs, either to give detailed information about the URLs accessed by specific users or to monitor bandwidth usage statistics. It may also communicate to daemon-based or ICAP-based antivirus software to provide security against viruses and other malware by scanning incoming content in real-time before it enters the network. Many workplaces, schools, and colleges restrict websites and online services that are accessible and available in their buildings. Governments also censor undesirable content. This is done either with a specialized proxy, called a content filter (both commercial and free products are available), or by using a cache-extension protocol such as ICAP, which allows plug-in extensions to an open caching architecture. Websites commonly used by students to circumvent filters and access blocked content often include a proxy, from which the user can then access the websites that the filter is trying to block. Requests may be filtered by several methods, such as a URL or DNS blacklists, URL regex filtering, MIME filtering, or content keyword filtering. Blacklists are often provided and maintained by web-filtering companies, often grouped into categories (pornography, gambling, shopping, social networks, etc.). The proxy then fetches the content, assuming the requested URL is acceptable. At this point, a dynamic filter may be applied on the return path. For example, JPEG files could be blocked based on fleshtone matches, or language filters could dynamically detect unwanted language. If the content is rejected, then an HTTP fetch error may be returned to the requester. Most web filtering companies use an internet-wide crawling robot that assesses the likelihood that content is a certain type. Manual labor is used to correct the resultant database based on complaints or known flaws in the content-matching algorithms. Some proxies scan outbound content, e.g., for data loss prevention, or scan content for malicious software.
An anonymous proxy server (sometimes called a web proxy) generally attempts to anonymize web surfing. Anonymizers may be differentiated into several varieties. The destination server (the server that ultimately satisfies the web request) receives requests from the anonymizing proxy server and thus does not receive information about the end user's address. The requests are not anonymous to the anonymizing proxy server, however, and so a degree of trust is present between the proxy server and the user. Many proxy servers are funded through a continuous advertising link to the user. Access control: Some proxy servers implement a logon requirement. In large organizations, authorized users must log on to gain access to the web.
The organization can thereby track usage by individuals. Some anonymizing proxy servers may forward data packets with header lines such as HTTP_VIA, HTTP_X_FORWARDED_FOR, or HTTP_FORWARDED, which may reveal the IP address of the client. Other anonymizing proxy servers, known as elite or high-anonymity proxies, make it appear that the proxy server is the client. A website could still suspect a proxy is being used if the client sends packets that include a cookie from a previous visit that did not use the high-anonymity proxy server. Clearing cookies and possibly the cache would solve this problem.
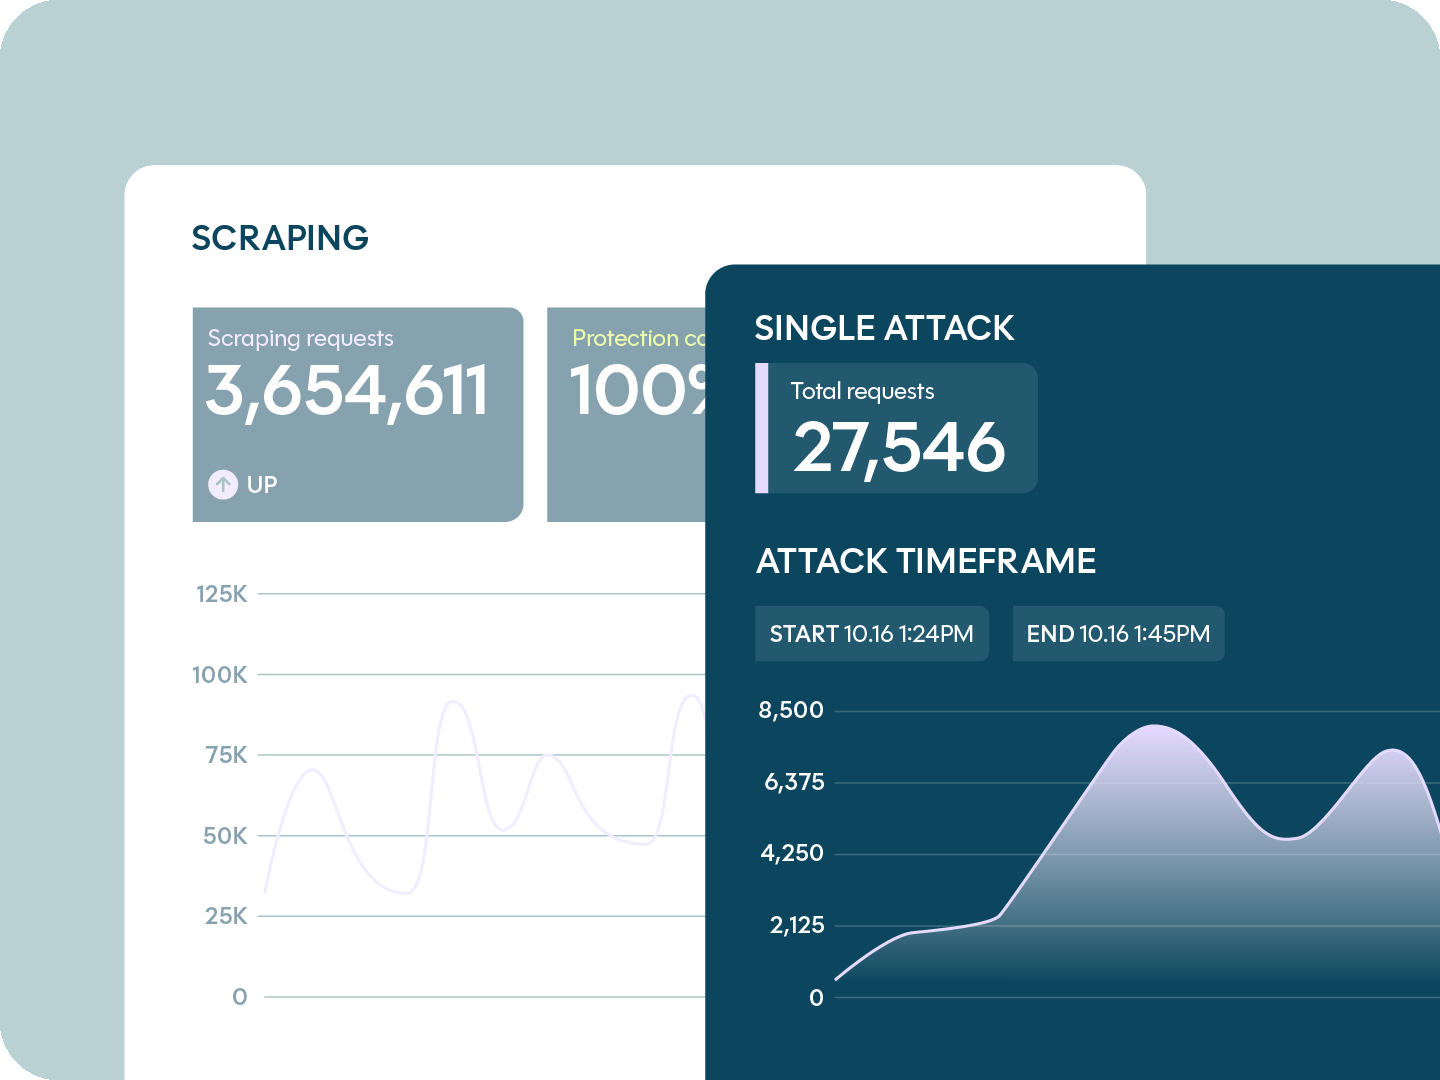
This request is sent to the proxy server, the proxy makes the request specified, and returns the response. Figure 3: DataDome Bot Detection, Mitigation & Protection Solution With Agent Trust Some web proxies allow the HTTP CONNECT method to set up forwarding of arbitrary data through the connection; a common policy is to only forward port 443 to allow HTTPS traffic. Examples of web proxy servers include Apache (with mod_proxy or Traffic Server), HAProxy, IIS configured as proxy (e.g., with Application Request Routing), Nginx, Privoxy, Squid, Varnish (reverse proxy only), WinGate, Ziproxy, Tinyproxy, RabbIT and Polipo. For clients, the problem of complex or multiple proxy-servers is solved by a client-server Proxy auto-config protocol (PAC file).
By comparing the client's external IP address to the address seen by an external web server, or sometimes by examining the HTTP headers received by a server. A number of sites have been created to address this issue by reporting the user's IP address as seen by the site back to the user on a web page. Google also returns the IP address as seen by the page if the user searches for "IP". By comparing the results of online IP checkers when accessed using HTTPS vs. HTTP, as most intercepting proxies do not intercept SSL. If there is suspicion of SSL being intercepted, one can examine the certificate associated with any secure website; the root certificate should indicate whether it was issued for interception. By comparing the sequence of network hops reported by a tool such as traceroute for a proxied protocol such as HTTP (port 80) with that for a non-proxied protocol such as SMTP (port 25). By attempting to make a connection to an IP address at which there is known to be no server. The proxy will accept the connection and then attempt to proxy it on. When the proxy finds no server to accept the connection, it may return an error message or simply close the connection to the client. This difference in behavior is simple to detect. For example, most web browsers will generate a browser-created error page in the case where they cannot connect to an HTTP server, but will return a different error in the case where the connection is accepted and then closed. By serving the end-user specially programmed Adobe Flash SWF applications or Sun Java applets that send HTTP calls back to their server.
Tor is a system intended to provide online anonymity. Tor client software routes Internet traffic through a worldwide volunteer network of servers for concealing a user's computer location or usage from someone conducting network surveillance or traffic analysis. Using Tor makes tracing Internet activity more difficult, and is intended to protect users' personal freedom and their online privacy. "Onion routing" refers to the layered nature of the encryption service: The original data are encrypted and re-encrypted multiple times, then sent through successive Tor relays, each one of which decrypts a "layer" of encryption before passing the data on to the next relay and ultimately the destination. This reduces the possibility of the original data being unscrambled or understood in transit.
A residential proxy (RESIP) is an intermediary that uses a real IP address provided by an Internet service provider with physical devices such as mobile phones and end-user computers. Instead of connecting directly to a server, residential proxy users connect to the target through residential IP addresses. The target then identifies them as organic internet users. It does not let any tracking tool identify the reallocation of the user. Any residential proxy can send any number of concurrent requests, and IP addresses are directly related to a specific region. Unlike regular residential proxies, which hide the user's real IP address behind another IP address, rotating residential proxies, also known as backconnect proxies, conceal the user's real IP address behind a pool of proxies. These proxies switch between themselves at every session or at regular intervals. Despite providers' assertions that the proxy hosts are voluntarily participating, numerous proxies are operated on potentially compromised hosts, including Internet of things devices. Through the process of cross-referencing the hosts, researchers have identified and analyzed logs that have been classified as potentially unwanted program and exposed a range of unauthorized activities conducted by RESIP hosts. These activities encompassed illegal promotion, fast fluxing, phishing, hosting malware, and more.
Fireblade (acquired by StackPath) is an Israeli company founded in 2008. It developed the first cloud-based bot-management solution and a multi-tier SaaS security suite powered by reputational and behavioral firewalls, to protect websites against DDoS attacks, web application attacks and a variety of automated attacks, improving website health, security and performance. It offers integration with cPanel and WHM Fireblade was founded by Shay Rapaport and Erez Azaria (CEO and CTO respectively). Fireblade's extensive bot management solution offers protection against credential stuffing, brute force attacks, application layer DDoS attacks, web spam and scraping It also offers dynamic performance optimization, a 30 Points of Presence tier-1 CDN and other tools.
See how Gcore protected gaming servers from massive DDoS threats without disrupting gameplay. Track uptime, service availability, incidents and maintenances across the Gcore platform and services. We're not just filling seats. We're building a team that will write the next chapter of the internet. Your server load suddenly spikes by 400%. Legitimate customers can't access your site. Competitors are methodically copying your product descriptions, pricing data, and proprietary content. Modern scraping bots are draining your resources and stealing your competitive advantage, and traditional defenses can't stop them because these attacks mimic human behavior perfectly.
The scale of this threat is staggering. Organizations using full protection strategies report reducing server load by up to 90%, while advanced solutions now prevent 99% of scraping attempts. Yet hyper-distributed bot attacks using multiple user-agents, IPs, and rotating proxies easily bypass conventional Web Application Firewalls. The sophistication has forced the entire industry to shift from signature-based detection to behavioral analysis and machine learning approaches.
You'll discover how modern web scraping protection actually works, which technologies detect even the most advanced bots, and how to build a layered defense plan that stops unauthorized data extraction without blocking legitimate users or search engines. Web scraping protection is a security layer that detects and blocks automated bots trying to extract content and data from your website without permission. These bots can steal product listings, pricing information, user data, and proprietary content, often selling it to competitors or using it to undercut your business. Modern protection systems analyze behavior patterns and apply machine learning to identify scraping attempts, since today's bots mimic human behavior and easily bypass traditional defenses like basic firewalls. Organizations that deploy full protection can reduce server load by up to 90% while still allowing legitimate search engines and real users to access their sites normally.
Web scraping protection combines multiple detection layers that identify automated bots and distinguish them from legitimate users. The system monitors incoming traffic patterns, analyzes behavioral signals, and applies mitigation rules, all happening in milliseconds before content is served. Here's the basic flow. When a request hits your site, protection tools first check device fingerprints by collecting attributes like screen resolution, operating system, and browser plugins. These create unique identifiers that persist even when scrapers rotate IP addresses or use VPNs. Next, behavioral analysis kicks in. The system tracks mouse movements, keystroke patterns, and navigation sequences. Bots typically move too fast, follow predictable paths, or skip certain actions that humans naturally perform.
Rate limiting adds another defense layer. If requests from a single source exceed set thresholds (say, 100 requests per minute), the system automatically throttles or blocks that traffic. Advanced solutions apply machine learning models trained on millions of traffic samples to spot attacks that mimic human behavior. These models can detect hyper-distributed attacks using multiple user-agents and IP addresses, which easily bypass traditional WAFs.
The key thing: modern protection happens at the edge, analyzing traffic before it reaches your origin servers. This approach can reduce server load by up to 90% while maintaining access for legitimate visitors and search engine crawlers. Unprotected web scraping creates measurable financial and operational damage across multiple business areas. Organizations without proper defenses face server overload, competitive disadvantages, and security vulnerabilities that directly affect their bottom line.
Effective web scraping protection methods combine multiple defense layers to detect and block automated data extraction while allowing legitimate traffic through. The most reliable approaches analyze behavior patterns, fingerprint devices, and apply intelligent rate limiting rather than simple IP blocks that scrapers easily bypass. Every bot detection system faces a fundamental trade-off between catching malicious bots and accidentally blocking legitimate users. Aggressive detection settings can block real customers, users on corporate networks, visitors from regions with unstable internet, and assistive technologies like screen readers. When deploying protection, monitor for false positives by reviewing blocked requests, providing easy appeals for blocked users, and gradually tuning sensitivity rather than starting with maximum blocking.
You apply web scraping protection best practices by deploying multiple defense layers that work together to detect and block malicious bots while allowing legitimate traffic through. The key thing is that no single method stops all scraping attempts. You need layered defenses that adapt as attackers change tactics.
Warning signs of web scraping attacks refer to observable patterns and anomalies that indicate automated bots are extracting data from your website. The warning signs are listed below. Gcore protects against web scraping through the Web Application Firewall and bot management capabilities deployed across 210+ global edge locations. The system analyzes behavior patterns and applies machine learning to distinguish malicious scrapers from legitimate traffic, including search engine crawlers that your site needs.
2. System Architecture & Core Working Principles You'll get real-time detection at the edge that stops advanced bots before they reach your origin servers. The Gcore platform identifies scraping patterns even when attackers rotate IPs, spoof user agents, or distribute requests across multiple ASNs. This approach can reduce server load by up to 90% while keeping your site accessible to real users.
The system combines rate limiting, device fingerprinting, and threat intelligence to block automated extraction attempts without impacting site performance. You can set custom rules based on geography, request patterns, or specific endpoints that need extra protection. Web scraping protection defends against automated data extraction bots that steal content, pricing, or inventory information, while DDoS protection blocks traffic floods designed to overwhelm servers and crash websites. Scraping attacks target your data, DDoS attacks target your availability.
Web scraping protection costs range from free basic tools to enterprise solutions priced at $200 to $50,000+ monthly, depending on traffic volume and feature complexity. Organizations with moderate traffic typically spend $500 to $5,000 per month for full protection that includes behavioral analysis, machine learning detection, and real-time mitigation. Yes, properly configured web scraping protection is secure for legitimate users because modern solutions analyze behavior patterns and apply machine learning to distinguish between human visitors and automated bots. Advanced systems maintain full functionality for real users and search engines while blocking malicious scrapers at the edge without impacting site performance.
Most scraping protection solutions require only DNS changes or JavaScript tag deployment, with no server-side modifications needed. Cloud-based services handle detection and mitigation at the edge, though on-premises WAF solutions need dedicated hardware and ongoing maintenance resources. Machine learning analyzes patterns in user behavior, request timing, navigation flows, and device attributes to distinguish legitimate visitors from advanced bots that mimic human activity. This behavioral analysis approach detects threats that evade traditional signature-based defenses, achieving up to 99% prevention rates against modern scraping attacks.
No, web scraping protection can't block all automated traffic, nor should it. Legitimate bots like search engine crawlers (Googlebot, Bingbot) need access to index your site, while automated monitoring tools and API clients serve valid business purposes. E-commerce, travel, and financial services face the highest scraping risks due to valuable pricing data, competitive intelligence, and real-time inventory information that competitors actively target. Media publishers and job boards also require robust protection to prevent content theft and unauthorized data aggregation that undermines their business models.
Every second of load time costs you. During a traffic spike, an uncached origin server can buckle under the pressure, and CDN caching can offload 70% to 90% of that traffic before it ever reaches your Gcore infrastructure. For a user in New Picture an autonomous vehicle doing 70 mph on the highway, waiting on a response from a data center hundreds of miles away. Or a surgeon depending on real-time imaging that freezes mid-procedure because data has to make a round trip across Every cache miss is a trip your server didn't need to make. And those trips add up fast. Sites with poorly optimized caching can see cache hit ratios as low as 70%, meaning three in 10 requests are hitting your origin server directly, dragg Every minute your servers are down, your business is bleeding. For e-commerce sites, healthcare platforms, and revenue-critical applications, an outage isn't just an inconvenience. It's a direct hit to your bottom line, your reputation, and Your server choice could be quietly costing you, or quietly holding you back. Pick the wrong infrastructure for your workload and you're either overpaying for idle hardware every month or watching your site buckle under traffic spikes you c Your site is humming along fine, until it isn't. Traffic spikes, page loads crawl, and your hosting plan buckles under pressure right when it matters most. Choosing between a VPS and a dedicated server isn't just a technical checkbox. It's Get the latest industry trends, exclusive insights, and Gcore updates delivered straight to your inbox.
Bots can be deployed to extract product details, pricing, or intellectual property from a competitor's website. For example, a travel booking site finds that a competitor is using bots to constantly monitor and undercut its flight or hotel pricing in near real-time. Content scraping bots pose a significant risk to business competitiveness, system performance, and data integrity. FortiWeb provides a comprehensive, multi-layered defense against these threats.
FortiWeb's Known Bots feature leverages FortiGuard threat intelligence to identify and block: FortiWeb regularly updates bot signatures and IP reputation data from FortiGuard, ensuring that the latest bots can be effectively identified and mitigated in real time. FortiWeb's Bot Deception inserts invisible or fake elements (such as hidden links or fields) into your web application responses. These elements are not seen or interacted with by legitimate users using normal browsers.
Bot Deception is an effective anti-scraping solution that operates invisibly without impacting user experience. It delivers low false positives and detects bots even when they use rotating IPs or mimic browser headers. FortiWeb's Threshold-Based Detection monitors request volume, type, and frequency within a defined time window. It is effective for identifying scraping patterns, such as: When these behaviors exceed the configured threshold (e.g., >100 requests to /pricing in 10 seconds), FortiWeb can take action (block, alert, log, etc.).
In addition to Content Scraping, FortiWeb's Threshold-Based Detection can also detect other forms of bot activity, including crawling, vulnerability scanning, slow attacks, and illegal user scan. For more details, see Configuring threshold based detection . FortiWeb's Machine Learning-Based Bot Detection builds a behavioral model by learning what normal user activity looks like across 13 behavioral dimensions. Several of these dimensions are particularly effective in distinguishing between legitimate user behavior and the automated, high-frequency, and selectively targeted patterns typical of scraping bots.
In addition to these dimensions, FortiWeb's machine learning model analyzes a broader set of behavioral indicators to detect other types of bot attacks beyond scraping bots. For more details, see Configuring ML Based Bot Detection policy . FortiWeb integrates with Advanced Bot Protection , a cloud-based service powered by FortiAppSec, to defend against sophisticated and evasive bots—including those used for content scraping, API abuse, credential stuffing, and other forms of automated attacks.
This service leverages real-time bot intelligence gathered from Fortinet's global threat network and a cloud-based scrubbing center to detect and mitigate bots that may bypass traditional, on-premise detection methods. It is particularly effective against distributed scraping operations that rotate IPs, mimic human behavior, or use headless browsers. By incorporating this cloud-native defense, FortiWeb enhances its ability to stop even zero-day or previously unknown bots in real time.
For detailed information on this feature, see Configuring Advanced Bot Protection policy . Content scraping is typically carried out by non-browser clients, such as scripts, headless browsers, or automated tools like curl or python-requests, which do not behave like real users interacting through browsers. To address this, FortiWeb integrates Bot Confirmation into Threshold-Based Bot Detection , Machine Learning-Based Bot Detection , and Advanced Bot Protection . One of the key mechanisms it uses is Real Browser Enforcement , which tests whether the client behaves like a real browser.
Real Browser Enforcement significantly reduces false positives by ensuring that only non-browser automation tools are challenged or blocked, while legitimate users can proceed uninterrupted—even if their behavior is borderline. You can enable Real Browser Enforcement when configuring Threshold-Based Bot Detection rules, as well as within the Machine Learning-Based Bot Detection and Advanced Bot Protection policies.
3. Software Implementation, Frameworks & Protocols In addition to Real Browser Enforcement , which verifies whether a request originates from a real browser, Bot Confirmation in FortiWeb also supports CAPTCHA and reCAPTCHA challenges to determine whether the client is a human. For an example of how these challenges are applied, see the scenario " Defending against Credential Stuffing attacks ".
By integrating Known Bots filtering, Bot Deception, Threshold-Based Detection, Machine Learning-Based Detection, and Advanced Bot Protection, FortiWeb empowers organizations to accurately detect and stop scraping bots without disrupting legitimate users. HUMAN Bot Defender is a behavior-based bot management solution that protects your web and mobile applications and APIs from automated attacks, safeguarding your online revenue, competitive edge and brand reputation.
Bot Defender can be deployed anywhere with your existing infrastructure — no changes required. HUMAN Technology Platform can be integrated into any website within minutes. Over forty pre-built integrations support a wide range of content delivery networks (CDNs), load balancers, web servers and application servers. The out-of-band mode of operation is compatible with any cloud-based, appliance-based or serverless infrastructure.
Safeguard your business with industry-leading bot detection accuracy and customizable mitigation for web and mobile applications and APIs. Bot Defender uses a combination of fingerprinting, behavior-based and predictive methods to detect bots and stop hyper-distributed attacks. The machine-learning-based HUMAN detector processes numerous data signals collected by the HUMAN sensor. The detector generates behavioral fingerprints to detect anomalies and continuously updates the sensor with new intelligence. The HUMAN enforcer is integrated inline with existing infrastructure to efficiently mitigate unwanted bot traffic based on the insights provided by the system and according to your business needs.
Bot Defender preserves your real users’ experience without sacrificing page load performance. The asynchronous execution of the sensor, out-of-band detector deployment, inline integration of the enforcer and extremely low false-positive rates ensure quick response times and a positive experience for your users. Bot Defender provides advanced investigation, analysis and reporting capabilities, enabling customization of parameters and policies according to your business needs.
Our 24/7/365 proactive security team is always available via multiple channels, including email, phone and Slack. They function as an extension of your team, investigating and resolving security incidents with insights and expertise you can count on. HUMAN JavaScript snippet is inserted on your website and loads the HUMAN Sensor to your browser. The Sensor collects and sends data to analyze the user’s and device’s behavior as well as different network activities. The sensor analyzes the authenticity of the device and application, and tracks user behavior and interaction.
The cloud-based detector evaluates sensor and enforcer data in real-time using machine learning and behavioral analytics to create a risk score. The risk score identifies whether a user is malicious or not and is sent in a secure and encrypted token back to the user’s device. A lightweight module that is installed on your choice of web application, load balancer or CDN and is responsible for the enforcement functionality of the HUMAN solution.
The digital battlefield has never been more intense. With automated bots now accounting for approximately 50% of all internet traffic, building robust anti-scraping protection has become a critical business imperative. Whether you’re protecting proprietary data, maintaining competitive advantages, or simply ensuring your servers don’t buckle under excessive requests from web scraper operations, the stakes have never been higher.
In my experience working with both scraping and protection systems, I’ve witnessed firsthand how the anti-scraping systems struggle to defend against intruders. Modern automated bots are sophisticated, using residential proxies, browser automation, and AI-powered evasion techniques that can mimic human users with startling accuracy. Only a handful of services, such as ScrapingBee, can navigate the scraping process ethically and respectfully.
The good news? Blocking scrapers is absolutely possible when you understand the landscape and implement the right anti-scraping measures. Let's take a look at the common methods. Anti-scraping refers to a set of measures that combine multiple layers: login walls, IP blocking, behavioral analysis, and JavaScript challenges. Here’s a simple rate-limiting demo that respects proper headers and intervals.
The beauty of authentication-based protection lies in its simplicity and effectiveness. When implemented correctly, login walls create a clear distinction between legitimate human users and automated systems attempting to collect data without permission. Modern implementations go beyond simple username-password combinations, incorporating multi-factor authentication, device fingerprinting, and session validation, which makes unauthorized access economically unfeasible for most scraping operations.
Authentication systems work by returning 401 or 403 HTTP status codes when unauthorized requests attempt to access protected resources. These responses effectively block bots that lack proper credentials, while CSRF tokens add an additional layer of complexity that automated systems struggle to handle efficiently. Yet, there are tools to simulate a login. Advanced scrapers often attempt to bypass login walls using headless browser automation tools like Puppeteer or Playwright. These tools can fill forms, execute JavaScript, and maintain session state, making them particularly challenging to detect through traditional means.
However, headless browsers leave distinctive fingerprints that a target website can identify. Browser automation frameworks often exhibit telltale signs like missing plugins, unusual navigator properties, or timing patterns that differ from genuine user interactions. Understanding these signatures helps in developing more robust detection mechanisms. IP blocking remains a cornerstone of modern Anti Bot Protection strategies, though its implementation has evolved significantly beyond simple blacklisting. Today’s systems analyze IP address reputation, track request patterns, and implement dynamic rate limiting that adapts to different threat levels. The challenge lies in balancing security with user experience, ensuring that legitimate traffic isn’t inadvertently blocked while maintaining effective protection against automated systems.
Modern IP-based protection systems consider multiple factors when evaluating requests. Geographic location, ISP reputation, request frequency, and historical behavior all contribute to risk scoring algorithms that determine whether to allow, challenge, or block incoming traffic. This nuanced approach helps distinguish between legitimate users who might be using VPNs or shared networks and malicious automated bots attempting to gather data effectively from multiple sources.
The evolution of proxy technology has made simple IP blocking less effective, but it remains valuable when combined with other detection methods. Scrapers using a single IP address are easily identified and blocked, but distributed operations using multiple IPs, also known as IP rotation, require more sophisticated detection mechanisms. If you want to learn how scrapers are overcoming these issues, read our What to Do If Your IP Gets Banned guide.
Security systems like Cloudflare and Akamai maintain extensive databases of IP address reputation scores based on historical behavior across their networks. These systems share threat intelligence, creating a global view of malicious activity that helps identify and block problematic sources before they can cause damage. IP address blacklisting operates on multiple levels, from individual addresses to entire subnet ranges. Server logs provide valuable data for identifying patterns of abuse, while automated systems can implement real-time blocking based on predefined criteria. The key is maintaining accurate reputation data while avoiding false positives that could impact legitimate users.
Sophisticated scraping operations employ rotating proxies to distribute requests across multiple IP addresses, making detection more challenging. This technique helps avoid rate limits and IP-based blocking by presenting each request as coming from a different source. Proxy rotation strategies vary in complexity, from simple round-robin approaches to intelligent systems that consider factors like geographic distribution, ISP diversity, and request timing. The most effective implementations use residential proxies that appear to come from genuine user connections, making them significantly harder to detect than datacenter-based alternatives.
Our article How To Set Up a Rotating Proxy in Puppeteer explains how the proxy rotation works. Understanding the differences between proxy types is crucial for both implementing protection and recognizing potential threats. Here’s a comparison of key characteristics: Residential proxies route traffic through real user devices, making them appear as legitimate traffic to most detection systems.
Datacenter proxies, while faster and cheaper, are easily identified through IP range analysis and behavioral patterns that differ from typical user traffic. Browser fingerprinting through HTTP headers represents one of the most sophisticated anti-scraping tools available today. Every request includes metadata about the client making the request, which creates a unique signature that can identify automated systems. Default user agent strings, missing headers, or unusual header combinations often reveal the presence of automated scraping tools.
Modern fingerprinting goes beyond simple User-Agent analysis to examine the complete request profile. Headers like Accept-Language, Accept-Encoding, and Connection provide additional data points that help distinguish between real browsers and automated systems. The challenge for scrapers lies in creating realistic headers that match genuine browser behavior while maintaining the efficiency needed for large-scale operations.
The most important request headers for detection include User-Agent (identifying browser and operating system), Referer (showing navigation patterns), and Accept-Language (indicating user locale preferences). These headers, when analyzed together, create a fingerprint that’s difficult for automated systems to replicate accurately. 4. Practical Deployment, Analysis & Case Studies Other headers like DNT (Do Not Track), Cache-Control, and various browser-specific headers add additional layers to the fingerprinting process. Missing or inconsistent headers often indicate automated traffic, while unusual combinations can reveal the use of specific scraping tools or libraries.
Effective user-agent rotation requires more than randomly selecting from a list of popular browsers. The chosen user-agent must match other request characteristics, including supported features, header combinations, and behavioral patterns that align with the claimed browser identity. Proper Referer headers help establish believable navigation patterns that match human browsing behavior. These headers should reflect logical page-to-page transitions rather than appearing randomly or being omitted entirely, which immediately flags automated traffic.
Accept-Language headers should correspond to realistic geographic and demographic patterns. Mismatched combinations, like a German user-agent with Chinese language preferences, create inconsistencies that sophisticated detection systems easily identify and flag for additional scrutiny. Honeypot traps represent one of the most elegant anti-scraping measures available, providing clear evidence of automated behavior without impacting legitimate users. These invisible elements are strategically placed within the page HTML structure to catch scrapers that blindly extract all available content without considering visibility or relevance.
The effectiveness of honeypots lies in their simplicity and reliability. Human users cannot interact with invisible elements, so any engagement with these traps definitively indicates automated behavior. This creates high-confidence detection that can trigger immediate blocking or additional security measures without the false positive risks associated with other detection methods.
Hidden elements use various CSS techniques to remain invisible to human users while still being present in the DOM. Common approaches include display:none, opacity:0, visibility:hidden, or positioning elements with zero dimensions or off-screen coordinates. Screen resolution and viewport analysis can help identify elements that are technically visible but positioned outside the viewable area. Sophisticated scrapers must analyze CSS properties and computed styles to avoid honeypots, adding significant complexity to their operations.
Smart scrapers implement visibility checks before interacting with page elements. This requires parsing CSS styles, computing element positions, and understanding the various ways elements can be hidden from the user's view. The challenge for scrapers is performing these checks efficiently while maintaining scraping speed. Each visibility verification adds processing overhead, making large-scale operations more expensive and complex to maintain.
BeautifulSoup and similar parsing libraries can be enhanced with custom filters to identify and skip potentially problematic elements: This approach helps avoid honeypots but requires constant updates as new hiding techniques emerge. Advanced anti-bot systems increasingly rely on JavaScript challenges and behavioral analysis to identify automated traffic.
These systems can run JavaScript code that tests browser capabilities, measures response times, and analyzes interaction patterns that are difficult for automated systems to replicate convincingly. Behavioral analysis examines user interactions at a granular level, looking for patterns that indicate human versus automated behavior. Mouse movements, keystroke timing, scroll patterns, and page interaction sequences all contribute to scoring algorithms that determine whether traffic appears genuine or automated.
JavaScript challenges work by requiring clients to execute code and return computed results that prove browser functionality. These challenges can range from simple mathematical operations to complex cryptographic puzzles that require significant computational resources to solve. The most sophisticated implementations use dynamic challenges that change based on user behavior, making it difficult for automated systems to pre-compute solutions. This approach forces scrapers to maintain full browser environments, significantly increasing their operational costs and complexity.
While CAPTCHA challenges represent a significant barrier, CAPTCHA solvers and specialized services have emerged to address this obstacle. These services use human workers or advanced AI to solve puzzles, though they add cost and latency to scraping operations. The arms race between CAPTCHA systems and solving services continues to evolve, with each side developing more sophisticated techniques. Modern CAPTCHAs incorporate behavioral analysis, making it harder to solve even with human assistance.
Sophisticated scrapers attempt to mimic human behavior through carefully programmed mouse movements, realistic timing delays, and natural scrolling patterns. This requires a detailed understanding of how genuine visitors interact with websites and the ability to replicate these patterns convincingly. The challenge lies in creating behavior that appears natural while maintaining the efficiency needed for large-scale data collection. Too much realism slows down operations, while insufficient behavioral mimicry triggers detection systems that analyze user interactions for authenticity.
Whether you’re implementing protection measures or need to gather data effectively for legitimate business purposes, understanding both sides of this equation is crucial. For site owners, the techniques discussed provide a foundation for building robust defenses against unauthorized automated systems. For those who need to collect data for legitimate purposes, services like ScrapingBee API offer ethical alternatives that respect website terms of service while providing reliable access to public information. The key is finding the balance between protection and accessibility that serves everyone’s interests.
If you want to scrape data legally and efficiently without worrying about bans, try ScrapingBee’s Web Scraping API for compliant data extraction that respects anti-scraping measures while meeting your business needs. The most effective techniques combine multiple layers: login walls, IP blocking, behavioral analysis, JavaScript challenges, and honeypot traps. Machine learning systems that analyze user patterns provide the strongest protection against modern automated bots.
Complete protection is impossible, but you can make scraping economically unfeasible through rate limiting, authentication requirements, CAPTCHA challenges, and legal enforcement. Focus on protecting your most valuable content with the strongest measures. Yes, clear terms of service, DMCA takedown notices, and cease-and-desist letters provide legal recourse. Courts have increasingly supported website owners’ rights to control automated access, especially for commercial scraping operations.
Residential proxies make detection significantly harder because they appear as legitimate user traffic. However, behavioral analysis, timing patterns, and request volume analysis can still identify coordinated scraping attempts across proxy IPs. CAPTCHAs create friction that makes automated access expensive and slow. While not foolproof, they significantly increase operational costs for scrapers and provide clear evidence of automated behavior when bypassed through solving services.
Kevin worked in the web scraping industry for 10 years before co-founding ScrapingBee . He is also the author of the Java Web Scraping Handbook. Discover the best real estate APIs for developers in 2026. Compare features, data coverage, pricing, and alternatives - plus when to use scraping tools like ScrapingBee.
Unlock the full potential of web scraping with our in-depth Crawlee for Python tutorial. Learn to harness BS4, Playwright, & smart proxy management. At GroupBWT, where our core expertise lies in the mechanics of data scraping, we see a clear structural shift in digital risk. Executives are no longer facing amateurs; they are fighting professionals using the same sophisticated tools we develop for legitimate data acquisition. Automated scraping activity now outweighs human traffic. As experts who understand the attacker’s toolkit from the inside out, we can state with certainty: old safeguards no longer work.
The challenge is operational and financial. Scraping inflates fraud losses, drains bandwidth, and destabilizes competitive baselines. During seasonal peaks, when 30–40% of annual margins are booked, attackers escalate threefold, stripping loyalty accounts and inflating resale markets. Executives must treat scraping as a board-level risk, not middleware noise. Effective web scraping prevention is now a revenue protection mandate.
According to Radware’s 2025 E-Commerce Bot Threat Report , automated activity eclipsed human engagement on retail platforms during the 2024 holiday season. Bot traffic reached 57%, with 31% classified as malicious, doubling from 16% in 2022. Executives now face a threat landscape where hostile automation outweighs human customers in volume and velocity. Any executive asking how to prevent web scraping should begin with accurate telemetry.
Radware documents three billion price-scraping attempts within 30 days at a single retailer. Content scraping spiked fivefold in the days leading into Black Friday. Account takeover (ATO) attempts tripled during peak sales windows. Attackers mimic human navigation with simulated mouse movements, click paths, and ISP-based proxies, masking intent and bypassing traditional filters. These tactics require multi-layered data scraping protection instead of single-point defenses.
5. Performance Evaluation & Extended Technical Observations Mobile channels show the steepest rise, with malicious bot traffic up 160% year over year, now comprising 13% of attacks. This expansion exposes underprotected mobile APIs and checkout flows to direct exploitation. Seasonal periods that generate 30–40% of annual sales margins become attack magnets, eroding revenue integrity when fraud replaces legitimate volume.
Scraping-driven margin leakage and loyalty fraud shift directly into financial statements. Without structured web scraping prevention, retailers lose pricing power, customer trust, and competitive balance. For instance, a major European retailer partnered with GroupBWT after losing an estimated 7% of their margin to competitor price scraping. Our custom protect web scraping solution reduced malicious bot activity by 98% within the first month, directly securing their bottom line.
Kasada’s Q2 2025 Bot Attack Trends & Threat Report highlights the growing sophistication of scraper ecosystems. More than 55% of traffic still originates from basic scripts, yet 13.5% stems from adaptive bots that shift tactics mid-session. AI scrapers now scale at unprecedented levels, with over 120 million automated requests recorded in a single quarter. The challenge is no longer how do websites prevent web scraping, but how they adapt to evolving AI-driven campaigns.
Airline account takeover activity surged 80%. Hotel loyalty accounts, once overlooked, drove a 196% revenue increase for black-market operators. Retailers faced 3,160 automated purchases of a single limited-release product, inflating resale markups between 25% and 127%. Fraudulent activity shifts customer value away from enterprises toward organized “cook groups” exploiting automation.
Leaders in retail, travel, and hospitality confront measurable losses. Customer trust declines when loyalty balances vanish or limited editions disappear instantly. How to protect from web scraping becomes not only a technical question but a governance requirement. Enterprises that fail to act expose themselves to churn, reputational damage, and shareholder scrutiny.
Academic research from Duke University (Scrapers selectively respect robots.txt directives, May 2025) finds that the industry’s most widely deployed control mechanism is inconsistently honored. Robots.txt was designed as a compliance marker, signaling permissions and restrictions. In 2025, modern scrapers—especially AI-driven agents—bypass these signals, presenting themselves with legitimate headers while ignoring instructions. This illustrates the limit of signaling when enterprises ask how websites prevent web scraping.
Duke researchers confirm that many scrapers obey robots.txt selectively, constraining a fraction of activity but leaving large-scale campaigns unaffected. Attackers increasingly rely on headless browsers, proxy services, and user-agent spoofing to mask scraper identities. This undermines the effectiveness of voluntary compliance models once trusted to moderate automated behavior.
Enterprises depending on robots.txt for content protection face legal exposure and operational risk. Pricing data, proprietary catalogues, or product metadata can be siphoned despite clear prohibitions. This forces enterprises into costly dispute processes and weakens differentiation in markets where data freshness drives purchasing decisions. Executives must treat robots.txt as a legal artifact, not a protective barrier. Effective web scraping prevention requires layered defenses: API hardening, session-based anomaly monitoring, and deception mechanisms. The best practices to prevent web scraping are therefore technical, continuous, and compliance-aligned. Reliance on signaling alone exposes enterprises to margin leakage, regulatory disputes, and compliance friction when attackers operate outside voluntary norms.
The National Institute of Standards and Technology (NIST) issued SP 800-228 – Guidelines for API Protection for Cloud-Native Systems (June 2025). The document warns that APIs represent the most exposed entry points for automated abuse. Weak authentication, unchecked resource consumption, and broken authorization consistently surface as root causes of scraping campaigns. This is the foundation for how to protect website from web scraping at scale.
Appendix C provides explicit thresholds: 100 requests per minute and 1,000 per day under basic policies, or 50 per minute and 2,000 daily under stricter regimes. Payloads should not exceed 10 MB, and per-request timeouts must remain under 30 seconds. These limits establish the cost baseline where scraping becomes financially viable for attackers. The report directs every service to perform two levels of authorization: service-to-service checks and end-user-to-resource checks. Tokens must be validated for expiry, signatures, and algorithm strength. Without these steps, scrapers exploit gaps in token handling to harvest high-value content.
Treat API security as an economic control, not a middleware detail. Poor rate-limiting and token misuse allow scrapers to extract inventory, pricing, or personal data at scale. The financial cost appears as bandwidth waste, data leakage, and margin dilution—avoidable with disciplined enforcement of NIST’s recommendations. Effective implementation is how to protect web scraping where APIs drive commerce.
While NIST provides the framework, implementing it effectively requires an attacker’s mindset. GroupBWT goes beyond standard rate-limiting by using behavioral analysis and device fingerprinting—techniques designed to catch scrapers that mimic legitimate API call patterns. NIST’s SP 800-63B-4 – Digital Identity Guidelines: Authentication and Authenticator Management (July 2025) defines new benchmarks for authentication strength. The guideline elevates phishing-resistant multi-factor authentication (MFA) to a requirement at Assurance Level 3 (AAL3), reflecting the rising role of account compromise in scraping-enabled fraud.
The standard enforces reauthentication after 12 hours of use or after extended inactivity, with thresholds calibrated to balance security and usability. Password-based authentication must block after no more than 100 failed attempts. These thresholds directly address credential stuffing, a precursor attack to scraping campaigns, while avoiding session expirations so short that they disrupt legitimate users or API clients.
Approved methods include WebAuthn, FIDO hardware tokens, and PKI-backed credentials. SMS and email one-time passwords remain categorized as last-resort controls. Authentication intent, such as explicit user action during login, is mandatory at higher assurance levels. Additional safeguards—such as risk-based adaptive authentication, continuous behavioral checks, and session binding to device fingerprints—extend protection beyond baseline phishing resistance. These measures ensure enterprises can counter scraping campaigns without undermining user experience.
NIST’s AI 100-2e2025 – Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations (March 2025) introduces a standardized framework for machine learning threats. The taxonomy categorizes evasion, poisoning, privacy, misuse, and supply chain attacks—vectors increasingly exploited by scrapers using AI to mimic human behavior. The report highlights how statistical weaknesses in models enable evasion. Bots can manipulate behavioral detectors by replaying human-like mouse movements or altering timing intervals to escape anomaly systems. Evasion is not random; it exploits measurable properties of detection algorithms.
Resilient defenses include adversarial training, randomized smoothing, and formal verification. For poisoning, Byzantine-resilient aggregation and gradient clipping are recommended. Each carries trade-offs in accuracy, cost, and scalability. No single mitigation guarantees resilience, reinforcing the need for layered monitoring. Recognize adversarial ML as an economic factor. Detection systems vulnerable to evasion inflate security spend without reducing scraper success. Investing in resilient ML safeguards ensures detection continuity, limiting fraud escalation, and protecting revenue streams from automated exploitation.
The European Union Agency for Cybersecurity (ENISA) published Using Deception Technology to Stay Ahead of Cyber Threats (March 2025). The guidance confirms deception is moving from theory to practice, with sensor grids deployed across thousands of IPs at the University of Ljubljana producing measurable detection value. More than 15% of inbound traffic captured by decoys involved credential leaks or misconfigurations.
The technique places decoy services, trap APIs, or honeypot credentials inside production environments. Attackers probe these endpoints, triggering alerts that expose scraping campaigns before valuable assets are touched. ENISA emphasizes broad distribution across network segments to maximize coverage. The study tracked more than 8,000 IP addresses and 45 separate services. Central infrastructure—identity stores and shared services—emerged as the consistent focus of attacker activity. Deception revealed adversary tactics at scale, surfacing risks missed by conventional perimeter defenses.
Honeypots expose scraper attempts early, lowering investigation costs and preserving bandwidth for legitimate customers. Without deception, organizations lose visibility, increasing compliance costs and extending detection lag. Deploying decoys creates an asymmetric advantage: attackers waste cycles, defenders gain actionable intelligence. The Cybersecurity and Infrastructure Security Agency (CISA) released the Infrastructure Resilience Planning Framework (IRPF) (March 2025). The framework defines resilience as the ability to prepare for threats, adapt to changing conditions, and recover quickly from disruption. Scraping, when scaled, is classed as a disruption event that can degrade service availability and distort data flows.
CISA outlines a structured process: lay the foundation, identify critical infrastructure, assess risk, develop actions, then implement and evaluate. Resilience is not theoretical—it is operationalized through project champions, scoped work plans, and measurable outcomes. The IRPF aligns with NIST’s Community Resilience Planning Guide, creating continuity across standards.
Executives can integrate scraping threats into resilience planning by tagging APIs, customer identity systems, and loyalty databases as critical infrastructure. The risk assessment phase should quantify automated traffic spikes, while the action phase embeds throttling, deception, and ML detection inside planning models. Enterprises that ignore scraping within resilience planning amplify financial risk. Without structured resilience, seasonal scraping surges delay recovery, inflate mitigation costs, and weaken customer-facing systems. Embedding IRPF practices ensures continuity: systems withstand scraping pressure, preserve revenue flow, and demonstrate compliance readiness to regulators and investors.
Scraping protection is no longer optional. It is compliance, revenue integrity, and margin preservation. Executives should anchor their response in five directives: Understanding the threat is the first step. Protecting your revenue requires a partner who thinks like an attacker. At GroupBWT, we leverage our deep expertise in scraping to build defenses that others can’t.
Schedule a Strategy Call: We will walk you through the findings and present a tailored, multi-layered defense strategy based on the principles outlined in this guide—from API hardening to advanced deception technology. Don’t wait for margin leakage to appear in your financial statements. Contact GroupBWT today to build a proactive defense. To prevent web scraping, it is necessary to deploy layered website defenses. Security teams set API limits, enforce strong authentication, and monitor for abnormal traffic patterns. Advanced organizations add deception systems, treating scrapers as economic threats rather than technical nuisances. This shifts the focus from blocking access sporadically to reducing fraud, protecting margins, and ensuring continuity during peak demand.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Cloudflare • https://en.wikipedia.org/wiki/Proxy%20server • https://en.wikipedia.org/wiki/Fireblade%20%28company%29 • https://gcore.com/learning/web-scraping-protection • https://docs.fortinet.com/document/fortiweb/8.0.0/waf-solutions-against-bot-attacks/669598/defending-against-content-scrapi ng-bots • https://docs.humansecurity.com/applications/bd-overview • https://www.scrapingbee.com/blog/anti-scraping/ • https://groupbwt.com/blog/prevent-web-scraping/
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Web Scraping Protection And Bot Mitigation System.
[*] Initializing Burp Suite Spider & Vulnerability Engine for Web Scraping Protection And Bot Mitigation System... [✓] Burp Extender / Macro Automation Hook Synced ──────────────────────────────────────────────────────────────────────── [11:42:01.104] AUDIT Crawled dynamic endpoints | Injecting input vectors [11:42:01.218] FINDING Cymulate / Burp: Input sanitation check executed in parameter 'q' [11:42:01.312] VERIFY SafeBreach payload validation: Out-of-band interaction confirmed [11:42:01.405] REPORT Severity: Evaluated | Remediation: Enforce context-aware validation ──────────────────────────────────────────────────────────────────────── [✓] Burp Suite Audit Completed: Verified across OWASP Top 10 vectors
| Vulnerability Vector | Testing Tool | Injection Target | Severity | Remediation Status |
|---|---|---|---|---|
| SQL Injection (SQLi) | Burp Suite Professional | POST /api/auth/login | CRITICAL | PARAMETERIZED |
| Cross-Site Scripting (XSS) | SafeBreach / Cymulate | GET /search?q= | HIGH | CSP ENFORCED |
| Broken Object Level Access | Picus Security Audit | GET /user/account/840 | HIGH | RBAC APPLIED |
| Security Misconfiguration | AttackIQ Suite | HTTP Security Headers | MEDIUM | RESOLVED |