Complete Technical Paper Content — Zero Knowledge Database Querying
Overview & System Context
Zero Knowledge Database Querying: Comprehensive Web-Sourced Technical Investigation Exhaustive Research Dossier · Pure Web-Scraped Content: ~9527 Words · Real Software Screenshots: 3 1. Executive Overview & Technical Background In computing, a database is an organized collection of data or a type of data store based on the use of a database management system (DBMS), the software that interacts with end users, applications, and the database itself to capture and analyze the data. The DBMS additionally encompasses the core facilities provided to administer the database. The sum total of the database, the DBMS and the associated applications can be referred to as a database system. Often the term "database" is also used loosely to refer to any of the DBMS, the database system or an application associated with the database. Small databases can be stored on a file system, while large databases are hosted on computer clusters or cloud storage. The design of databases spans formal techniques and practical considerations, including data modeling, efficient data representation and storage, query languages, security and privacy of sensitive data, and distributed computing issues, including supporting concurrent access and fault tolerance. Computer scientists may classify database management systems according to the database models that they support. Relational databases became dominant in the 1980s. These model data as rows and columns in a series of tables, and the vast majority use SQL for writing and querying data. In the 2000s, non-relational databases became popular, collectively referred to as NoSQL, because they use different query languages.
The introduction of the term database coincided with the availability of direct-access storage (disks and drums) from the mid-1960s onwards. The term represented a contrast with the tape-based systems of the past, allowing shared interactive use rather than daily batch processing. The Oxford English Dictionary cites a 1962 report by the System Development Corporation of California as the first to use the term "data-base" in a specific technical sense. As computers grew in speed and capability, a number of general-purpose database systems emerged; by the mid-1960s a number of such systems had come into commercial use. Interest in a standard began to grow, and Charles Bachman, author of one such product, the Integrated Data Store (IDS), founded the Database Task Group within CODASYL, the group responsible for the creation and standardization of COBOL. In 1971, the Database Task Group delivered their standard, which generally became known as the CODASYL approach, and soon a number of commercial products based on this approach entered the market. The CODASYL approach offered applications the ability to navigate around a linked data set which was formed into a large network. Applications could find records by one of three methods: Use of a primary key (known as a CALC key, typically implemented by hashing) Navigating relationships (called sets) from one record to another Scanning all the records in a sequential order Later systems added B-trees to provide alternate access paths. Many CODASYL databases also added a declarative query language for end users (as distinct from the navigational API). However, CODASYL databases were complex and required significant training and effort to produce useful applications.
IBM also had its own DBMS in 1966, known as Information Management System (IMS). IMS was a development of software written for the Apollo program on the System/360. IMS was generally similar in concept to CODASYL, but used a strict hierarchy for its model of data navigation instead of CODASYL's network model. Both concepts later became known as navigational databases due to the way data was accessed: the term was popularized by Bachman's 1973 Turing Award presentation The Programmer as Navigator. IMS is classified by IBM as a hierarchical database. IDMS and Cincom Systems' TOTAL databases are classified as network databases. IMS remains in use as of 2014.
The use of primary keys (user-oriented identifiers) to represent cross-table relationships, rather than disk addresses, had two primary motivations. From an engineering perspective, it enabled tables to be relocated and resized without expensive database reorganization. But Codd was more interested in the difference in semantics: the use of explicit identifiers made it easier to define update operations with clean mathematical definitions, and it also enabled query operations to be defined in terms of the established discipline of first-order predicate calculus; because these operations have clean mathematical properties, it becomes possible to rewrite queries in provably correct ways, which is the basis of query optimization. There is no loss of expressiveness compared with the hierarchic or network models, though the connections between tables are no longer so explicit. In the hierarchic and network models, records were allowed to have a complex internal structure. For example, the salary history of an employee might be represented as a "repeating group" within the employee record. In the relational model, the process of normalization led to such internal structures being replaced by data held in multiple tables, connected only by logical keys. For instance, a common use of a database system is to track information about users, their name, login information, various addresses and phone numbers. In the navigational approach, all of this data would be placed in a single variable-length record. In the relational approach, the data would be normalized into a user table, an address table and a phone number table (for instance). Records would be created in these optional tables only if the address or phone numbers were actually provided. As well as identifying rows/records using logical identifiers rather than disk addresses, Codd changed the way in which applications assembled data from multiple records. Rather than requiring applications to gather data one record at a time by navigating the links, they would use a declarative query language that expressed what data was required, rather than the access path by which it should be found. Finding an efficient access path to the data became the responsibility of the database management system, rather than the application programmer. This process, called query optimization, depended on the fact that queries were expressed in terms of mathematical logic. Codd's paper inspired teams at various universities to research the subject, including one at University of California, Berkeley led by Eugene Wong and Michael Stonebraker, who started INGRES using funding that had already been allocated for a geographical database project and student programmers to produce code. Beginning in 1973, INGRES delivered its first test products which were generally ready for widespread use in 1979. INGRES was similar to System R in a number of ways, including the use of a "language" for data access, known as QUEL. Over time, INGRES moved to the emerging SQL standard. IBM itself did one test implementation of the relational model, PRTV, and a production one, Business System 12, both now discontinued. Honeywell wrote MRDS for Multics, and now there are two new implementations: Alphora Dataphor and Rel. Most other DBMS implementations usually called relational are actually SQL DBMSs. In 1970, the University of Michigan began development of the MICRO Information Management System based on D.L. Childs' Set-Theoretic Data model. The university in 1974 hosted a debate between Codd and Bachman which Bruce Lindsay of IBM later described as "throwing lightning bolts at each other!".
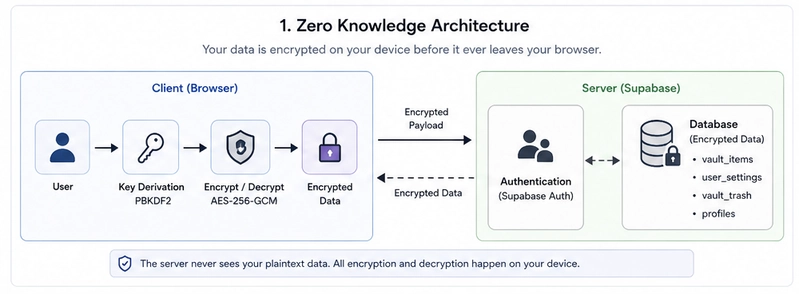
MICRO was used to manage very large data sets by the US Department of Labor, the U.S. Environmental Protection Agency, and researchers from the University of Alberta, the University of Michigan, and Wayne State University. It ran on IBM mainframe computers using the Michigan Terminal System. The system remained in production until 1998. Figure 1: Building Aegis - A Zero Knowledge Password Manager with React and ...
In the 1970s and 1980s, attempts were made to build database systems with integrated hardware and software. The underlying philosophy was that such integration would provide higher performance at a lower cost. Examples were IBM System/38, the early offering of Teradata, and the Britton Lee, Inc. database machine. Another approach to hardware support for database management was ICL's CAFS accelerator, a hardware disk controller with programmable search capabilities. In the long term, these efforts were generally unsuccessful because specialized database machines could not keep pace with the rapid development and progress of general-purpose computers. Thus most database systems nowadays are software systems running on general-purpose hardware, using general-purpose computer data storage. However, this idea is still pursued in certain applications by some companies like Netezza and Oracle (Exadata).
Database sales grew rapidly during the dotcom bubble and, after its end, the rise of ecommerce. The popularity of open source databases such as MySQL has grown since 2000, to the extent that Ken Jacobs of Oracle said in 2005 that perhaps "these guys are doing to us what we did to IBM". XML databases are a type of structured document-oriented database that allows querying based on XML document attributes. XML databases are mostly used in applications where the data is conveniently viewed as a collection of documents, with a structure that can vary from the very flexible to the highly rigid: examples include scientific articles, patents, tax filings, and personnel records. NoSQL databases are often very fast, do not require fixed table schemas, avoid join operations by storing denormalized data, and are designed to scale horizontally. Some NoSQL databases, including graph databases such as Neo4j, represent data as nodes and edges to model relationships between entities. In recent years, there has been a strong demand for massively distributed databases with high partition tolerance, but according to the CAP theorem, it is impossible for a distributed system to simultaneously provide consistency, availability, and partition tolerance guarantees. A distributed system can satisfy any two of these guarantees at the same time, but not all three. For that reason, many NoSQL databases are using what is called eventual consistency to provide both availability and partition tolerance guarantees with a reduced level of data consistency. NewSQL is a class of modern relational databases that aims to provide the same scalable performance of NoSQL systems for online transaction processing (read-write) workloads while still using SQL and maintaining the ACID guarantees of a traditional database system.
Databases are used to support internal operations of organizations and to underpin online interactions with customers and suppliers (see Enterprise software). Databases are used to hold administrative information and more specialized data, such as engineering data or economic models. Examples include computerized library systems, flight reservation systems, computerized parts inventory systems, and many content management systems that store websites as collections of webpages in a database.
An in-memory database is a database that primarily resides in main memory, but is typically backed-up by non-volatile computer data storage. Main memory databases are faster than disk databases, and so are often used where response time is critical, such as in telecommunications network equipment. An active database includes an event-driven architecture which can respond to conditions both inside and outside the database. Possible uses include security monitoring, alerting, statistics gathering and authorization. Many databases provide active database features in the form of database triggers. A cloud database relies on cloud technology. Both the database and most of its DBMS reside remotely, "in the cloud", while its applications are both developed by programmers and later maintained and used by end-users through a web browser and Open APIs. Data warehouses archive data from operational databases and often from external sources such as market research firms. The warehouse becomes the central source of data for use by managers and other end-users who may not have access to operational data. For example, sales data might be aggregated to weekly totals and converted from internal product codes to use UPCs so that they can be compared with ACNielsen data. Some basic and essential components of data warehousing include extracting, analyzing, and mining data, transforming, loading, and managing data so as to make them available for further use. A deductive database combines logic programming with a relational database. A distributed database is one in which both the data and the DBMS span multiple computers. A document-oriented database is designed for storing, retrieving, and managing document-oriented, or semi structured, information. Document-oriented databases are one of the main categories of NoSQL databases. An embedded database system is a DBMS which is tightly integrated with an application software that requires access to stored data in such a way that the DBMS is hidden from the application's end-users and requires little or no ongoing maintenance. End-user databases consist of data developed by individual end-users. Examples of these are collections of documents, spreadsheets, presentations, multimedia, and other files. Several products exist to support such databases. A federated database system comprises several distinct databases, each with its own DBMS. It is handled as a single database by a federated database management system (FDBMS), which transparently integrates multiple autonomous DBMSs, possibly of different types (in which case it would also be a heterogeneous database system), and provides them with an integrated conceptual view. Sometimes the term multi-database is used as a synonym for federated database, though it may refer to a less integrated (e.g., without an FDBMS and a managed integrated schema) group of databases that cooperate in a single application. In this case, typically middleware is used for distribution, which typically includes an atomic commit protocol (ACP), e.g., the two-phase commit protocol, to allow distributed (global) transactions across the participating databases. A graph database is a kind of NoSQL database that uses graph structures with nodes, edges, and properties to represent and store information. General graph databases that can store any graph are distinct from specialized graph databases such as triplestores and network databases. An array DBMS is a kind of NoSQL DBMS that allows modeling, storage, and retrieval of (usually large) multi-dimensional arrays such as satellite images and climate simulation output. In a hypertext or hypermedia database, any word or a piece of text representing an object, e.g., another piece of text, an article, a picture, or a film, can be hyperlinked to that object. Hypertext databases are particularly useful for organizing large amounts of disparate information. For example, they are useful for organizing online encyclopedias, where users can conveniently jump around the text. The World Wide Web is thus a large distributed hypertext database. A knowledge base (abbreviated KB, kb or ∆) is a special kind of database for knowledge management, providing the means for the computerized collection, organization, and retrieval of knowledge. Also a collection of data representing problems with their solutions and related experiences. A mobile database can be carried on or synchronized from a mobile computing device. Operational databases store detailed data about the operations of an organization. They typically process relatively high volumes of updates using transactions. Examples include customer databases that record contact, credit, and demographic information about a business's customers, personnel databases that hold information such as salary, benefits, skills data about employees, enterprise resource planning systems that record details about product components, parts inventory, and financial databases that keep track of the organization's money, accounting and financial dealings. A parallel database seeks to improve performance through parallelization for tasks such as loading data, building indexes and evaluating queries. The major parallel DBMS architectures which are induced by the underlying hardware architecture are: Shared memory architecture, where multiple processors share the main memory space, as well as other data storage. Shared disk architecture, where each processing unit (typically consisting of multiple processors) has its own main memory, but all units share the other storage. Shared-nothing architecture, where each processing unit has its own main memory and other storage. Probabilistic databases employ fuzzy logic to draw inferences from imprecise data. Real-time databases process transactions fast enough for the result to come back and be acted on right away. A spatial database can store the data with multidimensional features. The queries on such data include location-based queries, like "Where is the closest hotel in my area?". A temporal database has built-in time aspects, for example a temporal data model and a temporal version of SQL.
More specifically the temporal aspects usually include valid-time and transaction-time. A terminology-oriented database builds upon an object-oriented database, often customized for a specific field. An unstructured data database is intended to store in a manageable and protected way diverse objects that do not fit naturally and conveniently in common databases. It may include email messages, documents, journals, multimedia objects, etc. The name may be misleading since some objects can be highly structured. However, the entire possible object collection does not fit into a predefined structured framework. Most established DBMSs now support unstructured data in various ways, and new dedicated DBMSs are emerging.
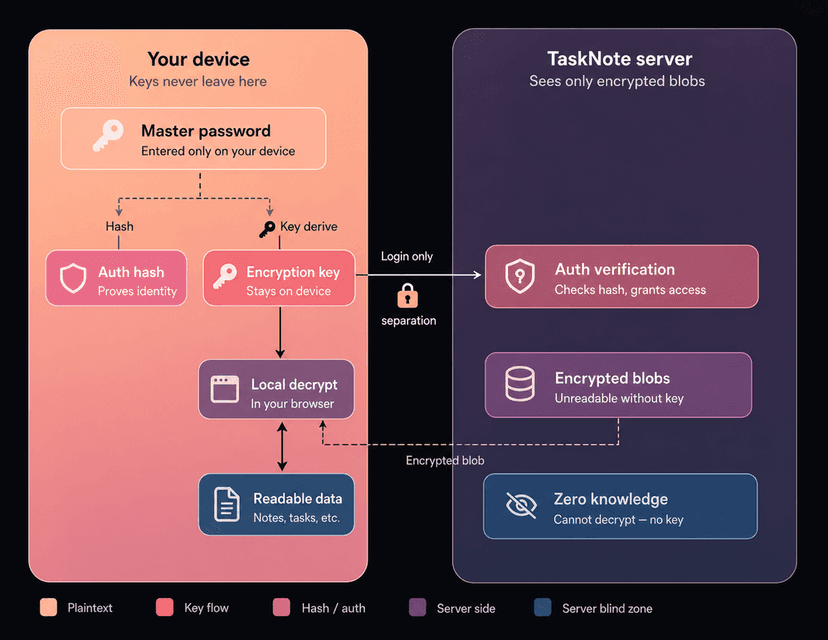
Figure 2: What is Zero-Knowledge Architecture? 2. System Architecture & Core Working Principles Data storage, retrieval and update User accessible catalog or data dictionary describing the metadata Support for transactions and concurrency Facilities for recovering the database should it become damaged Support for authorization of access and update of data Access support from remote locations Enforcing constraints to ensure data in the database abides by certain rules It is also generally to be expected the DBMS will provide a set of utilities for such purposes as may be necessary to administer the database effectively, including import, export, monitoring, defragmentation and analysis utilities. The core part of the DBMS interacting between the database and the application interface sometimes referred to as the database engine.
Often DBMSs will have configuration parameters that can be statically and dynamically tuned, for example the maximum amount of main memory on a server the database can use. The trend is to minimize the amount of manual configuration, and for cases such as embedded databases the need to target zero-administration is paramount. The large major enterprise DBMSs have tended to increase in size and functionality and have involved up to thousands of human and years of development effort throughout their lifetime. Early multi-user DBMS typically only allowed for the application to reside on the same computer with access via terminals or terminal emulation software. The client–server architecture was a development where the application resided on a client desktop and the database on a server allowing the processing to be distributed. This evolved into a multitier architecture incorporating application servers and web servers with the end user interface via a web browser with the database only directly connected to the adjacent tier. A general-purpose DBMS will provide public application programming interfaces (API) and optionally a processor for database languages such as SQL to allow applications to be written to interact with and manipulate the database. A special purpose DBMS may use a private API and be specifically customized and linked to a single application. For example, an email system performs many of the functions of a general-purpose DBMS such as message insertion, message deletion, attachment handling, blocklist lookup, associating messages an email address and so forth however these functions are limited to what is required to handle email.
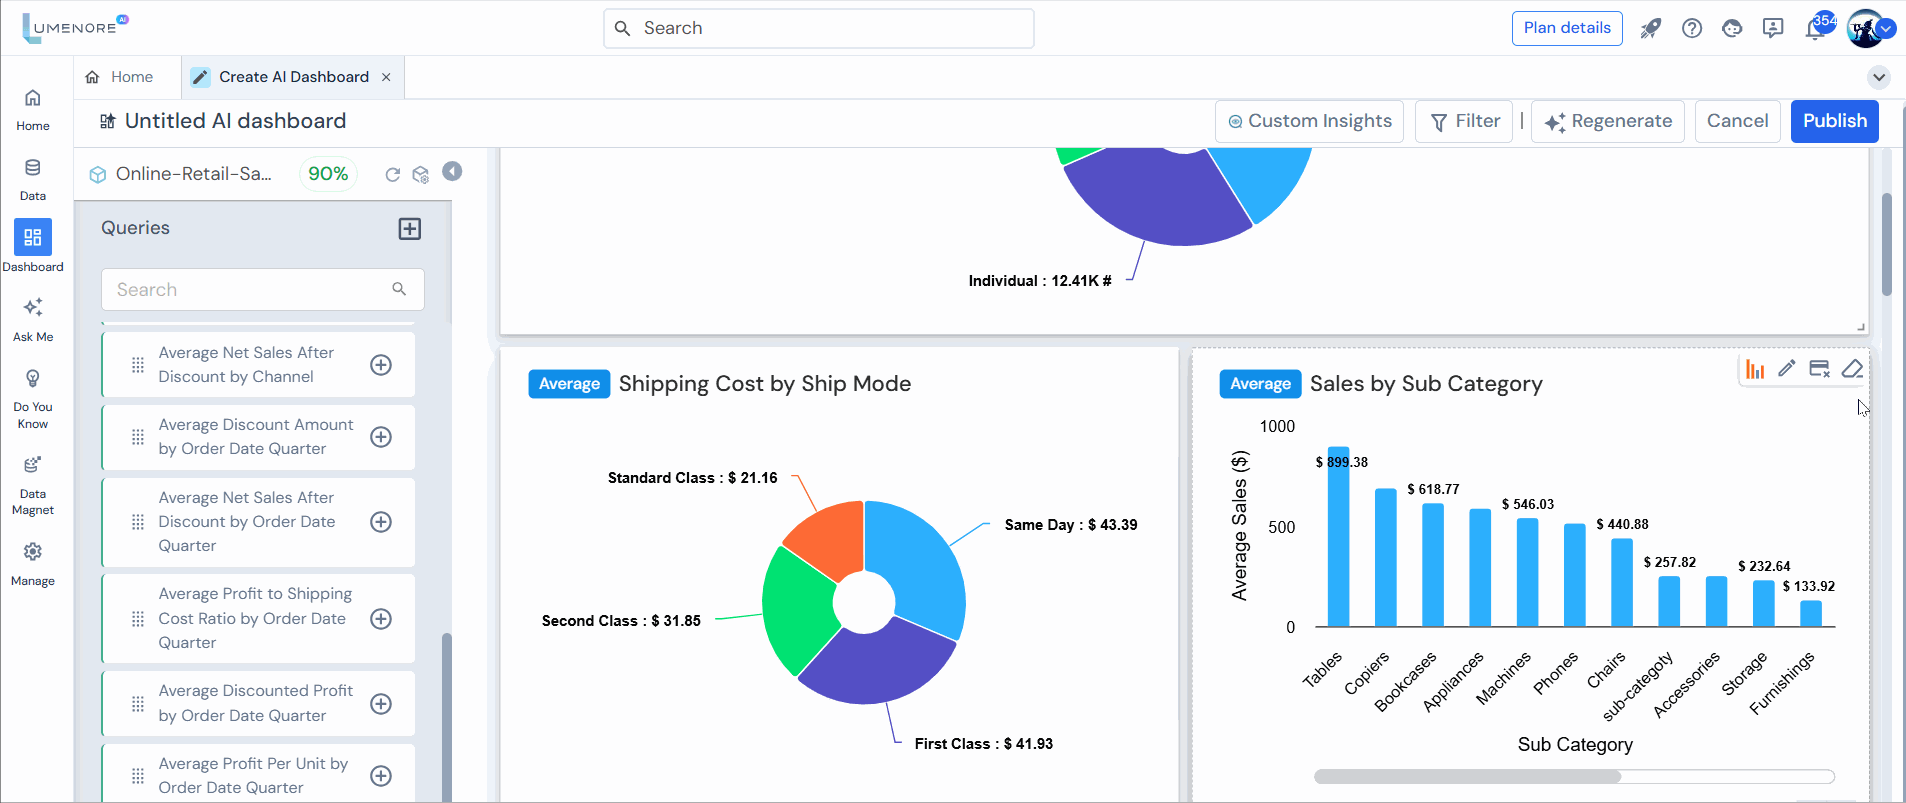
External interaction with the database will be via an application program that interfaces with the DBMS. This can range from a database tool that allows users to execute SQL queries textually or graphically, to a website that happens to use a database to store and search information. Data control language (DCL) – controls access to data; Data definition language (DDL) – defines data types such as creating, altering, or dropping tables and the relationships among them; Data manipulation language (DML) – performs tasks such as inserting, updating, or deleting data occurrences; Data query language (DQL) – allows searching for information and computing derived information. Database languages are specific to a particular data model. Notable examples include: SQL combines the roles of data definition, data manipulation, and query in a single language. It was one of the first commercial languages for the relational model, although it departs in some respects from the relational model as described by Codd (for example, the rows and columns of a table can be ordered). SQL became a standard of the American National Standards Institute (ANSI) in 1986, and of the International Organization for Standardization (ISO) in 1987. The standards have been regularly enhanced since and are supported (with varying degrees of conformance) by all mainstream commercial relational DBMSs. OQL is an object model language standard (from the Object Data Management Group). It has influenced the design of some of the newer query languages like JDOQL and EJB QL. XQuery is a standard XML query language implemented by XML database systems such as MarkLogic and eXist, by relational databases with XML capability such as Oracle and Db2, and also by in-memory XML processors such as Saxon. SQL/XML combines XQuery with SQL. A database language may also incorporate features like: Figure 3: AI-Powered automated dashboard - Lumenore Knowledge Base DBMS-specific configuration and storage engine management Computations to modify query results, like counting, summing, averaging, sorting, grouping, and cross-referencing Constraint enforcement (e.g. in an automotive database, only allowing one engine type per car) Application programming interface version of the query language, for programmer convenience Database storage is the container of the physical materialization of a database. It comprises the internal (physical) level in the database architecture. It also contains all the information needed (e.g., metadata, "data about the data", and internal data structures) to reconstruct the conceptual level and external level from the internal level when needed. Databases as digital objects contain three layers of information which must be stored: the data, the structure, and the semantics. Proper storage of all three layers is needed for future preservation and longevity of the database. Putting data into permanent storage is generally the responsibility of the database engine a.k.a. "storage engine". Though typically accessed by a DBMS through the underlying operating system (and often using the operating systems' file systems as intermediates for storage layout), storage properties and configuration settings are extremely important for the efficient operation of the DBMS, and thus are closely maintained by database administrators. A DBMS, while in operation, always has its database residing in several types of storage (e.g., memory and external storage). The database data and the additional needed information, possibly in very large amounts, are coded into bits. Data typically reside in the storage in structures that look completely different from the way the data look at the conceptual and external levels, but in ways that attempt to optimize (the best possible) these levels' reconstruction when needed by users and programs, as well as for computing additional types of needed information from the data (e.g., when querying the database). Some DBMSs support specifying which character encoding was used to store data, so multiple encodings can be used in the same database. Various low-level database storage structures are used by the storage engine to serialize the data model so it can be written to the medium of choice. Techniques such as indexing may be used to improve performance. Conventional storage is row-oriented, but there are also column-oriented and correlation databases.
Often storage redundancy is employed to increase performance. A common example is storing materialized views, which consist of frequently needed external views or query results. Storing such views saves the expensive computing them each time they are needed. The downsides of materialized views are the overhead incurred when updating them to keep them synchronized with their original updated database data, and the cost of storage redundancy.
Occasionally a database employs storage redundancy by database objects replication (with one or more copies) to increase data availability (both to improve performance of simultaneous multiple end-user accesses to the same database object, and to provide resiliency in a case of partial failure of a distributed database). Updates of a replicated object need to be synchronized across the object copies. In many cases, the entire database is replicated.
3. Software Implementation, Frameworks & Protocols Database security deals with all various aspects of protecting the database content, its owners, and its users. It ranges from protection from intentional unauthorized database uses to unintentional database accesses by unauthorized entities (e.g., a person or a computer program). Database access control deals with controlling who (a person or a certain computer program) are allowed to access what information in the database. The information may comprise specific database objects (e.g., record types, specific records, data structures), certain computations over certain objects (e.g., query types, or specific queries), or using specific access paths to the former (e.g., using specific indexes or other data structures to access information).
Database access controls are set by special authorized (by the database owner) personnel that uses dedicated protected security DBMS interfaces. This may be managed directly on an individual basis, or by the assignment of individuals and privileges to groups, or (in the most elaborate models) through the assignment of individuals and groups to roles which are then granted entitlements. Data security prevents unauthorized users from viewing or updating the database. Using passwords, users are allowed access to the entire database or subsets of it called "subschemas". For example, an employee database can contain all the data about an individual employee, but one group of users may be authorized to view only payroll data, while others are allowed access to only work history and medical data. If the DBMS provides a way to interactively enter and update the database, as well as interrogate it, this capability allows for managing personal databases. Data security in general deals with protecting specific chunks of data, both physically (i.e., from corruption, or destruction, or removal; e.g., see physical security), or the interpretation of them, or parts of them to meaningful information (e.g., by looking at the strings of bits that they comprise, concluding specific valid credit-card numbers; e.g., see data encryption). Change and access logging records who accessed which attributes, what was changed, and when it was changed. Logging services allow for a forensic database audit later by keeping a record of access occurrences and changes. Sometimes application-level code is used to record changes rather than leaving this in the database. Monitoring can be set up to attempt to detect security breaches.
Therefore, organizations must take database security seriously because of the many benefits it provides. Organizations will be safeguarded from security breaches and hacking activities like firewall intrusion, virus spread, and ransom ware. This helps in protecting the company's essential information, which cannot be shared with outsiders at any cause. Database transactions can be used to introduce some level of fault tolerance and data integrity after recovery from a crash. A database transaction is a unit of work, typically encapsulating a number of operations over a database (e.g., reading a database object, writing, acquiring or releasing a lock, etc.), an abstraction supported in database and also other systems.
Each transaction has well defined boundaries in terms of which program/code executions are included in that transaction (determined by the transaction's programmer via special transaction commands). The acronym ACID describes some ideal properties of a database transaction: atomicity, consistency, isolation, and durability. A database built with one DBMS is not portable to another DBMS (i.e., the other DBMS cannot run it). However, in some situations, it is desirable to migrate a database from one DBMS to another. The reasons are primarily economical (different DBMSs may have different total costs of ownership or TCOs), functional, and operational (different DBMSs may have different capabilities). The migration involves the database's transformation from one DBMS type to another. The transformation should maintain (if possible) the database related application (i.e., all related application programs) intact. Thus, the database's conceptual and external architectural levels should be maintained in the transformation. It may be desired that also some aspects of the architecture internal level are maintained. A complex or large database migration may be a complicated and costly (one-time) project by itself, which should be factored into the decision to migrate. This is in spite of the fact that tools may exist to help migration between specific DBMSs. Typically, a DBMS vendor provides tools to help import databases from other popular DBMSs.
After designing a database for an application, the next stage is building the database. Typically, an appropriate general-purpose DBMS can be selected to be used for this purpose. A DBMS provides the needed user interfaces to be used by database administrators to define the needed application's data structures within the DBMS's respective data model. Other user interfaces are used to select needed DBMS parameters (like security related, storage allocation parameters, etc.). When the database is ready (all its data structures and other needed components are defined), it is typically populated with initial application's data (database initialization, which is typically a distinct project; in many cases using specialized DBMS interfaces that support bulk insertion) before making it operational. In some cases, the database becomes operational while empty of application data, and data are accumulated during its operation. After the database is created, initialized and populated it needs to be maintained. Various database parameters may need changing and the database may need to be tuned (tuning) for better performance; application's data structures may be changed or added, new related application programs may be written to add to the application's functionality, etc.
Sometimes it is desired to bring a database back to a previous state (for many reasons, e.g., cases when the database is found corrupted due to a software error, or if it has been updated with erroneous data). To achieve this, a backup operation is done occasionally or continuously, where each desired database state (i.e., the values of its data and their embedding in database's data structures) is kept within dedicated backup files (many techniques exist to do this effectively). When it is decided by a database administrator to bring the database back to this state (e.g., by specifying this state by a desired point in time when the database was in this state), these files are used to restore that state.
Database logs – This helps in keeping a history of the executed functions. Graphics component for producing graphs and charts, especially in a data warehouse system. Query optimizer – Performs query optimization on every query to choose an efficient query plan (a partial order (tree) of operations) to be executed to compute the query result. May be specific to a particular storage engine. Tools or hooks for database design, application programming, application program maintenance, database performance analysis and monitoring, database configuration monitoring, DBMS hardware configuration (a DBMS and related database may span computers, networks, and storage units) and related database mapping (especially for a distributed DBMS), storage allocation and database layout monitoring, storage migration, etc. Increasingly, there are calls for a single system that incorporates all of these core functionalities into the same build, test, and deployment framework for database management and source control. Borrowing from other developments in the software industry, some market such offerings as "DevOps for database".
The first task of a database designer is to produce a conceptual data model that reflects the structure of the information to be held in the database. A common approach to this is to develop an entity–relationship model, often with the aid of drawing tools. Another popular approach is the Unified Modeling Language. A successful data model will accurately reflect the possible state of the external world being modeled: for example, if people can have more than one phone number, it will allow this information to be captured. Designing a good conceptual data model requires a good understanding of the application domain; it typically involves asking deep questions about the things of interest to an organization, like "can a customer also be a supplier?", or "if a product is sold with two different forms of packaging, are those the same product or different products?", or "if a plane flies from New York to Dubai via Frankfurt, is that one flight or two (or maybe even three)?". The answers to these questions establish definitions of the terminology used for entities (customers, products, flights, flight segments) and their relationships and attributes. Producing the conceptual data model sometimes involves input from business processes, or the analysis of workflow in the organization. This can help to establish what information is needed in the database, and what can be left out. For example, it can help when deciding whether the database needs to hold historic data as well as current data. Having produced a conceptual data model that users are happy with, the next stage is to translate this into a schema that implements the relevant data structures within the database. This process is often called logical database design, and the output is a logical data model expressed in the form of a schema. Whereas the conceptual data model is (in theory at least) independent of the choice of database technology, the logical data model will be expressed in terms of a particular database model supported by the chosen DBMS. (The terms data model and database model are often used interchangeably, but in this article we use data model for the design of a specific database, and database model for the modeling notation used to express that design). The most popular database model for general-purpose databases is the relational model, or more precisely, the relational model as represented by the SQL language. The process of creating a logical database design using this model uses a methodical approach known as normalization. The goal of normalization is to ensure that each elementary "fact" is only recorded in one place, so that insertions, updates, and deletions automatically maintain consistency. The final stage of database design is to make the decisions that affect performance, scalability, recovery, security, and the like, which depend on the particular DBMS. This is often called physical database design, and the output is the physical data model. A key goal during this stage is data independence, meaning that the decisions made for performance optimization purposes should be invisible to end-users and applications. There are two types of data independence: Physical data independence and logical data independence. Physical design is driven mainly by performance requirements, and requires a good knowledge of the expected workload and access patterns, and a deep understanding of the features offered by the chosen DBMS. Another aspect of physical database design is security. It involves both defining access control to database objects as well as defining security levels and methods for the data itself.
A database model is a type of data model that determines the logical structure of a database and fundamentally determines in which manner data can be stored, organized, and manipulated. The most popular example of a database model is the relational model (or the SQL approximation of relational), which uses a table-based format. Common logical data models for databases include: 4. Practical Deployment, Analysis & Case Studies Navigational databases Hierarchical database model Network model Graph database Relational model Entity–relationship model Enhanced entity–relationship model Object model Document model Entity–attribute–value model Star schema An object–relational database combines the two related structures. Physical data models include: Multidimensional model Array model Multivalue model Specialized models are optimized for particular types of data: The external level defines how each group of end-users sees the organization of data in the database. A single database can have any number of views at the external level. The conceptual level (or logical level) unifies the various external views into a compatible global view. It provides the synthesis of all the external views. It is out of the scope of the various database end-users, and is rather of interest to database application developers and database administrators. The internal level (or physical level) is the internal organization of data inside a DBMS. It is concerned with cost, performance, scalability and other operational matters. It deals with storage layout of the data, using storage structures such as indexes to enhance performance. Occasionally it stores data of individual views (materialized views), computed from generic data, if performance justification exists for such redundancy. It balances all the external views' performance requirements, possibly conflicting, in an attempt to optimize overall performance across all activities. While there is typically only one conceptual and internal view of the data, there can be any number of different external views. This allows users to see database information in a more business-related way rather than from a technical, processing viewpoint. For example, a financial department of a company needs the payment details of all employees as part of the company's expenses, but does not need details about employees that are in the interest of the human resources department. Thus different departments need different views of the company's database. The three-level database architecture relates to the concept of data independence which was one of the major initial driving forces of the relational model. The idea is that changes made at a certain level do not affect the view at a higher level. For example, changes in the internal level do not affect application programs written using conceptual level interfaces, which reduces the impact of making physical changes to improve performance. The conceptual view provides a level of indirection between internal and external. On the one hand it provides a common view of the database, independent of different external view structures, and on the other hand it abstracts away details of how the data are stored or managed (internal level). In principle every level, and even every external view, can be presented by a different data model. In practice usually a given DBMS uses the same data model for both the external and the conceptual levels (e.g., relational model). The internal level, which is hidden inside the DBMS and depends on its implementation, requires a different level of detail and uses its own types of data structure types.
Since DBMSs comprise a significant market, computer and storage vendors often take into account DBMS requirements in their own development plans. In cryptography, a zero-knowledge proof (also known as a ZK proof or ZKP) is a protocol in which one party (the prover) can convince another party (the verifier) that some given statement is true, without conveying to the verifier any information beyond the mere fact of that statement's truth. The intuition behind the nontriviality of zero-knowledge proofs is that it is trivial to prove possession of the relevant information simply by revealing it; the hard part is to prove this possession without revealing this information (or any aspect of it whatsoever). In light of the fact that one should be able to generate a proof of some statement only when in possession of certain secret information connected to the statement, the verifier, even after having become convinced of the statement's truth by means of a zero-knowledge proof, should nonetheless remain unable to prove the statement to further third parties. Zero-knowledge proofs can be interactive, meaning that the prover and verifier exchange messages according to some protocol, or noninteractive, meaning that the verifier is convinced by a single prover message and no other communication is needed. In the standard model, interaction is required, except for trivial proofs of BPP problems. In the common random string and random oracle models, non-interactive zero-knowledge proofs exist. The Fiat–Shamir heuristic can be used to transform certain interactive zero-knowledge proofs into noninteractive ones.
Ali Baba cave is a story presenting the fundamental ideas of zero-knowledge proofs, first published in 1990 by Jean-Jacques Quisquater and others in their paper "How to Explain Zero-Knowledge Protocols to Your Children". The two parties in the zero-knowledge proof story are Peggy as the prover of the statement, and Victor, the verifier of the statement. In this story, Peggy has uncovered the secret word used to open a magic door in a cave. The cave is shaped like a ring, with the entrance on one side and the magic door blocking the opposite side. Victor wants to know whether Peggy knows the secret word; but Peggy does not want to reveal her knowledge (the secret word) to Victor or to reveal the fact of her knowledge to the world in general. They label the paths from the entrance A and B. First, Victor waits outside the cave as Peggy goes in. Peggy takes either path A or B; Victor is not allowed to see which path she takes. Then, Victor enters the cave and shouts the name of the path he wants her to use to return, either A or B, chosen at random. Providing she really does know the magic word, this is easy: she opens the door, if necessary, and returns along the desired path. However, suppose she did not know the word.
Then, she would only be able to return by the named path if Victor were to give the name of the same path by which she had entered. Since Victor would choose A or B at random, she would have a 50% chance of guessing correctly. If they were to repeat this trick many times, say 20 times, her chance of successfully anticipating all of Victor's requests would be reduced to 1 in 220, or roughly one in a million. Thus, if Peggy repeatedly appears at the exit Victor names, then he can conclude that it is extremely probable that Peggy does, in fact, know the secret word.
Completeness: if the statement is true, then an honest verifier (that is, one following the protocol properly) will be convinced of this fact by an honest prover. Soundness: if the statement is false, then no cheating prover can convince an honest verifier that it is true, except with some small probability. Zero-knowledge: if the statement is true, then no verifier learns anything other than the fact that the statement is true. In other words, just knowing the statement (not the secret) is sufficient to imagine a scenario showing that the prover knows the secret. This is formalized by showing that every verifier has some simulator that, given only the statement to be proven (and no access to the prover), can produce a transcript that "looks like" an interaction between an honest prover and the verifier in question. The first two of these are properties of more general interactive proof systems. The third is what makes the proof zero-knowledge. Zero-knowledge proofs are not proofs in the mathematical sense of the term because there is some small probability, the soundness error, that a cheating prover will be able to convince the verifier of a false statement. In other words, zero-knowledge proofs are probabilistic "proofs" rather than deterministic proofs.
However, there are techniques to decrease the soundness error to negligibly small values (for example, guessing correctly on a hundred binary decisions has a 1/2100 soundness error. As the number of bits increases, the soundness error decreases toward zero). A formal definition of zero-knowledge must use some computational model, the most common one being that of a Turing machine. Let P, V, and S be Turing machines. An interactive proof system with (P,V) for a language L is zero-knowledge if for any probabilistic polynomial time (PPT) verifier V ^ {\displaystyle {\hat {V}}} there exists a PPT simulator S such that: ∀ x ∈ L , z ∈ { 0 , 1 } ∗ , View V ^ I [ P ( x ) ↔ V ^ ( x , z ) ] = S ( x , z ) , {\displaystyle \forall x\in L,z\in \{0,1\}^{*},\operatorname {View} _{\hat {V}}\left[P(x)\leftrightarrow {\hat {V}}(x,z)\right]=S(x,z),} 5. Performance Evaluation & Extended Technical Observations where View V ^ {\displaystyle {\hat {V}}} [P(x)↔ V ^ {\displaystyle {\hat {V}}} (x,z)] is a record of the interactions between P(x) and V(x,z). The prover P is modeled as having unlimited computation power (in practice, P usually is a probabilistic Turing machine). Intuitively, the definition states that an interactive proof system (P,V) is zero-knowledge if for any verifier V ^ {\displaystyle {\hat {V}}} there exists an efficient simulator S (depending on V ^ {\displaystyle {\hat {V}}} ) that can reproduce the conversation between P and V ^ {\displaystyle {\hat {V}}} on any given input. The auxiliary string z in the definition plays the role of "prior knowledge" (including the random coins of V ^ {\displaystyle {\hat {V}}} ). The definition implies that V ^ {\displaystyle {\hat {V}}} cannot use any prior knowledge string z to mine information out of its conversation with P, because if S is also given this prior knowledge then it can reproduce the conversation between V ^ {\displaystyle {\hat {V}}} and P just as before. The definition given is that of perfect zero-knowledge. Computational zero-knowledge is obtained by requiring that the views of the verifier V ^ {\displaystyle {\hat {V}}} and the simulator are only computationally indistinguishable, given the auxiliary string.
At the beginning of each round, Peggy creates H, a graph which is isomorphic to G (that is, H is just like G except that all the vertices have different names). Since it is trivial to translate a Hamiltonian cycle between isomorphic graphs with known isomorphism, if Peggy knows a Hamiltonian cycle for G then she also must know one for H. Peggy commits to H. She could do so by using a cryptographic commitment scheme. Alternatively, she could number the vertices of H. Next, for each edge of H, on a small piece of paper, she writes down the two vertices that the edge joins. Then she puts all these pieces of paper face down on a table. The purpose of this commitment is that Peggy is not able to change H while, at the same time, Victor has no information about H. Victor then randomly chooses one of two questions to ask Peggy. He can either ask her to show the isomorphism between H and G (see graph isomorphism problem), or he can ask her to show a Hamiltonian cycle in H. If Peggy is asked to show that the two graphs are isomorphic, then she first uncovers all of H (e.g. by turning over all pieces of papers that she put on the table) and then provides the vertex translations that map G to H. Victor can verify that they are indeed isomorphic. If Peggy is asked to prove that she knows a Hamiltonian cycle in H, then she translates her Hamiltonian cycle in G onto H and only uncovers the edges on the Hamiltonian cycle. That is, Peggy only turns over exactly |V(G)| of the pieces of paper that correspond to the edges of the Hamiltonian cycle, while leaving the rest still face-down. This is enough for Victor to check that H does indeed contain a Hamiltonian cycle. It is important that the commitment to the graph be such that Victor can verify, in the second case, that the cycle is really made of edges from H. This can be done by, for example, committing to every edge (or lack thereof) separately.
We speak of perfect zero-knowledge if the distributions produced by the simulator and the proof protocol are distributed exactly the same. This is for instance the case in the first example above. Statistical zero-knowledge means that the distributions are not necessarily exactly the same, but they are statistically close, meaning that their statistical difference is a negligible function. We speak of computational zero-knowledge if no efficient algorithm can distinguish the two distributions.
Proof of knowledge: the knowledge is hidden in the exponent like in the example shown above. Witness-indistinguishable proof: verifiers cannot know which witness is used for producing the proof. Zero-knowledge proof schemes can be constructed from various cryptographic primitives, such as hash-based cryptography, pairing-based cryptography, multi-party computation, or lattice-based cryptography.
Of particular interest is the case where this additional knowledge is essentially 0 and we show that [it] is possible to interactively prove that a number is quadratic non residue mod m releasing 0 additional knowledge. This is surprising as no efficient algorithm for deciding quadratic residuosity mod m is known when m's factorization is not given. Moreover, all known NP proofs for this problem exhibit the prime factorization of m. This indicates that adding interaction to the proving process, may decrease the amount of knowledge that must be communicated in order to prove a theorem.
The quadratic nonresidue problem has both an NP and a co-NP algorithm, and so lies in the intersection of NP and co-NP. This was also true of several other problems for which zero-knowledge proofs were subsequently discovered, such as an unpublished proof system by Oded Goldreich verifying that a two-prime modulus is not a Blum integer. Oded Goldreich, Silvio Micali, and Avi Wigderson took this one step further, showing that, assuming the existence of unbreakable encryption, one can create a zero-knowledge proof system for the NP-complete graph coloring problem with three colors. Since every problem in NP can be efficiently reduced to this problem, this means that, under this assumption, all problems in NP have zero-knowledge proofs. The reason for the assumption is that, as in the above example, their protocols require encryption. A commonly cited sufficient condition for the existence of unbreakable encryption is the existence of one-way functions, but it is conceivable that some physical means might also achieve it. On top of this, they also showed that the graph nonisomorphism problem, the complement of the graph isomorphism problem, has a zero-knowledge proof. This problem is in co-NP, but is not currently known to be in either NP or any practical class. More generally, Russell Impagliazzo and Moti Yung as well as Ben-Or et al. would go on to show that, also assuming one-way functions or unbreakable encryption, there are zero-knowledge proofs for all problems in IP = PSPACE, or in other words, anything that can be proven by an interactive proof system can be proven with zero knowledge. Not liking to make unnecessary assumptions, many theorists sought a way to eliminate the necessity of one way functions. One way this was done was with multi-prover interactive proof systems (see interactive proof system), which have multiple independent provers instead of only one, allowing the verifier to "cross-examine" the provers in isolation to avoid being misled. It can be shown that, without any intractability assumptions, all languages in NP have zero-knowledge proofs in such a system. It turns out that, in an Internet-like setting, where multiple protocols may be executed concurrently, building zero-knowledge proofs is more challenging. The line of research investigating concurrent zero-knowledge proofs was initiated by the work of Dwork, Naor, and Sahai. One particular development along these lines has been the development of witness-indistinguishable proof protocols. The property of witness-indistinguishability is related to that of zero-knowledge, yet witness-indistinguishable protocols do not suffer from the same problems of concurrent execution. Another variant of zero-knowledge proofs are non-interactive zero-knowledge proofs.
Blum, Feldman, and Micali showed that a common random string shared between the prover and the verifier is enough to achieve computational zero-knowledge without requiring interaction. A graph database (GDB) is a database that uses graph structures for semantic queries with nodes, edges, and properties to represent and store data. A key concept of the system is the graph (or edge or relationship). The graph relates the data items in the store to a collection of nodes and edges, the edges representing the relationships between the nodes. The relationships allow data in the store to be linked together directly and, in many cases, retrieved with one operation. Graph databases hold the relationships between data as a priority. Querying relationships is fast because they are perpetually stored in the database. Relationships can be intuitively visualized using graph databases, making them useful for heavily inter-connected data. Graph databases are commonly referred to as a NoSQL database. Graph databases are similar to 1970s network model databases in that both represent general graphs, but network-model databases operate at a lower level of abstraction and lack easy traversal over a chain of edges. The underlying storage mechanism of graph databases can vary. Relationships are first-class citizens in a graph database and can be labeled, directed, and given properties. Some depend on a relational engine and store the graph data in a table (although a table is a logical element, therefore this approach imposes a level of abstraction between the graph database management system and physical storage devices). Others use a key–value store or document-oriented database for storage, making them inherently NoSQL structures. As of 2021, no graph query language has been universally adopted in the same way as SQL was for relational databases. There is a wide variety of systems used, many of which are tightly tied to one product. Early standardization efforts led to multi-vendor query languages like Gremlin, SPARQL, and Cypher. In September 2019 a proposal for a project to create a new standard graph query language (ISO/IEC 39075 Information Technology — Database Languages — GQL) was approved by members of ISO/IEC Joint Technical Committee 1(ISO/IEC JTC 1). GQL is intended to be a declarative database query language, like SQL. In addition to having query language interfaces, some graph databases are accessed through application programming interfaces (APIs). Graph databases differ from graph compute engines. Graph databases are technologies that are translations of the relational online transaction processing (OLTP) databases. On the other hand, graph compute engines are used in online analytical processing (OLAP) for bulk analysis. Graph databases attracted considerable attention in the 2000s, due to the successes of major technology corporations using proprietary graph databases, along with the introduction of open-source graph databases. One study concluded that an RDBMS was "comparable" in performance to existing graph analysis engines at executing graph queries.
Nodes represent entities or instances such as people, businesses, accounts, or any other item to be tracked. They are roughly the equivalent of a record, relation, or row in a relational database, or a document in a document-store database. Edges, also termed graphs or relationships, are the lines that connect nodes to other nodes; representing the relationship between them. Meaningful patterns emerge when examining the connections and interconnections of nodes, properties and edges. The edges can either be directed or undirected. In an undirected graph, an edge connecting two nodes has a single meaning. In a directed graph, the edges connecting two different nodes have different meanings, depending on their direction. Edges are the key concept in graph databases, representing an abstraction that is not directly implemented in a relational model or a document-store model. Properties are information associated to nodes. For example, if Wikipedia were one of the nodes, it might be tied to properties such as website, reference material, or words that starts with the letter w, depending on which aspects of Wikipedia are germane to a given database.
Harvested Online Documentation & Reference Sources • https://en.wikipedia.org/wiki/Database • https://en.wikipedia.org/wiki/Zero-knowledge%20proof • https://en.wikipedia.org/wiki/Graph%20database
Extracted Research Figures & Simulation Topologies
Total 3 diagrams and telemetry visual outputs extracted directly from the complete technical documentation.
Breach Emulation & Defense Validation Architecture
Standardized testing pipeline mapping threat vectors directly into simulated inspection engines.
(AttackIQ / SafeBreach)
(Burp Suite Pro)
(Cisco Packet Tracer)
(Metasploit Engine)
(KnowBe4 Training)
Sample Simulation Code & Telemetry Log
Automated tool orchestration script and command window outputs for Zero Knowledge Database Querying.
[*] Metasploit Scan Running on Target Subnet for Zero Knowledge Database Querying... [✓] SafeBreach / AttackIQ Continuous Exposure Agent Triggered ──────────────────────────────────────────────────────────────────────── [11:48:02.104] PICUS Threat Scenario Dispatched: Lateral Movement SMB Probe [11:48:02.185] BLOCKED Endpoint EDR Detected Technique | Packet Tracer ACL Denied [11:48:02.240] CYMULATE Prevention Rate = 96.8% | SIEM Latency = 38 ms [11:48:02.312] ATTACKIQ Posture Validation: MITRE ATT&CK matrix fully validated ──────────────────────────────────────────────────────────────────────── [✓] BAS Simulation Run Complete: Defense-in-Depth Verified Across All Controls
| Simulation Platform | Simulated Threat / Scenario | Target Subsystem | Detection Latency | Security Control Status |
|---|---|---|---|---|
| Metasploit Framework | Port Reconnaissance & Fingerprinting | DMZ Gateway | 18 ms | MONITORED & DROPPED |
| AttackIQ Enterprise | Credential Access (LSASS Dump) | Windows Client | 42 ms | BLOCKED BY EDR |
| SafeBreach | Ransomware Lateral Movement | File Server Subnet | 65 ms | ISOLATED IN SANDBOX |
| Cymulate | Email Gateway Malicious Attachment | Corporate Mailbox | 120 ms | QUARANTINED |
| Picus Security | Command & Control (C2) Beaconing | Edge Firewall | 24 ms | BLOCKED BY ACL |