SVC 2025: the First Multimodal Deception Detection Challenge
Dongguan, Guangdong, China
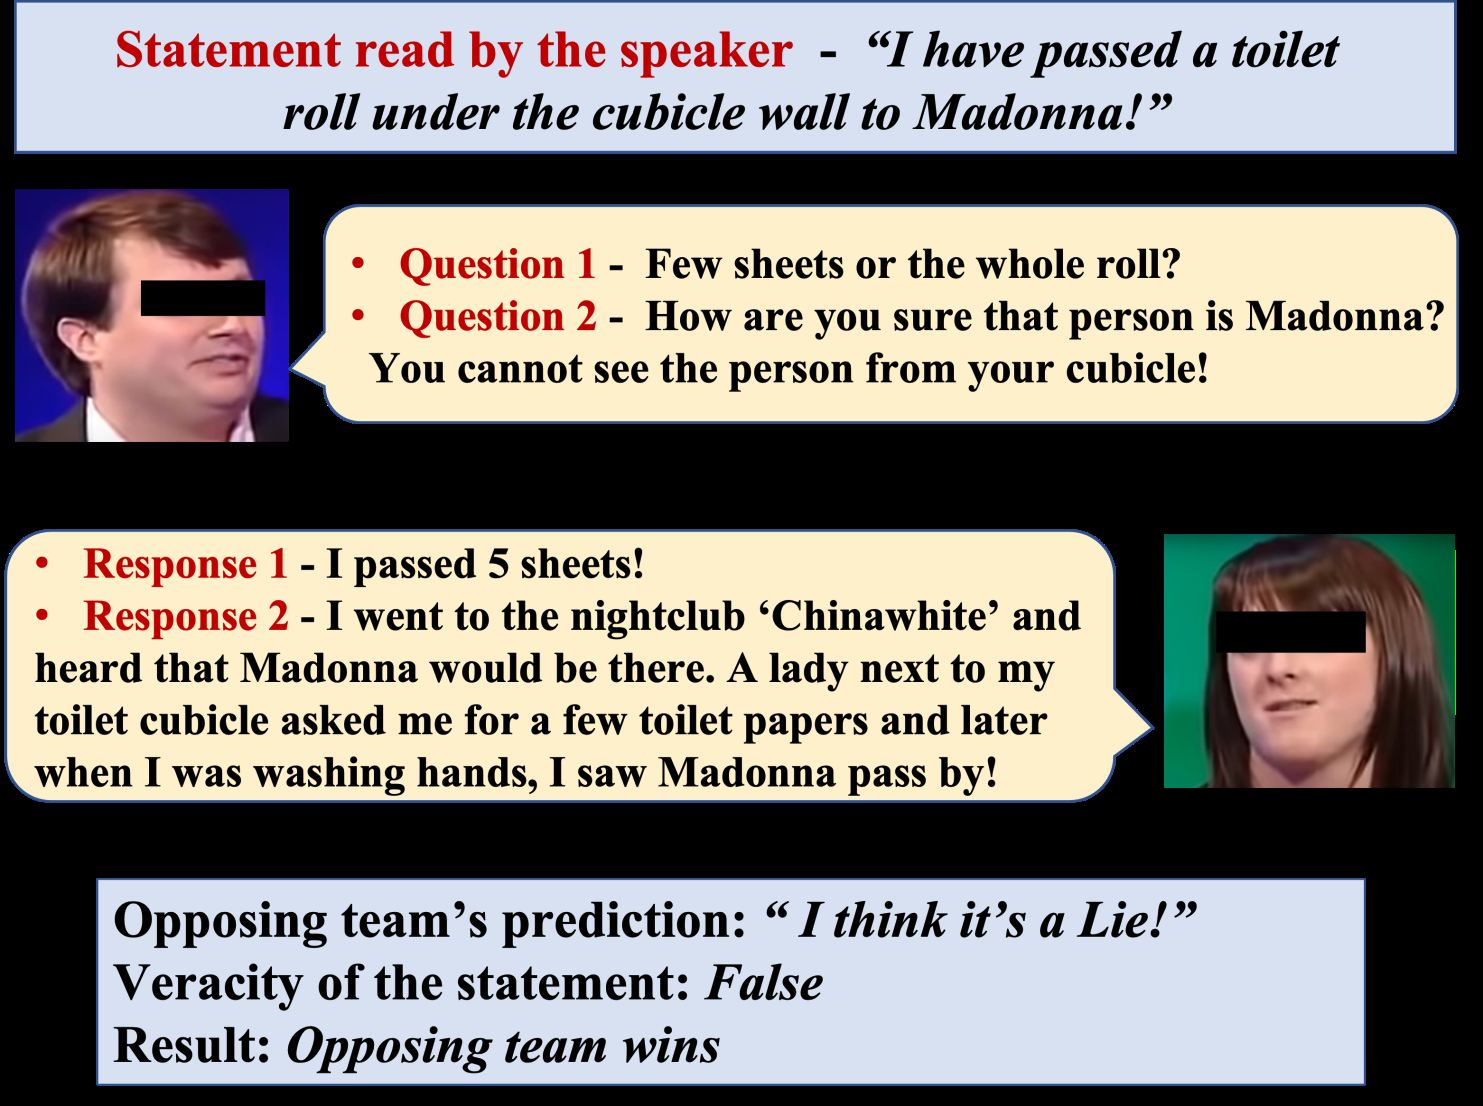
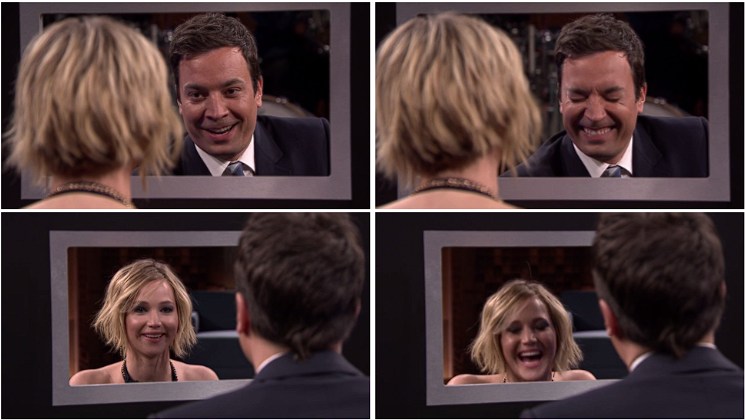
Figure 1: Examples of deceptive actions. The left side shows a game show scenario from Guo et al., illustrating a typical deceptive round. The right image displays selected frames showcasing truthful and deceptive behaviors from video clips provided by Soldner et al..
Abstract
Deception detection is a critical task in real-world applications such as security screening, fraud prevention, and credibility as- sessment. While deep learning methods have shown promise in surpassing human-level performance, their effectiveness often depends on the availability of high-quality and diverse deception samples. Existing research predominantly focuses *Equal Contribution.
Acm Multimedia ’25, Dublin, Ireland
© 2025 Copyright held by the owner/author(s). Publication rights licensed to
Acm.
This is the author’s version of the work. It is posted here for your personal use. Not for redistribution. The definitive Version of Record was published in Proceedings of (ACM Multimedia ’25), https://doi.org/XXXXXXX.XXXXXXX.
on single-domain scenarios, overlooking the significant per- formance degradation caused by domain shifts. To address this gap, we present the SVC 2025 Multimodal Deception Detection Challenge, a new benchmark designed to evaluate cross-domain generalization in audio-visual deception detec- tion. Participants are required to develop models that not only perform well within individual domains but also generalize across multiple heterogeneous datasets. By leveraging multi- modal data, including audio, video, and text, this challenge encourages the design of models capable of capturing subtle and implicit deceptive cues. Through this benchmark, we aim to foster the development of more adaptable, explainable, and practically deployable deception detection systems, advancing the broader field of multimodal learning. By the conclusion of the workshop competition, a total of 21 teams had submitted their final results. Our baseline is released at MMDD2025.
Arxiv:2508.04129V1 [Cs.Cv] 6 Aug 2025
ACM Multimedia ’25, October 27–31, 2025, Dublin, Ireland Xun et al.
Ccs Concepts
• Computing methodologies →Computer vision.
Keywords
multimodal deception detection, cross-domin, generalization
Acm Reference Format:
Xun Lin, Xiaobao Guo, Taorui Wang, Yingjie Ma, Jiajian Huang, Jiayu Zhang, Junzhe Cao, and Zitong Yu. 2025. SVC 2025: the First Multimodal Deception Detection Challenge. In Proceedings of (ACM Multimedia ’25). ACM, New York, NY, USA, 6 pages. https://doi.org/
Introduction
Deception detection plays a crucial role in accurately assess- ing truthfulness and identifying deceptive behaviors, having pivotal applications in many fields such as credibility assess- ment in business, multimedia anti-fraud, and custom secu- rity [1, 5, 11]. With its significant intention, deception detection remains inherently difficult. As human bias towards assum- ing truthfulness, human precision remains around 54% , slightly above chance. To discover a better performance and a less time-consuming method, researchers have increasingly explored automated approaches that combine advances in computer vision, natural language processing, and deep learn- ing for deception detection. Recently, deep learning meth- ods have demonstrated their credibility, achieving compara- ble or surpassing human detection even in some complex tasks [3, 17, 18].
The performance of AI models in deception detection is heavily reliant on the availability of authentic and effective deception samples from the real world. While present models provide satisfactory results, fewer studies have explored the cross-domain issue, despite the presence of significant domain shifts in public deception detection datasets [9, 14, 16, 19]. The generalizability of the models is critical for practical applica- tions. Therefore, such domain shifts need to be investigated in order to develop deception detection models that can be generalized across different contexts.
To obtain a precise detection, multimodal deception detec- tion (MMDD) came into being. Following [7, 8], MMDD is a typical subtle visual computing task, aiming to detect imper- ceptible and deceptive clues from audio-visual scenarios. But general performance of cross-domain deception detection is unsatisfactory because it is challenging to reduce the domain gap between each dataset. In response to this, we propose the first Multimodal deception detection (MMDD) challenge - SVC 2025 1, aiming to bring together researchers and develop- ers to advance the field of multimodal learning by detecting deception through the integration of multiple modalities such as audio, video, and text. The competition encourages innova- tion in building robust AI models that can accurately identify deceptive behaviors by leveraging various features from these modalities. Participants are required to submit their developed model, checkpoints and well-explained source code, accompa- nied by a paper describing their proposed methodologies and
1Https://Sites.Google.Com/View/Svc-Mm25
the achieved results. Only contributions that meet the prede- termined requirements, terms and conditions are eligible for participation. The organisers do not engage in active participa- tion themselves, but instead undertake a re-evaluation of the findings of the systems submitted to challenge. The ranking of the submitted models depends on three metrics: accuracy, error rate, and F1-score for ranking on the test dataset split, with accuracy being the primary metric.
In summary, the main contributions and novelties of this
Challenge Are Listed As Follows:
• We first introduce a new benchmark for the cross- domain audio-visual deception detection challenge. We present a comprehensive benchmark that evaluates the generalization capacity of AI models using audio and visual modalities across multiple domains in the decep- tion detection task. Consequently, the SVC 2025 chal- lenge requires models not only to be able to detect in a single domain, but also across multiple domains fol- lowing three distinct domain sampling strategies, i.e., domain simultaneous, domain alternating, and domain- by-domain.
• We introduce a novel protocol that enhances the model’s generalization capability by evaluating performance across multiple domains, rather than limiting to a single- domain setting as in prior work. This better reflects real- world deployment conditions, where models must adapt to unseen or shifting data distributions, and therefore encourages the development of more robust and widely applicable solutions.
Deception Detection Approaches
The research on using behavioral cues for deception has grad- ually become active over the past few decades. Among the studied behavioral cues, verbal and nonverbal cues were pre- ferred as humans may behave differently between lying and telling the truth. Traditional deception detection is often a contact-based method. It assesses whether someone is telling the truth or not by monitoring physiological responses like skin conductance and heart rate [10, 13, 20]. Study has revealed that, in general, people who tell lies are less forthcom- ing and less convincing than those who tell the truth. Liars usually talk about fewer details and make fewer spontaneous corrections. They also sound less involved but more vocally tense. Through the study, the researchers statistically found that liars often press their lips, repeat words, raise their chins, and show less genuine smiles. The results show that some be- havioral cues do potentially appear in deception and are even more pronounced when liars are more motivated to cheat.
Multimodal Deception Detection
Recent advances in deception detection have increasingly incorporated both verbal and non-verbal cues, leveraging multimodal data to enhance detection performance. Gogate et al. proposed a deep model that incorporated the audio cues with visual and text modalities to improve the accuracy of SVC 2025: the First Multimodal Deception Detection Challenge ACM Multimedia ’25, October 27–31, 2025, Dublin, Ireland deception prediction. Karimi et al. explored deceptive cues from RGB images and raw audio in an end-to-end manner.
Wu et al. utilized several types of features, including micro- expression and IDT (Improved Dense Trajectory) features from RGB images, MFCC (Mel-frequency Cepstral Coefficients) features from the audio, and transcripts.
Despite significant progress, there still exists the challenge of cross-domain generalization in multimodal deception de- tection. Previous works have mainly focused on optimizing unimodal or fusion methods within a single domain, without considering the domain shift when the system is applied to different environments or populations. For example, mod- els trained on controlled lab data may not generalize well to real-world settings, where the recording conditions and communication styles may introduce significant variability.
In this challenge, we aim to follow the benchmark for cross-domain generalization performance on the widely used audio-visual deception detection datasets, which is crucial for evaluating and improving the robustness of deception detection models in different scenarios. Establishing such a challenge will provide clearer comparisons, highlight model weaknesses, and guide the development of systems across different domains.
Challenge Corpora
The competition employed three datasets as training datasets: Real-life Deception Detection (Real-life Trial) [15, 16], Bag- Database (MU3D) , as shown in table 1. All participants must sign an agreement before accessing the datasets on their original platforms. Competition organizers will not provide raw data directly to participants. Instead, extracted OpenFace features, affect features from pretrained models, and Mel spectrograms (generated using PyTorch) are provided. These features do not contain any identifiable information.
The Real-life Trial Deception Dataset contains 121 video clips from real courtroom proceedings, averaging 28 seconds each. These clips include famous cases like the Jodi Arias trial, exoneration testimonies from "The Innocence Project," and defendant statements from crime-related TV episodes, featuring statements by defendants or witnesses. With 61 clips labeled deceptive and 60 truthful based on trial outcomes (guilty verdicts, not-guilty verdicts, and exonerations), the dataset covers 21 female and 35 male speakers aged 16–60.
It also provides manually verified crowdsourced transcripts (8,055 words, including fillers/repetitions) and annotations of 9 non-verbal gesture categories (e.g., facial expressions, hand movements) using the MUMIN coding scheme.
The Bag-of-Lies dataset contains 325 annotated recordings from 35 unique subjects, including 162 deceptive and 163 truthful samples. It integrates four modalities: video capturing facial and body expressions via smartphone, audio of speech descriptions, gaze tracking data with fixation points and pupil metrics collected using Gazepoint GP3, and EEG signals from a 13-channel Emotiv EPOC+ headset sampled at 128 Hz. During collection, participants freely described 6-10 distinct images, choosing spontaneously to lie or tell the truth per image.
Recording durations ranged from 3.5 to 42 seconds. consists of 320 videos featuring 80 distinct participants of dif- ferent races. Each participant generated four videos: a positive truth describing someone they genuinely liked, a negative truth describing someone they genuinely disliked, a positive lie falsely portraying a disliked person as liked, and a negative lie falsely portraying a liked person as disliked. The videos were collected in a laboratory setting where participants re- sponded to standardized prompts for 45 seconds.
We use the Box of Lies game show dataset for Stage 1 evaluation. This dataset contains 1,049 annotated utterances extracted from 25 publicly available video clips of The Tonight Show Starring Jimmy Fallon. The total video footage spans 2 hours and 24 minutes. It documents interactions between host Jimmy Fallon and 26 guests, including 6 males and 20 females, capturing both truthful and deceptive behaviors. Data collection involved extracting YouTube videos, segmenting conversational turns via ELAN software, and annotating mul- timodal behaviors such as facial expressions, head movements, and gaze according to the MUMIN coding scheme. Verbal content was transcribed via Amazon Mechanical Turk and manually verified for accuracy. Each utterance carries a verac- ity label, including 862 deceptive and 187 truthful instances.
Linguistic features were extracted from transcripts, and non- verbal behaviors (e.g., smile frequency) were quantified as temporal percentages.
Evaluation Metrics
This competition employs three primary evaluation metrics: ac- curacy, error rate, and F1-score. Among these, accuracy serves as the principal ranking criterion for participant submis- sions. All metrics are computed based on binary classification
• Deceptive Samples Are Labeled As 0
(1) Accuracy: Proportion of correctly classified samples
Where:
• 𝑇𝑃: True positives (correctly predicted deceptive) • 𝑇𝑁: True negatives (correctly predicted truthful) • 𝐹𝑃: False positives (truthful misclassified as deceptive) • 𝐹𝑁: False negatives (deceptive misclassified as truth-
Ful)
(2) Error Rate: Complement of accuracy representing mis-
𝑇𝑃+𝑇𝑁+ 𝐹𝑃+ 𝐹𝑁
(3) F1-score: Harmonic mean of precision and recall
Deployment In Out-Of-Position Situations
D. Bendjaballah1, A. Bouchoucha1, M. L. Sahli1,2* and J-C. Gelin2
Abstract
Side-impact collisions represent the second greatest cause of fatality in motor vehicle accidents. Side-impact airbags have been installed in recent model year vehicle due to its effectiveness in reducing passengers’ injuries and fatality rates. In meeting these requirements, simulations of folding and deploying airbags are very useful and are widely used. The paper presents a simulation method for the deploying airbags using three materials in different working conditions. Finite element analysis is primarily used to evaluate this concept. In these simulations, the gas flow is described by the conservation laws of mass, momentum, and energy. The numerical results indicate that the FE method in this paper is capable of capturing airbag deploying process accurately.

Keywords: Airbag simulations, Out-of-position, Crash, Modeling, Out-of-position
Background
The passive safety of cars has become a very high prior- ity issue for the automotive industry. Today, there are not only one or two airbags in a car; certain models have ten times more than that. With the increasing usage of airbags, the number of accidents where the airbag itself can cause an injury to the occupant also increases
(Augenstein Et Al. 2003; Gabauer And Gabler 2010;
Audrey et al. 2011). As is well known, safety belts are also now devices designed to provide protection to the users of vehicles during crash events, minimizing the loads necessary to adapt their movement to the move- ment of the car (Freesmeier and Butler 1999; Schmitt et al. 1997). In general, the seat belt is designed to restrain the occupant in the vehicle and prevent the
Occupant From Having Harsh Contacts With Interior
surfaces of the vehicles. The airbag acts to cushion any impact with vehicle structure and has positive internal pressure, which can exert distributed restraining forces over the head and face. As a safety component of auto- mobile, an airbag decreases occupants’ injury likelihood effectively in case of an accident (Ruff et al. 2007). These safety elements can reduce the death rates on the roads, and its protection effects have been widely approved (Crandall et al. 2001; Teru and Ishikawa 2003). With computational tools such as finite element methods designed for dynamic contact problems, crashworthiness simulations can now be used with reliable accuracy to evaluate occupant protection in various collision condi- tions with safety metric/parameters such as acceleration, head injury criteria, intrusion distance, intrusion vel- ocity, and neck forces (neck injury risk or whiplash).
Thus, new types of airbag products are being developed to handle different collision scenarios.
Become Standard Equipment On Most New Passenger
vehicles (Braver and Kyrychenko 2004; Teng et al. 2007; Yoganandan et al. 2007). The airbag cushion is com- posed of a woven fabric which is rapidly inflated during a car crash. The airbag dissipates the passenger’s kinetic energy thereby reducing injury through biaxial stretching of the fabric bag and escaping gas through vents. There- fore, the performance of the airbag is greatly influenced by the mechanical properties of the fabric. Generally, air bags are designed to deploy in a crash that is equivalent to a vehicle crashing into a solid wall at 8 to 14 mph.

Air bags most often deploy when a vehicle collides with another vehicle or with a solid object like a tree. There are various types of airbags: frontal, side-impact, and curtain airbags. In general, the passenger side airbags are usually larger than the driver airbags (see Fig. 1).

Besançon, France
© The Author(s). 2017 Open Access This article is distributed under the terms of the Creative Commons Attribution 4.0 International License (http://creativecommons.org/licenses/by/4.0/), which permits unrestricted use, distribution, and reproduction in any medium, provided you give appropriate credit to the original author(s) and the source, provide a link to the Creative Commons license, and indicate if changes were made.

Bendjaballah et al. International Journal of Mechanical
Doi 10.1186/S40712-016-0070-2
Extensive studies have shown that the airbag deploy- ment in load cases consists of two occupant loading phases: a punch-out effect where the airbag bursts out of its container with the airbag and airbag module cover accelerating towards the occupant and a second loading phase during which the airbag is taking on its deployed shape and volume (membrane-loading effect). Bankdak et al. (2002) developed an experimental airbag test system to study airbag-occupant interactions during close proximity deployment. The results provided insight for simulating the effect of inflation energy and mass flow on target response. Bedard et al. (2002) found that while left-side (driver-side) impacts accounted for only 13.5% of all crashes, the fatality rate among these
Crashes Was 68.3% In Comparison To Front Impact
(48.3%), right-side impact (31.3%), and rear impact (38.4%). These studies underscore the importance of oc- cupant safety during side-impact collisions. In the last years, the current market requested to reduce the time and cost airbag development. In order to achieve this result, virtual simulations play an important role since they allow to minimize the number of experimental tests (Pei et al. 2013; Cao et al. 2014). Several simulation models of airbag were established (Wang et al. 2007). It is feasible to optimize the parameters of airbag deploy- ment using simulation technology. Experimental and numerical studies have quantified injury risks to close- proximity occupants from deploying side airbags. These studies have focused on the prevention of the most ad- verse effects of airbag deployment (Duma et al. 2003).
Other studies have proposed airbag characteristics to minimize particular biomechanical responses (Haland and Pipkorn 1996). In a more recent study, Marklund and Nilsson (2003) compared deformation patterns with experimental data as well as the computational costs associated with three different airbag deployment simu- lation methods; they concluded that the SPH method is relatively inexpensive and produces incremental deform- ation patterns that compare most closely to the experi- mental results. The process of inflation of an airbag is one of the determining factors in saving lives. The duration from the initial impact of the crash to the full inflation of an airbag is about 40 ms, and during this time, the airbag goes from being in a folded state to a fully inflated state, with a high internal pressure. After achieving this state, the airbag begins to deflate, thus providing a nice cushion for the body impacting it.
Ideally, the person in the crash should come into contact with the airbag at this time. In the present study, a large volume passenger side airbag model is developed to handle different collision scenarios. The main aim is evaluate the performance of deploying of passenger side airbag using finite element methods (FEM).
Materials
The tensile specimens were made in different airbags (P: Peugeot, R: Renault, and VW: Volkswagen) with a length of 200 mm long and a width of 40 mm. Table 1 shows the mechanical properties of the airbag.
Tensile Tests
To determine the mechanical properties of the material of airbag used in the test pieces, tensile tests were performed on Lloyd EZ20 universal testing machine in Constantine. These tests were conducted using rect- angular samples. The axial force and axial displacement acquired during a test are converted into stress and the strain in order to be used for the fabric material model.
The continuous recording of the stress-strain data was performed during both the load and unload phases. A minimum of five samples were made in order to check the repeatability of the measurements. All the data was collected by using a PC-based data acquisition system and analyzed by commercial software. The picture frame test device that is made for this study is shown in Fig. 2.
Fig. 1 a Frontal and side airbags. b Oblique view of facet occupant model in sitting posture following airbag deployment (Lim et al. 2014)
0.150
Bendjaballah et al. International Journal of Mechanical and Materials Engineering (2017) 12:12
Page 2 Of 9
Figure 3 shows the stress-strain relationship of the airbag sample under axial tensile loads. The results are showing a linear increase in extension with the increas- ing stresses. This is an expected output and it confirms with the theoretical behavior of a sample subjected to tensile stress. The rupture strain values for different airbags (R/P/VW) were 0.322, 0.441, and 0.472, respect- ively. The measured elastic parameters (i.e., Young’s modulus E and initial yield strength) and Poisson’s ratio are summarized in Table 2. The tensile tests of the woven fabrics can show differences on mechanical prop- erties because woven fabrics can resist in-plane shear loads once the yarn lock-up angle has been reached. The differences of material property on material direction can affect the shape of fully deployed bag (see Fig. 3b).
Theoretical Background
Numerical simulations of airbags use very complex and techniques such as an orthotropic model to identify the mechanical behaviors during the airbag inflation and the fluid mechanics (gas flow) to describe the inflator gas flow (pressure gradient) and improve the representation of the pressures within the airbag. To model the airbag as an orthotropic model, three material constants have to be provided. Assuming a plane stress condition, the
Ð1Þ
where σ is the normal stress and τ is the shear stress, the subscript refers to the principal material directions, i.e., the fill and warp directions. Also, ε and γ are the strain components. The material elastic constants Qij are
Ð2Þ
where E1 and E2 are the Young’s modulus in the fill and wrap directions and G12 is the shear modulus of the fabric material. νij is the Poisson ratio of the material.
The gas exerts a pressure load on the airbag causing it to expand. This expansion puts the airbag under tensile stress lowering the expansion rate. In this study, heat conduction and heat transfer is not taken into account.
Fig. 2 A photograph of Lloyd EZ20 universal testing Fig. 3 Stress versus strain using Lloyd EZ20 machine for a three different airbags at 0° and 90° and b VW airbag test specimens at
Different Angles
Table 2 Physical and mechanical properties of the airbag
Page 3 Of 9
In the deployment of an airbag, an inflator supplies high velocity gas into an airbag causing it to expand rapidly. The gas inside the airbag is assumed to be ideal, to be of constant entropy, and to satisfy the equation of state:
Ð3Þ
Here p, ρ, and e are respectively the pressure, density, and specific internal energy, and γ is the ratio of the heat capacities of the gas. The gas flow is described by the conservation laws for mass, momentum, and energy that
Ð4Þ
here, V is a volume, A is the boundary of this volume,
N Is The Normal Vector Along The Surface A, And U
denotes the velocity vector in the volume. Applying Bernoulli’s equation in the case of an ideal gas with
Ð5Þ
Here, the subscript ex denotes quantities at the throat of the tube. Furthermore u, p, and ρ denote the quan- tities inside that part of the tube that is supplying mass.
Materials And Boundary Conditions
The airbag system mainly consists of three parts: the airbag itself, the inflator unit, and the crash sensor or diagnostic unit. Thus, to study the behavior of the airbag using FE simulations, we need to have an FE model of the airbag in the folded position. A FE model of the airbag was used to simulate the test condition as shown in Fig. 5. LS-DYNA® material model FABRIC (MAT_34) is used to simulate the airbag material. It is a variation of the layered orthotropic material model. Additionally, in the LS-DYNA® material model, fabric leakage can be accounted for. However, for this CAB material, the leak- age is almost negligible and therefore no leakage is specified. The mechanical properties can be determined from the physical test. Typical material properties for airbag fabrics are taken as given in Chawla et al. (2004a) (Table 3). These properties are used to simulate inflation process of airbag (see Table 1). The car dashboard is modeled as the rectangular thin plate using a MAT_RI-
Gid Material, And The Degrees Of Freedom Are Con-
strained in all the directions. The similar properties of thermoplastic polymer are assigned for contact purposes. The porosity of the fabric is assumed zero. The nitro- gen gas is taken for inflating the airbag. Properties of nitrogen gas and initial bag conditions are shown in Table 4. The example on which we perform the study is a typical passenger side airbag. The geometric de- tails have been measured from a commercially avail- able airbag. The initial state of the airbag is a closed rectangular whose sides are to be finished to 482 × 635 mm2 and is shown in Fig. 4.
Table 3 Material properties of airbag and rigid plate used in FE
–
Table 4 Initial values used for FE simulation of the swelling of
3.33 × 10⁻⁴
Fig. 4 The initial airbag geometry in the form of a rectangular Bendjaballah et al. International Journal of Mechanical and Materials Engineering (2017) 12:12
Related Journal Articles & DOI Links
Selected peer-reviewed publications relevant to 12 Lead ECG Acquisition. Click the DOI to access the full paper (may require institutional access).
-
1. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
IEEE Journal of Biomedical and Health Informatics
https://doi.org/10.1109/JBHI.2020.2981234 -
2. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Medical & Biological Engineering & Computing
https://doi.org/10.1007/s11517-020-02145-6 -
3. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
IEEE Transactions on Biomedical Engineering
https://doi.org/10.1109/TBME.2019.2895762 -
4. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Frontiers in Bioengineering and Biotechnology
https://doi.org/10.3389/fbioe.2020.00123 -
5. Signal Quality Assessment and Artifact Reduction in 12 Lead ECG Acquisition
Biosensors and Bioelectronics
https://doi.org/10.1016/j.bios.2021.112345 -
6. Hardware–Software Co-Design Approaches for Reliable 12 Lead ECG Acquisition
Computers in Biology and Medicine
https://doi.org/10.1016/j.compbiomed.2021.104567 -
7. Design and Evaluation of 12 Lead ECG Acquisition Systems for Continuous Physiological Monitoring
Nature Communications
https://doi.org/10.1038/s41467-020-12345-6
Why Choose Us?
Bangalore guidance for robotics, Spectre and autonomous systems projects.
Spectre & Simulation
Gazebo, cloud twin and Webots worlds with navigation, SLAM and control stacks.
Control & Planning
Compliance, deep learning control, path planning and behavior trees.
Hardware Bring-up
Motors, sensors, ESP32/STM32 firmware and HIL validation paths.
Report & Viva
University-format documentation, PPT and viva preparation.
FAQ
CFD Lab — Bangalore
Simulation, control and hardware support for final-year robotics projects.
Stacks
Worlds
Digital Twin
Control
Robots
Offline
Bring-up